diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/cohere2_vision.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/cohere2_vision.md
new file mode 100644
index 0000000000000000000000000000000000000000..bd01992e85a03c292830f781a8a630ba65f524c0
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/cohere2_vision.md
@@ -0,0 +1,140 @@
+
+*This model was released on 2025-07-31 and added to Hugging Face Transformers on 2025-07-31.*
+
+# Command A Vision
+
+
+
+
+
+
+
+
+## Overview
+
+Command A Vision ([blog post](https://cohere.com/blog/command-a-vision)) is a state-of-the-art multimodal model designed to seamlessly integrate visual and textual information for a wide range of applications. By combining advanced computer vision techniques with natural language processing capabilities, Command A Vision enables users to analyze, understand, and generate insights from both visual and textual data.
+
+The model excels at tasks including image captioning, visual question answering, document understanding, and chart understanding. This makes it a versatile tool for AI practitioners. Its ability to process complex visual and textual inputs makes it useful in settings where text-only representations are imprecise or unavailable, like real-world image understanding and graphics-heavy document processing.
+
+Command A Vision is built upon a robust architecture that leverages the latest advancements in VLMs. It's highly performant and efficient, even when dealing with large-scale datasets. The model's flexibility makes it suitable for a wide range of use cases, from content moderation and image search to medical imaging analysis and robotics.
+
+## Usage tips
+
+The model and image processor can be loaded as follows:
+
+
+
+
+```python
+import torch
+
+from transformers import AutoProcessor, AutoModelForImageTextToText
+
+model_id = "CohereLabs/command-a-vision-07-2025"
+
+processor = AutoProcessor.from_pretrained(model_id)
+model = AutoModelForImageTextToText.from_pretrained(
+ model_id, device_map="auto", torch_dtype=torch.float16
+)
+
+# Format message with the Command-A-Vision chat template
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {
+ "type": "image",
+ "url": "https://images.pexels.com/photos/1108099/pexels-photo-1108099.jpeg",
+ },
+ {"type": "text", "text": "what is in this image?"},
+ ],
+ },
+]
+
+inputs = processor.apply_chat_template(
+ messages,
+ padding=True,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+gen_tokens = model.generate(
+ **inputs,
+ max_new_tokens=300,
+ do_sample=True,
+ temperature=0.3,
+)
+
+print(
+ processor.tokenizer.decode(
+ gen_tokens[0][inputs.input_ids.shape[1] :], skip_special_tokens=True
+ )
+)
+```
+
+
+
+
+```python
+from transformers import pipeline
+
+pipe = pipeline(model="CohereLabs/command-a-vision-07-2025", task="image-text-to-text", device_map="auto")
+
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {
+ "type": "image",
+ "url": "https://media.istockphoto.com/id/458012057/photo/istanbul-turkey.jpg?s=612x612&w=0&k=20&c=qogAOVvkpfUyqLUMr_XJQyq-HkACXyYUSZbKhBlPrxo=",
+ },
+ {"type": "text", "text": "Where was this taken ?"},
+ ],
+ },
+]
+
+outputs = pipe(text=messages, max_new_tokens=300, return_full_text=False)
+
+print(outputs)
+```
+
+
+
+## Cohere2VisionConfig
+
+[[autodoc]] Cohere2VisionConfig
+
+## Cohere2VisionForConditionalGeneration
+
+[[autodoc]] Cohere2VisionForConditionalGeneration
+ - forward
+
+## Cohere2VisionModel
+
+[[autodoc]] Cohere2VisionModel
+ - forward
+
+## Cohere2VisionImageProcessorFast
+
+[[autodoc]] Cohere2VisionImageProcessorFast
+ - preprocess
+
+## Cohere2VisionProcessor
+
+[[autodoc]] Cohere2VisionProcessor
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/colpali.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/colpali.md
new file mode 100644
index 0000000000000000000000000000000000000000..b1555e3c5fbbefd2d741347fa8a5a2ee822e14e5
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/colpali.md
@@ -0,0 +1,171 @@
+
+*This model was released on 2024-06-27 and added to Hugging Face Transformers on 2024-12-17.*
+
+
+
+
+
+
+
+# ColPali
+
+[ColPali](https://huggingface.co/papers/2407.01449) is a model designed to retrieve documents by analyzing their visual features. Unlike traditional systems that rely heavily on text extraction and OCR, ColPali treats each page as an image. It uses [Paligemma-3B](./paligemma) to capture not only text, but also the layout, tables, charts, and other visual elements to create detailed multi-vector embeddings that can be used for retrieval by computing pairwise late interaction similarity scores. This offers a more comprehensive understanding of documents and enables more efficient and accurate retrieval.
+
+This model was contributed by [@tonywu71](https://huggingface.co/tonywu71) (ILLUIN Technology) and [@yonigozlan](https://huggingface.co/yonigozlan) (HuggingFace).
+
+You can find all the original ColPali checkpoints under Vidore's [Hf-native ColVision Models](https://huggingface.co/collections/vidore/hf-native-colvision-models-6755d68fc60a8553acaa96f7) collection.
+
+> [!TIP]
+> Click on the ColPali models in the right sidebar for more examples of how to use ColPali for image retrieval.
+
+
+
+
+```python
+import requests
+import torch
+from PIL import Image
+
+from transformers import ColPaliForRetrieval, ColPaliProcessor
+
+
+# Load the model and the processor
+model_name = "vidore/colpali-v1.3-hf"
+
+model = ColPaliForRetrieval.from_pretrained(
+ model_name,
+ torch_dtype=torch.bfloat16,
+ device_map="auto", # "cpu", "cuda", "xpu", or "mps" for Apple Silicon
+)
+processor = ColPaliProcessor.from_pretrained(model_name)
+
+# The document page screenshots from your corpus
+url1 = "https://upload.wikimedia.org/wikipedia/commons/8/89/US-original-Declaration-1776.jpg"
+url2 = "https://upload.wikimedia.org/wikipedia/commons/thumb/4/4c/Romeoandjuliet1597.jpg/500px-Romeoandjuliet1597.jpg"
+
+images = [
+ Image.open(requests.get(url1, stream=True).raw),
+ Image.open(requests.get(url2, stream=True).raw),
+]
+
+# The queries you want to retrieve documents for
+queries = [
+ "When was the United States Declaration of Independence proclaimed?",
+ "Who printed the edition of Romeo and Juliet?",
+]
+
+# Process the inputs
+inputs_images = processor(images=images).to(model.device)
+inputs_text = processor(text=queries).to(model.device)
+
+# Forward pass
+with torch.no_grad():
+ image_embeddings = model(**inputs_images).embeddings
+ query_embeddings = model(**inputs_text).embeddings
+
+# Score the queries against the images
+scores = processor.score_retrieval(query_embeddings, image_embeddings)
+
+print("Retrieval scores (query x image):")
+print(scores)
+```
+
+If you have issue with loading the images with PIL, you can use the following code to create dummy images:
+
+```python
+images = [
+ Image.new("RGB", (128, 128), color="white"),
+ Image.new("RGB", (64, 32), color="black"),
+]
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to quantize the weights to int4.
+
+```python
+import requests
+import torch
+from PIL import Image
+
+from transformers import BitsAndBytesConfig, ColPaliForRetrieval, ColPaliProcessor
+
+
+model_name = "vidore/colpali-v1.3-hf"
+
+# 4-bit quantization configuration
+bnb_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_use_double_quant=True,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_compute_dtype=torch.float16,
+)
+
+model = ColPaliForRetrieval.from_pretrained(
+ model_name,
+ quantization_config=bnb_config,
+ device_map="auto",
+)
+
+processor = ColPaliProcessor.from_pretrained(model_name)
+
+url1 = "https://upload.wikimedia.org/wikipedia/commons/8/89/US-original-Declaration-1776.jpg"
+url2 = "https://upload.wikimedia.org/wikipedia/commons/thumb/4/4c/Romeoandjuliet1597.jpg/500px-Romeoandjuliet1597.jpg"
+
+images = [
+ Image.open(requests.get(url1, stream=True).raw),
+ Image.open(requests.get(url2, stream=True).raw),
+]
+
+queries = [
+ "When was the United States Declaration of Independence proclaimed?",
+ "Who printed the edition of Romeo and Juliet?",
+]
+
+# Process the inputs
+inputs_images = processor(images=images, return_tensors="pt").to(model.device)
+inputs_text = processor(text=queries, return_tensors="pt").to(model.device)
+
+# Forward pass
+with torch.no_grad():
+ image_embeddings = model(**inputs_images).embeddings
+ query_embeddings = model(**inputs_text).embeddings
+
+# Score the queries against the images
+scores = processor.score_retrieval(query_embeddings, image_embeddings)
+
+print("Retrieval scores (query x image):")
+print(scores)
+```
+
+## Notes
+
+- [`~ColPaliProcessor.score_retrieval`] returns a 2D tensor where the first dimension is the number of queries and the second dimension is the number of images. A higher score indicates more similarity between the query and image.
+
+## ColPaliConfig
+
+[[autodoc]] ColPaliConfig
+
+## ColPaliProcessor
+
+[[autodoc]] ColPaliProcessor
+
+## ColPaliForRetrieval
+
+[[autodoc]] ColPaliForRetrieval
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/colqwen2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/colqwen2.md
new file mode 100644
index 0000000000000000000000000000000000000000..a8249bc5c5f22d9b28411007ff09d2f3d4793dcf
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/colqwen2.md
@@ -0,0 +1,177 @@
+
+*This model was released on 2024-06-27 and added to Hugging Face Transformers on 2025-06-02.*
+
+
+
+
+
+
+
+# ColQwen2
+
+[ColQwen2](https://huggingface.co/papers/2407.01449) is a variant of the [ColPali](./colpali) model designed to retrieve documents by analyzing their visual features. Unlike traditional systems that rely heavily on text extraction and OCR, ColQwen2 treats each page as an image. It uses the [Qwen2-VL](./qwen2_vl) backbone to capture not only text, but also the layout, tables, charts, and other visual elements to create detailed multi-vector embeddings that can be used for retrieval by computing pairwise late interaction similarity scores. This offers a more comprehensive understanding of documents and enables more efficient and accurate retrieval.
+
+This model was contributed by [@tonywu71](https://huggingface.co/tonywu71) (ILLUIN Technology) and [@yonigozlan](https://huggingface.co/yonigozlan) (HuggingFace).
+
+You can find all the original ColPali checkpoints under Vidore's [Hf-native ColVision Models](https://huggingface.co/collections/vidore/hf-native-colvision-models-6755d68fc60a8553acaa96f7) collection.
+
+> [!TIP]
+> Click on the ColQwen2 models in the right sidebar for more examples of how to use ColQwen2 for image retrieval.
+
+
+
+
+```python
+import requests
+import torch
+from PIL import Image
+
+from transformers import ColQwen2ForRetrieval, ColQwen2Processor
+from transformers.utils.import_utils import is_flash_attn_2_available
+
+
+# Load the model and the processor
+model_name = "vidore/colqwen2-v1.0-hf"
+
+model = ColQwen2ForRetrieval.from_pretrained(
+ model_name,
+ torch_dtype=torch.bfloat16,
+ device_map="auto", # "cpu", "cuda", or "mps" for Apple Silicon
+ attn_implementation="flash_attention_2" if is_flash_attn_2_available() else "sdpa",
+)
+processor = ColQwen2Processor.from_pretrained(model_name)
+
+# The document page screenshots from your corpus
+url1 = "https://upload.wikimedia.org/wikipedia/commons/8/89/US-original-Declaration-1776.jpg"
+url2 = "https://upload.wikimedia.org/wikipedia/commons/thumb/4/4c/Romeoandjuliet1597.jpg/500px-Romeoandjuliet1597.jpg"
+
+images = [
+ Image.open(requests.get(url1, stream=True).raw),
+ Image.open(requests.get(url2, stream=True).raw),
+]
+
+# The queries you want to retrieve documents for
+queries = [
+ "When was the United States Declaration of Independence proclaimed?",
+ "Who printed the edition of Romeo and Juliet?",
+]
+
+# Process the inputs
+inputs_images = processor(images=images).to(model.device)
+inputs_text = processor(text=queries).to(model.device)
+
+# Forward pass
+with torch.no_grad():
+ image_embeddings = model(**inputs_images).embeddings
+ query_embeddings = model(**inputs_text).embeddings
+
+# Score the queries against the images
+scores = processor.score_retrieval(query_embeddings, image_embeddings)
+
+print("Retrieval scores (query x image):")
+print(scores)
+```
+
+If you have issue with loading the images with PIL, you can use the following code to create dummy images:
+
+```python
+images = [
+ Image.new("RGB", (128, 128), color="white"),
+ Image.new("RGB", (64, 32), color="black"),
+]
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to quantize the weights to int4.
+
+```python
+import requests
+import torch
+from PIL import Image
+
+from transformers import BitsAndBytesConfig, ColQwen2ForRetrieval, ColQwen2Processor
+
+
+model_name = "vidore/colqwen2-v1.0-hf"
+
+# 4-bit quantization configuration
+bnb_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_use_double_quant=True,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_compute_dtype=torch.float16,
+)
+
+model = ColQwen2ForRetrieval.from_pretrained(
+ model_name,
+ quantization_config=bnb_config,
+ device_map="cuda",
+).eval()
+
+processor = ColQwen2Processor.from_pretrained(model_name)
+
+url1 = "https://upload.wikimedia.org/wikipedia/commons/8/89/US-original-Declaration-1776.jpg"
+url2 = "https://upload.wikimedia.org/wikipedia/commons/thumb/4/4c/Romeoandjuliet1597.jpg/500px-Romeoandjuliet1597.jpg"
+
+images = [
+ Image.open(requests.get(url1, stream=True).raw),
+ Image.open(requests.get(url2, stream=True).raw),
+]
+
+queries = [
+ "When was the United States Declaration of Independence proclaimed?",
+ "Who printed the edition of Romeo and Juliet?",
+]
+
+# Process the inputs
+inputs_images = processor(images=images, return_tensors="pt").to(model.device)
+inputs_text = processor(text=queries, return_tensors="pt").to(model.device)
+
+# Forward pass
+with torch.no_grad():
+ image_embeddings = model(**inputs_images).embeddings
+ query_embeddings = model(**inputs_text).embeddings
+
+# Score the queries against the images
+scores = processor.score_retrieval(query_embeddings, image_embeddings)
+
+print("Retrieval scores (query x image):")
+print(scores)
+```
+
+## Notes
+
+- [`~ColQwen2Processor.score_retrieval`] returns a 2D tensor where the first dimension is the number of queries and the second dimension is the number of images. A higher score indicates more similarity between the query and image.
+- Unlike ColPali, ColQwen2 supports arbitrary image resolutions and aspect ratios, which means images are not resized into fixed-size squares. This preserves more of the original input signal.
+- Larger input images generate longer multi-vector embeddings, allowing users to adjust image resolution to balance performance and memory usage.
+
+## ColQwen2Config
+
+[[autodoc]] ColQwen2Config
+
+## ColQwen2Processor
+
+[[autodoc]] ColQwen2Processor
+
+## ColQwen2ForRetrieval
+
+[[autodoc]] ColQwen2ForRetrieval
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/conditional_detr.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/conditional_detr.md
new file mode 100644
index 0000000000000000000000000000000000000000..f5297e49eef3c48951d409307a6c1b2a4b3e6366
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/conditional_detr.md
@@ -0,0 +1,84 @@
+
+*This model was released on 2021-08-13 and added to Hugging Face Transformers on 2022-09-22.*
+
+# Conditional DETR
+
+
+
+
+
+## Overview
+
+The Conditional DETR model was proposed in [Conditional DETR for Fast Training Convergence](https://huggingface.co/papers/2108.06152) by Depu Meng, Xiaokang Chen, Zejia Fan, Gang Zeng, Houqiang Li, Yuhui Yuan, Lei Sun, Jingdong Wang. Conditional DETR presents a conditional cross-attention mechanism for fast DETR training. Conditional DETR converges 6.7× to 10× faster than DETR.
+
+The abstract from the paper is the following:
+
+*The recently-developed DETR approach applies the transformer encoder and decoder architecture to object detection and achieves promising performance. In this paper, we handle the critical issue, slow training convergence, and present a conditional cross-attention mechanism for fast DETR training. Our approach is motivated by that the cross-attention in DETR relies highly on the content embeddings for localizing the four extremities and predicting the box, which increases the need for high-quality content embeddings and thus the training difficulty. Our approach, named conditional DETR, learns a conditional spatial query from the decoder embedding for decoder multi-head cross-attention. The benefit is that through the conditional spatial query, each cross-attention head is able to attend to a band containing a distinct region, e.g., one object extremity or a region inside the object box. This narrows down the spatial range for localizing the distinct regions for object classification and box regression, thus relaxing the dependence on the content embeddings and easing the training. Empirical results show that conditional DETR converges 6.7× faster for the backbones R50 and R101 and 10× faster for stronger backbones DC5-R50 and DC5-R101. Code is available at https://github.com/Atten4Vis/ConditionalDETR.*
+
+
+
+ Conditional DETR shows much faster convergence compared to the original DETR. Taken from the original paper.
+
+This model was contributed by [DepuMeng](https://huggingface.co/DepuMeng). The original code can be found [here](https://github.com/Atten4Vis/ConditionalDETR).
+
+## Resources
+
+- Scripts for finetuning [`ConditionalDetrForObjectDetection`] with [`Trainer`] or [Accelerate](https://huggingface.co/docs/accelerate/index) can be found [here](https://github.com/huggingface/transformers/tree/main/examples/pytorch/object-detection).
+- See also: [Object detection task guide](../tasks/object_detection).
+
+## ConditionalDetrConfig
+
+[[autodoc]] ConditionalDetrConfig
+
+## ConditionalDetrImageProcessor
+
+[[autodoc]] ConditionalDetrImageProcessor
+ - preprocess
+
+## ConditionalDetrImageProcessorFast
+
+[[autodoc]] ConditionalDetrImageProcessorFast
+ - preprocess
+ - post_process_object_detection
+ - post_process_instance_segmentation
+ - post_process_semantic_segmentation
+ - post_process_panoptic_segmentation
+
+## ConditionalDetrFeatureExtractor
+
+[[autodoc]] ConditionalDetrFeatureExtractor
+ - __call__
+ - post_process_object_detection
+ - post_process_instance_segmentation
+ - post_process_semantic_segmentation
+ - post_process_panoptic_segmentation
+
+## ConditionalDetrModel
+
+[[autodoc]] ConditionalDetrModel
+ - forward
+
+## ConditionalDetrForObjectDetection
+
+[[autodoc]] ConditionalDetrForObjectDetection
+ - forward
+
+## ConditionalDetrForSegmentation
+
+[[autodoc]] ConditionalDetrForSegmentation
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/convbert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/convbert.md
new file mode 100644
index 0000000000000000000000000000000000000000..1fbfb809638018601e6c5662b94c5329f1799a29
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/convbert.md
@@ -0,0 +1,142 @@
+
+*This model was released on 2020-08-06 and added to Hugging Face Transformers on 2021-01-27.*
+
+# ConvBERT
+
+
+
+
+
+
+## Overview
+
+The ConvBERT model was proposed in [ConvBERT: Improving BERT with Span-based Dynamic Convolution](https://huggingface.co/papers/2008.02496) by Zihang Jiang, Weihao Yu, Daquan Zhou, Yunpeng Chen, Jiashi Feng, Shuicheng
+Yan.
+
+The abstract from the paper is the following:
+
+*Pre-trained language models like BERT and its variants have recently achieved impressive performance in various
+natural language understanding tasks. However, BERT heavily relies on the global self-attention block and thus suffers
+large memory footprint and computation cost. Although all its attention heads query on the whole input sequence for
+generating the attention map from a global perspective, we observe some heads only need to learn local dependencies,
+which means the existence of computation redundancy. We therefore propose a novel span-based dynamic convolution to
+replace these self-attention heads to directly model local dependencies. The novel convolution heads, together with the
+rest self-attention heads, form a new mixed attention block that is more efficient at both global and local context
+learning. We equip BERT with this mixed attention design and build a ConvBERT model. Experiments have shown that
+ConvBERT significantly outperforms BERT and its variants in various downstream tasks, with lower training cost and
+fewer model parameters. Remarkably, ConvBERTbase model achieves 86.4 GLUE score, 0.7 higher than ELECTRAbase, while
+using less than 1/4 training cost. Code and pre-trained models will be released.*
+
+This model was contributed by [abhishek](https://huggingface.co/abhishek). The original implementation can be found
+here: https://github.com/yitu-opensource/ConvBert
+
+## Usage tips
+
+ConvBERT training tips are similar to those of BERT. For usage tips refer to [BERT documentation](bert).
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## ConvBertConfig
+
+[[autodoc]] ConvBertConfig
+
+## ConvBertTokenizer
+
+[[autodoc]] ConvBertTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## ConvBertTokenizerFast
+
+[[autodoc]] ConvBertTokenizerFast
+
+
+
+
+## ConvBertModel
+
+[[autodoc]] ConvBertModel
+ - forward
+
+## ConvBertForMaskedLM
+
+[[autodoc]] ConvBertForMaskedLM
+ - forward
+
+## ConvBertForSequenceClassification
+
+[[autodoc]] ConvBertForSequenceClassification
+ - forward
+
+## ConvBertForMultipleChoice
+
+[[autodoc]] ConvBertForMultipleChoice
+ - forward
+
+## ConvBertForTokenClassification
+
+[[autodoc]] ConvBertForTokenClassification
+ - forward
+
+## ConvBertForQuestionAnswering
+
+[[autodoc]] ConvBertForQuestionAnswering
+ - forward
+
+
+
+
+## TFConvBertModel
+
+[[autodoc]] TFConvBertModel
+ - call
+
+## TFConvBertForMaskedLM
+
+[[autodoc]] TFConvBertForMaskedLM
+ - call
+
+## TFConvBertForSequenceClassification
+
+[[autodoc]] TFConvBertForSequenceClassification
+ - call
+
+## TFConvBertForMultipleChoice
+
+[[autodoc]] TFConvBertForMultipleChoice
+ - call
+
+## TFConvBertForTokenClassification
+
+[[autodoc]] TFConvBertForTokenClassification
+ - call
+
+## TFConvBertForQuestionAnswering
+
+[[autodoc]] TFConvBertForQuestionAnswering
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/convnext.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/convnext.md
new file mode 100644
index 0000000000000000000000000000000000000000..dc05d3ed3269e3c167fd7547341676d5c38f2440
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/convnext.md
@@ -0,0 +1,105 @@
+
+*This model was released on 2022-01-10 and added to Hugging Face Transformers on 2022-02-07.*
+
+# ConvNeXT
+
+
+
+
+
+
+## Overview
+
+The ConvNeXT model was proposed in [A ConvNet for the 2020s](https://huggingface.co/papers/2201.03545) by Zhuang Liu, Hanzi Mao, Chao-Yuan Wu, Christoph Feichtenhofer, Trevor Darrell, Saining Xie.
+ConvNeXT is a pure convolutional model (ConvNet), inspired by the design of Vision Transformers, that claims to outperform them.
+
+The abstract from the paper is the following:
+
+*The "Roaring 20s" of visual recognition began with the introduction of Vision Transformers (ViTs), which quickly superseded ConvNets as the state-of-the-art image classification model.
+A vanilla ViT, on the other hand, faces difficulties when applied to general computer vision tasks such as object detection and semantic segmentation. It is the hierarchical Transformers
+(e.g., Swin Transformers) that reintroduced several ConvNet priors, making Transformers practically viable as a generic vision backbone and demonstrating remarkable performance on a wide
+variety of vision tasks. However, the effectiveness of such hybrid approaches is still largely credited to the intrinsic superiority of Transformers, rather than the inherent inductive
+biases of convolutions. In this work, we reexamine the design spaces and test the limits of what a pure ConvNet can achieve. We gradually "modernize" a standard ResNet toward the design
+of a vision Transformer, and discover several key components that contribute to the performance difference along the way. The outcome of this exploration is a family of pure ConvNet models
+dubbed ConvNeXt. Constructed entirely from standard ConvNet modules, ConvNeXts compete favorably with Transformers in terms of accuracy and scalability, achieving 87.8% ImageNet top-1 accuracy
+and outperforming Swin Transformers on COCO detection and ADE20K segmentation, while maintaining the simplicity and efficiency of standard ConvNets.*
+
+
+
+ ConvNeXT architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). TensorFlow version of the model was contributed by [ariG23498](https://github.com/ariG23498),
+[gante](https://github.com/gante), and [sayakpaul](https://github.com/sayakpaul) (equal contribution). The original code can be found [here](https://github.com/facebookresearch/ConvNeXt).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with ConvNeXT.
+
+
+
+- [`ConvNextForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## ConvNextConfig
+
+[[autodoc]] ConvNextConfig
+
+## ConvNextFeatureExtractor
+
+[[autodoc]] ConvNextFeatureExtractor
+
+## ConvNextImageProcessor
+
+[[autodoc]] ConvNextImageProcessor
+ - preprocess
+
+## ConvNextImageProcessorFast
+
+[[autodoc]] ConvNextImageProcessorFast
+ - preprocess
+
+
+
+
+## ConvNextModel
+
+[[autodoc]] ConvNextModel
+ - forward
+
+## ConvNextForImageClassification
+
+[[autodoc]] ConvNextForImageClassification
+ - forward
+
+
+
+
+## TFConvNextModel
+
+[[autodoc]] TFConvNextModel
+ - call
+
+## TFConvNextForImageClassification
+
+[[autodoc]] TFConvNextForImageClassification
+ - call
+
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/convnextv2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/convnextv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..531b5a9dcf67bb84a4d64759a51a044c48844b4a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/convnextv2.md
@@ -0,0 +1,74 @@
+
+*This model was released on 2023-01-02 and added to Hugging Face Transformers on 2023-03-14.*
+
+# ConvNeXt V2
+
+
+
+
+
+
+## Overview
+
+The ConvNeXt V2 model was proposed in [ConvNeXt V2: Co-designing and Scaling ConvNets with Masked Autoencoders](https://huggingface.co/papers/2301.00808) by Sanghyun Woo, Shoubhik Debnath, Ronghang Hu, Xinlei Chen, Zhuang Liu, In So Kweon, Saining Xie.
+ConvNeXt V2 is a pure convolutional model (ConvNet), inspired by the design of Vision Transformers, and a successor of [ConvNeXT](convnext).
+
+The abstract from the paper is the following:
+
+*Driven by improved architectures and better representation learning frameworks, the field of visual recognition has enjoyed rapid modernization and performance boost in the early 2020s. For example, modern ConvNets, represented by ConvNeXt, have demonstrated strong performance in various scenarios. While these models were originally designed for supervised learning with ImageNet labels, they can also potentially benefit from self-supervised learning techniques such as masked autoencoders (MAE). However, we found that simply combining these two approaches leads to subpar performance. In this paper, we propose a fully convolutional masked autoencoder framework and a new Global Response Normalization (GRN) layer that can be added to the ConvNeXt architecture to enhance inter-channel feature competition. This co-design of self-supervised learning techniques and architectural improvement results in a new model family called ConvNeXt V2, which significantly improves the performance of pure ConvNets on various recognition benchmarks, including ImageNet classification, COCO detection, and ADE20K segmentation. We also provide pre-trained ConvNeXt V2 models of various sizes, ranging from an efficient 3.7M-parameter Atto model with 76.7% top-1 accuracy on ImageNet, to a 650M Huge model that achieves a state-of-the-art 88.9% accuracy using only public training data.*
+
+
+
+ ConvNeXt V2 architecture. Taken from the original paper.
+
+This model was contributed by [adirik](https://huggingface.co/adirik). The original code can be found [here](https://github.com/facebookresearch/ConvNeXt-V2).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with ConvNeXt V2.
+
+
+
+- [`ConvNextV2ForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## ConvNextV2Config
+
+[[autodoc]] ConvNextV2Config
+
+## ConvNextV2Model
+
+[[autodoc]] ConvNextV2Model
+ - forward
+
+## ConvNextV2ForImageClassification
+
+[[autodoc]] ConvNextV2ForImageClassification
+ - forward
+
+## TFConvNextV2Model
+
+[[autodoc]] TFConvNextV2Model
+ - call
+
+
+## TFConvNextV2ForImageClassification
+
+[[autodoc]] TFConvNextV2ForImageClassification
+ - call
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/cpm.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/cpm.md
new file mode 100644
index 0000000000000000000000000000000000000000..0fe2caa6a4dd04b1f5de71a8dbab8a88970463b1
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/cpm.md
@@ -0,0 +1,63 @@
+
+*This model was released on 2020-12-01 and added to Hugging Face Transformers on 2021-04-10.*
+
+# CPM
+
+
+
+
+
+
+
+## Overview
+
+The CPM model was proposed in [CPM: A Large-scale Generative Chinese Pre-trained Language Model](https://huggingface.co/papers/2012.00413) by Zhengyan Zhang, Xu Han, Hao Zhou, Pei Ke, Yuxian Gu, Deming Ye, Yujia Qin,
+Yusheng Su, Haozhe Ji, Jian Guan, Fanchao Qi, Xiaozhi Wang, Yanan Zheng, Guoyang Zeng, Huanqi Cao, Shengqi Chen,
+Daixuan Li, Zhenbo Sun, Zhiyuan Liu, Minlie Huang, Wentao Han, Jie Tang, Juanzi Li, Xiaoyan Zhu, Maosong Sun.
+
+The abstract from the paper is the following:
+
+*Pre-trained Language Models (PLMs) have proven to be beneficial for various downstream NLP tasks. Recently, GPT-3,
+with 175 billion parameters and 570GB training data, drew a lot of attention due to the capacity of few-shot (even
+zero-shot) learning. However, applying GPT-3 to address Chinese NLP tasks is still challenging, as the training corpus
+of GPT-3 is primarily English, and the parameters are not publicly available. In this technical report, we release the
+Chinese Pre-trained Language Model (CPM) with generative pre-training on large-scale Chinese training data. To the best
+of our knowledge, CPM, with 2.6 billion parameters and 100GB Chinese training data, is the largest Chinese pre-trained
+language model, which could facilitate several downstream Chinese NLP tasks, such as conversation, essay generation,
+cloze test, and language understanding. Extensive experiments demonstrate that CPM achieves strong performance on many
+NLP tasks in the settings of few-shot (even zero-shot) learning.*
+
+This model was contributed by [canwenxu](https://huggingface.co/canwenxu). The original implementation can be found
+here: https://github.com/TsinghuaAI/CPM-Generate
+
+
+
+
+CPM's architecture is the same as GPT-2, except for tokenization method. Refer to [GPT-2 documentation](gpt2) for
+API reference information.
+
+
+
+
+## CpmTokenizer
+
+[[autodoc]] CpmTokenizer
+
+## CpmTokenizerFast
+
+[[autodoc]] CpmTokenizerFast
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/cpmant.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/cpmant.md
new file mode 100644
index 0000000000000000000000000000000000000000..6f13f785ac1ef0143f5cf451af111bbce4301f25
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/cpmant.md
@@ -0,0 +1,52 @@
+
+*This model was released on 2022-09-16 and added to Hugging Face Transformers on 2023-04-12.*
+
+# CPMAnt
+
+
+
+
+
+## Overview
+
+CPM-Ant is an open-source Chinese pre-trained language model (PLM) with 10B parameters. It is also the first milestone of the live training process of CPM-Live. The training process is cost-effective and environment-friendly. CPM-Ant also achieves promising results with delta tuning on the CUGE benchmark. Besides the full model, we also provide various compressed versions to meet the requirements of different hardware configurations. [See more](https://github.com/OpenBMB/CPM-Live/tree/cpm-ant/cpm-live)
+
+This model was contributed by [OpenBMB](https://huggingface.co/openbmb). The original code can be found [here](https://github.com/OpenBMB/CPM-Live/tree/cpm-ant/cpm-live).
+
+## Resources
+
+- A tutorial on [CPM-Live](https://github.com/OpenBMB/CPM-Live/tree/cpm-ant/cpm-live).
+
+## CpmAntConfig
+
+[[autodoc]] CpmAntConfig
+ - all
+
+## CpmAntTokenizer
+
+[[autodoc]] CpmAntTokenizer
+ - all
+
+## CpmAntModel
+
+[[autodoc]] CpmAntModel
+ - all
+
+## CpmAntForCausalLM
+
+[[autodoc]] CpmAntForCausalLM
+ - all
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/csm.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/csm.md
new file mode 100644
index 0000000000000000000000000000000000000000..57d42f7f32abfe68d0e473876254c35790073069
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/csm.md
@@ -0,0 +1,383 @@
+
+*This model was released on 2025-02-27 and added to Hugging Face Transformers on 2025-05-07.*
+
+# Csm
+
+## Overview
+
+The Conversational Speech Model (CSM) is the first open-source contextual text-to-speech model [released by Sesame](https://www.sesame.com/research/crossing_the_uncanny_valley_of_voice). It is designed to generate natural-sounding speech with or without conversational context. This context typically consists of multi-turn dialogue between speakers, represented as sequences of text and corresponding spoken audio.
+
+**Model Architecture:**
+CSM is composed of two LLaMA-style auto-regressive transformer decoders: a backbone decoder that predicts the first codebook token and a depth decoder that generates the remaining tokens. It uses the pretrained codec model [Mimi](./mimi), introduced by Kyutai, to encode speech into discrete codebook tokens and decode them back into audio.
+
+The original csm-1b checkpoint is available under the [Sesame](https://huggingface.co/sesame/csm-1b) organization on Hugging Face.
+
+
+
+
+
+## Usage Tips
+
+### Without Conversational Context
+
+CSM can be used to simply generate speech from a text prompt:
+
+```python
+import torch
+from transformers import CsmForConditionalGeneration, AutoProcessor, infer_device
+
+model_id = "sesame/csm-1b"
+device = infer_device()
+
+# load the model and the processor
+processor = AutoProcessor.from_pretrained(model_id)
+model = CsmForConditionalGeneration.from_pretrained(model_id, device_map=device)
+
+# prepare the inputs
+text = "[0]The past is just a story we tell ourselves." # `[0]` for speaker id 0
+inputs = processor(text, add_special_tokens=True).to(device)
+
+# another equivalent way to prepare the inputs
+conversation = [
+ {"role": "0", "content": [{"type": "text", "text": "The past is just a story we tell ourselves."}]},
+]
+inputs = processor.apply_chat_template(
+ conversation,
+ tokenize=True,
+ return_dict=True,
+).to(device)
+
+# infer the model
+audio = model.generate(**inputs, output_audio=True)
+processor.save_audio(audio, "example_without_context.wav")
+```
+
+### With Conversational Context
+
+CSM can be used to generate speech given a conversation, allowing consistency in the voices and content-aware generation:
+
+```python
+import torch
+from transformers import CsmForConditionalGeneration, AutoProcessor, infer_device
+from datasets import load_dataset, Audio
+
+model_id = "sesame/csm-1b"
+device = infer_device()
+
+# load the model and the processor
+processor = AutoProcessor.from_pretrained(model_id)
+model = CsmForConditionalGeneration.from_pretrained(model_id, device_map=device)
+
+# prepare the inputs
+ds = load_dataset("hf-internal-testing/dailytalk-dummy", split="train")
+# ensure the audio is 24kHz
+ds = ds.cast_column("audio", Audio(sampling_rate=24000))
+conversation = []
+
+# 1. context
+for text, audio, speaker_id in zip(ds[:4]["text"], ds[:4]["audio"], ds[:4]["speaker_id"]):
+ conversation.append(
+ {
+ "role": f"{speaker_id}",
+ "content": [{"type": "text", "text": text}, {"type": "audio", "path": audio["array"]}],
+ }
+ )
+
+# 2. text prompt
+conversation.append({"role": f"{ds[4]['speaker_id']}", "content": [{"type": "text", "text": ds[4]["text"]}]})
+
+inputs = processor.apply_chat_template(
+ conversation,
+ tokenize=True,
+ return_dict=True,
+).to(device)
+
+# infer the model
+audio = model.generate(**inputs, output_audio=True)
+processor.save_audio(audio, "example_with_context.wav")
+```
+
+### Batched Inference
+
+CSM supports batched inference!
+
+```python
+import torch
+from transformers import CsmForConditionalGeneration, AutoProcessor, infer_device
+from datasets import load_dataset, Audio
+
+model_id = "sesame/csm-1b"
+device = infer_device()
+
+# load the model and the processor
+processor = AutoProcessor.from_pretrained(model_id)
+model = CsmForConditionalGeneration.from_pretrained(model_id, device_map=device)
+
+# prepare the inputs
+ds = load_dataset("hf-internal-testing/dailytalk-dummy", split="train")
+# ensure the audio is 24kHz
+ds = ds.cast_column("audio", Audio(sampling_rate=24000))
+# here a batch with two prompts
+conversation = [
+ [
+ {
+ "role": f"{ds[0]['speaker_id']}",
+ "content": [
+ {"type": "text", "text": ds[0]["text"]},
+ {"type": "audio", "path": ds[0]["audio"]["array"]},
+ ],
+ },
+ {
+ "role": f"{ds[1]['speaker_id']}",
+ "content": [
+ {"type": "text", "text": ds[1]["text"]},
+ ],
+ },
+ ],
+ [
+ {
+ "role": f"{ds[0]['speaker_id']}",
+ "content": [
+ {"type": "text", "text": ds[0]["text"]},
+ ],
+ }
+ ],
+]
+inputs = processor.apply_chat_template(
+ conversation,
+ tokenize=True,
+ return_dict=True,
+).to(device)
+
+audio = model.generate(**inputs, output_audio=True)
+processor.save_audio(audio, [f"speech_batch_idx_{i}.wav" for i in range(len(audio))])
+```
+
+### Making The Model Go Brrr
+
+CSM supports full-graph compilation with CUDA graphs!
+
+```python
+import torch
+import copy
+from transformers import CsmForConditionalGeneration, AutoProcessor
+from datasets import load_dataset
+
+model_id = "sesame/csm-1b"
+device = "cuda"
+
+# set logs to ensure no recompilation and graph breaks
+torch._logging.set_logs(graph_breaks=True, recompiles=True, cudagraphs=True)
+
+# load the model and the processor
+processor = AutoProcessor.from_pretrained(model_id)
+model = CsmForConditionalGeneration.from_pretrained(model_id, device_map=device)
+
+# use static cache, enabling automatically torch compile with fullgraph and reduce-overhead
+model.generation_config.max_length = 250 # big enough to avoid recompilation
+model.generation_config.max_new_tokens = None # would take precedence over max_length
+model.generation_config.cache_implementation = "static"
+model.depth_decoder.generation_config.cache_implementation = "static"
+
+# generation kwargs
+gen_kwargs = {
+ "do_sample": False,
+ "depth_decoder_do_sample": False,
+ "temperature": 1.0,
+ "depth_decoder_temperature": 1.0,
+}
+
+# Define a timing decorator
+class TimerContext:
+ def __init__(self, name="Execution"):
+ self.name = name
+ self.start_event = None
+ self.end_event = None
+
+ def __enter__(self):
+ # Use CUDA events for more accurate GPU timing
+ self.start_event = torch.cuda.Event(enable_timing=True)
+ self.end_event = torch.cuda.Event(enable_timing=True)
+ self.start_event.record()
+ return self
+
+ def __exit__(self, *args):
+ self.end_event.record()
+ torch.cuda.synchronize()
+ elapsed_time = self.start_event.elapsed_time(self.end_event) / 1000.0
+ print(f"{self.name} time: {elapsed_time:.4f} seconds")
+
+# prepare the inputs
+ds = load_dataset("hf-internal-testing/dailytalk-dummy", split="train")
+
+conversation = [
+ {
+ "role": f"{ds[0]['speaker_id']}",
+ "content": [
+ {"type": "text", "text": ds[0]["text"]},
+ {"type": "audio", "path": ds[0]["audio"]["array"]},
+ ],
+ },
+ {
+ "role": f"{ds[1]['speaker_id']}",
+ "content": [
+ {"type": "text", "text": ds[1]["text"]},
+ {"type": "audio", "path": ds[1]["audio"]["array"]},
+ ],
+ },
+ {
+ "role": f"{ds[2]['speaker_id']}",
+ "content": [
+ {"type": "text", "text": ds[2]["text"]},
+ ],
+ },
+]
+
+padded_inputs_1 = processor.apply_chat_template(
+ conversation,
+ tokenize=True,
+ return_dict=True,
+).to(device)
+
+print("\n" + "="*50)
+print("First generation - compiling and recording CUDA graphs...")
+with TimerContext("First generation"):
+ _ = model.generate(**padded_inputs_1, **gen_kwargs)
+print("="*50)
+
+print("\n" + "="*50)
+print("Second generation - fast !!!")
+with TimerContext("Second generation"):
+ _ = model.generate(**padded_inputs_1, **gen_kwargs)
+print("="*50)
+
+# now with different inputs
+conversation = [
+ {
+ "role": f"{ds[0]['speaker_id']}",
+ "content": [
+ {"type": "text", "text": ds[2]["text"]},
+ {"type": "audio", "path": ds[2]["audio"]["array"]},
+ ],
+ },
+ {
+ "role": f"{ds[1]['speaker_id']}",
+ "content": [
+ {"type": "text", "text": ds[3]["text"]},
+ {"type": "audio", "path": ds[3]["audio"]["array"]},
+ ],
+ },
+ {
+ "role": f"{ds[2]['speaker_id']}",
+ "content": [
+ {"type": "text", "text": ds[4]["text"]},
+ ],
+ },
+]
+padded_inputs_2 = processor.apply_chat_template(
+ conversation,
+ tokenize=True,
+ return_dict=True,
+).to(device)
+
+print("\n" + "="*50)
+print("Generation with other inputs!")
+with TimerContext("Generation with different inputs"):
+ _ = model.generate(**padded_inputs_2, **gen_kwargs)
+print("="*50)
+```
+
+### Training
+
+CSM Transformers integration supports training!
+
+```python
+from transformers import CsmForConditionalGeneration, AutoProcessor, infer_device
+from datasets import load_dataset, Audio
+
+model_id = "sesame/csm-1b"
+device = infer_device()
+
+# load the model and the processor
+processor = AutoProcessor.from_pretrained(model_id)
+model = CsmForConditionalGeneration.from_pretrained(model_id, device_map=device)
+model.train()
+model.codec_model.eval()
+
+ds = load_dataset("hf-internal-testing/dailytalk-dummy", split="train")
+# ensure the audio is 24kHz
+ds = ds.cast_column("audio", Audio(sampling_rate=24000))
+conversation = []
+
+# context
+for text, audio, speaker_id in zip(ds[:4]["text"], ds[:4]["audio"], ds[:4]["speaker_id"]):
+ conversation.append(
+ {
+ "role": f"{speaker_id}",
+ "content": [{"type": "text", "text": text}, {"type": "audio", "path": audio["array"]}],
+ }
+ )
+
+inputs = processor.apply_chat_template(
+ conversation,
+ tokenize=True,
+ return_dict=True,
+ output_labels=True,
+).to(device)
+
+out = model(**inputs)
+out.loss.backward()
+```
+
+This model was contributed by [Eustache Le Bihan](https://huggingface.co/eustlb).
+The original code can be found [here](https://github.com/SesameAILabs/csm).
+
+
+## CsmConfig
+
+[[autodoc]] CsmConfig
+
+## CsmDepthDecoderConfig
+
+[[autodoc]] CsmDepthDecoderConfig
+
+## CsmProcessor
+
+
+
+
+
+[[autodoc]] CsmProcessor
+ - __call__
+
+## CsmForConditionalGeneration
+
+[[autodoc]] CsmForConditionalGeneration
+ - forward
+ - generate
+
+## CsmDepthDecoderForCausalLM
+
+[[autodoc]] CsmDepthDecoderForCausalLM
+
+## CsmDepthDecoderModel
+
+[[autodoc]] CsmDepthDecoderModel
+
+## CsmBackboneModel
+
+[[autodoc]] CsmBackboneModel
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ctrl.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ctrl.md
new file mode 100644
index 0000000000000000000000000000000000000000..a0ce5434d6ac03c99e1f8d6e32d98ed2b96cf929
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ctrl.md
@@ -0,0 +1,111 @@
+
+*This model was released on 2019-09-11 and added to Hugging Face Transformers on 2020-11-16.*
+
+# CTRL
+
+
+
+
+
+
+## Overview
+
+CTRL model was proposed in [CTRL: A Conditional Transformer Language Model for Controllable Generation](https://huggingface.co/papers/1909.05858) by Nitish Shirish Keskar*, Bryan McCann*, Lav R. Varshney, Caiming Xiong and
+Richard Socher. It's a causal (unidirectional) transformer pre-trained using language modeling on a very large corpus
+of ~140 GB of text data with the first token reserved as a control code (such as Links, Books, Wikipedia etc.).
+
+The abstract from the paper is the following:
+
+*Large-scale language models show promising text generation capabilities, but users cannot easily control particular
+aspects of the generated text. We release CTRL, a 1.63 billion-parameter conditional transformer language model,
+trained to condition on control codes that govern style, content, and task-specific behavior. Control codes were
+derived from structure that naturally co-occurs with raw text, preserving the advantages of unsupervised learning while
+providing more explicit control over text generation. These codes also allow CTRL to predict which parts of the
+training data are most likely given a sequence. This provides a potential method for analyzing large amounts of data
+via model-based source attribution.*
+
+This model was contributed by [keskarnitishr](https://huggingface.co/keskarnitishr). The original code can be found
+[here](https://github.com/salesforce/ctrl).
+
+## Usage tips
+
+- CTRL makes use of control codes to generate text: it requires generations to be started by certain words, sentences
+ or links to generate coherent text. Refer to the [original implementation](https://github.com/salesforce/ctrl) for
+ more information.
+- CTRL is a model with absolute position embeddings so it's usually advised to pad the inputs on the right rather than
+ the left.
+- CTRL was trained with a causal language modeling (CLM) objective and is therefore powerful at predicting the next
+ token in a sequence. Leveraging this feature allows CTRL to generate syntactically coherent text as it can be
+ observed in the *run_generation.py* example script.
+- The PyTorch models can take the `past_key_values` as input, which is the previously computed key/value attention pairs.
+ TensorFlow models accepts `past` as input. Using the `past_key_values` value prevents the model from re-computing
+ pre-computed values in the context of text generation. See the [`forward`](model_doc/ctrl#transformers.CTRLModel.forward)
+ method for more information on the usage of this argument.
+
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## CTRLConfig
+
+[[autodoc]] CTRLConfig
+
+## CTRLTokenizer
+
+[[autodoc]] CTRLTokenizer
+ - save_vocabulary
+
+
+
+
+## CTRLModel
+
+[[autodoc]] CTRLModel
+ - forward
+
+## CTRLLMHeadModel
+
+[[autodoc]] CTRLLMHeadModel
+ - forward
+
+## CTRLForSequenceClassification
+
+[[autodoc]] CTRLForSequenceClassification
+ - forward
+
+
+
+
+## TFCTRLModel
+
+[[autodoc]] TFCTRLModel
+ - call
+
+## TFCTRLLMHeadModel
+
+[[autodoc]] TFCTRLLMHeadModel
+ - call
+
+## TFCTRLForSequenceClassification
+
+[[autodoc]] TFCTRLForSequenceClassification
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/cvt.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/cvt.md
new file mode 100644
index 0000000000000000000000000000000000000000..b247668cc4efb7d84584b66526e0603435040929
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/cvt.md
@@ -0,0 +1,121 @@
+
+*This model was released on 2021-03-29 and added to Hugging Face Transformers on 2022-05-18.*
+
+
+
+
+
+
+
+
+# Convolutional Vision Transformer (CvT)
+
+[Convolutional Vision Transformer (CvT)](https://huggingface.co/papers/2103.15808) is a model that combines the strengths of convolutional neural networks (CNNs) and Vision transformers for the computer vision tasks. It introduces convolutional layers into the vision transformer architecture, allowing it to capture local patterns in images while maintaining the global context provided by self-attention mechanisms.
+
+You can find all the CvT checkpoints under the [Microsoft](https://huggingface.co/microsoft?search_models=cvt) organization.
+
+> [!TIP]
+> This model was contributed by [anujunj](https://huggingface.co/anugunj).
+>
+> Click on the CvT models in the right sidebar for more examples of how to apply CvT to different computer vision tasks.
+
+The example below demonstrates how to classify an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="image-classification",
+ model="microsoft/cvt-13",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg")
+```
+
+
+
+
+```py
+import torch
+import requests
+from PIL import Image
+from transformers import AutoModelForImageClassification, AutoImageProcessor
+
+image_processor = AutoImageProcessor.from_pretrained("microsoft/cvt-13")
+model = AutoModelForImageClassification.from_pretrained(
+ "microsoft/cvt-13",
+ torch_dtype=torch.float16,
+ device_map="auto"
+)
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+image = Image.open(requests.get(url, stream=True).raw)
+inputs = image_processor(image, return_tensors="pt").to(model.device)
+
+with torch.no_grad():
+ logits = model(**inputs).logits
+predicted_class_id = logits.argmax(dim=-1).item()
+
+class_labels = model.config.id2label
+predicted_class_label = class_labels[predicted_class_id]
+print(f"The predicted class label is: {predicted_class_label}")
+```
+
+
+
+
+## Resources
+
+Refer to this set of ViT [notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/VisionTransformer) for examples of inference and fine-tuning on custom datasets. Replace [`ViTFeatureExtractor`] and [`ViTForImageClassification`] in these notebooks with [`AutoImageProcessor`] and [`CvtForImageClassification`].
+
+## CvtConfig
+
+[[autodoc]] CvtConfig
+
+
+
+
+## CvtModel
+
+[[autodoc]] CvtModel
+ - forward
+
+## CvtForImageClassification
+
+[[autodoc]] CvtForImageClassification
+ - forward
+
+
+
+
+## TFCvtModel
+
+[[autodoc]] TFCvtModel
+ - call
+
+## TFCvtForImageClassification
+
+[[autodoc]] TFCvtForImageClassification
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/d_fine.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/d_fine.md
new file mode 100644
index 0000000000000000000000000000000000000000..9dffde75ebc792cc38cdcff31c00697f8d1db16e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/d_fine.md
@@ -0,0 +1,77 @@
+
+*This model was released on 2024-10-17 and added to Hugging Face Transformers on 2025-04-29.*
+
+# D-FINE
+
+## Overview
+
+The D-FINE model was proposed in [D-FINE: Redefine Regression Task in DETRs as Fine-grained Distribution Refinement](https://huggingface.co/papers/2410.13842) by
+Yansong Peng, Hebei Li, Peixi Wu, Yueyi Zhang, Xiaoyan Sun, Feng Wu
+
+The abstract from the paper is the following:
+
+*We introduce D-FINE, a powerful real-time object detector that achieves outstanding localization precision by redefining the bounding box regression task in DETR models. D-FINE comprises two key components: Fine-grained Distribution Refinement (FDR) and Global Optimal Localization Self-Distillation (GO-LSD).
+FDR transforms the regression process from predicting fixed coordinates to iteratively refining probability distributions, providing a fine-grained intermediate representation that significantly enhances localization accuracy. GO-LSD is a bidirectional optimization strategy that transfers localization knowledge from refined distributions to shallower layers through self-distillation, while also simplifying the residual prediction tasks for deeper layers. Additionally, D-FINE incorporates lightweight optimizations in computationally intensive modules and operations, achieving a better balance between speed and accuracy. Specifically, D-FINE-L / X achieves 54.0% / 55.8% AP on the COCO dataset at 124 / 78 FPS on an NVIDIA T4 GPU. When pretrained on Objects365, D-FINE-L / X attains 57.1% / 59.3% AP, surpassing all existing real-time detectors. Furthermore, our method significantly enhances the performance of a wide range of DETR models by up to 5.3% AP with negligible extra parameters and training costs. Our code and pretrained models: this https URL.*
+
+This model was contributed by [VladOS95-cyber](https://github.com/VladOS95-cyber).
+The original code can be found [here](https://github.com/Peterande/D-FINE).
+
+## Usage tips
+
+```python
+>>> import torch
+>>> from transformers.image_utils import load_image
+>>> from transformers import DFineForObjectDetection, AutoImageProcessor
+
+>>> url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+>>> image = load_image(url)
+
+>>> image_processor = AutoImageProcessor.from_pretrained("ustc-community/dfine_x_coco")
+>>> model = DFineForObjectDetection.from_pretrained("ustc-community/dfine_x_coco")
+
+>>> inputs = image_processor(images=image, return_tensors="pt")
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> results = image_processor.post_process_object_detection(outputs, target_sizes=[(image.height, image.width)], threshold=0.5)
+
+>>> for result in results:
+... for score, label_id, box in zip(result["scores"], result["labels"], result["boxes"]):
+... score, label = score.item(), label_id.item()
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"{model.config.id2label[label]}: {score:.2f} {box}")
+cat: 0.96 [344.49, 23.4, 639.84, 374.27]
+cat: 0.96 [11.71, 53.52, 316.64, 472.33]
+remote: 0.95 [40.46, 73.7, 175.62, 117.57]
+sofa: 0.92 [0.59, 1.88, 640.25, 474.74]
+remote: 0.89 [333.48, 77.04, 370.77, 187.3]
+```
+
+## DFineConfig
+
+[[autodoc]] DFineConfig
+
+## DFineModel
+
+[[autodoc]] DFineModel
+ - forward
+
+## DFineForObjectDetection
+
+[[autodoc]] DFineForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dab-detr.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dab-detr.md
new file mode 100644
index 0000000000000000000000000000000000000000..32b27d4b24796d9f0daa29d4dad6f19a572e6adc
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dab-detr.md
@@ -0,0 +1,124 @@
+
+*This model was released on 2022-01-28 and added to Hugging Face Transformers on 2025-02-04.*
+
+# DAB-DETR
+
+
+
+
+
+## Overview
+
+The DAB-DETR model was proposed in [DAB-DETR: Dynamic Anchor Boxes are Better Queries for DETR](https://huggingface.co/papers/2201.12329) by Shilong Liu, Feng Li, Hao Zhang, Xiao Yang, Xianbiao Qi, Hang Su, Jun Zhu, Lei Zhang.
+DAB-DETR is an enhanced variant of Conditional DETR. It utilizes dynamically updated anchor boxes to provide both a reference query point (x, y) and a reference anchor size (w, h), improving cross-attention computation. This new approach achieves 45.7% AP when trained for 50 epochs with a single ResNet-50 model as the backbone.
+
+
+
+The abstract from the paper is the following:
+
+*We present in this paper a novel query formulation using dynamic anchor boxes
+for DETR (DEtection TRansformer) and offer a deeper understanding of the role
+of queries in DETR. This new formulation directly uses box coordinates as queries
+in Transformer decoders and dynamically updates them layer-by-layer. Using box
+coordinates not only helps using explicit positional priors to improve the query-to-feature similarity and eliminate the slow training convergence issue in DETR,
+but also allows us to modulate the positional attention map using the box width
+and height information. Such a design makes it clear that queries in DETR can be
+implemented as performing soft ROI pooling layer-by-layer in a cascade manner.
+As a result, it leads to the best performance on MS-COCO benchmark among
+the DETR-like detection models under the same setting, e.g., AP 45.7% using
+ResNet50-DC5 as backbone trained in 50 epochs. We also conducted extensive
+experiments to confirm our analysis and verify the effectiveness of our methods.*
+
+This model was contributed by [davidhajdu](https://huggingface.co/davidhajdu).
+The original code can be found [here](https://github.com/IDEA-Research/DAB-DETR).
+
+## How to Get Started with the Model
+
+Use the code below to get started with the model.
+
+```python
+import torch
+import requests
+
+from PIL import Image
+from transformers import AutoModelForObjectDetection, AutoImageProcessor
+
+url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+image = Image.open(requests.get(url, stream=True).raw)
+
+image_processor = AutoImageProcessor.from_pretrained("IDEA-Research/dab-detr-resnet-50")
+model = AutoModelForObjectDetection.from_pretrained("IDEA-Research/dab-detr-resnet-50")
+
+inputs = image_processor(images=image, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+results = image_processor.post_process_object_detection(outputs, target_sizes=torch.tensor([image.size[::-1]]), threshold=0.3)
+
+for result in results:
+ for score, label_id, box in zip(result["scores"], result["labels"], result["boxes"]):
+ score, label = score.item(), label_id.item()
+ box = [round(i, 2) for i in box.tolist()]
+ print(f"{model.config.id2label[label]}: {score:.2f} {box}")
+```
+This should output
+```
+cat: 0.87 [14.7, 49.39, 320.52, 469.28]
+remote: 0.86 [41.08, 72.37, 173.39, 117.2]
+cat: 0.86 [344.45, 19.43, 639.85, 367.86]
+remote: 0.61 [334.27, 75.93, 367.92, 188.81]
+couch: 0.59 [-0.04, 1.34, 639.9, 477.09]
+```
+
+There are three other ways to instantiate a DAB-DETR model (depending on what you prefer):
+
+Option 1: Instantiate DAB-DETR with pre-trained weights for entire model
+```py
+>>> from transformers import DabDetrForObjectDetection
+
+>>> model = DabDetrForObjectDetection.from_pretrained("IDEA-Research/dab-detr-resnet-50")
+```
+
+Option 2: Instantiate DAB-DETR with randomly initialized weights for Transformer, but pre-trained weights for backbone
+```py
+>>> from transformers import DabDetrConfig, DabDetrForObjectDetection
+
+>>> config = DabDetrConfig()
+>>> model = DabDetrForObjectDetection(config)
+```
+Option 3: Instantiate DAB-DETR with randomly initialized weights for backbone + Transformer
+```py
+>>> config = DabDetrConfig(use_pretrained_backbone=False)
+>>> model = DabDetrForObjectDetection(config)
+```
+
+
+## DabDetrConfig
+
+[[autodoc]] DabDetrConfig
+
+## DabDetrModel
+
+[[autodoc]] DabDetrModel
+ - forward
+
+## DabDetrForObjectDetection
+
+[[autodoc]] DabDetrForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dac.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dac.md
new file mode 100644
index 0000000000000000000000000000000000000000..e17cc69fc37aaab3b271d69710d422c29211d0a1
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dac.md
@@ -0,0 +1,85 @@
+
+*This model was released on 2023-06-11 and added to Hugging Face Transformers on 2024-08-19.*
+
+# DAC
+
+
+
+
+
+## Overview
+
+
+The DAC model was proposed in [Descript Audio Codec: High-Fidelity Audio Compression with Improved RVQGAN](https://huggingface.co/papers/2306.06546) by Rithesh Kumar, Prem Seetharaman, Alejandro Luebs, Ishaan Kumar, Kundan Kumar.
+
+The Descript Audio Codec (DAC) model is a powerful tool for compressing audio data, making it highly efficient for storage and transmission. By compressing 44.1 KHz audio into tokens at just 8kbps bandwidth, the DAC model enables high-quality audio processing while significantly reducing the data footprint. This is particularly useful in scenarios where bandwidth is limited or storage space is at a premium, such as in streaming applications, remote conferencing, and archiving large audio datasets.
+
+The abstract from the paper is the following:
+
+*Language models have been successfully used to model natural signals, such as images, speech, and music. A key component of these models is a high quality neural compression model that can compress high-dimensional natural signals into lower dimensional discrete tokens. To that end, we introduce a high-fidelity universal neural audio compression algorithm that achieves ~90x compression of 44.1 KHz audio into tokens at just 8kbps bandwidth. We achieve this by combining advances in high-fidelity audio generation with better vector quantization techniques from the image domain, along with improved adversarial and reconstruction losses. We compress all domains (speech, environment, music, etc.) with a single universal model, making it widely applicable to generative modeling of all audio. We compare with competing audio compression algorithms, and find our method outperforms them significantly. We provide thorough ablations for every design choice, as well as open-source code and trained model weights. We hope our work can lay the foundation for the next generation of high-fidelity audio modeling.*
+
+This model was contributed by [Kamil Akesbi](https://huggingface.co/kamilakesbi).
+The original code can be found [here](https://github.com/descriptinc/descript-audio-codec/tree/main?tab=readme-ov-file).
+
+
+## Model structure
+
+The Descript Audio Codec (DAC) model is structured into three distinct stages:
+
+1. Encoder Model: This stage compresses the input audio, reducing its size while retaining essential information.
+2. Residual Vector Quantizer (RVQ) Model: Working in tandem with the encoder, this model quantizes the latent codes of the audio, refining the compression and ensuring high-quality reconstruction.
+3. Decoder Model: This final stage reconstructs the audio from its compressed form, restoring it to a state that closely resembles the original input.
+
+## Usage example
+
+Here is a quick example of how to encode and decode an audio using this model:
+
+```python
+>>> from datasets import load_dataset, Audio
+>>> from transformers import DacModel, AutoProcessor
+>>> librispeech_dummy = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+
+>>> model = DacModel.from_pretrained("descript/dac_16khz")
+>>> processor = AutoProcessor.from_pretrained("descript/dac_16khz")
+>>> librispeech_dummy = librispeech_dummy.cast_column("audio", Audio(sampling_rate=processor.sampling_rate))
+>>> audio_sample = librispeech_dummy[-1]["audio"]["array"]
+>>> inputs = processor(raw_audio=audio_sample, sampling_rate=processor.sampling_rate, return_tensors="pt")
+
+>>> encoder_outputs = model.encode(inputs["input_values"])
+>>> # Get the intermediate audio codes
+>>> audio_codes = encoder_outputs.audio_codes
+>>> # Reconstruct the audio from its quantized representation
+>>> audio_values = model.decode(encoder_outputs.quantized_representation)
+>>> # or the equivalent with a forward pass
+>>> audio_values = model(inputs["input_values"]).audio_values
+```
+
+## DacConfig
+
+[[autodoc]] DacConfig
+
+## DacFeatureExtractor
+
+[[autodoc]] DacFeatureExtractor
+ - __call__
+
+## DacModel
+
+[[autodoc]] DacModel
+ - decode
+ - encode
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/data2vec.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/data2vec.md
new file mode 100644
index 0000000000000000000000000000000000000000..ed2b01622fb1d8de92805e9a6b79644966dc1a23
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/data2vec.md
@@ -0,0 +1,235 @@
+
+*This model was released on 2022-02-07 and added to Hugging Face Transformers on 2022-03-01.*
+
+# Data2Vec
+
+
+
+
+
+
+
+## Overview
+
+The Data2Vec model was proposed in [data2vec: A General Framework for Self-supervised Learning in Speech, Vision and Language](https://huggingface.co/papers/2202.03555) by Alexei Baevski, Wei-Ning Hsu, Qiantong Xu, Arun Babu, Jiatao Gu and Michael Auli.
+Data2Vec proposes a unified framework for self-supervised learning across different data modalities - text, audio and images.
+Importantly, predicted targets for pre-training are contextualized latent representations of the inputs, rather than modality-specific, context-independent targets.
+
+The abstract from the paper is the following:
+
+*While the general idea of self-supervised learning is identical across modalities, the actual algorithms and
+objectives differ widely because they were developed with a single modality in mind. To get us closer to general
+self-supervised learning, we present data2vec, a framework that uses the same learning method for either speech,
+NLP or computer vision. The core idea is to predict latent representations of the full input data based on a
+masked view of the input in a selfdistillation setup using a standard Transformer architecture.
+Instead of predicting modality-specific targets such as words, visual tokens or units of human speech which
+are local in nature, data2vec predicts contextualized latent representations that contain information from
+the entire input. Experiments on the major benchmarks of speech recognition, image classification, and
+natural language understanding demonstrate a new state of the art or competitive performance to predominant approaches.
+Models and code are available at www.github.com/pytorch/fairseq/tree/master/examples/data2vec.*
+
+This model was contributed by [edugp](https://huggingface.co/edugp) and [patrickvonplaten](https://huggingface.co/patrickvonplaten).
+[sayakpaul](https://github.com/sayakpaul) and [Rocketknight1](https://github.com/Rocketknight1) contributed Data2Vec for vision in TensorFlow.
+
+The original code (for NLP and Speech) can be found [here](https://github.com/pytorch/fairseq/tree/main/examples/data2vec).
+The original code for vision can be found [here](https://github.com/facebookresearch/data2vec_vision/tree/main/beit).
+
+## Usage tips
+
+- Data2VecAudio, Data2VecText, and Data2VecVision have all been trained using the same self-supervised learning method.
+- For Data2VecAudio, preprocessing is identical to [`Wav2Vec2Model`], including feature extraction
+- For Data2VecText, preprocessing is identical to [`RobertaModel`], including tokenization.
+- For Data2VecVision, preprocessing is identical to [`BeitModel`], including feature extraction.
+- The `head_mask` argument is ignored when using all attention implementation other than "eager". If you have a `head_mask` and want it to have effect, load the model with `XXXModel.from_pretrained(model_id, attn_implementation="eager")`
+
+### Using Scaled Dot Product Attention (SDPA)
+
+PyTorch includes a native scaled dot-product attention (SDPA) operator as part of `torch.nn.functional`. This function
+encompasses several implementations that can be applied depending on the inputs and the hardware in use. See the
+[official documentation](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)
+or the [GPU Inference](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)
+page for more information.
+
+SDPA is used by default for `torch>=2.1.1` when an implementation is available, but you may also set
+`attn_implementation="sdpa"` in `from_pretrained()` to explicitly request SDPA to be used.
+
+The SDPA implementation is currently available for the Data2VecAudio and Data2VecVision models.
+
+```
+from transformers import Data2VecVisionForImageClassification
+model = Data2VecVisionForImageClassification.from_pretrained("facebook/data2vec-vision-base", attn_implementation="sdpa", torch_dtype=torch.float16)
+...
+```
+
+For the best speedups, we recommend loading the model in half-precision (e.g. `torch.float16` or `torch.bfloat16`).
+
+For the Data2VecVision model, on a local benchmark (NVIDIA GeForce RTX 2060-8GB, PyTorch 2.5.1, OS Ubuntu 20.04)
+with `float16` and `facebook/data2vec-vision-base` model, we saw the following improvements during training and
+inference:
+
+#### Training
+
+| num_training_steps | batch_size | image_size | is_cuda | Time per batch (eager - s) | Time per batch (sdpa - s) | Speedup (%) | Eager peak mem (MB) | SDPA peak mem (MB) | Mem saving (%) |
+|--------------------|------------|--------------|---------|----------------------------|---------------------------|-------------|----------------------|--------------------|----------------|
+| 50 | 2 | (1048, 640) | True | 0.996 | 0.754 | 32.147 | 6722.198 | 4264.653 | 57.626 |
+
+#### Inference
+
+| Image batch size | Eager (s/iter) | Eager CI, % | Eager memory (MB) | SDPA (s/iter) | SDPA CI, % | SDPA memory (MB) | SDPA speedup | SDPA memory saved |
+|-------------------:|-----------------:|:--------------|--------------------:|----------------:|:-------------|-------------------:|---------------:|--------------------:|
+| 1 | 0.011 | ±0.3% | 3.76143e+08 | 0.01 | ±0.3% | 3.74397e+08 | 1.101 | 0.466 |
+| 4 | 0.014 | ±0.1% | 4.02756e+08 | 0.012 | ±0.2% | 3.91373e+08 | 1.219 | 2.909 |
+| 16 | 0.046 | ±0.3% | 4.96482e+08 | 0.035 | ±0.2% | 4.51017e+08 | 1.314 | 10.081 |
+| 32 | 0.088 | ±0.1% | 6.23903e+08 | 0.067 | ±0.1% | 5.32974e+08 | 1.33 | 17.061 |
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Data2Vec.
+
+
+
+- [`Data2VecVisionForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- To fine-tune [`TFData2VecVisionForImageClassification`] on a custom dataset, see [this notebook](https://colab.research.google.com/github/sayakpaul/TF-2.0-Hacks/blob/master/data2vec_vision_image_classification.ipynb).
+
+**Data2VecText documentation resources**
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+**Data2VecAudio documentation resources**
+- [Audio classification task guide](../tasks/audio_classification)
+- [Automatic speech recognition task guide](../tasks/asr)
+
+**Data2VecVision documentation resources**
+- [Image classification](../tasks/image_classification)
+- [Semantic segmentation](../tasks/semantic_segmentation)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## Data2VecTextConfig
+
+[[autodoc]] Data2VecTextConfig
+
+## Data2VecAudioConfig
+
+[[autodoc]] Data2VecAudioConfig
+
+## Data2VecVisionConfig
+
+[[autodoc]] Data2VecVisionConfig
+
+
+
+
+## Data2VecAudioModel
+
+[[autodoc]] Data2VecAudioModel
+ - forward
+
+## Data2VecAudioForAudioFrameClassification
+
+[[autodoc]] Data2VecAudioForAudioFrameClassification
+ - forward
+
+## Data2VecAudioForCTC
+
+[[autodoc]] Data2VecAudioForCTC
+ - forward
+
+## Data2VecAudioForSequenceClassification
+
+[[autodoc]] Data2VecAudioForSequenceClassification
+ - forward
+
+## Data2VecAudioForXVector
+
+[[autodoc]] Data2VecAudioForXVector
+ - forward
+
+## Data2VecTextModel
+
+[[autodoc]] Data2VecTextModel
+ - forward
+
+## Data2VecTextForCausalLM
+
+[[autodoc]] Data2VecTextForCausalLM
+ - forward
+
+## Data2VecTextForMaskedLM
+
+[[autodoc]] Data2VecTextForMaskedLM
+ - forward
+
+## Data2VecTextForSequenceClassification
+
+[[autodoc]] Data2VecTextForSequenceClassification
+ - forward
+
+## Data2VecTextForMultipleChoice
+
+[[autodoc]] Data2VecTextForMultipleChoice
+ - forward
+
+## Data2VecTextForTokenClassification
+
+[[autodoc]] Data2VecTextForTokenClassification
+ - forward
+
+## Data2VecTextForQuestionAnswering
+
+[[autodoc]] Data2VecTextForQuestionAnswering
+ - forward
+
+## Data2VecVisionModel
+
+[[autodoc]] Data2VecVisionModel
+ - forward
+
+## Data2VecVisionForImageClassification
+
+[[autodoc]] Data2VecVisionForImageClassification
+ - forward
+
+## Data2VecVisionForSemanticSegmentation
+
+[[autodoc]] Data2VecVisionForSemanticSegmentation
+ - forward
+
+
+
+
+## TFData2VecVisionModel
+
+[[autodoc]] TFData2VecVisionModel
+ - call
+
+## TFData2VecVisionForImageClassification
+
+[[autodoc]] TFData2VecVisionForImageClassification
+ - call
+
+## TFData2VecVisionForSemanticSegmentation
+
+[[autodoc]] TFData2VecVisionForSemanticSegmentation
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dbrx.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dbrx.md
new file mode 100644
index 0000000000000000000000000000000000000000..3647e4196cdf0e213ce064e827a245fd9775f111
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dbrx.md
@@ -0,0 +1,126 @@
+
+*This model was released on 2024-03-27 and added to Hugging Face Transformers on 2024-04-18.*
+
+# DBRX
+
+
+
+
+
+
+
+## Overview
+
+DBRX is a [transformer-based](https://www.isattentionallyouneed.com/) decoder-only large language model (LLM) that was trained using next-token prediction.
+It uses a *fine-grained* mixture-of-experts (MoE) architecture with 132B total parameters of which 36B parameters are active on any input.
+It was pre-trained on 12T tokens of text and code data.
+Compared to other open MoE models like Mixtral-8x7B and Grok-1, DBRX is fine-grained, meaning it uses a larger number of smaller experts. DBRX has 16 experts and chooses 4, while Mixtral-8x7B and Grok-1 have 8 experts and choose 2.
+This provides 65x more possible combinations of experts and we found that this improves model quality.
+DBRX uses rotary position encodings (RoPE), gated linear units (GLU), and grouped query attention (GQA).
+It is a BPE based model and uses the GPT-4 tokenizer as described in the [tiktoken](https://github.com/openai/tiktoken) repository.
+We made these choices based on exhaustive evaluation and scaling experiments.
+
+DBRX was pretrained on 12T tokens of carefully curated data and a maximum context length of 32K tokens.
+We estimate that this data is at least 2x better token-for-token than the data we used to pretrain the MPT family of models.
+This new dataset was developed using the full suite of Databricks tools, including Apache Spark™ and Databricks notebooks for data processing, and Unity Catalog for data management and governance.
+We used curriculum learning for pretraining, changing the data mix during training in ways we found to substantially improve model quality.
+
+
+More detailed information about DBRX Instruct and DBRX Base can be found in our [technical blog post](https://www.databricks.com/blog/introducing-dbrx-new-state-art-open-llm).
+
+This model was contributed by [eitan-turok](https://huggingface.co/eitanturok) and [abhi-db](https://huggingface.co/abhi-db). The original code can be found [here](https://github.com/databricks/dbrx-instruct), though this may not be up to date.
+
+## Usage Examples
+
+The `generate()` method can be used to generate text using DBRX. You can generate using the standard attention implementation, flash-attention, and the PyTorch scaled dot product attention. The last two attention implementations give speed ups.
+
+```python
+from transformers import DbrxForCausalLM, AutoTokenizer
+import torch
+
+tokenizer = AutoTokenizer.from_pretrained("databricks/dbrx-instruct", token="YOUR_HF_TOKEN")
+model = DbrxForCausalLM.from_pretrained(
+ "databricks/dbrx-instruct",
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+ token="YOUR_HF_TOKEN",
+ )
+
+input_text = "What does it take to build a great LLM?"
+messages = [{"role": "user", "content": input_text}]
+input_ids = tokenizer.apply_chat_template(messages, return_dict=True, tokenize=True, add_generation_prompt=True, return_tensors="pt").to(model.device)
+
+outputs = model.generate(**input_ids, max_new_tokens=200)
+print(tokenizer.decode(outputs[0]))
+```
+
+If you have flash-attention installed (`pip install flash-attn`), it is possible to generate faster. (The HuggingFace documentation for flash-attention can be found [here](https://huggingface.co/docs/transformers/perf_infer_gpu_one#flashattention-2).)
+```python
+from transformers import DbrxForCausalLM, AutoTokenizer
+import torch
+
+tokenizer = AutoTokenizer.from_pretrained("databricks/dbrx-instruct", token="YOUR_HF_TOKEN")
+model = DbrxForCausalLM.from_pretrained(
+ "databricks/dbrx-instruct",
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+ token="YOUR_HF_TOKEN",
+ attn_implementation="flash_attention_2",
+ )
+
+input_text = "What does it take to build a great LLM?"
+messages = [{"role": "user", "content": input_text}]
+input_ids = tokenizer.apply_chat_template(messages, return_dict=True, tokenize=True, add_generation_prompt=True, return_tensors="pt").to(model.device)
+
+outputs = model.generate(**input_ids, max_new_tokens=200)
+print(tokenizer.decode(outputs[0]))
+```
+
+You can also generate faster using the PyTorch scaled dot product attention. (The HuggingFace documentation for scaled dot product attention can be found [here](https://huggingface.co/docs/transformers/perf_infer_gpu_one#pytorch-scaled-dot-product-attention).)
+```python
+from transformers import DbrxForCausalLM, AutoTokenizer
+import torch
+
+tokenizer = AutoTokenizer.from_pretrained("databricks/dbrx-instruct", token="YOUR_HF_TOKEN")
+model = DbrxForCausalLM.from_pretrained(
+ "databricks/dbrx-instruct",
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+ token="YOUR_HF_TOKEN",
+ attn_implementation="sdpa",
+ )
+
+input_text = "What does it take to build a great LLM?"
+messages = [{"role": "user", "content": input_text}]
+input_ids = tokenizer.apply_chat_template(messages, return_dict=True, tokenize=True, add_generation_prompt=True, return_tensors="pt").to(model.device)
+
+outputs = model.generate(**input_ids, max_new_tokens=200)
+print(tokenizer.decode(outputs[0]))
+```
+
+## DbrxConfig
+
+[[autodoc]] DbrxConfig
+
+
+## DbrxModel
+
+[[autodoc]] DbrxModel
+ - forward
+
+
+## DbrxForCausalLM
+
+[[autodoc]] DbrxForCausalLM
+ - forward
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deberta-v2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deberta-v2.md
new file mode 100644
index 0000000000000000000000000000000000000000..db7e9c0561d0e28a6e00ab0c3e9e395538fda275
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deberta-v2.md
@@ -0,0 +1,219 @@
+
+*This model was released on 2020-06-05 and added to Hugging Face Transformers on 2021-02-19.*
+
+
+
+
+
+
+
+
+
+# DeBERTa-v2
+
+[DeBERTa-v2](https://huggingface.co/papers/2006.03654) improves on the original [DeBERTa](./deberta) architecture by using a SentencePiece-based tokenizer and a new vocabulary size of 128K. It also adds an additional convolutional layer within the first transformer layer to better learn local dependencies of input tokens. Finally, the position projection and content projection matrices are shared in the attention layer to reduce the number of parameters.
+
+You can find all the original [DeBERTa-v2] checkpoints under the [Microsoft](https://huggingface.co/microsoft?search_models=deberta-v2) organization.
+
+
+> [!TIP]
+> This model was contributed by [Pengcheng He](https://huggingface.co/DeBERTa).
+>
+> Click on the DeBERTa-v2 models in the right sidebar for more examples of how to apply DeBERTa-v2 to different language tasks.
+
+The example below demonstrates how to classify text with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="text-classification",
+ model="microsoft/deberta-v2-xlarge-mnli",
+ device=0,
+ torch_dtype=torch.float16
+)
+result = pipeline("DeBERTa-v2 is great at understanding context!")
+print(result)
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "microsoft/deberta-v2-xlarge-mnli"
+)
+model = AutoModelForSequenceClassification.from_pretrained(
+ "microsoft/deberta-v2-xlarge-mnli",
+ torch_dtype=torch.float16,
+ device_map="auto"
+)
+
+inputs = tokenizer("DeBERTa-v2 is great at understanding context!", return_tensors="pt").to("cuda")
+outputs = model(**inputs)
+
+logits = outputs.logits
+predicted_class_id = logits.argmax().item()
+predicted_label = model.config.id2label[predicted_class_id]
+print(f"Predicted label: {predicted_label}")
+
+```
+
+
+
+
+
+```bash
+echo -e "DeBERTa-v2 is great at understanding context!" | transformers-cli run --task fill-mask --model microsoft/deberta-v2-xlarge-mnli --device 0
+```
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes quantization](../quantization/bitsandbytes) to only quantize the weights to 4-bit.
+
+```py
+from transformers import AutoModelForSequenceClassification, AutoTokenizer, BitsAndBytesConfig
+
+model_id = "microsoft/deberta-v2-xlarge-mnli"
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_compute_dtype="float16",
+ bnb_4bit_use_double_quant=True,
+)
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = AutoModelForSequenceClassification.from_pretrained(
+ model_id,
+ quantization_config=quantization_config,
+ torch_dtype="float16"
+)
+
+inputs = tokenizer("DeBERTa-v2 is great at understanding context!", return_tensors="pt").to("cuda")
+outputs = model(**inputs)
+logits = outputs.logits
+predicted_class_id = logits.argmax().item()
+predicted_label = model.config.id2label[predicted_class_id]
+print(f"Predicted label: {predicted_label}")
+
+```
+
+
+## DebertaV2Config
+
+[[autodoc]] DebertaV2Config
+
+## DebertaV2Tokenizer
+
+[[autodoc]] DebertaV2Tokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## DebertaV2TokenizerFast
+
+[[autodoc]] DebertaV2TokenizerFast
+ - build_inputs_with_special_tokens
+ - create_token_type_ids_from_sequences
+
+
+
+
+## DebertaV2Model
+
+[[autodoc]] DebertaV2Model
+ - forward
+
+## DebertaV2PreTrainedModel
+
+[[autodoc]] DebertaV2PreTrainedModel
+ - forward
+
+## DebertaV2ForMaskedLM
+
+[[autodoc]] DebertaV2ForMaskedLM
+ - forward
+
+## DebertaV2ForSequenceClassification
+
+[[autodoc]] DebertaV2ForSequenceClassification
+ - forward
+
+## DebertaV2ForTokenClassification
+
+[[autodoc]] DebertaV2ForTokenClassification
+ - forward
+
+## DebertaV2ForQuestionAnswering
+
+[[autodoc]] DebertaV2ForQuestionAnswering
+ - forward
+
+## DebertaV2ForMultipleChoice
+
+[[autodoc]] DebertaV2ForMultipleChoice
+ - forward
+
+
+
+
+## TFDebertaV2Model
+
+[[autodoc]] TFDebertaV2Model
+ - call
+
+## TFDebertaV2PreTrainedModel
+
+[[autodoc]] TFDebertaV2PreTrainedModel
+ - call
+
+## TFDebertaV2ForMaskedLM
+
+[[autodoc]] TFDebertaV2ForMaskedLM
+ - call
+
+## TFDebertaV2ForSequenceClassification
+
+[[autodoc]] TFDebertaV2ForSequenceClassification
+ - call
+
+## TFDebertaV2ForTokenClassification
+
+[[autodoc]] TFDebertaV2ForTokenClassification
+ - call
+
+## TFDebertaV2ForQuestionAnswering
+
+[[autodoc]] TFDebertaV2ForQuestionAnswering
+ - call
+
+## TFDebertaV2ForMultipleChoice
+
+[[autodoc]] TFDebertaV2ForMultipleChoice
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deberta.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deberta.md
new file mode 100644
index 0000000000000000000000000000000000000000..b5f18b6430f3e36588cccd8daaab729ce905f058
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deberta.md
@@ -0,0 +1,187 @@
+
+*This model was released on 2020-06-05 and added to Hugging Face Transformers on 2020-11-16.*
+
+
+
+
+
+
+
+
+
+# DeBERTa
+
+[DeBERTa](https://huggingface.co/papers/2006.03654) improves the pretraining efficiency of BERT and RoBERTa with two key ideas, disentangled attention and an enhanced mask decoder. Instead of mixing everything together like BERT, DeBERTa separates a word's *content* from its *position* and processes them independently. This gives it a clearer sense of what's being said and where in the sentence it's happening.
+
+The enhanced mask decoder replaces the traditional softmax decoder to make better predictions.
+
+Even with less training data than RoBERTa, DeBERTa manages to outperform it on several benchmarks.
+
+You can find all the original DeBERTa checkpoints under the [Microsoft](https://huggingface.co/microsoft?search_models=deberta) organization.
+
+
+> [!TIP]
+> Click on the DeBERTa models in the right sidebar for more examples of how to apply DeBERTa to different language tasks.
+
+The example below demonstrates how to classify text with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+classifier = pipeline(
+ task="text-classification",
+ model="microsoft/deberta-base-mnli",
+ device=0,
+)
+
+classifier({
+ "text": "A soccer game with multiple people playing.",
+ "text_pair": "Some people are playing a sport."
+})
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForSequenceClassification, AutoTokenizer
+
+model_name = "microsoft/deberta-base-mnli"
+tokenizer = AutoTokenizer.from_pretrained("microsoft/deberta-base-mnli")
+model = AutoModelForSequenceClassification.from_pretrained("microsoft/deberta-base-mnli", device_map="auto")
+
+inputs = tokenizer(
+ "A soccer game with multiple people playing.",
+ "Some people are playing a sport.",
+ return_tensors="pt"
+).to("cuda")
+
+with torch.no_grad():
+ logits = model(**inputs).logits
+ predicted_class = logits.argmax().item()
+
+labels = ["contradiction", "neutral", "entailment"]
+print(f"The predicted relation is: {labels[predicted_class]}")
+
+```
+
+
+
+
+```bash
+echo -e '{"text": "A soccer game with multiple people playing.", "text_pair": "Some people are playing a sport."}' | transformers run --task text-classification --model microsoft/deberta-base-mnli --device 0
+```
+
+
+
+
+## Notes
+- DeBERTa uses **relative position embeddings**, so it does not require **right-padding** like BERT.
+- For best results, use DeBERTa on sentence-level or sentence-pair classification tasks like MNLI, RTE, or SST-2.
+- If you're using DeBERTa for token-level tasks like masked language modeling, make sure to load a checkpoint specifically pretrained or fine-tuned for token-level tasks.
+
+## DebertaConfig
+
+[[autodoc]] DebertaConfig
+
+## DebertaTokenizer
+
+[[autodoc]] DebertaTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## DebertaTokenizerFast
+
+[[autodoc]] DebertaTokenizerFast
+ - build_inputs_with_special_tokens
+ - create_token_type_ids_from_sequences
+
+
+
+
+## DebertaModel
+
+[[autodoc]] DebertaModel
+ - forward
+
+## DebertaPreTrainedModel
+
+[[autodoc]] DebertaPreTrainedModel
+
+## DebertaForMaskedLM
+
+[[autodoc]] DebertaForMaskedLM
+ - forward
+
+## DebertaForSequenceClassification
+
+[[autodoc]] DebertaForSequenceClassification
+ - forward
+
+## DebertaForTokenClassification
+
+[[autodoc]] DebertaForTokenClassification
+ - forward
+
+## DebertaForQuestionAnswering
+
+[[autodoc]] DebertaForQuestionAnswering
+ - forward
+
+
+
+
+## TFDebertaModel
+
+[[autodoc]] TFDebertaModel
+ - call
+
+## TFDebertaPreTrainedModel
+
+[[autodoc]] TFDebertaPreTrainedModel
+ - call
+
+## TFDebertaForMaskedLM
+
+[[autodoc]] TFDebertaForMaskedLM
+ - call
+
+## TFDebertaForSequenceClassification
+
+[[autodoc]] TFDebertaForSequenceClassification
+ - call
+
+## TFDebertaForTokenClassification
+
+[[autodoc]] TFDebertaForTokenClassification
+ - call
+
+## TFDebertaForQuestionAnswering
+
+[[autodoc]] TFDebertaForQuestionAnswering
+ - call
+
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/decision_transformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/decision_transformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..cdfcd42f9a343009c4874ecc7e204e08c02ecfd2
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/decision_transformer.md
@@ -0,0 +1,58 @@
+
+*This model was released on 2021-06-02 and added to Hugging Face Transformers on 2022-03-23.*
+
+# Decision Transformer
+
+
+
+
+
+## Overview
+
+The Decision Transformer model was proposed in [Decision Transformer: Reinforcement Learning via Sequence Modeling](https://huggingface.co/papers/2106.01345)
+by Lili Chen, Kevin Lu, Aravind Rajeswaran, Kimin Lee, Aditya Grover, Michael Laskin, Pieter Abbeel, Aravind Srinivas, Igor Mordatch.
+
+The abstract from the paper is the following:
+
+*We introduce a framework that abstracts Reinforcement Learning (RL) as a sequence modeling problem.
+This allows us to draw upon the simplicity and scalability of the Transformer architecture, and associated advances
+ in language modeling such as GPT-x and BERT. In particular, we present Decision Transformer, an architecture that
+ casts the problem of RL as conditional sequence modeling. Unlike prior approaches to RL that fit value functions or
+ compute policy gradients, Decision Transformer simply outputs the optimal actions by leveraging a causally masked
+ Transformer. By conditioning an autoregressive model on the desired return (reward), past states, and actions, our
+ Decision Transformer model can generate future actions that achieve the desired return. Despite its simplicity,
+ Decision Transformer matches or exceeds the performance of state-of-the-art model-free offline RL baselines on
+ Atari, OpenAI Gym, and Key-to-Door tasks.*
+
+This version of the model is for tasks where the state is a vector.
+
+This model was contributed by [edbeeching](https://huggingface.co/edbeeching). The original code can be found [here](https://github.com/kzl/decision-transformer).
+
+## DecisionTransformerConfig
+
+[[autodoc]] DecisionTransformerConfig
+
+
+## DecisionTransformerGPT2Model
+
+[[autodoc]] DecisionTransformerGPT2Model
+ - forward
+
+## DecisionTransformerModel
+
+[[autodoc]] DecisionTransformerModel
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deepseek_v2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deepseek_v2.md
new file mode 100644
index 0000000000000000000000000000000000000000..bcdf65fbe8c0b8b400f418203a28d8133f7087ea
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deepseek_v2.md
@@ -0,0 +1,50 @@
+
+*This model was released on 2024-05-07 and added to Hugging Face Transformers on 2025-07-09.*
+
+# DeepSeek-V2
+
+## Overview
+
+The DeepSeek-V2 model was proposed in [DeepSeek-V2: A Strong, Economical, and Efficient Mixture-of-Experts Language Model](https://huggingface.co/papers/2405.04434) by DeepSeek-AI Team.
+
+The abstract from the paper is the following:
+We present DeepSeek-V2, a strong Mixture-of-Experts (MoE) language model characterized by economical training and efficient inference. It comprises 236B total parameters, of which 21B are activated for each token, and supports a context length of 128K tokens. DeepSeek-V2 adopts innovative architectures including Multi-head Latent Attention (MLA) and DeepSeekMoE. MLA guarantees efficient inference through significantly compressing the Key-Value (KV) cache into a latent vector, while DeepSeekMoE enables training strong models at an economical cost through sparse computation. Compared with DeepSeek 67B, DeepSeek-V2 achieves significantly stronger performance, and meanwhile saves 42.5% of training costs, reduces the KV cache by 93.3%, and boosts the maximum generation throughput to 5.76 times. We pretrain DeepSeek-V2 on a high-quality and multi-source corpus consisting of 8.1T tokens, and further perform Supervised Fine-Tuning (SFT) and Reinforcement Learning (RL) to fully unlock its potential. Evaluation results show that, even with only 21B activated parameters, DeepSeek-V2 and its chat versions still achieve top-tier performance among open-source models.
+
+This model was contributed by [VladOS95-cyber](https://github.com/VladOS95-cyber).
+The original code can be found [here](https://huggingface.co/deepseek-ai/DeepSeek-V2).
+
+### Usage tips
+The model uses Multi-head Latent Attention (MLA) and DeepSeekMoE architectures for efficient inference and cost-effective training. It employs an auxiliary-loss-free strategy for load balancing and multi-token prediction training objective. The model can be used for various language tasks after being pre-trained on 14.8 trillion tokens and going through Supervised Fine-Tuning and Reinforcement Learning stages.
+
+## DeepseekV2Config
+
+[[autodoc]] DeepseekV2Config
+
+## DeepseekV2Model
+
+[[autodoc]] DeepseekV2Model
+ - forward
+
+## DeepseekV2ForCausalLM
+
+[[autodoc]] DeepseekV2ForCausalLM
+ - forward
+
+## DeepseekV2ForSequenceClassification
+
+[[autodoc]] DeepseekV2ForSequenceClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deepseek_v3.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deepseek_v3.md
new file mode 100644
index 0000000000000000000000000000000000000000..85008b1596af744535651c9e6543af73ef5dfc63
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deepseek_v3.md
@@ -0,0 +1,185 @@
+
+*This model was released on 2024-12-27 and added to Hugging Face Transformers on 2025-03-28.*
+
+# DeepSeek-V3
+
+## Overview
+
+The DeepSeek-V3 model was proposed in [DeepSeek-V3 Technical Report](https://huggingface.co/papers/2412.19437) by DeepSeek-AI Team.
+
+The abstract from the paper is the following:
+We present DeepSeek-V3, a strong Mixture-of-Experts (MoE) language model with 671B total parameters with 37B activated for each token. To achieve efficient inference and cost-effective training, DeepSeek-V3 adopts Multi-head Latent Attention (MLA) and DeepSeekMoE architectures, which were thoroughly validated in DeepSeek-V2. Furthermore, DeepSeek-V3 pioneers an auxiliary-loss-free strategy for load balancing and sets a multi-token prediction training objective for stronger performance. We pre-train DeepSeek-V3 on 14.8 trillion diverse and high-quality tokens, followed by Supervised Fine-Tuning and Reinforcement Learning stages to fully harness its capabilities. Comprehensive evaluations reveal that DeepSeek-V3 outperforms other open-source models and achieves performance comparable to leading closed-source models. Despite its excellent performance, DeepSeek-V3 requires only 2.788M H800 GPU hours for its full training. In addition, its training process is remarkably stable. Throughout the entire training process, we did not experience any irrecoverable loss spikes or perform any rollbacks. The model checkpoints are available at https://github.com/deepseek-ai/DeepSeek-V3.
+
+## Limitations and call for contribution!
+
+We are super happy to make this code community-powered, and would love to see how you can best optimize the following:
+
+- current implementation uses the "naive" attention compution (so not really MLA)
+- current implementation loops through the experts. This should be replaced. Pointers to use `get_packed_weights` from `integrations/tensor_parallel`.
+- current implementation uses the eleuther formula for ROPE, using the original one would be more efficient! (should still follow our API)
+- static cache is not supported (this should be just a generation config issue / config shape issues)
+
+### Usage tips
+The model uses Multi-head Latent Attention (MLA) and DeepSeekMoE architectures for efficient inference and cost-effective training. It employs an auxiliary-loss-free strategy for load balancing and multi-token prediction training objective. The model can be used for various language tasks after being pre-trained on 14.8 trillion tokens and going through Supervised Fine-Tuning and Reinforcement Learning stages.
+
+You can run the model in `FP8` automatically, using 2 nodes of 8 H100 should be more than enough!
+
+```python
+# `run_deepseek_v1.py`
+from transformers import AutoModelForCausalLM, AutoTokenizer
+import torch
+torch.manual_seed(30)
+
+tokenizer = AutoTokenizer.from_pretrained("deepseek-r1")
+
+chat = [
+ {"role": "user", "content": "Hello, how are you?"},
+ {"role": "assistant", "content": "I'm doing great. How can I help you today?"},
+ {"role": "user", "content": "I'd like to show off how chat templating works!"},
+]
+
+
+model = AutoModelForCausalLM.from_pretrained("deepseek-r1", device_map="auto", torch_dtype=torch.bfloat16)
+inputs = tokenizer.apply_chat_template(chat, tokenize=True, add_generation_prompt=True, return_tensors="pt").to(model.device)
+import time
+start = time.time()
+outputs = model.generate(inputs, max_new_tokens=50)
+print(tokenizer.batch_decode(outputs))
+print(time.time()-start)
+```
+This generated:
+
+``````
+<|Assistant|>
+Okay, the user wants to demonstrate how chat templating works. Let me break down what that means. Chat templating is about structuring the conversation data, especially for models that need specific input formats. Maybe they're referring to something like how messages are formatted with roles (user, assistant, system) in APIs like OpenAI.
+
+First, I should explain what chat templating is. It's the process of formatting conversation data into a structured format that the model can understand. This usually includes roles and content. For example, user messages, assistant responses, and system messages each have their own role tags.
+
+They might want an example. Let me think of a simple conversation. The user says "Hello, how are you?" and the assistant responds "I'm doing great. How can I help you today?" Then the user follows up with wanting to show off chat templating. So the example should include the history and the new message.
+
+In some frameworks, like Hugging Face's Transformers, chat templates are applied using Jinja2 templates. The template might look something like combining system messages, then looping through user and assistant messages with appropriate tags. For instance, using {% for message in messages %} and assigning roles like <|user|>, <|assistant|>, etc.
+
+I should structure the example with the messages array, showing each role and content. Then apply a hypothetical template to convert that into a formatted string the model uses. Also, mention that different models have different templating requirements, like using special tokens or varying role labels.
+
+Wait, the user mentioned "chat templating" in the context of showing off. Maybe they want a practical example they can present. So providing a code snippet or a structured data example would be helpful. Let me outline a typical messages array and then the templated output.
+
+Also, it's important to note that proper templating ensures the model knows the conversation flow, which is crucial for generating coherent responses. Maybe include a note about why it's important, like maintaining context and role-specific processing.
+
+Let me check if there are any common mistakes or things to avoid. For example, not closing tags properly, or mismatching roles. But maybe that's too detailed unless the user asks. Focus on the positive example first.
+
+Putting it all together, the response should have an example messages array, the applied template, and the final formatted string. Maybe use angle brackets or special tokens as placeholders. Also, mention that this helps in training or fine-tuning models with structured data.
+
+I think that's a solid approach. Let me structure it step by step to make it clear.
+
+
+Chat templating is a way to structure conversation data (e.g., user/assistant interactions) into a format that language models understand. This is especially important for models trained to handle multi-turn dialogues, where the input must explicitly separate roles (user, assistant, system, etc.) and messages. Let’s break this down with an example!
+
+---
+
+### **Step 1: Raw Conversation History**
+Suppose we have this conversation:
+- **User**: "Hello, how are you?"
+- **Assistant**: "I'm doing great. How can I help you today?"
+- **User**: "I'd like to show off how chat templating works!"
+
+---
+
+### **Step 2: Structured Messages**
+In frameworks like Hugging Face Transformers or OpenAI, conversations are often formatted as a list of dictionaries with `role` and `content`:
+```python
+messages = [
+ {"role": "user", "content": "Hello, how are you?"},
+ {"role": "assistant", "content": "I'm doing great. How can I help you today?"},
+ {"role": "user", "content": "I'd like to show off how chat templating works!"},
+]
+```
+
+---
+
+### **Step 3: Apply a Chat Template**
+A **chat template** converts this structured data into a single string formatted for the model. For example, using a Jinja-style template (common in Hugging Face):
+
+```jinja
+{% for message in messages %}
+ {% if message['role'] == 'user' %}
+ <|user|>{{ message['content'] }}<|end|>
+ {% elif message['role'] == 'assistant' %}
+ <|assistant|>{{ message['content'] }}<|end|>
+ {% endif %}
+{% endfor %}
+<|assistant|>
+```
+
+---
+
+### **Step 4: Final Templated Output**
+Applying the template to our `messages` list would produce:
+```text
+<|user|>Hello, how are you?<|end|>
+<|assistant|>I'm doing great. How can I help you today?<|end|>
+<|user|>I'd like to show off how chat templating works!<|end|>
+<|assistant|>
+```
+
+This tells the model:
+1. The conversation history (user/assistant turns).
+2. The model’s turn to generate a response (`<|assistant|>` at the end).
+
+---
+
+### **Key Notes**:
+- **Role Separation**: Tags like `<|user|>` and `<|assistant|>` help the model distinguish speakers.
+- **Special Tokens**: Models often use unique tokens (e.g., `<|end|>`) to mark message boundaries.
+- **Flexibility**: Templates vary by model (e.g., OpenAI uses `{"role": "user", "content": "..."}` instead of tags).
+
+---
+
+### **Why This Matters**:
+- **Consistency**: Ensures the model understands dialogue structure.
+- **Context Preservation**: Maintains the flow of multi-turn conversations.
+- **Alignment**: Matches the format the model was trained on for better performance.
+
+Want to dive deeper or see a specific framework’s implementation (e.g., OpenAI, Llama, Mistral)? Let me know! 😊<|end▁of▁sentence|>
+``````
+
+Use the following to run it
+```bash
+torchrun --nproc_per_node=8 --nnodes=2 --node_rank=0|1 --rdzv-id an_id --rdzv-backend c10d --rdzv-endpoint master_addr:master_port run_deepseek_r1.py
+```
+
+If you have:
+```bash
+[rank0]: ncclInternalError: Internal check failed.
+[rank0]: Last error:
+[rank0]: Bootstrap : no socket interface found
+```
+error, it means NCCL was probably not loaded.
+
+
+## DeepseekV3Config
+
+[[autodoc]] DeepseekV3Config
+
+## DeepseekV3Model
+
+[[autodoc]] DeepseekV3Model
+ - forward
+
+## DeepseekV3ForCausalLM
+
+[[autodoc]] DeepseekV3ForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deepseek_vl.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deepseek_vl.md
new file mode 100644
index 0000000000000000000000000000000000000000..863472118d4ac17c980701d3b9d5dd8ea87f5781
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deepseek_vl.md
@@ -0,0 +1,225 @@
+
+*This model was released on 2024-03-08 and added to Hugging Face Transformers on 2025-07-25.*
+
+
+
+
+
+
+
+
+
+# DeepseekVL
+
+[Deepseek-VL](https://huggingface.co/papers/2403.05525) was introduced by the DeepSeek AI team. It is a vision-language model (VLM) designed to process both text and images for generating contextually relevant responses. The model leverages [LLaMA](./llama) as its text encoder, while [SigLip](./siglip) is used for encoding images.
+
+You can find all the original Deepseek-VL checkpoints under the [DeepSeek-community](https://huggingface.co/deepseek-community) organization.
+
+> [!TIP]
+> Click on the Deepseek-VL models in the right sidebar for more examples of how to apply Deepseek-VL to different vision and language tasks.
+
+The example below demonstrates how to generate text based on an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipe = pipeline(
+ task="image-text-to-text",
+ model="deepseek-community/deepseek-vl-1.3b-chat",
+ device=0,
+ torch_dtype=torch.float16
+)
+
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {
+ "type": "image",
+ "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg",
+ },
+ { "type": "text", "text": "Describe this image."},
+ ]
+ }
+]
+
+pipe(text=messages, max_new_tokens=20, return_full_text=False)
+```
+
+
+
+
+```py
+import torch
+from transformers import DeepseekVLForConditionalGeneration, AutoProcessor
+
+model = DeepseekVLForConditionalGeneration.from_pretrained(
+ "deepseek-community/deepseek-vl-1.3b-chat",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+
+processor = AutoProcessor.from_pretrained("deepseek-community/deepseek-vl-1.3b-chat")
+
+messages = [
+ {
+ "role":"user",
+ "content":[
+ {
+ "type":"image",
+ "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+ },
+ {
+ "type":"text",
+ "text":"Describe this image."
+ }
+ ]
+ }
+
+]
+
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+).to(model.device, dtype=model.dtype)
+
+generated_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids_trimmed = [
+ out_ids[len(in_ids) :] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
+]
+output_text = processor.batch_decode(
+ generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
+)
+
+print(output_text)
+```
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [torchao](../quantization/torchao) to only quantize the weights to int4.
+
+```python
+import torch
+from transformers import TorchAoConfig, DeepseekVLForConditionalGeneration, AutoProcessor
+
+quantization_config = TorchAoConfig(
+ "int4_weight_only",
+ group_size=128
+)
+
+model = DeepseekVLForConditionalGeneration.from_pretrained(
+ "deepseek-community/deepseek-vl-1.3b-chat",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+```
+### Notes
+
+- Do inference with multiple images in a single conversation.
+ ```py
+ import torch
+ from transformers import DeepseekVLForConditionalGeneration, AutoProcessor
+
+ model = DeepseekVLForConditionalGeneration.from_pretrained(
+ "deepseek-community/deepseek-vl-1.3b-chat",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+ )
+
+ processor = AutoProcessor.from_pretrained("deepseek-community/deepseek-vl-1.3b-chat")
+
+ messages = [
+ [
+ {
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "What’s the difference between"},
+ {"type": "image", "url": "http://images.cocodataset.org/val2017/000000039769.jpg"},
+ {"type": "text", "text": " and "},
+ {"type": "image", "url": "https://www.ilankelman.org/stopsigns/australia.jpg"}
+ ]
+ }
+ ],
+ [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/snowman.jpg"},
+ {"type": "text", "text": "What do you see in this image?"}
+ ]
+ }
+ ]
+ ]
+
+ inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ padding=True,
+ truncation=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+ ).to(model.device, dtype=model.dtype)
+
+ generated_ids = model.generate(**inputs, max_new_tokens=128)
+ generated_ids_trimmed = [
+ out_ids[len(in_ids) :] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
+ ]
+ output_text = processor.batch_decode(
+ generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
+ )
+
+ print(output_text)
+ ```
+
+## DeepseekVLConfig
+
+[[autodoc]] DeepseekVLConfig
+
+## DeepseekVLProcessor
+
+[[autodoc]] DeepseekVLProcessor
+
+## DeepseekVLImageProcessor
+
+[[autodoc]] DeepseekVLImageProcessor
+
+## DeepseekVLImageProcessorFast
+
+[[autodoc]] DeepseekVLImageProcessorFast
+
+## DeepseekVLModel
+
+[[autodoc]] DeepseekVLModel
+ - forward
+
+## DeepseekVLForConditionalGeneration
+
+[[autodoc]] DeepseekVLForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deepseek_vl_hybrid.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deepseek_vl_hybrid.md
new file mode 100644
index 0000000000000000000000000000000000000000..b9aec339aeb14b2edb430efb656d85c2144efee7
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deepseek_vl_hybrid.md
@@ -0,0 +1,224 @@
+
+*This model was released on 2024-03-08 and added to Hugging Face Transformers on 2025-07-25.*
+
+
+
+
+
+
+
+
+# DeepseekVLHybrid
+
+[Deepseek-VL-Hybrid](https://huggingface.co/papers/2403.05525) was introduced by the DeepSeek AI team. It is a vision-language model (VLM) designed to process both text and images for generating contextually relevant responses. The model leverages [LLaMA](./llama) as its text encoder, while [SigLip](./siglip) is used for encoding low-resolution images and [SAM (Segment Anything Model)](./sam) is incorporated to handle high-resolution image encoding, enhancing the model’s ability to process fine-grained visual details. Deepseek-VL-Hybrid is a variant of Deepseek-VL that uses [SAM (Segment Anything Model)](./sam) to handle high-resolution image encoding.
+
+You can find all the original Deepseek-VL-Hybrid checkpoints under the [DeepSeek-community](https://huggingface.co/deepseek-community) organization.
+
+> [!TIP]
+> Click on the Deepseek-VL-Hybrid models in the right sidebar for more examples of how to apply Deepseek-VL-Hybrid to different vision and language tasks.
+
+The example below demonstrates how to generate text based on an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipe = pipeline(
+ task="image-text-to-text",
+ model="deepseek-community/deepseek-vl-7b-chat",
+ device=0,
+ torch_dtype=torch.float16
+)
+
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {
+ "type": "image",
+ "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg",
+ },
+ { "type": "text", "text": "Describe this image."},
+ ]
+ }
+]
+
+pipe(text=messages, max_new_tokens=20, return_full_text=False)
+```
+
+
+
+
+```py
+import torch
+from transformers import DeepseekVLHybridForConditionalGeneration, AutoProcessor
+
+model = DeepseekVLHybridForConditionalGeneration.from_pretrained(
+ "deepseek-community/deepseek-vl-7b-chat",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+
+processor = AutoProcessor.from_pretrained("deepseek-community/deepseek-vl-7b-chat")
+
+messages = [
+ {
+ "role":"user",
+ "content":[
+ {
+ "type":"image",
+ "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+ },
+ {
+ "type":"text",
+ "text":"Describe this image."
+ }
+ ]
+ }
+
+]
+
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+).to(model.device, dtype=model.dtype)
+
+generated_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids_trimmed = [
+ out_ids[len(in_ids) :] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
+]
+output_text = processor.batch_decode(
+ generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
+)
+
+print(output_text)
+```
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [torchao](../quantization/torchao) to only quantize the weights to int4.
+
+```python
+import torch
+from transformers import TorchAoConfig, DeepseekVLHybridForConditionalGeneration, AutoProcessor
+
+quantization_config = TorchAoConfig(
+ "int4_weight_only",
+ group_size=128
+)
+
+model = DeepseekVLHybridForConditionalGeneration.from_pretrained(
+ "deepseek-community/deepseek-vl-7b-chat",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+```
+### Notes
+
+- Do inference with multiple images in a single conversation.
+ ```py
+ import torch
+ from transformers import DeepseekVLHybridForConditionalGeneration, AutoProcessor
+
+ model = DeepseekVLHybridForConditionalGeneration.from_pretrained(
+ "deepseek-community/deepseek-vl-7b-chat",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+ )
+
+ processor = AutoProcessor.from_pretrained("deepseek-community/deepseek-vl-7b-chat")
+
+ messages = [
+ [
+ {
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "What’s the difference between"},
+ {"type": "image", "url": "http://images.cocodataset.org/val2017/000000039769.jpg"},
+ {"type": "text", "text": " and "},
+ {"type": "image", "url": "https://www.ilankelman.org/stopsigns/australia.jpg"}
+ ]
+ }
+ ],
+ [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/snowman.jpg"},
+ {"type": "text", "text": "What do you see in this image?"}
+ ]
+ }
+ ]
+ ]
+
+ inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ padding=True,
+ truncation=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+ ).to(model.device, dtype=model.dtype)
+
+ generated_ids = model.generate(**inputs, max_new_tokens=128)
+ generated_ids_trimmed = [
+ out_ids[len(in_ids) :] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
+ ]
+ output_text = processor.batch_decode(
+ generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
+ )
+
+ print(output_text)
+ ```
+
+## DeepseekVLHybridConfig
+
+[[autodoc]] DeepseekVLHybridConfig
+
+## DeepseekVLHybridProcessor
+
+[[autodoc]] DeepseekVLHybridProcessor
+
+## DeepseekVLHybridImageProcessor
+
+[[autodoc]] DeepseekVLHybridImageProcessor
+
+## DeepseekVLHybridImageProcessorFast
+
+[[autodoc]] DeepseekVLHybridImageProcessorFast
+
+## DeepseekVLHybridModel
+
+[[autodoc]] DeepseekVLHybridModel
+ - forward
+
+## DeepseekVLHybridForConditionalGeneration
+
+[[autodoc]] DeepseekVLHybridForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deformable_detr.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deformable_detr.md
new file mode 100644
index 0000000000000000000000000000000000000000..a8c57f490d4bb54c8d3cf4012ee5382e47253342
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deformable_detr.md
@@ -0,0 +1,126 @@
+
+*This model was released on 2020-10-08 and added to Hugging Face Transformers on 2022-09-14.*
+
+
+
+
+
+
+
+# Deformable DETR
+
+[Deformable DETR](https://huggingface.co/papers/2010.04159) improves on the original [DETR](./detr) by using a deformable attention module. This mechanism selectively attends to a small set of key sampling points around a reference. It improves training speed and improves accuracy.
+
+
+
+ Deformable DETR architecture. Taken from the original paper.
+
+You can find all the available Deformable DETR checkpoints under the [SenseTime](https://huggingface.co/SenseTime) organization.
+
+> [!TIP]
+> This model was contributed by [nielsr](https://huggingface.co/nielsr).
+>
+> Click on the Deformable DETR models in the right sidebar for more examples of how to apply Deformable DETR to different object detection and segmentation tasks.
+
+The example below demonstrates how to perform object detection with the [`Pipeline`] and the [`AutoModel`] class.
+
+
+
+
+```python
+from transformers import pipeline
+import torch
+
+pipeline = pipeline(
+ "object-detection",
+ model="SenseTime/deformable-detr",
+ torch_dtype=torch.float16,
+ device_map=0
+)
+
+pipeline("http://images.cocodataset.org/val2017/000000039769.jpg")
+```
+
+
+
+
+```python
+from transformers import AutoImageProcessor, AutoModelForObjectDetection
+from PIL import Image
+import requests
+import torch
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+image_processor = AutoImageProcessor.from_pretrained("SenseTime/deformable-detr")
+model = AutoModelForObjectDetection.from_pretrained("SenseTime/deformable-detr")
+
+# prepare image for the model
+inputs = image_processor(images=image, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+results = image_processor.post_process_object_detection(outputs, target_sizes=torch.tensor([image.size[::-1]]), threshold=0.3)
+
+for result in results:
+ for score, label_id, box in zip(result["scores"], result["labels"], result["boxes"]):
+ score, label = score.item(), label_id.item()
+ box = [round(i, 2) for i in box.tolist()]
+ print(f"{model.config.id2label[label]}: {score:.2f} {box}")
+```
+
+
+
+
+## Resources
+
+- Refer to this set of [notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Deformable-DETR) for inference and fine-tuning [`DeformableDetrForObjectDetection`] on a custom dataset.
+
+## DeformableDetrImageProcessor
+
+[[autodoc]] DeformableDetrImageProcessor
+ - preprocess
+ - post_process_object_detection
+
+## DeformableDetrImageProcessorFast
+
+[[autodoc]] DeformableDetrImageProcessorFast
+ - preprocess
+ - post_process_object_detection
+
+## DeformableDetrFeatureExtractor
+
+[[autodoc]] DeformableDetrFeatureExtractor
+ - __call__
+ - post_process_object_detection
+
+## DeformableDetrConfig
+
+[[autodoc]] DeformableDetrConfig
+
+## DeformableDetrModel
+
+[[autodoc]] DeformableDetrModel
+ - forward
+
+## DeformableDetrForObjectDetection
+
+[[autodoc]] DeformableDetrForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deit.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deit.md
new file mode 100644
index 0000000000000000000000000000000000000000..7af7514d67cc023b7ffbd863b62fcb82cf6972b2
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deit.md
@@ -0,0 +1,188 @@
+
+*This model was released on 2020-12-23 and added to Hugging Face Transformers on 2021-04-13.*
+
+# DeiT
+
+
+
+
+
+
+
+
+## Overview
+
+The DeiT model was proposed in [Training data-efficient image transformers & distillation through attention](https://huggingface.co/papers/2012.12877) by Hugo Touvron, Matthieu Cord, Matthijs Douze, Francisco Massa, Alexandre
+Sablayrolles, Hervé Jégou. The [Vision Transformer (ViT)](vit) introduced in [Dosovitskiy et al., 2020](https://huggingface.co/papers/2010.11929) has shown that one can match or even outperform existing convolutional neural
+networks using a Transformer encoder (BERT-like). However, the ViT models introduced in that paper required training on
+expensive infrastructure for multiple weeks, using external data. DeiT (data-efficient image transformers) are more
+efficiently trained transformers for image classification, requiring far less data and far less computing resources
+compared to the original ViT models.
+
+The abstract from the paper is the following:
+
+*Recently, neural networks purely based on attention were shown to address image understanding tasks such as image
+classification. However, these visual transformers are pre-trained with hundreds of millions of images using an
+expensive infrastructure, thereby limiting their adoption. In this work, we produce a competitive convolution-free
+transformer by training on Imagenet only. We train them on a single computer in less than 3 days. Our reference vision
+transformer (86M parameters) achieves top-1 accuracy of 83.1% (single-crop evaluation) on ImageNet with no external
+data. More importantly, we introduce a teacher-student strategy specific to transformers. It relies on a distillation
+token ensuring that the student learns from the teacher through attention. We show the interest of this token-based
+distillation, especially when using a convnet as a teacher. This leads us to report results competitive with convnets
+for both Imagenet (where we obtain up to 85.2% accuracy) and when transferring to other tasks. We share our code and
+models.*
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The TensorFlow version of this model was added by [amyeroberts](https://huggingface.co/amyeroberts).
+
+## Usage tips
+
+- Compared to ViT, DeiT models use a so-called distillation token to effectively learn from a teacher (which, in the
+ DeiT paper, is a ResNet like-model). The distillation token is learned through backpropagation, by interacting with
+ the class ([CLS]) and patch tokens through the self-attention layers.
+- There are 2 ways to fine-tune distilled models, either (1) in a classic way, by only placing a prediction head on top
+ of the final hidden state of the class token and not using the distillation signal, or (2) by placing both a
+ prediction head on top of the class token and on top of the distillation token. In that case, the [CLS] prediction
+ head is trained using regular cross-entropy between the prediction of the head and the ground-truth label, while the
+ distillation prediction head is trained using hard distillation (cross-entropy between the prediction of the
+ distillation head and the label predicted by the teacher). At inference time, one takes the average prediction
+ between both heads as final prediction. (2) is also called "fine-tuning with distillation", because one relies on a
+ teacher that has already been fine-tuned on the downstream dataset. In terms of models, (1) corresponds to
+ [`DeiTForImageClassification`] and (2) corresponds to
+ [`DeiTForImageClassificationWithTeacher`].
+- Note that the authors also did try soft distillation for (2) (in which case the distillation prediction head is
+ trained using KL divergence to match the softmax output of the teacher), but hard distillation gave the best results.
+- All released checkpoints were pre-trained and fine-tuned on ImageNet-1k only. No external data was used. This is in
+ contrast with the original ViT model, which used external data like the JFT-300M dataset/Imagenet-21k for
+ pre-training.
+- The authors of DeiT also released more efficiently trained ViT models, which you can directly plug into
+ [`ViTModel`] or [`ViTForImageClassification`]. Techniques like data
+ augmentation, optimization, and regularization were used in order to simulate training on a much larger dataset
+ (while only using ImageNet-1k for pre-training). There are 4 variants available (in 3 different sizes):
+ *facebook/deit-tiny-patch16-224*, *facebook/deit-small-patch16-224*, *facebook/deit-base-patch16-224* and
+ *facebook/deit-base-patch16-384*. Note that one should use [`DeiTImageProcessor`] in order to
+ prepare images for the model.
+
+### Using Scaled Dot Product Attention (SDPA)
+
+PyTorch includes a native scaled dot-product attention (SDPA) operator as part of `torch.nn.functional`. This function
+encompasses several implementations that can be applied depending on the inputs and the hardware in use. See the
+[official documentation](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)
+or the [GPU Inference](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)
+page for more information.
+
+SDPA is used by default for `torch>=2.1.1` when an implementation is available, but you may also set
+`attn_implementation="sdpa"` in `from_pretrained()` to explicitly request SDPA to be used.
+
+```
+from transformers import DeiTForImageClassification
+model = DeiTForImageClassification.from_pretrained("facebook/deit-base-distilled-patch16-224", attn_implementation="sdpa", torch_dtype=torch.float16)
+...
+```
+
+For the best speedups, we recommend loading the model in half-precision (e.g. `torch.float16` or `torch.bfloat16`).
+
+On a local benchmark (A100-40GB, PyTorch 2.3.0, OS Ubuntu 22.04) with `float32` and `facebook/deit-base-distilled-patch16-224` model, we saw the following speedups during inference.
+
+| Batch size | Average inference time (ms), eager mode | Average inference time (ms), sdpa model | Speed up, Sdpa / Eager (x) |
+|--------------|-------------------------------------------|-------------------------------------------|------------------------------|
+| 1 | 8 | 6 | 1.33 |
+| 2 | 9 | 6 | 1.5 |
+| 4 | 9 | 6 | 1.5 |
+| 8 | 8 | 6 | 1.33 |
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with DeiT.
+
+
+
+- [`DeiTForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+Besides that:
+
+- [`DeiTForMaskedImageModeling`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-pretraining).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## DeiTConfig
+
+[[autodoc]] DeiTConfig
+
+## DeiTFeatureExtractor
+
+[[autodoc]] DeiTFeatureExtractor
+ - __call__
+
+## DeiTImageProcessor
+
+[[autodoc]] DeiTImageProcessor
+ - preprocess
+
+## DeiTImageProcessorFast
+
+[[autodoc]] DeiTImageProcessorFast
+ - preprocess
+
+
+
+
+## DeiTModel
+
+[[autodoc]] DeiTModel
+ - forward
+
+## DeiTForMaskedImageModeling
+
+[[autodoc]] DeiTForMaskedImageModeling
+ - forward
+
+## DeiTForImageClassification
+
+[[autodoc]] DeiTForImageClassification
+ - forward
+
+## DeiTForImageClassificationWithTeacher
+
+[[autodoc]] DeiTForImageClassificationWithTeacher
+ - forward
+
+
+
+
+## TFDeiTModel
+
+[[autodoc]] TFDeiTModel
+ - call
+
+## TFDeiTForMaskedImageModeling
+
+[[autodoc]] TFDeiTForMaskedImageModeling
+ - call
+
+## TFDeiTForImageClassification
+
+[[autodoc]] TFDeiTForImageClassification
+ - call
+
+## TFDeiTForImageClassificationWithTeacher
+
+[[autodoc]] TFDeiTForImageClassificationWithTeacher
+ - call
+
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deplot.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deplot.md
new file mode 100644
index 0000000000000000000000000000000000000000..651ddcef7fe9734f5eb0f529ab57e02c6ff8bb10
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deplot.md
@@ -0,0 +1,71 @@
+
+*This model was released on 2022-12-20 and added to Hugging Face Transformers on 2023-06-20.*
+
+# DePlot
+
+
+
+
+
+## Overview
+
+DePlot was proposed in the paper [DePlot: One-shot visual language reasoning by plot-to-table translation](https://huggingface.co/papers/2212.10505) from Fangyu Liu, Julian Martin Eisenschlos, Francesco Piccinno, Syrine Krichene, Chenxi Pang, Kenton Lee, Mandar Joshi, Wenhu Chen, Nigel Collier, Yasemin Altun.
+
+The abstract of the paper states the following:
+
+*Visual language such as charts and plots is ubiquitous in the human world. Comprehending plots and charts requires strong reasoning skills. Prior state-of-the-art (SOTA) models require at least tens of thousands of training examples and their reasoning capabilities are still much limited, especially on complex human-written queries. This paper presents the first one-shot solution to visual language reasoning. We decompose the challenge of visual language reasoning into two steps: (1) plot-to-text translation, and (2) reasoning over the translated text. The key in this method is a modality conversion module, named as DePlot, which translates the image of a plot or chart to a linearized table. The output of DePlot can then be directly used to prompt a pretrained large language model (LLM), exploiting the few-shot reasoning capabilities of LLMs. To obtain DePlot, we standardize the plot-to-table task by establishing unified task formats and metrics, and train DePlot end-to-end on this task. DePlot can then be used off-the-shelf together with LLMs in a plug-and-play fashion. Compared with a SOTA model finetuned on more than >28k data points, DePlot+LLM with just one-shot prompting achieves a 24.0% improvement over finetuned SOTA on human-written queries from the task of chart QA.*
+
+DePlot is a model that is trained using `Pix2Struct` architecture. You can find more information about `Pix2Struct` in the [Pix2Struct documentation](https://huggingface.co/docs/transformers/main/en/model_doc/pix2struct).
+DePlot is a Visual Question Answering subset of `Pix2Struct` architecture. It renders the input question on the image and predicts the answer.
+
+## Usage example
+
+Currently one checkpoint is available for DePlot:
+
+- `google/deplot`: DePlot fine-tuned on ChartQA dataset
+
+
+```python
+from transformers import AutoProcessor, Pix2StructForConditionalGeneration
+import requests
+from PIL import Image
+
+model = Pix2StructForConditionalGeneration.from_pretrained("google/deplot")
+processor = AutoProcessor.from_pretrained("google/deplot")
+url = "https://raw.githubusercontent.com/vis-nlp/ChartQA/main/ChartQA%20Dataset/val/png/5090.png"
+image = Image.open(requests.get(url, stream=True).raw)
+
+inputs = processor(images=image, text="Generate underlying data table of the figure below:", return_tensors="pt")
+predictions = model.generate(**inputs, max_new_tokens=512)
+print(processor.decode(predictions[0], skip_special_tokens=True))
+```
+
+## Fine-tuning
+
+To fine-tune DePlot, refer to the pix2struct [fine-tuning notebook](https://github.com/huggingface/notebooks/blob/main/examples/image_captioning_pix2struct.ipynb). For `Pix2Struct` models, we have found out that fine-tuning the model with Adafactor and cosine learning rate scheduler leads to faster convergence:
+```python
+from transformers.optimization import Adafactor, get_cosine_schedule_with_warmup
+
+optimizer = Adafactor(self.parameters(), scale_parameter=False, relative_step=False, lr=0.01, weight_decay=1e-05)
+scheduler = get_cosine_schedule_with_warmup(optimizer, num_warmup_steps=1000, num_training_steps=40000)
+```
+
+
+
+DePlot is a model trained using `Pix2Struct` architecture. For API reference, see [`Pix2Struct` documentation](pix2struct).
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/depth_anything.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/depth_anything.md
new file mode 100644
index 0000000000000000000000000000000000000000..cf3c96d4ee1e1ad5b841df991cb0abe8bb367b50
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/depth_anything.md
@@ -0,0 +1,89 @@
+
+*This model was released on 2024-01-19 and added to Hugging Face Transformers on 2024-01-25.*
+
+
+
+
+
+
+
+# Depth Anything
+
+[Depth Anything](https://huggingface.co/papers/2401.10891) is designed to be a foundation model for monocular depth estimation (MDE). It is jointly trained on labeled and ~62M unlabeled images to enhance the dataset. It uses a pretrained [DINOv2](./dinov2) model as an image encoder to inherit its existing rich semantic priors, and [DPT](./dpt) as the decoder. A teacher model is trained on unlabeled images to create pseudo-labels. The student model is trained on a combination of the pseudo-labels and labeled images. To improve the student model's performance, strong perturbations are added to the unlabeled images to challenge the student model to learn more visual knowledge from the image.
+
+You can find all the original Depth Anything checkpoints under the [Depth Anything](https://huggingface.co/collections/LiheYoung/depth-anything-release-65b317de04eec72abf6b55aa) collection.
+
+> [!TIP]
+> Click on the Depth Anything models in the right sidebar for more examples of how to apply Depth Anything to different vision tasks.
+
+The example below demonstrates how to obtain a depth map with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipe = pipeline(task="depth-estimation", model="LiheYoung/depth-anything-base-hf", torch_dtype=torch.bfloat16, device=0)
+pipe("http://images.cocodataset.org/val2017/000000039769.jpg")["depth"]
+```
+
+
+
+
+```py
+import torch
+import requests
+import numpy as np
+from PIL import Image
+from transformers import AutoImageProcessor, AutoModelForDepthEstimation
+
+image_processor = AutoImageProcessor.from_pretrained("LiheYoung/depth-anything-base-hf")
+model = AutoModelForDepthEstimation.from_pretrained("LiheYoung/depth-anything-base-hf", torch_dtype=torch.bfloat16)
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+inputs = image_processor(images=image, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+post_processed_output = image_processor.post_process_depth_estimation(
+ outputs,
+ target_sizes=[(image.height, image.width)],
+)
+predicted_depth = post_processed_output[0]["predicted_depth"]
+depth = (predicted_depth - predicted_depth.min()) / (predicted_depth.max() - predicted_depth.min())
+depth = depth.detach().cpu().numpy() * 255
+Image.fromarray(depth.astype("uint8"))
+```
+
+
+
+
+## Notes
+
+- [DepthAnythingV2](./depth_anything_v2), released in June 2024, uses the same architecture as Depth Anything and is compatible with all code examples and existing workflows. It uses synthetic data and a larger capacity teacher model to achieve much finer and robust depth predictions.
+
+## DepthAnythingConfig
+
+[[autodoc]] DepthAnythingConfig
+
+## DepthAnythingForDepthEstimation
+
+[[autodoc]] DepthAnythingForDepthEstimation
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/depth_anything_v2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/depth_anything_v2.md
new file mode 100644
index 0000000000000000000000000000000000000000..e8637ba6192cc9fee6115dbdecb349ce47ea9b10
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/depth_anything_v2.md
@@ -0,0 +1,113 @@
+
+*This model was released on 2024-06-13 and added to Hugging Face Transformers on 2024-07-05.*
+
+# Depth Anything V2
+
+## Overview
+
+Depth Anything V2 was introduced in [the paper of the same name](https://huggingface.co/papers/2406.09414) by Lihe Yang et al. It uses the same architecture as the original [Depth Anything model](depth_anything), but uses synthetic data and a larger capacity teacher model to achieve much finer and robust depth predictions.
+
+The abstract from the paper is the following:
+
+*This work presents Depth Anything V2. Without pursuing fancy techniques, we aim to reveal crucial findings to pave the way towards building a powerful monocular depth estimation model. Notably, compared with V1, this version produces much finer and more robust depth predictions through three key practices: 1) replacing all labeled real images with synthetic images, 2) scaling up the capacity of our teacher model, and 3) teaching student models via the bridge of large-scale pseudo-labeled real images. Compared with the latest models built on Stable Diffusion, our models are significantly more efficient (more than 10x faster) and more accurate. We offer models of different scales (ranging from 25M to 1.3B params) to support extensive scenarios. Benefiting from their strong generalization capability, we fine-tune them with metric depth labels to obtain our metric depth models. In addition to our models, considering the limited diversity and frequent noise in current test sets, we construct a versatile evaluation benchmark with precise annotations and diverse scenes to facilitate future research.*
+
+
+
+ Depth Anything overview. Taken from the original paper.
+
+The Depth Anything models were contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/DepthAnything/Depth-Anything-V2).
+
+## Usage example
+
+There are 2 main ways to use Depth Anything V2: either using the pipeline API, which abstracts away all the complexity for you, or by using the `DepthAnythingForDepthEstimation` class yourself.
+
+### Pipeline API
+
+The pipeline allows to use the model in a few lines of code:
+
+```python
+>>> from transformers import pipeline
+>>> from PIL import Image
+>>> import requests
+
+>>> # load pipe
+>>> pipe = pipeline(task="depth-estimation", model="depth-anything/Depth-Anything-V2-Small-hf")
+
+>>> # load image
+>>> url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> # inference
+>>> depth = pipe(image)["depth"]
+```
+
+### Using the model yourself
+
+If you want to do the pre- and post-processing yourself, here's how to do that:
+
+```python
+>>> from transformers import AutoImageProcessor, AutoModelForDepthEstimation
+>>> import torch
+>>> import numpy as np
+>>> from PIL import Image
+>>> import requests
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> image_processor = AutoImageProcessor.from_pretrained("depth-anything/Depth-Anything-V2-Small-hf")
+>>> model = AutoModelForDepthEstimation.from_pretrained("depth-anything/Depth-Anything-V2-Small-hf")
+
+>>> # prepare image for the model
+>>> inputs = image_processor(images=image, return_tensors="pt")
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> # interpolate to original size and visualize the prediction
+>>> post_processed_output = image_processor.post_process_depth_estimation(
+... outputs,
+... target_sizes=[(image.height, image.width)],
+... )
+
+>>> predicted_depth = post_processed_output[0]["predicted_depth"]
+>>> depth = (predicted_depth - predicted_depth.min()) / (predicted_depth.max() - predicted_depth.min())
+>>> depth = depth.detach().cpu().numpy() * 255
+>>> depth = Image.fromarray(depth.astype("uint8"))
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Depth Anything.
+
+- [Monocular depth estimation task guide](../tasks/monocular_depth_estimation)
+- [Depth Anything V2 demo](https://huggingface.co/spaces/depth-anything/Depth-Anything-V2).
+- A notebook showcasing inference with [`DepthAnythingForDepthEstimation`] can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/Depth%20Anything/Predicting_depth_in_an_image_with_Depth_Anything.ipynb). 🌎
+- [Core ML conversion of the `small` variant for use on Apple Silicon](https://huggingface.co/apple/coreml-depth-anything-v2-small).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## DepthAnythingConfig
+
+[[autodoc]] DepthAnythingConfig
+
+## DepthAnythingForDepthEstimation
+
+[[autodoc]] DepthAnythingForDepthEstimation
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/depth_pro.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/depth_pro.md
new file mode 100644
index 0000000000000000000000000000000000000000..db0d27d1d308577852a9e02a93b939ce6d13719e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/depth_pro.md
@@ -0,0 +1,188 @@
+
+*This model was released on 2024-10-02 and added to Hugging Face Transformers on 2025-02-10.*
+
+# DepthPro
+
+
+
+
+
+## Overview
+
+The DepthPro model was proposed in [Depth Pro: Sharp Monocular Metric Depth in Less Than a Second](https://huggingface.co/papers/2410.02073) by Aleksei Bochkovskii, Amaël Delaunoy, Hugo Germain, Marcel Santos, Yichao Zhou, Stephan R. Richter, Vladlen Koltun.
+
+DepthPro is a foundation model for zero-shot metric monocular depth estimation, designed to generate high-resolution depth maps with remarkable sharpness and fine-grained details. It employs a multi-scale Vision Transformer (ViT)-based architecture, where images are downsampled, divided into patches, and processed using a shared Dinov2 encoder. The extracted patch-level features are merged, upsampled, and refined using a DPT-like fusion stage, enabling precise depth estimation.
+
+The abstract from the paper is the following:
+
+*We present a foundation model for zero-shot metric monocular depth estimation. Our model, Depth Pro, synthesizes high-resolution depth maps with unparalleled sharpness and high-frequency details. The predictions are metric, with absolute scale, without relying on the availability of metadata such as camera intrinsics. And the model is fast, producing a 2.25-megapixel depth map in 0.3 seconds on a standard GPU. These characteristics are enabled by a number of technical contributions, including an efficient multi-scale vision transformer for dense prediction, a training protocol that combines real and synthetic datasets to achieve high metric accuracy alongside fine boundary tracing, dedicated evaluation metrics for boundary accuracy in estimated depth maps, and state-of-the-art focal length estimation from a single image. Extensive experiments analyze specific design choices and demonstrate that Depth Pro outperforms prior work along multiple dimensions.*
+
+
+
+ DepthPro Outputs. Taken from the official code.
+
+This model was contributed by [geetu040](https://github.com/geetu040). The original code can be found [here](https://github.com/apple/ml-depth-pro).
+
+## Usage Tips
+
+The DepthPro model processes an input image by first downsampling it at multiple scales and splitting each scaled version into patches. These patches are then encoded using a shared Vision Transformer (ViT)-based Dinov2 patch encoder, while the full image is processed by a separate image encoder. The extracted patch features are merged into feature maps, upsampled, and fused using a DPT-like decoder to generate the final depth estimation. If enabled, an additional Field of View (FOV) encoder processes the image for estimating the camera's field of view, aiding in depth accuracy.
+
+```py
+>>> import requests
+>>> from PIL import Image
+>>> import torch
+>>> from transformers import DepthProImageProcessorFast, DepthProForDepthEstimation, infer_device
+
+>>> device = infer_device()
+
+>>> url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> image_processor = DepthProImageProcessorFast.from_pretrained("apple/DepthPro-hf")
+>>> model = DepthProForDepthEstimation.from_pretrained("apple/DepthPro-hf").to(device)
+
+>>> inputs = image_processor(images=image, return_tensors="pt").to(model.device)
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> post_processed_output = image_processor.post_process_depth_estimation(
+... outputs, target_sizes=[(image.height, image.width)],
+... )
+
+>>> field_of_view = post_processed_output[0]["field_of_view"]
+>>> focal_length = post_processed_output[0]["focal_length"]
+>>> depth = post_processed_output[0]["predicted_depth"]
+>>> depth = (depth - depth.min()) / depth.max()
+>>> depth = depth * 255.
+>>> depth = depth.detach().cpu().numpy()
+>>> depth = Image.fromarray(depth.astype("uint8"))
+```
+
+### Architecture and Configuration
+
+
+
+ DepthPro architecture. Taken from the original paper.
+
+The `DepthProForDepthEstimation` model uses a `DepthProEncoder`, for encoding the input image and a `FeatureFusionStage` for fusing the output features from encoder.
+
+The `DepthProEncoder` further uses two encoders:
+- `patch_encoder`
+ - Input image is scaled with multiple ratios, as specified in the `scaled_images_ratios` configuration.
+ - Each scaled image is split into smaller **patches** of size `patch_size` with overlapping areas determined by `scaled_images_overlap_ratios`.
+ - These patches are processed by the **`patch_encoder`**
+- `image_encoder`
+ - Input image is also rescaled to `patch_size` and processed by the **`image_encoder`**
+
+Both these encoders can be configured via `patch_model_config` and `image_model_config` respectively, both of which are separate `Dinov2Model` by default.
+
+Outputs from both encoders (`last_hidden_state`) and selected intermediate states (`hidden_states`) from **`patch_encoder`** are fused by a `DPT`-based `FeatureFusionStage` for depth estimation.
+
+### Field-of-View (FOV) Prediction
+
+The network is supplemented with a focal length estimation head. A small convolutional head ingests frozen features from the depth estimation network and task-specific features from a separate ViT image encoder to predict the horizontal angular field-of-view.
+
+The `use_fov_model` parameter in `DepthProConfig` controls whether **FOV prediction** is enabled. By default, it is set to `False` to conserve memory and computation. When enabled, the **FOV encoder** is instantiated based on the `fov_model_config` parameter, which defaults to a `Dinov2Model`. The `use_fov_model` parameter can also be passed when initializing the `DepthProForDepthEstimation` model.
+
+The pretrained model at checkpoint `apple/DepthPro-hf` uses the FOV encoder. To use the pretrained-model without FOV encoder, set `use_fov_model=False` when loading the model, which saves computation.
+```py
+>>> from transformers import DepthProForDepthEstimation
+>>> model = DepthProForDepthEstimation.from_pretrained("apple/DepthPro-hf", use_fov_model=False)
+```
+
+To instantiate a new model with FOV encoder, set `use_fov_model=True` in the config.
+```py
+>>> from transformers import DepthProConfig, DepthProForDepthEstimation
+>>> config = DepthProConfig(use_fov_model=True)
+>>> model = DepthProForDepthEstimation(config)
+```
+
+Or set `use_fov_model=True` when initializing the model, which overrides the value in config.
+```py
+>>> from transformers import DepthProConfig, DepthProForDepthEstimation
+>>> config = DepthProConfig()
+>>> model = DepthProForDepthEstimation(config, use_fov_model=True)
+```
+
+### Using Scaled Dot Product Attention (SDPA)
+
+PyTorch includes a native scaled dot-product attention (SDPA) operator as part of `torch.nn.functional`. This function
+encompasses several implementations that can be applied depending on the inputs and the hardware in use. See the
+[official documentation](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)
+or the [GPU Inference](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)
+page for more information.
+
+SDPA is used by default for `torch>=2.1.1` when an implementation is available, but you may also set
+`attn_implementation="sdpa"` in `from_pretrained()` to explicitly request SDPA to be used.
+
+```py
+from transformers import DepthProForDepthEstimation
+model = DepthProForDepthEstimation.from_pretrained("apple/DepthPro-hf", attn_implementation="sdpa", torch_dtype=torch.float16)
+```
+
+For the best speedups, we recommend loading the model in half-precision (e.g. `torch.float16` or `torch.bfloat16`).
+
+On a local benchmark (A100-40GB, PyTorch 2.3.0, OS Ubuntu 22.04) with `float32` and `google/vit-base-patch16-224` model, we saw the following speedups during inference.
+
+| Batch size | Average inference time (ms), eager mode | Average inference time (ms), sdpa model | Speed up, Sdpa / Eager (x) |
+|--------------|-------------------------------------------|-------------------------------------------|------------------------------|
+| 1 | 7 | 6 | 1.17 |
+| 2 | 8 | 6 | 1.33 |
+| 4 | 8 | 6 | 1.33 |
+| 8 | 8 | 6 | 1.33 |
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with DepthPro:
+
+- Research Paper: [Depth Pro: Sharp Monocular Metric Depth in Less Than a Second](https://huggingface.co/papers/2410.02073)
+- Official Implementation: [apple/ml-depth-pro](https://github.com/apple/ml-depth-pro)
+- DepthPro Inference Notebook: [DepthPro Inference](https://github.com/qubvel/transformers-notebooks/blob/main/notebooks/DepthPro_inference.ipynb)
+- DepthPro for Super Resolution and Image Segmentation
+ - Read blog on Medium: [Depth Pro: Beyond Depth](https://medium.com/@raoarmaghanshakir040/depth-pro-beyond-depth-9d822fc557ba)
+ - Code on Github: [geetu040/depthpro-beyond-depth](https://github.com/geetu040/depthpro-beyond-depth)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## DepthProConfig
+
+[[autodoc]] DepthProConfig
+
+## DepthProImageProcessor
+
+[[autodoc]] DepthProImageProcessor
+ - preprocess
+ - post_process_depth_estimation
+
+## DepthProImageProcessorFast
+
+[[autodoc]] DepthProImageProcessorFast
+ - preprocess
+ - post_process_depth_estimation
+
+## DepthProModel
+
+[[autodoc]] DepthProModel
+ - forward
+
+## DepthProForDepthEstimation
+
+[[autodoc]] DepthProForDepthEstimation
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deta.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deta.md
new file mode 100644
index 0000000000000000000000000000000000000000..0dda1c891791dabb4f9ab0323686298d351db387
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deta.md
@@ -0,0 +1,78 @@
+
+*This model was released on 2022-12-12 and added to Hugging Face Transformers on 2023-06-20.*
+
+# DETA
+
+
+
+
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The DETA model was proposed in [NMS Strikes Back](https://huggingface.co/papers/2212.06137) by Jeffrey Ouyang-Zhang, Jang Hyun Cho, Xingyi Zhou, Philipp Krähenbühl.
+DETA (short for Detection Transformers with Assignment) improves [Deformable DETR](deformable_detr) by replacing the one-to-one bipartite Hungarian matching loss
+with one-to-many label assignments used in traditional detectors with non-maximum suppression (NMS). This leads to significant gains of up to 2.5 mAP.
+
+The abstract from the paper is the following:
+
+*Detection Transformer (DETR) directly transforms queries to unique objects by using one-to-one bipartite matching during training and enables end-to-end object detection. Recently, these models have surpassed traditional detectors on COCO with undeniable elegance. However, they differ from traditional detectors in multiple designs, including model architecture and training schedules, and thus the effectiveness of one-to-one matching is not fully understood. In this work, we conduct a strict comparison between the one-to-one Hungarian matching in DETRs and the one-to-many label assignments in traditional detectors with non-maximum supervision (NMS). Surprisingly, we observe one-to-many assignments with NMS consistently outperform standard one-to-one matching under the same setting, with a significant gain of up to 2.5 mAP. Our detector that trains Deformable-DETR with traditional IoU-based label assignment achieved 50.2 COCO mAP within 12 epochs (1x schedule) with ResNet50 backbone, outperforming all existing traditional or transformer-based detectors in this setting. On multiple datasets, schedules, and architectures, we consistently show bipartite matching is unnecessary for performant detection transformers. Furthermore, we attribute the success of detection transformers to their expressive transformer architecture.*
+
+
+
+ DETA overview. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/jozhang97/DETA).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with DETA.
+
+- Demo notebooks for DETA can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/DETA).
+- Scripts for finetuning [`DetaForObjectDetection`] with [`Trainer`] or [Accelerate](https://huggingface.co/docs/accelerate/index) can be found [here](https://github.com/huggingface/transformers/tree/main/examples/pytorch/object-detection).
+- See also: [Object detection task guide](../tasks/object_detection).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## DetaConfig
+
+[[autodoc]] DetaConfig
+
+## DetaImageProcessor
+
+[[autodoc]] DetaImageProcessor
+ - preprocess
+ - post_process_object_detection
+
+## DetaModel
+
+[[autodoc]] DetaModel
+ - forward
+
+## DetaForObjectDetection
+
+[[autodoc]] DetaForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/detr.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/detr.md
new file mode 100644
index 0000000000000000000000000000000000000000..86c42c8adf584ac6f220cb8f7aa24712868200dd
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/detr.md
@@ -0,0 +1,206 @@
+
+*This model was released on 2020-05-26 and added to Hugging Face Transformers on 2021-06-09.*
+
+
+
+
+
+
+
+# DETR
+
+[DETR](https://huggingface.co/papers/2005.12872) consists of a convolutional backbone followed by an encoder-decoder Transformer which can be trained end-to-end for object detection. It greatly simplifies a lot of the complexity of models like Faster-R-CNN and Mask-R-CNN, which use things like region proposals, non-maximum suppression procedure and anchor generation. Moreover, DETR can also be naturally extended to perform panoptic segmentation, by simply adding a mask head on top of the decoder outputs.
+
+You can find all the original DETR checkpoints under the [AI at Meta](https://huggingface.co/facebook/models?search=detr) organization.
+
+> [!TIP]
+> This model was contributed by [nielsr](https://huggingface.co/nielsr).
+>
+> Click on the DETR models in the right sidebar for more examples of how to apply DETR to different object detection and segmentation tasks.
+
+The example below demonstrates how to perform object detection with the [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```python
+from transformers import pipeline
+import torch
+
+pipeline = pipeline(
+ "object-detection",
+ model="facebook/detr-resnet-50",
+ torch_dtype=torch.float16,
+ device_map=0
+)
+
+pipeline("http://images.cocodataset.org/val2017/000000039769.jpg")
+```
+
+
+
+
+```python
+from transformers import AutoImageProcessor, AutoModelForObjectDetection
+from PIL import Image
+import requests
+import torch
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+image_processor = AutoImageProcessor.from_pretrained("facebook/detr-resnet-50")
+model = AutoModelForObjectDetection.from_pretrained("facebook/detr-resnet-50")
+
+# prepare image for the model
+inputs = image_processor(images=image, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+results = image_processor.post_process_object_detection(outputs, target_sizes=torch.tensor([image.size[::-1]]), threshold=0.3)
+
+for result in results:
+ for score, label_id, box in zip(result["scores"], result["labels"], result["boxes"]):
+ score, label = score.item(), label_id.item()
+ box = [round(i, 2) for i in box.tolist()]
+ print(f"{model.config.id2label[label]}: {score:.2f} {box}")
+```
+
+
+
+
+
+How DETR works
+
+Here's a TLDR explaining how [`~transformers.DetrForObjectDetection`] works:
+
+First, an image is sent through a pre-trained convolutional backbone (in the paper, the authors use ResNet-50/ResNet-101). Let's assume we also add a batch dimension. This means that the input to the backbone is a tensor of shape `(batch_size, 3, height, width)`, assuming the image has 3 color channels (RGB). The CNN backbone outputs a new lower-resolution feature map, typically of shape `(batch_size, 2048, height/32, width/32)`. This is then projected to match the hidden dimension of the Transformer of DETR, which is `256` by default, using a `nn.Conv2D` layer. So now, we have a tensor of shape `(batch_size, 256, height/32, width/32).` Next, the feature map is flattened and transposed to obtain a tensor of shape `(batch_size, seq_len, d_model)` = `(batch_size, width/32*height/32, 256)`. So a difference with NLP models is that the sequence length is actually longer than usual, but with a smaller `d_model` (which in NLP is typically 768 or higher).
+
+Next, this is sent through the encoder, outputting `encoder_hidden_states` of the same shape (you can consider these as image features). Next, so-called **object queries** are sent through the decoder. This is a tensor of shape `(batch_size, num_queries, d_model)`, with `num_queries` typically set to 100 and initialized with zeros. These input embeddings are learnt positional encodings that the authors refer to as object queries, and similarly to the encoder, they are added to the input of each attention layer. Each object query will look for a particular object in the image. The decoder updates these embeddings through multiple self-attention and encoder-decoder attention layers to output `decoder_hidden_states` of the same shape: `(batch_size, num_queries, d_model)`. Next, two heads are added on top for object detection: a linear layer for classifying each object query into one of the objects or "no object", and a MLP to predict bounding boxes for each query.
+
+The model is trained using a **bipartite matching loss**: so what we actually do is compare the predicted classes + bounding boxes of each of the N = 100 object queries to the ground truth annotations, padded up to the same length N (so if an image only contains 4 objects, 96 annotations will just have a "no object" as class and "no bounding box" as bounding box). The [Hungarian matching algorithm](https://en.wikipedia.org/wiki/Hungarian_algorithm) is used to find an optimal one-to-one mapping of each of the N queries to each of the N annotations. Next, standard cross-entropy (for the classes) and a linear combination of the L1 and [generalized IoU loss](https://giou.stanford.edu/) (for the bounding boxes) are used to optimize the parameters of the model.
+
+DETR can be naturally extended to perform panoptic segmentation (which unifies semantic segmentation and instance segmentation). [`~transformers.DetrForSegmentation`] adds a segmentation mask head on top of [`~transformers.DetrForObjectDetection`]. The mask head can be trained either jointly, or in a two steps process, where one first trains a [`~transformers.DetrForObjectDetection`] model to detect bounding boxes around both "things" (instances) and "stuff" (background things like trees, roads, sky), then freeze all the weights and train only the mask head for 25 epochs. Experimentally, these two approaches give similar results. Note that predicting boxes is required for the training to be possible, since the Hungarian matching is computed using distances between boxes.
+
+
+
+## Notes
+
+- DETR uses so-called **object queries** to detect objects in an image. The number of queries determines the maximum number of objects that can be detected in a single image, and is set to 100 by default (see parameter `num_queries` of [`~transformers.DetrConfig`]). Note that it's good to have some slack (in COCO, the authors used 100, while the maximum number of objects in a COCO image is ~70).
+- The decoder of DETR updates the query embeddings in parallel. This is different from language models like GPT-2, which use autoregressive decoding instead of parallel. Hence, no causal attention mask is used.
+- DETR adds position embeddings to the hidden states at each self-attention and cross-attention layer before projecting to queries and keys. For the position embeddings of the image, one can choose between fixed sinusoidal or learned absolute position embeddings. By default, the parameter `position_embedding_type` of [`~transformers.DetrConfig`] is set to `"sine"`.
+- During training, the authors of DETR did find it helpful to use auxiliary losses in the decoder, especially to help the model output the correct number of objects of each class. If you set the parameter `auxiliary_loss` of [`~transformers.DetrConfig`] to `True`, then prediction feedforward neural networks and Hungarian losses are added after each decoder layer (with the FFNs sharing parameters).
+- If you want to train the model in a distributed environment across multiple nodes, then one should update the _num_boxes_ variable in the _DetrLoss_ class of _modeling_detr.py_. When training on multiple nodes, this should be set to the average number of target boxes across all nodes, as can be seen in the original implementation [here](https://github.com/facebookresearch/detr/blob/a54b77800eb8e64e3ad0d8237789fcbf2f8350c5/models/detr.py#L227-L232).
+- [`~transformers.DetrForObjectDetection`] and [`~transformers.DetrForSegmentation`] can be initialized with any convolutional backbone available in the [timm library](https://github.com/rwightman/pytorch-image-models). Initializing with a MobileNet backbone for example can be done by setting the `backbone` attribute of [`~transformers.DetrConfig`] to `"tf_mobilenetv3_small_075"`, and then initializing the model with that config.
+- DETR resizes the input images such that the shortest side is at least a certain amount of pixels while the longest is at most 1333 pixels. At training time, scale augmentation is used such that the shortest side is randomly set to at least 480 and at most 800 pixels. At inference time, the shortest side is set to 800. One can use [`~transformers.DetrImageProcessor`] to prepare images (and optional annotations in COCO format) for the model. Due to this resizing, images in a batch can have different sizes. DETR solves this by padding images up to the largest size in a batch, and by creating a pixel mask that indicates which pixels are real/which are padding. Alternatively, one can also define a custom `collate_fn` in order to batch images together, using [`~transformers.DetrImageProcessor.pad_and_create_pixel_mask`].
+- The size of the images will determine the amount of memory being used, and will thus determine the `batch_size`. It is advised to use a batch size of 2 per GPU. See [this Github thread](https://github.com/facebookresearch/detr/issues/150) for more info.
+
+There are three other ways to instantiate a DETR model (depending on what you prefer):
+
+- Option 1: Instantiate DETR with pre-trained weights for entire model
+```python
+from transformers import DetrForObjectDetection
+
+model = DetrForObjectDetection.from_pretrained("facebook/detr-resnet-50")
+```
+
+- Option 2: Instantiate DETR with randomly initialized weights for Transformer, but pre-trained weights for backbone
+```python
+from transformers import DetrConfig, DetrForObjectDetection
+
+config = DetrConfig()
+model = DetrForObjectDetection(config)
+```
+
+- Option 3: Instantiate DETR with randomly initialized weights for backbone + Transformer
+```python
+config = DetrConfig(use_pretrained_backbone=False)
+model = DetrForObjectDetection(config)
+```
+
+As a summary, consider the following table:
+
+| Task | Object detection | Instance segmentation | Panoptic segmentation |
+|------|------------------|-----------------------|-----------------------|
+| **Description** | Predicting bounding boxes and class labels around objects in an image | Predicting masks around objects (i.e. instances) in an image | Predicting masks around both objects (i.e. instances) as well as "stuff" (i.e. background things like trees and roads) in an image |
+| **Model** | [`~transformers.DetrForObjectDetection`] | [`~transformers.DetrForSegmentation`] | [`~transformers.DetrForSegmentation`] |
+| **Example dataset** | COCO detection | COCO detection, COCO panoptic | COCO panoptic | |
+| **Format of annotations to provide to** [`~transformers.DetrImageProcessor`] | {'image_id': `int`, 'annotations': `list[Dict]`} each Dict being a COCO object annotation | {'image_id': `int`, 'annotations': `list[Dict]`} (in case of COCO detection) or {'file_name': `str`, 'image_id': `int`, 'segments_info': `list[Dict]`} (in case of COCO panoptic) | {'file_name': `str`, 'image_id': `int`, 'segments_info': `list[Dict]`} and masks_path (path to directory containing PNG files of the masks) |
+| **Postprocessing** (i.e. converting the output of the model to Pascal VOC format) | [`~transformers.DetrImageProcessor.post_process`] | [`~transformers.DetrImageProcessor.post_process_segmentation`] | [`~transformers.DetrImageProcessor.post_process_segmentation`], [`~transformers.DetrImageProcessor.post_process_panoptic`] |
+| **evaluators** | `CocoEvaluator` with `iou_types="bbox"` | `CocoEvaluator` with `iou_types="bbox"` or `"segm"` | `CocoEvaluator` with `iou_tupes="bbox"` or `"segm"`, `PanopticEvaluator` |
+
+- In short, one should prepare the data either in COCO detection or COCO panoptic format, then use [`~transformers.DetrImageProcessor`] to create `pixel_values`, `pixel_mask` and optional `labels`, which can then be used to train (or fine-tune) a model.
+- For evaluation, one should first convert the outputs of the model using one of the postprocessing methods of [`~transformers.DetrImageProcessor`]. These can be provided to either `CocoEvaluator` or `PanopticEvaluator`, which allow you to calculate metrics like mean Average Precision (mAP) and Panoptic Quality (PQ). The latter objects are implemented in the [original repository](https://github.com/facebookresearch/detr). See the [example notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/DETR) for more info regarding evaluation.
+
+## Resources
+
+- Refer to these [notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/DETR) for examples of fine-tuning [`DetrForObjectDetection`] and [`DetrForSegmentation`] on a custom dataset.
+
+## DetrConfig
+
+[[autodoc]] DetrConfig
+
+## DetrImageProcessor
+
+[[autodoc]] DetrImageProcessor
+ - preprocess
+ - post_process_object_detection
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## DetrImageProcessorFast
+
+[[autodoc]] DetrImageProcessorFast
+ - preprocess
+ - post_process_object_detection
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## DetrFeatureExtractor
+
+[[autodoc]] DetrFeatureExtractor
+ - __call__
+ - post_process_object_detection
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## DETR specific outputs
+
+[[autodoc]] models.detr.modeling_detr.DetrModelOutput
+
+[[autodoc]] models.detr.modeling_detr.DetrObjectDetectionOutput
+
+[[autodoc]] models.detr.modeling_detr.DetrSegmentationOutput
+
+## DetrModel
+
+[[autodoc]] DetrModel
+ - forward
+
+## DetrForObjectDetection
+
+[[autodoc]] DetrForObjectDetection
+ - forward
+
+## DetrForSegmentation
+
+[[autodoc]] DetrForSegmentation
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dia.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dia.md
new file mode 100644
index 0000000000000000000000000000000000000000..1a07e8831ee7eb9b7bf9d85c10df3d6140c2904e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dia.md
@@ -0,0 +1,163 @@
+
+*This model was released on 2025-04-21 and added to Hugging Face Transformers on 2025-06-26.*
+
+# Dia
+
+
+
+
+
+
+
+
+
+## Overview
+
+[Dia](https://github.com/nari-labs/dia) is an open-source text-to-speech (TTS) model (1.6B parameters) developed by [Nari Labs](https://huggingface.co/nari-labs).
+It can generate highly realistic dialogue from transcript including non-verbal communications such as laughter and coughing.
+Furthermore, emotion and tone control is also possible via audio conditioning (voice cloning).
+
+**Model Architecture:**
+Dia is an encoder-decoder transformer based on the original transformer architecture. However, some more modern features such as
+rotational positional embeddings (RoPE) are also included. For its text portion (encoder), a byte tokenizer is utilized while
+for the audio portion (decoder), a pretrained codec model [DAC](./dac) is used - DAC encodes speech into discrete codebook
+tokens and decodes them back into audio.
+
+## Usage Tips
+
+### Generation with Text
+
+```python
+from transformers import AutoProcessor, DiaForConditionalGeneration, infer_device
+
+torch_device = infer_device()
+model_checkpoint = "nari-labs/Dia-1.6B-0626"
+
+text = ["[S1] Dia is an open weights text to dialogue model."]
+processor = AutoProcessor.from_pretrained(model_checkpoint)
+inputs = processor(text=text, padding=True, return_tensors="pt").to(torch_device)
+
+model = DiaForConditionalGeneration.from_pretrained(model_checkpoint).to(torch_device)
+outputs = model.generate(**inputs, max_new_tokens=256) # corresponds to around ~2s
+
+# save audio to a file
+outputs = processor.batch_decode(outputs)
+processor.save_audio(outputs, "example.wav")
+
+```
+
+### Generation with Text and Audio (Voice Cloning)
+
+```python
+from datasets import load_dataset, Audio
+from transformers import AutoProcessor, DiaForConditionalGeneration, infer_device
+
+torch_device = infer_device()
+model_checkpoint = "nari-labs/Dia-1.6B-0626"
+
+ds = load_dataset("hf-internal-testing/dailytalk-dummy", split="train")
+ds = ds.cast_column("audio", Audio(sampling_rate=44100))
+audio = ds[-1]["audio"]["array"]
+# text is a transcript of the audio + additional text you want as new audio
+text = ["[S1] I know. It's going to save me a lot of money, I hope. [S2] I sure hope so for you."]
+
+processor = AutoProcessor.from_pretrained(model_checkpoint)
+inputs = processor(text=text, audio=audio, padding=True, return_tensors="pt").to(torch_device)
+prompt_len = processor.get_audio_prompt_len(inputs["decoder_attention_mask"])
+
+model = DiaForConditionalGeneration.from_pretrained(model_checkpoint).to(torch_device)
+outputs = model.generate(**inputs, max_new_tokens=256) # corresponds to around ~2s
+
+# retrieve actually generated audio and save to a file
+outputs = processor.batch_decode(outputs, audio_prompt_len=prompt_len)
+processor.save_audio(outputs, "example_with_audio.wav")
+```
+
+### Training
+
+```python
+from datasets import load_dataset, Audio
+from transformers import AutoProcessor, DiaForConditionalGeneration, infer_device
+
+torch_device = infer_device()
+model_checkpoint = "nari-labs/Dia-1.6B-0626"
+
+ds = load_dataset("hf-internal-testing/dailytalk-dummy", split="train")
+ds = ds.cast_column("audio", Audio(sampling_rate=44100))
+audio = ds[-1]["audio"]["array"]
+# text is a transcript of the audio
+text = ["[S1] I know. It's going to save me a lot of money, I hope."]
+
+processor = AutoProcessor.from_pretrained(model_checkpoint)
+inputs = processor(
+ text=text,
+ audio=audio,
+ generation=False,
+ output_labels=True,
+ padding=True,
+ return_tensors="pt"
+).to(torch_device)
+
+model = DiaForConditionalGeneration.from_pretrained(model_checkpoint).to(torch_device)
+out = model(**inputs)
+out.loss.backward()
+```
+
+
+This model was contributed by [Jaeyong Sung](https://huggingface.co/buttercrab), [Arthur Zucker](https://huggingface.co/ArthurZ),
+and [Anton Vlasjuk](https://huggingface.co/AntonV). The original code can be found [here](https://github.com/nari-labs/dia/).
+
+
+## DiaConfig
+
+[[autodoc]] DiaConfig
+
+## DiaDecoderConfig
+
+[[autodoc]] DiaDecoderConfig
+
+## DiaEncoderConfig
+
+[[autodoc]] DiaEncoderConfig
+
+## DiaTokenizer
+
+[[autodoc]] DiaTokenizer
+ - __call__
+
+## DiaFeatureExtractor
+
+[[autodoc]] DiaFeatureExtractor
+ - __call__
+
+## DiaProcessor
+
+[[autodoc]] DiaProcessor
+ - __call__
+ - batch_decode
+ - decode
+
+## DiaModel
+
+[[autodoc]] DiaModel
+ - forward
+
+## DiaForConditionalGeneration
+
+[[autodoc]] DiaForConditionalGeneration
+ - forward
+ - generate
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dialogpt.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dialogpt.md
new file mode 100644
index 0000000000000000000000000000000000000000..cce264d34241540e9f581f3a26500b4628f52aba
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dialogpt.md
@@ -0,0 +1,64 @@
+
+*This model was released on 2019-11-01 and added to Hugging Face Transformers on 2020-11-16.*
+
+# DialoGPT
+
+
+
+
+
+
+
+## Overview
+
+DialoGPT was proposed in [DialoGPT: Large-Scale Generative Pre-training for Conversational Response Generation](https://huggingface.co/papers/1911.00536) by Yizhe Zhang, Siqi Sun, Michel Galley, Yen-Chun Chen, Chris Brockett, Xiang Gao,
+Jianfeng Gao, Jingjing Liu, Bill Dolan. It's a GPT2 Model trained on 147M conversation-like exchanges extracted from
+Reddit.
+
+The abstract from the paper is the following:
+
+*We present a large, tunable neural conversational response generation model, DialoGPT (dialogue generative pre-trained
+transformer). Trained on 147M conversation-like exchanges extracted from Reddit comment chains over a period spanning
+from 2005 through 2017, DialoGPT extends the Hugging Face PyTorch transformer to attain a performance close to human
+both in terms of automatic and human evaluation in single-turn dialogue settings. We show that conversational systems
+that leverage DialoGPT generate more relevant, contentful and context-consistent responses than strong baseline
+systems. The pre-trained model and training pipeline are publicly released to facilitate research into neural response
+generation and the development of more intelligent open-domain dialogue systems.*
+
+The original code can be found [here](https://github.com/microsoft/DialoGPT).
+
+## Usage tips
+
+- DialoGPT is a model with absolute position embeddings so it's usually advised to pad the inputs on the right rather
+ than the left.
+- DialoGPT was trained with a causal language modeling (CLM) objective on conversational data and is therefore powerful
+ at response generation in open-domain dialogue systems.
+- DialoGPT enables the user to create a chat bot in just 10 lines of code as shown on [DialoGPT's model card](https://huggingface.co/microsoft/DialoGPT-medium).
+
+Training:
+
+In order to train or fine-tune DialoGPT, one can use causal language modeling training. To cite the official paper: *We
+follow the OpenAI GPT-2 to model a multiturn dialogue session as a long text and frame the generation task as language
+modeling. We first concatenate all dialog turns within a dialogue session into a long text x_1,..., x_N (N is the
+sequence length), ended by the end-of-text token.* For more information please confer to the original paper.
+
+
+
+DialoGPT's architecture is based on the GPT2 model, refer to [GPT2's documentation page](gpt2) for API reference and examples.
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/diffllama.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/diffllama.md
new file mode 100644
index 0000000000000000000000000000000000000000..406bae43c5f205a2683a22ee31bd614eff373815
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/diffllama.md
@@ -0,0 +1,66 @@
+
+*This model was released on 2024-10-07 and added to Hugging Face Transformers on 2025-01-07.*
+
+# DiffLlama
+
+
+
+
+
+
+
+## Overview
+
+The DiffLlama model was proposed in [Differential Transformer](https://huggingface.co/papers/2410.05258) by Kazuma Matsumoto and .
+This model is combine Llama model and Differential Transformer's Attention.
+
+The abstract from the paper is the following:
+
+*Transformer tends to overallocate attention to irrelevant context. In this work, we introduce Diff Transformer, which amplifies attention to the relevant context while canceling noise. Specifically, the differential attention mechanism calculates attention scores as the difference between two separate softmax attention maps. The subtraction cancels noise, promoting the emergence of sparse attention patterns. Experimental results on language modeling show that Diff Transformer outperforms Transformer in various settings of scaling up model size and training tokens. More intriguingly, it offers notable advantages in practical applications, such as long-context modeling, key information retrieval, hallucination mitigation, in-context learning, and reduction of activation outliers. By being less distracted by irrelevant context, Diff Transformer can mitigate hallucination in question answering and text summarization. For in-context learning, Diff Transformer not only enhances accuracy but is also more robust to order permutation, which was considered as a chronic robustness issue. The results position Diff Transformer as a highly effective and promising architecture to advance large language models.*
+
+### Usage tips
+The hyperparameters of this model is the same as Llama model.
+
+
+## DiffLlamaConfig
+
+[[autodoc]] DiffLlamaConfig
+
+## DiffLlamaModel
+
+[[autodoc]] DiffLlamaModel
+ - forward
+
+## DiffLlamaForCausalLM
+
+[[autodoc]] DiffLlamaForCausalLM
+ - forward
+
+## DiffLlamaForSequenceClassification
+
+[[autodoc]] DiffLlamaForSequenceClassification
+ - forward
+
+## DiffLlamaForQuestionAnswering
+
+[[autodoc]] DiffLlamaForQuestionAnswering
+ - forward
+
+## DiffLlamaForTokenClassification
+
+[[autodoc]] DiffLlamaForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dinat.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dinat.md
new file mode 100644
index 0000000000000000000000000000000000000000..e6d3385003cbcad5c0de44e11f0ec323a1a0d66d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dinat.md
@@ -0,0 +1,96 @@
+
+*This model was released on 2022-09-29 and added to Hugging Face Transformers on 2022-11-18.*
+
+# Dilated Neighborhood Attention Transformer
+
+
+
+
+
+## Overview
+
+DiNAT was proposed in [Dilated Neighborhood Attention Transformer](https://huggingface.co/papers/2209.15001)
+by Ali Hassani and Humphrey Shi.
+
+It extends [NAT](nat) by adding a Dilated Neighborhood Attention pattern to capture global context,
+and shows significant performance improvements over it.
+
+The abstract from the paper is the following:
+
+*Transformers are quickly becoming one of the most heavily applied deep learning architectures across modalities,
+domains, and tasks. In vision, on top of ongoing efforts into plain transformers, hierarchical transformers have
+also gained significant attention, thanks to their performance and easy integration into existing frameworks.
+These models typically employ localized attention mechanisms, such as the sliding-window Neighborhood Attention (NA)
+or Swin Transformer's Shifted Window Self Attention. While effective at reducing self attention's quadratic complexity,
+local attention weakens two of the most desirable properties of self attention: long range inter-dependency modeling,
+and global receptive field. In this paper, we introduce Dilated Neighborhood Attention (DiNA), a natural, flexible and
+efficient extension to NA that can capture more global context and expand receptive fields exponentially at no
+additional cost. NA's local attention and DiNA's sparse global attention complement each other, and therefore we
+introduce Dilated Neighborhood Attention Transformer (DiNAT), a new hierarchical vision transformer built upon both.
+DiNAT variants enjoy significant improvements over strong baselines such as NAT, Swin, and ConvNeXt.
+Our large model is faster and ahead of its Swin counterpart by 1.5% box AP in COCO object detection,
+1.3% mask AP in COCO instance segmentation, and 1.1% mIoU in ADE20K semantic segmentation.
+Paired with new frameworks, our large variant is the new state of the art panoptic segmentation model on COCO (58.2 PQ)
+and ADE20K (48.5 PQ), and instance segmentation model on Cityscapes (44.5 AP) and ADE20K (35.4 AP) (no extra data).
+It also matches the state of the art specialized semantic segmentation models on ADE20K (58.2 mIoU),
+and ranks second on Cityscapes (84.5 mIoU) (no extra data). *
+
+
+
+ Neighborhood Attention with different dilation values.
+Taken from the original paper.
+
+This model was contributed by [Ali Hassani](https://huggingface.co/alihassanijr).
+The original code can be found [here](https://github.com/SHI-Labs/Neighborhood-Attention-Transformer).
+
+## Usage tips
+
+DiNAT can be used as a *backbone*. When `output_hidden_states = True`,
+it will output both `hidden_states` and `reshaped_hidden_states`. The `reshaped_hidden_states` have a shape of `(batch, num_channels, height, width)` rather than `(batch_size, height, width, num_channels)`.
+
+Notes:
+- DiNAT depends on [NATTEN](https://github.com/SHI-Labs/NATTEN/)'s implementation of Neighborhood Attention and Dilated Neighborhood Attention.
+You can install it with pre-built wheels for Linux by referring to [shi-labs.com/natten](https://shi-labs.com/natten), or build on your system by running `pip install natten`.
+Note that the latter will likely take time to compile. NATTEN does not support Windows devices yet.
+- Patch size of 4 is only supported at the moment.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with DiNAT.
+
+
+
+- [`DinatForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## DinatConfig
+
+[[autodoc]] DinatConfig
+
+## DinatModel
+
+[[autodoc]] DinatModel
+ - forward
+
+## DinatForImageClassification
+
+[[autodoc]] DinatForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dinov2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dinov2.md
new file mode 100644
index 0000000000000000000000000000000000000000..11c0eceedb71863197f204a725cdf801ef804b3c
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dinov2.md
@@ -0,0 +1,210 @@
+
+*This model was released on 2023-04-14 and added to Hugging Face Transformers on 2023-07-18.*
+
+
+
+
+
+
+
+
+
+
+
+# DINOv2
+
+[DINOv2](https://huggingface.co/papers/2304.07193) is a vision foundation model that uses [ViT](./vit) as a feature extractor for multiple downstream tasks like image classification and depth estimation. It focuses on stabilizing and accelerating training through techniques like a faster memory-efficient attention, sequence packing, improved stochastic depth, Fully Sharded Data Parallel (FSDP), and model distillation.
+
+You can find all the original DINOv2 checkpoints under the [Dinov2](https://huggingface.co/collections/facebook/dinov2-6526c98554b3d2576e071ce3) collection.
+
+> [!TIP]
+> Click on the DINOv2 models in the right sidebar for more examples of how to apply DINOv2 to different vision tasks.
+
+The example below demonstrates how to obtain an image embedding with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipe = pipeline(
+ task="image-classification",
+ model="facebook/dinov2-small-imagenet1k-1-layer",
+ torch_dtype=torch.float16,
+ device=0
+)
+
+pipe("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg")
+```
+
+
+
+
+```py
+import requests
+from transformers import AutoImageProcessor, AutoModelForImageClassification
+from PIL import Image
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+processor = AutoImageProcessor.from_pretrained("facebook/dinov2-small-imagenet1k-1-layer")
+model = AutoModelForImageClassification.from_pretrained(
+ "facebook/dinov2-small-imagenet1k-1-layer",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+
+inputs = processor(images=image, return_tensors="pt")
+logits = model(**inputs).logits
+predicted_class_idx = logits.argmax(-1).item()
+print("Predicted class:", model.config.id2label[predicted_class_idx])
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [torchao](../quantization/torchao) to only quantize the weights to int4.
+
+```py
+# pip install torchao
+import requests
+from transformers import TorchAoConfig, AutoImageProcessor, AutoModelForImageClassification
+from torchao.quantization import Int4WeightOnlyConfig
+from PIL import Image
+
+url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+image = Image.open(requests.get(url, stream=True).raw)
+
+processor = AutoImageProcessor.from_pretrained('facebook/dinov2-giant-imagenet1k-1-layer')
+
+quant_config = Int4WeightOnlyConfig(group_size=128)
+quantization_config = TorchAoConfig(quant_type=quant_config)
+
+model = AutoModelForImageClassification.from_pretrained(
+ 'facebook/dinov2-giant-imagenet1k-1-layer',
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+inputs = processor(images=image, return_tensors="pt")
+outputs = model(**inputs)
+logits = outputs.logits
+predicted_class_idx = logits.argmax(-1).item()
+print("Predicted class:", model.config.id2label[predicted_class_idx])
+```
+
+## Notes
+
+- The example below shows how to split the output tensor into:
+ - one embedding for the whole image, commonly referred to as a `CLS` token,
+ useful for classification and retrieval
+ - a set of local embeddings, one for each `14x14` patch of the input image,
+ useful for dense tasks, such as semantic segmentation
+
+ ```py
+ from transformers import AutoImageProcessor, AutoModel
+ from PIL import Image
+ import requests
+
+ url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+ image = Image.open(requests.get(url, stream=True).raw)
+ print(image.height, image.width) # [480, 640]
+
+ processor = AutoImageProcessor.from_pretrained('facebook/dinov2-base')
+ model = AutoModel.from_pretrained('facebook/dinov2-base')
+ patch_size = model.config.patch_size
+
+ inputs = processor(images=image, return_tensors="pt")
+ print(inputs.pixel_values.shape) # [1, 3, 224, 224]
+ batch_size, rgb, img_height, img_width = inputs.pixel_values.shape
+ num_patches_height, num_patches_width = img_height // patch_size, img_width // patch_size
+ num_patches_flat = num_patches_height * num_patches_width
+
+ outputs = model(**inputs)
+ last_hidden_states = outputs[0]
+ print(last_hidden_states.shape) # [1, 1 + 256, 768]
+ assert last_hidden_states.shape == (batch_size, 1 + num_patches_flat, model.config.hidden_size)
+
+ cls_token = last_hidden_states[:, 0, :]
+ patch_features = last_hidden_states[:, 1:, :].unflatten(1, (num_patches_height, num_patches_width))
+ ```
+
+- Use [torch.jit.trace](https://pytorch.org/docs/stable/generated/torch.jit.trace.html) to speedup inference.
+ However, it will produce some mismatched elements. The difference between the original and traced model is 1e-4.
+
+ ```py
+ import torch
+ from transformers import AutoImageProcessor, AutoModel
+ from PIL import Image
+ import requests
+
+ url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+ image = Image.open(requests.get(url, stream=True).raw)
+
+ processor = AutoImageProcessor.from_pretrained('facebook/dinov2-base')
+ model = AutoModel.from_pretrained('facebook/dinov2-base')
+
+ inputs = processor(images=image, return_tensors="pt")
+ outputs = model(**inputs)
+ last_hidden_states = outputs[0]
+
+ # We have to force return_dict=False for tracing
+ model.config.return_dict = False
+
+ with torch.no_grad():
+ traced_model = torch.jit.trace(model, [inputs.pixel_values])
+ traced_outputs = traced_model(inputs.pixel_values)
+
+ print((last_hidden_states - traced_outputs[0]).abs().max())
+ ```
+
+## Dinov2Config
+
+[[autodoc]] Dinov2Config
+
+
+
+
+## Dinov2Model
+
+[[autodoc]] Dinov2Model
+ - forward
+
+## Dinov2ForImageClassification
+
+[[autodoc]] Dinov2ForImageClassification
+ - forward
+
+
+
+
+## FlaxDinov2Model
+
+[[autodoc]] FlaxDinov2Model
+ - __call__
+
+
+## FlaxDinov2ForImageClassification
+
+[[autodoc]] FlaxDinov2ForImageClassification
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dinov2_with_registers.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dinov2_with_registers.md
new file mode 100644
index 0000000000000000000000000000000000000000..f89de76d216830b94b49018dc780b7d70353d1e5
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dinov2_with_registers.md
@@ -0,0 +1,61 @@
+
+*This model was released on 2023-09-28 and added to Hugging Face Transformers on 2024-12-24.*
+
+# DINOv2 with Registers
+
+
+
+
+
+
+
+## Overview
+
+The DINOv2 with Registers model was proposed in [Vision Transformers Need Registers](https://huggingface.co/papers/2309.16588) by Timothée Darcet, Maxime Oquab, Julien Mairal, Piotr Bojanowski.
+
+The [Vision Transformer](vit) (ViT) is a transformer encoder model (BERT-like) originally introduced to do supervised image classification on ImageNet.
+
+Next, people figured out ways to make ViT work really well on self-supervised image feature extraction (i.e. learning meaningful features, also called embeddings) on images without requiring any labels. Some example papers here include [DINOv2](dinov2) and [MAE](vit_mae).
+
+The authors of DINOv2 noticed that ViTs have artifacts in attention maps. It’s due to the model using some image patches as “registers”. The authors propose a fix: just add some new tokens (called "register" tokens), which you only use during pre-training (and throw away afterwards). This results in:
+- no artifacts
+- interpretable attention maps
+- and improved performances.
+
+The abstract from the paper is the following:
+
+*Transformers have recently emerged as a powerful tool for learning visual representations. In this paper, we identify and characterize artifacts in feature maps of both supervised and self-supervised ViT networks. The artifacts correspond to high-norm tokens appearing during inference primarily in low-informative background areas of images, that are repurposed for internal computations. We propose a simple yet effective solution based on providing additional tokens to the input sequence of the Vision Transformer to fill that role. We show that this solution fixes that problem entirely for both supervised and self-supervised models, sets a new state of the art for self-supervised visual models on dense visual prediction tasks, enables object discovery methods with larger models, and most importantly leads to smoother feature maps and attention maps for downstream visual processing.*
+
+
+
+ Visualization of attention maps of various models trained with vs. without registers. Taken from the original paper.
+
+Tips:
+
+- Usage of DINOv2 with Registers is identical to DINOv2 without, you'll just get better performance.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/facebookresearch/dinov2).
+
+
+## Dinov2WithRegistersConfig
+
+[[autodoc]] Dinov2WithRegistersConfig
+
+## Dinov2WithRegistersModel
+
+[[autodoc]] Dinov2WithRegistersModel
+ - forward
+
+## Dinov2WithRegistersForImageClassification
+
+[[autodoc]] Dinov2WithRegistersForImageClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dinov3.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dinov3.md
new file mode 100644
index 0000000000000000000000000000000000000000..b3f2067fe92dfee76d8d90034a854577c220792c
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dinov3.md
@@ -0,0 +1,181 @@
+
+
+
+
+
+
+
+
+
+
+
+
+# DINOv3
+
+DINOv3 is a family of versatile vision foundation models that outperforms the specialized state of the art across a broad range of settings, without fine-tuning. DINOv3 produces high-quality dense features that achieve outstanding performance on various vision tasks, significantly surpassing previous self- and weakly-supervised foundation models.
+
+You can find all the original DINOv3 checkpoints under the [DINOv3](https://huggingface.co/collections/facebook/dinov3-68924841bd6b561778e31009) collection.
+
+> [!TIP]
+> Click on the DINOv3 models in the right sidebar for more examples of how to apply DINOv3 to different vision tasks.
+
+The example below demonstrates how to obtain an image embedding with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipe = pipeline(
+ task="image-feature-extraction",
+ model="facebook/dinov3-vits16-pretrain-lvd1689m",
+ torch_dtype=torch.bfloat16,
+)
+
+pipe("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg")
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoImageProcessor, AutoModel
+from transformers.image_utils import load_image
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = load_image(url)
+
+processor = AutoImageProcessor.from_pretrained("facebook/dinov3-vits16-pretrain-lvd1689m")
+model = AutoModel.from_pretrained(
+ "facebook/dinov3-vits16-pretrain-lvd1689m",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+
+inputs = processor(images=image, return_tensors="pt").to(model.device)
+with torch.inference_mode():
+ outputs = model(**inputs)
+
+pooled_output = outputs.pooler_output
+print("Pooled output shape:", pooled_output.shape)
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [torchao](../quantization/torchao) to only quantize the weights to int4.
+
+```py
+# pip install torchao
+import torch
+from transformers import TorchAoConfig, AutoImageProcessor, AutoModel
+from torchao.quantization import Int4WeightOnlyConfig
+from transformers.image_utils import load_image
+
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = load_image(url)
+
+processor = AutoImageProcessor.from_pretrained("facebook/dinov3-vitsplus-pretrain-lvd1689m")
+
+quant_type = Int4WeightOnlyConfig(group_size=128)
+quantization_config = TorchAoConfig(quant_type=quant_type)
+
+model = AutoModel.from_pretrained(
+ "facebook/dinov3-vit7b16-pretrain-lvd1689m",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+inputs = processor(images=image, return_tensors="pt").to(model.device)
+with torch.inference_mode():
+ outputs = model(**inputs)
+
+pooled_output = outputs.pooler_output
+print("Pooled output shape:", pooled_output.shape)
+```
+
+## Notes
+
+- The example below shows how to split the output tensor into:
+ - one embedding for the whole image, commonly referred to as a `CLS` token,
+ useful for classification and retrieval
+ - register tokens - learnable embeddings that act as dedicated “memory slots” for global information,
+ they reduce high-norm artifacts in patch tokens, yielding cleaner attention maps and better
+ performance on dense prediction tasks.
+ - a set of local embeddings, one for each `16x16` patch of the input image,
+ useful for dense tasks, such as semantic segmentation
+
+ ```py
+ import torch
+ from transformers import AutoImageProcessor, AutoModel
+ from transformers.image_utils import load_image
+
+ url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ image = load_image(url)
+ print("Image size:", image.height, image.width) # [480, 640]
+
+ processor = AutoImageProcessor.from_pretrained("facebook/dinov3-vits16-pretrain-lvd1689m")
+ model = AutoModel.from_pretrained("facebook/dinov3-vits16-pretrain-lvd1689m")
+ patch_size = model.config.patch_size
+ print("Patch size:", patch_size) # 16
+ print("Num register tokens:", model.config.num_register_tokens) # 4
+
+ inputs = processor(images=image, return_tensors="pt")
+ print("Preprocessed image size:", inputs.pixel_values.shape) # [1, 3, 224, 224]
+
+ batch_size, _, img_height, img_width = inputs.pixel_values.shape
+ num_patches_height, num_patches_width = img_height // patch_size, img_width // patch_size
+ num_patches_flat = num_patches_height * num_patches_width
+
+ with torch.inference_mode():
+ outputs = model(**inputs)
+
+ last_hidden_states = outputs.last_hidden_state
+ print(last_hidden_states.shape) # [1, 1 + 4 + 256, 384]
+ assert last_hidden_states.shape == (batch_size, 1 + model.config.num_register_tokens + num_patches_flat, model.config.hidden_size)
+
+ cls_token = last_hidden_states[:, 0, :]
+ patch_features_flat = last_hidden_states[:, 1 + model.config.num_register_tokens:, :]
+ patch_features = patch_features_flat.unflatten(1, (num_patches_height, num_patches_width))
+ ```
+
+## DINOv3ViTConfig
+
+[[autodoc]] DINOv3ViTConfig
+
+## DINOv3ConvNextConfig
+
+[[autodoc]] DINOv3ConvNextConfig
+
+## DINOv3ViTModel
+
+[[autodoc]] DINOv3ViTModel
+ - forward
+
+## DINOv3ConvNextModel
+
+[[autodoc]] DINOv3ConvNextModel
+ - forward
+
+## DINOv3ViTImageProcessorFast
+
+[[autodoc]] DINOv3ViTImageProcessorFast
+ - preprocess
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/distilbert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/distilbert.md
new file mode 100644
index 0000000000000000000000000000000000000000..254cdc7008e8e795a395b3ef50a32eb2343b14a2
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/distilbert.md
@@ -0,0 +1,216 @@
+
+*This model was released on 2019-10-02 and added to Hugging Face Transformers on 2020-11-16.*
+
+
+
+
+
+
+
+
+
+
+
+# DistilBERT
+
+[DistilBERT](https://huggingface.co/papers/1910.01108) is pretrained by knowledge distillation to create a smaller model with faster inference and requires less compute to train. Through a triple loss objective during pretraining, language modeling loss, distillation loss, cosine-distance loss, DistilBERT demonstrates similar performance to a larger transformer language model.
+
+You can find all the original DistilBERT checkpoints under the [DistilBERT](https://huggingface.co/distilbert) organization.
+
+> [!TIP]
+> Click on the DistilBERT models in the right sidebar for more examples of how to apply DistilBERT to different language tasks.
+
+The example below demonstrates how to classify text with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+
+```py
+from transformers import pipeline
+
+classifier = pipeline(
+ task="text-classification",
+ model="distilbert-base-uncased-finetuned-sst-2-english",
+ torch_dtype=torch.float16,
+ device=0
+)
+
+result = classifier("I love using Hugging Face Transformers!")
+print(result)
+# Output: [{'label': 'POSITIVE', 'score': 0.9998}]
+```
+
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForSequenceClassification, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "distilbert/distilbert-base-uncased-finetuned-sst-2-english",
+)
+model = AutoModelForSequenceClassification.from_pretrained(
+ "distilbert/distilbert-base-uncased-finetuned-sst-2-english",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+inputs = tokenizer("I love using Hugging Face Transformers!", return_tensors="pt").to(model.device)
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+predicted_class_id = torch.argmax(outputs.logits, dim=-1).item()
+predicted_label = model.config.id2label[predicted_class_id]
+print(f"Predicted label: {predicted_label}")
+```
+
+
+
+
+
+```bash
+echo -e "I love using Hugging Face Transformers!" | transformers run --task text-classification --model distilbert-base-uncased-finetuned-sst-2-english
+```
+
+
+
+
+
+## Notes
+
+- DistilBERT doesn't have `token_type_ids`, you don't need to indicate which token belongs to which segment. Just
+ separate your segments with the separation token `tokenizer.sep_token` (or `[SEP]`).
+- DistilBERT doesn't have options to select the input positions (`position_ids` input). This could be added if
+ necessary though, just let us know if you need this option.
+
+## DistilBertConfig
+
+[[autodoc]] DistilBertConfig
+
+## DistilBertTokenizer
+
+[[autodoc]] DistilBertTokenizer
+
+## DistilBertTokenizerFast
+
+[[autodoc]] DistilBertTokenizerFast
+
+
+
+
+## DistilBertModel
+
+[[autodoc]] DistilBertModel
+ - forward
+
+## DistilBertForMaskedLM
+
+[[autodoc]] DistilBertForMaskedLM
+ - forward
+
+## DistilBertForSequenceClassification
+
+[[autodoc]] DistilBertForSequenceClassification
+ - forward
+
+## DistilBertForMultipleChoice
+
+[[autodoc]] DistilBertForMultipleChoice
+ - forward
+
+## DistilBertForTokenClassification
+
+[[autodoc]] DistilBertForTokenClassification
+ - forward
+
+## DistilBertForQuestionAnswering
+
+[[autodoc]] DistilBertForQuestionAnswering
+ - forward
+
+
+
+
+## TFDistilBertModel
+
+[[autodoc]] TFDistilBertModel
+ - call
+
+## TFDistilBertForMaskedLM
+
+[[autodoc]] TFDistilBertForMaskedLM
+ - call
+
+## TFDistilBertForSequenceClassification
+
+[[autodoc]] TFDistilBertForSequenceClassification
+ - call
+
+## TFDistilBertForMultipleChoice
+
+[[autodoc]] TFDistilBertForMultipleChoice
+ - call
+
+## TFDistilBertForTokenClassification
+
+[[autodoc]] TFDistilBertForTokenClassification
+ - call
+
+## TFDistilBertForQuestionAnswering
+
+[[autodoc]] TFDistilBertForQuestionAnswering
+ - call
+
+
+
+
+## FlaxDistilBertModel
+
+[[autodoc]] FlaxDistilBertModel
+ - __call__
+
+## FlaxDistilBertForMaskedLM
+
+[[autodoc]] FlaxDistilBertForMaskedLM
+ - __call__
+
+## FlaxDistilBertForSequenceClassification
+
+[[autodoc]] FlaxDistilBertForSequenceClassification
+ - __call__
+
+## FlaxDistilBertForMultipleChoice
+
+[[autodoc]] FlaxDistilBertForMultipleChoice
+ - __call__
+
+## FlaxDistilBertForTokenClassification
+
+[[autodoc]] FlaxDistilBertForTokenClassification
+ - __call__
+
+## FlaxDistilBertForQuestionAnswering
+
+[[autodoc]] FlaxDistilBertForQuestionAnswering
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dit.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dit.md
new file mode 100644
index 0000000000000000000000000000000000000000..736b41f91af2a94b809b8bcc40713479e37e074c
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dit.md
@@ -0,0 +1,98 @@
+
+*This model was released on 2022-03-04 and added to Hugging Face Transformers on 2022-03-10.*
+
+
+
+
+
+
+
+# DiT
+
+[DiT](https://huggingface.co/papers/2203.02378) is an image transformer pretrained on large-scale unlabeled document images. It learns to predict the missing visual tokens from a corrupted input image. The pretrained DiT model can be used as a backbone in other models for visual document tasks like document image classification and table detection.
+
+
+
+You can find all the original DiT checkpoints under the [Microsoft](https://huggingface.co/microsoft?search_models=dit) organization.
+
+> [!TIP]
+> Refer to the [BEiT](./beit) docs for more examples of how to apply DiT to different vision tasks.
+
+The example below demonstrates how to classify an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="image-classification",
+ model="microsoft/dit-base-finetuned-rvlcdip",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/model_doc/dit-example.jpg")
+```
+
+
+
+
+```py
+import torch
+import requests
+from PIL import Image
+from transformers import AutoModelForImageClassification, AutoImageProcessor
+
+image_processor = AutoImageProcessor.from_pretrained(
+ "microsoft/dit-base-finetuned-rvlcdip",
+ use_fast=True,
+)
+model = AutoModelForImageClassification.from_pretrained(
+ "microsoft/dit-base-finetuned-rvlcdip",
+ device_map="auto",
+)
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/model_doc/dit-example.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+inputs = image_processor(image, return_tensors="pt").to(model.device)
+
+with torch.no_grad():
+ logits = model(**inputs).logits
+predicted_class_id = logits.argmax(dim=-1).item()
+
+class_labels = model.config.id2label
+predicted_class_label = class_labels[predicted_class_id]
+print(f"The predicted class label is: {predicted_class_label}")
+```
+
+
+
+
+## Notes
+
+- The pretrained DiT weights can be loaded in a [BEiT] model with a modeling head to predict visual tokens.
+ ```py
+ from transformers import BeitForMaskedImageModeling
+
+ model = BeitForMaskedImageModeling.from_pretraining("microsoft/dit-base")
+ ```
+
+## Resources
+
+- Refer to this [notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/DiT/Inference_with_DiT_(Document_Image_Transformer)_for_document_image_classification.ipynb) for a document image classification inference example.
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/doge.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/doge.md
new file mode 100644
index 0000000000000000000000000000000000000000..6221940d5d5a29e3deae7af2c0c7ae144b680f06
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/doge.md
@@ -0,0 +1,104 @@
+
+*This model was released on 2024-12-27 and added to Hugging Face Transformers on 2025-07-08.*
+
+# Doge
+
+
+## Overview
+
+Doge is a series of small language models based on the [Doge](https://github.com/SmallDoges/small-doge) architecture, aiming to combine the advantages of state-space and self-attention algorithms, calculate dynamic masks from cached value states using the zero-order hold method, and solve the problem of existing mainstream language models getting lost in context. It uses the `wsd_scheduler` scheduler to pre-train on the `smollm-corpus`, and can continue training on new datasets or add sparse activation feedforward networks from stable stage checkpoints.
+
+
+
+As shown in the figure below, the sequence transformation part of the Doge architecture uses `Dynamic Mask Attention`, which can be understood as using self-attention related to value states during training, and using state-space without past state decay during inference, to solve the problem of existing Transformers or SSMs getting lost in long text. The state transformation part of Doge uses `Cross Domain Mixture of Experts`, which consists of dense linear layers and sparse embedding layers, and can additionally increase sparse parameters to continue training from dense weight checkpoints without retraining the entire model, thereby reducing the cost of continuous iteration of the model. In addition, Doge also uses `RMSNorm` and `Residual` with learnable parameters to adapt the gradient range of deep models.
+
+Checkout all Doge model checkpoints [here](https://huggingface.co/collections/SmallDoge/doge-slm-679cc991f027c4a3abbded4a).
+
+
+## Usage
+
+
+Using Doge-Base for text generation
+
+```python
+from transformers import AutoTokenizer, AutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("SmallDoge/Doge-20M")
+model = AutoModelForCausalLM.from_pretrained("SmallDoge/Doge-20M")
+inputs = tokenizer("Hey how are you doing?", return_tensors="pt")
+
+outputs = model.generate(**inputs, max_new_tokens=100)
+print(tokenizer.batch_decode(outputs))
+```
+
+
+
+Using Doge-Instruct for question answering
+
+```python
+from transformers import AutoTokenizer, AutoModelForCausalLM, GenerationConfig, TextStreamer
+
+tokenizer = AutoTokenizer.from_pretrained("SmallDoge/Doge-20M-Instruct")
+model = AutoModelForCausalLM.from_pretrained("SmallDoge/Doge-20M-Instruct")
+
+generation_config = GenerationConfig(
+ max_new_tokens=100,
+ use_cache=True,
+ do_sample=True,
+ temperature=0.8,
+ top_p=0.9,
+ repetition_penalty=1.0
+)
+steamer = TextStreamer(tokenizer=tokenizer, skip_prompt=True)
+
+prompt = "Hi, how are you doing today?"
+conversation = [
+ {"role": "user", "content": prompt}
+]
+inputs = tokenizer.apply_chat_template(
+ conversation=conversation,
+ tokenize=True,
+ return_tensors="pt",
+)
+
+outputs = model.generate(
+ inputs,
+ tokenizer=tokenizer,
+ generation_config=generation_config,
+ streamer=steamer
+)
+```
+
+
+## DogeConfig
+
+[[autodoc]] DogeConfig
+
+## DogeModel
+
+[[autodoc]] DogeModel
+ - forward
+
+## DogeForCausalLM
+
+[[autodoc]] DogeForCausalLM
+ - forward
+
+## DogeForSequenceClassification
+
+[[autodoc]] DogeForSequenceClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/donut.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/donut.md
new file mode 100644
index 0000000000000000000000000000000000000000..28fed293b465a05939bc3f24925dbcdea6a98841
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/donut.md
@@ -0,0 +1,239 @@
+
+*This model was released on 2021-11-30 and added to Hugging Face Transformers on 2022-08-12.*
+
+
+
+
+
+
+
+# Donut
+
+[Donut (Document Understanding Transformer)](https://huggingface.co/papers/2111.15664) is a visual document understanding model that doesn't require an Optical Character Recognition (OCR) engine. Unlike traditional approaches that extract text using OCR before processing, Donut employs an end-to-end Transformer-based architecture to directly analyze document images. This eliminates OCR-related inefficiencies making it more accurate and adaptable to diverse languages and formats.
+
+Donut features vision encoder ([Swin](./swin)) and a text decoder ([BART](./bart)). Swin converts document images into embeddings and BART processes them into meaningful text sequences.
+
+You can find all the original Donut checkpoints under the [Naver Clova Information Extraction](https://huggingface.co/naver-clova-ix) organization.
+
+> [!TIP]
+> Click on the Donut models in the right sidebar for more examples of how to apply Donut to different language and vision tasks.
+
+The examples below demonstrate how to perform document understanding tasks using Donut with [`Pipeline`] and [`AutoModel`]
+
+
+
+
+```py
+# pip install datasets
+import torch
+from transformers import pipeline
+from PIL import Image
+
+pipeline = pipeline(
+ task="document-question-answering",
+ model="naver-clova-ix/donut-base-finetuned-docvqa",
+ device=0,
+ torch_dtype=torch.float16
+)
+dataset = load_dataset("hf-internal-testing/example-documents", split="test")
+image = dataset[0]["image"]
+
+pipeline(image=image, question="What time is the coffee break?")
+```
+
+
+
+
+```py
+# pip install datasets
+import torch
+from datasets import load_dataset
+from transformers import AutoProcessor, AutoModelForVision2Seq
+
+processor = AutoProcessor.from_pretrained("naver-clova-ix/donut-base-finetuned-docvqa")
+model = AutoModelForVision2Seq.from_pretrained("naver-clova-ix/donut-base-finetuned-docvqa")
+
+dataset = load_dataset("hf-internal-testing/example-documents", split="test")
+image = dataset[0]["image"]
+question = "What time is the coffee break?"
+task_prompt = f"{question}"
+inputs = processor(image, task_prompt, return_tensors="pt")
+
+outputs = model.generate(
+ input_ids=inputs.input_ids,
+ pixel_values=inputs.pixel_values,
+ max_length=512
+)
+answer = processor.decode(outputs[0], skip_special_tokens=True)
+print(answer)
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [torchao](../quantization/torchao) to only quantize the weights to int4.
+
+```py
+# pip install datasets torchao
+import torch
+from datasets import load_dataset
+from transformers import TorchAoConfig, AutoProcessor, AutoModelForVision2Seq
+
+quantization_config = TorchAoConfig("int4_weight_only", group_size=128)
+processor = AutoProcessor.from_pretrained("naver-clova-ix/donut-base-finetuned-docvqa")
+model = AutoModelForVision2Seq.from_pretrained("naver-clova-ix/donut-base-finetuned-docvqa", quantization_config=quantization_config)
+
+dataset = load_dataset("hf-internal-testing/example-documents", split="test")
+image = dataset[0]["image"]
+question = "What time is the coffee break?"
+task_prompt = f"{question}"
+inputs = processor(image, task_prompt, return_tensors="pt")
+
+outputs = model.generate(
+ input_ids=inputs.input_ids,
+ pixel_values=inputs.pixel_values,
+ max_length=512
+)
+answer = processor.decode(outputs[0], skip_special_tokens=True)
+print(answer)
+```
+
+## Notes
+
+- Use Donut for document image classification as shown below.
+
+ ```py
+ >>> import re
+ >>> from transformers import DonutProcessor, VisionEncoderDecoderModel, infer_device
+ >>> from datasets import load_dataset
+ >>> import torch
+
+ >>> processor = DonutProcessor.from_pretrained("naver-clova-ix/donut-base-finetuned-rvlcdip")
+ >>> model = VisionEncoderDecoderModel.from_pretrained("naver-clova-ix/donut-base-finetuned-rvlcdip")
+
+ >>> device = infer_device()
+ >>> model.to(device) # doctest: +IGNORE_RESULT
+
+ >>> # load document image
+ >>> dataset = load_dataset("hf-internal-testing/example-documents", split="test")
+ >>> image = dataset[1]["image"]
+
+ >>> # prepare decoder inputs
+ >>> task_prompt = ""
+ >>> decoder_input_ids = processor.tokenizer(task_prompt, add_special_tokens=False, return_tensors="pt").input_ids
+
+ >>> pixel_values = processor(image, return_tensors="pt").pixel_values
+
+ >>> outputs = model.generate(
+ ... pixel_values.to(device),
+ ... decoder_input_ids=decoder_input_ids.to(device),
+ ... max_length=model.decoder.config.max_position_embeddings,
+ ... pad_token_id=processor.tokenizer.pad_token_id,
+ ... eos_token_id=processor.tokenizer.eos_token_id,
+ ... use_cache=True,
+ ... bad_words_ids=[[processor.tokenizer.unk_token_id]],
+ ... return_dict_in_generate=True,
+ ... )
+
+ >>> sequence = processor.batch_decode(outputs.sequences)[0]
+ >>> sequence = sequence.replace(processor.tokenizer.eos_token, "").replace(processor.tokenizer.pad_token, "")
+ >>> sequence = re.sub(r"<.*?>", "", sequence, count=1).strip() # remove first task start token
+ >>> print(processor.token2json(sequence))
+ {'class': 'advertisement'}
+ ```
+
+- Use Donut for document parsing as shown below.
+
+ ```py
+ >>> import re
+ >>> from transformers import DonutProcessor, VisionEncoderDecoderModel, infer_device
+ >>> from datasets import load_dataset
+ >>> import torch
+
+ >>> processor = DonutProcessor.from_pretrained("naver-clova-ix/donut-base-finetuned-cord-v2")
+ >>> model = VisionEncoderDecoderModel.from_pretrained("naver-clova-ix/donut-base-finetuned-cord-v2")
+
+ >>> device = infer_device()
+ >>> model.to(device) # doctest: +IGNORE_RESULT
+
+ >>> # load document image
+ >>> dataset = load_dataset("hf-internal-testing/example-documents", split="test")
+ >>> image = dataset[2]["image"]
+
+ >>> # prepare decoder inputs
+ >>> task_prompt = ""
+ >>> decoder_input_ids = processor.tokenizer(task_prompt, add_special_tokens=False, return_tensors="pt").input_ids
+
+ >>> pixel_values = processor(image, return_tensors="pt").pixel_values
+
+ >>> outputs = model.generate(
+ ... pixel_values.to(device),
+ ... decoder_input_ids=decoder_input_ids.to(device),
+ ... max_length=model.decoder.config.max_position_embeddings,
+ ... pad_token_id=processor.tokenizer.pad_token_id,
+ ... eos_token_id=processor.tokenizer.eos_token_id,
+ ... use_cache=True,
+ ... bad_words_ids=[[processor.tokenizer.unk_token_id]],
+ ... return_dict_in_generate=True,
+ ... )
+
+ >>> sequence = processor.batch_decode(outputs.sequences)[0]
+ >>> sequence = sequence.replace(processor.tokenizer.eos_token, "").replace(processor.tokenizer.pad_token, "")
+ >>> sequence = re.sub(r"<.*?>", "", sequence, count=1).strip() # remove first task start token
+ >>> print(processor.token2json(sequence))
+ {'menu': {'nm': 'CINNAMON SUGAR', 'unitprice': '17,000', 'cnt': '1 x', 'price': '17,000'}, 'sub_total': {'subtotal_price': '17,000'}, 'total':
+ {'total_price': '17,000', 'cashprice': '20,000', 'changeprice': '3,000'}}
+ ```
+
+## DonutSwinConfig
+
+[[autodoc]] DonutSwinConfig
+
+## DonutImageProcessor
+
+[[autodoc]] DonutImageProcessor
+ - preprocess
+
+## DonutImageProcessorFast
+
+[[autodoc]] DonutImageProcessorFast
+ - preprocess
+
+## DonutFeatureExtractor
+
+[[autodoc]] DonutFeatureExtractor
+ - __call__
+
+## DonutProcessor
+
+[[autodoc]] DonutProcessor
+ - __call__
+ - from_pretrained
+ - save_pretrained
+ - batch_decode
+ - decode
+
+## DonutSwinModel
+
+[[autodoc]] DonutSwinModel
+ - forward
+
+## DonutSwinForImageClassification
+
+[[autodoc]] transformers.DonutSwinForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dots1.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dots1.md
new file mode 100644
index 0000000000000000000000000000000000000000..337cad8cb4c7103bf7821af7930c5712925da8b9
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dots1.md
@@ -0,0 +1,41 @@
+
+*This model was released on 2025-06-06 and added to Hugging Face Transformers on 2025-06-25.*
+
+# dots.llm1
+
+## Overview
+
+The `dots.llm1` model was proposed in [dots.llm1 technical report](https://huggingface.co/papers/2506.05767) by rednote-hilab team.
+
+The abstract from the report is the following:
+
+*Mixture of Experts (MoE) models have emerged as a promising paradigm for scaling language models efficiently by activating only a subset of parameters for each input token. In this report, we present dots.llm1, a large-scale MoE model that activates 14B parameters out of a total of 142B parameters, delivering performance on par with state-of-the-art models while reducing training and inference costs. Leveraging our meticulously crafted and efficient data processing pipeline, dots.llm1 achieves performance comparable to Qwen2.5-72B after pretraining on high-quality corpus and post-training to fully unlock its capabilities. Notably, no synthetic data is used during pretraining. To foster further research, we open-source intermediate training checkpoints spanning the entire training process, providing valuable insights into the learning dynamics of large language models.*
+
+
+## Dots1Config
+
+[[autodoc]] Dots1Config
+
+## Dots1Model
+
+[[autodoc]] Dots1Model
+ - forward
+
+## Dots1ForCausalLM
+
+[[autodoc]] Dots1ForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dpr.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dpr.md
new file mode 100644
index 0000000000000000000000000000000000000000..3534009e17bcc7382f150c0fa644a89feb86db18
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dpr.md
@@ -0,0 +1,126 @@
+
+*This model was released on 2020-04-10 and added to Hugging Face Transformers on 2020-11-16.*
+
+# DPR
+
+
+
+
+
+
+
+## Overview
+
+Dense Passage Retrieval (DPR) is a set of tools and models for state-of-the-art open-domain Q&A research. It was
+introduced in [Dense Passage Retrieval for Open-Domain Question Answering](https://huggingface.co/papers/2004.04906) by
+Vladimir Karpukhin, Barlas Oğuz, Sewon Min, Patrick Lewis, Ledell Wu, Sergey Edunov, Danqi Chen, Wen-tau Yih.
+
+The abstract from the paper is the following:
+
+*Open-domain question answering relies on efficient passage retrieval to select candidate contexts, where traditional
+sparse vector space models, such as TF-IDF or BM25, are the de facto method. In this work, we show that retrieval can
+be practically implemented using dense representations alone, where embeddings are learned from a small number of
+questions and passages by a simple dual-encoder framework. When evaluated on a wide range of open-domain QA datasets,
+our dense retriever outperforms a strong Lucene-BM25 system largely by 9%-19% absolute in terms of top-20 passage
+retrieval accuracy, and helps our end-to-end QA system establish new state-of-the-art on multiple open-domain QA
+benchmarks.*
+
+This model was contributed by [lhoestq](https://huggingface.co/lhoestq). The original code can be found [here](https://github.com/facebookresearch/DPR).
+
+## Usage tips
+
+- DPR consists in three models:
+
+ * Question encoder: encode questions as vectors
+ * Context encoder: encode contexts as vectors
+ * Reader: extract the answer of the questions inside retrieved contexts, along with a relevance score (high if the inferred span actually answers the question).
+
+## DPRConfig
+
+[[autodoc]] DPRConfig
+
+## DPRContextEncoderTokenizer
+
+[[autodoc]] DPRContextEncoderTokenizer
+
+## DPRContextEncoderTokenizerFast
+
+[[autodoc]] DPRContextEncoderTokenizerFast
+
+## DPRQuestionEncoderTokenizer
+
+[[autodoc]] DPRQuestionEncoderTokenizer
+
+## DPRQuestionEncoderTokenizerFast
+
+[[autodoc]] DPRQuestionEncoderTokenizerFast
+
+## DPRReaderTokenizer
+
+[[autodoc]] DPRReaderTokenizer
+
+## DPRReaderTokenizerFast
+
+[[autodoc]] DPRReaderTokenizerFast
+
+## DPR specific outputs
+
+[[autodoc]] models.dpr.modeling_dpr.DPRContextEncoderOutput
+
+[[autodoc]] models.dpr.modeling_dpr.DPRQuestionEncoderOutput
+
+[[autodoc]] models.dpr.modeling_dpr.DPRReaderOutput
+
+
+
+
+## DPRContextEncoder
+
+[[autodoc]] DPRContextEncoder
+ - forward
+
+## DPRQuestionEncoder
+
+[[autodoc]] DPRQuestionEncoder
+ - forward
+
+## DPRReader
+
+[[autodoc]] DPRReader
+ - forward
+
+
+
+
+## TFDPRContextEncoder
+
+[[autodoc]] TFDPRContextEncoder
+ - call
+
+## TFDPRQuestionEncoder
+
+[[autodoc]] TFDPRQuestionEncoder
+ - call
+
+## TFDPRReader
+
+[[autodoc]] TFDPRReader
+ - call
+
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dpt.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dpt.md
new file mode 100644
index 0000000000000000000000000000000000000000..d4415dac8395cdb7e19b6b8b82a72206578e77e4
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dpt.md
@@ -0,0 +1,103 @@
+
+*This model was released on 2021-03-24 and added to Hugging Face Transformers on 2022-03-28.*
+
+# DPT
+
+
+
+
+
+
+
+## Overview
+
+The DPT model was proposed in [Vision Transformers for Dense Prediction](https://huggingface.co/papers/2103.13413) by René Ranftl, Alexey Bochkovskiy, Vladlen Koltun.
+DPT is a model that leverages the [Vision Transformer (ViT)](vit) as backbone for dense prediction tasks like semantic segmentation and depth estimation.
+
+The abstract from the paper is the following:
+
+*We introduce dense vision transformers, an architecture that leverages vision transformers in place of convolutional networks as a backbone for dense prediction tasks. We assemble tokens from various stages of the vision transformer into image-like representations at various resolutions and progressively combine them into full-resolution predictions using a convolutional decoder. The transformer backbone processes representations at a constant and relatively high resolution and has a global receptive field at every stage. These properties allow the dense vision transformer to provide finer-grained and more globally coherent predictions when compared to fully-convolutional networks. Our experiments show that this architecture yields substantial improvements on dense prediction tasks, especially when a large amount of training data is available. For monocular depth estimation, we observe an improvement of up to 28% in relative performance when compared to a state-of-the-art fully-convolutional network. When applied to semantic segmentation, dense vision transformers set a new state of the art on ADE20K with 49.02% mIoU. We further show that the architecture can be fine-tuned on smaller datasets such as NYUv2, KITTI, and Pascal Context where it also sets the new state of the art.*
+
+
+
+ DPT architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found [here](https://github.com/isl-org/DPT).
+
+## Usage tips
+
+DPT is compatible with the [`AutoBackbone`] class. This allows to use the DPT framework with various computer vision backbones available in the library, such as [`VitDetBackbone`] or [`Dinov2Backbone`]. One can create it as follows:
+
+```python
+from transformers import Dinov2Config, DPTConfig, DPTForDepthEstimation
+
+# initialize with a Transformer-based backbone such as DINOv2
+# in that case, we also specify `reshape_hidden_states=False` to get feature maps of shape (batch_size, num_channels, height, width)
+backbone_config = Dinov2Config.from_pretrained("facebook/dinov2-base", out_features=["stage1", "stage2", "stage3", "stage4"], reshape_hidden_states=False)
+
+config = DPTConfig(backbone_config=backbone_config)
+model = DPTForDepthEstimation(config=config)
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with DPT.
+
+- Demo notebooks for [`DPTForDepthEstimation`] can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/DPT).
+
+- [Semantic segmentation task guide](../tasks/semantic_segmentation)
+- [Monocular depth estimation task guide](../tasks/monocular_depth_estimation)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## DPTConfig
+
+[[autodoc]] DPTConfig
+
+## DPTFeatureExtractor
+
+[[autodoc]] DPTFeatureExtractor
+ - __call__
+ - post_process_semantic_segmentation
+
+## DPTImageProcessor
+
+[[autodoc]] DPTImageProcessor
+ - preprocess
+
+## DPTImageProcessorFast
+
+[[autodoc]] DPTImageProcessorFast
+ - preprocess
+ - post_process_semantic_segmentation
+ - post_process_depth_estimation
+
+## DPTModel
+
+[[autodoc]] DPTModel
+ - forward
+
+## DPTForDepthEstimation
+
+[[autodoc]] DPTForDepthEstimation
+ - forward
+
+## DPTForSemanticSegmentation
+
+[[autodoc]] DPTForSemanticSegmentation
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/efficientformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/efficientformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..320834a439b8dd47de86b7ca6529b3e22b87ac71
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/efficientformer.md
@@ -0,0 +1,110 @@
+
+*This model was released on 2022-06-02 and added to Hugging Face Transformers on 2023-06-20.*
+
+# EfficientFormer
+
+
+
+
+
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The EfficientFormer model was proposed in [EfficientFormer: Vision Transformers at MobileNet Speed](https://huggingface.co/papers/2206.01191)
+by Yanyu Li, Geng Yuan, Yang Wen, Eric Hu, Georgios Evangelidis, Sergey Tulyakov, Yanzhi Wang, Jian Ren. EfficientFormer proposes a
+dimension-consistent pure transformer that can be run on mobile devices for dense prediction tasks like image classification, object
+detection and semantic segmentation.
+
+The abstract from the paper is the following:
+
+*Vision Transformers (ViT) have shown rapid progress in computer vision tasks, achieving promising results on various benchmarks.
+However, due to the massive number of parameters and model design, e.g., attention mechanism, ViT-based models are generally
+times slower than lightweight convolutional networks. Therefore, the deployment of ViT for real-time applications is particularly
+challenging, especially on resource-constrained hardware such as mobile devices. Recent efforts try to reduce the computation
+complexity of ViT through network architecture search or hybrid design with MobileNet block, yet the inference speed is still
+unsatisfactory. This leads to an important question: can transformers run as fast as MobileNet while obtaining high performance?
+To answer this, we first revisit the network architecture and operators used in ViT-based models and identify inefficient designs.
+Then we introduce a dimension-consistent pure transformer (without MobileNet blocks) as a design paradigm.
+Finally, we perform latency-driven slimming to get a series of final models dubbed EfficientFormer.
+Extensive experiments show the superiority of EfficientFormer in performance and speed on mobile devices.
+Our fastest model, EfficientFormer-L1, achieves 79.2% top-1 accuracy on ImageNet-1K with only 1.6 ms inference latency on
+iPhone 12 (compiled with CoreML), which { runs as fast as MobileNetV2×1.4 (1.6 ms, 74.7% top-1),} and our largest model,
+EfficientFormer-L7, obtains 83.3% accuracy with only 7.0 ms latency. Our work proves that properly designed transformers can
+reach extremely low latency on mobile devices while maintaining high performance.*
+
+This model was contributed by [novice03](https://huggingface.co/novice03) and [Bearnardd](https://huggingface.co/Bearnardd).
+The original code can be found [here](https://github.com/snap-research/EfficientFormer). The TensorFlow version of this model was added by [D-Roberts](https://huggingface.co/D-Roberts).
+
+## Documentation resources
+
+- [Image classification task guide](../tasks/image_classification)
+
+## EfficientFormerConfig
+
+[[autodoc]] EfficientFormerConfig
+
+## EfficientFormerImageProcessor
+
+[[autodoc]] EfficientFormerImageProcessor
+ - preprocess
+
+
+
+
+## EfficientFormerModel
+
+[[autodoc]] EfficientFormerModel
+ - forward
+
+## EfficientFormerForImageClassification
+
+[[autodoc]] EfficientFormerForImageClassification
+ - forward
+
+## EfficientFormerForImageClassificationWithTeacher
+
+[[autodoc]] EfficientFormerForImageClassificationWithTeacher
+ - forward
+
+
+
+
+## TFEfficientFormerModel
+
+[[autodoc]] TFEfficientFormerModel
+ - call
+
+## TFEfficientFormerForImageClassification
+
+[[autodoc]] TFEfficientFormerForImageClassification
+ - call
+
+## TFEfficientFormerForImageClassificationWithTeacher
+
+[[autodoc]] TFEfficientFormerForImageClassificationWithTeacher
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/efficientloftr.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/efficientloftr.md
new file mode 100644
index 0000000000000000000000000000000000000000..465961864c947d833a358ce015c95a17ce6f8d00
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/efficientloftr.md
@@ -0,0 +1,150 @@
+
+*This model was released on 2024-03-07 and added to Hugging Face Transformers on 2025-07-22.*
+
+
+
+
+
+
+
+# EfficientLoFTR
+
+[EfficientLoFTR](https://huggingface.co/papers/2403.04765) is an efficient detector-free local feature matching method that produces semi-dense matches across images with sparse-like speed. It builds upon the original [LoFTR](https://huggingface.co/papers/2104.00680) architecture but introduces significant improvements for both efficiency and accuracy. The key innovation is an aggregated attention mechanism with adaptive token selection that makes the model ~2.5× faster than LoFTR while achieving higher accuracy. EfficientLoFTR can even surpass state-of-the-art efficient sparse matching pipelines like [SuperPoint](./superpoint) + [LightGlue](./lightglue) in terms of speed, making it suitable for large-scale or latency-sensitive applications such as image retrieval and 3D reconstruction.
+
+> [!TIP]
+> This model was contributed by [stevenbucaille](https://huggingface.co/stevenbucaille).
+>
+> Click on the EfficientLoFTR models in the right sidebar for more examples of how to apply EfficientLoFTR to different computer vision tasks.
+
+The example below demonstrates how to match keypoints between two images with the [`AutoModel`] class.
+
+
+
+
+```py
+from transformers import AutoImageProcessor, AutoModelForKeypointMatching
+import torch
+from PIL import Image
+import requests
+
+url_image1 = "https://raw.githubusercontent.com/magicleap/SuperGluePretrainedNetwork/refs/heads/master/assets/phototourism_sample_images/united_states_capitol_98169888_3347710852.jpg"
+image1 = Image.open(requests.get(url_image1, stream=True).raw)
+url_image2 = "https://raw.githubusercontent.com/magicleap/SuperGluePretrainedNetwork/refs/heads/master/assets/phototourism_sample_images/united_states_capitol_26757027_6717084061.jpg"
+image2 = Image.open(requests.get(url_image2, stream=True).raw)
+
+images = [image1, image2]
+
+processor = AutoImageProcessor.from_pretrained("zju-community/efficientloftr")
+model = AutoModelForKeypointMatching.from_pretrained("zju-community/efficientloftr")
+
+inputs = processor(images, return_tensors="pt")
+with torch.no_grad():
+ outputs = model(**inputs)
+
+# Post-process to get keypoints and matches
+image_sizes = [[(image.height, image.width) for image in images]]
+processed_outputs = processor.post_process_keypoint_matching(outputs, image_sizes, threshold=0.2)
+```
+
+
+
+
+## Notes
+
+- EfficientLoFTR is designed for efficiency while maintaining high accuracy. It uses an aggregated attention mechanism with adaptive token selection to reduce computational overhead compared to the original LoFTR.
+
+ ```py
+ from transformers import AutoImageProcessor, AutoModelForKeypointMatching
+ import torch
+ from PIL import Image
+ import requests
+
+ processor = AutoImageProcessor.from_pretrained("zju-community/efficientloftr")
+ model = AutoModelForKeypointMatching.from_pretrained("zju-community/efficientloftr")
+
+ # EfficientLoFTR requires pairs of images
+ images = [image1, image2]
+ inputs = processor(images, return_tensors="pt")
+ outputs = model(**inputs)
+
+ # Extract matching information
+ keypoints = outputs.keypoints # Keypoints in both images
+ matches = outputs.matches # Matching indices
+ matching_scores = outputs.matching_scores # Confidence scores
+ ```
+
+- The model produces semi-dense matches, offering a good balance between the density of matches and computational efficiency. It excels in handling large viewpoint changes and texture-poor scenarios.
+
+- For better visualization and analysis, use the [`~EfficientLoFTRImageProcessor.post_process_keypoint_matching`] method to get matches in a more readable format.
+
+ ```py
+ # Process outputs for visualization
+ image_sizes = [[(image.height, image.width) for image in images]]
+ processed_outputs = processor.post_process_keypoint_matching(outputs, image_sizes, threshold=0.2)
+
+ for i, output in enumerate(processed_outputs):
+ print(f"For the image pair {i}")
+ for keypoint0, keypoint1, matching_score in zip(
+ output["keypoints0"], output["keypoints1"], output["matching_scores"]
+ ):
+ print(f"Keypoint at {keypoint0.numpy()} matches with keypoint at {keypoint1.numpy()} with score {matching_score}")
+ ```
+
+- Visualize the matches between the images using the built-in plotting functionality.
+
+ ```py
+ # Easy visualization using the built-in plotting method
+ visualized_images = processor.visualize_keypoint_matching(images, processed_outputs)
+ ```
+
+- EfficientLoFTR uses a novel two-stage correlation layer that achieves accurate subpixel correspondences, improving upon the original LoFTR's fine correlation module.
+
+
+
+
+
+## Resources
+
+- Refer to the [original EfficientLoFTR repository](https://github.com/zju3dv/EfficientLoFTR) for more examples and implementation details.
+- [EfficientLoFTR project page](https://zju3dv.github.io/efficientloftr/) with interactive demos and additional information.
+
+## EfficientLoFTRConfig
+
+[[autodoc]] EfficientLoFTRConfig
+
+## EfficientLoFTRImageProcessor
+
+[[autodoc]] EfficientLoFTRImageProcessor
+
+- preprocess
+- post_process_keypoint_matching
+- visualize_keypoint_matching
+
+
+
+## EfficientLoFTRModel
+
+[[autodoc]] EfficientLoFTRModel
+
+- forward
+
+## EfficientLoFTRForKeypointMatching
+
+[[autodoc]] EfficientLoFTRForKeypointMatching
+
+- forward
+
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/efficientnet.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/efficientnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..859923126a9d1088ba6ad60f7dd48d5fdd8179eb
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/efficientnet.md
@@ -0,0 +1,61 @@
+
+*This model was released on 2019-05-28 and added to Hugging Face Transformers on 2023-02-20.*
+
+# EfficientNet
+
+
+
+
+
+## Overview
+
+The EfficientNet model was proposed in [EfficientNet: Rethinking Model Scaling for Convolutional Neural Networks](https://huggingface.co/papers/1905.11946)
+by Mingxing Tan and Quoc V. Le. EfficientNets are a family of image classification models, which achieve state-of-the-art accuracy, yet being an order-of-magnitude smaller and faster than previous models.
+
+The abstract from the paper is the following:
+
+*Convolutional Neural Networks (ConvNets) are commonly developed at a fixed resource budget, and then scaled up for better accuracy if more resources are available. In this paper, we systematically study model scaling and identify that carefully balancing network depth, width, and resolution can lead to better performance. Based on this observation, we propose a new scaling method that uniformly scales all dimensions of depth/width/resolution using a simple yet highly effective compound coefficient. We demonstrate the effectiveness of this method on scaling up MobileNets and ResNet.
+To go even further, we use neural architecture search to design a new baseline network and scale it up to obtain a family of models, called EfficientNets, which achieve much better accuracy and efficiency than previous ConvNets. In particular, our EfficientNet-B7 achieves state-of-the-art 84.3% top-1 accuracy on ImageNet, while being 8.4x smaller and 6.1x faster on inference than the best existing ConvNet. Our EfficientNets also transfer well and achieve state-of-the-art accuracy on CIFAR-100 (91.7%), Flowers (98.8%), and 3 other transfer learning datasets, with an order of magnitude fewer parameters.*
+
+This model was contributed by [adirik](https://huggingface.co/adirik).
+The original code can be found [here](https://github.com/tensorflow/tpu/tree/master/models/official/efficientnet).
+
+
+## EfficientNetConfig
+
+[[autodoc]] EfficientNetConfig
+
+## EfficientNetImageProcessor
+
+[[autodoc]] EfficientNetImageProcessor
+ - preprocess
+
+## EfficientNetImageProcessorFast
+
+[[autodoc]] EfficientNetImageProcessorFast
+ - preprocess
+
+## EfficientNetModel
+
+[[autodoc]] EfficientNetModel
+ - forward
+
+## EfficientNetForImageClassification
+
+[[autodoc]] EfficientNetForImageClassification
+ - forward
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/electra.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/electra.md
new file mode 100644
index 0000000000000000000000000000000000000000..074479019dcb0b5f0e754f1a57cec75d62488a00
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/electra.md
@@ -0,0 +1,251 @@
+
+*This model was released on 2020-03-23 and added to Hugging Face Transformers on 2020-11-16.*
+
+
+
+
+
+
+
+
+
+
+# ELECTRA
+
+[ELECTRA](https://huggingface.co/papers/2003.10555) modifies the pretraining objective of traditional masked language models like BERT. Instead of just masking tokens and asking the model to predict them, ELECTRA trains two models, a generator and a discriminator. The generator replaces some tokens with plausible alternatives and the discriminator (the model you'll actually use) learns to detect which tokens are original and which were replaced. This training approach is very efficient and scales to larger models while using considerably less compute.
+
+This approach is super efficient because ELECTRA learns from every single token in the input, not just the masked ones. That's why even the small ELECTRA models can match or outperform much larger models while using way less computing resources.
+
+You can find all the original ELECTRA checkpoints under the [ELECTRA](https://huggingface.co/collections/google/electra-release-64ff6e8b18830fabea30a1ab) release.
+
+> [!TIP]
+> Click on the right sidebar for more examples of how to use ELECTRA for different language tasks like sequence classification, token classification, and question answering.
+
+The example below demonstrates how to classify text with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+classifier = pipeline(
+ task="text-classification",
+ model="bhadresh-savani/electra-base-emotion",
+ torch_dtype=torch.float16,
+ device=0
+)
+classifier("This restaurant has amazing food!")
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "bhadresh-savani/electra-base-emotion",
+)
+model = AutoModelForSequenceClassification.from_pretrained(
+ "bhadresh-savani/electra-base-emotion",
+ torch_dtype=torch.float16
+)
+inputs = tokenizer("ELECTRA is more efficient than BERT", return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs)
+ logits = outputs.logits
+ predicted_class_id = logits.argmax(dim=-1).item()
+ predicted_label = model.config.id2label[predicted_class_id]
+print(f"Predicted label: {predicted_label}")
+```
+
+
+
+
+```bash
+echo -e "This restaurant has amazing food." | transformers run --task text-classification --model bhadresh-savani/electra-base-emotion --device 0
+```
+
+
+
+
+## Notes
+
+- ELECTRA consists of two transformer models, a generator (G) and a discriminator (D). For most downstream tasks, use the discriminator model (as indicated by `*-discriminator` in the name) rather than the generator.
+- ELECTRA comes in three sizes: small (14M parameters), base (110M parameters), and large (335M parameters).
+- ELECTRA can use a smaller embedding size than the hidden size for efficiency. When `embedding_size` is smaller than `hidden_size` in the configuration, a projection layer connects them.
+- When using batched inputs with padding, make sure to use attention masks to prevent the model from attending to padding tokens.
+
+ ```py
+ # Example of properly handling padding with attention masks
+ inputs = tokenizer(["Short text", "This is a much longer text that needs padding"],
+ padding=True,
+ return_tensors="pt")
+ outputs = model(**inputs) # automatically uses the attention_mask
+ ```
+
+- When using the discriminator for a downstream task, you can load it into any of the ELECTRA model classes ([`ElectraForSequenceClassification`], [`ElectraForTokenClassification`], etc.).
+
+## ElectraConfig
+
+[[autodoc]] ElectraConfig
+
+## ElectraTokenizer
+
+[[autodoc]] ElectraTokenizer
+
+## ElectraTokenizerFast
+
+[[autodoc]] ElectraTokenizerFast
+
+## Electra specific outputs
+
+[[autodoc]] models.electra.modeling_electra.ElectraForPreTrainingOutput
+
+[[autodoc]] models.electra.modeling_tf_electra.TFElectraForPreTrainingOutput
+
+
+
+
+## ElectraModel
+
+[[autodoc]] ElectraModel
+ - forward
+
+## ElectraForPreTraining
+
+[[autodoc]] ElectraForPreTraining
+ - forward
+
+## ElectraForCausalLM
+
+[[autodoc]] ElectraForCausalLM
+ - forward
+
+## ElectraForMaskedLM
+
+[[autodoc]] ElectraForMaskedLM
+ - forward
+
+## ElectraForSequenceClassification
+
+[[autodoc]] ElectraForSequenceClassification
+ - forward
+
+## ElectraForMultipleChoice
+
+[[autodoc]] ElectraForMultipleChoice
+ - forward
+
+## ElectraForTokenClassification
+
+[[autodoc]] ElectraForTokenClassification
+ - forward
+
+## ElectraForQuestionAnswering
+
+[[autodoc]] ElectraForQuestionAnswering
+ - forward
+
+
+
+
+## TFElectraModel
+
+[[autodoc]] TFElectraModel
+ - call
+
+## TFElectraForPreTraining
+
+[[autodoc]] TFElectraForPreTraining
+ - call
+
+## TFElectraForMaskedLM
+
+[[autodoc]] TFElectraForMaskedLM
+ - call
+
+## TFElectraForSequenceClassification
+
+[[autodoc]] TFElectraForSequenceClassification
+ - call
+
+## TFElectraForMultipleChoice
+
+[[autodoc]] TFElectraForMultipleChoice
+ - call
+
+## TFElectraForTokenClassification
+
+[[autodoc]] TFElectraForTokenClassification
+ - call
+
+## TFElectraForQuestionAnswering
+
+[[autodoc]] TFElectraForQuestionAnswering
+ - call
+
+
+
+
+## FlaxElectraModel
+
+[[autodoc]] FlaxElectraModel
+ - __call__
+
+## FlaxElectraForPreTraining
+
+[[autodoc]] FlaxElectraForPreTraining
+ - __call__
+
+## FlaxElectraForCausalLM
+
+[[autodoc]] FlaxElectraForCausalLM
+ - __call__
+
+## FlaxElectraForMaskedLM
+
+[[autodoc]] FlaxElectraForMaskedLM
+ - __call__
+
+## FlaxElectraForSequenceClassification
+
+[[autodoc]] FlaxElectraForSequenceClassification
+ - __call__
+
+## FlaxElectraForMultipleChoice
+
+[[autodoc]] FlaxElectraForMultipleChoice
+ - __call__
+
+## FlaxElectraForTokenClassification
+
+[[autodoc]] FlaxElectraForTokenClassification
+ - __call__
+
+## FlaxElectraForQuestionAnswering
+
+[[autodoc]] FlaxElectraForQuestionAnswering
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/emu3.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/emu3.md
new file mode 100644
index 0000000000000000000000000000000000000000..bac73a47ab75dced23bd01a0c5a8f199e70a1e04
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/emu3.md
@@ -0,0 +1,190 @@
+
+*This model was released on 2024-09-27 and added to Hugging Face Transformers on 2025-01-10.*
+
+# Emu3
+
+
+
+
+
+
+
+## Overview
+
+The Emu3 model was proposed in [Emu3: Next-Token Prediction is All You Need](https://huggingface.co/papers/2409.18869) by Xinlong Wang, Xiaosong Zhang, Zhengxiong Luo, Quan Sun, Yufeng Cui, Jinsheng Wang, Fan Zhang, Yueze Wang, Zhen Li, Qiying Yu, Yingli Zhao, Yulong Ao, Xuebin Min, Tao Li, Boya Wu, Bo Zhao, Bowen Zhang, Liangdong Wang, Guang Liu, Zheqi He, Xi Yang, Jingjing Liu, Yonghua Lin, Tiejun Huang, Zhongyuan Wang.
+
+Emu3 is a multimodal LLM that uses vector quantization to tokenize images into discrete tokens. Discretized image tokens are later fused with text token ids for image and text generation. The model can additionally generate images by predicting image token ids.
+
+
+The abstract from the paper is the following:
+
+*While next-token prediction is considered a promising path towards artificial general intelligence, it has struggled to excel in multimodal tasks, which are still dominated by diffusion models (e.g., Stable Diffusion) and compositional approaches (e.g., CLIP combined with LLMs). In this paper, we introduce Emu3, a new suite of state-of-the-art multimodal models trained solely with next-token prediction. By tokenizing images, text, and videos into a discrete space, we train a single transformer from scratch on a mixture of multimodal sequences. Emu3 outperforms several well-established task-specific models in both generation and perception tasks, surpassing flagship models such as SDXL and LLaVA-1.6, while eliminating the need for diffusion or compositional architectures. Emu3 is also capable of generating high-fidelity video via predicting the next token in a video sequence. We simplify complex multimodal model designs by converging on a singular focus: tokens, unlocking great potential for scaling both during training and inference. Our results demonstrate that next-token prediction is a promising path towards building general multimodal intelligence beyond language. We open-source key techniques and models to support further research in this direction.*
+
+Tips:
+
+- We advise users to set `processor.tokenizer.padding_side = "left"` before batched generation as it leads to more accurate results.
+
+- Note that the model has been trained with a specific prompt format for chatting. Use `processor.apply_chat_template(my_conversation_dict)` to correctly format your prompts.
+
+- Emu3 has two different checkpoints for image-generation and text-generation, make sure to use the correct checkpoint when loading the model. To generate an image, it is advised to use `prefix_constraints` so that the generated tokens are sampled only from possible image tokens. See more below for usage examples.
+
+> [!TIP]
+> Emu3 implementation in Transformers uses a special image token to indicate where to merge image embeddings. The special image token isn't new and uses one of the reserved tokens: `<|extra_0|>`. You have to add `` to your prompt in the place where the image should be embedded for correct generation.
+
+
+This model was contributed by [RaushanTurganbay](https://huggingface.co/RaushanTurganbay).
+The original code can be found [here](https://github.com/baaivision/Emu3).
+
+
+## Usage example
+
+### Text generation inference
+
+Here's how to load the model and perform inference in half-precision (`torch.bfloat16`) to generate textual output from text or text and image inputs:
+
+```python
+from transformers import Emu3Processor, Emu3ForConditionalGeneration
+import torch
+from PIL import Image
+import requests
+
+processor = Emu3Processor.from_pretrained("BAAI/Emu3-Chat-hf")
+model = Emu3ForConditionalGeneration.from_pretrained("BAAI/Emu3-Chat-hf", torch_dtype=torch.bfloat16, device_map="auto")
+
+# prepare image and text prompt
+url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+image = Image.open(requests.get(url, stream=True).raw)
+prompt = "What do you see in this image?"
+
+inputs = processor(images=image, text=prompt, return_tensors="pt").to(model.device, dtype=torch.bfloat16)
+
+# autoregressively complete prompt
+output = model.generate(**inputs, max_new_tokens=50)
+print(processor.decode(output[0], skip_special_tokens=True))
+```
+
+### Image generation inference
+
+Emu3 can also generate images from textual input. Here is how you can do it:
+
+```python
+processor = Emu3Processor.from_pretrained("BAAI/Emu3-Gen-hf")
+model = Emu3ForConditionalGeneration.from_pretrained("BAAI/Emu3-Gen-hf", torch_dtype="bfloat16", device_map="auto", attn_implementation="flash_attention_2")
+
+
+inputs = processor(
+ text=["a portrait of young girl. masterpiece, film grained, best quality.", "a dog running under the rain"],
+ padding=True,
+ return_tensors="pt",
+ return_for_image_generation=True,
+)
+inputs = inputs.to(device=model.device, dtype=torch.bfloat16)
+
+neg_prompt = "lowres, bad anatomy, bad hands, text, error, missing fingers, extra digit, fewer digits, cropped, worst quality, low quality, normal quality, jpeg artifacts, signature, watermark, username, blurry."
+neg_inputs = processor(text=[neg_prompt] * 2, return_tensors="pt").to(device=model.device)
+
+image_sizes = inputs.pop("image_sizes")
+HEIGHT, WIDTH = image_sizes[0]
+VISUAL_TOKENS = model.vocabulary_mapping.image_tokens
+
+def prefix_allowed_tokens_fn(batch_id, input_ids):
+ height, width = HEIGHT, WIDTH
+ visual_tokens = VISUAL_TOKENS
+ image_wrapper_token_id = torch.tensor([processor.tokenizer.image_wrapper_token_id], device=model.device)
+ eoi_token_id = torch.tensor([processor.tokenizer.eoi_token_id], device=model.device)
+ eos_token_id = torch.tensor([processor.tokenizer.eos_token_id], device=model.device)
+ pad_token_id = torch.tensor([processor.tokenizer.pad_token_id], device=model.device)
+ eof_token_id = torch.tensor([processor.tokenizer.eof_token_id], device=model.device)
+ eol_token_id = processor.tokenizer.encode("<|extra_200|>", return_tensors="pt")[0]
+
+ position = torch.nonzero(input_ids == image_wrapper_token_id, as_tuple=True)[0][0]
+ offset = input_ids.shape[0] - position
+ if offset % (width + 1) == 0:
+ return (eol_token_id, )
+ elif offset == (width + 1) * height + 1:
+ return (eof_token_id, )
+ elif offset == (width + 1) * height + 2:
+ return (eoi_token_id, )
+ elif offset == (width + 1) * height + 3:
+ return (eos_token_id, )
+ elif offset > (width + 1) * height + 3:
+ return (pad_token_id, )
+ else:
+ return visual_tokens
+
+
+out = model.generate(
+ **inputs,
+ max_new_tokens=50_000, # make sure to have enough tokens for one image
+ prefix_allowed_tokens_fn=prefix_allowed_tokens_fn,
+ return_dict_in_generate=True,
+ negative_prompt_ids=neg_inputs.input_ids, # indicate for Classifier-Free Guidance
+ negative_prompt_attention_mask=neg_inputs.attention_mask,
+)
+
+image = model.decode_image_tokens(out.sequences[:, inputs.input_ids.shape[1]: ], height=HEIGHT, width=WIDTH)
+images = processor.postprocess(list(image.float()), return_tensors="PIL.Image.Image") # internally we convert to np but it's not supported in bf16 precision
+for i, image in enumerate(images['pixel_values']):
+ image.save(f"result{i}.png")
+
+```
+
+
+## Emu3Config
+
+[[autodoc]] Emu3Config
+
+## Emu3VQVAEConfig
+
+[[autodoc]] Emu3VQVAEConfig
+
+## Emu3TextConfig
+
+[[autodoc]] Emu3TextConfig
+
+## Emu3Processor
+
+[[autodoc]] Emu3Processor
+
+## Emu3ImageProcessor
+
+[[autodoc]] Emu3ImageProcessor
+ - preprocess
+
+## Emu3VQVAE
+
+[[autodoc]] Emu3VQVAE
+ - forward
+
+## Emu3TextModel
+
+[[autodoc]] Emu3TextModel
+ - forward
+
+## Emu3Model
+
+[[autodoc]] Emu3Model
+
+## Emu3ForCausalLM
+
+[[autodoc]] Emu3ForCausalLM
+ - forward
+
+## Emu3ForConditionalGeneration
+
+[[autodoc]] Emu3ForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/encodec.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/encodec.md
new file mode 100644
index 0000000000000000000000000000000000000000..890991730391e9e3cc244cff2a20b1170721b613
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/encodec.md
@@ -0,0 +1,71 @@
+
+*This model was released on 2022-10-24 and added to Hugging Face Transformers on 2023-06-14.*
+
+# EnCodec
+
+
+
+
+
+## Overview
+
+The EnCodec neural codec model was proposed in [High Fidelity Neural Audio Compression](https://huggingface.co/papers/2210.13438) by Alexandre Défossez, Jade Copet, Gabriel Synnaeve, Yossi Adi.
+
+The abstract from the paper is the following:
+
+*We introduce a state-of-the-art real-time, high-fidelity, audio codec leveraging neural networks. It consists in a streaming encoder-decoder architecture with quantized latent space trained in an end-to-end fashion. We simplify and speed-up the training by using a single multiscale spectrogram adversary that efficiently reduces artifacts and produce high-quality samples. We introduce a novel loss balancer mechanism to stabilize training: the weight of a loss now defines the fraction of the overall gradient it should represent, thus decoupling the choice of this hyper-parameter from the typical scale of the loss. Finally, we study how lightweight Transformer models can be used to further compress the obtained representation by up to 40%, while staying faster than real time. We provide a detailed description of the key design choices of the proposed model including: training objective, architectural changes and a study of various perceptual loss functions. We present an extensive subjective evaluation (MUSHRA tests) together with an ablation study for a range of bandwidths and audio domains, including speech, noisy-reverberant speech, and music. Our approach is superior to the baselines methods across all evaluated settings, considering both 24 kHz monophonic and 48 kHz stereophonic audio.*
+
+This model was contributed by [Matthijs](https://huggingface.co/Matthijs), [Patrick Von Platen](https://huggingface.co/patrickvonplaten) and [Arthur Zucker](https://huggingface.co/ArthurZ).
+The original code can be found [here](https://github.com/facebookresearch/encodec).
+
+## Usage example
+
+Here is a quick example of how to encode and decode an audio using this model:
+
+```python
+>>> from datasets import load_dataset, Audio
+>>> from transformers import EncodecModel, AutoProcessor
+>>> librispeech_dummy = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+
+>>> model = EncodecModel.from_pretrained("facebook/encodec_24khz")
+>>> processor = AutoProcessor.from_pretrained("facebook/encodec_24khz")
+>>> librispeech_dummy = librispeech_dummy.cast_column("audio", Audio(sampling_rate=processor.sampling_rate))
+>>> audio_sample = librispeech_dummy[-1]["audio"]["array"]
+>>> inputs = processor(raw_audio=audio_sample, sampling_rate=processor.sampling_rate, return_tensors="pt")
+
+>>> encoder_outputs = model.encode(inputs["input_values"], inputs["padding_mask"])
+>>> # `encoder_outputs.audio_codes` contains discrete codes
+>>> audio_values = model.decode(**encoder_outputs, padding_mask=inputs["padding_mask"])[0]
+>>> # or the equivalent with a forward pass
+>>> audio_values = model(inputs["input_values"], inputs["padding_mask"]).audio_values
+```
+
+## EncodecConfig
+
+[[autodoc]] EncodecConfig
+
+## EncodecFeatureExtractor
+
+[[autodoc]] EncodecFeatureExtractor
+ - __call__
+
+## EncodecModel
+
+[[autodoc]] EncodecModel
+ - decode
+ - encode
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/encoder-decoder.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/encoder-decoder.md
new file mode 100644
index 0000000000000000000000000000000000000000..96a3874c3ca532509a7c222afa2adcb4ae1eb746
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/encoder-decoder.md
@@ -0,0 +1,193 @@
+
+*This model was released on 2017-06-12 and added to Hugging Face Transformers on 2020-11-16.*
+
+
+
+
+
+
+
+
+
+
+# Encoder Decoder Models
+
+[`EncoderDecoderModel`](https://huggingface.co/papers/1706.03762) initializes a sequence-to-sequence model with any pretrained autoencoder and pretrained autoregressive model. It is effective for sequence generation tasks as demonstrated in [Text Summarization with Pretrained Encoders](https://huggingface.co/papers/1908.08345) which uses [`BertModel`] as the encoder and decoder.
+
+> [!TIP]
+> This model was contributed by [thomwolf](https://huggingface.co/thomwolf) and the TensorFlow/Flax version by [ydshieh](https://huggingface.co/ydshieh).
+>
+> Click on the Encoder Decoder models in the right sidebar for more examples of how to apply Encoder Decoder to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```python
+from transformers import pipeline
+
+summarizer = pipeline(
+ "summarization",
+ model="patrickvonplaten/bert2bert-cnn_dailymail-fp16",
+ device=0
+)
+
+text = "Plants create energy through a process known as photosynthesis. This involves capturing sunlight and converting carbon dioxide and water into glucose and oxygen."
+print(summarizer(text))
+```
+
+
+
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("patrickvonplaten/bert2bert-cnn_dailymail-fp16")
+model = AutoModelForCausalLM.from_pretrained("patrickvonplaten/bert2bert-cnn_dailymail-fp16", torch_dtype=torch.bfloat16, device_map="auto",attn_implementation="sdpa")
+
+text = "Plants create energy through a process known as photosynthesis. This involves capturing sunlight and converting carbon dioxide and water into glucose and oxygen."
+
+inputs = tokenizer(text, return_tensors="pt", truncation=True, padding=True).to(model.device)
+
+summary = model.generate(**inputs, max_length=60, num_beams=4, early_stopping=True)
+print(tokenizer.decode(summary[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+echo -e "Plants create energy through a process known as photosynthesis. This involves capturing sunlight and converting carbon dioxide and water into glucose and oxygen." | transformers-cli run --task summarization --model "patrickvonplaten/bert2bert-cnn_dailymail-fp16" --device 0
+```
+
+
+
+
+## Notes
+
+- [`EncoderDecoderModel`] can be initialized using any pretrained encoder and decoder. But depending on the decoder architecture, the cross-attention layers may be randomly initialized.
+
+These models require downstream fine-tuning, as discussed in this [blog post](https://huggingface.co/blog/warm-starting-encoder-decoder). Use [`~EncoderDecoderModel.from_encoder_decoder_pretrained`] to combine encoder and decoder checkpoints.
+
+```python
+from transformers import EncoderDecoderModel, BertTokenizer
+
+tokenizer = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+model = EncoderDecoderModel.from_encoder_decoder_pretrained(
+ "google-bert/bert-base-uncased",
+ "google-bert/bert-base-uncased"
+)
+```
+
+- Encoder Decoder models can be fine-tuned like BART, T5 or any other encoder-decoder model. Only 2 inputs are required to compute a loss, `input_ids` and `labels`. Refer to this [notebook](https://colab.research.google.com/drive/1WIk2bxglElfZewOHboPFNj8H44_VAyKE?usp=sharing#scrollTo=ZwQIEhKOrJpl) for a more detailed training example.
+
+```python
+>>> from transformers import BertTokenizer, EncoderDecoderModel
+
+>>> tokenizer = BertTokenizer.from_pretrained("google-bert/bert-base-uncased")
+>>> model = EncoderDecoderModel.from_encoder_decoder_pretrained("google-bert/bert-base-uncased", "google-bert/bert-base-uncased")
+
+>>> model.config.decoder_start_token_id = tokenizer.cls_token_id
+>>> model.config.pad_token_id = tokenizer.pad_token_id
+
+>>> input_ids = tokenizer(
+... "The tower is 324 metres (1,063 ft) tall, about the same height as an 81-storey building, and the tallest structure in Paris. Its base is square, measuring 125 metres (410 ft) on each side.During its construction, the Eiffel Tower surpassed the Washington Monument to become the tallest man-made structure in the world, a title it held for 41 years until the Chrysler Building in New York City was finished in 1930. It was the first structure to reach a height of 300 metres. Due to the addition of a broadcasting aerial at the top of the tower in 1957, it is now taller than the Chrysler Building by 5.2 metres (17 ft).Excluding transmitters, the Eiffel Tower is the second tallest free-standing structure in France after the Millau Viaduct.",
+... return_tensors="pt",
+... ).input_ids
+
+>>> labels = tokenizer(
+... "the eiffel tower surpassed the washington monument to become the tallest structure in the world. it was the first structure to reach a height of 300 metres in paris in 1930. it is now taller than the chrysler building by 5. 2 metres ( 17 ft ) and is the second tallest free - standing structure in paris.",
+... return_tensors="pt",
+... ).input_ids
+
+>>> # the forward function automatically creates the correct decoder_input_ids
+>>> loss = model(input_ids=input_ids, labels=labels).loss
+```
+
+- [`EncoderDecoderModel`] can be randomly initialized from an encoder and a decoder config as shown below.
+
+```python
+>>> from transformers import BertConfig, EncoderDecoderConfig, EncoderDecoderModel
+
+>>> config_encoder = BertConfig()
+>>> config_decoder = BertConfig()
+
+>>> config = EncoderDecoderConfig.from_encoder_decoder_configs(config_encoder, config_decoder)
+>>> model = EncoderDecoderModel(config=config)
+```
+
+- The Encoder Decoder Model can also be used for translation as shown below.
+
+```python
+from transformers import AutoTokenizer, EncoderDecoderModel
+
+# Load a pre-trained translation model
+model_name = "google/bert2bert_L-24_wmt_en_de"
+tokenizer = AutoTokenizer.from_pretrained(model_name, pad_token="", eos_token="", bos_token="")
+model = EncoderDecoderModel.from_pretrained(model_name)
+
+# Input sentence to translate
+input_text = "Plants create energy through a process known as"
+
+# Encode the input text
+inputs = tokenizer(input_text, return_tensors="pt", add_special_tokens=False).input_ids
+
+# Generate the translated output
+outputs = model.generate(inputs)[0]
+
+# Decode the output tokens to get the translated sentence
+translated_text = tokenizer.decode(outputs, skip_special_tokens=True)
+
+print("Translated text:", translated_text)
+```
+
+## EncoderDecoderConfig
+
+[[autodoc]] EncoderDecoderConfig
+
+
+
+
+## EncoderDecoderModel
+
+[[autodoc]] EncoderDecoderModel
+ - forward
+ - from_encoder_decoder_pretrained
+
+
+
+
+## TFEncoderDecoderModel
+
+[[autodoc]] TFEncoderDecoderModel
+ - call
+ - from_encoder_decoder_pretrained
+
+
+
+
+## FlaxEncoderDecoderModel
+
+[[autodoc]] FlaxEncoderDecoderModel
+ - __call__
+ - from_encoder_decoder_pretrained
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/eomt.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/eomt.md
new file mode 100644
index 0000000000000000000000000000000000000000..754b88e2c3307f5a3856a24ecf0d0fdb83e98971
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/eomt.md
@@ -0,0 +1,211 @@
+
+*This model was released on 2025-03-24 and added to Hugging Face Transformers on 2025-06-27.*
+
+# EoMT
+
+
+
+
+
+## Overview
+
+[The Encoder-only Mask Transformer]((https://www.tue-mps.org/eomt)) (EoMT) model was introduced in the CVPR 2025 Highlight Paper *[Your ViT is Secretly an Image Segmentation Model](https://huggingface.co/papers/2503.19108)* by Tommie Kerssies, Niccolò Cavagnero, Alexander Hermans, Narges Norouzi, Giuseppe Averta, Bastian Leibe, Gijs Dubbelman, and Daan de Geus.
+EoMT reveals Vision Transformers can perform image segmentation efficiently without task-specific components.
+
+The abstract from the paper is the following:
+
+*Vision Transformers (ViTs) have shown remarkable performance and scalability across various computer vision tasks. To apply single-scale ViTs to image segmentation, existing methods adopt a convolutional adapter to generate multi-scale features, a pixel decoder to fuse these features, and a Transformer decoder that uses the fused features to make predictions. In this paper, we show that the inductive biases introduced by these task-specific components can instead be learned by the ViT itself, given sufficiently large models and extensive pre-training. Based on these findings, we introduce the Encoder-only Mask Transformer (EoMT), which repurposes the plain ViT architecture to conduct image segmentation. With large-scale models and pre-training, EoMT obtains a segmentation accuracy similar to state-of-the-art models that use task-specific components. At the same time, EoMT is significantly faster than these methods due to its architectural simplicity, e.g., up to 4x faster with ViT-L. Across a range of model sizes, EoMT demonstrates an optimal balance between segmentation accuracy and prediction speed, suggesting that compute resources are better spent on scaling the ViT itself rather than adding architectural complexity.*
+
+This model was contributed by [Yaswanth Gali](https://huggingface.co/yaswanthgali).
+The original code can be found [here](https://github.com/tue-mps/eomt).
+
+## Architecture Info
+
+The `EoMT` model uses a DINOv2-pretrained Vision Transformer with **register tokens** as its backbone. EoMT simplifies the segmentation pipeline by relying solely on the encoder, eliminating the need for task-specific decoders commonly used in prior approaches.
+
+Architecturally, EoMT introduces a small set of **learned queries** and a lightweight **mask prediction module**. These queries are injected into the final encoder blocks, enabling **joint attention** between image patches and object queries. During training, **masked attention** is applied to constrain each query to focus on its corresponding region—effectively mimicking cross-attention. This constraint is gradually phased out via a **mask annealing strategy**, allowing for **efficient, decoder-free inference** without compromising segmentation performance.
+
+
+
+
+
+
+The model supports semantic, instance, and panoptic segmentation using a unified architecture and task-specific post-processing.
+
+## Usage Examples
+
+Use the Hugging Face implementation of EoMT for inference with pre-trained models.
+
+### Semantic Segmentation
+
+The EoMT model performs semantic segmentation using sliding-window inference. The input image is resized such that the shorter side matches the target input size, then it is split into overlapping crops. Each crop is then passed through the model. After inference, the predicted logits from each crop are stitched back together and rescaled to the original image size to get the final segmentation mask.
+
+> **Note:**
+> If you want to use a custom target size for **semantic segmentation**, specify it in the following format:
+> `{"shortest_edge": 512}`
+> Notice that `longest_edge` is not provided here — this is intentional. For semantic segmentation, images are typically **scaled so that the shortest edge is greater than or equal to the target size** hence longest_edge is not necessary.
+
+```python
+import matplotlib.pyplot as plt
+import requests
+import torch
+from PIL import Image
+
+from transformers import EomtForUniversalSegmentation, AutoImageProcessor
+
+
+model_id = "tue-mps/ade20k_semantic_eomt_large_512"
+processor = AutoImageProcessor.from_pretrained(model_id)
+model = EomtForUniversalSegmentation.from_pretrained(model_id)
+
+image = Image.open(requests.get("http://images.cocodataset.org/val2017/000000039769.jpg", stream=True).raw)
+
+inputs = processor(
+ images=image,
+ return_tensors="pt",
+)
+
+with torch.inference_mode():
+ outputs = model(**inputs)
+
+# Prepare the original image size in the format (height, width)
+target_sizes = [(image.height, image.width)]
+
+# Post-process the model outputs to get final segmentation prediction
+preds = processor.post_process_semantic_segmentation(
+ outputs,
+ target_sizes=target_sizes,
+)
+
+# Visualize the segmentation mask
+plt.imshow(preds[0])
+plt.axis("off")
+plt.title("Semantic Segmentation")
+plt.show()
+```
+
+### Instance Segmentation
+
+The EoMT model performs instance segmentation using padded inference. The input image is resized so that the longer side matches the target input size, and the shorter side is zero-padded to form a square. The resulting mask and class logits are combined through post-processing (adapted from Mask2Former) to produce a unified instance segmentation map, along with segment metadata like segment id, class labels and confidence scores.
+
+> **Note:**
+> To use a custom target size, specify the size as a dictionary in the following format:
+> `{"shortest_edge": 512, "longest_edge": 512}`
+> For both instance and panoptic segmentation, input images will be **scaled and padded** to this target size.
+
+```python
+import matplotlib.pyplot as plt
+import requests
+import torch
+from PIL import Image
+
+from transformers import EomtForUniversalSegmentation, AutoImageProcessor
+
+
+model_id = "tue-mps/coco_instance_eomt_large_640"
+processor = AutoImageProcessor.from_pretrained(model_id)
+model = EomtForUniversalSegmentation.from_pretrained(model_id)
+
+image = Image.open(requests.get("http://images.cocodataset.org/val2017/000000039769.jpg", stream=True).raw)
+
+inputs = processor(
+ images=image,
+ return_tensors="pt",
+)
+
+with torch.inference_mode():
+ outputs = model(**inputs)
+
+# Prepare the original image size in the format (height, width)
+target_sizes = [(image.height, image.width)]
+
+# Post-process the model outputs to get final segmentation prediction
+preds = processor.post_process_instance_segmentation(
+ outputs,
+ target_sizes=target_sizes,
+)
+
+# Visualize the segmentation mask
+plt.imshow(preds[0]["segmentation"])
+plt.axis("off")
+plt.title("Instance Segmentation")
+plt.show()
+```
+
+### Panoptic Segmentation
+
+The EoMT model performs panoptic segmentation using the same padded inference strategy as in instance segmentation. After padding and normalization, the model predicts both thing (instances) and stuff (amorphous regions) classes. The resulting mask and class logits are combined through post-processing (adapted from Mask2Former) to produce a unified panoptic segmentation map, along with segment metadata like segment id, class labels and confidence scores.
+
+```python
+import matplotlib.pyplot as plt
+import requests
+import torch
+from PIL import Image
+
+from transformers import EomtForUniversalSegmentation, AutoImageProcessor
+
+
+model_id = "tue-mps/coco_panoptic_eomt_large_640"
+processor = AutoImageProcessor.from_pretrained(model_id)
+model = EomtForUniversalSegmentation.from_pretrained(model_id)
+
+image = Image.open(requests.get("http://images.cocodataset.org/val2017/000000039769.jpg", stream=True).raw)
+
+inputs = processor(
+ images=image,
+ return_tensors="pt",
+)
+
+with torch.inference_mode():
+ outputs = model(**inputs)
+
+# Prepare the original image size in the format (height, width)
+target_sizes = [(image.height, image.width)]
+
+# Post-process the model outputs to get final segmentation prediction
+preds = processor.post_process_panoptic_segmentation(
+ outputs,
+ target_sizes=target_sizes,
+)
+
+# Visualize the panoptic segmentation mask
+plt.imshow(preds[0]["segmentation"])
+plt.axis("off")
+plt.title("Panoptic Segmentation")
+plt.show()
+```
+
+## EomtImageProcessor
+
+[[autodoc]] EomtImageProcessor
+ - preprocess
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## EomtImageProcessorFast
+
+[[autodoc]] EomtImageProcessorFast
+ - preprocess
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## EomtConfig
+
+[[autodoc]] EomtConfig
+
+## EomtForUniversalSegmentation
+
+[[autodoc]] EomtForUniversalSegmentation
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ernie.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ernie.md
new file mode 100644
index 0000000000000000000000000000000000000000..8a97ea226f50f35235dbcdd6208bcd8c44c73763
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ernie.md
@@ -0,0 +1,167 @@
+
+*This model was released on 2019-04-19 and added to Hugging Face Transformers on 2022-09-09.*
+
+
+
+
+
+
+
+# ERNIE
+
+[ERNIE1.0](https://huggingface.co/papers/1904.09223), [ERNIE2.0](https://ojs.aaai.org/index.php/AAAI/article/view/6428),
+[ERNIE3.0](https://huggingface.co/papers/2107.02137), [ERNIE-Gram](https://huggingface.co/papers/2010.12148), [ERNIE-health](https://huggingface.co/papers/2110.07244) are a series of powerful models proposed by baidu, especially in Chinese tasks.
+
+ERNIE (Enhanced Representation through kNowledge IntEgration) is designed to learn language representation enhanced by knowledge masking strategies, which includes entity-level masking and phrase-level masking.
+
+Other ERNIE models released by baidu can be found at [Ernie 4.5](./ernie4_5), and [Ernie 4.5 MoE](./ernie4_5_moe).
+
+> [!TIP]
+> This model was contributed by [nghuyong](https://huggingface.co/nghuyong), and the official code can be found in [PaddleNLP](https://github.com/PaddlePaddle/PaddleNLP) (in PaddlePaddle).
+>
+> Click on the ERNIE models in the right sidebar for more examples of how to apply ERNIE to different language tasks.
+
+The example below demonstrates how to predict the `[MASK]` token with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```py
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="fill-mask",
+ model="nghuyong/ernie-3.0-xbase-zh"
+)
+
+pipeline("巴黎是[MASK]国的首都。")
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForMaskedLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "nghuyong/ernie-3.0-xbase-zh",
+)
+model = AutoModelForMaskedLM.from_pretrained(
+ "nghuyong/ernie-3.0-xbase-zh",
+ torch_dtype=torch.float16,
+ device_map="auto"
+)
+inputs = tokenizer("巴黎是[MASK]国的首都。", return_tensors="pt").to("cuda")
+
+with torch.no_grad():
+ outputs = model(**inputs)
+ predictions = outputs.logits
+
+masked_index = torch.where(inputs['input_ids'] == tokenizer.mask_token_id)[1]
+predicted_token_id = predictions[0, masked_index].argmax(dim=-1)
+predicted_token = tokenizer.decode(predicted_token_id)
+
+print(f"The predicted token is: {predicted_token}")
+```
+
+
+
+
+```bash
+echo -e "巴黎是[MASK]国的首都。" | transformers run --task fill-mask --model nghuyong/ernie-3.0-xbase-zh --device 0
+```
+
+
+
+
+## Notes
+
+Model variants are available in different sizes and languages.
+
+| Model Name | Language | Description |
+|:-------------------:|:--------:|:-------------------------------:|
+| ernie-1.0-base-zh | Chinese | Layer:12, Heads:12, Hidden:768 |
+| ernie-2.0-base-en | English | Layer:12, Heads:12, Hidden:768 |
+| ernie-2.0-large-en | English | Layer:24, Heads:16, Hidden:1024 |
+| ernie-3.0-base-zh | Chinese | Layer:12, Heads:12, Hidden:768 |
+| ernie-3.0-medium-zh | Chinese | Layer:6, Heads:12, Hidden:768 |
+| ernie-3.0-mini-zh | Chinese | Layer:6, Heads:12, Hidden:384 |
+| ernie-3.0-micro-zh | Chinese | Layer:4, Heads:12, Hidden:384 |
+| ernie-3.0-nano-zh | Chinese | Layer:4, Heads:12, Hidden:312 |
+| ernie-health-zh | Chinese | Layer:12, Heads:12, Hidden:768 |
+| ernie-gram-zh | Chinese | Layer:12, Heads:12, Hidden:768 |
+
+## Resources
+
+You can find all the supported models from huggingface's model hub: [huggingface.co/nghuyong](https://huggingface.co/nghuyong), and model details from paddle's official
+repo: [PaddleNLP](https://paddlenlp.readthedocs.io/zh/latest/model_zoo/transformers/ERNIE/contents.html)
+and [ERNIE's legacy branch](https://github.com/PaddlePaddle/ERNIE/tree/legacy/develop).
+
+## ErnieConfig
+
+[[autodoc]] ErnieConfig
+ - all
+
+## Ernie specific outputs
+
+[[autodoc]] models.ernie.modeling_ernie.ErnieForPreTrainingOutput
+
+## ErnieModel
+
+[[autodoc]] ErnieModel
+ - forward
+
+## ErnieForPreTraining
+
+[[autodoc]] ErnieForPreTraining
+ - forward
+
+## ErnieForCausalLM
+
+[[autodoc]] ErnieForCausalLM
+ - forward
+
+## ErnieForMaskedLM
+
+[[autodoc]] ErnieForMaskedLM
+ - forward
+
+## ErnieForNextSentencePrediction
+
+[[autodoc]] ErnieForNextSentencePrediction
+ - forward
+
+## ErnieForSequenceClassification
+
+[[autodoc]] ErnieForSequenceClassification
+ - forward
+
+## ErnieForMultipleChoice
+
+[[autodoc]] ErnieForMultipleChoice
+ - forward
+
+## ErnieForTokenClassification
+
+[[autodoc]] ErnieForTokenClassification
+ - forward
+
+## ErnieForQuestionAnswering
+
+[[autodoc]] ErnieForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ernie4_5.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ernie4_5.md
new file mode 100644
index 0000000000000000000000000000000000000000..e0a7e30015ffc06b534f27cec447dca8d7ea11b5
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ernie4_5.md
@@ -0,0 +1,100 @@
+
+*This model was released on 2025-06-30 and added to Hugging Face Transformers on 2025-07-21.*
+
+
+
+
+
+
+
+
+
+
+# Ernie 4.5
+
+## Overview
+
+The Ernie 4.5 model was released in the [Ernie 4.5 Model Family](https://ernie.baidu.com/blog/posts/ernie4.5/) release by baidu.
+This family of models contains multiple different architectures and model sizes. This model in specific targets the base text
+model without mixture of experts (moe) with 0.3B parameters in total. It uses the standard [Llama](./llama) at its core.
+
+Other models from the family can be found at [Ernie 4.5 Moe](./ernie4_5_moe).
+
+
+
+
+
+
+## Usage Tips
+
+### Generate text
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_name = "baidu/ERNIE-4.5-0.3B-PT"
+
+# load the tokenizer and the model
+tokenizer = AutoTokenizer.from_pretrained(model_name)
+model = AutoModelForCausalLM.from_pretrained(
+ model_name,
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+)
+
+# prepare the model input
+inputs = tokenizer("Hey, are you conscious? Can you talk to me?", return_tensors="pt")
+prompt = "Hey, are you conscious? Can you talk to me?"
+messages = [
+ {"role": "user", "content": prompt}
+]
+text = tokenizer.apply_chat_template(
+ messages,
+ tokenize=False,
+ add_generation_prompt=True
+)
+model_inputs = tokenizer([text], add_special_tokens=False, return_tensors="pt").to(model.device)
+
+# conduct text completion
+generated_ids = model.generate(
+ **model_inputs,
+ max_new_tokens=32,
+)
+output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
+
+# decode the generated ids
+generate_text = tokenizer.decode(output_ids, skip_special_tokens=True)
+```
+
+This model was contributed by [Anton Vlasjuk](https://huggingface.co/AntonV).
+The original code can be found [here](https://github.com/PaddlePaddle/ERNIE).
+
+
+## Ernie4_5Config
+
+[[autodoc]] Ernie4_5Config
+
+## Ernie4_5Model
+
+[[autodoc]] Ernie4_5Model
+ - forward
+
+## Ernie4_5ForCausalLM
+
+[[autodoc]] Ernie4_5ForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ernie4_5_moe.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ernie4_5_moe.md
new file mode 100644
index 0000000000000000000000000000000000000000..9df56edd1557f550441b2785d0f8966bd4e54213
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ernie4_5_moe.md
@@ -0,0 +1,184 @@
+
+*This model was released on 2025-06-30 and added to Hugging Face Transformers on 2025-07-21.*
+
+
+
+
+
+
+
+
+
+
+# Ernie 4.5 Moe
+
+## Overview
+
+The Ernie 4.5 Moe model was released in the [Ernie 4.5 Model Family](https://ernie.baidu.com/blog/posts/ernie4.5/) release by baidu.
+This family of models contains multiple different architectures and model sizes. This model in specific targets the base text
+model with mixture of experts (moe) - one with 21B total, 3B active parameters and another one with 300B total, 47B active parameters.
+It uses the standard [Llama](./llama) at its core combined with a specialized MoE based on [Mixtral](./mixtral) with additional shared
+experts.
+
+Other models from the family can be found at [Ernie 4.5](./ernie4_5).
+
+
+
+
+
+
+## Usage Tips
+
+### Generate text
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_name = "baidu/ERNIE-4.5-21B-A3B-PT"
+
+# load the tokenizer and the model
+tokenizer = AutoTokenizer.from_pretrained(model_name)
+model = AutoModelForCausalLM.from_pretrained(
+ model_name,
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+)
+
+# prepare the model input
+inputs = tokenizer("Hey, are you conscious? Can you talk to me?", return_tensors="pt")
+prompt = "Hey, are you conscious? Can you talk to me?"
+messages = [
+ {"role": "user", "content": prompt}
+]
+text = tokenizer.apply_chat_template(
+ messages,
+ tokenize=False,
+ add_generation_prompt=True
+)
+model_inputs = tokenizer([text], add_special_tokens=False, return_tensors="pt").to(model.device)
+
+# conduct text completion
+generated_ids = model.generate(
+ **model_inputs,
+ max_new_tokens=32,
+)
+output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
+
+# decode the generated ids
+generate_text = tokenizer.decode(output_ids, skip_special_tokens=True)
+```
+
+### Distributed Generation with Tensor Parallelism
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_name = "baidu/ERNIE-4.5-21B-A3B-PT"
+
+# load the tokenizer and the model
+tokenizer = AutoTokenizer.from_pretrained(model_name)
+model = AutoModelForCausalLM.from_pretrained(
+ model_name,
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+ tp_plan="auto",
+)
+
+# prepare the model input
+inputs = tokenizer("Hey, are you conscious? Can you talk to me?", return_tensors="pt")
+prompt = "Hey, are you conscious? Can you talk to me?"
+messages = [
+ {"role": "user", "content": prompt}
+]
+text = tokenizer.apply_chat_template(
+ messages,
+ tokenize=False,
+ add_generation_prompt=True
+)
+model_inputs = tokenizer([text], add_special_tokens=False, return_tensors="pt").to(model.device)
+
+# conduct text completion
+generated_ids = model.generate(
+ **model_inputs,
+ max_new_tokens=32,
+)
+output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
+
+# decode the generated ids
+generate_text = tokenizer.decode(output_ids, skip_special_tokens=True)
+```
+
+### Quantization with Bitsandbytes
+
+```python
+import torch
+from transformers import BitsAndBytesConfig, AutoModelForCausalLM, AutoTokenizer
+
+model_name = "baidu/ERNIE-4.5-21B-A3B-PT"
+
+# load the tokenizer and the model
+tokenizer = AutoTokenizer.from_pretrained(model_name)
+model = AutoModelForCausalLM.from_pretrained(
+ model_name,
+ device_map="auto",
+ quantization_config=BitsAndBytesConfig(load_in_4bit=True),
+)
+
+# prepare the model input
+inputs = tokenizer("Hey, are you conscious? Can you talk to me?", return_tensors="pt")
+prompt = "Hey, are you conscious? Can you talk to me?"
+messages = [
+ {"role": "user", "content": prompt}
+]
+text = tokenizer.apply_chat_template(
+ messages,
+ tokenize=False,
+ add_generation_prompt=True
+)
+model_inputs = tokenizer([text], add_special_tokens=False, return_tensors="pt").to(model.device)
+
+# conduct text completion
+generated_ids = model.generate(
+ **model_inputs,
+ max_new_tokens=32,
+)
+output_ids = generated_ids[0][len(model_inputs.input_ids[0]):].tolist()
+
+# decode the generated ids
+generate_text = tokenizer.decode(output_ids, skip_special_tokens=True)
+```
+
+This model was contributed by [Anton Vlasjuk](https://huggingface.co/AntonV).
+The original code can be found [here](https://github.com/PaddlePaddle/ERNIE).
+
+
+## Ernie4_5_MoeConfig
+
+[[autodoc]] Ernie4_5_MoeConfig
+
+## Ernie4_5_MoeModel
+
+[[autodoc]] Ernie4_5_MoeModel
+ - forward
+
+## Ernie4_5_MoeForCausalLM
+
+[[autodoc]] Ernie4_5_MoeForCausalLM
+ - forward
+ - generate
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ernie_m.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ernie_m.md
new file mode 100644
index 0000000000000000000000000000000000000000..508fe2f596b2d17c3fe7c16efb65bca42c96c432
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ernie_m.md
@@ -0,0 +1,103 @@
+
+*This model was released on 2020-12-31 and added to Hugging Face Transformers on 2023-06-20.*
+
+# ErnieM
+
+
+
+
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The ErnieM model was proposed in [ERNIE-M: Enhanced Multilingual Representation by Aligning
+Cross-lingual Semantics with Monolingual Corpora](https://huggingface.co/papers/2012.15674) by Xuan Ouyang, Shuohuan Wang, Chao Pang, Yu Sun,
+Hao Tian, Hua Wu, Haifeng Wang.
+
+The abstract from the paper is the following:
+
+*Recent studies have demonstrated that pre-trained cross-lingual models achieve impressive performance in downstream cross-lingual tasks. This improvement benefits from learning a large amount of monolingual and parallel corpora. Although it is generally acknowledged that parallel corpora are critical for improving the model performance, existing methods are often constrained by the size of parallel corpora, especially for lowresource languages. In this paper, we propose ERNIE-M, a new training method that encourages the model to align the representation of multiple languages with monolingual corpora, to overcome the constraint that the parallel corpus size places on the model performance. Our key insight is to integrate back-translation into the pre-training process. We generate pseudo-parallel sentence pairs on a monolingual corpus to enable the learning of semantic alignments between different languages, thereby enhancing the semantic modeling of cross-lingual models. Experimental results show that ERNIE-M outperforms existing cross-lingual models and delivers new state-of-the-art results in various cross-lingual downstream tasks.*
+This model was contributed by [Susnato Dhar](https://huggingface.co/susnato). The original code can be found [here](https://github.com/PaddlePaddle/PaddleNLP/tree/develop/paddlenlp/transformers/ernie_m).
+
+
+## Usage tips
+
+- Ernie-M is a BERT-like model so it is a stacked Transformer Encoder.
+- Instead of using MaskedLM for pretraining (like BERT) the authors used two novel techniques: `Cross-attention Masked Language Modeling` and `Back-translation Masked Language Modeling`. For now these two LMHead objectives are not implemented here.
+- It is a multilingual language model.
+- Next Sentence Prediction was not used in pretraining process.
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## ErnieMConfig
+
+[[autodoc]] ErnieMConfig
+
+
+## ErnieMTokenizer
+
+[[autodoc]] ErnieMTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+
+## ErnieMModel
+
+[[autodoc]] ErnieMModel
+ - forward
+
+## ErnieMForSequenceClassification
+
+[[autodoc]] ErnieMForSequenceClassification
+ - forward
+
+
+## ErnieMForMultipleChoice
+
+[[autodoc]] ErnieMForMultipleChoice
+ - forward
+
+
+## ErnieMForTokenClassification
+
+[[autodoc]] ErnieMForTokenClassification
+ - forward
+
+
+## ErnieMForQuestionAnswering
+
+[[autodoc]] ErnieMForQuestionAnswering
+ - forward
+
+## ErnieMForInformationExtraction
+
+[[autodoc]] ErnieMForInformationExtraction
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/esm.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/esm.md
new file mode 100644
index 0000000000000000000000000000000000000000..5d0f48f3a54ae582480f519c29f8136fdcb9e164
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/esm.md
@@ -0,0 +1,168 @@
+
+*This model was released on 2019-04-19 and added to Hugging Face Transformers on 2022-09-30.*
+
+# ESM
+
+
+
+
+
+
+## Overview
+
+This page provides code and pre-trained weights for Transformer protein language models from Meta AI's Fundamental
+AI Research Team, providing the state-of-the-art ESMFold and ESM-2, and the previously released ESM-1b and ESM-1v.
+Transformer protein language models were introduced in the paper [Biological structure and function emerge from scaling
+unsupervised learning to 250 million protein sequences](https://www.pnas.org/content/118/15/e2016239118) by
+Alexander Rives, Joshua Meier, Tom Sercu, Siddharth Goyal, Zeming Lin, Jason Liu, Demi Guo, Myle Ott,
+C. Lawrence Zitnick, Jerry Ma, and Rob Fergus.
+The first version of this paper was [preprinted in 2019](https://www.biorxiv.org/content/10.1101/622803v1?versioned=true).
+
+ESM-2 outperforms all tested single-sequence protein language models across a range of structure prediction tasks,
+and enables atomic resolution structure prediction.
+It was released with the paper [Language models of protein sequences at the scale of evolution enable accurate
+structure prediction](https://doi.org/10.1101/2022.07.20.500902) by Zeming Lin, Halil Akin, Roshan Rao, Brian Hie,
+Zhongkai Zhu, Wenting Lu, Allan dos Santos Costa, Maryam Fazel-Zarandi, Tom Sercu, Sal Candido and Alexander Rives.
+
+Also introduced in this paper was ESMFold. It uses an ESM-2 stem with a head that can predict folded protein
+structures with state-of-the-art accuracy. Unlike [AlphaFold2](https://www.nature.com/articles/s41586-021-03819-2),
+it relies on the token embeddings from the large pre-trained protein language model stem and does not perform a multiple
+sequence alignment (MSA) step at inference time, which means that ESMFold checkpoints are fully "standalone" -
+they do not require a database of known protein sequences and structures with associated external query tools
+to make predictions, and are much faster as a result.
+
+
+The abstract from
+"Biological structure and function emerge from scaling unsupervised learning to 250
+million protein sequences" is
+
+
+*In the field of artificial intelligence, a combination of scale in data and model capacity enabled by unsupervised
+learning has led to major advances in representation learning and statistical generation. In the life sciences, the
+anticipated growth of sequencing promises unprecedented data on natural sequence diversity. Protein language modeling
+at the scale of evolution is a logical step toward predictive and generative artificial intelligence for biology. To
+this end, we use unsupervised learning to train a deep contextual language model on 86 billion amino acids across 250
+million protein sequences spanning evolutionary diversity. The resulting model contains information about biological
+properties in its representations. The representations are learned from sequence data alone. The learned representation
+space has a multiscale organization reflecting structure from the level of biochemical properties of amino acids to
+remote homology of proteins. Information about secondary and tertiary structure is encoded in the representations and
+can be identified by linear projections. Representation learning produces features that generalize across a range of
+applications, enabling state-of-the-art supervised prediction of mutational effect and secondary structure and
+improving state-of-the-art features for long-range contact prediction.*
+
+
+The abstract from
+"Language models of protein sequences at the scale of evolution enable accurate structure prediction" is
+
+*Large language models have recently been shown to develop emergent capabilities with scale, going beyond
+simple pattern matching to perform higher level reasoning and generate lifelike images and text. While
+language models trained on protein sequences have been studied at a smaller scale, little is known about
+what they learn about biology as they are scaled up. In this work we train models up to 15 billion parameters,
+the largest language models of proteins to be evaluated to date. We find that as models are scaled they learn
+information enabling the prediction of the three-dimensional structure of a protein at the resolution of
+individual atoms. We present ESMFold for high accuracy end-to-end atomic level structure prediction directly
+from the individual sequence of a protein. ESMFold has similar accuracy to AlphaFold2 and RoseTTAFold for
+sequences with low perplexity that are well understood by the language model. ESMFold inference is an
+order of magnitude faster than AlphaFold2, enabling exploration of the structural space of metagenomic
+proteins in practical timescales.*
+
+The original code can be found [here](https://github.com/facebookresearch/esm) and was
+was developed by the Fundamental AI Research team at Meta AI.
+ESM-1b, ESM-1v and ESM-2 were contributed to huggingface by [jasonliu](https://huggingface.co/jasonliu)
+and [Matt](https://huggingface.co/Rocketknight1).
+
+ESMFold was contributed to huggingface by [Matt](https://huggingface.co/Rocketknight1) and
+[Sylvain](https://huggingface.co/sgugger), with a big thank you to Nikita Smetanin, Roshan Rao and Tom Sercu for their
+help throughout the process!
+
+## Usage tips
+
+- ESM models are trained with a masked language modeling (MLM) objective.
+- The HuggingFace port of ESMFold uses portions of the [openfold](https://github.com/aqlaboratory/openfold) library. The `openfold` library is licensed under the Apache License 2.0.
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+
+## EsmConfig
+
+[[autodoc]] EsmConfig
+ - all
+
+## EsmTokenizer
+
+[[autodoc]] EsmTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+
+
+
+## EsmModel
+
+[[autodoc]] EsmModel
+ - forward
+
+## EsmForMaskedLM
+
+[[autodoc]] EsmForMaskedLM
+ - forward
+
+## EsmForSequenceClassification
+
+[[autodoc]] EsmForSequenceClassification
+ - forward
+
+## EsmForTokenClassification
+
+[[autodoc]] EsmForTokenClassification
+ - forward
+
+## EsmForProteinFolding
+
+[[autodoc]] EsmForProteinFolding
+ - forward
+
+
+
+
+## TFEsmModel
+
+[[autodoc]] TFEsmModel
+ - call
+
+## TFEsmForMaskedLM
+
+[[autodoc]] TFEsmForMaskedLM
+ - call
+
+## TFEsmForSequenceClassification
+
+[[autodoc]] TFEsmForSequenceClassification
+ - call
+
+## TFEsmForTokenClassification
+
+[[autodoc]] TFEsmForTokenClassification
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/evolla.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/evolla.md
new file mode 100644
index 0000000000000000000000000000000000000000..a39103a06d1265f70786580645ce78579f0dd6e0
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/evolla.md
@@ -0,0 +1,96 @@
+
+*This model was released on 2025-01-05 and added to Hugging Face Transformers on 2025-07-26.*
+
+# Evolla
+
+## Overview
+
+The Evolla model was proposed in [Decoding the Molecular Language of Proteins with Evolla](https://doi.org/10.1101/2025.01.05.630192) by [Zhou et al.](https://doi.org/10.1101/2025.01.05.630192).
+
+Evolla is an advanced 80-billion-parameter protein-language generative model designed to decode the molecular language of proteins. It integrates information from protein sequences, structures, and user queries to generate precise and contextually nuanced insights into protein function. Trained on an unprecedented AI-generated dataset of 546 million protein question-answer pairs and 150 billion word tokens, Evolla significantly advances research in proteomics and functional genomics, providing expert-level insights and shedding light on the molecular logic encoded in proteins.
+
+The abstract from the paper is the following:
+
+*Proteins, nature’s intricate molecular machines, are the products of billions of years of evolution and play fundamental roles in sustaining life. Yet, deciphering their molecular language - that is, understanding how protein sequences and structures encode and determine biological functions - remains a corner-stone challenge in modern biology. Here, we introduce Evolla, an 80 billion frontier protein-language generative model designed to decode the molecular language of proteins. By integrating information from protein sequences, structures, and user queries, Evolla generates precise and contextually nuanced insights into protein function. A key innovation of Evolla lies in its training on an unprecedented AI-generated dataset: 546 million protein question-answer pairs and 150 billion word tokens, designed to reflect the immense complexity and functional diversity of proteins. Post-pretraining, Evolla integrates Direct Preference Optimization (DPO) to refine the model based on preference signals and Retrieval-Augmented Generation (RAG) for external knowledge incorporation, improving response quality and relevance. To evaluate its performance, we propose a novel framework, Instructional Response Space (IRS), demonstrating that Evolla delivers expert-level insights, advancing research in proteomics and functional genomics while shedding light on the molecular logic encoded in proteins. The online demo is available at http://www.chat-protein.com/.*
+
+Examples:
+
+```python
+processor = EvollaProcessor.from_pretrained("westlake-repl/Evolla-10B-DPO-hf")
+model = EvollaForProteinText2Text.from_pretrained("westlake-repl/Evolla-10B-DPO-hf")
+# aa_seq should have same length as foldseek
+protein_inputs = [
+ {
+
+ "aa_seq": "MATGGRRG...",
+ "foldseek": "###lqpfd...", # hashtag means the low-confidence foldseek tokens
+ },
+ {
+ "aa_seq": "MLPGLALL...",
+ "foldseek": "dfwwkwad...",
+ }
+]
+message_list = [
+ [
+ {
+ "role": "system",
+ "content": "You are an AI expert that can answer any questions about protein.",
+ },
+ {"role": "user", "content": "What is the function of this protein?"},
+ ],
+ [
+ {
+ "role": "system",
+ "content": "You are an AI expert that can answer any questions about protein.",
+ },
+ {"role": "user", "content": "What is the function of this protein?"},
+ ]
+]
+input_dict = processor(
+ protein_informations, messages_list, return_tensors="pt", text_max_length=512, protein_max_length=1024
+)
+with torch.no_grad():
+ generated_ids = hf_model.generate(**input_dict)
+generated_texts = processor.batch_decode(
+ generated_ids, skip_special_tokens=True
+)
+```
+
+Tips:
+
+- This model was contributed by [Xibin Bayes Zhou](https://huggingface.co/XibinBayesZhou).
+- The original code can be found [here](https://github.com/westlake-repl/Evolla).
+
+
+## EvollaConfig
+
+[[autodoc]] EvollaConfig
+
+## EvollaModel
+
+[[autodoc]] EvollaModel
+ - forward
+
+## EvollaForProteinText2Text
+
+[[autodoc]] EvollaForProteinText2Text
+ - forward
+
+## EvollaProcessor
+
+[[autodoc]] EvollaProcessor
+ - __call__
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/exaone4.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/exaone4.md
new file mode 100644
index 0000000000000000000000000000000000000000..166da68575db99b5cfb8b1114e1253697297eaba
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/exaone4.md
@@ -0,0 +1,209 @@
+
+*This model was released on 2025-07-15 and added to Hugging Face Transformers on 2025-07-26.*
+
+# EXAONE 4
+
+## Overview
+
+**[EXAONE 4.0](https://github.com/LG-AI-EXAONE/EXAONE-4.0)** model is the language model, which integrates a **Non-reasoning mode** and **Reasoning mode** to achieve both the excellent usability of [EXAONE 3.5](https://github.com/LG-AI-EXAONE/EXAONE-3.5) and the advanced reasoning abilities of [EXAONE Deep](https://github.com/LG-AI-EXAONE/EXAONE-Deep). To pave the way for the agentic AI era, EXAONE 4.0 incorporates essential features such as agentic tool use, and its multilingual capabilities are extended
+to support Spanish in addition to English and Korean.
+
+The EXAONE 4.0 model series consists of two sizes: a mid-size **32B** model optimized for high performance, and a small-size **1.2B** model designed for on-device applications.
+
+In the EXAONE 4.0 architecture, we apply new architectural changes compared to previous EXAONE models as below:
+
+1. **Hybrid Attention**: For the 32B model, we adopt hybrid attention scheme, which combines *Local attention (sliding window attention)* with *Global attention (full attention)* in a 3:1 ratio. We do not use RoPE (Rotary Positional Embedding) for global attention for better global context understanding.
+2. **QK-Reorder-Norm**: We reorder the LayerNorm position from the traditional Pre-LN scheme by applying LayerNorm directly to the attention and MLP outputs, and we add RMS normalization right after the Q and K projection. It helps yield better performance on downstream tasks despite consuming more computation.
+
+For more details, please refer to our [technical report](https://huggingface.co/papers/2507.11407), [HuggingFace paper](https://huggingface.co/papers/2507.11407), [blog](https://www.lgresearch.ai/blog/view?seq=576), and [GitHub](https://github.com/LG-AI-EXAONE/EXAONE-4.0).
+
+All model weights including quantized versions are available at [Huggingface Collections](https://huggingface.co/collections/LGAI-EXAONE/exaone-40-686b2e0069800c835ed48375).
+
+
+## Model Details
+
+### Model Specifications
+
+| Model Configuration | 32B | 1.2B |
+|:-------------------|:-----:|:------:|
+| d_model | 5,120 | 2,048 |
+| Number of layers | 64 | 30 |
+| Normalization | QK-Reorder-LN | QK-Reorder-LN |
+| Non-linearity | SwiGLU | SwiGLU |
+| Feedforward dimension | 27,392 | 4,096 |
+| Attention type | Hybrid (3:1 Local-Global) | Global |
+| Head type | GQA | GQA |
+| Number of heads | 40 | 32 |
+| Number of KV heads | 8 | 8 |
+| Head size | 128 | 64 |
+| Max sequence length | 131,072 | 65,536 |
+| RoPE theta | 1,000,000 | 1,000,000 |
+| Tokenizer | BBPE | BBPE |
+| Vocab size | 102,400 | 102,400 |
+| Tied word embedding | False | True |
+| Knowledge cut-off | Nov. 2024 | Nov. 2024 |
+
+
+## Usage tips
+
+### Non-reasoning mode
+
+For general use, you can use the EXAONE 4.0 models with the following example:
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_name = "LGAI-EXAONE/EXAONE-4.0-32B"
+
+model = AutoModelForCausalLM.from_pretrained(
+ model_name,
+ torch_dtype="bfloat16",
+ device_map="auto"
+)
+tokenizer = AutoTokenizer.from_pretrained(model_name)
+
+# choose your prompt
+prompt = "Explain how wonderful you are"
+prompt = "Explica lo increíble que eres"
+prompt = "너가 얼마나 대단한지 설명해 봐"
+
+messages = [
+ {"role": "user", "content": prompt}
+]
+input_ids = tokenizer.apply_chat_template(
+ messages,
+ tokenize=True,
+ add_generation_prompt=True,
+ return_tensors="pt"
+)
+
+output = model.generate(
+ input_ids.to(model.device),
+ max_new_tokens=128,
+ do_sample=False,
+)
+print(tokenizer.decode(output[0]))
+```
+
+### Reasoning mode
+
+The EXAONE 4.0 models have reasoning capabilities for handling complex problems. You can activate reasoning mode by using the `enable_thinking=True` argument with the tokenizer, which opens a reasoning block that starts with `` tag without closing it.
+
+```python
+messages = [
+ {"role": "user", "content": "Which one is bigger, 3.12 vs 3.9?"}
+]
+input_ids = tokenizer.apply_chat_template(
+ messages,
+ tokenize=True,
+ add_generation_prompt=True,
+ return_tensors="pt",
+ enable_thinking=True,
+)
+
+output = model.generate(
+ input_ids.to(model.device),
+ max_new_tokens=128,
+ do_sample=True,
+ temperature=0.6,
+ top_p=0.95
+)
+print(tokenizer.decode(output[0]))
+```
+
+> [!IMPORTANT]
+> The model generation with reasoning mode can be affected sensitively by sampling parameters, so please refer to the [Usage Guideline](https://github.com/LG-AI-EXAONE/EXAONE-4.0#usage-guideline) on official GitHub page for better quality.
+
+### Agentic tool use
+
+The EXAONE 4.0 models can be used as agents with their tool calling capabilities. You can provide tool schemas to the model for effective tool calling.
+
+```python
+import random
+
+def roll_dice(max_num: int):
+ return random.randint(1, max_num)
+
+tools = [
+ {
+ "type": "function",
+ "function": {
+ "name": "roll_dice",
+ "description": "Roll a dice with the number 1 to N. User can select the number N.",
+ "parameters": {
+ "type": "object",
+ "required": ["max_num"],
+ "properties": {
+ "max_num": {
+ "type": "int",
+ "description": "Max number of the dice"
+ }
+ }
+ }
+ }
+ }
+]
+
+messages = [
+ {"role": "user", "content": "Roll D6 dice twice!"}
+]
+input_ids = tokenizer.apply_chat_template(
+ messages,
+ tokenize=True,
+ add_generation_prompt=True,
+ return_tensors="pt",
+ tools=tools,
+)
+
+output = model.generate(
+ input_ids.to(model.device),
+ max_new_tokens=1024,
+ do_sample=True,
+ temperature=0.6,
+ top_p=0.95,
+)
+print(tokenizer.decode(output[0]))
+```
+
+## Exaone4Config
+
+[[autodoc]] Exaone4Config
+
+## Exaone4Model
+
+[[autodoc]] Exaone4Model
+ - forward
+
+## Exaone4ForCausalLM
+
+[[autodoc]] Exaone4ForCausalLM
+ - forward
+
+## Exaone4ForSequenceClassification
+
+[[autodoc]] Exaone4ForSequenceClassification
+ - forward
+
+## Exaone4ForTokenClassification
+
+[[autodoc]] Exaone4ForTokenClassification
+ - forward
+
+## Exaone4ForQuestionAnswering
+
+[[autodoc]] Exaone4ForQuestionAnswering
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/falcon.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/falcon.md
new file mode 100644
index 0000000000000000000000000000000000000000..3391b9f73f70648bd2c670aa82041cac49b71174
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/falcon.md
@@ -0,0 +1,154 @@
+
+*This model was released on 2023-11-28 and added to Hugging Face Transformers on 2023-07-11.*
+
+
+
+
+
+
+
+
+
+# Falcon
+
+[Falcon](https://huggingface.co/papers/2311.16867) is a family of large language models, available in 7B, 40B, and 180B parameters, as pretrained and instruction tuned variants. This model focuses on scaling pretraining over three categories, performance, data, and hardware. Falcon uses multigroup attention to significantly reduce inference memory requirements and rotary positional embeddings (RoPE). These models are pretrained on [RefinedWeb](https://huggingface.co/datasets/tiiuae/falcon-refinedweb), a high-quality and deduplicated 5T token dataset.
+
+You can find all the original Falcon checkpoints under the [Falcon](https://huggingface.co/collections/tiiuae/falcon-64fb432660017eeec9837b5a) collection.
+
+> [!TIP]
+> Click on the Falcon models in the right sidebar for more examples of how to apply Falcon to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="text-generation",
+ model="tiiuae/falcon-7b-instruct",
+ torch_dtype=torch.bfloat16,
+ device=0
+)
+pipeline(
+ "Write a short poem about coding",
+ max_length=100,
+ do_sample=True,
+ temperature=0.7
+)
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoTokenizer, AutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("tiiuae/falcon-7b-instruct")
+model = AutoModelForCausalLM.from_pretrained(
+ "tiiuae/falcon-7b-instruct",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa",
+)
+
+input_ids = tokenizer("Write a short poem about coding", return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids)
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+# pip install -U flash-attn --no-build-isolation
+transformers chat tiiuae/falcon-7b-instruct --torch_dtype auto --attn_implementation flash_attention_2 --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to 4-bits.
+
+```python
+import torch
+from transformers import AutoTokenizer, AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_compute_dtype=torch.bfloat16,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_use_double_quant=True,
+)
+
+tokenizer = AutoTokenizer.from_pretrained("tiiuae/falcon-7b")
+model = AutoModelForCausalLM.from_pretrained(
+ "tiiuae/falcon-7b",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config,
+)
+
+inputs = tokenizer("In quantum physics, entanglement means", return_tensors="pt").to(model.device)
+outputs = model.generate(**inputs, max_new_tokens=100)
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+## Notes
+
+- If you're upgrading from an older custom code checkpoint, remember to convert it to the official Transformers format for better stability and performance using the conversion script located in the [Falcon model directory](https://github.com/huggingface/transformers/tree/main/src/transformers/models/falcon).
+
+ ```bash
+ python convert_custom_code_checkpoint.py --checkpoint_dir my_model
+ ```
+
+## FalconConfig
+
+[[autodoc]] FalconConfig
+ - all
+
+## FalconModel
+
+[[autodoc]] FalconModel
+ - forward
+
+## FalconForCausalLM
+
+[[autodoc]] FalconForCausalLM
+ - forward
+
+## FalconForSequenceClassification
+
+[[autodoc]] FalconForSequenceClassification
+ - forward
+
+## FalconForTokenClassification
+
+[[autodoc]] FalconForTokenClassification
+ - forward
+
+## FalconForQuestionAnswering
+
+[[autodoc]] FalconForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/falcon3.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/falcon3.md
new file mode 100644
index 0000000000000000000000000000000000000000..93dc356e21df7ce05be49934025bb6c5bb525122
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/falcon3.md
@@ -0,0 +1,36 @@
+
+*This model was released on 2024-12-17 and added to Hugging Face Transformers on 2024-12-17.*
+
+# Falcon3
+
+
+
+
+
+
+## Overview
+
+[Falcon3](https://falconllm.tii.ae/falcon3/index.html) represents a natural evolution from previous releases, emphasizing expanding the models' science, math, and code capabilities. This iteration includes five base models: Falcon3-1B-Base, Falcon3-3B-Base, Falcon3-Mamba-7B-Base, Falcon3-7B-Base, and Falcon3-10B-Base. In developing these models, we incorporated several key innovations aimed at improving the models' performances while reducing training costs:
+
+One pre-training: We conducted a single large-scale pretraining run on the 7B model, using 2048 H100 GPU chips, leveraging 14 trillion tokens featuring web, code, STEM, and curated high-quality and multilingual data.
+Depth up-scaling for improved reasoning: Building on recent studies on the effects of model depth, we upscaled the 7B model to a 10B parameters model by duplicating the redundant layers and continuing pre-training with 2TT of high-quality data. This yielded Falcon3-10B-Base which achieves state-of-the-art zero-shot and few-shot performance for models under 13B parameters.
+Knowledge distillation for better tiny models: To provide compact and efficient alternatives, we developed Falcon3-1B-Base and Falcon3-3B-Base by leveraging pruning and knowledge distillation techniques, using less than 100GT of curated high-quality data, thereby redefining pre-training efficiency.
+
+## Resources
+- [Blog post](https://huggingface.co/blog/falcon3)
+- [Models on Huggingface](https://huggingface.co/collections/tiiuae/falcon3-67605ae03578be86e4e87026)
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/falcon_h1.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/falcon_h1.md
new file mode 100644
index 0000000000000000000000000000000000000000..981c00bd626b23bd1b60177b3eaf8cc517734894
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/falcon_h1.md
@@ -0,0 +1,66 @@
+
+*This model was released on 2025-05-21 and added to Hugging Face Transformers on 2025-05-21.*
+
+# FalconH1
+
+## Overview
+
+The [FalconH1](https://huggingface.co/blog/tiiuae/falcon-h1) model was developed by the TII Pretraining team. A comprehensive research paper covering the architecture, pretraining dynamics, experimental results, and conclusions is forthcoming. You can read more about this series in [this website](https://github.com/tiiuae/Falcon-H1).
+
+## Contributors
+
+This model was contributed by [DhiyaEddine](https://huggingface.co/DhiyaEddine), [ybelkada](https://huggingface.co/ybelkada), [JingweiZuo](https://huggingface.co/JingweiZuo), [IlyasChahed](https://huggingface.co/IChahed), and [MaksimVelikanov](https://huggingface.co/yellowvm).
+The original code can be found [here](https://github.com/tiiuae/Falcon-H1).
+
+
+## FalconH1Config
+
+| Model | Depth | Dim | Attn Heads | KV | Mamba Heads | d_head | d_state | Ctx Len |
+|-----------|--------|------|------------|----|--------------|--------------|------|-----------------|
+| H1 0.5B | 36 | 1024 | 8 | 2 | 24 | 64 / 64 | 128 | 4K, 16K-SFT |
+| H1 1.5B | 24 | 2048 | 8 | 2 | 48 | 128 / 64 | 256 | 128K |
+| H1 1.5B-d | 66 | 1280 | 6 | 2 | 24 | 128 / 64 | 256 | 128K |
+| H1 3B | 32 | 2560 | 10 | 2 | 32 | 128 / 128 | 256 | 128K |
+| H1 7B | 44 | 3072 | 12 | 2 | 24 | 128 / 128 | 256 | 256K |
+| H1 34B | 72 | 5120 | 20 | 4 | 32 | 128 / 128 | 256 | 256K |
+
+
+
+[[autodoc]] FalconH1Config
+
+
+
+## FalconH1ForCausalLM
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained("tiiuae/Falcon-H1-7B-Instruct")
+tokenizer = AutoTokenizer.from_pretrained("tiiuae/Falcon-H1-7B-Instruct")
+
+message = ["Mamba is a snake with following properties "]
+inputs = tokenizer(message, return_tensors='pt', return_token_type_ids=False)
+response = model.generate(**inputs, max_new_tokens=64)
+print(tokenizer.batch_decode(response, skip_special_tokens=True)[0])
+```
+
+[[autodoc]] FalconH1ForCausalLM
+ - forward
+
+This HF implementation is contributed by [younesbelkada](https://github.com/younesbelkada) and [DhiaEddineRhaiem](https://github.com/dhiaEddineRhaiem).
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/falcon_mamba.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/falcon_mamba.md
new file mode 100644
index 0000000000000000000000000000000000000000..505c244ccb1fd9c0058e7c27acbc13d449aa865d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/falcon_mamba.md
@@ -0,0 +1,133 @@
+
+*This model was released on 2024-10-07 and added to Hugging Face Transformers on 2024-08-12.*
+
+
+
+
+
+
+
+# FalconMamba
+
+[FalconMamba](https://huggingface.co/papers/2410.05355) is a 7B large language model, available as pretrained and instruction-tuned variants, based on the [Mamba](./mamba). This model implements a pure Mamba design that focuses on computational efficiency while maintaining strong performance. FalconMamba is significantly faster at inference and requires substantially less memory for long sequence generation. The models are pretrained on a diverse 5.8T token dataset including [RefinedWeb](https://huggingface.co/datasets/tiiuae/falcon-refinedweb), technical content, code, and mathematical data.
+
+You can find the official FalconMamba checkpoints in the [FalconMamba 7B](https://huggingface.co/collections/tiiuae/falconmamba-7b-66b9a580324dd1598b0f6d4a) collection.
+
+> [!TIP]
+> Click on the FalconMamba models in the right sidebar for more examples of how to apply FalconMamba to different language tasks.
+
+The examples below demonstrate how to generate text with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ "text-generation",
+ model="tiiuae/falcon-mamba-7b-instruct",
+ torch_dtype=torch.bfloat16,
+ device=0
+)
+pipeline(
+ "Explain the difference between transformers and SSMs",
+ max_length=100,
+ do_sample=True,
+ temperature=0.7
+)
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoTokenizer, AutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("tiiuae/falcon-mamba-7b-instruct")
+model = AutoModelForCausalLM.from_pretrained(
+ "tiiuae/falcon-mamba-7b-instruct",
+ torch_dtype=torch.bfloat16,
+ device_map="auto"
+)
+
+input_ids = tokenizer("Explain the difference between transformers and SSMs", return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, max_new_tokens=100, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+transformers chat tiiuae/falcon-mamba-7b-instruct --torch_dtype auto --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to quantize the weights to 4-bits.
+
+```python
+import torch
+from transformers import AutoTokenizer, FalconMambaForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_compute_dtype=torch.bfloat16,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_use_double_quant=True,
+)
+
+tokenizer = AutoTokenizer.from_pretrained("tiiuae/falcon-mamba-7b")
+model = FalconMambaForCausalLM.from_pretrained(
+ "tiiuae/falcon-mamba-7b",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config,
+)
+
+inputs = tokenizer("Explain the concept of state space models in simple terms", return_tensors="pt").to(model.device)
+outputs = model.generate(**inputs, max_new_tokens=100)
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+## FalconMambaCache
+
+[[autodoc]] FalconMambaCache
+ - update_conv_state
+ - update_ssm_state
+ - reset
+
+## FalconMambaConfig
+
+[[autodoc]] FalconMambaConfig
+
+## FalconMambaModel
+
+[[autodoc]] FalconMambaModel
+ - forward
+
+## FalconMambaLMHeadModel
+
+[[autodoc]] FalconMambaForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/fastspeech2_conformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/fastspeech2_conformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..a131f75f95cece7b3f380a62adcaddd68fb42c46
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/fastspeech2_conformer.md
@@ -0,0 +1,139 @@
+
+*This model was released on 2020-10-26 and added to Hugging Face Transformers on 2024-01-03.*
+
+# FastSpeech2Conformer
+
+
+
+
+
+## Overview
+
+The FastSpeech2Conformer model was proposed with the paper [Recent Developments On Espnet Toolkit Boosted By Conformer](https://huggingface.co/papers/2010.13956) by Pengcheng Guo, Florian Boyer, Xuankai Chang, Tomoki Hayashi, Yosuke Higuchi, Hirofumi Inaguma, Naoyuki Kamo, Chenda Li, Daniel Garcia-Romero, Jiatong Shi, Jing Shi, Shinji Watanabe, Kun Wei, Wangyou Zhang, and Yuekai Zhang.
+
+The abstract from the original FastSpeech2 paper is the following:
+
+*Non-autoregressive text to speech (TTS) models such as FastSpeech (Ren et al., 2019) can synthesize speech significantly faster than previous autoregressive models with comparable quality. The training of FastSpeech model relies on an autoregressive teacher model for duration prediction (to provide more information as input) and knowledge distillation (to simplify the data distribution in output), which can ease the one-to-many mapping problem (i.e., multiple speech variations correspond to the same text) in TTS. However, FastSpeech has several disadvantages: 1) the teacher-student distillation pipeline is complicated and time-consuming, 2) the duration extracted from the teacher model is not accurate enough, and the target mel-spectrograms distilled from teacher model suffer from information loss due to data simplification, both of which limit the voice quality. In this paper, we propose FastSpeech 2, which addresses the issues in FastSpeech and better solves the one-to-many mapping problem in TTS by 1) directly training the model with ground-truth target instead of the simplified output from teacher, and 2) introducing more variation information of speech (e.g., pitch, energy and more accurate duration) as conditional inputs. Specifically, we extract duration, pitch and energy from speech waveform and directly take them as conditional inputs in training and use predicted values in inference. We further design FastSpeech 2s, which is the first attempt to directly generate speech waveform from text in parallel, enjoying the benefit of fully end-to-end inference. Experimental results show that 1) FastSpeech 2 achieves a 3x training speed-up over FastSpeech, and FastSpeech 2s enjoys even faster inference speed; 2) FastSpeech 2 and 2s outperform FastSpeech in voice quality, and FastSpeech 2 can even surpass autoregressive models. Audio samples are available at https://speechresearch.github.io/fastspeech2/.*
+
+This model was contributed by [Connor Henderson](https://huggingface.co/connor-henderson). The original code can be found [here](https://github.com/espnet/espnet/blob/master/espnet2/tts/fastspeech2/fastspeech2.py).
+
+
+## 🤗 Model Architecture
+FastSpeech2's general structure with a Mel-spectrogram decoder was implemented, and the traditional transformer blocks were replaced with conformer blocks as done in the ESPnet library.
+
+#### FastSpeech2 Model Architecture
+
+
+#### Conformer Blocks
+
+
+#### Convolution Module
+
+
+## 🤗 Transformers Usage
+
+You can run FastSpeech2Conformer locally with the 🤗 Transformers library.
+
+1. First install the 🤗 [Transformers library](https://github.com/huggingface/transformers), g2p-en:
+
+```bash
+pip install --upgrade pip
+pip install --upgrade transformers g2p-en
+```
+
+2. Run inference via the Transformers modelling code with the model and hifigan separately
+
+```python
+
+from transformers import FastSpeech2ConformerTokenizer, FastSpeech2ConformerModel, FastSpeech2ConformerHifiGan
+import soundfile as sf
+
+tokenizer = FastSpeech2ConformerTokenizer.from_pretrained("espnet/fastspeech2_conformer")
+inputs = tokenizer("Hello, my dog is cute.", return_tensors="pt")
+input_ids = inputs["input_ids"]
+
+model = FastSpeech2ConformerModel.from_pretrained("espnet/fastspeech2_conformer")
+output_dict = model(input_ids, return_dict=True)
+spectrogram = output_dict["spectrogram"]
+
+hifigan = FastSpeech2ConformerHifiGan.from_pretrained("espnet/fastspeech2_conformer_hifigan")
+waveform = hifigan(spectrogram)
+
+sf.write("speech.wav", waveform.squeeze().detach().numpy(), samplerate=22050)
+```
+
+3. Run inference via the Transformers modelling code with the model and hifigan combined
+
+```python
+from transformers import FastSpeech2ConformerTokenizer, FastSpeech2ConformerWithHifiGan
+import soundfile as sf
+
+tokenizer = FastSpeech2ConformerTokenizer.from_pretrained("espnet/fastspeech2_conformer")
+inputs = tokenizer("Hello, my dog is cute.", return_tensors="pt")
+input_ids = inputs["input_ids"]
+
+model = FastSpeech2ConformerWithHifiGan.from_pretrained("espnet/fastspeech2_conformer_with_hifigan")
+output_dict = model(input_ids, return_dict=True)
+waveform = output_dict["waveform"]
+
+sf.write("speech.wav", waveform.squeeze().detach().numpy(), samplerate=22050)
+```
+
+4. Run inference with a pipeline and specify which vocoder to use
+```python
+from transformers import pipeline, FastSpeech2ConformerHifiGan
+import soundfile as sf
+
+vocoder = FastSpeech2ConformerHifiGan.from_pretrained("espnet/fastspeech2_conformer_hifigan")
+synthesiser = pipeline(model="espnet/fastspeech2_conformer", vocoder=vocoder)
+
+speech = synthesiser("Hello, my dog is cooler than you!")
+
+sf.write("speech.wav", speech["audio"].squeeze(), samplerate=speech["sampling_rate"])
+```
+
+
+## FastSpeech2ConformerConfig
+
+[[autodoc]] FastSpeech2ConformerConfig
+
+## FastSpeech2ConformerHifiGanConfig
+
+[[autodoc]] FastSpeech2ConformerHifiGanConfig
+
+## FastSpeech2ConformerWithHifiGanConfig
+
+[[autodoc]] FastSpeech2ConformerWithHifiGanConfig
+
+## FastSpeech2ConformerTokenizer
+
+[[autodoc]] FastSpeech2ConformerTokenizer
+ - __call__
+ - save_vocabulary
+ - decode
+ - batch_decode
+
+## FastSpeech2ConformerModel
+
+[[autodoc]] FastSpeech2ConformerModel
+ - forward
+
+## FastSpeech2ConformerHifiGan
+
+[[autodoc]] FastSpeech2ConformerHifiGan
+ - forward
+
+## FastSpeech2ConformerWithHifiGan
+
+[[autodoc]] FastSpeech2ConformerWithHifiGan
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/flan-t5.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/flan-t5.md
new file mode 100644
index 0000000000000000000000000000000000000000..cc2b7681720f5690bff8b6684279b3756bb371df
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/flan-t5.md
@@ -0,0 +1,65 @@
+
+*This model was released on 2022-10-20 and added to Hugging Face Transformers on 2023-06-20.*
+
+# FLAN-T5
+
+
+
+
+
+
+
+## Overview
+
+FLAN-T5 was released in the paper [Scaling Instruction-Finetuned Language Models](https://huggingface.co/papers/2210.11416) - it is an enhanced version of T5 that has been finetuned in a mixture of tasks.
+
+One can directly use FLAN-T5 weights without finetuning the model:
+
+```python
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("google/flan-t5-small")
+>>> tokenizer = AutoTokenizer.from_pretrained("google/flan-t5-small")
+
+>>> inputs = tokenizer("A step by step recipe to make bolognese pasta:", return_tensors="pt")
+>>> outputs = model.generate(**inputs)
+>>> print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['Pour a cup of bolognese into a large bowl and add the pasta']
+```
+
+FLAN-T5 includes the same improvements as T5 version 1.1 (see [here](https://huggingface.co/docs/transformers/model_doc/t5v1.1) for the full details of the model's improvements.)
+
+Google has released the following variants:
+
+- [google/flan-t5-small](https://huggingface.co/google/flan-t5-small)
+
+- [google/flan-t5-base](https://huggingface.co/google/flan-t5-base)
+
+- [google/flan-t5-large](https://huggingface.co/google/flan-t5-large)
+
+- [google/flan-t5-xl](https://huggingface.co/google/flan-t5-xl)
+
+- [google/flan-t5-xxl](https://huggingface.co/google/flan-t5-xxl).
+
+The original checkpoints can be found [here](https://github.com/google-research/t5x/blob/main/docs/models.md#flan-t5-checkpoints).
+
+
+
+Refer to [T5's documentation page](t5) for all API reference, code examples and notebooks. For more details regarding training and evaluation of the FLAN-T5, refer to the model card.
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/flan-ul2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/flan-ul2.md
new file mode 100644
index 0000000000000000000000000000000000000000..f8cab7f79be6d9beb5996c8a390e0da7f4bca75e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/flan-ul2.md
@@ -0,0 +1,62 @@
+
+*This model was released on 2023-03-03 and added to Hugging Face Transformers on 2023-06-20.*
+
+# FLAN-UL2
+
+
+
+
+
+
+
+## Overview
+
+[Flan-UL2](https://www.yitay.net/blog/flan-ul2-20b) is an encoder decoder model based on the T5 architecture. It uses the same configuration as the [UL2](ul2) model released earlier last year.
+It was fine tuned using the "Flan" prompt tuning and dataset collection. Similar to `Flan-T5`, one can directly use FLAN-UL2 weights without finetuning the model:
+
+According to the original blog here are the notable improvements:
+
+- The original UL2 model was only trained with receptive field of 512, which made it non-ideal for N-shot prompting where N is large.
+- The Flan-UL2 checkpoint uses a receptive field of 2048 which makes it more usable for few-shot in-context learning.
+- The original UL2 model also had mode switch tokens that was rather mandatory to get good performance. However, they were a little cumbersome as this requires often some changes during inference or finetuning. In this update/change, we continue training UL2 20B for an additional 100k steps (with small batch) to forget “mode tokens” before applying Flan instruction tuning. This Flan-UL2 checkpoint does not require mode tokens anymore.
+Google has released the following variants:
+
+The original checkpoints can be found [here](https://github.com/google-research/google-research/tree/master/ul2).
+
+
+## Running on low resource devices
+
+The model is pretty heavy (~40GB in half precision) so if you just want to run the model, make sure you load your model in 8bit, and use `device_map="auto"` to make sure you don't have any OOM issue!
+
+```python
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("google/flan-ul2", load_in_8bit=True, device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("google/flan-ul2")
+
+>>> inputs = tokenizer("A step by step recipe to make bolognese pasta:", return_tensors="pt")
+>>> outputs = model.generate(**inputs)
+>>> print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['In a large skillet, brown the ground beef and onion over medium heat. Add the garlic']
+```
+
+
+
+Refer to [T5's documentation page](t5) for API reference, tips, code examples and notebooks.
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/flaubert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/flaubert.md
new file mode 100644
index 0000000000000000000000000000000000000000..810bde229bcfe0f2b2f9d672dc20c68ad8f7c4d7
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/flaubert.md
@@ -0,0 +1,141 @@
+
+*This model was released on 2019-12-11 and added to Hugging Face Transformers on 2020-11-16.*
+
+# FlauBERT
+
+
+
+
+
+
+## Overview
+
+The FlauBERT model was proposed in the paper [FlauBERT: Unsupervised Language Model Pre-training for French](https://huggingface.co/papers/1912.05372) by Hang Le et al. It's a transformer model pretrained using a masked language
+modeling (MLM) objective (like BERT).
+
+The abstract from the paper is the following:
+
+*Language models have become a key step to achieve state-of-the art results in many different Natural Language
+Processing (NLP) tasks. Leveraging the huge amount of unlabeled texts nowadays available, they provide an efficient way
+to pre-train continuous word representations that can be fine-tuned for a downstream task, along with their
+contextualization at the sentence level. This has been widely demonstrated for English using contextualized
+representations (Dai and Le, 2015; Peters et al., 2018; Howard and Ruder, 2018; Radford et al., 2018; Devlin et al.,
+2019; Yang et al., 2019b). In this paper, we introduce and share FlauBERT, a model learned on a very large and
+heterogeneous French corpus. Models of different sizes are trained using the new CNRS (French National Centre for
+Scientific Research) Jean Zay supercomputer. We apply our French language models to diverse NLP tasks (text
+classification, paraphrasing, natural language inference, parsing, word sense disambiguation) and show that most of the
+time they outperform other pretraining approaches. Different versions of FlauBERT as well as a unified evaluation
+protocol for the downstream tasks, called FLUE (French Language Understanding Evaluation), are shared to the research
+community for further reproducible experiments in French NLP.*
+
+This model was contributed by [formiel](https://huggingface.co/formiel). The original code can be found [here](https://github.com/getalp/Flaubert).
+
+Tips:
+- Like RoBERTa, without the sentence ordering prediction (so just trained on the MLM objective).
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## FlaubertConfig
+
+[[autodoc]] FlaubertConfig
+
+## FlaubertTokenizer
+
+[[autodoc]] FlaubertTokenizer
+
+
+
+
+## FlaubertModel
+
+[[autodoc]] FlaubertModel
+ - forward
+
+## FlaubertWithLMHeadModel
+
+[[autodoc]] FlaubertWithLMHeadModel
+ - forward
+
+## FlaubertForSequenceClassification
+
+[[autodoc]] FlaubertForSequenceClassification
+ - forward
+
+## FlaubertForMultipleChoice
+
+[[autodoc]] FlaubertForMultipleChoice
+ - forward
+
+## FlaubertForTokenClassification
+
+[[autodoc]] FlaubertForTokenClassification
+ - forward
+
+## FlaubertForQuestionAnsweringSimple
+
+[[autodoc]] FlaubertForQuestionAnsweringSimple
+ - forward
+
+## FlaubertForQuestionAnswering
+
+[[autodoc]] FlaubertForQuestionAnswering
+ - forward
+
+
+
+
+## TFFlaubertModel
+
+[[autodoc]] TFFlaubertModel
+ - call
+
+## TFFlaubertWithLMHeadModel
+
+[[autodoc]] TFFlaubertWithLMHeadModel
+ - call
+
+## TFFlaubertForSequenceClassification
+
+[[autodoc]] TFFlaubertForSequenceClassification
+ - call
+
+## TFFlaubertForMultipleChoice
+
+[[autodoc]] TFFlaubertForMultipleChoice
+ - call
+
+## TFFlaubertForTokenClassification
+
+[[autodoc]] TFFlaubertForTokenClassification
+ - call
+
+## TFFlaubertForQuestionAnsweringSimple
+
+[[autodoc]] TFFlaubertForQuestionAnsweringSimple
+ - call
+
+
+
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/flava.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/flava.md
new file mode 100644
index 0000000000000000000000000000000000000000..05b63399eac06c5dc6e8d00c459052913c632d23
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/flava.md
@@ -0,0 +1,113 @@
+
+*This model was released on 2021-12-08 and added to Hugging Face Transformers on 2022-05-11.*
+
+# FLAVA
+
+
+
+
+
+## Overview
+
+The FLAVA model was proposed in [FLAVA: A Foundational Language And Vision Alignment Model](https://huggingface.co/papers/2112.04482) by Amanpreet Singh, Ronghang Hu, Vedanuj Goswami, Guillaume Couairon, Wojciech Galuba, Marcus Rohrbach, and Douwe Kiela and is accepted at CVPR 2022.
+
+The paper aims at creating a single unified foundation model which can work across vision, language
+as well as vision-and-language multimodal tasks.
+
+The abstract from the paper is the following:
+
+*State-of-the-art vision and vision-and-language models rely on large-scale visio-linguistic pretraining for obtaining good performance on a variety
+of downstream tasks. Generally, such models are often either cross-modal (contrastive) or multi-modal
+(with earlier fusion) but not both; and they often only target specific modalities or tasks. A promising
+direction would be to use a single holistic universal model, as a "foundation", that targets all modalities
+at once -- a true vision and language foundation model should be good at vision tasks, language tasks, and
+cross- and multi-modal vision and language tasks. We introduce FLAVA as such a model and demonstrate
+impressive performance on a wide range of 35 tasks spanning these target modalities.*
+
+This model was contributed by [aps](https://huggingface.co/aps). The original code can be found [here](https://github.com/facebookresearch/multimodal/tree/main/examples/flava).
+
+## FlavaConfig
+
+[[autodoc]] FlavaConfig
+
+## FlavaTextConfig
+
+[[autodoc]] FlavaTextConfig
+
+## FlavaImageConfig
+
+[[autodoc]] FlavaImageConfig
+
+## FlavaMultimodalConfig
+
+[[autodoc]] FlavaMultimodalConfig
+
+## FlavaImageCodebookConfig
+
+[[autodoc]] FlavaImageCodebookConfig
+
+## FlavaProcessor
+
+[[autodoc]] FlavaProcessor
+
+## FlavaFeatureExtractor
+
+[[autodoc]] FlavaFeatureExtractor
+
+## FlavaImageProcessor
+
+[[autodoc]] FlavaImageProcessor
+ - preprocess
+
+## FlavaImageProcessorFast
+
+[[autodoc]] FlavaImageProcessorFast
+ - preprocess
+
+## FlavaForPreTraining
+
+[[autodoc]] FlavaForPreTraining
+ - forward
+
+## FlavaModel
+
+[[autodoc]] FlavaModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## FlavaImageCodebook
+
+[[autodoc]] FlavaImageCodebook
+ - forward
+ - get_codebook_indices
+ - get_codebook_probs
+
+## FlavaTextModel
+
+[[autodoc]] FlavaTextModel
+ - forward
+
+## FlavaImageModel
+
+[[autodoc]] FlavaImageModel
+ - forward
+
+## FlavaMultimodalModel
+
+[[autodoc]] FlavaMultimodalModel
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/fnet.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/fnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..79a4e9e4434ded04fe7d7ca0f7fca5101522cc0b
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/fnet.md
@@ -0,0 +1,115 @@
+
+*This model was released on 2021-05-09 and added to Hugging Face Transformers on 2021-09-20.*
+
+# FNet
+
+
+
+
+
+## Overview
+
+The FNet model was proposed in [FNet: Mixing Tokens with Fourier Transforms](https://huggingface.co/papers/2105.03824) by
+James Lee-Thorp, Joshua Ainslie, Ilya Eckstein, Santiago Ontanon. The model replaces the self-attention layer in a BERT
+model with a fourier transform which returns only the real parts of the transform. The model is significantly faster
+than the BERT model because it has fewer parameters and is more memory efficient. The model achieves about 92-97%
+accuracy of BERT counterparts on GLUE benchmark, and trains much faster than the BERT model. The abstract from the
+paper is the following:
+
+*We show that Transformer encoder architectures can be sped up, with limited accuracy costs, by replacing the
+self-attention sublayers with simple linear transformations that "mix" input tokens. These linear mixers, along with
+standard nonlinearities in feed-forward layers, prove competent at modeling semantic relationships in several text
+classification tasks. Most surprisingly, we find that replacing the self-attention sublayer in a Transformer encoder
+with a standard, unparameterized Fourier Transform achieves 92-97% of the accuracy of BERT counterparts on the GLUE
+benchmark, but trains 80% faster on GPUs and 70% faster on TPUs at standard 512 input lengths. At longer input lengths,
+our FNet model is significantly faster: when compared to the "efficient" Transformers on the Long Range Arena
+benchmark, FNet matches the accuracy of the most accurate models, while outpacing the fastest models across all
+sequence lengths on GPUs (and across relatively shorter lengths on TPUs). Finally, FNet has a light memory footprint
+and is particularly efficient at smaller model sizes; for a fixed speed and accuracy budget, small FNet models
+outperform Transformer counterparts.*
+
+This model was contributed by [gchhablani](https://huggingface.co/gchhablani). The original code can be found [here](https://github.com/google-research/google-research/tree/master/f_net).
+
+## Usage tips
+
+The model was trained without an attention mask as it is based on Fourier Transform. The model was trained with
+maximum sequence length 512 which includes pad tokens. Hence, it is highly recommended to use the same maximum
+sequence length for fine-tuning and inference.
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## FNetConfig
+
+[[autodoc]] FNetConfig
+
+## FNetTokenizer
+
+[[autodoc]] FNetTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## FNetTokenizerFast
+
+[[autodoc]] FNetTokenizerFast
+
+## FNetModel
+
+[[autodoc]] FNetModel
+ - forward
+
+## FNetForPreTraining
+
+[[autodoc]] FNetForPreTraining
+ - forward
+
+## FNetForMaskedLM
+
+[[autodoc]] FNetForMaskedLM
+ - forward
+
+## FNetForNextSentencePrediction
+
+[[autodoc]] FNetForNextSentencePrediction
+ - forward
+
+## FNetForSequenceClassification
+
+[[autodoc]] FNetForSequenceClassification
+ - forward
+
+## FNetForMultipleChoice
+
+[[autodoc]] FNetForMultipleChoice
+ - forward
+
+## FNetForTokenClassification
+
+[[autodoc]] FNetForTokenClassification
+ - forward
+
+## FNetForQuestionAnswering
+
+[[autodoc]] FNetForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/focalnet.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/focalnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..b5ce29086a2b61a44232f5777b2313888be53c7b
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/focalnet.md
@@ -0,0 +1,55 @@
+
+*This model was released on 2022-03-22 and added to Hugging Face Transformers on 2023-04-23.*
+
+# FocalNet
+
+
+
+
+
+## Overview
+
+The FocalNet model was proposed in [Focal Modulation Networks](https://huggingface.co/papers/2203.11926) by Jianwei Yang, Chunyuan Li, Xiyang Dai, Lu Yuan, Jianfeng Gao.
+FocalNets completely replace self-attention (used in models like [ViT](vit) and [Swin](swin)) by a focal modulation mechanism for modeling token interactions in vision.
+The authors claim that FocalNets outperform self-attention based models with similar computational costs on the tasks of image classification, object detection, and segmentation.
+
+The abstract from the paper is the following:
+
+*We propose focal modulation networks (FocalNets in short), where self-attention (SA) is completely replaced by a focal modulation mechanism for modeling token interactions in vision. Focal modulation comprises three components: (i) hierarchical contextualization, implemented using a stack of depth-wise convolutional layers, to encode visual contexts from short to long ranges, (ii) gated aggregation to selectively gather contexts for each query token based on its
+content, and (iii) element-wise modulation or affine transformation to inject the aggregated context into the query. Extensive experiments show FocalNets outperform the state-of-the-art SA counterparts (e.g., Swin and Focal Transformers) with similar computational costs on the tasks of image classification, object detection, and segmentation. Specifically, FocalNets with tiny and base size achieve 82.3% and 83.9% top-1 accuracy on ImageNet-1K. After pretrained on ImageNet-22K in 224 resolution, it attains 86.5% and 87.3% top-1 accuracy when finetuned with resolution 224 and 384, respectively. When transferred to downstream tasks, FocalNets exhibit clear superiority. For object detection with Mask R-CNN, FocalNet base trained with 1\times outperforms the Swin counterpart by 2.1 points and already surpasses Swin trained with 3\times schedule (49.0 v.s. 48.5). For semantic segmentation with UPerNet, FocalNet base at single-scale outperforms Swin by 2.4, and beats Swin at multi-scale (50.5 v.s. 49.7). Using large FocalNet and Mask2former, we achieve 58.5 mIoU for ADE20K semantic segmentation, and 57.9 PQ for COCO Panoptic Segmentation. Using huge FocalNet and DINO, we achieved 64.3 and 64.4 mAP on COCO minival and test-dev, respectively, establishing new SoTA on top of much larger attention-based models like Swinv2-G and BEIT-3.*
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/microsoft/FocalNet).
+
+## FocalNetConfig
+
+[[autodoc]] FocalNetConfig
+
+## FocalNetModel
+
+[[autodoc]] FocalNetModel
+ - forward
+
+## FocalNetForMaskedImageModeling
+
+[[autodoc]] FocalNetForMaskedImageModeling
+ - forward
+
+## FocalNetForImageClassification
+
+[[autodoc]] FocalNetForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/fsmt.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/fsmt.md
new file mode 100644
index 0000000000000000000000000000000000000000..27c7d3a899c4c1cafdfc9098563713bc060937e0
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/fsmt.md
@@ -0,0 +1,65 @@
+
+*This model was released on 2019-07-15 and added to Hugging Face Transformers on 2020-11-16.*
+
+# FSMT
+
+## Overview
+
+FSMT (FairSeq MachineTranslation) models were introduced in [Facebook FAIR's WMT19 News Translation Task Submission](https://huggingface.co/papers/1907.06616) by Nathan Ng, Kyra Yee, Alexei Baevski, Myle Ott, Michael Auli, Sergey Edunov.
+
+The abstract of the paper is the following:
+
+*This paper describes Facebook FAIR's submission to the WMT19 shared news translation task. We participate in two
+language pairs and four language directions, English <-> German and English <-> Russian. Following our submission from
+last year, our baseline systems are large BPE-based transformer models trained with the Fairseq sequence modeling
+toolkit which rely on sampled back-translations. This year we experiment with different bitext data filtering schemes,
+as well as with adding filtered back-translated data. We also ensemble and fine-tune our models on domain-specific
+data, then decode using noisy channel model reranking. Our submissions are ranked first in all four directions of the
+human evaluation campaign. On En->De, our system significantly outperforms other systems as well as human translations.
+This system improves upon our WMT'18 submission by 4.5 BLEU points.*
+
+This model was contributed by [stas](https://huggingface.co/stas). The original code can be found
+[here](https://github.com/pytorch/fairseq/tree/master/examples/wmt19).
+
+## Implementation Notes
+
+- FSMT uses source and target vocabulary pairs that aren't combined into one. It doesn't share embeddings tokens
+ either. Its tokenizer is very similar to [`XLMTokenizer`] and the main model is derived from
+ [`BartModel`].
+
+
+## FSMTConfig
+
+[[autodoc]] FSMTConfig
+
+## FSMTTokenizer
+
+[[autodoc]] FSMTTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## FSMTModel
+
+[[autodoc]] FSMTModel
+ - forward
+
+## FSMTForConditionalGeneration
+
+[[autodoc]] FSMTForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/funnel.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/funnel.md
new file mode 100644
index 0000000000000000000000000000000000000000..606541d38846bcb179f6805bf1382d67b75cae62
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/funnel.md
@@ -0,0 +1,181 @@
+
+*This model was released on 2020-06-05 and added to Hugging Face Transformers on 2020-11-16.*
+
+# Funnel Transformer
+
+
+
+
+
+
+## Overview
+
+The Funnel Transformer model was proposed in the paper [Funnel-Transformer: Filtering out Sequential Redundancy for
+Efficient Language Processing](https://huggingface.co/papers/2006.03236). It is a bidirectional transformer model, like
+BERT, but with a pooling operation after each block of layers, a bit like in traditional convolutional neural networks
+(CNN) in computer vision.
+
+The abstract from the paper is the following:
+
+*With the success of language pretraining, it is highly desirable to develop more efficient architectures of good
+scalability that can exploit the abundant unlabeled data at a lower cost. To improve the efficiency, we examine the
+much-overlooked redundancy in maintaining a full-length token-level presentation, especially for tasks that only
+require a single-vector presentation of the sequence. With this intuition, we propose Funnel-Transformer which
+gradually compresses the sequence of hidden states to a shorter one and hence reduces the computation cost. More
+importantly, by re-investing the saved FLOPs from length reduction in constructing a deeper or wider model, we further
+improve the model capacity. In addition, to perform token-level predictions as required by common pretraining
+objectives, Funnel-Transformer is able to recover a deep representation for each token from the reduced hidden sequence
+via a decoder. Empirically, with comparable or fewer FLOPs, Funnel-Transformer outperforms the standard Transformer on
+a wide variety of sequence-level prediction tasks, including text classification, language understanding, and reading
+comprehension.*
+
+This model was contributed by [sgugger](https://huggingface.co/sgugger). The original code can be found [here](https://github.com/laiguokun/Funnel-Transformer).
+
+## Usage tips
+
+- Since Funnel Transformer uses pooling, the sequence length of the hidden states changes after each block of layers. This way, their length is divided by 2, which speeds up the computation of the next hidden states.
+ The base model therefore has a final sequence length that is a quarter of the original one. This model can be used
+ directly for tasks that just require a sentence summary (like sequence classification or multiple choice). For other
+ tasks, the full model is used; this full model has a decoder that upsamples the final hidden states to the same
+ sequence length as the input.
+- For tasks such as classification, this is not a problem, but for tasks like masked language modeling or token classification, we need a hidden state with the same sequence length as the original input. In those cases, the final hidden states are upsampled to the input sequence length and go through two additional layers. That's why there are two versions of each checkpoint. The version suffixed with “-base” contains only the three blocks, while the version without that suffix contains the three blocks and the upsampling head with its additional layers.
+- The Funnel Transformer checkpoints are all available with a full version and a base version. The first ones should be
+ used for [`FunnelModel`], [`FunnelForPreTraining`],
+ [`FunnelForMaskedLM`], [`FunnelForTokenClassification`] and
+ [`FunnelForQuestionAnswering`]. The second ones should be used for
+ [`FunnelBaseModel`], [`FunnelForSequenceClassification`] and
+ [`FunnelForMultipleChoice`].
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+
+## FunnelConfig
+
+[[autodoc]] FunnelConfig
+
+## FunnelTokenizer
+
+[[autodoc]] FunnelTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## FunnelTokenizerFast
+
+[[autodoc]] FunnelTokenizerFast
+
+## Funnel specific outputs
+
+[[autodoc]] models.funnel.modeling_funnel.FunnelForPreTrainingOutput
+
+[[autodoc]] models.funnel.modeling_tf_funnel.TFFunnelForPreTrainingOutput
+
+
+
+
+## FunnelBaseModel
+
+[[autodoc]] FunnelBaseModel
+ - forward
+
+## FunnelModel
+
+[[autodoc]] FunnelModel
+ - forward
+
+## FunnelModelForPreTraining
+
+[[autodoc]] FunnelForPreTraining
+ - forward
+
+## FunnelForMaskedLM
+
+[[autodoc]] FunnelForMaskedLM
+ - forward
+
+## FunnelForSequenceClassification
+
+[[autodoc]] FunnelForSequenceClassification
+ - forward
+
+## FunnelForMultipleChoice
+
+[[autodoc]] FunnelForMultipleChoice
+ - forward
+
+## FunnelForTokenClassification
+
+[[autodoc]] FunnelForTokenClassification
+ - forward
+
+## FunnelForQuestionAnswering
+
+[[autodoc]] FunnelForQuestionAnswering
+ - forward
+
+
+
+
+## TFFunnelBaseModel
+
+[[autodoc]] TFFunnelBaseModel
+ - call
+
+## TFFunnelModel
+
+[[autodoc]] TFFunnelModel
+ - call
+
+## TFFunnelModelForPreTraining
+
+[[autodoc]] TFFunnelForPreTraining
+ - call
+
+## TFFunnelForMaskedLM
+
+[[autodoc]] TFFunnelForMaskedLM
+ - call
+
+## TFFunnelForSequenceClassification
+
+[[autodoc]] TFFunnelForSequenceClassification
+ - call
+
+## TFFunnelForMultipleChoice
+
+[[autodoc]] TFFunnelForMultipleChoice
+ - call
+
+## TFFunnelForTokenClassification
+
+[[autodoc]] TFFunnelForTokenClassification
+ - call
+
+## TFFunnelForQuestionAnswering
+
+[[autodoc]] TFFunnelForQuestionAnswering
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/fuyu.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/fuyu.md
new file mode 100644
index 0000000000000000000000000000000000000000..91506f88395e71d52795532977d893ed37e12181
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/fuyu.md
@@ -0,0 +1,124 @@
+
+*This model was released on 2023-10-17 and added to Hugging Face Transformers on 2023-10-19.*
+
+# Fuyu
+
+
+
+
+
+## Overview
+
+The Fuyu model was created by [ADEPT](https://www.adept.ai/blog/fuyu-8b), and authored by Rohan Bavishi, Erich Elsen, Curtis Hawthorne, Maxwell Nye, Augustus Odena, Arushi Somani, Sağnak Taşırlar.
+
+The authors introduced Fuyu-8B, a decoder-only multimodal model based on the classic transformers architecture, with query and key normalization. A linear encoder is added to create multimodal embeddings from image inputs.
+
+By treating image tokens like text tokens and using a special image-newline character, the model knows when an image line ends. Image positional embeddings are removed. This avoids the need for different training phases for various image resolutions. With 8 billion parameters and licensed under CC-BY-NC, Fuyu-8B is notable for its ability to handle both text and images, its impressive context size of 16K, and its overall performance.
+
+
+
+The `Fuyu` models were trained using `bfloat16`, but the original inference uses `float16` The checkpoints uploaded on the hub use `torch_dtype = 'float16'` which will be
+used by the `AutoModel` API to cast the checkpoints from `torch.float32` to `torch.float16`.
+
+The `dtype` of the online weights is mostly irrelevant, unless you are using `torch_dtype="auto"` when initializing a model using `model = AutoModelForCausalLM.from_pretrained("path", torch_dtype = "auto")`. The reason is that the model will first be downloaded ( using the `dtype` of the checkpoints online) then it will be cast to the default `dtype` of `torch` (becomes `torch.float32`). Users should specify the `torch_dtype` they want, and if they don't it will be `torch.float32`.
+
+Finetuning the model in `float16` is not recommended and known to produce `nan`, as such the model should be fine-tuned in `bfloat16`.
+
+
+
+
+Tips:
+
+- To convert the model, you need to clone the original repository using `git clone https://github.com/persimmon-ai-labs/adept-inference`, then get the checkpoints:
+
+```bash
+git clone https://github.com/persimmon-ai-labs/adept-inference
+wget path/to/fuyu-8b-model-weights.tar
+tar -xvf fuyu-8b-model-weights.tar
+python src/transformers/models/fuyu/convert_fuyu_weights_to_hf.py --input_dir /path/to/downloaded/fuyu/weights/ --output_dir /output/path \
+ --pt_model_path /path/to/fuyu_8b_release/iter_0001251/mp_rank_00/model_optim_rng.pt
+ --ada_lib_path /path/to/adept-inference
+```
+
+For the chat model:
+```bash
+wget https://axtkn4xl5cip.objectstorage.us-phoenix-1.oci.customer-oci.com/n/axtkn4xl5cip/b/adept-public-data/o/8b_chat_model_release.tar
+tar -xvf 8b_base_model_release.tar
+```
+Then, model can be loaded via:
+
+```py
+from transformers import FuyuConfig, FuyuForCausalLM
+model_config = FuyuConfig()
+model = FuyuForCausalLM(model_config).from_pretrained('/output/path')
+```
+
+Inputs need to be passed through a specific Processor to have the correct formats.
+A processor requires an image_processor and a tokenizer. Hence, inputs can be loaded via:
+
+```py
+from PIL import Image
+from transformers import AutoTokenizer
+from transformers.models.fuyu.processing_fuyu import FuyuProcessor
+from transformers.models.fuyu.image_processing_fuyu import FuyuImageProcessor
+
+
+tokenizer = AutoTokenizer.from_pretrained('adept-hf-collab/fuyu-8b')
+image_processor = FuyuImageProcessor()
+
+
+processor = FuyuProcessor(image_processor=image_processor, tokenizer=tokenizer)
+text_prompt = "Generate a coco-style caption.\\n"
+
+bus_image_url = "https://huggingface.co/datasets/hf-internal-testing/fixtures-captioning/resolve/main/bus.png"
+bus_image_pil = Image.open(io.BytesIO(requests.get(bus_image_url).content))
+inputs_to_model = processor(images=bus_image_pil, text=text_prompt)
+
+
+```
+
+This model was contributed by [Molbap](https://huggingface.co/Molbap).
+The original code can be found [here](https://github.com/persimmon-ai-labs/adept-inference).
+
+- Fuyu uses a `sentencepiece` based tokenizer, with a `Unigram` model. It supports bytefallback, which is only available in `tokenizers==0.14.0` for the fast tokenizer.
+The `LlamaTokenizer` is used as it is a standard wrapper around sentencepiece.
+
+- The authors suggest to use the following prompt for image captioning: `f"Generate a coco-style caption.\\n"`
+
+
+## FuyuConfig
+
+[[autodoc]] FuyuConfig
+
+## FuyuModel
+
+[[autodoc]] FuyuModel
+
+## FuyuForCausalLM
+
+[[autodoc]] FuyuForCausalLM
+ - forward
+
+## FuyuImageProcessor
+
+[[autodoc]] FuyuImageProcessor
+ - __call__
+
+## FuyuProcessor
+
+[[autodoc]] FuyuProcessor
+ - __call__
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gemma.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gemma.md
new file mode 100644
index 0000000000000000000000000000000000000000..ad4a3e2b1647d40fe81a2722ca14eb2e649cff36
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gemma.md
@@ -0,0 +1,202 @@
+
+
+*This model was released on 2024-03-13 and added to Hugging Face Transformers on 2024-02-21.*
+
+
+
+
+
+
+
+
+
+
+
+
+# Gemma
+
+[Gemma](https://huggingface.co/papers/2403.08295) is a family of lightweight language models with pretrained and instruction-tuned variants, available in 2B and 7B parameters. The architecture is based on a transformer decoder-only design. It features Multi-Query Attention, rotary positional embeddings (RoPE), GeGLU activation functions, and RMSNorm layer normalization.
+
+The instruction-tuned variant was fine-tuned with supervised learning on instruction-following data, followed by reinforcement learning from human feedback (RLHF) to align the model outputs with human preferences.
+
+You can find all the original Gemma checkpoints under the [Gemma](https://huggingface.co/collections/google/gemma-release-65d5efbccdbb8c4202ec078b) release.
+
+
+> [!TIP]
+> Click on the Gemma models in the right sidebar for more examples of how to apply Gemma to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`] or the [`AutoModel`] class, and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="text-generation",
+ model="google/gemma-2b",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+)
+
+pipeline("LLMs generate text through a process known as", max_new_tokens=50)
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoTokenizer, AutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("google/gemma-2b")
+model = AutoModelForCausalLM.from_pretrained(
+ "google/gemma-2b",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+
+input_text = "LLMs generate text through a process known as"
+input_ids = tokenizer(input_text, return_tensors="pt").to(model.device)
+
+outputs = model.generate(**input_ids, max_new_tokens=50, cache_implementation="static")
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+echo -e "LLMs generate text through a process known as" | transformers run --task text-generation --model google/gemma-2b --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to int4.
+
+```py
+#!pip install bitsandbytes
+import torch
+from transformers import AutoTokenizer, AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_compute_dtype=torch.bfloat16,
+ bnb_4bit_quant_type="nf4"
+)
+tokenizer = AutoTokenizer.from_pretrained("google/gemma-7b")
+model = AutoModelForCausalLM.from_pretrained(
+ "google/gemma-7b",
+ quantization_config=quantization_config,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+
+input_text = "LLMs generate text through a process known as."
+input_ids = tokenizer(input_text, return_tensors="pt").to(model.device)
+outputs = model.generate(
+ **input_ids,
+ max_new_tokens=50,
+ cache_implementation="static"
+)
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+Use the [AttentionMaskVisualizer](https://github.com/huggingface/transformers/blob/beb9b5b02246b9b7ee81ddf938f93f44cfeaad19/src/transformers/utils/attention_visualizer.py#L139) to better understand what tokens the model can and cannot attend to.
+
+```py
+from transformers.utils.attention_visualizer import AttentionMaskVisualizer
+
+visualizer = AttentionMaskVisualizer("google/gemma-2b")
+visualizer("LLMs generate text through a process known as")
+```
+
+
+
+
+
+## Notes
+
+- The original Gemma models support standard kv-caching used in many transformer-based language models. You can use use the default [`DynamicCache`] instance or a tuple of tensors for past key values during generation. This makes it compatible with typical autoregressive generation workflows.
+
+ ```py
+ import torch
+ from transformers import AutoTokenizer, AutoModelForCausalLM, DynamicCache
+
+ tokenizer = AutoTokenizer.from_pretrained("google/gemma-2b")
+ model = AutoModelForCausalLM.from_pretrained(
+ "google/gemma-2b",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa"
+ )
+ input_text = "LLMs generate text through a process known as"
+ input_ids = tokenizer(input_text, return_tensors="pt").to(model.device)
+ past_key_values = DynamicCache()
+ outputs = model.generate(**input_ids, max_new_tokens=50, past_key_values=past_key_values)
+ print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+ ```
+
+## GemmaConfig
+
+[[autodoc]] GemmaConfig
+
+## GemmaTokenizer
+
+[[autodoc]] GemmaTokenizer
+
+
+## GemmaTokenizerFast
+
+[[autodoc]] GemmaTokenizerFast
+
+## GemmaModel
+
+[[autodoc]] GemmaModel
+ - forward
+
+## GemmaForCausalLM
+
+[[autodoc]] GemmaForCausalLM
+ - forward
+
+## GemmaForSequenceClassification
+
+[[autodoc]] GemmaForSequenceClassification
+ - forward
+
+## GemmaForTokenClassification
+
+[[autodoc]] GemmaForTokenClassification
+ - forward
+
+## FlaxGemmaModel
+
+[[autodoc]] FlaxGemmaModel
+ - __call__
+
+## FlaxGemmaForCausalLM
+
+[[autodoc]] FlaxGemmaForCausalLM
+ - __call__
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gemma2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gemma2.md
new file mode 100644
index 0000000000000000000000000000000000000000..ff227c3e3882a42979f7a961c227766fbbb93d49
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gemma2.md
@@ -0,0 +1,168 @@
+
+
+*This model was released on 2024-07-31 and added to Hugging Face Transformers on 2024-06-27.*
+
+
+
+
+
+
+
+
+
+
+
+# Gemma2
+
+[Gemma 2](https://huggingface.co/papers/2408.00118) is a family of language models with pretrained and instruction-tuned variants, available in 2B, 9B, 27B parameters. The architecture is similar to the previous Gemma, except it features interleaved local attention (4096 tokens) and global attention (8192 tokens) and grouped-query attention (GQA) to increase inference performance.
+
+The 2B and 9B models are trained with knowledge distillation, and the instruction-tuned variant was post-trained with supervised fine-tuning and reinforcement learning.
+
+You can find all the original Gemma 2 checkpoints under the [Gemma 2](https://huggingface.co/collections/google/gemma-2-release-667d6600fd5220e7b967f315) collection.
+
+> [!TIP]
+> Click on the Gemma 2 models in the right sidebar for more examples of how to apply Gemma to different language tasks.
+
+The example below demonstrates how to chat with the model with [`Pipeline`] or the [`AutoModel`] class, and from the command line.
+
+
+
+
+
+```python
+import torch
+from transformers import pipeline
+
+pipe = pipeline(
+ task="text-generation",
+ model="google/gemma-2-9b",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+)
+
+pipe("Explain quantum computing simply. ", max_new_tokens=50)
+```
+
+
+
+
+```python
+import torch
+from transformers import AutoTokenizer, AutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("google/gemma-2-9b")
+model = AutoModelForCausalLM.from_pretrained(
+ "google/gemma-2-9b",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+
+input_text = "Explain quantum computing simply."
+input_ids = tokenizer(input_text, return_tensors="pt").to(model.device)
+
+outputs = model.generate(**input_ids, max_new_tokens=32, cache_implementation="static")
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+
+```
+
+
+
+
+```
+echo -e "Explain quantum computing simply." | transformers run --task text-generation --model google/gemma-2-2b --device 0
+```
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to int4.
+
+```python
+import torch
+from transformers import AutoTokenizer, AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_4bit=True)
+tokenizer = AutoTokenizer.from_pretrained("google/gemma-2-27b")
+model = AutoModelForCausalLM.from_pretrained(
+ "google/gemma-2-27b",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+
+input_text = "Explain quantum computing simply."
+input_ids = tokenizer(input_text, return_tensors="pt").to(model.device)
+
+outputs = model.generate(**input_ids, max_new_tokens=32, cache_implementation="static")
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+Use the [AttentionMaskVisualizer](https://github.com/huggingface/transformers/blob/beb9b5b02246b9b7ee81ddf938f93f44cfeaad19/src/transformers/utils/attention_visualizer.py#L139) to better understand what tokens the model can and cannot attend to.
+
+
+```python
+from transformers.utils.attention_visualizer import AttentionMaskVisualizer
+visualizer = AttentionMaskVisualizer("google/gemma-2b")
+visualizer("You are an assistant. Make sure you print me")
+```
+
+
+
+
+
+## Notes
+
+- Use a [`HybridCache`] instance to enable caching in Gemma 2. Gemma 2 doesn't support kv-caching strategies like [`DynamicCache`] or tuples of tensors because it uses sliding window attention every second layer.
+
+ ```python
+ from transformers import AutoTokenizer, AutoModelForCausalLM, HybridCache
+
+ model = AutoModelForCausalLM.from_pretrained("google/gemma-2-2b")
+ tokenizer = AutoTokenizer.from_pretrained("google/gemma-2-2b")
+
+ inputs = tokenizer(text="My name is Gemma", return_tensors="pt")
+ max_generated_length = inputs.input_ids.shape[1] + 10
+ past_key_values = HybridCache(config=model.config, max_cache_len=max_generated_length)
+ outputs = model(**inputs, past_key_values=past_key_values, use_cache=True)
+ ```
+
+## Gemma2Config
+
+[[autodoc]] Gemma2Config
+
+## Gemma2Model
+
+[[autodoc]] Gemma2Model
+ - forward
+
+## Gemma2ForCausalLM
+
+[[autodoc]] Gemma2ForCausalLM
+ - forward
+
+## Gemma2ForSequenceClassification
+
+[[autodoc]] Gemma2ForSequenceClassification
+ - forward
+
+## Gemma2ForTokenClassification
+
+[[autodoc]] Gemma2ForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gemma3.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gemma3.md
new file mode 100644
index 0000000000000000000000000000000000000000..3e949df4ef21bdee2a8f173f44bb43846a3f86bc
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gemma3.md
@@ -0,0 +1,275 @@
+
+
+*This model was released on 2025-03-25 and added to Hugging Face Transformers on 2025-03-12.*
+
+
+
+
+
+
+
+
+# Gemma 3
+
+[Gemma 3](https://huggingface.co/papers/2503.19786) is a multimodal model with pretrained and instruction-tuned variants, available in 1B, 13B, and 27B parameters. The architecture is mostly the same as the previous Gemma versions. The key differences are alternating 5 local sliding window self-attention layers for every global self-attention layer, support for a longer context length of 128K tokens, and a [SigLip](./siglip) encoder that can "pan & scan" high-resolution images to prevent information from disappearing in high resolution images or images with non-square aspect ratios.
+
+The instruction-tuned variant was post-trained with knowledge distillation and reinforcement learning.
+
+You can find all the original Gemma 3 checkpoints under the [Gemma 3](https://huggingface.co/collections/google/gemma-3-release-67c6c6f89c4f76621268bb6d) release.
+
+> [!TIP]
+> Click on the Gemma 3 models in the right sidebar for more examples of how to apply Gemma to different vision and language tasks.
+
+The example below demonstrates how to generate text based on an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="image-text-to-text",
+ model="google/gemma-3-4b-pt",
+ device=0,
+ torch_dtype=torch.bfloat16
+)
+pipeline(
+ "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg",
+ text=" What is shown in this image?"
+)
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoProcessor, Gemma3ForConditionalGeneration
+
+model = Gemma3ForConditionalGeneration.from_pretrained(
+ "google/gemma-3-4b-it",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+processor = AutoProcessor.from_pretrained(
+ "google/gemma-3-4b-it",
+ padding_side="left"
+)
+
+messages = [
+ {
+ "role": "system",
+ "content": [
+ {"type": "text", "text": "You are a helpful assistant."}
+ ]
+ },
+ {
+ "role": "user", "content": [
+ {"type": "image", "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ]
+ },
+]
+inputs = processor.apply_chat_template(
+ messages,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+ add_generation_prompt=True,
+).to(model.device)
+
+output = model.generate(**inputs, max_new_tokens=50, cache_implementation="static")
+print(processor.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+echo -e "Plants create energy through a process known as" | transformers run --task text-generation --model google/gemma-3-1b-pt --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [torchao](../quantization/torchao) to only quantize the weights to int4.
+
+```py
+# pip install torchao
+import torch
+from transformers import TorchAoConfig, Gemma3ForConditionalGeneration, AutoProcessor
+
+quantization_config = TorchAoConfig("int4_weight_only", group_size=128)
+model = Gemma3ForConditionalGeneration.from_pretrained(
+ "google/gemma-3-27b-it",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+processor = AutoProcessor.from_pretrained(
+ "google/gemma-3-27b-it",
+ padding_side="left"
+)
+
+messages = [
+ {
+ "role": "system",
+ "content": [
+ {"type": "text", "text": "You are a helpful assistant."}
+ ]
+ },
+ {
+ "role": "user", "content": [
+ {"type": "image", "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ]
+ },
+]
+inputs = processor.apply_chat_template(
+ messages,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+ add_generation_prompt=True,
+).to(model.device)
+
+output = model.generate(**inputs, max_new_tokens=50, cache_implementation="static")
+print(processor.decode(output[0], skip_special_tokens=True))
+```
+
+Use the [AttentionMaskVisualizer](https://github.com/huggingface/transformers/blob/beb9b5b02246b9b7ee81ddf938f93f44cfeaad19/src/transformers/utils/attention_visualizer.py#L139) to better understand what tokens the model can and cannot attend to.
+
+```py
+from transformers.utils.attention_visualizer import AttentionMaskVisualizer
+
+visualizer = AttentionMaskVisualizer("google/gemma-3-4b-it")
+visualizer("What is shown in this image?")
+```
+
+
+
+
+
+## Notes
+
+- Use [`Gemma3ForConditionalGeneration`] for image-and-text and image-only inputs.
+- Gemma 3 supports multiple input images, but make sure the images are correctly batched before passing them to the processor. Each batch should be a list of one or more images.
+
+ ```py
+ url_cow = "https://media.istockphoto.com/id/1192867753/photo/cow-in-berchida-beach-siniscola.jpg?s=612x612&w=0&k=20&c=v0hjjniwsMNfJSuKWZuIn8pssmD5h5bSN1peBd1CmH4="
+ url_cat = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+
+ messages =[
+ {
+ "role": "system",
+ "content": [
+ {"type": "text", "text": "You are a helpful assistant."}
+ ]
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": url_cow},
+ {"type": "image", "url": url_cat},
+ {"type": "text", "text": "Which image is cuter?"},
+ ]
+ },
+ ]
+ ```
+- Text passed to the processor should have a `` token wherever an image should be inserted.
+- The processor has its own [`~ProcessorMixin.apply_chat_template`] method to convert chat messages to model inputs.
+- By default, images aren't cropped and only the base image is forwarded to the model. In high resolution images or images with non-square aspect ratios, artifacts can result because the vision encoder uses a fixed resolution of 896x896. To prevent these artifacts and improve performance during inference, set `do_pan_and_scan=True` to crop the image into multiple smaller patches and concatenate them with the base image embedding. You can disable pan and scan for faster inference.
+
+ ```diff
+ inputs = processor.apply_chat_template(
+ messages,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+ add_generation_prompt=True,
+ + do_pan_and_scan=True,
+ ).to(model.device)
+ ```
+- For Gemma-3 1B checkpoint trained in text-only mode, use [`AutoModelForCausalLM`] instead.
+
+ ```py
+ import torch
+ from transformers import AutoModelForCausalLM, AutoTokenizer
+
+ tokenizer = AutoTokenizer.from_pretrained(
+ "google/gemma-3-1b-pt",
+ )
+ model = AutoModelForCausalLM.from_pretrained(
+ "google/gemma-3-1b-pt",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa"
+ )
+ input_ids = tokenizer("Plants create energy through a process known as", return_tensors="pt").to(model.device)
+
+ output = model.generate(**input_ids, cache_implementation="static")
+ print(tokenizer.decode(output[0], skip_special_tokens=True))
+ ```
+
+## Gemma3ImageProcessor
+
+[[autodoc]] Gemma3ImageProcessor
+
+## Gemma3ImageProcessorFast
+
+[[autodoc]] Gemma3ImageProcessorFast
+
+## Gemma3Processor
+
+[[autodoc]] Gemma3Processor
+
+## Gemma3TextConfig
+
+[[autodoc]] Gemma3TextConfig
+
+## Gemma3Config
+
+[[autodoc]] Gemma3Config
+
+## Gemma3TextModel
+
+[[autodoc]] Gemma3TextModel
+ - forward
+
+## Gemma3Model
+
+[[autodoc]] Gemma3Model
+
+## Gemma3ForCausalLM
+
+[[autodoc]] Gemma3ForCausalLM
+ - forward
+
+## Gemma3ForConditionalGeneration
+
+[[autodoc]] Gemma3ForConditionalGeneration
+ - forward
+
+## Gemma3ForSequenceClassification
+
+[[autodoc]] Gemma3ForSequenceClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gemma3n.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gemma3n.md
new file mode 100644
index 0000000000000000000000000000000000000000..eef1cb3713fd1a19d5649b344f7dde181f4174bd
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gemma3n.md
@@ -0,0 +1,206 @@
+
+
+*This model was released on 2025-05-20 and added to Hugging Face Transformers on 2025-06-26.*
+
+
+
+
+
+
+
+
+# Gemma3n
+
+## Overview
+
+[Gemma3n](https://developers.googleblog.com/en/introducing-gemma-3n/) is a multimodal model with pretrained and instruction-tuned variants, available in E4B and E2B sizes. While
+large portions of the language model architecture are shared with prior Gemma releases, there are many new additions in
+this model, including [Alternating Updates][altup] (AltUp), [Learned Augmented Residual Layer][laurel] (LAuReL),
+[MatFormer][matformer], Per-Layer Embeddings (PLE), [Activation Sparsity with Statistical Top-k][spark-transformer], and KV cache sharing. The language model uses
+a similar attention pattern to [Gemma 3](./gemma3) with alternating 4 local sliding window self-attention layers for
+every global self-attention layer with a maximum context length of 32k tokens. Gemma 3n introduces
+[MobileNet v5][mobilenetv5] as the vision encoder, using a default resolution of 768x768 pixels, and adds a newly
+trained audio encoder based on the [Universal Speech Model][usm] (USM) architecture.
+
+The instruction-tuned variant was post-trained with knowledge distillation and reinforcement learning.
+
+You can find all the original Gemma 3n checkpoints under the [Gemma 3n][gemma3n-collection] release.
+
+> [!TIP]
+> Click on the Gemma 3n models in the right sidebar for more examples of how to apply Gemma to different vision, audio,
+> and language tasks.
+
+The example below demonstrates how to generate text based on an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="image-text-to-text",
+ model="google/gemma-3n-e4b",
+ device=0,
+ torch_dtype=torch.bfloat16
+)
+pipeline(
+ "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg",
+ text=" What is shown in this image?"
+)
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoProcessor, Gemma3nForConditionalGeneration
+
+model = Gemma3nForConditionalGeneration.from_pretrained(
+ "google/gemma-3n-e4b-it",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+processor = AutoProcessor.from_pretrained(
+ "google/gemma-3n-e4b-it",
+ padding_side="left"
+)
+
+messages = [
+ {
+ "role": "system",
+ "content": [
+ {"type": "text", "text": "You are a helpful assistant."}
+ ]
+ },
+ {
+ "role": "user", "content": [
+ {"type": "image", "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ]
+ },
+]
+inputs = processor.apply_chat_template(
+ messages,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+ add_generation_prompt=True,
+).to("cuda")
+
+output = model.generate(**inputs, max_new_tokens=50, cache_implementation="static")
+print(processor.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+echo -e "Plants create energy through a process known as" | transformers run --task text-generation --model google/gemma-3n-e2b --device 0
+```
+
+
+
+
+## Notes
+
+- Use [`Gemma3nForConditionalGeneration`] for image-audio-and-text, image-and-text, image-and-audio, audio-and-text,
+ image-only and audio-only inputs.
+- Gemma 3n supports multiple images per input, but make sure the images are correctly batched before passing them to
+ the processor. Each batch should be a list of one or more images.
+
+ ```py
+ url_cow = "https://media.istockphoto.com/id/1192867753/photo/cow-in-berchida-beach-siniscola.jpg?s=612x612&w=0&k=20&c=v0hjjniwsMNfJSuKWZuIn8pssmD5h5bSN1peBd1CmH4="
+ url_cat = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+
+ messages =[
+ {
+ "role": "system",
+ "content": [
+ {"type": "text", "text": "You are a helpful assistant."}
+ ]
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": url_cow},
+ {"type": "image", "url": url_cat},
+ {"type": "text", "text": "Which image is cuter?"},
+ ]
+ },
+ ]
+ ```
+- Text passed to the processor should have a `` token wherever an image should be inserted.
+- Gemma 3n accept at most one target audio clip per input, though multiple audio clips can be provided in few-shot
+ prompts, for example.
+- Text passed to the processor should have a `` token wherever an audio clip should be inserted.
+- The processor has its own [`~ProcessorMixin.apply_chat_template`] method to convert chat messages to model inputs.
+
+## Gemma3nAudioFeatureExtractor
+
+[[autodoc]] Gemma3nAudioFeatureExtractor
+
+## Gemma3nProcessor
+
+[[autodoc]] Gemma3nProcessor
+
+## Gemma3nTextConfig
+
+[[autodoc]] Gemma3nTextConfig
+
+## Gemma3nVisionConfig
+
+[[autodoc]] Gemma3nVisionConfig
+
+## Gemma3nAudioConfig
+
+[[autodoc]] Gemma3nAudioConfig
+
+## Gemma3nConfig
+
+[[autodoc]] Gemma3nConfig
+
+## Gemma3nTextModel
+
+[[autodoc]] Gemma3nTextModel
+ - forward
+
+## Gemma3nModel
+
+[[autodoc]] Gemma3nModel
+ - forward
+
+## Gemma3nForCausalLM
+
+[[autodoc]] Gemma3nForCausalLM
+ - forward
+
+## Gemma3nForConditionalGeneration
+
+[[autodoc]] Gemma3nForConditionalGeneration
+ - forward
+
+[altup]: https://proceedings.neurips.cc/paper_files/paper/2023/hash/f2059277ac6ce66e7e5543001afa8bb5-Abstract-Conference.html
+[attention-mask-viz]: https://github.com/huggingface/transformers/blob/beb9b5b02246b9b7ee81ddf938f93f44cfeaad19/src/transformers/utils/attention_visualizer.py#L139
+[gemma3n-collection]: https://huggingface.co/collections/google/gemma-3n
+[laurel]: https://huggingface.co/papers/2411.07501
+[matformer]: https://huggingface.co/papers/2310.07707
+[spark-transformer]: https://arxiv.org/abs/2506.06644
+[usm]: https://huggingface.co/papers/2303.01037
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/git.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/git.md
new file mode 100644
index 0000000000000000000000000000000000000000..a2aa0901b21fd030252af1878e0aa84a015e6edf
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/git.md
@@ -0,0 +1,84 @@
+
+*This model was released on 2022-05-27 and added to Hugging Face Transformers on 2023-01-03.*
+
+# GIT
+
+
+
+
+
+## Overview
+
+The GIT model was proposed in [GIT: A Generative Image-to-text Transformer for Vision and Language](https://huggingface.co/papers/2205.14100) by
+Jianfeng Wang, Zhengyuan Yang, Xiaowei Hu, Linjie Li, Kevin Lin, Zhe Gan, Zicheng Liu, Ce Liu, Lijuan Wang. GIT is a decoder-only Transformer
+that leverages [CLIP](clip)'s vision encoder to condition the model on vision inputs besides text. The model obtains state-of-the-art results on
+image captioning and visual question answering benchmarks.
+
+The abstract from the paper is the following:
+
+*In this paper, we design and train a Generative Image-to-text Transformer, GIT, to unify vision-language tasks such as image/video captioning and question answering. While generative models provide a consistent network architecture between pre-training and fine-tuning, existing work typically contains complex structures (uni/multi-modal encoder/decoder) and depends on external modules such as object detectors/taggers and optical character recognition (OCR). In GIT, we simplify the architecture as one image encoder and one text decoder under a single language modeling task. We also scale up the pre-training data and the model size to boost the model performance. Without bells and whistles, our GIT establishes new state of the arts on 12 challenging benchmarks with a large margin. For instance, our model surpasses the human performance for the first time on TextCaps (138.2 vs. 125.5 in CIDEr). Furthermore, we present a new scheme of generation-based image classification and scene text recognition, achieving decent performance on standard benchmarks.*
+
+
+
+ GIT architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/microsoft/GenerativeImage2Text).
+
+## Usage tips
+
+- GIT is implemented in a very similar way to GPT-2, the only difference being that the model is also conditioned on `pixel_values`.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with GIT.
+
+- Demo notebooks regarding inference + fine-tuning GIT on custom data can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/GIT).
+- See also: [Causal language modeling task guide](../tasks/language_modeling)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we will review it.
+The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## GitVisionConfig
+
+[[autodoc]] GitVisionConfig
+
+## GitVisionModel
+
+[[autodoc]] GitVisionModel
+ - forward
+
+## GitConfig
+
+[[autodoc]] GitConfig
+ - all
+
+## GitProcessor
+
+[[autodoc]] GitProcessor
+ - __call__
+
+## GitModel
+
+[[autodoc]] GitModel
+ - forward
+
+## GitForCausalLM
+
+[[autodoc]] GitForCausalLM
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm.md
new file mode 100644
index 0000000000000000000000000000000000000000..ca50c32da21b62922da09ac306728f4faa980591
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm.md
@@ -0,0 +1,107 @@
+
+*This model was released on 2024-06-18 and added to Hugging Face Transformers on 2024-10-18.*
+
+# GLM
+
+
+
+
+
+
+
+
+## Overview
+
+The GLM Model was proposed
+in [ChatGLM: A Family of Large Language Models from GLM-130B to GLM-4 All Tools](https://huggingface.co/papers/2406.12793)
+by GLM Team, THUDM & ZhipuAI.
+
+The abstract from the paper is the following:
+
+*We introduce ChatGLM, an evolving family of large language models that we have been developing over time. This report
+primarily focuses on the GLM-4 language series, which includes GLM-4, GLM-4-Air, and GLM-4-9B. They represent our most
+capable models that are trained with all the insights and lessons gained from the preceding three generations of
+ChatGLM. To date, the GLM-4 models are pre-trained on ten trillions of tokens mostly in Chinese and English, along with
+a small set of corpus from 24 languages, and aligned primarily for Chinese and English usage. The high-quality alignment
+is achieved via a multi-stage post-training process, which involves supervised fine-tuning and learning from human
+feedback. Evaluations show that GLM-4 1) closely rivals or outperforms GPT-4 in terms of general metrics such as MMLU,
+GSM8K, MATH, BBH, GPQA, and HumanEval, 2) gets close to GPT-4-Turbo in instruction following as measured by IFEval, 3)
+matches GPT-4 Turbo (128K) and Claude 3 for long context tasks, and 4) outperforms GPT-4 in Chinese alignments as
+measured by AlignBench. The GLM-4 All Tools model is further aligned to understand user intent and autonomously decide
+when and which tool(s) to use—including web browser, Python interpreter, text-to-image model, and user-defined
+functions—to effectively complete complex tasks. In practical applications, it matches and even surpasses GPT-4 All
+Tools in tasks like accessing online information via web browsing and solving math problems using Python interpreter.
+Over the course, we have open-sourced a series of models, including ChatGLM-6B (three generations), GLM-4-9B (128K, 1M),
+GLM-4V-9B, WebGLM, and CodeGeeX, attracting over 10 million downloads on Hugging face in the year 2023 alone.*
+
+Tips:
+
+- This model was contributed by [THUDM](https://huggingface.co/THUDM). The most recent code can be
+ found [here](https://github.com/thudm/GLM-4).
+
+
+## Usage tips
+
+`GLM-4` can be found on the [Huggingface Hub](https://huggingface.co/collections/THUDM/glm-4-665fcf188c414b03c2f7e3b7)
+
+In the following, we demonstrate how to use `glm-4-9b-chat` for the inference. Note that we have used the ChatML format for dialog, in this demo we show how to leverage `apply_chat_template` for this purpose.
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, infer_device
+>>> device = infer_device() # the device to load the model onto
+
+>>> model = AutoModelForCausalLM.from_pretrained("THUDM/glm-4-9b-chat", device_map="auto", trust_remote_code=True)
+>>> tokenizer = AutoTokenizer.from_pretrained("THUDM/glm-4-9b-chat")
+
+>>> prompt = "Give me a short introduction to large language model."
+
+>>> messages = [{"role": "user", "content": prompt}]
+
+>>> text = tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
+
+>>> model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
+
+>>> generated_ids = model.generate(model_inputs.input_ids, max_new_tokens=512, do_sample=True)
+
+>>> generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(model_inputs.input_ids, generated_ids)]
+
+>>> response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+```
+
+## GlmConfig
+
+[[autodoc]] GlmConfig
+
+## GlmModel
+
+[[autodoc]] GlmModel
+ - forward
+
+## GlmForCausalLM
+
+[[autodoc]] GlmForCausalLM
+ - forward
+
+## GlmForSequenceClassification
+
+[[autodoc]] GlmForSequenceClassification
+ - forward
+
+## GlmForTokenClassification
+
+[[autodoc]] GlmForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm4.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm4.md
new file mode 100644
index 0000000000000000000000000000000000000000..a10926bd5a09da251ab78aebe5df1b35a0df5330
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm4.md
@@ -0,0 +1,76 @@
+
+*This model was released on 2024-06-18 and added to Hugging Face Transformers on 2025-04-09.*
+
+# Glm4
+
+## Overview
+
+The GLM family welcomes new members [GLM-4-0414](https://huggingface.co/papers/2406.12793) series models.
+
+The **GLM-4-32B-0414** series models, featuring 32 billion parameters. Its performance is comparable to OpenAI’s GPT
+series and DeepSeek’s V3/R1 series. It also supports very user-friendly local deployment features. GLM-4-32B-Base-0414
+was pre-trained on 15T of high-quality data, including substantial reasoning-type synthetic data. This lays the
+foundation for subsequent reinforcement learning extensions. In the post-training stage, we employed human preference
+alignment for dialogue scenarios. Additionally, using techniques like rejection sampling and reinforcement learning, we
+enhanced the model’s performance in instruction following, engineering code, and function calling, thus strengthening
+the atomic capabilities required for agent tasks. GLM-4-32B-0414 achieves good results in engineering code, Artifact
+generation, function calling, search-based Q&A, and report generation. In particular, on several benchmarks, such as
+code generation or specific Q&A tasks, GLM-4-32B-Base-0414 achieves comparable performance with those larger models like
+GPT-4o and DeepSeek-V3-0324 (671B).
+
+**GLM-Z1-32B-0414** is a reasoning model with deep thinking capabilities. This was developed based on GLM-4-32B-0414
+through cold start, extended reinforcement learning, and further training on tasks including mathematics, code, and
+logic. Compared to the base model, GLM-Z1-32B-0414 significantly improves mathematical abilities and the capability to
+solve complex tasks. During training, we also introduced general reinforcement learning based on pairwise ranking
+feedback, which enhances the model's general capabilities.
+
+**GLM-Z1-Rumination-32B-0414** is a deep reasoning model with rumination capabilities (against OpenAI's Deep Research).
+Unlike typical deep thinking models, the rumination model is capable of deeper and longer thinking to solve more
+open-ended and complex problems (e.g., writing a comparative analysis of AI development in two cities and their future
+development plans). Z1-Rumination is trained through scaling end-to-end reinforcement learning with responses graded by
+the ground truth answers or rubrics and can make use of search tools during its deep thinking process to handle complex
+tasks. The model shows significant improvements in research-style writing and complex tasks.
+
+Finally, **GLM-Z1-9B-0414** is a surprise. We employed all the aforementioned techniques to train a small model (9B).
+GLM-Z1-9B-0414 exhibits excellent capabilities in mathematical reasoning and general tasks. Its overall performance is
+top-ranked among all open-source models of the same size. Especially in resource-constrained scenarios, this model
+achieves an excellent balance between efficiency and effectiveness, providing a powerful option for users seeking
+lightweight deployment.
+
+## Glm4Config
+
+[[autodoc]] Glm4Config
+
+## Glm4Model
+
+[[autodoc]] Glm4Model
+ - forward
+
+## Glm4ForCausalLM
+
+[[autodoc]] Glm4ForCausalLM
+ - forward
+
+## Glm4ForSequenceClassification
+
+[[autodoc]] Glm4ForSequenceClassification
+ - forward
+
+## Glm4ForTokenClassification
+
+[[autodoc]] Glm4ForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm4_moe.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm4_moe.md
new file mode 100644
index 0000000000000000000000000000000000000000..3ea84ed3394160fc2d7ffa1f85c4caabc920aff3
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm4_moe.md
@@ -0,0 +1,50 @@
+
+*This model was released on 2025-07-28 and added to Hugging Face Transformers on 2025-07-21.*
+
+# Glm4Moe
+
+## Overview
+
+The [**GLM-4.5**](https://huggingface.co/papers/2508.06471) series models are foundation models designed for intelligent agents, MoE variants are documented here as Glm4Moe.
+
+GLM-4.5 has **355** billion total parameters with **32** billion active parameters, while GLM-4.5-Air adopts a more compact design with **106** billion total parameters and **12** billion active parameters. GLM-4.5 models unify reasoning, coding, and intelligent agent capabilities to meet the complex demands of intelligent agent applications.
+
+Both GLM-4.5 and GLM-4.5-Air are hybrid reasoning models that provide two modes: thinking mode for complex reasoning and tool usage, and non-thinking mode for immediate responses.
+
+We have open-sourced the base models, hybrid reasoning models, and FP8 versions of the hybrid reasoning models for both GLM-4.5 and GLM-4.5-Air. They are released under the MIT open-source license and can be used commercially and for secondary development.
+
+As demonstrated in our comprehensive evaluation across 12 industry-standard benchmarks, GLM-4.5 achieves exceptional performance with a score of **63.2**, in the **3rd** place among all the proprietary and open-source models. Notably, GLM-4.5-Air delivers competitive results at **59.8** while maintaining superior efficiency.
+
+
+
+For more eval results, show cases, and technical details, please visit our [technical report](https://huggingface.co/papers/2508.06471) or [technical blog](https://z.ai/blog/glm-4.5).
+
+The model code, tool parser and reasoning parser can be found in the implementation of [transformers](https://github.com/huggingface/transformers/tree/main/src/transformers/models/glm4_moe), [vLLM](https://github.com/vllm-project/vllm/blob/main/vllm/model_executor/models/glm4_moe_mtp.py) and [SGLang](https://github.com/sgl-project/sglang/blob/main/python/sglang/srt/models/glm4_moe.py).
+
+## Glm4MoeConfig
+
+[[autodoc]] Glm4MoeConfig
+
+## Glm4MoeModel
+
+[[autodoc]] Glm4MoeModel
+ - forward
+
+## Glm4MoeForCausalLM
+
+[[autodoc]] Glm4MoeForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm4v.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm4v.md
new file mode 100644
index 0000000000000000000000000000000000000000..f19a1a1130a137822496b4e718ee85bb8ddda571
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm4v.md
@@ -0,0 +1,206 @@
+
+*This model was released on 2025-07-01 and added to Hugging Face Transformers on 2025-06-25.*
+
+
+
+
+
+
+
+
+# GLM-4.1V
+
+## Overview
+
+**GLM-4.1V-9B-Thinking** is a bilingual vision-language model optimized for reasoning, built on GLM-4-9B. It introduces
+a "thinking paradigm" with reinforcement learning, achieving state-of-the-art results among 10B-class models and
+rivaling 72B-scale models. It supports 64k context, 4K resolution, and arbitrary aspect ratios, with an open-source base
+model for further research. You can check our paper [here](https://huggingface.co/papers/2507.01006). and below is a abstract.
+
+*We present GLM-4.1V-Thinking, a vision-language model (VLM) designed to advance general-purpose multimodal understanding
+and reasoning. In this report, we share our key findings in the development of the reasoning-centric training framework.
+We first develop a capable vision foundation model with significant potential through large-scale pre-training, which
+arguably sets the upper bound for the final performance. We then propose Reinforcement Learning with Curriculum
+Sampling (RLCS) to unlock the full potential of the model, leading to comprehensive capability enhancement across a
+diverse range of tasks, including STEM problem solving, video understanding, content recognition, coding, grounding,
+GUI-based agents, and long document understanding. We open-source GLM-4.1V-9B-Thinking, which achieves state-of-the-art
+performance among models of comparable size. In a comprehensive evaluation across 28 public benchmarks, our model
+outperforms Qwen2.5-VL-7B on nearly all tasks and achieves comparable or even superior performance on 18 benchmarks
+relative to the significantly larger Qwen2.5-VL-72B. Notably, GLM-4.1V-9B-Thinking also demonstrates competitive or
+superior performance compared to closed-source models such as GPT-4o on challenging tasks including long document
+understanding and STEM reasoning, further underscoring its strong capabilities. Code, models and more information
+are released at https://github.com/THUDM/GLM-4.1V-Thinking.*
+
+## Usage
+
+The example below demonstrates how to generate text based on an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+pipe = pipeline(
+ task="image-text-to-text",
+ model="THUDM/GLM-4.1V-9B-Thinking",
+ device=0,
+ torch_dtype=torch.bfloat16
+)
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {
+ "type": "image",
+ "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg",
+ },
+ { "type": "text", "text": "Describe this image."},
+ ]
+ }
+]
+pipe(text=messages,max_new_tokens=20, return_full_text=False)
+```
+
+
+
+```py
+import torch
+from transformers import Glm4vForConditionalGeneration, AutoProcessor
+
+model = Glm4vForConditionalGeneration.from_pretrained(
+ "THUDM/GLM-4.1V-9B-Thinking",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+processor = AutoProcessor.from_pretrained("THUDM/GLM-4.1V-9B-Thinking")
+messages = [
+ {
+ "role":"user",
+ "content":[
+ {
+ "type":"image",
+ "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+ },
+ {
+ "type":"text",
+ "text":"Describe this image."
+ }
+ ]
+ }
+
+]
+
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+).to(model.device)
+
+generated_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids_trimmed = [
+ out_ids[len(in_ids) :] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
+]
+output_text = processor.batch_decode(
+ generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
+)
+print(output_text)
+```
+
+
+
+Using GLM-4.1V with video input is similar to using it with image input.
+The model can process video data and generate text based on the content of the video.
+
+```python
+from transformers import AutoProcessor, Glm4vForConditionalGeneration, infer_device
+import torch
+
+device = f"{infer_device()}:0"
+
+processor = AutoProcessor.from_pretrained("THUDM/GLM-4.1V-9B-Thinking")
+model = Glm4vForConditionalGeneration.from_pretrained(
+ pretrained_model_name_or_path="THUDM/GLM-4.1V-9B-Thinking",
+ torch_dtype=torch.bfloat16,
+ device_map=device
+)
+
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {
+ "type": "video",
+ "url": "https://test-videos.co.uk/vids/bigbuckbunny/mp4/h264/720/Big_Buck_Bunny_720_10s_10MB.mp4",
+ },
+ {
+ "type": "text",
+ "text": "discribe this video",
+ },
+ ],
+ }
+]
+inputs = processor.apply_chat_template(messages, tokenize=True, add_generation_prompt=True, return_dict=True, return_tensors="pt", padding=True).to(model.device)
+generated_ids = model.generate(**inputs, max_new_tokens=1024, do_sample=True, temperature=1.0)
+output_text = processor.decode(generated_ids[0][inputs["input_ids"].shape[1] :], skip_special_tokens=True)
+print(output_text)
+```
+
+## Glm4vConfig
+
+[[autodoc]] Glm4vConfig
+
+## Glm4vTextConfig
+
+[[autodoc]] Glm4vTextConfig
+
+## Glm4vImageProcessor
+
+[[autodoc]] Glm4vImageProcessor
+ - preprocess
+
+## Glm4vVideoProcessor
+
+[[autodoc]] Glm4vVideoProcessor
+ - preprocess
+
+## Glm4vImageProcessorFast
+
+[[autodoc]] Glm4vImageProcessorFast
+ - preprocess
+
+## Glm4vProcessor
+
+[[autodoc]] Glm4vProcessor
+
+## Glm4vTextModel
+
+[[autodoc]] Glm4vTextModel
+ - forward
+
+## Glm4vModel
+
+[[autodoc]] Glm4vModel
+ - forward
+
+## Glm4vForConditionalGeneration
+
+[[autodoc]] Glm4vForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm4v_moe.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm4v_moe.md
new file mode 100644
index 0000000000000000000000000000000000000000..0388cc9eb61da665ba149ba9d0e395010559b174
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm4v_moe.md
@@ -0,0 +1,67 @@
+
+*This model was released on 2025-07-28 and added to Hugging Face Transformers on 2025-08-08.*
+
+
+
+
+
+
+
+
+# Glm4vMoe
+
+## Overview
+
+Vision-language models (VLMs) have become a key cornerstone of intelligent systems. As real-world AI tasks grow increasingly complex, VLMs urgently need to enhance reasoning capabilities beyond basic multimodal perception — improving accuracy, comprehensiveness, and intelligence — to enable complex problem solving, long-context understanding, and multimodal agents.
+
+Through our open-source work, we aim to explore the technological frontier together with the community while empowering more developers to create exciting and innovative applications.
+
+[GLM-4.5V](https://huggingface.co/papers/2508.06471) ([Github repo](https://github.com/zai-org/GLM-V)) is based on ZhipuAI’s next-generation flagship text foundation model GLM-4.5-Air (106B parameters, 12B active). It continues the technical approach of [GLM-4.1V-Thinking](https://huggingface.co/papers/2507.01006), achieving SOTA performance among models of the same scale on 42 public vision-language benchmarks. It covers common tasks such as image, video, and document understanding, as well as GUI agent operations.
+
+
+
+Beyond benchmark performance, GLM-4.5V focuses on real-world usability. Through efficient hybrid training, it can handle diverse types of visual content, enabling full-spectrum vision reasoning, including:
+- **Image reasoning** (scene understanding, complex multi-image analysis, spatial recognition)
+- **Video understanding** (long video segmentation and event recognition)
+- **GUI tasks** (screen reading, icon recognition, desktop operation assistance)
+- **Complex chart & long document parsing** (research report analysis, information extraction)
+- **Grounding** (precise visual element localization)
+
+The model also introduces a **Thinking Mode** switch, allowing users to balance between quick responses and deep reasoning. This switch works the same as in the `GLM-4.5` language model.
+
+## Glm4vMoeConfig
+
+[[autodoc]] Glm4vMoeConfig
+
+## Glm4vMoeTextConfig
+
+[[autodoc]] Glm4vMoeTextConfig
+
+## Glm4vMoeTextModel
+
+[[autodoc]] Glm4vMoeTextModel
+ - forward
+
+## Glm4vMoeModel
+
+[[autodoc]] Glm4vMoeModel
+ - forward
+
+## Glm4vMoeForConditionalGeneration
+
+[[autodoc]] Glm4vMoeForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glpn.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glpn.md
new file mode 100644
index 0000000000000000000000000000000000000000..810e00e00e569b1e614a1c14b735fe92186808c5
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glpn.md
@@ -0,0 +1,77 @@
+
+*This model was released on 2022-01-19 and added to Hugging Face Transformers on 2022-03-22.*
+
+# GLPN
+
+
+
+
+
+
+
+This is a recently introduced model so the API hasn't been tested extensively. There may be some bugs or slight
+breaking changes to fix it in the future. If you see something strange, file a [Github Issue](https://github.com/huggingface/transformers/issues/new?assignees=&labels=&template=bug-report.md&title).
+
+
+
+## Overview
+
+The GLPN model was proposed in [Global-Local Path Networks for Monocular Depth Estimation with Vertical CutDepth](https://huggingface.co/papers/2201.07436) by Doyeon Kim, Woonghyun Ga, Pyungwhan Ahn, Donggyu Joo, Sehwan Chun, Junmo Kim.
+GLPN combines [SegFormer](segformer)'s hierarchical mix-Transformer with a lightweight decoder for monocular depth estimation. The proposed decoder shows better performance than the previously proposed decoders, with considerably
+less computational complexity.
+
+The abstract from the paper is the following:
+
+*Depth estimation from a single image is an important task that can be applied to various fields in computer vision, and has grown rapidly with the development of convolutional neural networks. In this paper, we propose a novel structure and training strategy for monocular depth estimation to further improve the prediction accuracy of the network. We deploy a hierarchical transformer encoder to capture and convey the global context, and design a lightweight yet powerful decoder to generate an estimated depth map while considering local connectivity. By constructing connected paths between multi-scale local features and the global decoding stream with our proposed selective feature fusion module, the network can integrate both representations and recover fine details. In addition, the proposed decoder shows better performance than the previously proposed decoders, with considerably less computational complexity. Furthermore, we improve the depth-specific augmentation method by utilizing an important observation in depth estimation to enhance the model. Our network achieves state-of-the-art performance over the challenging depth dataset NYU Depth V2. Extensive experiments have been conducted to validate and show the effectiveness of the proposed approach. Finally, our model shows better generalisation ability and robustness than other comparative models.*
+
+
+
+ Summary of the approach. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found [here](https://github.com/vinvino02/GLPDepth).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with GLPN.
+
+- Demo notebooks for [`GLPNForDepthEstimation`] can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/GLPN).
+- [Monocular depth estimation task guide](../tasks/monocular_depth_estimation)
+
+## GLPNConfig
+
+[[autodoc]] GLPNConfig
+
+## GLPNFeatureExtractor
+
+[[autodoc]] GLPNFeatureExtractor
+ - __call__
+
+## GLPNImageProcessor
+
+[[autodoc]] GLPNImageProcessor
+ - preprocess
+
+## GLPNModel
+
+[[autodoc]] GLPNModel
+ - forward
+
+## GLPNForDepthEstimation
+
+[[autodoc]] GLPNForDepthEstimation
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/got_ocr2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/got_ocr2.md
new file mode 100644
index 0000000000000000000000000000000000000000..e1f7f1d430e94623488c6c4bdc6bb9e09131bbe6
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/got_ocr2.md
@@ -0,0 +1,288 @@
+
+*This model was released on 2024-09-03 and added to Hugging Face Transformers on 2025-01-31.*
+
+# GOT-OCR2
+
+
+
+
+
+## Overview
+
+The GOT-OCR2 model was proposed in [General OCR Theory: Towards OCR-2.0 via a Unified End-to-end Model](https://huggingface.co/papers/2409.01704) by Haoran Wei, Chenglong Liu, Jinyue Chen, Jia Wang, Lingyu Kong, Yanming Xu, Zheng Ge, Liang Zhao, Jianjian Sun, Yuang Peng, Chunrui Han, Xiangyu Zhang.
+
+The abstract from the paper is the following:
+
+*Traditional OCR systems (OCR-1.0) are increasingly unable to meet people’snusage due to the growing demand for intelligent processing of man-made opticalncharacters. In this paper, we collectively refer to all artificial optical signals (e.g., plain texts, math/molecular formulas, tables, charts, sheet music, and even geometric shapes) as "characters" and propose the General OCR Theory along with an excellent model, namely GOT, to promote the arrival of OCR-2.0. The GOT, with 580M parameters, is a unified, elegant, and end-to-end model, consisting of a high-compression encoder and a long-contexts decoder. As an OCR-2.0 model, GOT can handle all the above "characters" under various OCR tasks. On the input side, the model supports commonly used scene- and document-style images in slice and whole-page styles. On the output side, GOT can generate plain or formatted results (markdown/tikz/smiles/kern) via an easy prompt. Besides, the model enjoys interactive OCR features, i.e., region-level recognition guided by coordinates or colors. Furthermore, we also adapt dynamic resolution and multipage OCR technologies to GOT for better practicality. In experiments, we provide sufficient results to prove the superiority of our model.*
+
+
+
+ GOT-OCR2 training stages. Taken from the original paper.
+
+
+Tips:
+
+GOT-OCR2 works on a wide range of tasks, including plain document OCR, scene text OCR, formatted document OCR, and even OCR for tables, charts, mathematical formulas, geometric shapes, molecular formulas and sheet music. While this implementation of the model will only output plain text, the outputs can be further processed to render the desired format, with packages like `pdftex`, `mathpix`, `matplotlib`, `tikz`, `verovio` or `pyecharts`.
+The model can also be used for interactive OCR, where the user can specify the region to be recognized by providing the coordinates or the color of the region's bounding box.
+
+This model was contributed by [yonigozlan](https://huggingface.co/yonigozlan).
+The original code can be found [here](https://github.com/Ucas-HaoranWei/GOT-OCR2.0).
+
+## Usage example
+
+### Plain text inference
+
+```python
+>>> import torch
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, infer_device
+
+>>> device = infer_device()
+>>> model = AutoModelForImageTextToText.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", device_map=device)
+>>> processor = AutoProcessor.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", use_fast=True)
+
+>>> image = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/image_ocr.jpg"
+>>> inputs = processor(image, return_tensors="pt", device=device).to(device)
+
+>>> generate_ids = model.generate(
+... **inputs,
+... do_sample=False,
+... tokenizer=processor.tokenizer,
+... stop_strings="<|im_end|>",
+... max_new_tokens=4096,
+... )
+
+>>> processor.decode(generate_ids[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+"R&D QUALITY IMPROVEMENT\nSUGGESTION/SOLUTION FORM\nName/Phone Ext. : (...)"
+```
+
+### Plain text inference batched
+
+```python
+>>> import torch
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, infer_device
+
+>>> device = infer_device()
+>>> model = AutoModelForImageTextToText.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", device_map=device)
+>>> processor = AutoProcessor.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", use_fast=True)
+
+>>> image1 = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/multi_box.png"
+>>> image2 = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/image_ocr.jpg"
+
+>>> inputs = processor([image1, image2], return_tensors="pt", device=device).to(device)
+
+>>> generate_ids = model.generate(
+... **inputs,
+... do_sample=False,
+... tokenizer=processor.tokenizer,
+... stop_strings="<|im_end|>",
+... max_new_tokens=4,
+... )
+
+>>> processor.batch_decode(generate_ids[:, inputs["input_ids"].shape[1] :], skip_special_tokens=True)
+["Reducing the number", "R&D QUALITY"]
+```
+
+### Formatted text inference
+
+GOT-OCR2 can also generate formatted text, such as markdown or LaTeX. Here is an example of how to generate formatted text:
+
+```python
+>>> import torch
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, infer_device
+
+>>> device = infer_device()
+>>> model = AutoModelForImageTextToText.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", device_map=device)
+>>> processor = AutoProcessor.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", use_fast=True)
+
+>>> image = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/latex.png"
+>>> inputs = processor(image, return_tensors="pt", format=True, device=device).to(device)
+
+>>> generate_ids = model.generate(
+... **inputs,
+... do_sample=False,
+... tokenizer=processor.tokenizer,
+... stop_strings="<|im_end|>",
+... max_new_tokens=4096,
+... )
+
+>>> processor.decode(generate_ids[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+"\\author{\nHanwen Jiang* \\(\\quad\\) Arjun Karpur \\({ }^{\\dagger} \\quad\\) Bingyi Cao \\({ }^{\\dagger} \\quad\\) (...)"
+```
+
+### Inference on multiple pages
+
+Although it might be reasonable in most cases to use a “for loop” for multi-page processing, some text data with formatting across several pages make it necessary to process all pages at once. GOT introduces a multi-page OCR (without “for loop”) feature, where multiple pages can be processed by the model at once, with the output being one continuous text.
+Here is an example of how to process multiple pages at once:
+
+
+```python
+>>> import torch
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, infer_device
+
+>>> device = infer_device()
+>>> model = AutoModelForImageTextToText.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", device_map=device)
+>>> processor = AutoProcessor.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", use_fast=True)
+
+>>> image1 = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/page1.png"
+>>> image2 = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/page2.png"
+>>> inputs = processor([image1, image2], return_tensors="pt", multi_page=True, format=True, device=device).to(device)
+
+>>> generate_ids = model.generate(
+... **inputs,
+... do_sample=False,
+... tokenizer=processor.tokenizer,
+... stop_strings="<|im_end|>",
+... max_new_tokens=4096,
+... )
+
+>>> processor.decode(generate_ids[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+"\\title{\nGeneral OCR Theory: Towards OCR-2.0 via a Unified End-to-end Model\n}\n\\author{\nHaoran Wei (...)"
+```
+
+### Inference on cropped patches
+
+GOT supports a 1024×1024 input resolution, which is sufficient for most OCR tasks, such as scene OCR or processing A4-sized PDF pages. However, certain scenarios, like horizontally stitched two-page PDFs commonly found in academic papers or images with unusual aspect ratios, can lead to accuracy issues when processed as a single image. To address this, GOT can dynamically crop an image into patches, process them all at once, and merge the results for better accuracy with such inputs.
+Here is an example of how to process cropped patches:
+
+```python
+>>> import torch
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, infer_device
+
+>>> device = infer_device()
+>>> model = AutoModelForImageTextToText.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", torch_dtype=torch.bfloat16, device_map=device)
+>>> processor = AutoProcessor.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", use_fast=True)
+
+>>> image = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/one_column.png"
+>>> inputs = processor(image, return_tensors="pt", format=True, crop_to_patches=True, max_patches=3, device=device).to(device)
+
+>>> generate_ids = model.generate(
+... **inputs,
+... do_sample=False,
+... tokenizer=processor.tokenizer,
+... stop_strings="<|im_end|>",
+... max_new_tokens=4096,
+... )
+
+>>> processor.decode(generate_ids[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+"on developing architectural improvements to make learnable matching methods generalize.\nMotivated by the above observations, (...)"
+```
+
+### Inference on a specific region
+
+GOT supports interactive OCR, where the user can specify the region to be recognized by providing the coordinates or the color of the region's bounding box. Here is an example of how to process a specific region:
+
+```python
+>>> import torch
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText
+
+>>> device = infer_device()
+>>> model = AutoModelForImageTextToText.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", device_map=device)
+>>> processor = AutoProcessor.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", use_fast=True)
+
+>>> image = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/multi_box.png"
+>>> inputs = processor(image, return_tensors="pt", color="green", device=device).to(device) # or box=[x1, y1, x2, y2] for coordinates (image pixels)
+
+>>> generate_ids = model.generate(
+... **inputs,
+... do_sample=False,
+... tokenizer=processor.tokenizer,
+... stop_strings="<|im_end|>",
+... max_new_tokens=4096,
+... )
+
+>>> processor.decode(generate_ids[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+"You should keep in mind what features from the module should be used, especially \nwhen you’re planning to sell a template."
+```
+
+### Inference on general OCR data example: sheet music
+
+Although this implementation of the model will only output plain text, the outputs can be further processed to render the desired format, with packages like `pdftex`, `mathpix`, `matplotlib`, `tikz`, `verovio` or `pyecharts`.
+Here is an example of how to process sheet music:
+
+```python
+>>> import torch
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, infer_device
+>>> import verovio
+
+>>> device = infer_device()
+>>> model = AutoModelForImageTextToText.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", device_map=device)
+>>> processor = AutoProcessor.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", use_fast=True)
+
+>>> image = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/sheet_music.png"
+>>> inputs = processor(image, return_tensors="pt", format=True, device=device).to(device)
+
+>>> generate_ids = model.generate(
+... **inputs,
+... do_sample=False,
+... tokenizer=processor.tokenizer,
+... stop_strings="<|im_end|>",
+... max_new_tokens=4096,
+... )
+
+>>> outputs = processor.decode(generate_ids[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+>>> tk = verovio.toolkit()
+>>> tk.loadData(outputs)
+>>> tk.setOptions(
+... {
+... "pageWidth": 2100,
+... "pageHeight": 800,
+... "footer": "none",
+... "barLineWidth": 0.5,
+... "beamMaxSlope": 15,
+... "staffLineWidth": 0.2,
+... "spacingStaff": 6,
+... }
+... )
+>>> tk.getPageCount()
+>>> svg = tk.renderToSVG()
+>>> svg = svg.replace('overflow="inherit"', 'overflow="visible"')
+>>> with open("output.svg", "w") as f:
+>>> f.write(svg)
+```
+
+
+## GotOcr2Config
+
+[[autodoc]] GotOcr2Config
+
+## GotOcr2VisionConfig
+
+[[autodoc]] GotOcr2VisionConfig
+
+## GotOcr2ImageProcessor
+
+[[autodoc]] GotOcr2ImageProcessor
+
+## GotOcr2ImageProcessorFast
+
+[[autodoc]] GotOcr2ImageProcessorFast
+
+## GotOcr2Processor
+
+[[autodoc]] GotOcr2Processor
+
+## GotOcr2Model
+
+[[autodoc]] GotOcr2Model
+
+## GotOcr2ForConditionalGeneration
+
+[[autodoc]] GotOcr2ForConditionalGeneration
+ - forward
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt-sw3.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt-sw3.md
new file mode 100644
index 0000000000000000000000000000000000000000..82de953418356a32b397efffac4df80560fd2325
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt-sw3.md
@@ -0,0 +1,77 @@
+
+*This model was released on 2022-06-25 and added to Hugging Face Transformers on 2022-12-12.*
+
+# GPT-Sw3
+
+
+
+
+
+
+
+## Overview
+
+The GPT-Sw3 model was first proposed in
+[Lessons Learned from GPT-SW3: Building the First Large-Scale Generative Language Model for Swedish](http://www.lrec-conf.org/proceedings/lrec2022/pdf/2022.lrec-1.376.pdf)
+by Ariel Ekgren, Amaru Cuba Gyllensten, Evangelia Gogoulou, Alice Heiman, Severine Verlinden, Joey Öhman,
+Fredrik Carlsson, Magnus Sahlgren.
+
+Since that first paper the authors have extended their work and trained new models on their new 1.2TB corpora named The Nordic Pile.
+
+GPT-Sw3 is a collection of large decoder-only pretrained transformer language models that were developed by AI Sweden
+in collaboration with RISE and the WASP WARA for Media and Language. GPT-Sw3 has been trained on a dataset containing
+320B tokens in Swedish, Norwegian, Danish, Icelandic, English, and programming code. The model was pretrained using a
+causal language modeling (CLM) objective utilizing the NeMo Megatron GPT implementation.
+
+This model was contributed by [AI Sweden Models](https://huggingface.co/AI-Sweden-Models).
+
+## Usage example
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForCausalLM
+
+>>> tokenizer = AutoTokenizer.from_pretrained("AI-Sweden-Models/gpt-sw3-356m")
+>>> model = AutoModelForCausalLM.from_pretrained("AI-Sweden-Models/gpt-sw3-356m")
+
+>>> input_ids = tokenizer("Träd är fina för att", return_tensors="pt")["input_ids"]
+
+>>> generated_token_ids = model.generate(inputs=input_ids, max_new_tokens=10, do_sample=True)[0]
+
+>>> print(tokenizer.decode(generated_token_ids))
+Träd är fina för att de är färgstarka. Men ibland är det fint
+```
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+
+
+The implementation uses the `GPT2Model` coupled with our `GPTSw3Tokenizer`. Refer to [GPT2Model documentation](gpt2)
+for API reference and examples.
+
+Note that sentencepiece is required to use our tokenizer and can be installed with `pip install transformers[sentencepiece]` or `pip install sentencepiece`
+
+
+
+## GPTSw3Tokenizer
+
+[[autodoc]] GPTSw3Tokenizer
+ - save_vocabulary
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt2.md
new file mode 100644
index 0000000000000000000000000000000000000000..54de3240374a3ff003e6ae1bd33d55e899505e88
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt2.md
@@ -0,0 +1,213 @@
+
+*This model was released on 2019-02-14 and added to Hugging Face Transformers on 2020-11-16.*
+
+
+
+
+
+
+
+
+
+
+
+# GPT-2
+
+[GPT-2](https://cdn.openai.com/better-language-models/language_models_are_unsupervised_multitask_learners.pdf) is a scaled up version of GPT, a causal transformer language model, with 10x more parameters and training data. The model was pretrained on a 40GB dataset to predict the next word in a sequence based on all the previous words. This approach enabled the model to perform many downstream tasks in a zero-shot setting. The blog post released by OpenAI can be found [here](https://openai.com/index/better-language-models/).
+
+The model architecture uses a unidirectional (causal) attention mechanism where each token can only attend to previous tokens, making it particularly effective for text generation tasks.
+
+You can find all the original GPT-2 checkpoints under the [OpenAI community](https://huggingface.co/openai-community?search_models=gpt) organization.
+
+> [!TIP]
+> Click on the GPT-2 models in the right sidebar for more examples of how to apply GPT-2 to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`] or the [`AutoModel`], and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(task="text-generation", model="openai-community/gpt2", torch_dtype=torch.float16, device=0)
+pipeline("Hello, I'm a language model")
+```
+
+
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained("openai-community/gpt2", torch_dtype=torch.float16, device_map="auto", attn_implementation="sdpa")
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2")
+
+input_ids = tokenizer("Hello, I'm a language model", return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+echo -e "Hello, I'm a language model" | transformers run --task text-generation --model openai-community/gpt2 --device 0
+```
+
+
+
+
+One can also serve the model using vLLM with the `transformers backend`.
+
+```
+vllm serve openai-community/gpt2 --model-imp transformers
+```
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to 4-bits.
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig, pipeline
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_compute_dtype="float16",
+ bnb_4bit_use_double_quant=True
+)
+
+model = AutoModelForCausalLM.from_pretrained(
+ "openai-community/gpt2-xl",
+ quantization_config=quantization_config,
+ device_map="auto"
+)
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2-xl")
+inputs = tokenizer("Once upon a time, there was a magical forest", return_tensors="pt").to(model.device)
+outputs = model.generate(**inputs, max_new_tokens=100)
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+## Notes
+
+- Pad inputs on the right because GPT-2 uses absolute position embeddings.
+- GPT-2 can reuse previously computed key-value attention pairs. Access this feature with the [past_key_values](https://huggingface.co/docs/transformers//en/model_doc/gpt2#transformers.GPT2Model.forward.past_key_values) parameter in [`GPT2Model.forward`].
+- Enable the [scale_attn_by_inverse_layer_idx](https://huggingface.co/docs/transformers/en/model_doc/gpt2#transformers.GPT2Config.scale_attn_by_inverse_layer_idx) and [reorder_and_upcast_attn](https://huggingface.co/docs/transformers/en/model_doc/gpt2#transformers.GPT2Config.reorder_and_upcast_attn) parameters to apply the training stability improvements from [Mistral](./mistral).
+
+## GPT2Config
+
+[[autodoc]] GPT2Config
+
+## GPT2Tokenizer
+
+[[autodoc]] GPT2Tokenizer
+ - save_vocabulary
+
+## GPT2TokenizerFast
+
+[[autodoc]] GPT2TokenizerFast
+
+## GPT2 specific outputs
+
+[[autodoc]] models.gpt2.modeling_gpt2.GPT2DoubleHeadsModelOutput
+
+[[autodoc]] models.gpt2.modeling_tf_gpt2.TFGPT2DoubleHeadsModelOutput
+
+
+
+
+## GPT2Model
+
+[[autodoc]] GPT2Model
+ - forward
+
+## GPT2LMHeadModel
+
+[[autodoc]] GPT2LMHeadModel
+ - forward
+
+## GPT2DoubleHeadsModel
+
+[[autodoc]] GPT2DoubleHeadsModel
+ - forward
+
+## GPT2ForQuestionAnswering
+
+[[autodoc]] GPT2ForQuestionAnswering
+ - forward
+
+## GPT2ForSequenceClassification
+
+[[autodoc]] GPT2ForSequenceClassification
+ - forward
+
+## GPT2ForTokenClassification
+
+[[autodoc]] GPT2ForTokenClassification
+ - forward
+
+
+
+
+## TFGPT2Model
+
+[[autodoc]] TFGPT2Model
+ - call
+
+## TFGPT2LMHeadModel
+
+[[autodoc]] TFGPT2LMHeadModel
+ - call
+
+## TFGPT2DoubleHeadsModel
+
+[[autodoc]] TFGPT2DoubleHeadsModel
+ - call
+
+## TFGPT2ForSequenceClassification
+
+[[autodoc]] TFGPT2ForSequenceClassification
+ - call
+
+## TFSequenceClassifierOutputWithPast
+
+[[autodoc]] modeling_tf_outputs.TFSequenceClassifierOutputWithPast
+
+## TFGPT2Tokenizer
+
+[[autodoc]] TFGPT2Tokenizer
+
+
+
+
+## FlaxGPT2Model
+
+[[autodoc]] FlaxGPT2Model
+ - __call__
+
+## FlaxGPT2LMHeadModel
+
+[[autodoc]] FlaxGPT2LMHeadModel
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt_bigcode.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt_bigcode.md
new file mode 100644
index 0000000000000000000000000000000000000000..ba32babe3f53ca62de4aee080876dced9678fe41
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt_bigcode.md
@@ -0,0 +1,117 @@
+
+*This model was released on 2023-01-09 and added to Hugging Face Transformers on 2023-04-10.*
+
+# GPTBigCode
+
+
+
+
+
+
+
+## Overview
+
+The GPTBigCode model was proposed in [SantaCoder: don't reach for the stars!](https://huggingface.co/papers/2301.03988) by BigCode. The listed authors are: Loubna Ben Allal, Raymond Li, Denis Kocetkov, Chenghao Mou, Christopher Akiki, Carlos Munoz Ferrandis, Niklas Muennighoff, Mayank Mishra, Alex Gu, Manan Dey, Logesh Kumar Umapathi, Carolyn Jane Anderson, Yangtian Zi, Joel Lamy Poirier, Hailey Schoelkopf, Sergey Troshin, Dmitry Abulkhanov, Manuel Romero, Michael Lappert, Francesco De Toni, Bernardo García del Río, Qian Liu, Shamik Bose, Urvashi Bhattacharyya, Terry Yue Zhuo, Ian Yu, Paulo Villegas, Marco Zocca, Sourab Mangrulkar, David Lansky, Huu Nguyen, Danish Contractor, Luis Villa, Jia Li, Dzmitry Bahdanau, Yacine Jernite, Sean Hughes, Daniel Fried, Arjun Guha, Harm de Vries, Leandro von Werra.
+
+The abstract from the paper is the following:
+
+*The BigCode project is an open-scientific collaboration working on the responsible development of large language models for code. This tech report describes the progress of the collaboration until December 2022, outlining the current state of the Personally Identifiable Information (PII) redaction pipeline, the experiments conducted to de-risk the model architecture, and the experiments investigating better preprocessing methods for the training data. We train 1.1B parameter models on the Java, JavaScript, and Python subsets of The Stack and evaluate them on the MultiPL-E text-to-code benchmark. We find that more aggressive filtering of near-duplicates can further boost performance and, surprisingly, that selecting files from repositories with 5+ GitHub stars deteriorates performance significantly. Our best model outperforms previous open-source multilingual code generation models (InCoder-6.7B and CodeGen-Multi-2.7B) in both left-to-right generation and infilling on the Java, JavaScript, and Python portions of MultiPL-E, despite being a substantially smaller model. All models are released under an OpenRAIL license at [this https URL.](https://huggingface.co/bigcode)*
+
+The model is an optimized [GPT2 model](https://huggingface.co/docs/transformers/model_doc/gpt2) with support for Multi-Query Attention.
+
+## Implementation details
+
+The main differences compared to GPT2.
+- Added support for Multi-Query Attention.
+- Use `gelu_pytorch_tanh` instead of classic `gelu`.
+- Avoid unnecessary synchronizations (this has since been added to GPT2 in #20061, but wasn't in the reference codebase).
+- Use Linear layers instead of Conv1D (good speedup but makes the checkpoints incompatible).
+- Merge `_attn` and `_upcast_and_reordered_attn`. Always merge the matmul with scaling. Rename `reorder_and_upcast_attn`->`attention_softmax_in_fp32`
+- Cache the attention mask value to avoid recreating it every time.
+- Use jit to fuse the attention fp32 casting, masking, softmax, and scaling.
+- Combine the attention and causal masks into a single one, pre-computed for the whole model instead of every layer.
+- Merge the key and value caches into one (this changes the format of layer_past/ present, does it risk creating problems?)
+- Use the memory layout (self.num_heads, 3, self.head_dim) instead of `(3, self.num_heads, self.head_dim)` for the QKV tensor with MHA. (prevents an overhead with the merged key and values, but makes the checkpoints incompatible with the original openai-community/gpt2 model).
+
+
+You can read more about the optimizations in the [original pull request](https://github.com/huggingface/transformers/pull/22575)
+
+> [!NOTE]
+> The `head_mask` argument is ignored when using all attention implementation other than "eager". If you have a `head_mask` and want it to have effect, load the model with `XXXModel.from_pretrained(model_id, attn_implementation="eager")`
+
+## Combining Starcoder and Flash Attention 2
+
+First, make sure to install the latest version of Flash Attention 2 to include the sliding window attention feature.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Make also sure that you have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of flash-attn repository. Make also sure to load your model in half-precision (e.g. `torch.float16``)
+
+To load and run a model using Flash Attention 2, refer to the snippet below:
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, infer_device
+>>> device = infer_device() # the device to load the model onto
+
+>>> model = AutoModelForCausalLM.from_pretrained("bigcode/gpt_bigcode-santacoder", torch_dtype=torch.float16, attn_implementation="flash_attention_2")
+>>> tokenizer = AutoTokenizer.from_pretrained("bigcode/gpt_bigcode-santacoder")
+
+>>> prompt = "def hello_world():"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to(model.device)
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=30, do_sample=False)
+>>> tokenizer.batch_decode(generated_ids)[0]
+'def hello_world():\n print("hello world")\n\nif __name__ == "__main__":\n print("hello world")\n<|endoftext|>'
+```
+
+### Expected speedups
+
+Below is a expected speedup diagram that compares pure inference time between the native implementation in transformers using `bigcode/starcoder` checkpoint and the Flash Attention 2 version of the model using two different sequence lengths.
+
+
+
+
+
+
+## GPTBigCodeConfig
+
+[[autodoc]] GPTBigCodeConfig
+
+## GPTBigCodeModel
+
+[[autodoc]] GPTBigCodeModel
+ - forward
+
+## GPTBigCodeForCausalLM
+
+[[autodoc]] GPTBigCodeForCausalLM
+ - forward
+
+## GPTBigCodeForSequenceClassification
+
+[[autodoc]] GPTBigCodeForSequenceClassification
+ - forward
+
+## GPTBigCodeForTokenClassification
+
+[[autodoc]] GPTBigCodeForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt_neo.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt_neo.md
new file mode 100644
index 0000000000000000000000000000000000000000..98c9cfa1f56934fe6b9df7bc31cd747c1b319093
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt_neo.md
@@ -0,0 +1,156 @@
+
+*This model was released on 2021-03-21 and added to Hugging Face Transformers on 2021-03-30.*
+
+
+
+
+
+
+
+
+
+
+## GPT-Neo
+
+[GPT-Neo](https://zenodo.org/records/5297715) is an open-source alternative to GPT-2 and GPT-3 models, built with Mesh TensorFlow for TPUs. GPT-Neo uses local attention in every other layer for more efficiency. It is trained on the [Pile](https://huggingface.co/datasets/EleutherAI/pile), a diverse dataset consisting of 22 smaller high-quality datasets. The original github repository can be found [here](https://github.com/EleutherAI/gpt-neo/tree/v1.1)
+
+
+You can find all the original GPT-Neo checkpoints under the [EleutherAI](https://huggingface.co/EleutherAI?search_models=gpt-neo) organization.
+
+> [!TIP]
+> Click on the GPT-Neo models in the right sidebar for more examples of how to apply GPT Neo to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`] or the [`AutoModel`], and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(task="text-generation", model="EleutherAI/gpt-neo-1.3B", torch_dtype=torch.float16, device=0)
+pipeline("Hello, I'm a language model")
+```
+
+
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained("EleutherAI/gpt-neo-1.3B", torch_dtype=torch.float16, device_map="auto", attn_implementation="flash_attention_2")
+tokenizer = AutoTokenizer.from_pretrained("EleutherAI/gpt-neo-1.3B")
+
+input_ids = tokenizer("Hello, I'm a language model", return_tensors="pt").to("cuda")
+
+output = model.generate(**input_ids)
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+echo -e "Hello, I'm a language model" | transformers-cli run --task text-generation --model EleutherAI/gpt-neo-1.3B --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to 4-bits.
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_compute_dtype="float16",
+ bnb_4bit_use_double_quant=True
+)
+
+model = AutoModelForCausalLM.from_pretrained(
+ "EleutherAI/gpt-neo-2.7B",
+ quantization_config=quantization_config,
+ device_map="auto"
+)
+
+tokenizer = AutoTokenizer.from_pretrained("EleutherAI/gpt-neo-2.7B")
+inputs = tokenizer("Hello, I'm a language model", return_tensors="pt").to("cuda")
+outputs = model.generate(**inputs, max_new_tokens=100)
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+## Notes
+
+- Pad inputs on the right because GPT-Neo uses absolute position embeddings.
+
+## GPTNeoConfig
+
+[[autodoc]] GPTNeoConfig
+
+
+
+
+
+## GPTNeoModel
+
+[[autodoc]] GPTNeoModel
+ - forward
+
+## GPTNeoForCausalLM
+
+[[autodoc]] GPTNeoForCausalLM
+ - forward
+
+## GPTNeoForQuestionAnswering
+
+[[autodoc]] GPTNeoForQuestionAnswering
+ - forward
+
+## GPTNeoForSequenceClassification
+
+[[autodoc]] GPTNeoForSequenceClassification
+ - forward
+
+## GPTNeoForTokenClassification
+
+[[autodoc]] GPTNeoForTokenClassification
+ - forward
+
+
+
+
+## FlaxGPTNeoModel
+
+[[autodoc]] FlaxGPTNeoModel
+ - __call__
+
+## FlaxGPTNeoForCausalLM
+
+[[autodoc]] FlaxGPTNeoForCausalLM
+ - __call__
+
+
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt_neox.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt_neox.md
new file mode 100644
index 0000000000000000000000000000000000000000..43a63624e8a8f9025f6c63ab7c966ade70dad25a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt_neox.md
@@ -0,0 +1,201 @@
+
+*This model was released on 2022-04-14 and added to Hugging Face Transformers on 2022-05-24.*
+
+# GPT-NeoX
+
+
+
+
+
+
+## Overview
+
+We introduce [GPT-NeoX-20B](https://huggingface.co/papers/2204.06745), a 20 billion parameter autoregressive language model trained on the Pile, whose weights will
+be made freely and openly available to the public through a permissive license. It is, to the best of our knowledge,
+the largest dense autoregressive model that has publicly available weights at the time of submission. In this work,
+we describe GPT-NeoX-20B's architecture and training and evaluate its performance on a range of language-understanding,
+mathematics, and knowledge-based tasks. We find that GPT-NeoX-20B is a particularly powerful few-shot reasoner and
+gains far more in performance when evaluated five-shot than similarly sized GPT-3 and FairSeq models. We open-source
+the training and evaluation code, as well as the model weights, at [https://github.com/EleutherAI/gpt-neox](https://github.com/EleutherAI/gpt-neox).
+
+Development of the model was led by Sid Black, Stella Biderman and Eric Hallahan, and the model was trained with
+generous the support of [CoreWeave](https://www.coreweave.com/).
+
+GPT-NeoX-20B was trained with fp16, thus it is recommended to initialize the model as follows:
+
+```python
+model = GPTNeoXForCausalLM.from_pretrained("EleutherAI/gpt-neox-20b").half().cuda()
+```
+
+GPT-NeoX-20B also has a different tokenizer from the one used in GPT-J-6B and GPT-Neo. The new tokenizer allocates
+additional tokens to whitespace characters, making the model more suitable for certain tasks like code generation.
+
+## Usage example
+
+The `generate()` method can be used to generate text using GPT Neo model.
+
+```python
+>>> from transformers import GPTNeoXForCausalLM, GPTNeoXTokenizerFast
+
+>>> model = GPTNeoXForCausalLM.from_pretrained("EleutherAI/gpt-neox-20b")
+>>> tokenizer = GPTNeoXTokenizerFast.from_pretrained("EleutherAI/gpt-neox-20b")
+
+>>> prompt = "GPTNeoX20B is a 20B-parameter autoregressive Transformer model developed by EleutherAI."
+
+>>> input_ids = tokenizer(prompt, return_tensors="pt").input_ids
+
+>>> gen_tokens = model.generate(
+... input_ids,
+... do_sample=True,
+... temperature=0.9,
+... max_length=100,
+... )
+>>> gen_text = tokenizer.batch_decode(gen_tokens)[0]
+```
+
+## Using Flash Attention 2
+
+Flash Attention 2 is an faster, optimized version of the model.
+
+### Installation
+
+First, check whether your hardware is compatible with Flash Attention 2. The latest list of compatible hardware can be found in the [official documentation](https://github.com/Dao-AILab/flash-attention#installation-and-features). If your hardware is not compatible with Flash Attention 2, you can still benefit from attention kernel optimisations through Better Transformer support covered [above](https://huggingface.co/docs/transformers/main/en/model_doc/bark#using-better-transformer).
+
+Next, [install](https://github.com/Dao-AILab/flash-attention#installation-and-features) the latest version of Flash Attention 2:
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+### Usage
+
+To load a model using Flash Attention 2, we can pass the argument `attn_implementation="flash_attention_2"` to [`.from_pretrained`](https://huggingface.co/docs/transformers/main/en/main_classes/model#transformers.PreTrainedModel.from_pretrained). We'll also load the model in half-precision (e.g. `torch.float16`), since it results in almost no degradation to audio quality but significantly lower memory usage and faster inference:
+
+```python
+>>> from transformers import GPTNeoXForCausalLM, GPTNeoXTokenizerFast
+
+model = GPTNeoXForCausalLM.from_pretrained("EleutherAI/gpt-neox-20b", torch_dtype=torch.float16, attn_implementation="flash_attention_2").to(device)
+...
+```
+
+
+### Expected speedups
+
+Below is an expected speedup diagram that compares pure inference time between the native implementation in transformers using `stockmark/gpt-neox-japanese-1.4b` checkpoint and the Flash Attention 2 version of the model using a sequence length of 2048.
+
+
+
+*This model was released on 2022-07-27 and added to Hugging Face Transformers on 2022-09-14.*
+
+# GPT-NeoX-Japanese
+
+GPT-NeoX-Japanese, a Japanese language model based on [GPT-NeoX](./gpt_neox).
+Japanese uses three types of characters (hiragana, katakana, kanji) and has a huge vocabulary. This model uses [BPEEncoder V2](https://github.com/tanreinama/Japanese-BPEEncoder_V2), a sub-word tokenizer to handle the different characters.
+
+
+
+The model also removes some bias parameters for better performance.
+
+You can find all the original GPT-NeoX-Japanese checkpoints under the [ABEJA](https://huggingface.co/abeja/models?search=gpt-neo-x) organization.
+
+> [!TIP]
+> This model was contributed by [Shinya Otani](https://github.com/SO0529), [Takayoshi Makabe](https://github.com/spider-man-tm), [Anuj Arora](https://github.com/Anuj040), and [Kyo Hattori](https://github.com/go5paopao) from [ABEJA, Inc.](https://www.abejainc.com/).
+>
+> Click on the GPT-NeoX-Japanese models in the right sidebar for more examples of how to apply GPT-NeoX-Japanese to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`] or the [`AutoModel`], and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+pipeline = pipeline(task="text-generation",
+ model="abeja/gpt-neox-japanese-2.7b", torch_dtype=torch.float16, device=0)
+pipeline("人とAIが協調するためには、")
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained("abeja/gpt-neox-japanese-2.7b", torch_dtype=torch.float16, device_map="auto")
+tokenizer = AutoTokenizer.from_pretrained("abeja/gpt-neox-japanese-2.7b")
+input_ids = tokenizer("人とAIが協調するためには、", return_tensors="pt").input_ids.to(model.device)
+outputs = model.generate(input_ids)
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+
+
+```bash
+echo -e "人とAIが協調するためには、" | transformers run --task text-generation --model abeja/gpt-neox-japanese-2.7b --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to 4-bits.
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_use_double_quant=True,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_compute_dtype="float16"
+)
+model = AutoModelForCausalLM.from_pretrained(
+ "abeja/gpt-neox-japanese-2.7b",
+ quantization_config=quantization_config,
+ device_map="auto"
+)
+
+tokenizer = AutoTokenizer.from_pretrained("abeja/gpt-neox-japanese-2.7b")
+input_ids = tokenizer.encode("人とAIが協調するためには、", return_tensors="pt").to(model.device)
+output = model.generate(input_ids)
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+Use the [AttentionMaskVisualizer](https://github.com/huggingface/transformers/blob/beb9b5b02246b9b7ee81ddf938f93f44cfeaad19/src/transformers/utils/attention_visualizer.py#L139) to better understand what tokens the model can and cannot attend to.
+
+```py
+from transformers.utils.attention_visualizer import AttentionMaskVisualizer
+
+visualizer = AttentionMaskVisualizer("abeja/gpt-neox-japanese-2.7b")
+visualizer("What is shown in this image?")
+```
+
+
+
+
+
+## Resources
+Refer to the [Training a better GPT model: Learnings from PaLM](https://medium.com/ml-abeja/training-a-better-gpt-2-93b157662ae4) blog post for more details about how ABEJA trained GPT-NeoX-Japanese.
+
+## GPTNeoXJapaneseConfig
+
+[[autodoc]] GPTNeoXJapaneseConfig
+
+## GPTNeoXJapaneseTokenizer
+
+[[autodoc]] GPTNeoXJapaneseTokenizer
+
+## GPTNeoXJapaneseModel
+
+[[autodoc]] GPTNeoXJapaneseModel
+ - forward
+
+## GPTNeoXJapaneseForCausalLM
+
+[[autodoc]] GPTNeoXJapaneseForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt_oss.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt_oss.md
new file mode 100644
index 0000000000000000000000000000000000000000..7b5e14c51ee473263d8ff6afb9c7b9d64a76a603
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt_oss.md
@@ -0,0 +1,64 @@
+
+*This model was released on 2025-08-05 and added to Hugging Face Transformers on 2025-08-05.*
+
+
+
+
+
+
+
+
+
+
+# GptOss
+
+## Overview
+
+The GptOss model was proposed in [blog post](https://openai.com/index/introducing-gpt-oss/) by .
+
+
+The abstract from the paper is the following:
+
+**
+
+Tips:
+
+
+
+This model was contributed by [INSERT YOUR HF USERNAME HERE](https://huggingface.co/).
+The original code can be found [here]().
+
+
+## GptOssConfig
+
+[[autodoc]] GptOssConfig
+
+## GptOssModel
+
+[[autodoc]] GptOssModel
+ - forward
+
+## GptOssForCausalLM
+
+[[autodoc]] GptOssForCausalLM
+ - forward
+
+## GptOssForSequenceClassification
+
+[[autodoc]] GptOssForSequenceClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gptj.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gptj.md
new file mode 100644
index 0000000000000000000000000000000000000000..9d13e8aa9256f16665f8a38d1c2621e320d3e5f8
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gptj.md
@@ -0,0 +1,209 @@
+
+*This model was released on 2021-06-04 and added to Hugging Face Transformers on 2021-08-31.*
+
+# GPT-J
+
+
+
+
+
+
+
+
+## Overview
+
+The [GPT-J](https://arankomatsuzaki.wordpress.com/2021/06/04/gpt-j/) model was released in the [kingoflolz/mesh-transformer-jax](https://github.com/kingoflolz/mesh-transformer-jax) repository by Ben Wang and Aran Komatsuzaki. It is a GPT-2-like
+causal language model trained on [the Pile](https://pile.eleuther.ai/) dataset.
+
+This model was contributed by [Stella Biderman](https://huggingface.co/stellaathena).
+
+## Usage tips
+
+- To load [GPT-J](https://huggingface.co/EleutherAI/gpt-j-6B) in float32 one would need at least 2x model size
+ RAM: 1x for initial weights and another 1x to load the checkpoint. So for GPT-J it would take at least 48GB
+ RAM to just load the model. To reduce the RAM usage there are a few options. The `torch_dtype` argument can be
+ used to initialize the model in half-precision on a CUDA device only. There is also a fp16 branch which stores the fp16 weights,
+ which could be used to further minimize the RAM usage:
+
+```python
+>>> from transformers import GPTJForCausalLM, infer_device
+>>> import torch
+
+>>> device = infer_device()
+>>> model = GPTJForCausalLM.from_pretrained(
+... "EleutherAI/gpt-j-6B",
+... revision="float16",
+... torch_dtype=torch.float16,
+... ).to(device)
+```
+
+- The model should fit on 16GB GPU for inference. For training/fine-tuning it would take much more GPU RAM. Adam
+ optimizer for example makes four copies of the model: model, gradients, average and squared average of the gradients.
+ So it would need at least 4x model size GPU memory, even with mixed precision as gradient updates are in fp32. This
+ is not including the activations and data batches, which would again require some more GPU RAM. So one should explore
+ solutions such as DeepSpeed, to train/fine-tune the model. Another option is to use the original codebase to
+ train/fine-tune the model on TPU and then convert the model to Transformers format for inference. Instructions for
+ that could be found [here](https://github.com/kingoflolz/mesh-transformer-jax/blob/master/howto_finetune.md)
+
+- Although the embedding matrix has a size of 50400, only 50257 entries are used by the GPT-2 tokenizer. These extra
+ tokens are added for the sake of efficiency on TPUs. To avoid the mismatch between embedding matrix size and vocab
+ size, the tokenizer for [GPT-J](https://huggingface.co/EleutherAI/gpt-j-6B) contains 143 extra tokens
+ `<|extratoken_1|>... <|extratoken_143|>`, so the `vocab_size` of tokenizer also becomes 50400.
+
+## Usage examples
+
+The [`~generation.GenerationMixin.generate`] method can be used to generate text using GPT-J
+model.
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("EleutherAI/gpt-j-6B")
+>>> tokenizer = AutoTokenizer.from_pretrained("EleutherAI/gpt-j-6B")
+
+>>> prompt = (
+... "In a shocking finding, scientists discovered a herd of unicorns living in a remote, "
+... "previously unexplored valley, in the Andes Mountains. Even more surprising to the "
+... "researchers was the fact that the unicorns spoke perfect English."
+... )
+
+>>> input_ids = tokenizer(prompt, return_tensors="pt").input_ids
+
+>>> gen_tokens = model.generate(
+... input_ids,
+... do_sample=True,
+... temperature=0.9,
+... max_length=100,
+... )
+>>> gen_text = tokenizer.batch_decode(gen_tokens)[0]
+```
+
+...or in float16 precision:
+
+```python
+>>> from transformers import GPTJForCausalLM, AutoTokenizer, infer_device
+>>> import torch
+
+>>> device = infer_device()
+>>> model = GPTJForCausalLM.from_pretrained("EleutherAI/gpt-j-6B", torch_dtype=torch.float16).to(device)
+>>> tokenizer = AutoTokenizer.from_pretrained("EleutherAI/gpt-j-6B")
+
+>>> prompt = (
+... "In a shocking finding, scientists discovered a herd of unicorns living in a remote, "
+... "previously unexplored valley, in the Andes Mountains. Even more surprising to the "
+... "researchers was the fact that the unicorns spoke perfect English."
+... )
+
+>>> input_ids = tokenizer(prompt, return_tensors="pt").input_ids.to(model.device)
+
+>>> gen_tokens = model.generate(
+... input_ids,
+... do_sample=True,
+... temperature=0.9,
+... max_length=100,
+... )
+>>> gen_text = tokenizer.batch_decode(gen_tokens)[0]
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with GPT-J. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- Description of [GPT-J](https://huggingface.co/EleutherAI/gpt-j-6B).
+- A blog on how to [Deploy GPT-J 6B for inference using Hugging Face Transformers and Amazon SageMaker](https://huggingface.co/blog/gptj-sagemaker).
+- A blog on how to [Accelerate GPT-J inference with DeepSpeed-Inference on GPUs](https://www.philschmid.de/gptj-deepspeed-inference).
+- A blog post introducing [GPT-J-6B: 6B JAX-Based Transformer](https://arankomatsuzaki.wordpress.com/2021/06/04/gpt-j/). 🌎
+- A notebook for [GPT-J-6B Inference Demo](https://colab.research.google.com/github/kingoflolz/mesh-transformer-jax/blob/master/colab_demo.ipynb). 🌎
+- Another notebook demonstrating [Inference with GPT-J-6B](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/GPT-J-6B/Inference_with_GPT_J_6B.ipynb).
+- [Causal language modeling](https://huggingface.co/course/en/chapter7/6?fw=pt#training-a-causal-language-model-from-scratch) chapter of the 🤗 Hugging Face Course.
+- [`GPTJForCausalLM`] is supported by this [causal language modeling example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/language-modeling#gpt-2gpt-and-causal-language-modeling), [text generation example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/text-generation), and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb).
+- [`TFGPTJForCausalLM`] is supported by this [causal language modeling example script](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/language-modeling#run_clmpy) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb).
+- [`FlaxGPTJForCausalLM`] is supported by this [causal language modeling example script](https://github.com/huggingface/transformers/tree/main/examples/flax/language-modeling#causal-language-modeling) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/causal_language_modeling_flax.ipynb).
+
+**Documentation resources**
+- [Text classification task guide](../tasks/sequence_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## GPTJConfig
+
+[[autodoc]] GPTJConfig
+ - all
+
+
+
+
+## GPTJModel
+
+[[autodoc]] GPTJModel
+ - forward
+
+## GPTJForCausalLM
+
+[[autodoc]] GPTJForCausalLM
+ - forward
+
+## GPTJForSequenceClassification
+
+[[autodoc]] GPTJForSequenceClassification
+ - forward
+
+## GPTJForQuestionAnswering
+
+[[autodoc]] GPTJForQuestionAnswering
+ - forward
+
+
+
+
+## TFGPTJModel
+
+[[autodoc]] TFGPTJModel
+ - call
+
+## TFGPTJForCausalLM
+
+[[autodoc]] TFGPTJForCausalLM
+ - call
+
+## TFGPTJForSequenceClassification
+
+[[autodoc]] TFGPTJForSequenceClassification
+ - call
+
+## TFGPTJForQuestionAnswering
+
+[[autodoc]] TFGPTJForQuestionAnswering
+ - call
+
+
+
+
+## FlaxGPTJModel
+
+[[autodoc]] FlaxGPTJModel
+ - __call__
+
+## FlaxGPTJForCausalLM
+
+[[autodoc]] FlaxGPTJForCausalLM
+ - __call__
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gptsan-japanese.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gptsan-japanese.md
new file mode 100644
index 0000000000000000000000000000000000000000..82928d083d920f98b2a54c85d50030dca4e8bb5d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gptsan-japanese.md
@@ -0,0 +1,135 @@
+
+*This model was released on 2023-02-07 and added to Hugging Face Transformers on 2023-06-20.*
+
+# GPTSAN-japanese
+
+
+
+
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The [GPTSAN-japanese](https://huggingface.co/Tanrei/GPTSAN-japanese) model was released in the repository by Toshiyuki Sakamoto (tanreinama).
+
+GPTSAN is a Japanese language model using Switch Transformer. It has the same structure as the model introduced as Prefix LM
+in the T5 paper, and support both Text Generation and Masked Language Modeling tasks. These basic tasks similarly can
+fine-tune for translation or summarization.
+
+### Usage example
+
+The `generate()` method can be used to generate text using GPTSAN-Japanese model.
+
+```python
+>>> from transformers import AutoModel, AutoTokenizer, infer_device
+>>> import torch
+
+>>> device = infer_device()
+>>> tokenizer = AutoTokenizer.from_pretrained("Tanrei/GPTSAN-japanese")
+>>> model = AutoModel.from_pretrained("Tanrei/GPTSAN-japanese").to(device)
+>>> x_tok = tokenizer("は、", prefix_text="織田信長", return_tensors="pt")
+>>> torch.manual_seed(0)
+>>> gen_tok = model.generate(x_tok.input_ids.to(model.device), token_type_ids=x_tok.token_type_ids.to(mdoel.device), max_new_tokens=20)
+>>> tokenizer.decode(gen_tok[0])
+'織田信長は、2004年に『戦国BASARA』のために、豊臣秀吉'
+```
+
+## GPTSAN Features
+
+GPTSAN has some unique features. It has a model structure of Prefix-LM. It works as a shifted Masked Language Model for Prefix Input tokens. Un-prefixed inputs behave like normal generative models.
+The Spout vector is a GPTSAN specific input. Spout is pre-trained with random inputs, but you can specify a class of text or an arbitrary vector during fine-tuning. This allows you to indicate the tendency of the generated text.
+GPTSAN has a sparse Feed Forward based on Switch-Transformer. You can also add other layers and train them partially. See the original GPTSAN repository for details.
+
+### Prefix-LM Model
+
+GPTSAN has the structure of the model named Prefix-LM in the `T5` paper. (The original GPTSAN repository calls it `hybrid`)
+In GPTSAN, the `Prefix` part of Prefix-LM, that is, the input position that can be referenced by both tokens, can be specified with any length.
+Arbitrary lengths can also be specified differently for each batch.
+This length applies to the text entered in `prefix_text` for the tokenizer.
+The tokenizer returns the mask of the `Prefix` part of Prefix-LM as `token_type_ids`.
+The model treats the part where `token_type_ids` is 1 as a `Prefix` part, that is, the input can refer to both tokens before and after.
+
+## Usage tips
+
+Specifying the Prefix part is done with a mask passed to self-attention.
+When token_type_ids=None or all zero, it is equivalent to regular causal mask
+
+for example:
+
+>>> x_token = tokenizer("アイウエ")
+input_ids: | SOT | SEG | ア | イ | ウ | エ |
+token_type_ids: | 1 | 0 | 0 | 0 | 0 | 0 |
+prefix_lm_mask:
+SOT | 1 0 0 0 0 0 |
+SEG | 1 1 0 0 0 0 |
+ア | 1 1 1 0 0 0 |
+イ | 1 1 1 1 0 0 |
+ウ | 1 1 1 1 1 0 |
+エ | 1 1 1 1 1 1 |
+
+>>> x_token = tokenizer("", prefix_text="アイウエ")
+input_ids: | SOT | ア | イ | ウ | エ | SEG |
+token_type_ids: | 1 | 1 | 1 | 1 | 1 | 0 |
+prefix_lm_mask:
+SOT | 1 1 1 1 1 0 |
+ア | 1 1 1 1 1 0 |
+イ | 1 1 1 1 1 0 |
+ウ | 1 1 1 1 1 0 |
+エ | 1 1 1 1 1 0 |
+SEG | 1 1 1 1 1 1 |
+
+>>> x_token = tokenizer("ウエ", prefix_text="アイ")
+input_ids: | SOT | ア | イ | SEG | ウ | エ |
+token_type_ids: | 1 | 1 | 1 | 0 | 0 | 0 |
+prefix_lm_mask:
+SOT | 1 1 1 0 0 0 |
+ア | 1 1 1 0 0 0 |
+イ | 1 1 1 0 0 0 |
+SEG | 1 1 1 1 0 0 |
+ウ | 1 1 1 1 1 0 |
+エ | 1 1 1 1 1 1 |
+
+### Spout Vector
+
+A Spout Vector is a special vector for controlling text generation.
+This vector is treated as the first embedding in self-attention to bring extraneous attention to the generated tokens.
+In the pre-trained model published from `Tanrei/GPTSAN-japanese`, the Spout Vector is a 128-dimensional vector that passes through 8 fully connected layers in the model and is projected into the space acting as external attention.
+The Spout Vector projected by the fully connected layer is split to be passed to all self-attentions.
+
+## GPTSanJapaneseConfig
+
+[[autodoc]] GPTSanJapaneseConfig
+
+## GPTSanJapaneseTokenizer
+
+[[autodoc]] GPTSanJapaneseTokenizer
+
+## GPTSanJapaneseModel
+
+[[autodoc]] GPTSanJapaneseModel
+
+## GPTSanJapaneseForConditionalGeneration
+
+[[autodoc]] GPTSanJapaneseForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granite.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granite.md
new file mode 100644
index 0000000000000000000000000000000000000000..321e0894e5c79b141fe188fa57f8a87cb89681ec
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granite.md
@@ -0,0 +1,126 @@
+
+*This model was released on 2024-08-23 and added to Hugging Face Transformers on 2024-08-27.*
+
+
+
+
+
+
+
+
+
+# Granite
+
+[Granite](https://huggingface.co/papers/2408.13359) is a 3B parameter language model trained with the Power scheduler. Discovering a good learning rate for pretraining large language models is difficult because it depends on so many variables (batch size, number of training tokens, etc.) and it is expensive to perform a hyperparameter search. The Power scheduler is based on a power-law relationship between the variables and their transferability to larger models. Combining the Power scheduler with Maximum Update Parameterization (MUP) allows a model to be pretrained with one set of hyperparameters regardless of all the variables.
+
+You can find all the original Granite checkpoints under the [IBM-Granite](https://huggingface.co/ibm-granite) organization.
+
+> [!TIP]
+> Click on the Granite models in the right sidebar for more examples of how to apply Granite to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`], [`AutoModel`, and from the command line.
+
+
+
+
+```python
+import torch
+from transformers import pipeline
+
+pipe = pipeline(
+ task="text-generation",
+ model="ibm-granite/granite-3.3-2b-base",
+ torch_dtype=torch.bfloat16,
+ device=0
+)
+pipe("Explain quantum computing in simple terms ", max_new_tokens=50)
+```
+
+
+
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("ibm-granite/granite-3.3-2b-base")
+model = AutoModelForCausalLM.from_pretrained(
+ "ibm-granite/granite-3.3-2b-base",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+
+inputs = tokenizer("Explain quantum computing in simple terms", return_tensors="pt").to(model.device)
+outputs = model.generate(**inputs, max_length=50, cache_implementation="static")
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+
+
+```python
+echo -e "Explain quantum computing simply." | transformers-cli run --task text-generation --model ibm-granite/granite-3.3-8b-instruct --device 0
+```
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to int4.
+
+```python
+import torch
+from transformers import AutoTokenizer, AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_4bit=True)
+tokenizer = AutoTokenizer.from_pretrained("ibm-granite/granite-3.3-8b-base")
+model = AutoModelForCausalLM.from_pretrained("ibm-granite/granite-3.3-8b-base", torch_dtype=torch.bfloat16, device_map="auto", attn_implementation="sdpa", quantization_config=quantization_config)
+
+inputs = tokenizer("Explain quantum computing in simple terms", return_tensors="pt").to(model.device)
+outputs = model.generate(**inputs, max_length=50, cache_implementation="static")
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+
+quantization_config = BitsAndBytesConfig(load_in_4bit=True)
+
+tokenizer = AutoTokenizer.from_pretrained("ibm-granite/granite-3.3-2b-base")
+model = AutoModelForCausalLM.from_pretrained(
+ "ibm-granite/granite-3.3-2b-base",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa",
+ quantization_config=quantization_config,
+)
+
+input_ids = tokenizer("Explain artificial intelligence to a 10 year old", return_tensors="pt").to(model.device)
+outputs = model.generate(**inputs, max_length=50, cache_implementation="static")
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+
+## GraniteConfig
+
+[[autodoc]] GraniteConfig
+
+## GraniteModel
+
+[[autodoc]] GraniteModel
+ - forward
+
+## GraniteForCausalLM
+
+[[autodoc]] GraniteForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granite_speech.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granite_speech.md
new file mode 100644
index 0000000000000000000000000000000000000000..5de42ff993f807f6d1642810c7c1dd952ebae083
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granite_speech.md
@@ -0,0 +1,69 @@
+
+*This model was released on 2025-04-16 and added to Hugging Face Transformers on 2025-04-11.*
+
+# Granite Speech
+
+
+
+
+
+## Overview
+The [Granite Speech](https://huggingface.co/papers/2505.08699) model ([blog post](https://www.ibm.com/new/announcements/ibm-granite-3-3-speech-recognition-refined-reasoning-rag-loras)) is a multimodal language model, consisting of a speech encoder, speech projector, large language model, and LoRA adapter(s). More details regarding each component for the current (Granite 3.2 Speech) model architecture may be found below.
+
+1. Speech Encoder: A [Conformer](https://huggingface.co/papers/2005.08100) encoder trained with Connectionist Temporal Classification (CTC) on character-level targets on ASR corpora. The encoder uses block-attention and self-conditioned CTC from the middle layer.
+
+2. Speech Projector: A query transformer (q-former) operating on the outputs of the last encoder block. The encoder and projector temporally downsample the audio features to be merged into the multimodal embeddings to be processed by the llm.
+
+3. Large Language Model: The Granite Speech model leverages Granite LLMs, which were originally proposed in [this paper](https://huggingface.co/papers/2408.13359).
+
+4. LoRA adapter(s): The Granite Speech model contains a modality specific LoRA, which will be enabled when audio features are provided, and disabled otherwise.
+
+
+Note that most of the aforementioned components are implemented generically to enable compatibility and potential integration with other model architectures in transformers.
+
+
+This model was contributed by [Alexander Brooks](https://huggingface.co/abrooks9944), [Avihu Dekel](https://huggingface.co/Avihu), and [George Saon](https://huggingface.co/gsaon).
+
+## Usage tips
+- This model bundles its own LoRA adapter, which will be automatically loaded and enabled/disabled as needed during inference calls. Be sure to install [PEFT](https://github.com/huggingface/peft) to ensure the LoRA is correctly applied!
+
+
+
+## GraniteSpeechConfig
+
+[[autodoc]] GraniteSpeechConfig
+
+
+## GraniteSpeechEncoderConfig
+
+[[autodoc]] GraniteSpeechEncoderConfig
+
+
+## GraniteSpeechProcessor
+
+[[autodoc]] GraniteSpeechProcessor
+
+
+## GraniteSpeechFeatureExtractor
+
+[[autodoc]] GraniteSpeechFeatureExtractor
+
+
+## GraniteSpeechForConditionalGeneration
+
+[[autodoc]] GraniteSpeechForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granitemoe.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granitemoe.md
new file mode 100644
index 0000000000000000000000000000000000000000..71c266a76b510123313127cb097ab4b349bfd5f2
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granitemoe.md
@@ -0,0 +1,81 @@
+
+*This model was released on 2024-08-23 and added to Hugging Face Transformers on 2024-09-20.*
+
+# GraniteMoe
+
+
+
+
+
+
+
+## Overview
+
+The GraniteMoe model was proposed in [Power Scheduler: A Batch Size and Token Number Agnostic Learning Rate Scheduler](https://huggingface.co/papers/2408.13359) by Yikang Shen, Matthew Stallone, Mayank Mishra, Gaoyuan Zhang, Shawn Tan, Aditya Prasad, Adriana Meza Soria, David D. Cox and Rameswar Panda.
+
+PowerMoE-3B is a 3B sparse Mixture-of-Experts (sMoE) language model trained with the Power learning rate scheduler. It sparsely activates 800M parameters for each token. It is trained on a mix of open-source and proprietary datasets. PowerMoE-3B has shown promising results compared to other dense models with 2x activate parameters across various benchmarks, including natural language multi-choices, code generation, and math reasoning.
+
+The abstract from the paper is the following:
+
+*Finding the optimal learning rate for language model pretraining is a challenging task.
+This is not only because there is a complicated correlation between learning rate, batch size, number of training tokens, model size, and other hyperparameters but also because it is prohibitively expensive to perform a hyperparameter search for large language models with Billions or Trillions of parameters. Recent studies propose using small proxy models and small corpus to perform hyperparameter searches and transposing the optimal parameters to large models and large corpus. While the zero-shot transferability is theoretically and empirically proven for model size related hyperparameters, like depth and width, the zero-shot transfer from small corpus to large corpus is underexplored.
+In this paper, we study the correlation between optimal learning rate, batch size, and number of training tokens for the recently proposed WSD scheduler. After thousands of small experiments, we found a power-law relationship between variables and demonstrated its transferability across model sizes. Based on the observation, we propose a new learning rate scheduler, Power scheduler, that is agnostic about the number of training tokens and batch size. The experiment shows that combining the Power scheduler with Maximum Update Parameterization (\mup) can consistently achieve impressive performance with one set of hyperparameters regardless of the number of training tokens, batch size, model size, and even model architecture. Our 3B dense and MoE models trained with the Power scheduler achieve comparable performance as state-of-the-art small language models.
+We [open source](https://huggingface.co/collections/ibm/power-lm-66be64ae647ddf11b9808000) these pretrained models.*
+
+Tips:
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_path = "ibm/PowerMoE-3b"
+tokenizer = AutoTokenizer.from_pretrained(model_path)
+
+# drop device_map if running on CPU
+model = AutoModelForCausalLM.from_pretrained(model_path, device_map="auto")
+model.eval()
+
+# change input text as desired
+prompt = "Write a code to find the maximum value in a list of numbers."
+
+# tokenize the text
+input_tokens = tokenizer(prompt, return_tensors="pt")
+# generate output tokens
+output = model.generate(**input_tokens, max_new_tokens=100)
+# decode output tokens into text
+output = tokenizer.batch_decode(output)
+# loop over the batch to print, in this example the batch size is 1
+for i in output:
+ print(i)
+```
+
+This model was contributed by [mayank-mishra](https://huggingface.co/mayank-mishra).
+
+
+## GraniteMoeConfig
+
+[[autodoc]] GraniteMoeConfig
+
+## GraniteMoeModel
+
+[[autodoc]] GraniteMoeModel
+ - forward
+
+## GraniteMoeForCausalLM
+
+[[autodoc]] GraniteMoeForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granitemoehybrid.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granitemoehybrid.md
new file mode 100644
index 0000000000000000000000000000000000000000..27b6e85d9e952ec758958e03f222d8cddf80a244
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granitemoehybrid.md
@@ -0,0 +1,91 @@
+
+*This model was released on 2025-05-02 and added to Hugging Face Transformers on 2025-05-05.*
+
+# GraniteMoeHybrid
+
+## Overview
+
+
+The [GraniteMoeHybrid](https://www.ibm.com/new/announcements/ibm-granite-4-0-tiny-preview-sneak-peek) model builds on top of GraniteMoeSharedModel and Bamba. Its decoding layers consist of state space layers or MoE attention layers with shared experts. By default, the attention layers do not use positional encoding.
+
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_path = "ibm-granite/granite-4.0-tiny-preview"
+tokenizer = AutoTokenizer.from_pretrained(model_path)
+
+# drop device_map if running on CPU
+model = AutoModelForCausalLM.from_pretrained(model_path, device_map="auto")
+model.eval()
+
+# change input text as desired
+prompt = "Write a code to find the maximum value in a list of numbers."
+
+# tokenize the text
+input_tokens = tokenizer(prompt, return_tensors="pt")
+# generate output tokens
+output = model.generate(**input_tokens, max_new_tokens=100)
+# decode output tokens into text
+output = tokenizer.batch_decode(output)
+# loop over the batch to print, in this example the batch size is 1
+for i in output:
+ print(i)
+```
+
+This HF implementation is contributed by [Sukriti Sharma](https://huggingface.co/SukritiSharma) and [Alexander Brooks](https://huggingface.co/abrooks9944).
+
+## Notes
+
+- `GraniteMoeHybridForCausalLM` supports padding-free training which concatenates distinct training examples while still processing inputs as separate batches. It can significantly accelerate inference by [~2x](https://github.com/huggingface/transformers/pull/35861#issue-2807873129) (depending on model and data distribution) and reduce memory-usage if there are examples of varying lengths by avoiding unnecessary compute and memory overhead from padding tokens.
+
+ Padding-free training requires the `flash-attn`, `mamba-ssm`, and `causal-conv1d` packages and the following arguments must be passed to the model in addition to `input_ids` and `labels`.
+
+ - `position_ids: torch.LongTensor`: the position index of each token in each sequence.
+ - `seq_idx: torch.IntTensor`: the index of each sequence in the batch.
+ - Each of the [`FlashAttentionKwargs`]
+ - `cu_seq_lens_q: torch.LongTensor`: the cumulative sequence lengths of all queries.
+ - `cu_seq_lens_k: torch.LongTensor`: the cumulative sequence lengths of all keys.
+ - `max_length_q: int`: the longest query length in the batch.
+ - `max_length_k: int`: the longest key length in the batch.
+
+ The `attention_mask` inputs should not be provided. The [`DataCollatorWithFlattening`] programmatically generates the set of additional arguments above using `return_seq_idx=True` and `return_flash_attn_kwargs=True`. See the [Improving Hugging Face Training Efficiency Through Packing with Flash Attention](https://huggingface.co/blog/packing-with-FA2) blog post for additional information.
+
+ ```python
+ from transformers import DataCollatorWithFlattening
+
+ # Example of using padding-free training
+ data_collator = DataCollatorWithFlattening(
+ tokenizer=tokenizer,
+ return_seq_idx=True,
+ return_flash_attn_kwargs=True
+ )
+ ```
+
+## GraniteMoeHybridConfig
+
+[[autodoc]] GraniteMoeHybridConfig
+
+## GraniteMoeHybridModel
+
+[[autodoc]] GraniteMoeHybridModel
+ - forward
+
+## GraniteMoeHybridForCausalLM
+
+[[autodoc]] GraniteMoeHybridForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granitemoeshared.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granitemoeshared.md
new file mode 100644
index 0000000000000000000000000000000000000000..d09ab5766faa9825aedeb4db62c4464e1ab01d9a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granitemoeshared.md
@@ -0,0 +1,67 @@
+
+*This model was released on 2024-08-23 and added to Hugging Face Transformers on 2025-02-14.*
+
+# GraniteMoeShared
+
+## Overview
+
+
+The GraniteMoe model was proposed in [Power Scheduler: A Batch Size and Token Number Agnostic Learning Rate Scheduler](https://huggingface.co/papers/2408.13359) by Yikang Shen, Matthew Stallone, Mayank Mishra, Gaoyuan Zhang, Shawn Tan, Aditya Prasad, Adriana Meza Soria, David D. Cox and Rameswar Panda.
+
+Additionally this class GraniteMoeSharedModel adds shared experts for Moe.
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model_path = "ibm-research/moe-7b-1b-active-shared-experts"
+tokenizer = AutoTokenizer.from_pretrained(model_path)
+
+# drop device_map if running on CPU
+model = AutoModelForCausalLM.from_pretrained(model_path, device_map="auto")
+model.eval()
+
+# change input text as desired
+prompt = "Write a code to find the maximum value in a list of numbers."
+
+# tokenize the text
+input_tokens = tokenizer(prompt, return_tensors="pt")
+# generate output tokens
+output = model.generate(**input_tokens, max_new_tokens=100)
+# decode output tokens into text
+output = tokenizer.batch_decode(output)
+# loop over the batch to print, in this example the batch size is 1
+for i in output:
+ print(i)
+```
+
+This HF implementation is contributed by [Mayank Mishra](https://huggingface.co/mayank-mishra), [Shawn Tan](https://huggingface.co/shawntan) and [Sukriti Sharma](https://huggingface.co/SukritiSharma).
+
+
+## GraniteMoeSharedConfig
+
+[[autodoc]] GraniteMoeSharedConfig
+
+## GraniteMoeSharedModel
+
+[[autodoc]] GraniteMoeSharedModel
+ - forward
+
+## GraniteMoeSharedForCausalLM
+
+[[autodoc]] GraniteMoeSharedForCausalLM
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granitevision.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granitevision.md
new file mode 100644
index 0000000000000000000000000000000000000000..b138c66f79d811d9f07377faf30deafc267aefae
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/granitevision.md
@@ -0,0 +1,88 @@
+
+*This model was released on 2024-12-18 and added to Hugging Face Transformers on 2025-01-23.*
+
+# Granite Vision
+
+## Overview
+
+The [Granite Vision](https://www.ibm.com/new/announcements/ibm-granite-3-1-powerful-performance-long-context-and-more) model is a variant of [LLaVA-NeXT](llava_next), leveraging a [Granite](granite) language model alongside a [SigLIP](SigLIP) visual encoder. It utilizes multiple concatenated vision hidden states as its image features, similar to [VipLlava](vipllava). It also uses a larger set of image grid pinpoints than the original LlaVa-NeXT models to support additional aspect ratios.
+
+Tips:
+- This model is loaded into Transformers as an instance of LlaVA-Next. The usage and tips from [LLaVA-NeXT](llava_next) apply to this model as well.
+
+- You can apply the chat template on the tokenizer / processor in the same way as well. Example chat format:
+```bash
+"<|user|>\nWhat’s shown in this image?\n<|assistant|>\nThis image shows a red stop sign.<|end_of_text|><|user|>\nDescribe the image in more details.\n<|assistant|>\n"
+```
+
+Sample inference:
+```python
+from transformers import LlavaNextProcessor, LlavaNextForConditionalGeneration, infer_device
+
+device = infer_device()
+
+model_path = "ibm-granite/granite-vision-3.1-2b-preview"
+processor = LlavaNextProcessor.from_pretrained(model_path)
+
+model = LlavaNextForConditionalGeneration.from_pretrained(model_path).to(device)
+
+# prepare image and text prompt, using the appropriate prompt template
+url = "https://github.com/haotian-liu/LLaVA/blob/1a91fc274d7c35a9b50b3cb29c4247ae5837ce39/images/llava_v1_5_radar.jpg?raw=true"
+
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": url},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+]
+inputs = processor.apply_chat_template(
+ conversation,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+).to(model.device)
+
+
+# autoregressively complete prompt
+output = model.generate(**inputs, max_new_tokens=100)
+
+print(processor.decode(output[0], skip_special_tokens=True))
+```
+
+This model was contributed by [Alexander Brooks](https://huggingface.co/abrooks9944).
+
+## LlavaNextConfig
+
+[[autodoc]] LlavaNextConfig
+
+## LlavaNextImageProcessor
+
+[[autodoc]] LlavaNextImageProcessor
+ - preprocess
+
+## LlavaNextProcessor
+
+[[autodoc]] LlavaNextProcessor
+
+## LlavaNextForConditionalGeneration
+
+[[autodoc]] LlavaNextForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/graphormer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/graphormer.md
new file mode 100644
index 0000000000000000000000000000000000000000..851f52df09f449afd203adc9c13abcdc827f7d6b
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/graphormer.md
@@ -0,0 +1,60 @@
+
+*This model was released on 2021-06-09 and added to Hugging Face Transformers on 2023-06-20.*
+
+# Graphormer
+
+
+
+
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The Graphormer model was proposed in [Do Transformers Really Perform Bad for Graph Representation?](https://huggingface.co/papers/2106.05234) by
+Chengxuan Ying, Tianle Cai, Shengjie Luo, Shuxin Zheng, Guolin Ke, Di He, Yanming Shen and Tie-Yan Liu. It is a Graph Transformer model, modified to allow computations on graphs instead of text sequences by generating embeddings and features of interest during preprocessing and collation, then using a modified attention.
+
+The abstract from the paper is the following:
+
+*The Transformer architecture has become a dominant choice in many domains, such as natural language processing and computer vision. Yet, it has not achieved competitive performance on popular leaderboards of graph-level prediction compared to mainstream GNN variants. Therefore, it remains a mystery how Transformers could perform well for graph representation learning. In this paper, we solve this mystery by presenting Graphormer, which is built upon the standard Transformer architecture, and could attain excellent results on a broad range of graph representation learning tasks, especially on the recent OGB Large-Scale Challenge. Our key insight to utilizing Transformer in the graph is the necessity of effectively encoding the structural information of a graph into the model. To this end, we propose several simple yet effective structural encoding methods to help Graphormer better model graph-structured data. Besides, we mathematically characterize the expressive power of Graphormer and exhibit that with our ways of encoding the structural information of graphs, many popular GNN variants could be covered as the special cases of Graphormer.*
+
+This model was contributed by [clefourrier](https://huggingface.co/clefourrier). The original code can be found [here](https://github.com/microsoft/Graphormer).
+
+## Usage tips
+
+This model will not work well on large graphs (more than 100 nodes/edges), as it will make the memory explode.
+You can reduce the batch size, increase your RAM, or decrease the `UNREACHABLE_NODE_DISTANCE` parameter in algos_graphormer.pyx, but it will be hard to go above 700 nodes/edges.
+
+This model does not use a tokenizer, but instead a special collator during training.
+
+## GraphormerConfig
+
+[[autodoc]] GraphormerConfig
+
+## GraphormerModel
+
+[[autodoc]] GraphormerModel
+ - forward
+
+## GraphormerForGraphClassification
+
+[[autodoc]] GraphormerForGraphClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/grounding-dino.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/grounding-dino.md
new file mode 100644
index 0000000000000000000000000000000000000000..22594ab1207b6f98ea0018aa7b05d1323ef8544a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/grounding-dino.md
@@ -0,0 +1,130 @@
+
+*This model was released on 2023-03-09 and added to Hugging Face Transformers on 2024-04-11.*
+
+# Grounding DINO
+
+
+
+
+
+## Overview
+
+The Grounding DINO model was proposed in [Grounding DINO: Marrying DINO with Grounded Pre-Training for Open-Set Object Detection](https://huggingface.co/papers/2303.05499) by Shilong Liu, Zhaoyang Zeng, Tianhe Ren, Feng Li, Hao Zhang, Jie Yang, Chunyuan Li, Jianwei Yang, Hang Su, Jun Zhu, Lei Zhang. Grounding DINO extends a closed-set object detection model with a text encoder, enabling open-set object detection. The model achieves remarkable results, such as 52.5 AP on COCO zero-shot.
+
+The abstract from the paper is the following:
+
+*In this paper, we present an open-set object detector, called Grounding DINO, by marrying Transformer-based detector DINO with grounded pre-training, which can detect arbitrary objects with human inputs such as category names or referring expressions. The key solution of open-set object detection is introducing language to a closed-set detector for open-set concept generalization. To effectively fuse language and vision modalities, we conceptually divide a closed-set detector into three phases and propose a tight fusion solution, which includes a feature enhancer, a language-guided query selection, and a cross-modality decoder for cross-modality fusion. While previous works mainly evaluate open-set object detection on novel categories, we propose to also perform evaluations on referring expression comprehension for objects specified with attributes. Grounding DINO performs remarkably well on all three settings, including benchmarks on COCO, LVIS, ODinW, and RefCOCO/+/g. Grounding DINO achieves a 52.5 AP on the COCO detection zero-shot transfer benchmark, i.e., without any training data from COCO. It sets a new record on the ODinW zero-shot benchmark with a mean 26.1 AP.*
+
+
+
+ Grounding DINO overview. Taken from the original paper.
+
+This model was contributed by [EduardoPacheco](https://huggingface.co/EduardoPacheco) and [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/IDEA-Research/GroundingDINO).
+
+## Usage tips
+
+- One can use [`GroundingDinoProcessor`] to prepare image-text pairs for the model.
+- To separate classes in the text use a period e.g. "a cat. a dog."
+- When using multiple classes (e.g. `"a cat. a dog."`), use `post_process_grounded_object_detection` from [`GroundingDinoProcessor`] to post process outputs. Since, the labels returned from `post_process_object_detection` represent the indices from the model dimension where prob > threshold.
+
+Here's how to use the model for zero-shot object detection:
+
+```python
+>>> import requests
+
+>>> import torch
+>>> from PIL import Image
+>>> from transformers import AutoProcessor, AutoModelForZeroShotObjectDetection
+
+>>> model_id = "IDEA-Research/grounding-dino-tiny"
+>>> device = "cuda"
+
+>>> processor = AutoProcessor.from_pretrained(model_id)
+>>> model = AutoModelForZeroShotObjectDetection.from_pretrained(model_id).to(device)
+
+>>> image_url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(image_url, stream=True).raw)
+>>> # Check for cats and remote controls
+>>> text_labels = [["a cat", "a remote control"]]
+
+>>> inputs = processor(images=image, text=text_labels, return_tensors="pt").to(device)
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> results = processor.post_process_grounded_object_detection(
+... outputs,
+... inputs.input_ids,
+... box_threshold=0.4,
+... text_threshold=0.3,
+... target_sizes=[image.size[::-1]]
+... )
+
+# Retrieve the first image result
+>>> result = results[0]
+>>> for box, score, labels in zip(result["boxes"], result["scores"], result["labels"]):
+... box = [round(x, 2) for x in box.tolist()]
+... print(f"Detected {labels} with confidence {round(score.item(), 3)} at location {box}")
+Detected a cat with confidence 0.468 at location [344.78, 22.9, 637.3, 373.62]
+Detected a cat with confidence 0.426 at location [11.74, 51.55, 316.51, 473.22]
+```
+
+## Grounded SAM
+
+One can combine Grounding DINO with the [Segment Anything](sam) model for text-based mask generation as introduced in [Grounded SAM: Assembling Open-World Models for Diverse Visual Tasks](https://huggingface.co/papers/2401.14159). You can refer to this [demo notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/Grounding%20DINO/GroundingDINO_with_Segment_Anything.ipynb) 🌍 for details.
+
+
+
+ Grounded SAM overview. Taken from the original repository.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Grounding DINO. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- Demo notebooks regarding inference with Grounding DINO as well as combining it with [SAM](sam) can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Grounding%20DINO). 🌎
+
+## GroundingDinoImageProcessor
+
+[[autodoc]] GroundingDinoImageProcessor
+ - preprocess
+
+## GroundingDinoImageProcessorFast
+
+[[autodoc]] GroundingDinoImageProcessorFast
+ - preprocess
+ - post_process_object_detection
+
+## GroundingDinoProcessor
+
+[[autodoc]] GroundingDinoProcessor
+ - post_process_grounded_object_detection
+
+## GroundingDinoConfig
+
+[[autodoc]] GroundingDinoConfig
+
+## GroundingDinoModel
+
+[[autodoc]] GroundingDinoModel
+ - forward
+
+## GroundingDinoForObjectDetection
+
+[[autodoc]] GroundingDinoForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/groupvit.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/groupvit.md
new file mode 100644
index 0000000000000000000000000000000000000000..ceb29d897f27c040cf32960330fdeb596ca11e45
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/groupvit.md
@@ -0,0 +1,102 @@
+
+*This model was released on 2022-02-22 and added to Hugging Face Transformers on 2022-06-28.*
+
+# GroupViT
+
+
+
+
+
+
+## Overview
+
+The GroupViT model was proposed in [GroupViT: Semantic Segmentation Emerges from Text Supervision](https://huggingface.co/papers/2202.11094) by Jiarui Xu, Shalini De Mello, Sifei Liu, Wonmin Byeon, Thomas Breuel, Jan Kautz, Xiaolong Wang.
+Inspired by [CLIP](clip), GroupViT is a vision-language model that can perform zero-shot semantic segmentation on any given vocabulary categories.
+
+The abstract from the paper is the following:
+
+*Grouping and recognition are important components of visual scene understanding, e.g., for object detection and semantic segmentation. With end-to-end deep learning systems, grouping of image regions usually happens implicitly via top-down supervision from pixel-level recognition labels. Instead, in this paper, we propose to bring back the grouping mechanism into deep networks, which allows semantic segments to emerge automatically with only text supervision. We propose a hierarchical Grouping Vision Transformer (GroupViT), which goes beyond the regular grid structure representation and learns to group image regions into progressively larger arbitrary-shaped segments. We train GroupViT jointly with a text encoder on a large-scale image-text dataset via contrastive losses. With only text supervision and without any pixel-level annotations, GroupViT learns to group together semantic regions and successfully transfers to the task of semantic segmentation in a zero-shot manner, i.e., without any further fine-tuning. It achieves a zero-shot accuracy of 52.3% mIoU on the PASCAL VOC 2012 and 22.4% mIoU on PASCAL Context datasets, and performs competitively to state-of-the-art transfer-learning methods requiring greater levels of supervision.*
+
+This model was contributed by [xvjiarui](https://huggingface.co/xvjiarui). The TensorFlow version was contributed by [ariG23498](https://huggingface.co/ariG23498) with the help of [Yih-Dar SHIEH](https://huggingface.co/ydshieh), [Amy Roberts](https://huggingface.co/amyeroberts), and [Joao Gante](https://huggingface.co/joaogante).
+The original code can be found [here](https://github.com/NVlabs/GroupViT).
+
+## Usage tips
+
+- You may specify `output_segmentation=True` in the forward of `GroupViTModel` to get the segmentation logits of input texts.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with GroupViT.
+
+- The quickest way to get started with GroupViT is by checking the [example notebooks](https://github.com/xvjiarui/GroupViT/blob/main/demo/GroupViT_hf_inference_notebook.ipynb) (which showcase zero-shot segmentation inference).
+- One can also check out the [HuggingFace Spaces demo](https://huggingface.co/spaces/xvjiarui/GroupViT) to play with GroupViT.
+
+## GroupViTConfig
+
+[[autodoc]] GroupViTConfig
+ - from_text_vision_configs
+
+## GroupViTTextConfig
+
+[[autodoc]] GroupViTTextConfig
+
+## GroupViTVisionConfig
+
+[[autodoc]] GroupViTVisionConfig
+
+
+
+
+## GroupViTModel
+
+[[autodoc]] GroupViTModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## GroupViTTextModel
+
+[[autodoc]] GroupViTTextModel
+ - forward
+
+## GroupViTVisionModel
+
+[[autodoc]] GroupViTVisionModel
+ - forward
+
+
+
+
+## TFGroupViTModel
+
+[[autodoc]] TFGroupViTModel
+ - call
+ - get_text_features
+ - get_image_features
+
+## TFGroupViTTextModel
+
+[[autodoc]] TFGroupViTTextModel
+ - call
+
+## TFGroupViTVisionModel
+
+[[autodoc]] TFGroupViTVisionModel
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/helium.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/helium.md
new file mode 100644
index 0000000000000000000000000000000000000000..ba06feb18fbe1711b2264d929a93a131de899f13
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/helium.md
@@ -0,0 +1,159 @@
+
+*This model was released on 2025-01-13 and added to Hugging Face Transformers on 2025-01-13.*
+
+# Helium
+
+
+
+
+
+
+
+## Overview
+
+Helium was proposed in [Announcing Helium-1 Preview](https://kyutai.org/2025/01/13/helium.html) by the Kyutai Team.
+
+
+Helium-1 preview is a lightweight language model with 2B parameters, targeting edge and mobile devices.
+It supports the following languages: English, French, German, Italian, Portuguese, Spanish.
+
+- **Developed by:** Kyutai
+- **Model type:** Large Language Model
+- **Language(s) (NLP):** English, French, German, Italian, Portuguese, Spanish
+- **License:** CC-BY 4.0
+
+
+
+
+## Evaluation
+
+
+
+#### Testing Data
+
+
+
+The model was evaluated on MMLU, TriviaQA, NaturalQuestions, ARC Easy & Challenge, Open Book QA, Common Sense QA,
+Physical Interaction QA, Social Interaction QA, HellaSwag, WinoGrande, Multilingual Knowledge QA, FLORES 200.
+
+#### Metrics
+
+
+
+We report accuracy on MMLU, ARC, OBQA, CSQA, PIQA, SIQA, HellaSwag, WinoGrande.
+We report exact match on TriviaQA, NQ and MKQA.
+We report BLEU on FLORES.
+
+### English Results
+
+| Benchmark | Helium-1 Preview | HF SmolLM2 (1.7B) | Gemma-2 (2.6B) | Llama-3.2 (3B) | Qwen2.5 (1.5B) |
+|--------------|--------|--------|--------|--------|--------|
+| | | | | | |
+| MMLU | 51.2 | 50.4 | 53.1 | 56.6 | 61.0 |
+| NQ | 17.3 | 15.1 | 17.7 | 22.0 | 13.1 |
+| TQA | 47.9 | 45.4 | 49.9 | 53.6 | 35.9 |
+| ARC E | 80.9 | 81.8 | 81.1 | 84.6 | 89.7 |
+| ARC C | 62.7 | 64.7 | 66.0 | 69.0 | 77.2 |
+| OBQA | 63.8 | 61.4 | 64.6 | 68.4 | 73.8 |
+| CSQA | 65.6 | 59.0 | 64.4 | 65.4 | 72.4 |
+| PIQA | 77.4 | 77.7 | 79.8 | 78.9 | 76.0 |
+| SIQA | 64.4 | 57.5 | 61.9 | 63.8 | 68.7 |
+| HS | 69.7 | 73.2 | 74.7 | 76.9 | 67.5 |
+| WG | 66.5 | 65.6 | 71.2 | 72.0 | 64.8 |
+| | | | | | |
+| Average | 60.7 | 59.3 | 62.2 | 64.7 | 63.6 |
+
+#### Multilingual Results
+
+| Language | Benchmark | Helium-1 Preview | HF SmolLM2 (1.7B) | Gemma-2 (2.6B) | Llama-3.2 (3B) | Qwen2.5 (1.5B) |
+|-----|--------------|--------|--------|--------|--------|--------|
+| | | | | | | |
+|German| MMLU | 45.6 | 35.3 | 45.0 | 47.5 | 49.5 |
+|| ARC C | 56.7 | 38.4 | 54.7 | 58.3 | 60.2 |
+|| HS | 53.5 | 33.9 | 53.4 | 53.7 | 42.8 |
+|| MKQA | 16.1 | 7.1 | 18.9 | 20.2 | 10.4 |
+| | | | | | | |
+|Spanish| MMLU | 46.5 | 38.9 | 46.2 | 49.6 | 52.8 |
+|| ARC C | 58.3 | 43.2 | 58.8 | 60.0 | 68.1 |
+|| HS | 58.6 | 40.8 | 60.5 | 61.1 | 51.4 |
+|| MKQA | 16.0 | 7.9 | 18.5 | 20.6 | 10.6 |
+
+
+## Technical Specifications
+
+### Model Architecture and Objective
+
+| Hyperparameter | Value |
+|--------------|--------|
+| Layers | 24 |
+| Heads | 20 |
+| Model dimension | 2560 |
+| MLP dimension | 7040 |
+| Context size | 4096 |
+| Theta RoPE | 100,000 |
+
+Tips:
+
+- This model was contributed by [Laurent Mazare](https://huggingface.co/lmz)
+
+
+## Usage tips
+
+`Helium` can be found on the [Huggingface Hub](https://huggingface.co/models?other=helium)
+
+In the following, we demonstrate how to use `helium-1-preview` for the inference.
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("kyutai/helium-1-preview-2b", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("kyutai/helium-1-preview-2b")
+
+>>> prompt = "Give me a short introduction to large language model."
+
+>>> model_inputs = tokenizer(prompt, return_tensors="pt").to(model.device)
+
+>>> generated_ids = model.generate(model_inputs.input_ids, max_new_tokens=512, do_sample=True)
+
+>>> generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(model_inputs.input_ids, generated_ids)]
+
+>>> response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+```
+
+## HeliumConfig
+
+[[autodoc]] HeliumConfig
+
+## HeliumModel
+
+[[autodoc]] HeliumModel
+ - forward
+
+## HeliumForCausalLM
+
+[[autodoc]] HeliumForCausalLM
+ - forward
+
+## HeliumForSequenceClassification
+
+[[autodoc]] HeliumForSequenceClassification
+ - forward
+
+## HeliumForTokenClassification
+
+[[autodoc]] HeliumForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/herbert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/herbert.md
new file mode 100644
index 0000000000000000000000000000000000000000..2e5f2cbe6679f81778f7f99698f82072777a6094
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/herbert.md
@@ -0,0 +1,84 @@
+
+*This model was released on 2020-05-01 and added to Hugging Face Transformers on 2020-11-16.*
+
+# HerBERT
+
+
+
+
+
+
+
+## Overview
+
+The HerBERT model was proposed in [KLEJ: Comprehensive Benchmark for Polish Language Understanding](https://huggingface.co/papers/2005.00630) by Piotr Rybak, Robert Mroczkowski, Janusz Tracz, and
+Ireneusz Gawlik. It is a BERT-based Language Model trained on Polish Corpora using only MLM objective with dynamic
+masking of whole words.
+
+The abstract from the paper is the following:
+
+*In recent years, a series of Transformer-based models unlocked major improvements in general natural language
+understanding (NLU) tasks. Such a fast pace of research would not be possible without general NLU benchmarks, which
+allow for a fair comparison of the proposed methods. However, such benchmarks are available only for a handful of
+languages. To alleviate this issue, we introduce a comprehensive multi-task benchmark for the Polish language
+understanding, accompanied by an online leaderboard. It consists of a diverse set of tasks, adopted from existing
+datasets for named entity recognition, question-answering, textual entailment, and others. We also introduce a new
+sentiment analysis task for the e-commerce domain, named Allegro Reviews (AR). To ensure a common evaluation scheme and
+promote models that generalize to different NLU tasks, the benchmark includes datasets from varying domains and
+applications. Additionally, we release HerBERT, a Transformer-based model trained specifically for the Polish language,
+which has the best average performance and obtains the best results for three out of nine tasks. Finally, we provide an
+extensive evaluation, including several standard baselines and recently proposed, multilingual Transformer-based
+models.*
+
+This model was contributed by [rmroczkowski](https://huggingface.co/rmroczkowski). The original code can be found
+[here](https://github.com/allegro/HerBERT).
+
+
+## Usage example
+
+```python
+>>> from transformers import HerbertTokenizer, RobertaModel
+
+>>> tokenizer = HerbertTokenizer.from_pretrained("allegro/herbert-klej-cased-tokenizer-v1")
+>>> model = RobertaModel.from_pretrained("allegro/herbert-klej-cased-v1")
+
+>>> encoded_input = tokenizer.encode("Kto ma lepszą sztukę, ma lepszy rząd – to jasne.", return_tensors="pt")
+>>> outputs = model(encoded_input)
+
+>>> # HerBERT can also be loaded using AutoTokenizer and AutoModel:
+>>> import torch
+>>> from transformers import AutoModel, AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("allegro/herbert-klej-cased-tokenizer-v1")
+>>> model = AutoModel.from_pretrained("allegro/herbert-klej-cased-v1")
+```
+
+
+
+Herbert implementation is the same as `BERT` except for the tokenization method. Refer to [BERT documentation](bert)
+for API reference and examples.
+
+
+
+## HerbertTokenizer
+
+[[autodoc]] HerbertTokenizer
+
+## HerbertTokenizerFast
+
+[[autodoc]] HerbertTokenizerFast
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/hgnet_v2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/hgnet_v2.md
new file mode 100644
index 0000000000000000000000000000000000000000..8c315e9b82525fa22f6b9b8bd1e48e88f0151671
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/hgnet_v2.md
@@ -0,0 +1,94 @@
+
+*This model was released on 2024-07-01 and added to Hugging Face Transformers on 2025-04-29.*
+
+
+
+
+
+
+
+# HGNet-V2
+
+[HGNetV2](https://github.com/PaddlePaddle/PaddleClas/blob/v2.6.0/docs/zh_CN/models/ImageNet1k/PP-HGNetV2.md) is a next-generation convolutional neural network (CNN) backbone built for optimal accuracy-latency tradeoff on NVIDIA GPUs. Building on the original[HGNet](https://github.com/PaddlePaddle/PaddleClas/blob/v2.6.0/docs/en/models/PP-HGNet_en.md), HGNetV2 delivers high accuracy at fast inference speeds and performs strongly on tasks like image classification, object detection, and segmentation, making it a practical choice for GPU-based computer vision applications.
+
+You can find all the original HGNet V2 models under the [USTC](https://huggingface.co/ustc-community/models?search=hgnet) organization.
+
+> [!TIP]
+> This model was contributed by [VladOS95-cyber](https://github.com/VladOS95-cyber).
+> Click on the HGNet V2 models in the right sidebar for more examples of how to apply HGNet V2 to different computer vision tasks.
+
+The example below demonstrates how to classify an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="image-classification",
+ model="ustc-community/hgnet-v2",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("http://images.cocodataset.org/val2017/000000039769.jpg")
+```
+
+
+
+
+```py
+import torch
+import requests
+from transformers import HGNetV2ForImageClassification, AutoImageProcessor
+from PIL import Image
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+model = HGNetV2ForImageClassification.from_pretrained("ustc-community/hgnet-v2")
+processor = AutoImageProcessor.from_pretrained("ustc-community/hgnet-v2")
+
+inputs = processor(images=image, return_tensors="pt")
+with torch.no_grad():
+ logits = model(**inputs).logits
+predicted_class_id = logits.argmax(dim=-1).item()
+
+class_labels = model.config.id2label
+predicted_class_label = class_labels[predicted_class_id]
+print(f"The predicted class label is: {predicted_class_label}")
+```
+
+
+
+
+## HGNetV2Config
+
+[[autodoc]] HGNetV2Config
+
+
+## HGNetV2Backbone
+
+[[autodoc]] HGNetV2Backbone
+ - forward
+
+
+## HGNetV2ForImageClassification
+
+[[autodoc]] HGNetV2ForImageClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/hiera.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/hiera.md
new file mode 100644
index 0000000000000000000000000000000000000000..9f4627dd53f149884042c087563c0ccd97efee8f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/hiera.md
@@ -0,0 +1,67 @@
+
+*This model was released on 2023-06-01 and added to Hugging Face Transformers on 2024-07-12.*
+
+# Hiera
+
+
+
+
+
+## Overview
+
+Hiera was proposed in [Hiera: A Hierarchical Vision Transformer without the Bells-and-Whistles](https://huggingface.co/papers/2306.00989) by Chaitanya Ryali, Yuan-Ting Hu, Daniel Bolya, Chen Wei, Haoqi Fan, Po-Yao Huang, Vaibhav Aggarwal, Arkabandhu Chowdhury, Omid Poursaeed, Judy Hoffman, Jitendra Malik, Yanghao Li, Christoph Feichtenhofer
+
+The paper introduces "Hiera," a hierarchical Vision Transformer that simplifies the architecture of modern hierarchical vision transformers by removing unnecessary components without compromising on accuracy or efficiency. Unlike traditional transformers that add complex vision-specific components to improve supervised classification performance, Hiera demonstrates that such additions, often termed "bells-and-whistles," are not essential for high accuracy. By leveraging a strong visual pretext task (MAE) for pretraining, Hiera retains simplicity and achieves superior accuracy and speed both in inference and training across various image and video recognition tasks. The approach suggests that spatial biases required for vision tasks can be effectively learned through proper pretraining, eliminating the need for added architectural complexity.
+
+The abstract from the paper is the following:
+
+*Modern hierarchical vision transformers have added several vision-specific components in the pursuit of supervised classification performance. While these components lead to effective accuracies and attractive FLOP counts, the added complexity actually makes these transformers slower than their vanilla ViT counterparts. In this paper, we argue that this additional bulk is unnecessary. By pretraining with a strong visual pretext task (MAE), we can strip out all the bells-and-whistles from a state-of-the-art multi-stage vision transformer without losing accuracy. In the process, we create Hiera, an extremely simple hierarchical vision transformer that is more accurate than previous models while being significantly faster both at inference and during training. We evaluate Hiera on a variety of tasks for image and video recognition. Our code and models are available at https://github.com/facebookresearch/hiera.*
+
+
+
+ Hiera architecture. Taken from the original paper.
+
+This model was a joint contribution by [EduardoPacheco](https://huggingface.co/EduardoPacheco) and [namangarg110](https://huggingface.co/namangarg110). The original code can be found [here] (https://github.com/facebookresearch/hiera).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Hiera. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- [`HieraForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+## HieraConfig
+
+[[autodoc]] HieraConfig
+
+## HieraModel
+
+[[autodoc]] HieraModel
+ - forward
+
+## HieraForPreTraining
+
+[[autodoc]] HieraForPreTraining
+ - forward
+
+## HieraForImageClassification
+
+[[autodoc]] HieraForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/hubert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/hubert.md
new file mode 100644
index 0000000000000000000000000000000000000000..36323e16ba906a27b3ed6bd3dd9e6e3204fc520a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/hubert.md
@@ -0,0 +1,160 @@
+
+*This model was released on 2021-06-14 and added to Hugging Face Transformers on 2021-06-16.*
+
+
+
+
+
+
+
+
+
+
+# HuBERT
+
+[HuBERT](https://huggingface.co/papers/2106.07447) is a self-supervised speech model to cluster aligned target labels for BERT-like prediction loss and applying the prediction loss only over masked regions to force the model to learn both acoustic and language modeling over continuous inputs. It addresses the challenges of multiple sound units per utterance, no lexicon during pre-training, and variable-length sound units without explicit segmentation.
+
+You can find all the original HuBERT checkpoints under the [HuBERT](https://huggingface.co/collections/facebook/hubert-651fca95d57549832161e6b6) collection.
+
+> [!TIP]
+> This model was contributed by [patrickvonplaten](https://huggingface.co/patrickvonplaten).
+>
+> Click on the HuBERT models in the right sidebar for more examples of how to apply HuBERT to different audio tasks.
+
+The example below demonstrates how to automatically transcribe speech into text with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```python
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="automatic-speech-recognition",
+ model="facebook/hubert-large-ls960-ft",
+ torch_dtype=torch.float16,
+ device=0
+)
+
+pipeline("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/1.flac")
+```
+
+
+
+
+```python
+import torch
+from transformers import AutoProcessor, AutoModelForCTC
+from datasets import load_dataset
+
+dataset = load_dataset("hf-internal-testing/librispeech_asr_demo", "clean", split="validation").sort("id")
+sampling_rate = dataset.features["audio"].sampling_rate
+
+processor = AutoProcessor.from_pretrained("facebook/hubert-base-ls960")
+model = AutoModelForCTC.from_pretrained("facebook/hubert-base-ls960", torch_dtype=torch.float16, device_map="auto", attn_implementation="sdpa")
+
+inputs = processor(dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
+with torch.no_grad():
+ logits = model(**inputs).logits
+predicted_ids = torch.argmax(logits, dim=-1)
+
+transcription = processor.batch_decode(predicted_ids)
+print(transcription[0])
+```
+
+
+
+
+## Quantization
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision.
+Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to quantize the weights to 4-bits.
+
+```python
+import torch
+from transformers import AutoProcessor, AutoModelForCTC, BitsAndBytesConfig
+from datasets import load_dataset
+
+bnb_config = BitsAndBytesConfig(
+ load_in_8bit=True,
+ llm_int8_threshold=6.0
+)
+
+dataset = load_dataset("hf-internal-testing/librispeech_asr_demo", "clean", split="validation").sort("id")
+sampling_rate = dataset.features["audio"].sampling_rate
+
+processor = AutoProcessor.from_pretrained("facebook/hubert-base-ls960")
+model = AutoModelForCTC.from_pretrained("facebook/hubert-base-ls960", quantization_config=bnb_config, torch_dtype=torch.float16, device_map="auto", attn_implementation="sdpa")
+
+inputs = processor(dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
+with torch.no_grad():
+ logits = model(**inputs).logits
+predicted_ids = torch.argmax(logits, dim=-1)
+
+transcription = processor.batch_decode(predicted_ids)
+print(transcription[0])
+```
+
+## Notes
+
+- HuBERT models expect raw audio input as a 1D float array sampled at 16kHz.
+- If you want to use a `head_mask`, use the model with `attn_implementation="eager"`.
+ ```python
+ model = HubertModel.from_pretrained("facebook/hubert-base-ls960", attn_implementation="eager")
+ ```
+
+## HubertConfig
+
+[[autodoc]] HubertConfig
+ - all
+
+
+
+
+## HubertModel
+
+[[autodoc]] HubertModel
+ - forward
+
+## HubertForCTC
+
+[[autodoc]] HubertForCTC
+ - forward
+
+## HubertForSequenceClassification
+
+[[autodoc]] HubertForSequenceClassification
+ - forward
+
+
+
+
+## TFHubertModel
+
+[[autodoc]] TFHubertModel
+ - call
+
+## TFHubertForCTC
+
+[[autodoc]] TFHubertForCTC
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ibert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ibert.md
new file mode 100644
index 0000000000000000000000000000000000000000..a04d291a6be5666121c30cb14ca102588d21899f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ibert.md
@@ -0,0 +1,88 @@
+
+*This model was released on 2021-01-05 and added to Hugging Face Transformers on 2021-02-26.*
+
+# I-BERT
+
+
+
+
+
+## Overview
+
+The I-BERT model was proposed in [I-BERT: Integer-only BERT Quantization](https://huggingface.co/papers/2101.01321) by
+Sehoon Kim, Amir Gholami, Zhewei Yao, Michael W. Mahoney and Kurt Keutzer. It's a quantized version of RoBERTa running
+inference up to four times faster.
+
+The abstract from the paper is the following:
+
+*Transformer based models, like BERT and RoBERTa, have achieved state-of-the-art results in many Natural Language
+Processing tasks. However, their memory footprint, inference latency, and power consumption are prohibitive for
+efficient inference at the edge, and even at the data center. While quantization can be a viable solution for this,
+previous work on quantizing Transformer based models use floating-point arithmetic during inference, which cannot
+efficiently utilize integer-only logical units such as the recent Turing Tensor Cores, or traditional integer-only ARM
+processors. In this work, we propose I-BERT, a novel quantization scheme for Transformer based models that quantizes
+the entire inference with integer-only arithmetic. Based on lightweight integer-only approximation methods for
+nonlinear operations, e.g., GELU, Softmax, and Layer Normalization, I-BERT performs an end-to-end integer-only BERT
+inference without any floating point calculation. We evaluate our approach on GLUE downstream tasks using
+RoBERTa-Base/Large. We show that for both cases, I-BERT achieves similar (and slightly higher) accuracy as compared to
+the full-precision baseline. Furthermore, our preliminary implementation of I-BERT shows a speedup of 2.4 - 4.0x for
+INT8 inference on a T4 GPU system as compared to FP32 inference. The framework has been developed in PyTorch and has
+been open-sourced.*
+
+This model was contributed by [kssteven](https://huggingface.co/kssteven). The original code can be found [here](https://github.com/kssteven418/I-BERT).
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/masked_language_modeling)
+
+## IBertConfig
+
+[[autodoc]] IBertConfig
+
+## IBertModel
+
+[[autodoc]] IBertModel
+ - forward
+
+## IBertForMaskedLM
+
+[[autodoc]] IBertForMaskedLM
+ - forward
+
+## IBertForSequenceClassification
+
+[[autodoc]] IBertForSequenceClassification
+ - forward
+
+## IBertForMultipleChoice
+
+[[autodoc]] IBertForMultipleChoice
+ - forward
+
+## IBertForTokenClassification
+
+[[autodoc]] IBertForTokenClassification
+ - forward
+
+## IBertForQuestionAnswering
+
+[[autodoc]] IBertForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/idefics.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/idefics.md
new file mode 100644
index 0000000000000000000000000000000000000000..57b2c8328b5d42e4a0b0a0862efdec43cec5e85d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/idefics.md
@@ -0,0 +1,80 @@
+
+*This model was released on 2023-06-21 and added to Hugging Face Transformers on 2023-08-18.*
+
+# IDEFICS
+
+
+
+
+
+
+
+## Overview
+
+The IDEFICS model was proposed in [OBELICS: An Open Web-Scale Filtered Dataset of Interleaved Image-Text Documents
+](https://huggingface.co/papers/2306.16527
+) by Hugo Laurençon, Lucile Saulnier, Léo Tronchon, Stas Bekman, Amanpreet Singh, Anton Lozhkov, Thomas Wang, Siddharth Karamcheti, Alexander M. Rush, Douwe Kiela, Matthieu Cord, Victor Sanh
+
+The abstract from the paper is the following:
+
+*Large multimodal models trained on natural documents, which interleave images and text, outperform models trained on image-text pairs on various multimodal benchmarks that require reasoning over one or multiple images to generate a text. However, the datasets used to train these models have not been released, and the collection process has not been fully specified. We introduce the OBELICS dataset, an open web-scale filtered dataset of interleaved image-text documents comprising 141 million web pages extracted from Common Crawl, 353 million associated images, and 115 billion text tokens. We describe the dataset creation process, present comprehensive filtering rules, and provide an analysis of the dataset's content. To show the viability of OBELISC, we train an 80 billion parameters vision and language model on the dataset and obtain competitive performance on various multimodal benchmarks. We release the code to reproduce the dataset along with the dataset itself.*
+
+This model was contributed by [HuggingFaceM4](https://huggingface.co/HuggingFaceM4). The original code can be found [here](). (TODO: don't have a public link yet).
+
+
+
+
+IDEFICS modeling code in Transformers is for finetuning and inferencing the pre-trained IDEFICS models.
+
+To train a new IDEFICS model from scratch use the m4 codebase (a link will be provided once it's made public)
+
+
+
+
+## IdeficsConfig
+
+[[autodoc]] IdeficsConfig
+
+## IdeficsModel
+
+[[autodoc]] IdeficsModel
+ - forward
+
+## IdeficsForVisionText2Text
+
+[[autodoc]] IdeficsForVisionText2Text
+ - forward
+
+## TFIdeficsModel
+
+[[autodoc]] TFIdeficsModel
+ - call
+
+## TFIdeficsForVisionText2Text
+
+[[autodoc]] TFIdeficsForVisionText2Text
+ - call
+
+## IdeficsImageProcessor
+
+[[autodoc]] IdeficsImageProcessor
+ - preprocess
+
+## IdeficsProcessor
+
+[[autodoc]] IdeficsProcessor
+ - __call__
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/idefics2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/idefics2.md
new file mode 100644
index 0000000000000000000000000000000000000000..d3bfcd0564231dc28fb9cc43f9e50763eb8fa894
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/idefics2.md
@@ -0,0 +1,228 @@
+
+*This model was released on 2024-05-03 and added to Hugging Face Transformers on 2024-04-15.*
+
+# Idefics2
+
+
+
+
+
+
+
+## Overview
+
+The Idefics2 model was proposed in [What matters when building vision-language models?](https://huggingface.co/papers/2405.02246) by Léo Tronchon, Hugo Laurencon, Victor Sanh. The accompanying blog post can be found [here](https://huggingface.co/blog/idefics2).
+
+Idefics2 is an open multimodal model that accepts arbitrary sequences of image and text inputs and produces text
+outputs. The model can answer questions about images, describe visual content, create stories grounded on multiple
+images, or simply behave as a pure language model without visual inputs. It improves upon IDEFICS-1, notably on
+document understanding, OCR, or visual reasoning. Idefics2 is lightweight (8 billion parameters) and treats
+images in their native aspect ratio and resolution, which allows for varying inference efficiency.
+
+The abstract from the paper is the following:
+
+*The growing interest in vision-language models (VLMs) has been driven by improvements in large language models and vision transformers. Despite the abundance of literature on this subject, we observe that critical decisions regarding the design of VLMs are often not justified. We argue that these unsupported decisions impede progress in the field by making it difficult to identify which choices improve model performance. To address this issue, we conduct extensive experiments around pre-trained models, architecture choice, data, and training methods. Our consolidation of findings includes the development of Idefics2, an efficient foundational VLM of 8 billion parameters. Idefics2 achieves state-of-the-art performance within its size category across various multimodal benchmarks, and is often on par with models four times its size. We release the model (base, instructed, and chat) along with the datasets created for its training.*
+
+
+
+ Idefics2 architecture. Taken from the original paper.
+
+This model was contributed by [amyeroberts](https://huggingface.co/amyeroberts).
+The original code can be found [here](https://huggingface.co/HuggingFaceM4/idefics2).
+
+## Usage tips
+
+- Each sample can contain multiple images, and the number of images can vary between samples. The processor will pad the inputs to the maximum number of images in a batch for input to the model.
+- The processor has a `do_image_splitting` option. If `True`, each input image will be split into 4 sub-images, and concatenated with the original to form 5 images. This is useful for increasing model performance. Make sure `processor.image_processor.do_image_splitting` is set to `False` if the model was not trained with this option.
+- `text` passed to the processor should have the `` tokens where the images should be inserted. And `` at the end of each utterance if the text is a chat message.
+- The processor has its own `apply_chat_template` method to convert chat messages to text that can then be passed as `text` to the processor.
+
+Example of how to use the processor on chat messages:
+
+```python
+import requests
+from PIL import Image
+from transformers import Idefics2Processor, Idefics2ForConditionalGeneration, infer_device
+import torch
+
+device = infer_device()
+
+url_1 = "http://images.cocodataset.org/val2017/000000039769.jpg"
+url_2 = "http://images.cocodataset.org/val2017/000000219578.jpg"
+
+image_1 = Image.open(requests.get(url_1, stream=True).raw)
+image_2 = Image.open(requests.get(url_2, stream=True).raw)
+images = [image_1, image_2]
+
+messages = [{
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "What’s the difference between these two images?"},
+ {"type": "image"},
+ {"type": "image"},
+ ],
+}]
+
+processor = Idefics2Processor.from_pretrained("HuggingFaceM4/idefics2-8b")
+model = Idefics2ForConditionalGeneration.from_pretrained("HuggingFaceM4/idefics2-8b")
+model.to(device)
+
+# at inference time, one needs to pass `add_generation_prompt=True` in order to make sure the model completes the prompt
+text = processor.apply_chat_template(messages, add_generation_prompt=True)
+print(text)
+# 'User: What’s the difference between these two images?\nAssistant:'
+
+inputs = processor(images=images, text=text, return_tensors="pt").to(model.device)
+
+generated_text = model.generate(**inputs, max_new_tokens=500)
+generated_text = processor.batch_decode(generated_text, skip_special_tokens=True)[0]
+print("Generated text:", generated_text)
+```
+
+- During training, it's important to determine which tokens the model should not learn. For Idefics2, this typically comes down to the image and padding tokens. This means that one can create the labels as follows:
+
+```python
+import requests
+from PIL import Image
+from transformers import Idefics2Processor, Idefics2ForConditionalGeneration, infer_device
+import torch
+
+url_1 = "http://images.cocodataset.org/val2017/000000039769.jpg"
+url_2 = "http://images.cocodataset.org/val2017/000000219578.jpg"
+
+image_1 = Image.open(requests.get(url_1, stream=True).raw)
+image_2 = Image.open(requests.get(url_2, stream=True).raw)
+images = [image_1, image_2]
+
+messages = [{
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "What’s the difference between these two images?"},
+ {"type": "image"},
+ {"type": "image"},
+ ],
+},
+{
+ "role": "assistant",
+ "content": [
+ {"type": "text", "text": "The difference is that one image is about dogs and the other one about cats."},
+ ],
+}]
+
+device = infer_device()
+
+processor = Idefics2Processor.from_pretrained("HuggingFaceM4/idefics2-8b")
+model = Idefics2ForConditionalGeneration.from_pretrained("HuggingFaceM4/idefics2-8b")
+model.to(device)
+
+text = processor.apply_chat_template(messages, add_generation_prompt=False)
+inputs = processor(images=images, text=text, return_tensors="pt").to(model.device)
+
+labels = inputs.input_ids.clone()
+labels[labels == processor.tokenizer.pad_token_id] = -100
+labels[labels == model.config.image_token_id] = -100
+
+inputs["labels"] = labels
+
+outputs = model(**inputs)
+loss = outputs.loss
+loss.backward()
+```
+
+Do note that when training Idefics2 on multi-turn conversations between a user and an assistant, one typically also sets all the tokens corresponding to the user messages to -100.
+
+## Model optimizations: Flash Attention
+
+The code snippets above showcase inference without any optimization tricks. However, one can drastically speed up the model by leveraging [Flash Attention](../perf_train_gpu_one#flash-attention-2), which is a faster implementation of the attention mechanism used inside the model.
+
+First, make sure to install the latest version of Flash Attention 2 to include the sliding window attention feature.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Make also sure that you have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of the [flash attention repository](https://github.com/Dao-AILab/flash-attention). Make also sure to load your model in half-precision (e.g. `torch.float16`)
+
+To load and run a model using Flash Attention-2, simply change the code snippet above with the following change:
+
+```diff
+model = Idefics2ForConditionalGeneration.from_pretrained(
+ "HuggingFaceM4/idefics2-8b",
++ torch_dtype=torch.float16,
++ attn_implementation="flash_attention_2",
+).to(device)
+```
+
+## Shrinking down Idefics2 using quantization
+
+As the Idefics2 model has 8 billion parameters, that would require about 16GB of GPU RAM in half precision (float16), since each parameter is stored in 2 bytes. However, one can shrink down the size of the model using [quantization](../quantization). If the model is quantized to 4 bits (or half a byte per parameter), that requires only about 3.5GB of RAM.
+
+Quantizing a model is as simple as passing a `quantization_config` to the model. One can change the code snippet above with the changes below. We'll leverage the BitsAndyBytes quantization (but refer to [this page](../quantization) for other quantization methods):
+
+```diff
++ from transformers import BitsAndBytesConfig
+
++ quantization_config = BitsAndBytesConfig(
++ load_in_4bit=True,
++ bnb_4bit_quant_type="nf4",
++ bnb_4bit_use_double_quant=True,
++ bnb_4bit_compute_dtype=torch.float16
++ )
+model = Idefics2ForConditionalGeneration.from_pretrained(
+ "HuggingFaceM4/idefics2-8b",
++ torch_dtype=torch.float16,
++ quantization_config=quantization_config,
+).to(device)
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Idefics2. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- A notebook on how to fine-tune Idefics2 on a custom dataset using the [Trainer](../main_classes/trainer) can be found [here](https://colab.research.google.com/drive/1NtcTgRbSBKN7pYD3Vdx1j9m8pt3fhFDB?usp=sharing). It supports both full fine-tuning as well as (quantized) LoRa.
+- A script regarding how to fine-tune Idefics2 using the TRL library can be found [here](https://gist.github.com/edbeeching/228652fc6c2b29a1641be5a5778223cb).
+- Demo notebook regarding fine-tuning Idefics2 for JSON extraction use cases can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Idefics2). 🌎
+
+## Idefics2Config
+
+[[autodoc]] Idefics2Config
+
+
+## Idefics2Model
+
+[[autodoc]] Idefics2Model
+ - forward
+
+
+## Idefics2ForConditionalGeneration
+
+[[autodoc]] Idefics2ForConditionalGeneration
+ - forward
+
+
+## Idefics2ImageProcessor
+[[autodoc]] Idefics2ImageProcessor
+ - preprocess
+
+## Idefics2ImageProcessorFast
+[[autodoc]] Idefics2ImageProcessorFast
+ - preprocess
+
+## Idefics2Processor
+[[autodoc]] Idefics2Processor
+ - __call__
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/idefics3.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/idefics3.md
new file mode 100644
index 0000000000000000000000000000000000000000..b3e199e2b882197d682ae2be9b0f8920747dae91
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/idefics3.md
@@ -0,0 +1,90 @@
+
+*This model was released on 2024-08-22 and added to Hugging Face Transformers on 2024-09-25.*
+
+# Idefics3
+
+
+
+
+
+
+
+## Overview
+
+The Idefics3 model was proposed in [Building and better understanding vision-language models: insights and future directions](https://huggingface.co/papers/2408.12637) by Hugo Laurençon, Andrés Marafioti, Victor Sanh, and Léo Tronchon.
+
+Idefics3 is an adaptation of the Idefics2 model with three main differences:
+
+- It uses Llama3 for the text model.
+- It uses an updated processing logic for the images.
+- It removes the perceiver.
+
+The abstract from the paper is the following:
+
+*The field of vision-language models (VLMs), which take images and texts as inputs and output texts, is rapidly evolving and has yet to reach consensus on several key aspects of the development pipeline, including data, architecture, and training methods. This paper can be seen as a tutorial for building a VLM. We begin by providing a comprehensive overview of the current state-of-the-art approaches, highlighting the strengths and weaknesses of each, addressing the major challenges in the field, and suggesting promising research directions for underexplored areas. We then walk through the practical steps to build Idefics3-8B, a powerful VLM that significantly outperforms its predecessor Idefics2-8B, while being trained efficiently, exclusively on open datasets, and using a straightforward pipeline. These steps include the creation of Docmatix, a dataset for improving document understanding capabilities, which is 240 times larger than previously available datasets. We release the model along with the datasets created for its training.*
+
+## Usage tips
+
+Input images are processed either by upsampling (if resizing is enabled) or at their original resolution. The resizing behavior depends on two parameters: do_resize and size.
+
+If `do_resize` is set to `True`, the model resizes images so that the longest edge is 4*364 pixels by default.
+The default resizing behavior can be customized by passing a dictionary to the `size` parameter. For example, `{"longest_edge": 4 * 364}` is the default, but you can change it to a different value if needed.
+
+Here’s how to control resizing and set a custom size:
+```python
+image_processor = Idefics3ImageProcessor(do_resize=True, size={"longest_edge": 2 * 364}, max_image_size=364)
+```
+
+Additionally, the `max_image_size` parameter, which controls the size of each square patch the image is decomposed into, is set to 364 by default but can be adjusted as needed. After resizing (if applicable), the image processor decomposes the images into square patches based on the `max_image_size` parameter.
+
+This model was contributed by [amyeroberts](https://huggingface.co/amyeroberts) and [andimarafioti](https://huggingface.co/andito).
+
+
+## Idefics3Config
+
+[[autodoc]] Idefics3Config
+
+## Idefics3VisionConfig
+
+[[autodoc]] Idefics3VisionConfig
+
+## Idefics3VisionTransformer
+
+[[autodoc]] Idefics3VisionTransformer
+
+## Idefics3Model
+
+[[autodoc]] Idefics3Model
+ - forward
+
+## Idefics3ForConditionalGeneration
+
+[[autodoc]] Idefics3ForConditionalGeneration
+ - forward
+
+
+## Idefics3ImageProcessor
+[[autodoc]] Idefics3ImageProcessor
+ - preprocess
+
+## Idefics3ImageProcessorFast
+[[autodoc]] Idefics3ImageProcessorFast
+ - preprocess
+
+## Idefics3Processor
+[[autodoc]] Idefics3Processor
+ - __call__
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ijepa.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ijepa.md
new file mode 100644
index 0000000000000000000000000000000000000000..a8582f19c7a28f6a3a089545327208901a98b751
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ijepa.md
@@ -0,0 +1,145 @@
+
+*This model was released on 2023-01-19 and added to Hugging Face Transformers on 2024-12-05.*
+
+
+
+
+
+
+
+
+
+# I-JEPA
+
+[I-JEPA](https://huggingface.co/papers/2301.08243) is a self-supervised learning method that learns semantic image representations by predicting parts of an image from other parts of the image. It compares the abstract representations of the image (rather than pixel level comparisons), which avoids the typical pitfalls of data augmentation bias and pixel-level details that don't capture semantic meaning.
+
+You can find the original I-JEPA checkpoints under the [AI at Meta](https://huggingface.co/facebook/models?search=ijepa) organization.
+> [!TIP]
+> This model was contributed by [jmtzt](https://huggingface.co/jmtzt).
+
+
+
+
+
+> Click on the I-JEPA models in the right sidebar for more examples of how to apply I-JEPA to different image representation and classification tasks.
+
+The example below demonstrates how to extract image features with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+feature_extractor = pipeline(
+ task="image-feature-extraction",
+ model="facebook/ijepa_vith14_1k",
+ device=0,
+ torch_dtype=torch.bfloat16
+)
+features = feature_extractor("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg", return_tensors=True)
+
+print(f"Feature shape: {features.shape}")
+
+```
+
+
+
+
+```py
+import requests
+import torch
+from PIL import Image
+from torch.nn.functional import cosine_similarity
+from transformers import AutoModel, AutoProcessor
+
+url_1 = "http://images.cocodataset.org/val2017/000000039769.jpg"
+url_2 = "http://images.cocodataset.org/val2017/000000219578.jpg"
+image_1 = Image.open(requests.get(url_1, stream=True).raw)
+image_2 = Image.open(requests.get(url_2, stream=True).raw)
+
+processor = AutoProcessor.from_pretrained("facebook/ijepa_vith14_1k")
+model = AutoModel.from_pretrained("facebook/ijepa_vith14_1k", torch_dtype="auto", attn_implementation="sdpa")
+
+
+def infer(image):
+ inputs = processor(image, return_tensors="pt")
+ outputs = model(**inputs)
+ return outputs.last_hidden_state.mean(dim=1)
+
+
+embed_1 = infer(image_1)
+embed_2 = infer(image_2)
+
+similarity = cosine_similarity(embed_1, embed_2)
+print(similarity)
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to 4-bits.
+
+```py
+import torch
+from transformers import BitsAndBytesConfig, AutoModel, AutoProcessor
+from datasets import load_dataset
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_compute_dtype=torch.bfloat16,
+ bnb_4bit_use_double_quant=True,
+)
+
+url_1 = "http://images.cocodataset.org/val2017/000000039769.jpg"
+url_2 = "http://images.cocodataset.org/val2017/000000219578.jpg"
+image_1 = Image.open(requests.get(url_1, stream=True).raw)
+image_2 = Image.open(requests.get(url_2, stream=True).raw)
+
+processor = AutoProcessor.from_pretrained("facebook/ijepa_vitg16_22k")
+model = AutoModel.from_pretrained("facebook/ijepa_vitg16_22k", quantization_config=quantization_config, torch_dtype="auto", attn_implementation="sdpa")
+
+
+def infer(image):
+ inputs = processor(image, return_tensors="pt")
+ outputs = model(**inputs)
+ return outputs.last_hidden_state.mean(dim=1)
+
+
+embed_1 = infer(image_1)
+embed_2 = infer(image_2)
+
+similarity = cosine_similarity(embed_1, embed_2)
+print(similarity)
+```
+
+## IJepaConfig
+
+[[autodoc]] IJepaConfig
+
+## IJepaModel
+
+[[autodoc]] IJepaModel
+ - forward
+
+## IJepaForImageClassification
+
+[[autodoc]] IJepaForImageClassification
+ - forward
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/imagegpt.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/imagegpt.md
new file mode 100644
index 0000000000000000000000000000000000000000..e3c5db15247ef435d1f0357c84a48e2159211315
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/imagegpt.md
@@ -0,0 +1,120 @@
+
+*This model was released on 2020-06-17 and added to Hugging Face Transformers on 2021-11-18.*
+
+# ImageGPT
+
+
+
+
+
+## Overview
+
+The ImageGPT model was proposed in [Generative Pretraining from Pixels](https://openai.com/blog/image-gpt) by Mark
+Chen, Alec Radford, Rewon Child, Jeffrey Wu, Heewoo Jun, David Luan, Ilya Sutskever. ImageGPT (iGPT) is a GPT-2-like
+model trained to predict the next pixel value, allowing for both unconditional and conditional image generation.
+
+The abstract from the [paper](https://cdn.openai.com/papers/Generative_Pretraining_from_Pixels_V1_ICML.pdf) is the following:
+
+*Inspired by progress in unsupervised representation learning for natural language, we examine whether similar models
+can learn useful representations for images. We train a sequence Transformer to auto-regressively predict pixels,
+without incorporating knowledge of the 2D input structure. Despite training on low-resolution ImageNet without labels,
+we find that a GPT-2 scale model learns strong image representations as measured by linear probing, fine-tuning, and
+low-data classification. On CIFAR-10, we achieve 96.3% accuracy with a linear probe, outperforming a supervised Wide
+ResNet, and 99.0% accuracy with full fine-tuning, matching the top supervised pre-trained models. We are also
+competitive with self-supervised benchmarks on ImageNet when substituting pixels for a VQVAE encoding, achieving 69.0%
+top-1 accuracy on a linear probe of our features.*
+
+
+
+ Summary of the approach. Taken from the [original paper](https://cdn.openai.com/papers/Generative_Pretraining_from_Pixels_V2.pdf).
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr), based on [this issue](https://github.com/openai/image-gpt/issues/7). The original code can be found
+[here](https://github.com/openai/image-gpt).
+
+## Usage tips
+
+- ImageGPT is almost exactly the same as [GPT-2](gpt2), with the exception that a different activation
+ function is used (namely "quick gelu"), and the layer normalization layers don't mean center the inputs. ImageGPT
+ also doesn't have tied input- and output embeddings.
+- As the time- and memory requirements of the attention mechanism of Transformers scales quadratically in the sequence
+ length, the authors pre-trained ImageGPT on smaller input resolutions, such as 32x32 and 64x64. However, feeding a
+ sequence of 32x32x3=3072 tokens from 0..255 into a Transformer is still prohibitively large. Therefore, the authors
+ applied k-means clustering to the (R,G,B) pixel values with k=512. This way, we only have a 32*32 = 1024-long
+ sequence, but now of integers in the range 0..511. So we are shrinking the sequence length at the cost of a bigger
+ embedding matrix. In other words, the vocabulary size of ImageGPT is 512, + 1 for a special "start of sentence" (SOS)
+ token, used at the beginning of every sequence. One can use [`ImageGPTImageProcessor`] to prepare
+ images for the model.
+- Despite being pre-trained entirely unsupervised (i.e. without the use of any labels), ImageGPT produces fairly
+ performant image features useful for downstream tasks, such as image classification. The authors showed that the
+ features in the middle of the network are the most performant, and can be used as-is to train a linear model (such as
+ a sklearn logistic regression model for example). This is also referred to as "linear probing". Features can be
+ easily obtained by first forwarding the image through the model, then specifying `output_hidden_states=True`, and
+ then average-pool the hidden states at whatever layer you like.
+- Alternatively, one can further fine-tune the entire model on a downstream dataset, similar to BERT. For this, you can
+ use [`ImageGPTForImageClassification`].
+- ImageGPT comes in different sizes: there's ImageGPT-small, ImageGPT-medium and ImageGPT-large. The authors did also
+ train an XL variant, which they didn't release. The differences in size are summarized in the following table:
+
+| **Model variant** | **Depths** | **Hidden sizes** | **Decoder hidden size** | **Params (M)** | **ImageNet-1k Top 1** |
+|---|---|---|---|---|---|
+| MiT-b0 | [2, 2, 2, 2] | [32, 64, 160, 256] | 256 | 3.7 | 70.5 |
+| MiT-b1 | [2, 2, 2, 2] | [64, 128, 320, 512] | 256 | 14.0 | 78.7 |
+| MiT-b2 | [3, 4, 6, 3] | [64, 128, 320, 512] | 768 | 25.4 | 81.6 |
+| MiT-b3 | [3, 4, 18, 3] | [64, 128, 320, 512] | 768 | 45.2 | 83.1 |
+| MiT-b4 | [3, 8, 27, 3] | [64, 128, 320, 512] | 768 | 62.6 | 83.6 |
+| MiT-b5 | [3, 6, 40, 3] | [64, 128, 320, 512] | 768 | 82.0 | 83.8 |
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with ImageGPT.
+
+
+
+- Demo notebooks for ImageGPT can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/ImageGPT).
+- [`ImageGPTForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## ImageGPTConfig
+
+[[autodoc]] ImageGPTConfig
+
+## ImageGPTFeatureExtractor
+
+[[autodoc]] ImageGPTFeatureExtractor
+ - __call__
+
+## ImageGPTImageProcessor
+
+[[autodoc]] ImageGPTImageProcessor
+ - preprocess
+
+## ImageGPTModel
+
+[[autodoc]] ImageGPTModel
+ - forward
+
+## ImageGPTForCausalImageModeling
+
+[[autodoc]] ImageGPTForCausalImageModeling
+ - forward
+
+## ImageGPTForImageClassification
+
+[[autodoc]] ImageGPTForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/informer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/informer.md
new file mode 100644
index 0000000000000000000000000000000000000000..7e79399cbc57081ea0eef8d2fa2bd16e69f9f7ff
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/informer.md
@@ -0,0 +1,55 @@
+
+*This model was released on 2020-12-14 and added to Hugging Face Transformers on 2023-03-08.*
+
+# Informer
+
+
+
+
+
+## Overview
+
+The Informer model was proposed in [Informer: Beyond Efficient Transformer for Long Sequence Time-Series Forecasting](https://huggingface.co/papers/2012.07436) by Haoyi Zhou, Shanghang Zhang, Jieqi Peng, Shuai Zhang, Jianxin Li, Hui Xiong, and Wancai Zhang.
+
+This method introduces a Probabilistic Attention mechanism to select the "active" queries rather than the "lazy" queries and provides a sparse Transformer thus mitigating the quadratic compute and memory requirements of vanilla attention.
+
+The abstract from the paper is the following:
+
+*Many real-world applications require the prediction of long sequence time-series, such as electricity consumption planning. Long sequence time-series forecasting (LSTF) demands a high prediction capacity of the model, which is the ability to capture precise long-range dependency coupling between output and input efficiently. Recent studies have shown the potential of Transformer to increase the prediction capacity. However, there are several severe issues with Transformer that prevent it from being directly applicable to LSTF, including quadratic time complexity, high memory usage, and inherent limitation of the encoder-decoder architecture. To address these issues, we design an efficient transformer-based model for LSTF, named Informer, with three distinctive characteristics: (i) a ProbSparse self-attention mechanism, which achieves O(L logL) in time complexity and memory usage, and has comparable performance on sequences' dependency alignment. (ii) the self-attention distilling highlights dominating attention by halving cascading layer input, and efficiently handles extreme long input sequences. (iii) the generative style decoder, while conceptually simple, predicts the long time-series sequences at one forward operation rather than a step-by-step way, which drastically improves the inference speed of long-sequence predictions. Extensive experiments on four large-scale datasets demonstrate that Informer significantly outperforms existing methods and provides a new solution to the LSTF problem.*
+
+This model was contributed by [elisim](https://huggingface.co/elisim) and [kashif](https://huggingface.co/kashif).
+The original code can be found [here](https://github.com/zhouhaoyi/Informer2020).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- Check out the Informer blog-post in HuggingFace blog: [Multivariate Probabilistic Time Series Forecasting with Informer](https://huggingface.co/blog/informer)
+
+## InformerConfig
+
+[[autodoc]] InformerConfig
+
+## InformerModel
+
+[[autodoc]] InformerModel
+ - forward
+
+## InformerForPrediction
+
+[[autodoc]] InformerForPrediction
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/instructblip.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/instructblip.md
new file mode 100644
index 0000000000000000000000000000000000000000..b0669f1c065f88b4715f551e4b03760e69c9d42f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/instructblip.md
@@ -0,0 +1,81 @@
+
+*This model was released on 2023-05-11 and added to Hugging Face Transformers on 2023-06-26.*
+
+# InstructBLIP
+
+
+
+
+
+## Overview
+
+The InstructBLIP model was proposed in [InstructBLIP: Towards General-purpose Vision-Language Models with Instruction Tuning](https://huggingface.co/papers/2305.06500) by Wenliang Dai, Junnan Li, Dongxu Li, Anthony Meng Huat Tiong, Junqi Zhao, Weisheng Wang, Boyang Li, Pascale Fung, Steven Hoi.
+InstructBLIP leverages the [BLIP-2](blip2) architecture for visual instruction tuning.
+
+The abstract from the paper is the following:
+
+*General-purpose language models that can solve various language-domain tasks have emerged driven by the pre-training and instruction-tuning pipeline. However, building general-purpose vision-language models is challenging due to the increased task discrepancy introduced by the additional visual input. Although vision-language pre-training has been widely studied, vision-language instruction tuning remains relatively less explored. In this paper, we conduct a systematic and comprehensive study on vision-language instruction tuning based on the pre-trained BLIP-2 models. We gather a wide variety of 26 publicly available datasets, transform them into instruction tuning format and categorize them into two clusters for held-in instruction tuning and held-out zero-shot evaluation. Additionally, we introduce instruction-aware visual feature extraction, a crucial method that enables the model to extract informative features tailored to the given instruction. The resulting InstructBLIP models achieve state-of-the-art zero-shot performance across all 13 held-out datasets, substantially outperforming BLIP-2 and the larger Flamingo. Our models also lead to state-of-the-art performance when finetuned on individual downstream tasks (e.g., 90.7% accuracy on ScienceQA IMG). Furthermore, we qualitatively demonstrate the advantages of InstructBLIP over concurrent multimodal models.*
+
+
+
+ InstructBLIP architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/salesforce/LAVIS/tree/main/projects/instructblip).
+
+## Usage tips
+
+InstructBLIP uses the same architecture as [BLIP-2](blip2) with a tiny but important difference: it also feeds the text prompt (instruction) to the Q-Former.
+
+> [!NOTE]
+> BLIP models after release v4.46 will raise warnings about adding `processor.num_query_tokens = {{num_query_tokens}}` and expand model embeddings layer to add special `` token. It is strongly recommended to add the attributes to the processor if you own the model checkpoint, or open a PR if it is not owned by you. Adding these attributes means that BLIP will add the number of query tokens required per image and expand the text with as many `` placeholders as there will be query tokens. Usually it is around 500 tokens per image, so make sure that the text is not truncated as otherwise there wil be failure when merging the embeddings.
+The attributes can be obtained from model config, as `model.config.num_query_tokens` and model embeddings expansion can be done by following [this link](https://gist.github.com/zucchini-nlp/e9f20b054fa322f84ac9311d9ab67042).
+
+## InstructBlipConfig
+
+[[autodoc]] InstructBlipConfig
+ - from_vision_qformer_text_configs
+
+## InstructBlipVisionConfig
+
+[[autodoc]] InstructBlipVisionConfig
+
+## InstructBlipQFormerConfig
+
+[[autodoc]] InstructBlipQFormerConfig
+
+## InstructBlipProcessor
+
+[[autodoc]] InstructBlipProcessor
+
+
+## InstructBlipVisionModel
+
+[[autodoc]] InstructBlipVisionModel
+ - forward
+
+## InstructBlipQFormerModel
+
+[[autodoc]] InstructBlipQFormerModel
+ - forward
+
+## InstructBlipModel
+
+[[autodoc]] InstructBlipModel
+
+## InstructBlipForConditionalGeneration
+
+[[autodoc]] InstructBlipForConditionalGeneration
+ - forward
+ - generate
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/instructblipvideo.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/instructblipvideo.md
new file mode 100644
index 0000000000000000000000000000000000000000..e34b454a12371d9903e05657a7d3623edd1b9e90
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/instructblipvideo.md
@@ -0,0 +1,91 @@
+
+*This model was released on 2023-05-11 and added to Hugging Face Transformers on 2024-06-25.*
+
+# InstructBlipVideo
+
+
+
+
+
+## Overview
+
+The InstructBLIPVideo is an extension of the models proposed in [InstructBLIP: Towards General-purpose Vision-Language Models with Instruction Tuning](https://huggingface.co/papers/2305.06500) by Wenliang Dai, Junnan Li, Dongxu Li, Anthony Meng Huat Tiong, Junqi Zhao, Weisheng Wang, Boyang Li, Pascale Fung, Steven Hoi.
+InstructBLIPVideo uses the same architecture as [InstructBLIP](instructblip) and works with the same checkpoints as [InstructBLIP](instructblip). The only difference is the ability to process videos.
+
+The abstract from the paper is the following:
+
+*General-purpose language models that can solve various language-domain tasks have emerged driven by the pre-training and instruction-tuning pipeline. However, building general-purpose vision-language models is challenging due to the increased task discrepancy introduced by the additional visual input. Although vision-language pre-training has been widely studied, vision-language instruction tuning remains relatively less explored. In this paper, we conduct a systematic and comprehensive study on vision-language instruction tuning based on the pre-trained BLIP-2 models. We gather a wide variety of 26 publicly available datasets, transform them into instruction tuning format and categorize them into two clusters for held-in instruction tuning and held-out zero-shot evaluation. Additionally, we introduce instruction-aware visual feature extraction, a crucial method that enables the model to extract informative features tailored to the given instruction. The resulting InstructBLIP models achieve state-of-the-art zero-shot performance across all 13 held-out datasets, substantially outperforming BLIP-2 and the larger Flamingo. Our models also lead to state-of-the-art performance when finetuned on individual downstream tasks (e.g., 90.7% accuracy on ScienceQA IMG). Furthermore, we qualitatively demonstrate the advantages of InstructBLIP over concurrent multimodal models.*
+
+
+
+ InstructBLIPVideo architecture. Taken from the original paper.
+
+This model was contributed by [RaushanTurganbay](https://huggingface.co/RaushanTurganbay).
+The original code can be found [here](https://github.com/salesforce/LAVIS/tree/main/projects/instructblip).
+
+## Usage tips
+
+- The model was trained by sampling 4 frames per video, so it's recommended to sample 4 frames
+
+> [!NOTE]
+> BLIP models after release v4.46 will raise warnings about adding `processor.num_query_tokens = {{num_query_tokens}}` and expand model embeddings layer to add special `` token. It is strongly recommended to add the attributes to the processor if you own the model checkpoint, or open a PR if it is not owned by you. Adding these attributes means that BLIP will add the number of query tokens required per image and expand the text with as many `` placeholders as there will be query tokens. Usually it is around 500 tokens per image, so make sure that the text is not truncated as otherwise there will be failure when merging the embeddings.
+The attributes can be obtained from model config, as `model.config.num_query_tokens` and model embeddings expansion can be done by following [this link](https://gist.github.com/zucchini-nlp/e9f20b054fa322f84ac9311d9ab67042).
+
+## InstructBlipVideoConfig
+
+[[autodoc]] InstructBlipVideoConfig
+ - from_vision_qformer_text_configs
+
+## InstructBlipVideoVisionConfig
+
+[[autodoc]] InstructBlipVideoVisionConfig
+
+## InstructBlipVideoQFormerConfig
+
+[[autodoc]] InstructBlipVideoQFormerConfig
+
+## InstructBlipVideoProcessor
+
+[[autodoc]] InstructBlipVideoProcessor
+
+
+## InstructBlipVideoVideoProcessor
+
+[[autodoc]] InstructBlipVideoVideoProcessor
+ - preprocess
+
+## InstructBlipVideoImageProcessor
+
+[[autodoc]] InstructBlipVideoImageProcessor
+ - preprocess
+
+## InstructBlipVideoVisionModel
+
+[[autodoc]] InstructBlipVideoVisionModel
+ - forward
+
+## InstructBlipVideoQFormerModel
+
+[[autodoc]] InstructBlipVideoQFormerModel
+ - forward
+
+## InstructBlipVideoModel
+[[autodoc]] InstructBlipVideoModel
+ - forward
+
+## InstructBlipVideoForConditionalGeneration
+
+[[autodoc]] InstructBlipVideoForConditionalGeneration
+ - forward
+ - generate
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/internvl.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/internvl.md
new file mode 100644
index 0000000000000000000000000000000000000000..f2d3a64fe00564ca8259c2ec5205306e0ec2b73e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/internvl.md
@@ -0,0 +1,355 @@
+
+*This model was released on 2025-04-14 and added to Hugging Face Transformers on 2025-04-18.*
+
+
+
+
+
+
+
+
+
+
+# InternVL
+
+The InternVL3 family of Visual Language Models was introduced in [InternVL3: Exploring Advanced Training and Test-Time Recipes for Open-Source Multimodal Models](https://huggingface.co/papers/2504.10479).
+
+The abstract from the paper is the following:
+
+*We introduce InternVL3, a significant advancement in the InternVL series featuring a native multimodal pre-training paradigm. Rather than adapting a text-only large language model (LLM) into a multimodal large language model (MLLM) that supports visual inputs, InternVL3 jointly acquires multimodal and linguistic capabilities from both diverse multimodal data and pure-text corpora during a single pre-training stage. This unified training paradigm effectively addresses the complexities and alignment challenges commonly encountered in conventional post-hoc training pipelines for MLLMs. To further improve performance and scalability, InternVL3 incorporates variable visual position encoding (V2PE) to support extended multimodal contexts, employs advanced post-training techniques such as supervised fine-tuning (SFT) and mixed preference optimization (MPO), and adopts test-time scaling strategies alongside an optimized training infrastructure. Extensive empirical evaluations demonstrate that InternVL3 delivers superior performance across a wide range of multi-modal tasks. In particular, InternVL3-78B achieves a score of 72.2 on the MMMU benchmark, setting a new state-of-the-art among open-source MLLMs. Its capabilities remain highly competitive with leading proprietary models, including ChatGPT-4o, Claude 3.5 Sonnet, and Gemini 2.5 Pro, while also maintaining strong pure-language proficiency. In pursuit of open-science principles, we will publicly release both the training data and model weights to foster further research and development in next-generation MLLMs.*
+
+
+
+
+ Overview of InternVL3 models architecture, which is the same as InternVL2.5. Taken from the original checkpoint.
+
+
+
+
+
+ Comparison of InternVL3 performance on OpenCompass against other SOTA VLLMs. Taken from the original checkpoint.
+
+
+
+This model was contributed by [yonigozlan](https://huggingface.co/yonigozlan).
+The original code can be found [here](https://github.com/OpenGVLab/InternVL).
+
+## Usage example
+
+### Inference with Pipeline
+
+Here is how you can use the `image-text-to-text` pipeline to perform inference with the `InternVL3` models in just a few lines of code:
+
+```python
+>>> from transformers import pipeline
+
+>>> messages = [
+... {
+... "role": "user",
+... "content": [
+... {
+... "type": "image",
+... "image": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg",
+... },
+... {"type": "text", "text": "Describe this image."},
+... ],
+... },
+... ]
+
+>>> pipe = pipeline("image-text-to-text", model="OpenGVLab/InternVL3-1B-hf")
+>>> outputs = pipe(text=messages, max_new_tokens=50, return_full_text=False)
+>>> outputs[0]["generated_text"]
+'The image showcases a vibrant scene of nature, featuring several flowers and a bee. \n\n1. **Foreground Flowers**: \n - The primary focus is on a large, pink cosmos flower with a prominent yellow center. The petals are soft and slightly r'
+```
+### Inference on a single image
+
+This example demonstrates how to perform inference on a single image with the InternVL models using chat templates.
+
+> [!NOTE]
+> Note that the model has been trained with a specific prompt format for chatting. Use `processor.apply_chat_template(my_conversation_dict)` to correctly format your prompts.
+
+```python
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText
+>>> import torch
+
+>>> model_checkpoint = "OpenGVLab/InternVL3-1B-hf"
+>>> processor = AutoProcessor.from_pretrained(model_checkpoint)
+>>> model = AutoModelForImageTextToText.from_pretrained(model_checkpoint, device_map="auto", torch_dtype=torch.bfloat16)
+
+>>> messages = [
+... {
+... "role": "user",
+... "content": [
+... {"type": "image", "url": "http://images.cocodataset.org/val2017/000000039769.jpg"},
+... {"type": "text", "text": "Please describe the image explicitly."},
+... ],
+... }
+... ]
+
+>>> inputs = processor.apply_chat_template(messages, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt").to(model.device, dtype=torch.bfloat16)
+
+>>> generate_ids = model.generate(**inputs, max_new_tokens=50)
+>>> decoded_output = processor.decode(generate_ids[0, inputs["input_ids"].shape[1] :], skip_special_tokens=True)
+
+>>> decoded_output
+'The image shows two cats lying on a pink blanket. The cat on the left is a tabby with a mix of brown, black, and white fur, and it appears to be sleeping with its head resting on the blanket. The cat on the'
+```
+
+### Text-only generation
+This example shows how to generate text using the InternVL model without providing any image input.
+
+
+```python
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText
+>>> import torch
+
+>>> model_checkpoint = "OpenGVLab/InternVL3-1B-hf"
+>>> processor = AutoProcessor.from_pretrained(model_checkpoint)
+>>> model = AutoModelForImageTextToText.from_pretrained(model_checkpoint, device_map="auto", torch_dtype=torch.bfloat16)
+
+>>> messages = [
+... {
+... "role": "user",
+... "content": [
+... {"type": "text", "text": "Write a haiku"},
+... ],
+... }
+... ]
+
+>>> inputs = processor.apply_chat_template(messages, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt").to(torch_device, dtype=torch.bfloat16)
+
+>>> generate_ids = model.generate(**inputs, max_new_tokens=50)
+>>> decoded_output = processor.decode(generate_ids[0, inputs["input_ids"].shape[1] :], skip_special_tokens=True)
+
+>>> print(decoded_output)
+"Whispers of dawn,\nSilent whispers of the night,\nNew day's light begins."
+```
+
+### Batched image and text inputs
+InternVL models also support batched image and text inputs.
+
+```python
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText
+>>> import torch
+
+>>> model_checkpoint = "OpenGVLab/InternVL3-1B-hf"
+>>> processor = AutoProcessor.from_pretrained(model_checkpoint)
+>>> model = AutoModelForImageTextToText.from_pretrained(model_checkpoint, device_map="auto", torch_dtype=torch.bfloat16)
+
+>>> messages = [
+... [
+... {
+... "role": "user",
+... "content": [
+... {"type": "image", "url": "https://llava-vl.github.io/static/images/view.jpg"},
+... {"type": "text", "text": "Write a haiku for this image"},
+... ],
+... },
+... ],
+... [
+... {
+... "role": "user",
+... "content": [
+... {"type": "image", "url": "https://www.ilankelman.org/stopsigns/australia.jpg"},
+... {"type": "text", "text": "Describe this image"},
+... ],
+... },
+... ],
+... ]
+
+
+>>> inputs = processor.apply_chat_template(messages, padding=True, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt").to(model.device, dtype=torch.bfloat16)
+
+>>> output = model.generate(**inputs, max_new_tokens=25)
+
+>>> decoded_outputs = processor.batch_decode(output, skip_special_tokens=True)
+>>> decoded_outputs
+["user\n\nWrite a haiku for this image\nassistant\nSilky lake, \nWooden pier, \nNature's peace.",
+ 'user\n\nDescribe this image\nassistant\nThe image shows a street scene with a traditional Chinese archway, known as a "Chinese Gate" or "Chinese Gate of']
+```
+
+### Batched multi-image input
+This implementation of the InternVL models supports batched text-images inputs with different number of images for each text.
+
+```python
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText
+>>> import torch
+
+>>> model_checkpoint = "OpenGVLab/InternVL3-1B-hf"
+>>> processor = AutoProcessor.from_pretrained(model_checkpoint)
+>>> model = AutoModelForImageTextToText.from_pretrained(model_checkpoint, device_map="auto", torch_dtype=torch.bfloat16)
+
+>>> messages = [
+... [
+... {
+... "role": "user",
+... "content": [
+... {"type": "image", "url": "https://llava-vl.github.io/static/images/view.jpg"},
+... {"type": "text", "text": "Write a haiku for this image"},
+... ],
+... },
+... ],
+... [
+... {
+... "role": "user",
+... "content": [
+... {"type": "image", "url": "https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg"},
+... {"type": "image", "url": "https://thumbs.dreamstime.com/b/golden-gate-bridge-san-francisco-purple-flowers-california-echium-candicans-36805947.jpg"},
+... {"type": "text", "text": "These images depict two different landmarks. Can you identify them?"},
+... ],
+... },
+... ],
+>>> ]
+
+>>> inputs = processor.apply_chat_template(messages, padding=True, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt").to(model.device, dtype=torch.bfloat16)
+
+>>> output = model.generate(**inputs, max_new_tokens=25)
+
+>>> decoded_outputs = processor.batch_decode(output, skip_special_tokens=True)
+>>> decoded_outputs
+["user\n\nWrite a haiku for this image\nassistant\nSilky lake, \nWooden pier, \nNature's peace.",
+ 'user\n\n\nThese images depict two different landmarks. Can you identify them?\nassistant\nYes, these images depict the Statue of Liberty and the Golden Gate Bridge.']
+```
+
+### Video input
+InternVL models can also handle video inputs. Here is an example of how to perform inference on a video input using chat templates.
+
+```python
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, BitsAndBytesConfig
+
+>>> model_checkpoint = "OpenGVLab/InternVL3-8B-hf"
+>>> quantization_config = BitsAndBytesConfig(load_in_4bit=True)
+>>> processor = AutoProcessor.from_pretrained(model_checkpoint)
+>>> model = AutoModelForImageTextToText.from_pretrained(model_checkpoint, quantization_config=quantization_config)
+
+>>> messages = [
+... {
+... "role": "user",
+... "content": [
+... {
+... "type": "video",
+... "url": "https://huggingface.co/datasets/hf-internal-testing/fixtures_videos/resolve/main/tennis.mp4",
+... },
+... {"type": "text", "text": "What type of shot is the man performing?"},
+... ],
+... }
+>>> ]
+>>> inputs = processor.apply_chat_template(
+... messages,
+... return_tensors="pt",
+... add_generation_prompt=True,
+... tokenize=True,
+... return_dict=True,
+... num_frames=8,
+>>> ).to(model.device, dtype=torch.float16)
+
+>>> output = model.generate(**inputs, max_new_tokens=25)
+
+>>> decoded_output = processor.decode(output[0, inputs["input_ids"].shape[1] :], skip_special_tokens=True)
+>>> decoded_output
+'The man is performing a forehand shot.'
+```
+
+### Interleaved image and video inputs
+This example showcases how to handle a batch of chat conversations with interleaved image and video inputs using chat template.
+
+```python
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, BitsAndBytesConfig
+>>> import torch
+
+>>> model_checkpoint = "OpenGVLab/InternVL3-1B-hf"
+>>> processor = AutoProcessor.from_pretrained(model_checkpoint)
+>>> model = AutoModelForImageTextToText.from_pretrained(model_checkpoint, device_map="auto", torch_dtype=torch.bfloat16)
+
+>>> messages = [
+... [
+... {
+... "role": "user",
+... "content": [
+... {"type": "image", "url": "https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg"},
+... {"type": "image", "url": "https://thumbs.dreamstime.com/b/golden-gate-bridge-san-francisco-purple-flowers-california-echium-candicans-36805947.jpg"},
+... {"type": "text", "text": "These images depict two different landmarks. Can you identify them?"},
+... ],
+... },
+... ],
+... [
+... {
+... "role": "user",
+... "content": [
+... {"type": "video", "url": "https://huggingface.co/datasets/hf-internal-testing/fixtures_videos/resolve/main/tennis.mp4"},
+... {"type": "text", "text": "What type of shot is the man performing?"},
+... ],
+... },
+... ],
+... [
+... {
+... "role": "user",
+... "content": [
+... {"type": "image", "url": "https://llava-vl.github.io/static/images/view.jpg"},
+... {"type": "text", "text": "Write a haiku for this image"},
+... ],
+... },
+... ],
+>>> ]
+>>> inputs = processor.apply_chat_template(
+... messages,
+... padding=True,
+... add_generation_prompt=True,
+... tokenize=True,
+... return_dict=True,
+... return_tensors="pt",
+>>> ).to(model.device, dtype=torch.bfloat16)
+
+>>> outputs = model.generate(**inputs, max_new_tokens=25)
+
+>>> decoded_outputs = processor.batch_decode(outputs, skip_special_tokens=True)
+>>> decoded_outputs
+['user\n\n\nThese images depict two different landmarks. Can you identify them?\nassistant\nThe images depict the Statue of Liberty and the Golden Gate Bridge.',
+ 'user\nFrame1: \nFrame2: \nFrame3: \nFrame4: \nFrame5: \nFrame6: \nFrame7: \nFrame8: \nWhat type of shot is the man performing?\nassistant\nA forehand shot',
+ "user\n\nWrite a haiku for this image\nassistant\nSilky lake, \nWooden pier, \nNature's peace."]
+```
+
+## InternVLVisionConfig
+
+[[autodoc]] InternVLVisionConfig
+
+## InternVLConfig
+
+[[autodoc]] InternVLConfig
+
+## InternVLVisionModel
+
+[[autodoc]] InternVLVisionModel
+ - forward
+
+## InternVLModel
+
+[[autodoc]] InternVLModel
+ - forward
+
+## InternVLForConditionalGeneration
+
+[[autodoc]] InternVLForConditionalGeneration
+ - forward
+
+## InternVLProcessor
+
+[[autodoc]] InternVLProcessor
+
+## InternVLVideoProcessor
+
+[[autodoc]] InternVLVideoProcessor
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/jamba.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/jamba.md
new file mode 100644
index 0000000000000000000000000000000000000000..46903a50cdf4ead95da398b35bf8acf495864ab4
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/jamba.md
@@ -0,0 +1,159 @@
+
+*This model was released on 2024-03-28 and added to Hugging Face Transformers on 2024-04-18.*
+
+
+
+
+
+
+
+
+
+# Jamba
+
+[Jamba](https://huggingface.co/papers/2403.19887) is a hybrid Transformer-Mamba mixture-of-experts (MoE) language model ranging from 52B to 398B total parameters. This model aims to combine the advantages of both model families, the performance of transformer models and the efficiency and longer context (256K tokens) of state space models (SSMs) like Mamba.
+
+Jamba's architecture features a blocks-and-layers approach that allows Jamba to successfully integrate Transformer and Mamba architectures altogether. Each Jamba block contains either an attention or a Mamba layer, followed by a multi-layer perceptron (MLP), producing an overall ratio of one Transformer layer out of every eight total layers. MoE layers are mixed in to increase model capacity.
+
+You can find all the original Jamba checkpoints under the [AI21](https://huggingface.co/ai21labs) organization.
+
+> [!TIP]
+> Click on the Jamba models in the right sidebar for more examples of how to apply Jamba to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```py
+# install optimized Mamba implementations
+# !pip install mamba-ssm causal-conv1d>=1.2.0
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="text-generation",
+ model="ai21labs/AI21-Jamba-Mini-1.6",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("Plants create energy through a process known as")
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "ai21labs/AI21-Jamba-Large-1.6",
+)
+model = AutoModelForCausalLM.from_pretrained(
+ "ai21labs/AI21-Jamba-Large-1.6",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+input_ids = tokenizer("Plants create energy through a process known as", return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+```bash
+echo -e "Plants create energy through a process known as" | transformers run --task text-generation --model ai21labs/AI21-Jamba-Mini-1.6 --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to 8-bits.
+
+```py
+import torch
+from transformers import AutoTokenizer, AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(load_in_8bit=True,
+ llm_int8_skip_modules=["mamba"])
+
+# a device map to distribute the model evenly across 8 GPUs
+device_map = {'model.embed_tokens': 0, 'model.layers.0': 0, 'model.layers.1': 0, 'model.layers.2': 0, 'model.layers.3': 0, 'model.layers.4': 0, 'model.layers.5': 0, 'model.layers.6': 0, 'model.layers.7': 0, 'model.layers.8': 0, 'model.layers.9': 1, 'model.layers.10': 1, 'model.layers.11': 1, 'model.layers.12': 1, 'model.layers.13': 1, 'model.layers.14': 1, 'model.layers.15': 1, 'model.layers.16': 1, 'model.layers.17': 1, 'model.layers.18': 2, 'model.layers.19': 2, 'model.layers.20': 2, 'model.layers.21': 2, 'model.layers.22': 2, 'model.layers.23': 2, 'model.layers.24': 2, 'model.layers.25': 2, 'model.layers.26': 2, 'model.layers.27': 3, 'model.layers.28': 3, 'model.layers.29': 3, 'model.layers.30': 3, 'model.layers.31': 3, 'model.layers.32': 3, 'model.layers.33': 3, 'model.layers.34': 3, 'model.layers.35': 3, 'model.layers.36': 4, 'model.layers.37': 4, 'model.layers.38': 4, 'model.layers.39': 4, 'model.layers.40': 4, 'model.layers.41': 4, 'model.layers.42': 4, 'model.layers.43': 4, 'model.layers.44': 4, 'model.layers.45': 5, 'model.layers.46': 5, 'model.layers.47': 5, 'model.layers.48': 5, 'model.layers.49': 5, 'model.layers.50': 5, 'model.layers.51': 5, 'model.layers.52': 5, 'model.layers.53': 5, 'model.layers.54': 6, 'model.layers.55': 6, 'model.layers.56': 6, 'model.layers.57': 6, 'model.layers.58': 6, 'model.layers.59': 6, 'model.layers.60': 6, 'model.layers.61': 6, 'model.layers.62': 6, 'model.layers.63': 7, 'model.layers.64': 7, 'model.layers.65': 7, 'model.layers.66': 7, 'model.layers.67': 7, 'model.layers.68': 7, 'model.layers.69': 7, 'model.layers.70': 7, 'model.layers.71': 7, 'model.final_layernorm': 7, 'lm_head': 7}
+model = AutoModelForCausalLM.from_pretrained("ai21labs/AI21-Jamba-Large-1.6",
+ torch_dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+ quantization_config=quantization_config,
+ device_map=device_map)
+
+tokenizer = AutoTokenizer.from_pretrained("ai21labs/AI21-Jamba-Large-1.6")
+
+messages = [
+ {"role": "system", "content": "You are an ancient oracle who speaks in cryptic but wise phrases, always hinting at deeper meanings."},
+ {"role": "user", "content": "Hello!"},
+]
+
+input_ids = tokenizer.apply_chat_template(messages, add_generation_prompt=True, return_tensors='pt').to(model.device)
+
+outputs = model.generate(input_ids, max_new_tokens=216)
+
+# Decode the output
+conversation = tokenizer.decode(outputs[0], skip_special_tokens=True)
+
+# Split the conversation to get only the assistant's response
+assistant_response = conversation.split(messages[-1]['content'])[1].strip()
+print(assistant_response)
+# Output: Seek and you shall find. The path is winding, but the journey is enlightening. What wisdom do you seek from the ancient echoes?
+```
+
+## Notes
+
+- Don't quantize the Mamba blocks to prevent model performance degradation.
+- It is not recommended to use Mamba without the optimized Mamba kernels as it results in significantly lower latencies. If you still want to use Mamba without the kernels, then set `use_mamba_kernels=False` in [`~AutoModel.from_pretrained`].
+
+ ```py
+ import torch
+ from transformers import AutoModelForCausalLM
+ model = AutoModelForCausalLM.from_pretrained("ai21labs/AI21-Jamba-1.5-Large",
+ use_mamba_kernels=False)
+ ```
+
+## JambaConfig
+
+[[autodoc]] JambaConfig
+
+
+## JambaModel
+
+[[autodoc]] JambaModel
+ - forward
+
+
+## JambaForCausalLM
+
+[[autodoc]] JambaForCausalLM
+ - forward
+
+
+## JambaForSequenceClassification
+
+[[autodoc]] transformers.JambaForSequenceClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/janus.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/janus.md
new file mode 100644
index 0000000000000000000000000000000000000000..047adb04b3a06183b4b640433553a5d30af63084
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/janus.md
@@ -0,0 +1,235 @@
+
+*This model was released on 2024-10-17 and added to Hugging Face Transformers on 2025-04-17.*
+
+# Janus
+
+## Overview
+
+The Janus Model was originally proposed in [Janus: Decoupling Visual Encoding for Unified Multimodal Understanding and Generation](https://huggingface.co/papers/2410.13848) by DeepSeek AI team and later refined in [Janus-Pro: Unified Multimodal Understanding and Generation with Data and Model Scaling](https://huggingface.co/papers/2501.17811). Janus is a vision-language model that can generate both image and text output, it can also take both images and text as input.
+
+> [!NOTE]
+> The model doesn't generate both images and text in an interleaved format. The user has to pass a parameter indicating whether to generate text or image.
+
+The abstract from the original paper is the following:
+
+*In this paper, we introduce Janus, an autoregressive framework that unifies multimodal understanding and generation. Prior research often relies on a single visual encoder for both tasks, such as Chameleon. However, due to the differing levels of information granularity required by multimodal understanding and generation, this approach can lead to suboptimal performance, particularly in multimodal understanding. To address this issue, we decouple visual encoding into separate pathways, while still leveraging a single, unified transformer architecture for processing. The decoupling not only alleviates the conflict between the visual encoder's roles in understanding and generation, but also enhances the framework's flexibility. For instance, both the multimodal understanding and generation components can independently select their most suitable encoding methods. Experiments show that Janus surpasses previous unified model and matches or exceeds the performance of task-specific models. The simplicity, high flexibility, and effectiveness of Janus make it a strong candidate for next-generation unified multimodal models.*
+
+The abstract from the aforementioned `Janus-Pro` paper, released afterwards, is the following:
+
+*In this work, we introduce Janus-Pro, an advanced version of the previous work Janus. Specifically, Janus-Pro incorporates (1) an optimized training strate (2) expanded training data, and (3) scaling to larger model size. With these improvements, Janus-Pro achieves significant advancements in both multimodal understanding and text-to-image instruction-following capabilities, while also enhancing the stability of text-to-image generation. We hope this work will inspire further exploration in the field. Code and models are publicly available.*
+
+This model was contributed by [Yaswanth Gali](https://huggingface.co/yaswanthgali) and [Hugo Silva](https://huggingface.co/hugosilva664).
+The original code can be found [here](https://github.com/deepseek-ai/Janus).
+
+## Usage Example
+
+### Single image inference
+
+Here is the example of visual understanding with a single image.
+
+> [!NOTE]
+> Note that the model has been trained with a specific prompt format for chatting. Use `processor.apply_chat_template(my_conversation_dict)` to correctly format your prompts.
+
+```python
+import torch
+from PIL import Image
+import requests
+
+from transformers import JanusForConditionalGeneration, JanusProcessor
+
+model_id = "deepseek-community/Janus-Pro-1B"
+# Prepare Input for generation.
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {'type':'image', 'url': 'http://images.cocodataset.org/val2017/000000039769.jpg'},
+ {'type':"text", "text":"What do you see in this image?."}
+ ]
+ },
+]
+
+# Set generation mode to `text` to perform text generation.
+processor = JanusProcessor.from_pretrained(model_id)
+model = JanusForConditionalGeneration.from_pretrained(model_id,
+ torch_dtype=torch.bfloat16,
+ device_map="auto")
+
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ generation_mode="text",
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device, dtype=torch.bfloat16)
+
+output = model.generate(**inputs, max_new_tokens=40,generation_mode='text',do_sample=True)
+text = processor.decode(output[0], skip_special_tokens=True)
+print(text)
+```
+
+### Multi image inference
+
+Janus can perform inference with multiple images as input, where images can belong to the same prompt or different prompts in batched inference, where the model processes many conversations in parallel. Here is how you can do it:
+
+```python
+import torch
+from PIL import Image
+import requests
+
+from transformers import JanusForConditionalGeneration, JanusProcessor
+
+model_id = "deepseek-community/Janus-Pro-1B"
+
+image_urls = [
+ "http://images.cocodataset.org/val2017/000000039769.jpg",
+ "https://www.ilankelman.org/stopsigns/australia.jpg",
+ "https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/snowman.jpg"
+]
+
+messages = [
+ [
+ {
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "What’s the difference between"},
+ {"type": "image", "url": image_urls[0]},
+ {"type": "text", "text": " and "},
+ {"type": "image", "url": image_urls[1]}
+ ]
+ }
+ ],
+ [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": image_urls[2]},
+ {"type": "text", "text": "What do you see in this image?"}
+ ]
+ }
+ ]
+]
+
+# Load model and processor
+processor = JanusProcessor.from_pretrained(model_id)
+model = JanusForConditionalGeneration.from_pretrained(
+ model_id, torch_dtype=torch.bfloat16, device_map="auto"
+)
+
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ generation_mode="text",
+ tokenize=True,
+ padding=True,
+ return_dict=True,
+ return_tensors="pt"
+).to(model.device, dtype=torch.bfloat16)
+
+# Generate response
+output = model.generate(**inputs, max_new_tokens=40, generation_mode='text', do_sample=False)
+text = processor.batch_decode(output, skip_special_tokens=True)
+print(text)
+```
+
+## Text to Image generation
+
+Janus can also generate images given a prompt.
+
+```python
+import torch
+from transformers import JanusForConditionalGeneration, JanusProcessor
+
+# Set generation mode to `image` to prepare inputs for image generation..
+
+model_id = "deepseek-community/Janus-Pro-1B"
+processor = JanusProcessor.from_pretrained(model_id)
+model = JanusForConditionalGeneration.from_pretrained(model_id,
+ torch_dtype=torch.bfloat16,
+ device_map="auto")
+
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "A dog running under the rain."},
+ ],
+ }
+]
+
+prompt = processor.apply_chat_template(messages, add_generation_prompt=True)
+inputs = processor(text=prompt,generation_mode="image",return_tensors="pt").to(model.device, dtype=torch.bfloat16)
+
+# Set num_return_sequence parameter to generate multiple images per prompt.
+model.generation_config.num_return_sequences = 2
+outputs = model.generate(**inputs,
+ generation_mode="image",
+ do_sample=True,
+ use_cache=True,
+ )
+# Perform post-processing on the generated token ids.
+decoded_image = model.decode_image_tokens(outputs)
+images = processor.postprocess(list(decoded_image.float()),return_tensors="PIL.Image.Image")
+# Save the image
+for i, image in enumerate(images['pixel_values']):
+ image.save(f"result{i}.png")
+```
+
+## JanusConfig
+
+[[autodoc]] JanusConfig
+
+## JanusVisionConfig
+
+[[autodoc]] JanusVisionConfig
+
+## JanusVQVAEConfig
+
+[[autodoc]] JanusVQVAEConfig
+
+## JanusProcessor
+
+[[autodoc]] JanusProcessor
+
+## JanusImageProcessor
+
+[[autodoc]] JanusImageProcessor
+
+## JanusImageProcessorFast
+
+[[autodoc]] JanusImageProcessorFast
+
+## JanusVisionModel
+
+[[autodoc]] JanusVisionModel
+ - forward
+
+## JanusVQVAE
+
+[[autodoc]] JanusVQVAE
+ - forward
+
+## JanusModel
+
+[[autodoc]] JanusModel
+ - forward
+
+## JanusForConditionalGeneration
+
+[[autodoc]] JanusForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/jetmoe.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/jetmoe.md
new file mode 100644
index 0000000000000000000000000000000000000000..059fb956ce2382d08ff5ff80a7a5db29666c686b
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/jetmoe.md
@@ -0,0 +1,56 @@
+
+*This model was released on 2023-06-07 and added to Hugging Face Transformers on 2024-05-14.*
+
+# JetMoe
+
+
+
+
+
+
+
+## Overview
+
+**JetMoe-8B** is an 8B Mixture-of-Experts (MoE) language model developed by [Yikang Shen](https://scholar.google.com.hk/citations?user=qff5rRYAAAAJ) and [MyShell](https://myshell.ai/).
+JetMoe project aims to provide a LLaMA2-level performance and efficient language model with a limited budget.
+To achieve this goal, JetMoe uses a sparsely activated architecture inspired by the [ModuleFormer](https://huggingface.co/papers/2306.04640).
+Each JetMoe block consists of two MoE layers: Mixture of Attention Heads and Mixture of MLP Experts.
+Given the input tokens, it activates a subset of its experts to process them.
+This sparse activation schema enables JetMoe to achieve much better training throughput than similar size dense models.
+The training throughput of JetMoe-8B is around 100B tokens per day on a cluster of 96 H100 GPUs with a straightforward 3-way pipeline parallelism strategy.
+
+This model was contributed by [Yikang Shen](https://huggingface.co/YikangS).
+
+
+## JetMoeConfig
+
+[[autodoc]] JetMoeConfig
+
+## JetMoeModel
+
+[[autodoc]] JetMoeModel
+ - forward
+
+## JetMoeForCausalLM
+
+[[autodoc]] JetMoeForCausalLM
+ - forward
+
+## JetMoeForSequenceClassification
+
+[[autodoc]] JetMoeForSequenceClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/jukebox.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/jukebox.md
new file mode 100644
index 0000000000000000000000000000000000000000..385eeb560e506d01779a20582e52a9944e4f67c3
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/jukebox.md
@@ -0,0 +1,98 @@
+
+*This model was released on 2020-04-30 and added to Hugging Face Transformers on 2023-06-20.*
+# Jukebox
+
+
+
+
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The Jukebox model was proposed in [Jukebox: A generative model for music](https://huggingface.co/papers/2005.00341)
+by Prafulla Dhariwal, Heewoo Jun, Christine Payne, Jong Wook Kim, Alec Radford,
+Ilya Sutskever. It introduces a generative music model which can produce minute long samples that can be conditioned on
+an artist, genres and lyrics.
+
+The abstract from the paper is the following:
+
+*We introduce Jukebox, a model that generates music with singing in the raw audio domain. We tackle the long context of raw audio using a multiscale VQ-VAE to compress it to discrete codes, and modeling those using autoregressive Transformers. We show that the combined model at scale can generate high-fidelity and diverse songs with coherence up to multiple minutes. We can condition on artist and genre to steer the musical and vocal style, and on unaligned lyrics to make the singing more controllable. We are releasing thousands of non cherry-picked samples, along with model weights and code.*
+
+As shown on the following figure, Jukebox is made of 3 `priors` which are decoder only models. They follow the architecture described in [Generating Long Sequences with Sparse Transformers](https://huggingface.co/papers/1904.10509), modified to support longer context length.
+First, a autoencoder is used to encode the text lyrics. Next, the first (also called `top_prior`) prior attends to the last hidden states extracted from the lyrics encoder. The priors are linked to the previous priors respectively via an `AudioConditioner` module. The`AudioConditioner` upsamples the outputs of the previous prior to raw tokens at a certain audio frame per second resolution.
+The metadata such as *artist, genre and timing* are passed to each prior, in the form of a start token and positional embedding for the timing data. The hidden states are mapped to the closest codebook vector from the VQVAE in order to convert them to raw audio.
+
+
+
+This model was contributed by [Arthur Zucker](https://huggingface.co/ArthurZ).
+The original code can be found [here](https://github.com/openai/jukebox).
+
+## Usage tips
+
+- This model only supports inference. This is for a few reasons, mostly because it requires a crazy amount of memory to train. Feel free to open a PR and add what's missing to have a full integration with the hugging face trainer!
+- This model is very slow, and takes 8h to generate a minute long audio using the 5b top prior on a V100 GPU. In order automaticallay handle the device on which the model should execute, use `accelerate`.
+- Contrary to the paper, the order of the priors goes from `0` to `1` as it felt more intuitive : we sample starting from `0`.
+- Primed sampling (conditioning the sampling on raw audio) requires more memory than ancestral sampling and should be used with `fp16` set to `True`.
+
+This model was contributed by [Arthur Zucker](https://huggingface.co/ArthurZ).
+The original code can be found [here](https://github.com/openai/jukebox).
+
+## JukeboxConfig
+
+[[autodoc]] JukeboxConfig
+
+## JukeboxPriorConfig
+
+[[autodoc]] JukeboxPriorConfig
+
+## JukeboxVQVAEConfig
+
+[[autodoc]] JukeboxVQVAEConfig
+
+## JukeboxTokenizer
+
+[[autodoc]] JukeboxTokenizer
+ - save_vocabulary
+
+## JukeboxModel
+
+[[autodoc]] JukeboxModel
+ - ancestral_sample
+ - primed_sample
+ - continue_sample
+ - upsample
+ - _sample
+
+## JukeboxPrior
+
+[[autodoc]] JukeboxPrior
+ - sample
+ - forward
+
+## JukeboxVQVAE
+
+[[autodoc]] JukeboxVQVAE
+ - forward
+ - encode
+ - decode
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/kosmos-2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/kosmos-2.md
new file mode 100644
index 0000000000000000000000000000000000000000..c449dfd71ad18d1ae624748e55886bd8d5c1f224
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/kosmos-2.md
@@ -0,0 +1,103 @@
+
+*This model was released on 2023-06-26 and added to Hugging Face Transformers on 2023-10-30.*
+
+# KOSMOS-2
+
+
+
+
+
+## Overview
+
+The KOSMOS-2 model was proposed in [Kosmos-2: Grounding Multimodal Large Language Models to the World](https://huggingface.co/papers/2306.14824) by Zhiliang Peng, Wenhui Wang, Li Dong, Yaru Hao, Shaohan Huang, Shuming Ma, Furu Wei.
+
+KOSMOS-2 is a Transformer-based causal language model and is trained using the next-word prediction task on a web-scale
+dataset of grounded image-text pairs [GRIT](https://huggingface.co/datasets/zzliang/GRIT). The spatial coordinates of
+the bounding boxes in the dataset are converted to a sequence of location tokens, which are appended to their respective
+entity text spans (for example, `a snowman` followed by ``). The data format is
+similar to “hyperlinks” that connect the object regions in an image to their text span in the corresponding caption.
+
+The abstract from the paper is the following:
+
+*We introduce Kosmos-2, a Multimodal Large Language Model (MLLM), enabling new capabilities of perceiving object descriptions (e.g., bounding boxes) and grounding text to the visual world. Specifically, we represent refer expressions as links in Markdown, i.e., ``[text span](bounding boxes)'', where object descriptions are sequences of location tokens. Together with multimodal corpora, we construct large-scale data of grounded image-text pairs (called GrIT) to train the model. In addition to the existing capabilities of MLLMs (e.g., perceiving general modalities, following instructions, and performing in-context learning), Kosmos-2 integrates the grounding capability into downstream applications. We evaluate Kosmos-2 on a wide range of tasks, including (i) multimodal grounding, such as referring expression comprehension, and phrase grounding, (ii) multimodal referring, such as referring expression generation, (iii) perception-language tasks, and (iv) language understanding and generation. This work lays out the foundation for the development of Embodiment AI and sheds light on the big convergence of language, multimodal perception, action, and world modeling, which is a key step toward artificial general intelligence. Code and pretrained models are available at https://aka.ms/kosmos-2.*
+
+
+
+ Overview of tasks that KOSMOS-2 can handle. Taken from the original paper.
+
+## Example
+
+```python
+>>> from PIL import Image
+>>> import requests
+>>> from transformers import AutoProcessor, Kosmos2ForConditionalGeneration
+
+>>> model = Kosmos2ForConditionalGeneration.from_pretrained("microsoft/kosmos-2-patch14-224")
+>>> processor = AutoProcessor.from_pretrained("microsoft/kosmos-2-patch14-224")
+
+>>> url = "https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/snowman.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> prompt = " An image of"
+
+>>> inputs = processor(text=prompt, images=image, return_tensors="pt")
+
+>>> generated_ids = model.generate(
+... pixel_values=inputs["pixel_values"],
+... input_ids=inputs["input_ids"],
+... attention_mask=inputs["attention_mask"],
+... image_embeds=None,
+... image_embeds_position_mask=inputs["image_embeds_position_mask"],
+... use_cache=True,
+... max_new_tokens=64,
+... )
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+>>> processed_text = processor.post_process_generation(generated_text, cleanup_and_extract=False)
+>>> processed_text
+' An image of a snowman warming himself by a fire.'
+
+>>> caption, entities = processor.post_process_generation(generated_text)
+>>> caption
+'An image of a snowman warming himself by a fire.'
+
+>>> entities
+[('a snowman', (12, 21), [(0.390625, 0.046875, 0.984375, 0.828125)]), ('a fire', (41, 47), [(0.171875, 0.015625, 0.484375, 0.890625)])]
+```
+
+This model was contributed by [Yih-Dar SHIEH](https://huggingface.co/ydshieh). The original code can be found [here](https://github.com/microsoft/unilm/tree/master/kosmos-2).
+
+## Kosmos2Config
+
+[[autodoc]] Kosmos2Config
+
+## Kosmos2ImageProcessor
+
+## Kosmos2Processor
+
+[[autodoc]] Kosmos2Processor
+ - __call__
+
+## Kosmos2Model
+
+[[autodoc]] Kosmos2Model
+ - forward
+
+## Kosmos2ForConditionalGeneration
+
+[[autodoc]] Kosmos2ForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/kosmos2_5.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/kosmos2_5.md
new file mode 100644
index 0000000000000000000000000000000000000000..d881bf61678c8350f4edf7926d5ccecaf64029a3
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/kosmos2_5.md
@@ -0,0 +1,196 @@
+
+
+
+
+
+
+
+
+
+
+
+
+# KOSMOS-2.5
+
+The Kosmos-2.5 model was proposed in [KOSMOS-2.5: A Multimodal Literate Model](https://arxiv.org/abs/2309.11419/) by Microsoft.
+
+The abstract from the paper is the following:
+
+*We present Kosmos-2.5, a multimodal literate model for machine reading of text-intensive images. Pre-trained on large-scale text-intensive images, Kosmos-2.5 excels in two distinct yet cooperative transcription tasks: (1) generating spatially-aware text blocks, where each block of text is assigned its spatial coordinates within the image, and (2) producing structured text output that captures styles and structures into the markdown format. This unified multimodal literate capability is achieved through a shared Transformer architecture, task-specific prompts, and flexible text representations. We evaluate Kosmos-2.5 on end-to-end document-level text recognition and image-to-markdown text generation. Furthermore, the model can be readily adapted for any text-intensive image understanding task with different prompts through supervised fine-tuning, making it a general-purpose tool for real-world applications involving text-rich images. This work also paves the way for the future scaling of multimodal large language models.*
+
+
+
+
+
+ Overview of tasks that KOSMOS-2.5 can handle. Taken from the original paper.
+
+The examples below demonstrates how to generate with [`AutoModel`], for both Markdown and OCR tasks.
+
+
+
+
+```py
+import re
+import torch
+import requests
+from PIL import Image, ImageDraw
+from transformers import AutoProcessor, Kosmos2_5ForConditionalGeneration
+
+repo = "ydshieh/kosmos-2.5"
+device = "cuda:0"
+dtype = torch.bfloat16
+model = Kosmos2_5ForConditionalGeneration.from_pretrained(repo, device_map=device, torch_dtype=dtype)
+processor = AutoProcessor.from_pretrained(repo)
+
+# sample image
+url = "https://huggingface.co/ydshieh/kosmos-2.5/resolve/main/receipt_00008.png"
+image = Image.open(requests.get(url, stream=True).raw)
+
+prompt = ""
+inputs = processor(text=prompt, images=image, return_tensors="pt")
+
+height, width = inputs.pop("height"), inputs.pop("width")
+raw_width, raw_height = image.size
+scale_height = raw_height / height
+scale_width = raw_width / width
+
+inputs = {k: v.to(device) if v is not None else None for k, v in inputs.items()}
+inputs["flattened_patches"] = inputs["flattened_patches"].to(dtype)
+generated_ids = model.generate(
+ **inputs,
+ max_new_tokens=1024,
+)
+
+generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+print(generated_text[0])
+```
+
+
+
+
+```py
+import re
+import torch
+import requests
+from PIL import Image, ImageDraw
+from transformers import AutoProcessor, Kosmos2_5ForConditionalGeneration
+
+repo = "ydshieh/kosmos-2.5"
+device = "cuda:0"
+dtype = torch.bfloat16
+model = Kosmos2_5ForConditionalGeneration.from_pretrained(repo, device_map=device, torch_dtype=dtype)
+processor = AutoProcessor.from_pretrained(repo)
+
+# sample image
+url = "https://huggingface.co/ydshieh/kosmos-2.5/resolve/main/receipt_00008.png"
+image = Image.open(requests.get(url, stream=True).raw)
+
+# bs = 1
+prompt = ""
+inputs = processor(text=prompt, images=image, return_tensors="pt")
+height, width = inputs.pop("height"), inputs.pop("width")
+raw_width, raw_height = image.size
+scale_height = raw_height / height
+scale_width = raw_width / width
+
+# bs > 1, batch generation
+# inputs = processor(text=[prompt, prompt], images=[image,image], return_tensors="pt")
+# height, width = inputs.pop("height"), inputs.pop("width")
+# raw_width, raw_height = image.size
+# scale_height = raw_height / height[0]
+# scale_width = raw_width / width[0]
+
+inputs = {k: v.to(device) if v is not None else None for k, v in inputs.items()}
+inputs["flattened_patches"] = inputs["flattened_patches"].to(dtype)
+generated_ids = model.generate(
+ **inputs,
+ max_new_tokens=1024,
+)
+
+generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+def post_process(y, scale_height, scale_width):
+ y = y.replace(prompt, "")
+ if "" in prompt:
+ return y
+ pattern = r""
+ bboxs_raw = re.findall(pattern, y)
+ lines = re.split(pattern, y)[1:]
+ bboxs = [re.findall(r"\d+", i) for i in bboxs_raw]
+ bboxs = [[int(j) for j in i] for i in bboxs]
+ info = ""
+ for i in range(len(lines)):
+ box = bboxs[i]
+ x0, y0, x1, y1 = box
+ if not (x0 >= x1 or y0 >= y1):
+ x0 = int(x0 * scale_width)
+ y0 = int(y0 * scale_height)
+ x1 = int(x1 * scale_width)
+ y1 = int(y1 * scale_height)
+ info += f"{x0},{y0},{x1},{y0},{x1},{y1},{x0},{y1},{lines[i]}"
+ return info
+
+output_text = post_process(generated_text[0], scale_height, scale_width)
+print(output_text)
+
+draw = ImageDraw.Draw(image)
+lines = output_text.split("\n")
+for line in lines:
+ # draw the bounding box
+ line = list(line.split(","))
+ if len(line) < 8:
+ continue
+ line = list(map(int, line[:8]))
+ draw.polygon(line, outline="red")
+image.save("output.png")
+```
+
+
+
+
+
+## Example
+**Markdown Task:** For usage instructions, please refer to [md.py](https://huggingface.co/ydshieh/kosmos-2.5/blob/main/md.py).
+
+**OCR Task:** For usage instructions, please refer to [ocr.py](https://huggingface.co/ydshieh/kosmos-2.5/blob/main/ocr.py).
+
+
+
+## Kosmos2_5Config
+
+[[autodoc]] Kosmos2_5Config
+
+## Kosmos2_5ImageProcessor
+
+[[autodoc]] Kosmos2_5ImageProcessor
+ - preprocess
+
+## Kosmos2_5ImageProcessorFast
+
+[[autodoc]] Kosmos2_5ImageProcessorFast
+ - preprocess
+
+## Kosmos2_5Processor
+
+[[autodoc]] Kosmos2_5Processor
+
+## Kosmos2_5Model
+
+[[autodoc]] Kosmos2_5Model
+ - forward
+
+## Kosmos2_5ForConditionalGeneration
+
+[[autodoc]] Kosmos2_5ForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/kyutai_speech_to_text.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/kyutai_speech_to_text.md
new file mode 100644
index 0000000000000000000000000000000000000000..0d9b45ba9380f4b6c9fad7497ff6cc30430598ee
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/kyutai_speech_to_text.md
@@ -0,0 +1,123 @@
+
+*This model was released on 2025-06-17 and added to Hugging Face Transformers on 2025-06-25.*
+
+# Kyutai Speech-To-Text
+## Overview
+
+[Kyutai STT](https://kyutai.org/next/stt) is a speech-to-text model architecture based on the [Mimi codec](https://huggingface.co/docs/transformers/en/model_doc/mimi), which encodes audio into discrete tokens in a streaming fashion, and a [Moshi-like](https://huggingface.co/docs/transformers/en/model_doc/moshi) autoregressive decoder. Kyutai’s lab has released two model checkpoints:
+- [kyutai/stt-1b-en_fr](https://huggingface.co/kyutai/stt-1b-en_fr): a 1B-parameter model capable of transcribing both English and French
+- [kyutai/stt-2.6b-en](https://huggingface.co/kyutai/stt-2.6b-en): a 2.6B-parameter model focused solely on English, optimized for maximum transcription accuracy
+
+
+
+
+
+## Usage Tips
+
+### Inference
+
+```python
+import torch
+from datasets import load_dataset, Audio
+from transformers import infer_device, KyutaiSpeechToTextProcessor, KyutaiSpeechToTextForConditionalGeneration
+
+# 1. load the model and the processor
+torch_device = infer_device()
+model_id = "kyutai/stt-2.6b-en-trfs"
+
+processor = KyutaiSpeechToTextProcessor.from_pretrained(model_id)
+model = KyutaiSpeechToTextForConditionalGeneration.from_pretrained(model_id, device_map=torch_device, torch_dtype="auto")
+
+# 2. load audio samples
+ds = load_dataset(
+ "hf-internal-testing/librispeech_asr_dummy", "clean", split="validation"
+)
+ds = ds.cast_column("audio", Audio(sampling_rate=24000))
+
+# 3. prepare the model inputs
+inputs = processor(
+ ds[0]["audio"]["array"],
+)
+inputs.to(model.device)
+
+# 4. infer the model
+output_tokens = model.generate(**inputs)
+
+# 5. decode the generated tokens
+print(processor.batch_decode(output_tokens, skip_special_tokens=True))
+```
+
+### Batched Inference
+
+```python
+import torch
+from datasets import load_dataset, Audio
+from transformers import infer_device, KyutaiSpeechToTextProcessor, KyutaiSpeechToTextForConditionalGeneration
+
+# 1. load the model and the processor
+torch_device = infer_device()
+model_id = "kyutai/stt-2.6b-en-trfs"
+
+processor = KyutaiSpeechToTextProcessor.from_pretrained(model_id)
+model = KyutaiSpeechToTextForConditionalGeneration.from_pretrained(model_id, device_map=torch_device, torch_dtype="auto")
+
+# 2. load audio samples
+ds = load_dataset(
+ "hf-internal-testing/librispeech_asr_dummy", "clean", split="validation"
+)
+ds = ds.cast_column("audio", Audio(sampling_rate=24000))
+
+# 3. prepare the model inputs
+audio_arrays = [ds[i]["audio"]["array"] for i in range(4)]
+inputs = processor(audio_arrays, return_tensors="pt", padding=True)
+inputs = inputs.to(model.device)
+
+# 4. infer the model
+output_tokens = model.generate(**inputs)
+
+# 5. decode the generated tokens
+decoded_outputs = processor.batch_decode(output_tokens, skip_special_tokens=True)
+for output in decoded_outputs:
+ print(output)
+```
+
+This model was contributed by [Eustache Le Bihan](https://huggingface.co/eustlb).
+The original code can be found [here](https://github.com/kyutai-labs/moshi).
+
+
+## KyutaiSpeechToTextConfig
+
+[[autodoc]] KyutaiSpeechToTextConfig
+
+## KyutaiSpeechToTextProcessor
+
+[[autodoc]] KyutaiSpeechToTextProcessor
+ - __call__
+
+## KyutaiSpeechToTextFeatureExtractor
+
+[[autodoc]] KyutaiSpeechToTextFeatureExtractor
+
+## KyutaiSpeechToTextForConditionalGeneration
+
+[[autodoc]] KyutaiSpeechToTextForConditionalGeneration
+ - forward
+ - generate
+
+## KyutaiSpeechToTextModel
+
+[[autodoc]] KyutaiSpeechToTextModel
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/layoutlm.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/layoutlm.md
new file mode 100644
index 0000000000000000000000000000000000000000..6fc4f0f2f056c942b37209502c450b9e7e738c6a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/layoutlm.md
@@ -0,0 +1,182 @@
+
+*This model was released on 2019-12-31 and added to Hugging Face Transformers on 2020-11-16.*
+
+
+
+
+
+
+
+
+# LayoutLM
+
+[LayoutLM](https://huggingface.co/papers/1912.13318) jointly learns text and the document layout rather than focusing only on text. It incorporates positional layout information and visual features of words from the document images.
+
+You can find all the original LayoutLM checkpoints under the [LayoutLM](https://huggingface.co/collections/microsoft/layoutlm-6564539601de72cb631d0902) collection.
+
+> [!TIP]
+> Click on the LayoutLM models in the right sidebar for more examples of how to apply LayoutLM to different vision and language tasks.
+
+The example below demonstrates question answering with the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from datasets import load_dataset
+from transformers import AutoTokenizer, LayoutLMForQuestionAnswering
+
+tokenizer = AutoTokenizer.from_pretrained("impira/layoutlm-document-qa", add_prefix_space=True)
+model = LayoutLMForQuestionAnswering.from_pretrained("impira/layoutlm-document-qa", torch_dtype=torch.float16)
+
+dataset = load_dataset("nielsr/funsd", split="train")
+example = dataset[0]
+question = "what's his name?"
+words = example["words"]
+boxes = example["bboxes"]
+
+encoding = tokenizer(
+ question.split(),
+ words,
+ is_split_into_words=True,
+ return_token_type_ids=True,
+ return_tensors="pt"
+)
+bbox = []
+for i, s, w in zip(encoding.input_ids[0], encoding.sequence_ids(0), encoding.word_ids(0)):
+ if s == 1:
+ bbox.append(boxes[w])
+ elif i == tokenizer.sep_token_id:
+ bbox.append([1000] * 4)
+ else:
+ bbox.append([0] * 4)
+encoding["bbox"] = torch.tensor([bbox])
+
+word_ids = encoding.word_ids(0)
+outputs = model(**encoding)
+loss = outputs.loss
+start_scores = outputs.start_logits
+end_scores = outputs.end_logits
+start, end = word_ids[start_scores.argmax(-1)], word_ids[end_scores.argmax(-1)]
+print(" ".join(words[start : end + 1]))
+```
+
+
+
+
+## Notes
+
+- The original LayoutLM was not designed with a unified processing workflow. Instead, it expects preprocessed text (`words`) and bounding boxes (`boxes`) from an external OCR engine (like [Pytesseract](https://pypi.org/project/pytesseract/)) and provide them as additional inputs to the tokenizer.
+
+- The [`~LayoutLMModel.forward`] method expects the input `bbox` (bounding boxes of the input tokens). Each bounding box should be in the format `(x0, y0, x1, y1)`. `(x0, y0)` corresponds to the upper left corner of the bounding box and `{x1, y1)` corresponds to the lower right corner. The bounding boxes need to be normalized on a 0-1000 scale as shown below.
+
+```python
+def normalize_bbox(bbox, width, height):
+ return [
+ int(1000 * (bbox[0] / width)),
+ int(1000 * (bbox[1] / height)),
+ int(1000 * (bbox[2] / width)),
+ int(1000 * (bbox[3] / height)),
+ ]
+```
+
+- `width` and `height` correspond to the width and height of the original document in which the token occurs. These values can be obtained as shown below.
+
+```python
+from PIL import Image
+
+# Document can be a png, jpg, etc. PDFs must be converted to images.
+image = Image.open(name_of_your_document).convert("RGB")
+
+width, height = image.size
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LayoutLM. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- Read [fine-tuning LayoutLM for document-understanding using Keras & Hugging Face Transformers](https://www.philschmid.de/fine-tuning-layoutlm-keras) to learn more.
+- Read [fine-tune LayoutLM for document-understanding using only Hugging Face Transformers](https://www.philschmid.de/fine-tuning-layoutlm) for more information.
+- Refer to this [notebook](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Add_image_embeddings_to_LayoutLM.ipynb) for a practical example of how to fine-tune LayoutLM.
+- Refer to this [notebook](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForSequenceClassification_on_RVL_CDIP.ipynb) for an example of how to fine-tune LayoutLM for sequence classification.
+- Refer to this [notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LayoutLM/Fine_tuning_LayoutLMForTokenClassification_on_FUNSD.ipynb) for an example of how to fine-tune LayoutLM for token classification.
+- Read [Deploy LayoutLM with Hugging Face Inference Endpoints](https://www.philschmid.de/inference-endpoints-layoutlm) to learn how to deploy LayoutLM.
+
+
+## LayoutLMConfig
+
+[[autodoc]] LayoutLMConfig
+
+## LayoutLMTokenizer
+
+[[autodoc]] LayoutLMTokenizer
+ - __call__
+
+## LayoutLMTokenizerFast
+
+[[autodoc]] LayoutLMTokenizerFast
+ - __call__
+
+
+
+
+## LayoutLMModel
+
+[[autodoc]] LayoutLMModel
+
+## LayoutLMForMaskedLM
+
+[[autodoc]] LayoutLMForMaskedLM
+
+## LayoutLMForSequenceClassification
+
+[[autodoc]] LayoutLMForSequenceClassification
+
+## LayoutLMForTokenClassification
+
+[[autodoc]] LayoutLMForTokenClassification
+
+## LayoutLMForQuestionAnswering
+
+[[autodoc]] LayoutLMForQuestionAnswering
+
+
+
+
+## TFLayoutLMModel
+
+[[autodoc]] TFLayoutLMModel
+
+## TFLayoutLMForMaskedLM
+
+[[autodoc]] TFLayoutLMForMaskedLM
+
+## TFLayoutLMForSequenceClassification
+
+[[autodoc]] TFLayoutLMForSequenceClassification
+
+## TFLayoutLMForTokenClassification
+
+[[autodoc]] TFLayoutLMForTokenClassification
+
+## TFLayoutLMForQuestionAnswering
+
+[[autodoc]] TFLayoutLMForQuestionAnswering
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/layoutlmv2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/layoutlmv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..c376c04ad76e2137f7f13e5d8d7a20729f22e8ab
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/layoutlmv2.md
@@ -0,0 +1,350 @@
+
+*This model was released on 2020-12-29 and added to Hugging Face Transformers on 2021-08-30.*
+
+# LayoutLMV2
+
+
+
+
+
+## Overview
+
+The LayoutLMV2 model was proposed in [LayoutLMv2: Multi-modal Pre-training for Visually-Rich Document Understanding](https://huggingface.co/papers/2012.14740) by Yang Xu, Yiheng Xu, Tengchao Lv, Lei Cui, Furu Wei, Guoxin Wang, Yijuan Lu,
+Dinei Florencio, Cha Zhang, Wanxiang Che, Min Zhang, Lidong Zhou. LayoutLMV2 improves [LayoutLM](layoutlm) to obtain
+state-of-the-art results across several document image understanding benchmarks:
+
+- information extraction from scanned documents: the [FUNSD](https://guillaumejaume.github.io/FUNSD/) dataset (a
+ collection of 199 annotated forms comprising more than 30,000 words), the [CORD](https://github.com/clovaai/cord)
+ dataset (a collection of 800 receipts for training, 100 for validation and 100 for testing), the [SROIE](https://rrc.cvc.uab.es/?ch=13) dataset (a collection of 626 receipts for training and 347 receipts for testing)
+ and the [Kleister-NDA](https://github.com/applicaai/kleister-nda) dataset (a collection of non-disclosure
+ agreements from the EDGAR database, including 254 documents for training, 83 documents for validation, and 203
+ documents for testing).
+- document image classification: the [RVL-CDIP](https://www.cs.cmu.edu/~aharley/rvl-cdip/) dataset (a collection of
+ 400,000 images belonging to one of 16 classes).
+- document visual question answering: the [DocVQA](https://huggingface.co/papers/2007.00398) dataset (a collection of 50,000
+ questions defined on 12,000+ document images).
+
+The abstract from the paper is the following:
+
+*Pre-training of text and layout has proved effective in a variety of visually-rich document understanding tasks due to
+its effective model architecture and the advantage of large-scale unlabeled scanned/digital-born documents. In this
+paper, we present LayoutLMv2 by pre-training text, layout and image in a multi-modal framework, where new model
+architectures and pre-training tasks are leveraged. Specifically, LayoutLMv2 not only uses the existing masked
+visual-language modeling task but also the new text-image alignment and text-image matching tasks in the pre-training
+stage, where cross-modality interaction is better learned. Meanwhile, it also integrates a spatial-aware self-attention
+mechanism into the Transformer architecture, so that the model can fully understand the relative positional
+relationship among different text blocks. Experiment results show that LayoutLMv2 outperforms strong baselines and
+achieves new state-of-the-art results on a wide variety of downstream visually-rich document understanding tasks,
+including FUNSD (0.7895 -> 0.8420), CORD (0.9493 -> 0.9601), SROIE (0.9524 -> 0.9781), Kleister-NDA (0.834 -> 0.852),
+RVL-CDIP (0.9443 -> 0.9564), and DocVQA (0.7295 -> 0.8672). The pre-trained LayoutLMv2 model is publicly available at
+this https URL.*
+
+LayoutLMv2 depends on `detectron2`, `torchvision` and `tesseract`. Run the
+following to install them:
+```bash
+python -m pip install 'git+https://github.com/facebookresearch/detectron2.git'
+python -m pip install torchvision tesseract
+```
+(If you are developing for LayoutLMv2, note that passing the doctests also requires the installation of these packages.)
+
+## Usage tips
+
+- The main difference between LayoutLMv1 and LayoutLMv2 is that the latter incorporates visual embeddings during
+ pre-training (while LayoutLMv1 only adds visual embeddings during fine-tuning).
+- LayoutLMv2 adds both a relative 1D attention bias as well as a spatial 2D attention bias to the attention scores in
+ the self-attention layers. Details can be found on page 5 of the [paper](https://huggingface.co/papers/2012.14740).
+- Demo notebooks on how to use the LayoutLMv2 model on RVL-CDIP, FUNSD, DocVQA, CORD can be found [here](https://github.com/NielsRogge/Transformers-Tutorials).
+- LayoutLMv2 uses Facebook AI's [Detectron2](https://github.com/facebookresearch/detectron2/) package for its visual
+ backbone. See [this link](https://detectron2.readthedocs.io/en/latest/tutorials/install.html) for installation
+ instructions.
+- In addition to `input_ids`, [`~LayoutLMv2Model.forward`] expects 2 additional inputs, namely
+ `image` and `bbox`. The `image` input corresponds to the original document image in which the text
+ tokens occur. The model expects each document image to be of size 224x224. This means that if you have a batch of
+ document images, `image` should be a tensor of shape (batch_size, 3, 224, 224). This can be either a
+ `torch.Tensor` or a `Detectron2.structures.ImageList`. You don't need to normalize the channels, as this is
+ done by the model. Important to note is that the visual backbone expects BGR channels instead of RGB, as all models
+ in Detectron2 are pre-trained using the BGR format. The `bbox` input are the bounding boxes (i.e. 2D-positions)
+ of the input text tokens. This is identical to [`LayoutLMModel`]. These can be obtained using an
+ external OCR engine such as Google's [Tesseract](https://github.com/tesseract-ocr/tesseract) (there's a [Python
+ wrapper](https://pypi.org/project/pytesseract/) available). Each bounding box should be in (x0, y0, x1, y1)
+ format, where (x0, y0) corresponds to the position of the upper left corner in the bounding box, and (x1, y1)
+ represents the position of the lower right corner. Note that one first needs to normalize the bounding boxes to be on
+ a 0-1000 scale. To normalize, you can use the following function:
+
+```python
+def normalize_bbox(bbox, width, height):
+ return [
+ int(1000 * (bbox[0] / width)),
+ int(1000 * (bbox[1] / height)),
+ int(1000 * (bbox[2] / width)),
+ int(1000 * (bbox[3] / height)),
+ ]
+```
+
+Here, `width` and `height` correspond to the width and height of the original document in which the token
+occurs (before resizing the image). Those can be obtained using the Python Image Library (PIL) library for example, as
+follows:
+
+```python
+from PIL import Image
+
+image = Image.open(
+ "name_of_your_document - can be a png, jpg, etc. of your documents (PDFs must be converted to images)."
+)
+
+width, height = image.size
+```
+
+However, this model includes a brand new [`~transformers.LayoutLMv2Processor`] which can be used to directly
+prepare data for the model (including applying OCR under the hood). More information can be found in the "Usage"
+section below.
+
+- Internally, [`~transformers.LayoutLMv2Model`] will send the `image` input through its visual backbone to
+ obtain a lower-resolution feature map, whose shape is equal to the `image_feature_pool_shape` attribute of
+ [`~transformers.LayoutLMv2Config`]. This feature map is then flattened to obtain a sequence of image tokens. As
+ the size of the feature map is 7x7 by default, one obtains 49 image tokens. These are then concatenated with the text
+ tokens, and send through the Transformer encoder. This means that the last hidden states of the model will have a
+ length of 512 + 49 = 561, if you pad the text tokens up to the max length. More generally, the last hidden states
+ will have a shape of `seq_length` + `image_feature_pool_shape[0]` *
+ `config.image_feature_pool_shape[1]`.
+- When calling [`~transformers.LayoutLMv2Model.from_pretrained`], a warning will be printed with a long list of
+ parameter names that are not initialized. This is not a problem, as these parameters are batch normalization
+ statistics, which are going to have values when fine-tuning on a custom dataset.
+- If you want to train the model in a distributed environment, make sure to call [`synchronize_batch_norm`] on the
+ model in order to properly synchronize the batch normalization layers of the visual backbone.
+
+In addition, there's LayoutXLM, which is a multilingual version of LayoutLMv2. More information can be found on
+[LayoutXLM's documentation page](layoutxlm).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LayoutLMv2. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- A notebook on how to [finetune LayoutLMv2 for text-classification on RVL-CDIP dataset](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/RVL-CDIP/Fine_tuning_LayoutLMv2ForSequenceClassification_on_RVL_CDIP.ipynb).
+- See also: [Text classification task guide](../tasks/sequence_classification)
+
+
+
+- A notebook on how to [finetune LayoutLMv2 for question-answering on DocVQA dataset](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/DocVQA/Fine_tuning_LayoutLMv2ForQuestionAnswering_on_DocVQA.ipynb).
+- See also: [Question answering task guide](../tasks/question_answering)
+- See also: [Document question answering task guide](../tasks/document_question_answering)
+
+
+
+
+- A notebook on how to [finetune LayoutLMv2 for token-classification on CORD dataset](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/CORD/Fine_tuning_LayoutLMv2ForTokenClassification_on_CORD.ipynb).
+- A notebook on how to [finetune LayoutLMv2 for token-classification on FUNSD dataset](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/FUNSD/Fine_tuning_LayoutLMv2ForTokenClassification_on_FUNSD_using_HuggingFace_Trainer.ipynb).
+- See also: [Token classification task guide](../tasks/token_classification)
+
+## Usage: LayoutLMv2Processor
+
+The easiest way to prepare data for the model is to use [`LayoutLMv2Processor`], which internally
+combines a image processor ([`LayoutLMv2ImageProcessor`]) and a tokenizer
+([`LayoutLMv2Tokenizer`] or [`LayoutLMv2TokenizerFast`]). The image processor
+handles the image modality, while the tokenizer handles the text modality. A processor combines both, which is ideal
+for a multi-modal model like LayoutLMv2. Note that you can still use both separately, if you only want to handle one
+modality.
+
+```python
+from transformers import LayoutLMv2ImageProcessor, LayoutLMv2TokenizerFast, LayoutLMv2Processor
+
+image_processor = LayoutLMv2ImageProcessor() # apply_ocr is set to True by default
+tokenizer = LayoutLMv2TokenizerFast.from_pretrained("microsoft/layoutlmv2-base-uncased")
+processor = LayoutLMv2Processor(image_processor, tokenizer)
+```
+
+In short, one can provide a document image (and possibly additional data) to [`LayoutLMv2Processor`],
+and it will create the inputs expected by the model. Internally, the processor first uses
+[`LayoutLMv2ImageProcessor`] to apply OCR on the image to get a list of words and normalized
+bounding boxes, as well to resize the image to a given size in order to get the `image` input. The words and
+normalized bounding boxes are then provided to [`LayoutLMv2Tokenizer`] or
+[`LayoutLMv2TokenizerFast`], which converts them to token-level `input_ids`,
+`attention_mask`, `token_type_ids`, `bbox`. Optionally, one can provide word labels to the processor,
+which are turned into token-level `labels`.
+
+[`LayoutLMv2Processor`] uses [PyTesseract](https://pypi.org/project/pytesseract/), a Python
+wrapper around Google's Tesseract OCR engine, under the hood. Note that you can still use your own OCR engine of
+choice, and provide the words and normalized boxes yourself. This requires initializing
+[`LayoutLMv2ImageProcessor`] with `apply_ocr` set to `False`.
+
+In total, there are 5 use cases that are supported by the processor. Below, we list them all. Note that each of these
+use cases work for both batched and non-batched inputs (we illustrate them for non-batched inputs).
+
+**Use case 1: document image classification (training, inference) + token classification (inference), apply_ocr =
+True**
+
+This is the simplest case, in which the processor (actually the image processor) will perform OCR on the image to get
+the words and normalized bounding boxes.
+
+```python
+from transformers import LayoutLMv2Processor
+from PIL import Image
+
+processor = LayoutLMv2Processor.from_pretrained("microsoft/layoutlmv2-base-uncased")
+
+image = Image.open(
+ "name_of_your_document - can be a png, jpg, etc. of your documents (PDFs must be converted to images)."
+).convert("RGB")
+encoding = processor(
+ image, return_tensors="pt"
+) # you can also add all tokenizer parameters here such as padding, truncation
+print(encoding.keys())
+# dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'bbox', 'image'])
+```
+
+**Use case 2: document image classification (training, inference) + token classification (inference), apply_ocr=False**
+
+In case one wants to do OCR themselves, one can initialize the image processor with `apply_ocr` set to
+`False`. In that case, one should provide the words and corresponding (normalized) bounding boxes themselves to
+the processor.
+
+```python
+from transformers import LayoutLMv2Processor
+from PIL import Image
+
+processor = LayoutLMv2Processor.from_pretrained("microsoft/layoutlmv2-base-uncased", revision="no_ocr")
+
+image = Image.open(
+ "name_of_your_document - can be a png, jpg, etc. of your documents (PDFs must be converted to images)."
+).convert("RGB")
+words = ["hello", "world"]
+boxes = [[1, 2, 3, 4], [5, 6, 7, 8]] # make sure to normalize your bounding boxes
+encoding = processor(image, words, boxes=boxes, return_tensors="pt")
+print(encoding.keys())
+# dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'bbox', 'image'])
+```
+
+**Use case 3: token classification (training), apply_ocr=False**
+
+For token classification tasks (such as FUNSD, CORD, SROIE, Kleister-NDA), one can also provide the corresponding word
+labels in order to train a model. The processor will then convert these into token-level `labels`. By default, it
+will only label the first wordpiece of a word, and label the remaining wordpieces with -100, which is the
+`ignore_index` of PyTorch's CrossEntropyLoss. In case you want all wordpieces of a word to be labeled, you can
+initialize the tokenizer with `only_label_first_subword` set to `False`.
+
+```python
+from transformers import LayoutLMv2Processor
+from PIL import Image
+
+processor = LayoutLMv2Processor.from_pretrained("microsoft/layoutlmv2-base-uncased", revision="no_ocr")
+
+image = Image.open(
+ "name_of_your_document - can be a png, jpg, etc. of your documents (PDFs must be converted to images)."
+).convert("RGB")
+words = ["hello", "world"]
+boxes = [[1, 2, 3, 4], [5, 6, 7, 8]] # make sure to normalize your bounding boxes
+word_labels = [1, 2]
+encoding = processor(image, words, boxes=boxes, word_labels=word_labels, return_tensors="pt")
+print(encoding.keys())
+# dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'bbox', 'labels', 'image'])
+```
+
+**Use case 4: visual question answering (inference), apply_ocr=True**
+
+For visual question answering tasks (such as DocVQA), you can provide a question to the processor. By default, the
+processor will apply OCR on the image, and create [CLS] question tokens [SEP] word tokens [SEP].
+
+```python
+from transformers import LayoutLMv2Processor
+from PIL import Image
+
+processor = LayoutLMv2Processor.from_pretrained("microsoft/layoutlmv2-base-uncased")
+
+image = Image.open(
+ "name_of_your_document - can be a png, jpg, etc. of your documents (PDFs must be converted to images)."
+).convert("RGB")
+question = "What's his name?"
+encoding = processor(image, question, return_tensors="pt")
+print(encoding.keys())
+# dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'bbox', 'image'])
+```
+
+**Use case 5: visual question answering (inference), apply_ocr=False**
+
+For visual question answering tasks (such as DocVQA), you can provide a question to the processor. If you want to
+perform OCR yourself, you can provide your own words and (normalized) bounding boxes to the processor.
+
+```python
+from transformers import LayoutLMv2Processor
+from PIL import Image
+
+processor = LayoutLMv2Processor.from_pretrained("microsoft/layoutlmv2-base-uncased", revision="no_ocr")
+
+image = Image.open(
+ "name_of_your_document - can be a png, jpg, etc. of your documents (PDFs must be converted to images)."
+).convert("RGB")
+question = "What's his name?"
+words = ["hello", "world"]
+boxes = [[1, 2, 3, 4], [5, 6, 7, 8]] # make sure to normalize your bounding boxes
+encoding = processor(image, question, words, boxes=boxes, return_tensors="pt")
+print(encoding.keys())
+# dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'bbox', 'image'])
+```
+
+## LayoutLMv2Config
+
+[[autodoc]] LayoutLMv2Config
+
+## LayoutLMv2FeatureExtractor
+
+[[autodoc]] LayoutLMv2FeatureExtractor
+ - __call__
+
+## LayoutLMv2ImageProcessor
+
+[[autodoc]] LayoutLMv2ImageProcessor
+ - preprocess
+
+## LayoutLMv2ImageProcessorFast
+
+[[autodoc]] LayoutLMv2ImageProcessorFast
+ - preprocess
+
+## LayoutLMv2Tokenizer
+
+[[autodoc]] LayoutLMv2Tokenizer
+ - __call__
+ - save_vocabulary
+
+## LayoutLMv2TokenizerFast
+
+[[autodoc]] LayoutLMv2TokenizerFast
+ - __call__
+
+## LayoutLMv2Processor
+
+[[autodoc]] LayoutLMv2Processor
+ - __call__
+
+## LayoutLMv2Model
+
+[[autodoc]] LayoutLMv2Model
+ - forward
+
+## LayoutLMv2ForSequenceClassification
+
+[[autodoc]] LayoutLMv2ForSequenceClassification
+
+## LayoutLMv2ForTokenClassification
+
+[[autodoc]] LayoutLMv2ForTokenClassification
+
+## LayoutLMv2ForQuestionAnswering
+
+[[autodoc]] LayoutLMv2ForQuestionAnswering
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/layoutlmv3.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/layoutlmv3.md
new file mode 100644
index 0000000000000000000000000000000000000000..737e9233c7a0e37a971d5e457aeb9924092c21d0
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/layoutlmv3.md
@@ -0,0 +1,160 @@
+
+*This model was released on 2022-04-18 and added to Hugging Face Transformers on 2022-05-24.*
+
+# LayoutLMv3
+
+## Overview
+
+The LayoutLMv3 model was proposed in [LayoutLMv3: Pre-training for Document AI with Unified Text and Image Masking](https://huggingface.co/papers/2204.08387) by Yupan Huang, Tengchao Lv, Lei Cui, Yutong Lu, Furu Wei.
+LayoutLMv3 simplifies [LayoutLMv2](layoutlmv2) by using patch embeddings (as in [ViT](vit)) instead of leveraging a CNN backbone, and pre-trains the model on 3 objectives: masked language modeling (MLM), masked image modeling (MIM)
+and word-patch alignment (WPA).
+
+The abstract from the paper is the following:
+
+*Self-supervised pre-training techniques have achieved remarkable progress in Document AI. Most multimodal pre-trained models use a masked language modeling objective to learn bidirectional representations on the text modality, but they differ in pre-training objectives for the image modality. This discrepancy adds difficulty to multimodal representation learning. In this paper, we propose LayoutLMv3 to pre-train multimodal Transformers for Document AI with unified text and image masking. Additionally, LayoutLMv3 is pre-trained with a word-patch alignment objective to learn cross-modal alignment by predicting whether the corresponding image patch of a text word is masked. The simple unified architecture and training objectives make LayoutLMv3 a general-purpose pre-trained model for both text-centric and image-centric Document AI tasks. Experimental results show that LayoutLMv3 achieves state-of-the-art performance not only in text-centric tasks, including form understanding, receipt understanding, and document visual question answering, but also in image-centric tasks such as document image classification and document layout analysis.*
+
+
+
+ LayoutLMv3 architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The TensorFlow version of this model was added by [chriskoo](https://huggingface.co/chriskoo), [tokec](https://huggingface.co/tokec), and [lre](https://huggingface.co/lre). The original code can be found [here](https://github.com/microsoft/unilm/tree/master/layoutlmv3).
+
+## Usage tips
+
+- In terms of data processing, LayoutLMv3 is identical to its predecessor [LayoutLMv2](layoutlmv2), except that:
+ - images need to be resized and normalized with channels in regular RGB format. LayoutLMv2 on the other hand normalizes the images internally and expects the channels in BGR format.
+ - text is tokenized using byte-pair encoding (BPE), as opposed to WordPiece.
+ Due to these differences in data preprocessing, one can use [`LayoutLMv3Processor`] which internally combines a [`LayoutLMv3ImageProcessor`] (for the image modality) and a [`LayoutLMv3Tokenizer`]/[`LayoutLMv3TokenizerFast`] (for the text modality) to prepare all data for the model.
+- Regarding usage of [`LayoutLMv3Processor`], we refer to the [usage guide](layoutlmv2#usage-layoutlmv2processor) of its predecessor.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LayoutLMv3. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+LayoutLMv3 is nearly identical to LayoutLMv2, so we've also included LayoutLMv2 resources you can adapt for LayoutLMv3 tasks. For these notebooks, take care to use [`LayoutLMv2Processor`] instead when preparing data for the model!
+
+
+
+- Demo notebooks for LayoutLMv3 can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/LayoutLMv3).
+- Demo scripts can be found [here](https://github.com/huggingface/transformers-research-projects/tree/main/layoutlmv3).
+
+
+
+- [`LayoutLMv2ForSequenceClassification`] is supported by this [notebook](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/RVL-CDIP/Fine_tuning_LayoutLMv2ForSequenceClassification_on_RVL_CDIP.ipynb).
+- [Text classification task guide](../tasks/sequence_classification)
+
+
+
+- [`LayoutLMv3ForTokenClassification`] is supported by this [example script](https://github.com/huggingface/transformers-research-projects/tree/main/layoutlmv3) and [notebook](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv3/Fine_tune_LayoutLMv3_on_FUNSD_(HuggingFace_Trainer).ipynb).
+- A [notebook](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/FUNSD/Inference_with_LayoutLMv2ForTokenClassification.ipynb) for how to perform inference with [`LayoutLMv2ForTokenClassification`] and a [notebook](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/FUNSD/True_inference_with_LayoutLMv2ForTokenClassification_%2B_Gradio_demo.ipynb) for how to perform inference when no labels are available with [`LayoutLMv2ForTokenClassification`].
+- A [notebook](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/FUNSD/Fine_tuning_LayoutLMv2ForTokenClassification_on_FUNSD_using_HuggingFace_Trainer.ipynb) for how to finetune [`LayoutLMv2ForTokenClassification`] with the 🤗 Trainer.
+- [Token classification task guide](../tasks/token_classification)
+
+
+
+- [`LayoutLMv2ForQuestionAnswering`] is supported by this [notebook](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/LayoutLMv2/DocVQA/Fine_tuning_LayoutLMv2ForQuestionAnswering_on_DocVQA.ipynb).
+- [Question answering task guide](../tasks/question_answering)
+
+**Document question answering**
+- [Document question answering task guide](../tasks/document_question_answering)
+
+## LayoutLMv3Config
+
+[[autodoc]] LayoutLMv3Config
+
+## LayoutLMv3FeatureExtractor
+
+[[autodoc]] LayoutLMv3FeatureExtractor
+ - __call__
+
+## LayoutLMv3ImageProcessor
+
+[[autodoc]] LayoutLMv3ImageProcessor
+ - preprocess
+
+## LayoutLMv3ImageProcessorFast
+
+[[autodoc]] LayoutLMv3ImageProcessorFast
+ - preprocess
+
+## LayoutLMv3Tokenizer
+
+[[autodoc]] LayoutLMv3Tokenizer
+ - __call__
+ - save_vocabulary
+
+## LayoutLMv3TokenizerFast
+
+[[autodoc]] LayoutLMv3TokenizerFast
+ - __call__
+
+## LayoutLMv3Processor
+
+[[autodoc]] LayoutLMv3Processor
+ - __call__
+
+
+
+
+## LayoutLMv3Model
+
+[[autodoc]] LayoutLMv3Model
+ - forward
+
+## LayoutLMv3ForSequenceClassification
+
+[[autodoc]] LayoutLMv3ForSequenceClassification
+ - forward
+
+## LayoutLMv3ForTokenClassification
+
+[[autodoc]] LayoutLMv3ForTokenClassification
+ - forward
+
+## LayoutLMv3ForQuestionAnswering
+
+[[autodoc]] LayoutLMv3ForQuestionAnswering
+ - forward
+
+
+
+
+## TFLayoutLMv3Model
+
+[[autodoc]] TFLayoutLMv3Model
+ - call
+
+## TFLayoutLMv3ForSequenceClassification
+
+[[autodoc]] TFLayoutLMv3ForSequenceClassification
+ - call
+
+## TFLayoutLMv3ForTokenClassification
+
+[[autodoc]] TFLayoutLMv3ForTokenClassification
+ - call
+
+## TFLayoutLMv3ForQuestionAnswering
+
+[[autodoc]] TFLayoutLMv3ForQuestionAnswering
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/layoutxlm.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/layoutxlm.md
new file mode 100644
index 0000000000000000000000000000000000000000..19051f55b683a55d23634c41f013ca97e763bdbf
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/layoutxlm.md
@@ -0,0 +1,90 @@
+
+*This model was released on 2021-04-18 and added to Hugging Face Transformers on 2021-11-03.*
+
+# LayoutXLM
+
+
+
+
+
+## Overview
+
+LayoutXLM was proposed in [LayoutXLM: Multimodal Pre-training for Multilingual Visually-rich Document Understanding](https://huggingface.co/papers/2104.08836) by Yiheng Xu, Tengchao Lv, Lei Cui, Guoxin Wang, Yijuan Lu, Dinei Florencio, Cha
+Zhang, Furu Wei. It's a multilingual extension of the [LayoutLMv2 model](https://huggingface.co/papers/2012.14740) trained
+on 53 languages.
+
+The abstract from the paper is the following:
+
+*Multimodal pre-training with text, layout, and image has achieved SOTA performance for visually-rich document
+understanding tasks recently, which demonstrates the great potential for joint learning across different modalities. In
+this paper, we present LayoutXLM, a multimodal pre-trained model for multilingual document understanding, which aims to
+bridge the language barriers for visually-rich document understanding. To accurately evaluate LayoutXLM, we also
+introduce a multilingual form understanding benchmark dataset named XFUN, which includes form understanding samples in
+7 languages (Chinese, Japanese, Spanish, French, Italian, German, Portuguese), and key-value pairs are manually labeled
+for each language. Experiment results show that the LayoutXLM model has significantly outperformed the existing SOTA
+cross-lingual pre-trained models on the XFUN dataset.*
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found [here](https://github.com/microsoft/unilm).
+
+## Usage tips and examples
+
+One can directly plug in the weights of LayoutXLM into a LayoutLMv2 model, like so:
+
+```python
+from transformers import LayoutLMv2Model
+
+model = LayoutLMv2Model.from_pretrained("microsoft/layoutxlm-base")
+```
+
+Note that LayoutXLM has its own tokenizer, based on
+[`LayoutXLMTokenizer`]/[`LayoutXLMTokenizerFast`]. You can initialize it as
+follows:
+
+```python
+from transformers import LayoutXLMTokenizer
+
+tokenizer = LayoutXLMTokenizer.from_pretrained("microsoft/layoutxlm-base")
+```
+
+Similar to LayoutLMv2, you can use [`LayoutXLMProcessor`] (which internally applies
+[`LayoutLMv2ImageProcessor`] and
+[`LayoutXLMTokenizer`]/[`LayoutXLMTokenizerFast`] in sequence) to prepare all
+data for the model.
+
+
+
+As LayoutXLM's architecture is equivalent to that of LayoutLMv2, one can refer to [LayoutLMv2's documentation page](layoutlmv2) for all tips, code examples and notebooks.
+
+
+## LayoutXLMTokenizer
+
+[[autodoc]] LayoutXLMTokenizer
+ - __call__
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## LayoutXLMTokenizerFast
+
+[[autodoc]] LayoutXLMTokenizerFast
+ - __call__
+
+## LayoutXLMProcessor
+
+[[autodoc]] LayoutXLMProcessor
+ - __call__
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/led.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/led.md
new file mode 100644
index 0000000000000000000000000000000000000000..2fc54929a4fef53b1621ef1ebf099474714a16be
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/led.md
@@ -0,0 +1,222 @@
+
+*This model was released on 2020-04-10 and added to Hugging Face Transformers on 2021-01-05.*
+
+
+
+
+
+
+
+
+# LED
+
+[Longformer-Encoder-Decoder (LED)](https://huggingface.co/papers/2004.05150) is an encoder-decoder transformer model for sequence-to-sequence tasks like summarization. It extends [Longformer](.longformer), an encoder-only model designed to handle long inputs, by adding a decoder layer. The decoder uses full self-attention on the encoded tokens and previously decoded locations. Because of Longformer's linear self-attention mechanism, LED is more efficient than standard encoder-decoder models when processing long sequences.
+
+You can find all the original [LED] checkpoints under the [Ai2](https://huggingface.co/allenai/models?search=led) organization.
+
+> [!TIP]
+> This model was contributed by [patrickvonplaten](https://huggingface.co/patrickvonplaten).
+>
+> Click on the LED models in the right sidebar for more examples of how to apply LED to different language tasks.
+
+The example below demonstrates how to summarize text with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```python
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="summarization",
+ model="allenai/led-base-16384",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("""Plants are among the most remarkable and essential life forms on Earth, possessing a unique ability to produce their own food through a process known as photosynthesis. This complex biochemical process is fundamental not only to plant life but to virtually all life on the planet.
+Through photosynthesis, plants capture energy from sunlight using a green pigment called chlorophyll, which is located in specialized cell structures called chloroplasts. In the presence of light, plants absorb carbon dioxide from the atmosphere through small pores in their leaves called stomata, and take in water from the soil through their root systems.
+These ingredients are then transformed into glucose, a type of sugar that serves as a source of chemical energy, and oxygen, which is released as a byproduct into the atmosphere. The glucose produced during photosynthesis is not just used immediately; plants also store it as starch or convert it into other organic compounds like cellulose, which is essential for building their cellular structure.
+This energy reserve allows them to grow, develop leaves, produce flowers, bear fruit, and carry out various physiological processes throughout their lifecycle.""")
+```
+
+
+
+
+```python
+import torch
+from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "allenai/led-base-16384"
+)
+model = AutoModelForSeq2SeqLM.from_pretrained(
+ "allenai/led-base-16384",
+ torch_dtype=torch.float16,
+ device_map="auto"
+)
+
+input_text = """Plants are among the most remarkable and essential life forms on Earth, possessing a unique ability to produce their own food through a process known as photosynthesis. This complex biochemical process is fundamental not only to plant life but to virtually all life on the planet.
+Through photosynthesis, plants capture energy from sunlight using a green pigment called chlorophyll, which is located in specialized cell structures called chloroplasts. In the presence of light, plants absorb carbon dioxide from the atmosphere through small pores in their leaves called stomata, and take in water from the soil through their root systems.
+These ingredients are then transformed into glucose, a type of sugar that serves as a source of chemical energy, and oxygen, which is released as a byproduct into the atmosphere. The glucose produced during photosynthesis is not just used immediately; plants also store it as starch or convert it into other organic compounds like cellulose, which is essential for building their cellular structure.
+This energy reserve allows them to grow, develop leaves, produce flowers, bear fruit, and carry out various physiological processes throughout their lifecycle."""
+input_ids = tokenizer(input_text, return_tensors="pt").to(model.device)
+
+# Place global attention on the first token
+global_attention_mask = torch.zeros_like(input_ids.input_ids).to(model.device)
+global_attention_mask[:, 0] = 1
+
+output = model.generate(**input_ids, global_attention_mask=global_attention_mask, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+!echo -e "Plants are among the most remarkable and essential life forms on Earth, possessing a unique ability to produce their own food through a process known as photosynthesis. This complex biochemical process is fundamental not only to plant life but to virtually all life on the planet. Through photosynthesis, plants capture energy from sunlight using a green pigment called chlorophyll, which is located in specialized cell structures called chloroplasts." | transformers-cli run --task summarization --model allenai/led-base-16384 --device 0
+```
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to int4.
+
+```python
+import torch
+from transformers import BitsAndBytesConfig, AutoModelForSeq2SeqLM, AutoTokenizer
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_compute_dtype=torch.bfloat16,
+ bnb_4bit_quant_type="nf4"
+)
+model = AutoModelForSeq2SeqLM.from_pretrained(
+ "allenai/led-large-16384",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "allenai/led-large-16384"
+)
+
+input_text = """Plants are among the most remarkable and essential life forms on Earth, possessing a unique ability to produce their own food through a process known as photosynthesis. This complex biochemical process is fundamental not only to plant life but to virtually all life on the planet.
+Through photosynthesis, plants capture energy from sunlight using a green pigment called chlorophyll, which is located in specialized cell structures called chloroplasts. In the presence of light, plants absorb carbon dioxide from the atmosphere through small pores in their leaves called stomata, and take in water from the soil through their root systems.
+These ingredients are then transformed into glucose, a type of sugar that serves as a source of chemical energy, and oxygen, which is released as a byproduct into the atmosphere. The glucose produced during photosynthesis is not just used immediately; plants also store it as starch or convert it into other organic compounds like cellulose, which is essential for building their cellular structure.
+This energy reserve allows them to grow, develop leaves, produce flowers, bear fruit, and carry out various physiological processes throughout their lifecycle."""
+input_ids = tokenizer(input_text, return_tensors="pt").to(model.device)
+
+# Place global attention on the first token
+global_attention_mask = torch.zeros_like(input_ids.input_ids).to(model.device)
+global_attention_mask[:, 0] = 1
+
+output = model.generate(**input_ids, global_attention_mask=global_attention_mask, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+## Notes
+
+- [`LEDForConditionalGeneration`] is an extension of [`BartForConditionalGeneration`] exchanging the traditional self-attention layer with Longformer's chunked self-attention layer. [`LEDTokenizer`] is an alias of [`BartTokenizer`].
+- LED pads the `input_ids` to be a multiple of `config.attention_window` if required. A small speedup is gained when [`LEDTokenizer`] is used with the `pad_to_multiple_of` argument.
+- LED works best on long-range sequence-to-sequence tasks where the `input_ids` are significantly longer than 1024 tokens.
+- LED uses global attention by means of the `global_attention_mask` (see [`LongformerModel`]). For summarization, it is advised to put global attention only on the first `` token. For question answering, it is advised to put global attention on all tokens of the question.
+- To fine-tune LED on all 16384 parameters, gradient checkpointing can be enabled in case training leads to out-of-memory (OOM) errors. Enable gradient checkpointing by adding `model.gradient_checkpointing_enable()` and setting `use_cache=False` to disable the caching mechanism to save memory.
+- Inputs should be padded on the right because LED uses absolute position embeddings.
+
+## Resources
+
+- Read the [LED on Arxiv notebook](https://colab.research.google.com/drive/12INTTR6n64TzS4RrXZxMSXfrOd9Xzamo?usp=sharing) to see how LED can achieve state-of-the-art performance on Arxiv article summarization.
+- Read the [Fine-tune LED notebook](https://colab.research.google.com/drive/12LjJazBl7Gam0XBPy_y0CTOJZeZ34c2v?usp=sharing) to learn how to fine-tune LED on PubMed articles.
+
+## LEDConfig
+
+[[autodoc]] LEDConfig
+
+## LEDTokenizer
+
+[[autodoc]] LEDTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## LEDTokenizerFast
+
+[[autodoc]] LEDTokenizerFast
+
+## LED specific outputs
+
+[[autodoc]] models.led.modeling_led.LEDEncoderBaseModelOutput
+
+[[autodoc]] models.led.modeling_led.LEDSeq2SeqModelOutput
+
+[[autodoc]] models.led.modeling_led.LEDSeq2SeqLMOutput
+
+[[autodoc]] models.led.modeling_led.LEDSeq2SeqSequenceClassifierOutput
+
+[[autodoc]] models.led.modeling_led.LEDSeq2SeqQuestionAnsweringModelOutput
+
+[[autodoc]] models.led.modeling_tf_led.TFLEDEncoderBaseModelOutput
+
+[[autodoc]] models.led.modeling_tf_led.TFLEDSeq2SeqModelOutput
+
+[[autodoc]] models.led.modeling_tf_led.TFLEDSeq2SeqLMOutput
+
+
+
+
+## LEDModel
+
+[[autodoc]] LEDModel
+ - forward
+
+## LEDForConditionalGeneration
+
+[[autodoc]] LEDForConditionalGeneration
+ - forward
+
+## LEDForSequenceClassification
+
+[[autodoc]] LEDForSequenceClassification
+ - forward
+
+## LEDForQuestionAnswering
+
+[[autodoc]] LEDForQuestionAnswering
+ - forward
+
+
+
+
+## TFLEDModel
+
+[[autodoc]] TFLEDModel
+ - call
+
+## TFLEDForConditionalGeneration
+
+[[autodoc]] TFLEDForConditionalGeneration
+ - call
+
+
+
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/levit.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/levit.md
new file mode 100644
index 0000000000000000000000000000000000000000..61ffcbfa958bb87c4df05fe663876ecb6b748f4a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/levit.md
@@ -0,0 +1,116 @@
+
+*This model was released on 2021-04-02 and added to Hugging Face Transformers on 2022-06-01.*
+
+# LeViT
+
+
+
+
+
+## Overview
+
+The LeViT model was proposed in [LeViT: Introducing Convolutions to Vision Transformers](https://huggingface.co/papers/2104.01136) by Ben Graham, Alaaeldin El-Nouby, Hugo Touvron, Pierre Stock, Armand Joulin, Hervé Jégou, Matthijs Douze. LeViT improves the [Vision Transformer (ViT)](vit) in performance and efficiency by a few architectural differences such as activation maps with decreasing resolutions in Transformers and the introduction of an attention bias to integrate positional information.
+
+The abstract from the paper is the following:
+
+*We design a family of image classification architectures that optimize the trade-off between accuracy
+and efficiency in a high-speed regime. Our work exploits recent findings in attention-based architectures,
+which are competitive on highly parallel processing hardware. We revisit principles from the extensive
+literature on convolutional neural networks to apply them to transformers, in particular activation maps
+with decreasing resolutions. We also introduce the attention bias, a new way to integrate positional information
+in vision transformers. As a result, we propose LeVIT: a hybrid neural network for fast inference image classification.
+We consider different measures of efficiency on different hardware platforms, so as to best reflect a wide range of
+application scenarios. Our extensive experiments empirically validate our technical choices and show they are suitable
+to most architectures. Overall, LeViT significantly outperforms existing convnets and vision transformers with respect
+to the speed/accuracy tradeoff. For example, at 80% ImageNet top-1 accuracy, LeViT is 5 times faster than EfficientNet on CPU. *
+
+
+
+ LeViT Architecture. Taken from the original paper.
+
+This model was contributed by [anugunj](https://huggingface.co/anugunj). The original code can be found [here](https://github.com/facebookresearch/LeViT).
+
+## Usage tips
+
+- Compared to ViT, LeViT models use an additional distillation head to effectively learn from a teacher (which, in the LeViT paper, is a ResNet like-model). The distillation head is learned through backpropagation under supervision of a ResNet like-model. They also draw inspiration from convolution neural networks to use activation maps with decreasing resolutions to increase the efficiency.
+- There are 2 ways to fine-tune distilled models, either (1) in a classic way, by only placing a prediction head on top
+ of the final hidden state and not using the distillation head, or (2) by placing both a prediction head and distillation
+ head on top of the final hidden state. In that case, the prediction head is trained using regular cross-entropy between
+ the prediction of the head and the ground-truth label, while the distillation prediction head is trained using hard distillation
+ (cross-entropy between the prediction of the distillation head and the label predicted by the teacher). At inference time,
+ one takes the average prediction between both heads as final prediction. (2) is also called "fine-tuning with distillation",
+ because one relies on a teacher that has already been fine-tuned on the downstream dataset. In terms of models, (1) corresponds
+ to [`LevitForImageClassification`] and (2) corresponds to [`LevitForImageClassificationWithTeacher`].
+- All released checkpoints were pre-trained and fine-tuned on [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k)
+ (also referred to as ILSVRC 2012, a collection of 1.3 million images and 1,000 classes). only. No external data was used. This is in
+ contrast with the original ViT model, which used external data like the JFT-300M dataset/Imagenet-21k for
+ pre-training.
+- The authors of LeViT released 5 trained LeViT models, which you can directly plug into [`LevitModel`] or [`LevitForImageClassification`].
+ Techniques like data augmentation, optimization, and regularization were used in order to simulate training on a much larger dataset
+ (while only using ImageNet-1k for pre-training). The 5 variants available are (all trained on images of size 224x224):
+ *facebook/levit-128S*, *facebook/levit-128*, *facebook/levit-192*, *facebook/levit-256* and
+ *facebook/levit-384*. Note that one should use [`LevitImageProcessor`] in order to
+ prepare images for the model.
+- [`LevitForImageClassificationWithTeacher`] currently supports only inference and not training or fine-tuning.
+- You can check out demo notebooks regarding inference as well as fine-tuning on custom data [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/VisionTransformer)
+ (you can just replace [`ViTFeatureExtractor`] by [`LevitImageProcessor`] and [`ViTForImageClassification`] by [`LevitForImageClassification`] or [`LevitForImageClassificationWithTeacher`]).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LeViT.
+
+
+
+- [`LevitForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## LevitConfig
+
+[[autodoc]] LevitConfig
+
+## LevitFeatureExtractor
+
+[[autodoc]] LevitFeatureExtractor
+ - __call__
+
+## LevitImageProcessor
+
+ [[autodoc]] LevitImageProcessor
+ - preprocess
+
+## LevitImageProcessorFast
+
+ [[autodoc]] LevitImageProcessorFast
+ - preprocess
+
+## LevitModel
+
+[[autodoc]] LevitModel
+ - forward
+
+## LevitForImageClassification
+
+[[autodoc]] LevitForImageClassification
+ - forward
+
+## LevitForImageClassificationWithTeacher
+
+[[autodoc]] LevitForImageClassificationWithTeacher
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/lfm2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/lfm2.md
new file mode 100644
index 0000000000000000000000000000000000000000..bffc7f7d14eb14d0953010da7851307307e9a0b4
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/lfm2.md
@@ -0,0 +1,85 @@
+
+*This model was released on 2025-07-10 and added to Hugging Face Transformers on 2025-07-10.*
+
+
+
+
+
+# LFM2
+
+## Overview
+
+[LFM2](https://www.liquid.ai/blog/liquid-foundation-models-v2-our-second-series-of-generative-ai-models) represents a new generation of Liquid Foundation Models developed by [Liquid AI](https://liquid.ai/), specifically designed for edge AI and on-device deployment.
+
+The models are available in three sizes (350M, 700M, and 1.2B parameters) and are engineered to run efficiently on CPU, GPU, and NPU hardware, making them particularly well-suited for applications requiring low latency, offline operation, and privacy.
+
+## Architecture
+
+The architecture consists of 16 blocks total: 10 double-gated short-range convolution blocks and 6 blocks of grouped query attention. This design stems from the concept of dynamical systems, where linear operations are modulated by input-dependent gates, allowing for "liquid" dynamics that can adapt in real-time. The short convolutions are particularly optimized for embedded SoC CPUs, making them ideal for devices that require fast, local inference without relying on cloud connectivity.
+
+The key architectural innovation of LFM2 lies in its systematic approach to balancing quality, latency, and memory efficiency through our STAR neural architecture search engine. Using STAR, Liquid AI optimized the models for real-world performance on embedded hardware, measuring actual peak memory usage and inference speed on Qualcomm Snapdragon processors. This results in models that achieve 2x faster decode and prefill performance compared to similar-sized models, while maintaining superior benchmark performance across knowledge, mathematics, instruction following, and multilingual tasks.
+
+## Example
+
+The following example shows how to generate an answer using the `AutoModelForCausalLM` class.
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+# Load model and tokenizer
+model_id = "LiquidAI/LFM2-1.2B"
+model = AutoModelForCausalLM.from_pretrained(
+ model_id,
+ device_map="auto",
+ torch_dtype="bfloat16",
+)
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+
+# Generate answer
+prompt = "What is C. elegans?"
+input_ids = tokenizer.apply_chat_template(
+ [{"role": "user", "content": prompt}],
+ add_generation_prompt=True,
+ return_tensors="pt",
+ tokenize=True,
+)
+
+output = model.generate(
+ input_ids,
+ do_sample=True,
+ temperature=0.3,
+ min_p=0.15,
+ repetition_penalty=1.05,
+ max_new_tokens=512,
+)
+
+print(tokenizer.decode(output[0], skip_special_tokens=False))
+```
+
+## Lfm2Config
+
+[[autodoc]] Lfm2Config
+
+## Lfm2Model
+
+[[autodoc]] Lfm2Model
+ - forward
+
+## Lfm2ForCausalLM
+
+[[autodoc]] Lfm2ForCausalLM
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/lightglue.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/lightglue.md
new file mode 100644
index 0000000000000000000000000000000000000000..33c0ad630916c342464cf08a848979faa800e54c
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/lightglue.md
@@ -0,0 +1,143 @@
+
+*This model was released on 2023-06-23 and added to Hugging Face Transformers on 2025-06-17.*
+
+
+
+
+
+
+
+# LightGlue
+
+[LightGlue](https://huggingface.co/papers/2306.13643) is a deep neural network that learns to match local features across images. It revisits multiple design decisions of SuperGlue and derives simple but effective improvements. Cumulatively, these improvements make LightGlue more efficient - in terms of both memory and computation, more accurate, and much easier to train. Similar to [SuperGlue](https://huggingface.co/magic-leap-community/superglue_outdoor), this model consists of matching two sets of local features extracted from two images, with the goal of being faster than SuperGlue. Paired with the [SuperPoint model](https://huggingface.co/magic-leap-community/superpoint), it can be used to match two images and estimate the pose between them.
+
+You can find all the original LightGlue checkpoints under the [ETH-CVG](https://huggingface.co/ETH-CVG) organization.
+
+> [!TIP]
+> This model was contributed by [stevenbucaille](https://huggingface.co/stevenbucaille).
+>
+> Click on the LightGlue models in the right sidebar for more examples of how to apply LightGlue to different computer vision tasks.
+
+The example below demonstrates how to match keypoints between two images with the [`AutoModel`] class.
+
+
+
+
+```py
+from transformers import AutoImageProcessor, AutoModel
+import torch
+from PIL import Image
+import requests
+
+url_image1 = "https://raw.githubusercontent.com/magicleap/SuperGluePretrainedNetwork/refs/heads/master/assets/phototourism_sample_images/united_states_capitol_98169888_3347710852.jpg"
+image1 = Image.open(requests.get(url_image1, stream=True).raw)
+url_image2 = "https://raw.githubusercontent.com/magicleap/SuperGluePretrainedNetwork/refs/heads/master/assets/phototourism_sample_images/united_states_capitol_26757027_6717084061.jpg"
+image2 = Image.open(requests.get(url_image2, stream=True).raw)
+
+images = [image1, image2]
+
+processor = AutoImageProcessor.from_pretrained("ETH-CVG/lightglue_superpoint")
+model = AutoModel.from_pretrained("ETH-CVG/lightglue_superpoint")
+
+inputs = processor(images, return_tensors="pt")
+with torch.no_grad():
+ outputs = model(**inputs)
+
+# Post-process to get keypoints and matches
+image_sizes = [[(image.height, image.width) for image in images]]
+processed_outputs = processor.post_process_keypoint_matching(outputs, image_sizes, threshold=0.2)
+```
+
+
+
+
+## Notes
+
+- LightGlue is adaptive to the task difficulty. Inference is much faster on image pairs that are intuitively easy to match, for example, because of a larger visual overlap or limited appearance change.
+
+ ```py
+ from transformers import AutoImageProcessor, AutoModel
+ import torch
+ from PIL import Image
+ import requests
+
+ processor = AutoImageProcessor.from_pretrained("ETH-CVG/lightglue_superpoint")
+ model = AutoModel.from_pretrained("ETH-CVG/lightglue_superpoint")
+
+ # LightGlue requires pairs of images
+ images = [image1, image2]
+ inputs = processor(images, return_tensors="pt")
+ outputs = model(**inputs)
+
+ # Extract matching information
+ keypoints0 = outputs.keypoints0 # Keypoints in first image
+ keypoints1 = outputs.keypoints1 # Keypoints in second image
+ matches = outputs.matches # Matching indices
+ matching_scores = outputs.matching_scores # Confidence scores
+ ```
+
+- The model outputs matching indices, keypoints, and confidence scores for each match, similar to SuperGlue but with improved efficiency.
+- For better visualization and analysis, use the [`LightGlueImageProcessor.post_process_keypoint_matching`] method to get matches in a more readable format.
+
+ ```py
+ # Process outputs for visualization
+ image_sizes = [[(image.height, image.width) for image in images]]
+ processed_outputs = processor.post_process_keypoint_matching(outputs, image_sizes, threshold=0.2)
+
+ for i, output in enumerate(processed_outputs):
+ print(f"For the image pair {i}")
+ for keypoint0, keypoint1, matching_score in zip(
+ output["keypoints0"], output["keypoints1"], output["matching_scores"]
+ ):
+ print(f"Keypoint at {keypoint0.numpy()} matches with keypoint at {keypoint1.numpy()} with score {matching_score}")
+ ```
+
+- Visualize the matches between the images using the built-in plotting functionality.
+
+ ```py
+ # Easy visualization using the built-in plotting method
+ processor.visualize_keypoint_matching(images, processed_outputs)
+ ```
+
+
+
+
+
+## Resources
+
+- Refer to the [original LightGlue repository](https://github.com/cvg/LightGlue) for more examples and implementation details.
+
+## LightGlueConfig
+
+[[autodoc]] LightGlueConfig
+
+## LightGlueImageProcessor
+
+[[autodoc]] LightGlueImageProcessor
+
+- preprocess
+- post_process_keypoint_matching
+- visualize_keypoint_matching
+
+
+
+## LightGlueForKeypointMatching
+
+[[autodoc]] LightGlueForKeypointMatching
+
+- forward
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/lilt.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/lilt.md
new file mode 100644
index 0000000000000000000000000000000000000000..54475e7cb3b59ae735472ab994d88cac7d48eba3
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/lilt.md
@@ -0,0 +1,93 @@
+
+*This model was released on 2022-02-28 and added to Hugging Face Transformers on 2022-10-12.*
+
+# LiLT
+
+
+
+
+
+## Overview
+
+The LiLT model was proposed in [LiLT: A Simple yet Effective Language-Independent Layout Transformer for Structured Document Understanding](https://huggingface.co/papers/2202.13669) by Jiapeng Wang, Lianwen Jin, Kai Ding.
+LiLT allows to combine any pre-trained RoBERTa text encoder with a lightweight Layout Transformer, to enable [LayoutLM](layoutlm)-like document understanding for many
+languages.
+
+The abstract from the paper is the following:
+
+*Structured document understanding has attracted considerable attention and made significant progress recently, owing to its crucial role in intelligent document processing. However, most existing related models can only deal with the document data of specific language(s) (typically English) included in the pre-training collection, which is extremely limited. To address this issue, we propose a simple yet effective Language-independent Layout Transformer (LiLT) for structured document understanding. LiLT can be pre-trained on the structured documents of a single language and then directly fine-tuned on other languages with the corresponding off-the-shelf monolingual/multilingual pre-trained textual models. Experimental results on eight languages have shown that LiLT can achieve competitive or even superior performance on diverse widely-used downstream benchmarks, which enables language-independent benefit from the pre-training of document layout structure.*
+
+
+
+ LiLT architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/jpwang/lilt).
+
+## Usage tips
+
+- To combine the Language-Independent Layout Transformer with a new RoBERTa checkpoint from the [hub](https://huggingface.co/models?search=roberta), refer to [this guide](https://github.com/jpWang/LiLT#or-generate-your-own-checkpoint-optional).
+The script will result in `config.json` and `pytorch_model.bin` files being stored locally. After doing this, one can do the following (assuming you're logged in with your HuggingFace account):
+
+```python
+from transformers import LiltModel
+
+model = LiltModel.from_pretrained("path_to_your_files")
+model.push_to_hub("name_of_repo_on_the_hub")
+```
+
+- When preparing data for the model, make sure to use the token vocabulary that corresponds to the RoBERTa checkpoint you combined with the Layout Transformer.
+- As [lilt-roberta-en-base](https://huggingface.co/SCUT-DLVCLab/lilt-roberta-en-base) uses the same vocabulary as [LayoutLMv3](layoutlmv3), one can use [`LayoutLMv3TokenizerFast`] to prepare data for the model.
+The same is true for [lilt-roberta-en-base](https://huggingface.co/SCUT-DLVCLab/lilt-infoxlm-base): one can use [`LayoutXLMTokenizerFast`] for that model.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LiLT.
+
+- Demo notebooks for LiLT can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/LiLT).
+
+**Documentation resources**
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## LiltConfig
+
+[[autodoc]] LiltConfig
+
+## LiltModel
+
+[[autodoc]] LiltModel
+ - forward
+
+## LiltForSequenceClassification
+
+[[autodoc]] LiltForSequenceClassification
+ - forward
+
+## LiltForTokenClassification
+
+[[autodoc]] LiltForTokenClassification
+ - forward
+
+## LiltForQuestionAnswering
+
+[[autodoc]] LiltForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llama.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llama.md
new file mode 100644
index 0000000000000000000000000000000000000000..d241ccdd1001dcfe9732875e652f889216fad4e5
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llama.md
@@ -0,0 +1,183 @@
+
+*This model was released on 2023-02-27 and added to Hugging Face Transformers on 2023-03-16.*
+
+
+
+
+
+
+
+
+
+
+
+# Llama
+
+[Llama](https://huggingface.co/papers/2302.13971) is a family of large language models ranging from 7B to 65B parameters. These models are focused on efficient inference (important for serving language models) by training a smaller model on more tokens rather than training a larger model on fewer tokens. The Llama model is based on the GPT architecture, but it uses pre-normalization to improve training stability, replaces ReLU with SwiGLU to improve performance, and replaces absolute positional embeddings with rotary positional embeddings (RoPE) to better handle longer sequence lengths.
+
+You can find all the original Llama checkpoints under the [Huggy Llama](https://huggingface.co/huggyllama) organization.
+
+> [!TIP]
+> Click on the Llama models in the right sidebar for more examples of how to apply Llama to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`] or the [`AutoModel`], and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="text-generation",
+ model="huggyllama/llama-7b",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("Plants create energy through a process known as")
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "huggyllama/llama-7b",
+)
+model = AutoModelForCausalLM.from_pretrained(
+ "huggyllama/llama-7b",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+input_ids = tokenizer("Plants create energy through a process known as", return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+echo -e "Plants create energy through a process known as" | transformers run --task text-generation --model huggyllama/llama-7b --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [torchao](../quantization/torchao) to only quantize the weights to int4.
+
+```py
+# pip install torchao
+import torch
+from transformers import TorchAoConfig, AutoModelForCausalLM, AutoTokenizer
+
+quantization_config = TorchAoConfig("int4_weight_only", group_size=128)
+model = AutoModelForCausalLM.from_pretrained(
+ "huggyllama/llama-30b",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained("huggyllama/llama-30b")
+input_ids = tokenizer("Plants create energy through a process known as", return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+Use the [AttentionMaskVisualizer](https://github.com/huggingface/transformers/blob/beb9b5b02246b9b7ee81ddf938f93f44cfeaad19/src/transformers/utils/attention_visualizer.py#L139) to better understand what tokens the model can and cannot attend to.
+
+```py
+from transformers.utils.attention_visualizer import AttentionMaskVisualizer
+
+visualizer = AttentionMaskVisualizer("huggyllama/llama-7b")
+visualizer("Plants create energy through a process known as")
+```
+
+
+
+
+
+## Notes
+
+- The tokenizer is a byte-pair encoding model based on [SentencePiece](https://github.com/google/sentencepiece). During decoding, if the first token is the start of the word (for example, "Banana"), the tokenizer doesn't prepend the prefix space to the string.
+
+## LlamaConfig
+
+[[autodoc]] LlamaConfig
+
+## LlamaTokenizer
+
+[[autodoc]] LlamaTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## LlamaTokenizerFast
+
+[[autodoc]] LlamaTokenizerFast
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - update_post_processor
+ - save_vocabulary
+
+## LlamaModel
+
+[[autodoc]] LlamaModel
+ - forward
+
+## LlamaForCausalLM
+
+[[autodoc]] LlamaForCausalLM
+ - forward
+
+## LlamaForSequenceClassification
+
+[[autodoc]] LlamaForSequenceClassification
+ - forward
+
+## LlamaForQuestionAnswering
+
+[[autodoc]] LlamaForQuestionAnswering
+ - forward
+
+## LlamaForTokenClassification
+
+[[autodoc]] LlamaForTokenClassification
+ - forward
+
+## FlaxLlamaModel
+
+[[autodoc]] FlaxLlamaModel
+ - __call__
+
+## FlaxLlamaForCausalLM
+
+[[autodoc]] FlaxLlamaForCausalLM
+ - __call__
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llama2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llama2.md
new file mode 100644
index 0000000000000000000000000000000000000000..4025830735cb2bb9d9918d74a85f2cb60caae4cf
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llama2.md
@@ -0,0 +1,179 @@
+
+*This model was released on 2023-07-18 and added to Hugging Face Transformers on 2023-07-18.*
+
+
+
+
+
+
+
+
+
+# Llama 2
+
+[Llama 2](https://huggingface.co/papers/2307.09288) is a family of large language models, Llama 2 and Llama 2-Chat, available in 7B, 13B, and 70B parameters. The Llama 2 model mostly keeps the same architecture as [Llama](./llama), but it is pretrained on more tokens, doubles the context length, and uses grouped-query attention (GQA) in the 70B model to improve inference.
+
+Llama 2-Chat is trained with supervised fine-tuning (SFT), and reinforcement learning with human feedback (RLHF) - rejection sampling and proximal policy optimization (PPO) - is applied to the fine-tuned model to align the chat model with human preferences.
+
+You can find all the original Llama 2 checkpoints under the [Llama 2 Family](https://huggingface.co/collections/meta-llama/llama-2-family-661da1f90a9d678b6f55773b) collection.
+
+> [!TIP]
+> Click on the Llama 2 models in the right sidebar for more examples of how to apply Llama to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`], [`AutoModel`], and how to chat with Llama 2-Chat from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="text-generation",
+ model="meta-llama/Llama-2-7b-hf",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("Plants create energy through a process known as")
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "meta-llama/Llama-2-7b-hf",
+)
+model = AutoModelForCausalLM.from_pretrained(
+ "meta-llama/Llama-2-7b-hf",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+input_ids = tokenizer("Plants create energy through a process known as", return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+transformers chat meta-llama/Llama-2-7b-chat-hf --torch_dtype auto --attn_implementation flash_attention_2
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [torchao](../quantization/torchao) to only quantize the weights to int4.
+
+```py
+# pip install torchao
+import torch
+from transformers import TorchAoConfig, AutoModelForCausalLM, AutoTokenizer
+
+quantization_config = TorchAoConfig("int4_weight_only", group_size=128)
+model = AutoModelForCausalLM.from_pretrained(
+ "meta-llama/Llama-2-13b-hf",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained("meta-llama/Llama-2-13b-hf")
+input_ids = tokenizer("Plants create energy through a process known as", return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+Use the [AttentionMaskVisualizer](https://github.com/huggingface/transformers/blob/beb9b5b02246b9b7ee81ddf938f93f44cfeaad19/src/transformers/utils/attention_visualizer.py#L139) to better understand what tokens the model can and cannot attend to.
+
+```py
+from transformers.utils.attention_visualizer import AttentionMaskVisualizer
+
+visualizer = AttentionMaskVisualizer("meta-llama/Llama-2-7b-hf")
+visualizer("Plants create energy through a process known as")
+```
+
+
+
+
+
+## Notes
+
+- Setting `config.pretraining_tp` to a value besides `1` activates a more accurate but slower computation of the linear layers. This matches the original logits better.
+- The original model uses `pad_id = -1` to indicate a padding token. The Transformers implementation requires adding a padding token and resizing the token embedding accordingly.
+
+ ```py
+ tokenizer.add_special_tokens({"pad_token":""})
+ # update model config with padding token
+ model.config.pad_token_id
+ ```
+- It is recommended to initialize the `embed_tokens` layer with the following code to ensure encoding the padding token outputs zeros.
+
+ ```py
+ self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.config.padding_idx)
+ ```
+- The tokenizer is a byte-pair encoding model based on [SentencePiece](https://github.com/google/sentencepiece). During decoding, if the first token is the start of the word (for example, "Banana"), the tokenizer doesn't prepend the prefix space to the string.
+- Don't use the `torch_dtype` parameter in [`~AutoModel.from_pretrained`] if you're using FlashAttention-2 because it only supports fp16 or bf16. You should use [Automatic Mixed Precision](https://pytorch.org/tutorials/recipes/recipes/amp_recipe.html), set fp16 or bf16 to `True` if using [`Trainer`], or use [torch.autocast](https://pytorch.org/docs/stable/amp.html#torch.autocast).
+
+## LlamaConfig
+
+[[autodoc]] LlamaConfig
+
+
+## LlamaTokenizer
+
+[[autodoc]] LlamaTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## LlamaTokenizerFast
+
+[[autodoc]] LlamaTokenizerFast
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - update_post_processor
+ - save_vocabulary
+
+## LlamaModel
+
+[[autodoc]] LlamaModel
+ - forward
+
+
+## LlamaForCausalLM
+
+[[autodoc]] LlamaForCausalLM
+ - forward
+
+## LlamaForSequenceClassification
+
+[[autodoc]] LlamaForSequenceClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llama3.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llama3.md
new file mode 100644
index 0000000000000000000000000000000000000000..f5587a0fb078bf9945f0287a89b13f2c2241462f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llama3.md
@@ -0,0 +1,90 @@
+
+*This model was released on 2024-04-18 and added to Hugging Face Transformers on 2024-04-24.*
+
+# Llama3
+
+
+
+
+
+
+
+```py3
+import transformers
+import torch
+
+model_id = "meta-llama/Meta-Llama-3-8B"
+
+pipeline = transformers.pipeline("text-generation", model=model_id, model_kwargs={"torch_dtype": torch.bfloat16}, device_map="auto")
+pipeline("Hey how are you doing today?")
+```
+
+## Overview
+
+The [Llama3](https://huggingface.co/papers/2407.21783) model was proposed in [Introducing Meta Llama 3: The most capable openly available LLM to date](https://ai.meta.com/blog/meta-llama-3/) by the meta AI team.
+
+The abstract from the blogpost is the following:
+
+*Today, we’re excited to share the first two models of the next generation of Llama, Meta Llama 3, available for broad use. This release features pretrained and instruction-fine-tuned language models with 8B and 70B parameters that can support a broad range of use cases. This next generation of Llama demonstrates state-of-the-art performance on a wide range of industry benchmarks and offers new capabilities, including improved reasoning. We believe these are the best open source models of their class, period. In support of our longstanding open approach, we’re putting Llama 3 in the hands of the community. We want to kickstart the next wave of innovation in AI across the stack—from applications to developer tools to evals to inference optimizations and more. We can’t wait to see what you build and look forward to your feedback.*
+
+Checkout all Llama3 model checkpoints [here](https://huggingface.co/models?search=llama3).
+The original code of the authors can be found [here](https://github.com/meta-llama/llama3).
+
+## Usage tips
+
+
+
+The `Llama3` models were trained using `bfloat16`, but the original inference uses `float16`. The checkpoints uploaded on the Hub use `torch_dtype = 'float16'`, which will be
+used by the `AutoModel` API to cast the checkpoints from `torch.float32` to `torch.float16`.
+
+The `dtype` of the online weights is mostly irrelevant unless you are using `torch_dtype="auto"` when initializing a model using `model = AutoModelForCausalLM.from_pretrained("path", torch_dtype = "auto")`. The reason is that the model will first be downloaded ( using the `dtype` of the checkpoints online), then it will be casted to the default `dtype` of `torch` (becomes `torch.float32`), and finally, if there is a `torch_dtype` provided in the config, it will be used.
+
+Training the model in `float16` is not recommended and is known to produce `nan`; as such, the model should be trained in `bfloat16`.
+
+
+
+Tips:
+
+- Weights for the Llama3 models can be obtained by filling out [this form](https://ai.meta.com/resources/models-and-libraries/llama-downloads/)
+- The architecture is exactly the same as Llama2.
+- The tokenizer is a BPE model based on [tiktoken](https://github.com/openai/tiktoken) (vs the one based on sentencepiece implementation for Llama2). The main difference that it ignores BPE merge rules when an input token is part of the vocab. This means that if no merge exist to produce `"hugging"`, instead of having the smallest units, like `["hug","ging"] form 2 tokens, if `"hugging"` is part of the vocab, it will be automatically returned as a token.
+- The original model uses `pad_id = -1` which means that there is no padding token. We can't have the same logic, make sure to add a padding token using `tokenizer.add_special_tokens({"pad_token":""})` and resize the token embedding accordingly. You should also set the `model.config.pad_token_id`. The `embed_tokens` layer of the model is initialized with `self.embed_tokens = nn.Embedding(config.vocab_size, config.hidden_size, self.config.padding_idx)`, which makes sure that encoding the padding token will output zeros, so passing it when initializing is recommended.
+- The original checkpoint can be converted using the [conversion script](https://github.com/huggingface/transformers/blob/main/src/transformers/models/llama/convert_llama_weights_to_hf.py). The script can be called with the following (example) command:
+
+ ```bash
+ python src/transformers/models/llama/convert_llama_weights_to_hf.py \
+ --input_dir /path/to/downloaded/llama/weights --model_size 7B --output_dir /output/path --llama_version 3
+ ```
+
+- After conversion, the model and tokenizer can be loaded via:
+
+ ```python
+ from transformers import AutoModelForCausalLM, AutoTokenizer
+
+ tokenizer = AutoTokenizer.from_pretrained("/output/path")
+ model = AutoModelForCausalLM.from_pretrained("/output/path")
+ ```
+
+ Note that executing the script requires enough CPU RAM to host the whole model in float16 precision (even if the biggest versions
+ come in several checkpoints they each contain a part of each weight of the model, so we need to load them all in RAM). For the 75B model, it's thus 145GB of RAM needed.
+
+- When using Flash Attention 2 via `attn_implementation="flash_attention_2"`, don't pass `torch_dtype` to the `from_pretrained` class method and use Automatic Mixed-Precision training. When using `Trainer`, it is simply specifying either `fp16` or `bf16` to `True`. Otherwise, make sure you are using `torch.autocast`. This is required because the Flash Attention only support `fp16` and `bf16` data type.
+
+## Resources
+
+A ton of cool resources are already available on the documentation page of [Llama2](./llama2), inviting contributors to add new resources curated for Llama3 here! 🤗
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llama4.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llama4.md
new file mode 100644
index 0000000000000000000000000000000000000000..2c21b38078c91ce22cb342ba686078d95a77da54
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llama4.md
@@ -0,0 +1,444 @@
+
+*This model was released on 2025-04-05 and added to Hugging Face Transformers on 2025-04-05.*
+
+# Llama4
+
+
+
+
+
+
+
+
+
+
+[Llama 4](https://ai.meta.com/blog/llama-4-multimodal-intelligence/), developed by Meta, introduces a new auto-regressive Mixture-of-Experts (MoE) architecture.
+This generation includes two models:
+- The highly capable Llama 4 Maverick with 17B active parameters out of ~400B total, with 128 experts.
+- The efficient Llama 4 Scout also has 17B active parameters out of ~109B total, using just 16 experts.
+-
+Both models leverage early fusion for native multimodality, enabling them to process text and image inputs.
+Maverick and Scout are both trained on up to 40 trillion tokens on data encompassing 200 languages
+(with specific fine-tuning support for 12 languages including Arabic, Spanish, German, and Hindi).
+
+For deployment, Llama 4 Scout is designed for accessibility, fitting on a single server-grade GPU via
+on-the-fly 4-bit or 8-bitint4 quantization, while Maverick is available in BF16 and FP8 formats.
+These models are released under the custom Llama 4 Community License Agreement, available on the model repositories.
+
+You can find all the original Llama checkpoints under the [meta-llama](https://huggingface.co/meta-llama) organization.
+
+> [!TIP]
+> The Llama 4 family of models comes in two flavors: 109B, and 402B parameters. Both of these flavors are extremely
+> large and won't fit on your run-of-the-mill device. See below for some examples to reduce the memory usage of the
+> model.
+>
+> For the download to be faster and more resilient, we recommend installing the `hf_xet` dependency as followed:
+> `pip install transformers[hf_xet]`
+
+The examples below demonstrates how to generate with [`Pipeline`] or the [`AutoModel`]. We additionally add an example
+showcasing how to toggle the right attributes to enable very long-context generations, as some flavors of Llama 4
+have context lengths going up to 10 million tokens.
+
+
+
+
+
+```py
+from transformers import pipeline
+import torch
+
+model_id = "meta-llama/Llama-4-Scout-17B-16E-Instruct"
+
+messages = [
+ {"role": "user", "content": "what is the recipe of mayonnaise?"},
+]
+
+pipe = pipeline(
+ "text-generation",
+ model=model_id,
+ device_map="auto",
+ torch_dtype=torch.bfloat16
+)
+
+output = pipe(messages, do_sample=False, max_new_tokens=200)
+print(output[0]["generated_text"][-1]["content"])
+```
+
+
+
+
+```py
+from transformers import AutoTokenizer, Llama4ForConditionalGeneration
+import torch
+
+model_id = "meta-llama/Llama-4-Scout-17B-16E-Instruct"
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+
+messages = [
+ {"role": "user", "content": "Who are you?"},
+]
+inputs = tokenizer.apply_chat_template(messages, add_generation_prompt=True, return_tensors="pt", return_dict=True)
+
+model = Llama4ForConditionalGeneration.from_pretrained(
+ model_id,
+ device_map="auto",
+ torch_dtype=torch.bfloat16
+)
+
+outputs = model.generate(**inputs.to(model.device), max_new_tokens=100)
+outputs = tokenizer.batch_decode(outputs[:, inputs["input_ids"].shape[-1]:])
+print(outputs[0])
+```
+
+
+
+
+```py
+from transformers import AutoProcessor, Llama4ForConditionalGeneration
+import torch
+
+model_id = "meta-llama/Llama-4-Scout-17B-16E-Instruct"
+
+processor = AutoProcessor.from_pretrained(model_id)
+model = Llama4ForConditionalGeneration.from_pretrained(
+ model_id,
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+)
+
+img_url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/0052a70beed5bf71b92610a43a52df6d286cd5f3/diffusers/rabbit.jpg"
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": img_url},
+ {"type": "text", "text": "Describe this image in two sentences."},
+ ]
+ },
+]
+
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+outputs = model.generate(
+ **inputs,
+ max_new_tokens=256,
+)
+
+response = processor.batch_decode(outputs[:, inputs["input_ids"].shape[-1]:])[0]
+print(response)
+```
+
+
+
+
+```py
+from transformers import AutoProcessor, Llama4ForConditionalGeneration
+import torch
+
+model_id = "meta-llama/Llama-4-Scout-17B-16E-Instruct"
+
+processor = AutoProcessor.from_pretrained(model_id)
+model = Llama4ForConditionalGeneration.from_pretrained(
+ model_id,
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+)
+
+url1 = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/0052a70beed5bf71b92610a43a52df6d286cd5f3/diffusers/rabbit.jpg"
+url2 = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/datasets/cat_style_layout.png"
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": url1},
+ {"type": "image", "url": url2},
+ {"type": "text", "text": "Can you describe how these two images are similar, and how they differ?"},
+ ]
+ },
+]
+
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device)
+
+outputs = model.generate(
+ **inputs,
+ max_new_tokens=256,
+)
+
+response = processor.batch_decode(outputs[:, inputs["input_ids"].shape[-1]:])[0]
+print(response)
+```
+
+
+
+
+Beware: the example below uses both `device_map="auto"` and flex-attention.
+Please use `torchrun` to run this example in tensor-parallel mode.
+
+We will work to enable running with `device_map="auto"` and flex-attention without
+tensor-parallel in the future.
+
+```py
+from transformers import Llama4ForConditionalGeneration, AutoTokenizer
+import torch
+import time
+
+file = "very_long_context_prompt.txt"
+model_id = "meta-llama/Llama-4-Scout-17B-16E-Instruct"
+
+with open(file, "r") as f:
+ very_long_text = "\n".join(f.readlines())
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+model = Llama4ForConditionalGeneration.from_pretrained(
+ model_id,
+ device_map="auto",
+ attn_implementation="flex_attention",
+ torch_dtype=torch.bfloat16
+)
+
+messages = [
+ {"role": "user", "content": f"Look at the following texts: [{very_long_text}]\n\n\n\nWhat are the books, and who wrote them? Make me a nice list."},
+]
+input_ids = tokenizer.apply_chat_template(messages, add_generation_prompt=True, return_tensors="pt")
+
+torch.cuda.synchronize()
+start = time.time()
+out = model.generate(
+ input_ids.to(model.device),
+ prefill_chunk_size=2048*8,
+ max_new_tokens=300,
+ cache_implementation="hybrid",
+)
+print(time.time()-start)
+print(tokenizer.batch_decode(out[:, input_ids.shape[-1]:]))
+print(f"{torch.cuda.max_memory_allocated(model.device) / 1024**3:.2f} GiB")
+```
+
+
+
+
+## Efficiency; how to get the best out of llama 4
+
+### The Attention methods
+
+Updating the default attention function can significantly improve compute performance as well as memory usage. Refer to the [Attention Interface](../attention_interface) overview for an in-depth explanation of our interface.
+
+As of release, the Llama 4 model supports the following attention methods: `eager`, `flex_attention`, `sdpa`. We recommend using `flex_attention` for best results.
+Switching attention mechanism is done at the model initialization step:
+
+
+
+
+
+Setting Flex Attention ensures the best results with the very long context the model can handle.
+
+> [!TIP] Beware: the example below uses both `device_map="auto"` and flex-attention.
+> Please use `torchrun` to run this example in tensor-parallel mode.
+>
+> We will work to enable running with `device_map="auto"` and flex-attention without
+> tensor-parallel in the future.
+
+```py
+from transformers import Llama4ForConditionalGeneration
+import torch
+
+model = Llama4ForConditionalGeneration.from_pretrained(
+ model_id,
+ attn_implementation="flex_attention",
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+)
+```
+
+
+The `sdpa` attention method is generally more compute-efficient than the `eager` method.
+
+```py
+from transformers import Llama4ForConditionalGeneration
+import torch
+
+model = Llama4ForConditionalGeneration.from_pretrained(
+ model_id,
+ attn_implementation="sdpa",
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+)
+```
+
+
+The `eager` attention method is set by default, so no need for anything different when loading the model:
+
+```py
+from transformers import Llama4ForConditionalGeneration
+import torch
+
+model = Llama4ForConditionalGeneration.from_pretrained(
+ model_id,
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+)
+```
+
+
+
+
+### Quantization
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for available quantization backends.
+At time of release, both FBGEMM and LLM-Compressor are supported; more quantization methods will be supported in the days that follow the release.
+
+See below for examples using both:
+
+
+
+Here is an example loading an BF16 model in FP8 using the FBGEMM approach:
+
+
+
+
+```python
+from transformers import AutoTokenizer, Llama4ForConditionalGeneration, FbgemmFp8Config
+import torch
+
+model_id = "meta-llama/Llama-4-Scout-17B-16E-Instruct"
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+
+messages = [
+ {"role": "user", "content": "Who are you?"},
+]
+inputs = tokenizer.apply_chat_template(messages, add_generation_prompt=True, return_tensors="pt", return_dict=True)
+
+model = Llama4ForConditionalGeneration.from_pretrained(
+ model_id,
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+ quantization_config=FbgemmFp8Config()
+)
+
+outputs = model.generate(**inputs.to(model.device), max_new_tokens=100)
+outputs = tokenizer.batch_decode(outputs[:, inputs["input_ids"].shape[-1]:])
+print(outputs[0])
+```
+
+
+
+
+To use the LLM-Compressor technique, we recommend leveraging the pre-quantized FP8 checkpoint available with the release:
+
+```python
+from transformers import AutoTokenizer, Llama4ForConditionalGeneration
+import torch
+
+model_id = "meta-llama/Llama-4-Maverick-17B-128E-Instruct-FP8"
+
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+
+messages = [
+ {"role": "user", "content": "Who are you?"},
+]
+inputs = tokenizer.apply_chat_template(messages, add_generation_prompt=True, return_tensors="pt", return_dict=True)
+
+model = Llama4ForConditionalGeneration.from_pretrained(
+ model_id,
+ tp_plan="auto",
+ torch_dtype=torch.bfloat16,
+)
+
+outputs = model.generate(**inputs.to(model.device), max_new_tokens=100)
+outputs = tokenizer.batch_decode(outputs[:, inputs["input_ids"].shape[-1]:])
+print(outputs[0])
+```
+
+
+
+### Offloading
+
+Enabling CPU-offloading means that components of the model might be moved to CPU instead of GPU in case the GPU-memory available isn't sufficient to load the entire model.
+At inference, different components will be loaded/unloaded from/to the GPU on the fly. This ensures that the model can be loaded on smaller machines as long as the CPU-memory is sufficient.
+However, this also slows down inference as it adds communication overhead.
+
+In order to enable CPU-offloading, you simply need to specify the `device_map` to `auto` at model load:
+
+```py
+from transformers import Llama4ForConditionalGeneration
+import torch
+
+model = Llama4ForConditionalGeneration.from_pretrained(
+ model_id,
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+)
+```
+
+## Llama4Config
+
+[[autodoc]] Llama4Config
+
+## Llama4TextConfig
+
+[[autodoc]] Llama4TextConfig
+
+## Llama4VisionConfig
+
+[[autodoc]] Llama4VisionConfig
+
+## Llama4Processor
+
+[[autodoc]] Llama4Processor
+
+## Llama4ImageProcessorFast
+
+[[autodoc]] Llama4ImageProcessorFast
+
+## Llama4ForConditionalGeneration
+
+[[autodoc]] Llama4ForConditionalGeneration
+- forward
+
+## Llama4ForCausalLM
+
+[[autodoc]] Llama4ForCausalLM
+- forward
+
+## Llama4TextModel
+
+[[autodoc]] Llama4TextModel
+- forward
+
+## Llama4ForCausalLM
+
+[[autodoc]] Llama4ForCausalLM
+- forward
+
+## Llama4VisionModel
+
+[[autodoc]] Llama4VisionModel
+- forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llava.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llava.md
new file mode 100644
index 0000000000000000000000000000000000000000..4748a88154c1842e827314e2ff74f258c0d65346
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llava.md
@@ -0,0 +1,267 @@
+
+*This model was released on 2023-04-17 and added to Hugging Face Transformers on 2023-12-07.*
+
+# LLaVa
+
+
+
+
+
+
+
+## Overview
+
+LLaVa is an open-source chatbot trained by fine-tuning LlamA/Vicuna on GPT-generated multimodal instruction-following data. It is an auto-regressive language model, based on the transformer architecture. In other words, it is an multi-modal version of LLMs fine-tuned for chat / instructions.
+
+The LLaVa model was proposed in [Visual Instruction Tuning](https://huggingface.co/papers/2304.08485) and improved in [Improved Baselines with Visual Instruction Tuning](https://huggingface.co/papers/2310.03744) by Haotian Liu, Chunyuan Li, Yuheng Li and Yong Jae Lee.
+
+The abstract from the paper is the following:
+
+*Large multimodal models (LMM) have recently shown encouraging progress with visual instruction tuning. In this note, we show that the fully-connected vision-language cross-modal connector in LLaVA is surprisingly powerful and data-efficient. With simple modifications to LLaVA, namely, using CLIP-ViT-L-336px with an MLP projection and adding academic-task-oriented VQA data with simple response formatting prompts, we establish stronger baselines that achieve state-of-the-art across 11 benchmarks. Our final 13B checkpoint uses merely 1.2M publicly available data, and finishes full training in ∼1 day on a single 8-A100 node. We hope this can make state-of-the-art LMM research more accessible. Code and model will be publicly available*
+
+
+
+ LLaVa architecture. Taken from the original paper.
+
+This model was contributed by [ArthurZ](https://huggingface.co/ArthurZ) and [ybelkada](https://huggingface.co/ybelkada).
+The original code can be found [here](https://github.com/haotian-liu/LLaVA/tree/main/llava).
+
+## Usage tips
+
+- We advise users to use `padding_side="left"` when computing batched generation as it leads to more accurate results. Simply make sure to call `processor.tokenizer.padding_side = "left"` before generating.
+
+- Note the model has not been explicitly trained to process multiple images in the same prompt, although this is technically possible, you may experience inaccurate results.
+
+
+> [!NOTE]
+> LLaVA models after release v4.46 will raise warnings about adding `processor.patch_size = {{patch_size}}`, `processor.num_additional_image_tokens = {{num_additional_image_tokens}}` and processor.vision_feature_select_strategy = {{vision_feature_select_strategy}}`. It is strongly recommended to add the attributes to the processor if you own the model checkpoint, or open a PR if it is not owned by you.
+Adding these attributes means that LLaVA will try to infer the number of image tokens required per image and expand the text with as many `` placeholders as there will be tokens. Usually it is around 500 tokens per image, so make sure that the text is not truncated as otherwise there will be failure when merging the embeddings.
+The attributes can be obtained from model config, as `model.config.vision_config.patch_size` or `model.config.vision_feature_select_strategy`. The `num_additional_image_tokens` should be `1` if the vision backbone adds a CLS token or `0` if nothing extra is added to the vision patches.
+
+
+### Formatting Prompts with Chat Templates
+
+Each **checkpoint** is trained with a specific prompt format, depending on the underlying large language model backbone. To ensure correct formatting, use the processor’s `apply_chat_template` method.
+
+**Important:**
+- You must construct a conversation history — passing a plain string won't work.
+- Each message should be a dictionary with `"role"` and `"content"` keys.
+- The `"content"` should be a list of dictionaries for different modalities like `"text"` and `"image"`.
+
+
+Here’s an example of how to structure your input.
+We will use [llava-hf/llava-1.5-7b-hf](https://huggingface.co/llava-hf/llava-1.5-7b-hf) and a conversation history of text and image. Each content field has to be a list of dicts, as follows:
+
+
+```python
+from transformers import AutoProcessor
+
+processor = AutoProcessor.from_pretrained("llava-hf/llava-1.5-7b-hf")
+
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What’s shown in this image?"},
+ ],
+ },
+ {
+ "role": "assistant",
+ "content": [{"type": "text", "text": "This image shows a red stop sign."},]
+ },
+ {
+
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Describe the image in more details."},
+ ],
+ },
+]
+
+text_prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+
+# Note that the template simply formats your prompt, you still have to tokenize it and obtain pixel values for your images
+print(text_prompt)
+>>> "USER: \nUSER: Describe the image in more details. ASSISTANT:"
+```
+
+- If you want to construct a chat prompt yourself, below is a list of prompt formats accepted by each llava checkpoint:
+
+[llava-interleave models](https://huggingface.co/collections/llava-hf/llava-interleave-668e19a97da0036aad4a2f19) requires the following format:
+```bash
+"<|im_start|>user \nWhat is shown in this image?<|im_end|><|im_start|>assistant"
+```
+
+For multiple turns conversation:
+
+```bash
+"<|im_start|>user \n<|im_end|><|im_start|>assistant <|im_end|><|im_start|>user \n<|im_end|><|im_start|>assistant "
+```
+
+[llava-1.5 models](https://huggingface.co/collections/llava-hf/llava-15-65f762d5b6941db5c2ba07e0) requires the following format:
+```bash
+"USER: \n ASSISTANT:"
+```
+
+For multiple turns conversation:
+
+```bash
+"USER: \n ASSISTANT: USER: ASSISTANT: USER: ASSISTANT:"
+```
+
+🚀 **Bonus:** If you're using `transformers>=4.49.0`, you can also get a vectorized output from `apply_chat_template`. See the **Usage Examples** below for more details on how to use it.
+
+
+## Usage examples
+
+### Single input inference
+
+
+```python
+import torch
+from transformers import AutoProcessor, LlavaForConditionalGeneration
+
+# Load the model in half-precision
+model = LlavaForConditionalGeneration.from_pretrained("llava-hf/llava-1.5-7b-hf", torch_dtype=torch.float16, device_map="auto")
+processor = AutoProcessor.from_pretrained("llava-hf/llava-1.5-7b-hf")
+
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "https://www.ilankelman.org/stopsigns/australia.jpg"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+]
+
+inputs = processor.apply_chat_template(
+ conversation,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+).to(model.device, torch.float16)
+
+# Generate
+generate_ids = model.generate(**inputs, max_new_tokens=30)
+processor.batch_decode(generate_ids, skip_special_tokens=True)
+```
+
+
+### Batched inference
+
+LLaVa also supports batched inference. Here is how you can do it:
+
+```python
+import torch
+from transformers import AutoProcessor, LlavaForConditionalGeneration
+
+# Load the model in half-precision
+model = LlavaForConditionalGeneration.from_pretrained("llava-hf/llava-1.5-7b-hf", torch_dtype=torch.float16, device_map="auto")
+processor = AutoProcessor.from_pretrained("llava-hf/llava-1.5-7b-hf")
+
+
+# Prepare a batch of two prompts
+conversation_1 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "https://www.ilankelman.org/stopsigns/australia.jpg"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+]
+
+conversation_2 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "http://images.cocodataset.org/val2017/000000039769.jpg"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+]
+
+inputs = processor.apply_chat_template(
+ [conversation_1, conversation_2],
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ padding=True,
+ return_tensors="pt"
+).to(model.device, torch.float16)
+
+
+# Generate
+generate_ids = model.generate(**inputs, max_new_tokens=30)
+processor.batch_decode(generate_ids, skip_special_tokens=True)
+```
+
+
+## Note regarding reproducing original implementation
+
+In order to match the logits of the [original implementation](https://github.com/haotian-liu/LLaVA/tree/main), one needs to additionally specify `do_pad=True` when instantiating `LlavaImageProcessor`:
+
+```python
+from transformers import LlavaImageProcessor
+
+image_processor = LlavaImageProcessor.from_pretrained("llava-hf/llava-1.5-7b-hf", do_pad=True)
+```
+
+### Using Flash Attention 2
+
+Flash Attention 2 is an even faster, optimized version of the previous optimization, please refer to the [Flash Attention 2 section of performance docs](https://huggingface.co/docs/transformers/perf_infer_gpu_one).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with BEiT.
+
+
+
+- A [Google Colab demo](https://colab.research.google.com/drive/1qsl6cd2c8gGtEW1xV5io7S8NHh-Cp1TV?usp=sharing) on how to run Llava on a free-tier Google colab instance leveraging 4-bit inference.
+- A [similar notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/LLaVa/Inference_with_LLaVa_for_multimodal_generation.ipynb) showcasing batched inference. 🌎
+
+
+## LlavaConfig
+
+[[autodoc]] LlavaConfig
+
+## LlavaImageProcessor
+
+[[autodoc]] LlavaImageProcessor
+ - preprocess
+
+## LlavaImageProcessorFast
+
+[[autodoc]] LlavaImageProcessorFast
+ - preprocess
+
+## LlavaProcessor
+
+[[autodoc]] LlavaProcessor
+
+## LlavaModel
+
+[[autodoc]] LlavaModel
+
+## LlavaForConditionalGeneration
+
+[[autodoc]] LlavaForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llava_next.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llava_next.md
new file mode 100644
index 0000000000000000000000000000000000000000..f6ca89fde44a2230e457c31bb26293e483879f0d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llava_next.md
@@ -0,0 +1,218 @@
+
+*This model was released on 2024-01-30 and added to Hugging Face Transformers on 2024-03-20.*
+
+
+
+
+
+
+
+
+
+# LLaVA-NeXT
+
+[LLaVA‑NeXT](https://llava-vl.github.io/blog/2024-01-30-llava-next/) improves on [Llava](./llava) by increasing the input image resolution by 4x more pixels and supporting 3 aspect ratios (up to 672x672, 336x1344, 1344x336) to better grasp visual details. It is also trained on an improved visual instruction tuning dataset covering more scenarios and applications to improve OCR and common sense reasoning.
+
+You can find all the original LLaVA‑NeXT checkpoints under the [LLaVA-NeXT](https://huggingface.co/collections/llava-hf/llava-next-65f75c4afac77fd37dbbe6cf) collection.
+
+> [!TIP]
+> This model was contributed by [nielsr](https://huggingface.co/nielsr).
+>
+> Click on the LLaVA‑NeXT models in the right sidebar for more examples of how to apply Llava-NeXT to different multimodal tasks.
+
+The example below demonstrates how to generate text based on an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+
+```python
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="image-text-to-text",
+ model="llava-hf/llava-v1.6-mistral-7b-hf",
+ device=0,
+ torch_dtype=torch.bfloat16
+)
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {
+ "type": "image",
+ "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg",
+ },
+ { "type": "text", "text": "Describe this image."},
+ ]
+ }
+]
+pipeline(text=messages, max_new_tokens=20, return_full_text=False)
+```
+
+
+
+
+
+```python
+import torch
+import requests
+from PIL import Image
+from transformers import AutoProcessor, LlavaNextForConditionalGeneration, infer_device
+
+device = infer_device()
+
+processor = AutoProcessor.from_pretrained("llava-hf/llava-v1.6-mistral-7b-hf")
+model = LlavaNextForConditionalGeneration.from_pretrained("llava-hf/llava-v1.6-mistral-7b-hf", torch_dtype=torch.float16).to(device)
+
+url = "https://github.com/haotian-liu/LLaVA/blob/1a91fc274d7c35a9b50b3cb29c4247ae5837ce39/images/llava_v1_5_radar.jpg?raw=true"
+image = Image.open(requests.get(url, stream=True).raw)
+
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+]
+prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+inputs = processor(image, prompt, return_tensors="pt").to(model.device)
+output = model.generate(**inputs, max_new_tokens=100)
+print(processor.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to int4.
+
+```python
+import torch
+import requests
+from PIL import Image
+from transformers import AutoModelForImageTextToText, AutoProcessor, BitsAndBytesConfig
+
+quant_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_compute_dtype=torch.float16,
+ bnb_4bit_quant_type="nf4"
+)
+
+processor = AutoProcessor.from_pretrained("llava-hf/llava-v1.6-mistral-7b-hf")
+model = AutoModelForImageTextToText.from_pretrained("llava-hf/llava-v1.6-mistral-7b-hf", quantization_config=quant_config, device_map="auto")
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/model_doc/llava_next_ocr.png"
+image = Image.open(requests.get(url, stream=True).raw)
+
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What does this chart show?"},
+ ],
+ },
+]
+prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+inputs = processor(image, prompt, return_tensors="pt").to(model.device)
+
+with torch.inference_mode():
+ output = model.generate(**inputs, max_new_tokens=100)
+print(processor.decode(output[0], skip_special_tokens=True))
+```
+
+
+## Notes
+
+* Different checkpoints (Mistral, Vicuna, etc.) require a specific prompt format depending on the underlying LLM. Always use [`~ProcessorMixin.apply_chat_template`] to ensure correct formatting. Refer to the [Templates](../chat_templating) guide for more details.
+
+* Set `padding_side="left"` during batched generation for more accurate results.
+
+```py
+processor.tokenizer.padding_side = "left"
+```
+
+* LLaVA-NeXT uses different numbers of patches for images and pads the inputs inside the modeling code except when padding is done during processing. The default setting is *left-padding* if the model is in `eval()` mode, otherwise it is *right-padding*.
+
+* LLaVA models after v4.46 raises warnings about adding `processor.patch_size = {{patch_size}}`, `processor.num_additional_image_tokens = {{num_additional_image_tokens}}`, and `processor.vision_feature_select_strategy = {{vision_feature_select_strategy}}`. It is strongly recommended to add these attributes to the processor if you own the model checkpoint or open a PR if it isn't.
+
+ Adding these attributes means LLaVA will try to infer the number of image tokens required per image and expand the text with the same number of `` token placeholders. There are usually ~500 tokens per image, so make sure the text is not truncated because it will cause a failure when merging the embeddings. The attributes can be found in `model.config.vision_config.patch_size` or `model.config.vision_feature_select_strategy`.
+
+ The `num_additional_image_tokens` should be `1` if the vision backbone adds a `CLS` token or `0` if nothing extra is added.
+
+* The example below demonstrates inference with multiple input images.
+
+```python
+from transformers import LlavaNextProcessor, LlavaNextForConditionalGeneration
+from PIL import Image
+import requests, torch
+
+processor = LlavaNextProcessor.from_pretrained("llava-hf/llava-v1.6-mistral-7b-hf")
+model = LlavaNextForConditionalGeneration.from_pretrained(
+ "llava-hf/llava-v1.6-mistral-7b-hf", torch_dtype=torch.float16, device_map="auto"
+)
+
+# Load multiple images
+url1 = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/model_doc/llava_next_ocr.png"
+url2 = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/model_doc/llava_next_comparison.png"
+
+image1 = Image.open(requests.get(url1, stream=True).raw)
+image2 = Image.open(requests.get(url2, stream=True).raw)
+
+conversation = [
+ {"role": "user", "content": [{"type": "image"}, {"type": "image"}, {"type": "text", "text": "Compare these two images and describe the differences."}]}
+]
+prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+inputs = processor([image1, image2], prompt, return_tensors="pt").to(model.device)
+
+output = model.generate(**inputs, max_new_tokens=100)
+print(processor.decode(output[0], skip_special_tokens=True))
+```
+
+
+## LlavaNextConfig
+
+[[autodoc]] LlavaNextConfig
+
+## LlavaNextImageProcessor
+
+[[autodoc]] LlavaNextImageProcessor
+ - preprocess
+
+## LlavaNextImageProcessorFast
+
+[[autodoc]] LlavaNextImageProcessorFast
+ - preprocess
+
+## LlavaNextProcessor
+
+[[autodoc]] LlavaNextProcessor
+
+## LlavaNextModel
+
+[[autodoc]] LlavaNextModel
+
+## LlavaNextForConditionalGeneration
+
+[[autodoc]] LlavaNextForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llava_next_video.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llava_next_video.md
new file mode 100644
index 0000000000000000000000000000000000000000..15438ae496a6e21f9556da0b9faecf142ef3df74
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llava_next_video.md
@@ -0,0 +1,277 @@
+
+*This model was released on 2024-05-31 and added to Hugging Face Transformers on 2024-06-26.*
+
+# LLaVa-NeXT-Video
+
+
+
+
+
+
+
+## Overview
+
+The LLaVa-NeXT-Video model was proposed in [LLaVA-NeXT: A Strong Zero-shot Video Understanding Model
+](https://llava-vl.github.io/blog/2024-04-30-llava-next-video/) by Yuanhan Zhang, Bo Li, Haotian Liu, Yong Jae Lee, Liangke Gui, Di Fu, Jiashi Feng, Ziwei Liu, Chunyuan Li. LLaVa-NeXT-Video improves upon [LLaVa-NeXT](llava_next) by fine-tuning on a mix if video and image dataset thus increasing the model's performance on videos.
+
+[LLaVA-NeXT](llava_next) surprisingly has strong performance in understanding video content in zero-shot fashion with the AnyRes technique that it uses. The AnyRes technique naturally represents a high-resolution image into multiple images. This technique is naturally generalizable to represent videos because videos can be considered as a set of frames (similar to a set of images in LLaVa-NeXT). The current version of LLaVA-NeXT makes use of AnyRes and trains with supervised fine-tuning (SFT) on top of LLaVA-Next on video data to achieves better video understanding capabilities.The model is a current SOTA among open-source models on [VideoMME bench](https://huggingface.co/papers/2405.21075).
+
+
+The introduction from the blog is the following:
+
+On January 30, 2024, we released LLaVA-NeXT, an open-source Large Multimodal Model (LMM) that has been trained exclusively on text-image data. With the proposed AnyRes technique, it boosts capabilities in reasoning, OCR, and world knowledge, demonstrating remarkable performance across a spectrum of image-based multimodal understanding tasks, and even exceeding Gemini-Pro on several image benchmarks, e.g. MMMU and MathVista.
+
+**In today’s exploration, we delve into the performance of LLaVA-NeXT within the realm of video understanding tasks. We reveal that LLaVA-NeXT surprisingly has strong performance in understanding video content. The current version of LLaVA-NeXT for videos has several improvements:
+
+- Zero-shot video representation capabilities with AnyRes: The AnyRes technique naturally represents a high-resolution image into multiple images that a pre-trained VIT is able to digest, and forms them into a concatenated sequence. This technique is naturally generalizable to represent videos (consisting of multiple frames), allowing the image-only-trained LLaVA-Next model to perform surprisingly well on video tasks. Notably, this is the first time that LMMs show strong zero-shot modality transfer ability.
+- Inference with length generalization improves on longer videos. The linear scaling technique enables length generalization, allowing LLaVA-NeXT to effectively handle long-video beyond the limitation of the "max_token_length" of the LLM.
+- Strong video understanding ability. (1) LLaVA-Next-Image, which combines the above two techniques, yields superior zero-shot performance than open-source LMMs tuned on videos. (2) LLaVA-Next-Video, further supervised fine-tuning (SFT) LLaVA-Next-Image on video data, achieves better video understanding capabilities compared to LLaVA-Next-Image. (3) LLaVA-Next-Video-DPO, which aligns the model response with AI feedback using direct preference optimization (DPO), showing significant performance boost.
+- Efficient deployment and inference with SGLang. It allows 5x faster inference on video tasks, allowing more scalable serving such as million-level video re-captioning. See instructions in our repo.**
+
+
+This model was contributed by [RaushanTurganbay](https://huggingface.co/RaushanTurganbay).
+The original code can be found [here](https://github.com/LLaVA-VL/LLaVA-NeXT/tree/inference).
+
+## Usage tips
+
+- We advise users to use `padding_side="left"` when computing batched generation as it leads to more accurate results. Simply make sure to call `processor.tokenizer.padding_side = "left"` before generating.
+
+
+
+- Llava-Next uses different number of patches for images and thus has to pad the inputs inside modeling code, aside from the padding done when processing the inputs. The default setting is "left-padding" if model is in `eval()` mode, otherwise "right-padding".
+
+
+
+
+> [!NOTE]
+> LLaVA models after release v4.46 will raise warnings about adding `processor.patch_size = {{patch_size}}`, `processor.num_additional_image_tokens = {{num_additional_image_tokens}}` and processor.vision_feature_select_strategy = {{vision_feature_select_strategy}}`. It is strongly recommended to add the attributes to the processor if you own the model checkpoint, or open a PR if it is not owned by you.
+Adding these attributes means that LLaVA will try to infer the number of image tokens required per image and expand the text with as many `` placeholders as there will be tokens. Usually it is around 500 tokens per image, so make sure that the text is not truncated as otherwise there will be failure when merging the embeddings.
+The attributes can be obtained from model config, as `model.config.vision_config.patch_size` or `model.config.vision_feature_select_strategy`. The `num_additional_image_tokens` should be `1` if the vision backbone adds a CLS token or `0` if nothing extra is added to the vision patches.
+
+
+### Formatting Prompts with Chat Templates
+
+Each **checkpoint** is trained with a specific prompt format, depending on the underlying large language model backbone. To ensure correct formatting, use the processor’s `apply_chat_template` method.
+
+**Important:**
+- You must construct a conversation history — passing a plain string won't work.
+- Each message should be a dictionary with `"role"` and `"content"` keys.
+- The `"content"` should be a list of dictionaries for different modalities like `"text"` and `"image"`.
+
+
+Here’s an example of how to structure your input. We will use [LLaVA-NeXT-Video-7B-hf](https://huggingface.co/llava-hf/LLaVA-NeXT-Video-7B-hf) and a conversation history of videos and images.
+
+```python
+from transformers import LlavaNextVideoProcessor
+
+processor = LlavaNextVideoProcessor.from_pretrained("llava-hf/LLaVA-NeXT-Video-7B-hf")
+
+conversation = [
+ {
+ "role": "system",
+ "content": [
+ {"type": "text", "text": "A chat between a curious human and an artificial intelligence assistant. The assistant gives helpful, detailed, and polite answers to the human's questions."},
+ ],
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "What’s shown in this image?"},
+ {"type": "image"},
+ ],
+ },
+ {
+ "role": "assistant",
+ "content": [{"type": "text", "text": "This image shows a red stop sign."},]
+ },
+ {
+
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Why is this video funny?"},
+ {"type": "video"},
+ ],
+ },
+]
+
+text_prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+
+# Note that the template simply formats your prompt, you still have to tokenize it and obtain pixel values for your visuals
+print(text_prompt)
+```
+
+🚀 **Bonus:** If you're using `transformers>=4.49.0`, you can also get a vectorized output from `apply_chat_template`. See the **Usage Examples** below for more details on how to use it.
+
+
+
+## Usage example
+
+### Single Media Mode
+
+The model can accept both images and videos as input. Here's an example code for inference in half-precision (`torch.float16`):
+
+```python
+from huggingface_hub import hf_hub_download
+import torch
+from transformers import LlavaNextVideoForConditionalGeneration, LlavaNextVideoProcessor
+
+# Load the model in half-precision
+model = LlavaNextVideoForConditionalGeneration.from_pretrained("llava-hf/LLaVA-NeXT-Video-7B-hf", torch_dtype=torch.float16, device_map="auto")
+processor = LlavaNextVideoProcessor.from_pretrained("llava-hf/LLaVA-NeXT-Video-7B-hf")
+
+# Load the video as an np.array, sampling uniformly 8 frames (can sample more for longer videos)
+video_path = hf_hub_download(repo_id="raushan-testing-hf/videos-test", filename="sample_demo_1.mp4", repo_type="dataset")
+
+conversation = [
+ {
+
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Why is this video funny?"},
+ {"type": "video", "path": video_path},
+ ],
+ },
+]
+
+inputs = processor.apply_chat_template(conversation, num_frames=8, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt")
+
+out = model.generate(**inputs, max_new_tokens=60)
+processor.batch_decode(out, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+```
+
+
+### Mixed Media Mode
+
+The model can also generate from an interleaved image-video inputs. However note, that it was not trained in interleaved image-video setting which might affect the performance. Below is an example usage for mixed media input, add the following lines to the above code snippet:
+
+```python
+
+# Generate from image and video mixed inputs
+conversation = [
+ {
+
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "How many cats are there in the image?"},
+ {"type": "image", "url": "http://images.cocodataset.org/val2017/000000039769.jpg"},
+ ],
+ },
+ {
+
+ "role": "assistant",
+ "content": [{"type": "text", "text": "There are two cats"}],
+ },
+ {
+
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Why is this video funny?"},
+ {"type": "video", "path": video_path},
+ ],
+ },
+]
+inputs = processor.apply_chat_template(conversation, num_frames=8, add_generation_prompt=True, tokenize=True, return_dict=True, padding=True, return_tensors="pt")
+
+# Generate
+generate_ids = model.generate(**inputs, max_length=50)
+processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+
+```
+
+## Model optimization
+
+### Quantization using Bitsandbytes for memory efficiency
+
+The model can be loaded in lower bits, significantly reducing memory burden while maintaining the performance of the original model. This allows for efficient deployment on resource-constrained cases.
+
+First, make sure to install bitsandbytes by running `pip install bitsandbytes` and to have access to a GPU/accelerator that is supported by the library.
+
+
+
+bitsandbytes is being refactored to support multiple backends beyond CUDA. Currently, ROCm (AMD GPU) and Intel CPU implementations are mature, with Intel XPU in progress and Apple Silicon support expected by Q4/Q1. For installation instructions and the latest backend updates, visit [this link](https://huggingface.co/docs/bitsandbytes/main/en/installation#multi-backend).
+
+We value your feedback to help identify bugs before the full release! Check out [these docs](https://huggingface.co/docs/bitsandbytes/main/en/non_cuda_backends) for more details and feedback links.
+
+
+
+Then simply load the quantized model by adding [`BitsAndBytesConfig`](../main_classes/quantization#transformers.BitsAndBytesConfig) as shown below:
+
+
+```python
+from transformers import LlavaNextVideoForConditionalGeneration, LlavaNextVideoProcessor
+
+# specify how to quantize the model
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_compute_dtype=torch.float16,
+)
+
+model = LlavaNextVideoForConditionalGeneration.from_pretrained("llava-hf/LLaVA-NeXT-Video-7B-hf", quantization_config=quantization_config, device_map="auto")
+```
+
+
+### Flash-Attention 2 to speed-up generation
+
+Additionally, we can greatly speed-up model inference by using [Flash Attention](../perf_train_gpu_one#flash-attention-2), which is a faster implementation of the attention mechanism used inside the model.
+
+First, make sure to install the latest version of Flash Attention 2:
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Also, you should have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of the [flash attention repository](https://github.com/Dao-AILab/flash-attention). FlashAttention-2 can only be used when a model is loaded in `torch.float16` or `torch.bfloat16`.
+
+To load and run a model using Flash Attention-2, simply add `attn_implementation="flash_attention_2"` when loading the model as follows:
+
+```python
+from transformers import LlavaNextVideoForConditionalGeneration
+
+model = LlavaNextVideoForConditionalGeneration.from_pretrained(
+ "llava-hf/LLaVA-NeXT-Video-7B-hf",
+ torch_dtype=torch.float16,
+ attn_implementation="flash_attention_2",
+).to(0)
+```
+
+
+
+## LlavaNextVideoConfig
+
+[[autodoc]] LlavaNextVideoConfig
+
+## LlavaNextVideoProcessor
+
+[[autodoc]] LlavaNextVideoProcessor
+
+## LlavaNextVideoImageProcessor
+
+[[autodoc]] LlavaNextVideoImageProcessor
+
+## LlavaNextVideoVideoProcessor
+
+[[autodoc]] LlavaNextVideoVideoProcessor
+
+## LlavaNextVideoModel
+
+[[autodoc]] LlavaNextVideoModel
+
+## LlavaNextVideoForConditionalGeneration
+
+[[autodoc]] LlavaNextVideoForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llava_onevision.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llava_onevision.md
new file mode 100644
index 0000000000000000000000000000000000000000..ec65f9a5502d78fddb6f15c4a09f0527341d55ac
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llava_onevision.md
@@ -0,0 +1,324 @@
+
+*This model was released on 2024-08-06 and added to Hugging Face Transformers on 2024-09-05.*
+
+# LLaVA-OneVision
+
+
+
+
+
+
+
+## Overview
+
+The LLaVA-OneVision model was proposed in [LLaVA-OneVision: Easy Visual Task Transfer](https://huggingface.co/papers/2408.03326) by
+
+ LLaVA-OneVision architecture. Taken from the original paper.
+
+Tips:
+
+- We advise users to use `padding_side="left"` when computing batched generation as it leads to more accurate results. Simply make sure to call `processor.tokenizer.padding_side = "left"` before generating.
+
+
+
+- Llava-OneVision uses different number of patches for images and thus has to pad the inputs inside modeling code, aside from the padding done when processing the inputs. The default setting is "left-padding" if model is in `eval()` mode, otherwise "right-padding".
+
+
+
+
+### Formatting Prompts with Chat Templates
+
+Each **checkpoint** is trained with a specific prompt format, depending on the underlying large language model backbone. To ensure correct formatting, use the processor’s `apply_chat_template` method.
+
+**Important:**
+- You must construct a conversation history — passing a plain string won't work.
+- Each message should be a dictionary with `"role"` and `"content"` keys.
+- The `"content"` should be a list of dictionaries for different modalities like `"text"` and `"image"`.
+
+
+Here’s an example of how to structure your input.
+We will use [llava-onevision-qwen2-7b-si-hf](https://huggingface.co/llava-hf/llava-onevision-qwen2-7b-si-hf) and a conversation history of text and image. Each content field has to be a list of dicts, as follows:
+
+```python
+from transformers import AutoProcessor
+
+processor = AutoProcessor.from_pretrained("llava-hf/llava-onevision-qwen2-7b-si-hf")
+
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What’s shown in this image?"},
+ ],
+ },
+ {
+ "role": "assistant",
+ "content": [{"type": "text", "text": "This image shows a red stop sign."},]
+ },
+ {
+
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Describe the image in more details."},
+ ],
+ },
+]
+
+text_prompt = processor.apply_chat_template(conversation, add_generation_prompt=True)
+
+# Note that the template simply formats your prompt, you still have to tokenize it and obtain pixel values for your images
+print(text_prompt)
+'<|im_start|>user\nWhat is shown in this image?<|im_end|>\n<|im_start|>assistant\nPage showing the list of options.<|im_end|>'
+```
+
+🚀 **Bonus:** If you're using `transformers>=4.49.0`, you can also get a vectorized output from `apply_chat_template`. See the **Usage Examples** below for more details on how to use it.
+
+
+This model was contributed by [RaushanTurganbay](https://huggingface.co/RaushanTurganbay).
+The original code can be found [here](https://github.com/LLaVA-VL/LLaVA-NeXT/tree/main).
+
+
+## Usage example
+
+### Single image inference
+
+Here's how to load the model and perform inference in half-precision (`torch.float16`):
+
+```python
+from transformers import AutoProcessor, LlavaOnevisionForConditionalGeneration
+import torch
+
+processor = AutoProcessor.from_pretrained("llava-hf/llava-onevision-qwen2-7b-ov-hf")
+model = LlavaOnevisionForConditionalGeneration.from_pretrained(
+ "llava-hf/llava-onevision-qwen2-7b-ov-hf",
+ torch_dtype=torch.float16,
+ device_map="cuda:0"
+)
+
+# prepare image and text prompt, using the appropriate prompt template
+url = "https://github.com/haotian-liu/LLaVA/blob/1a91fc274d7c35a9b50b3cb29c4247ae5837ce39/images/llava_v1_5_radar.jpg?raw=true"
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": url},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+]
+inputs = processor.apply_chat_template(conversation, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt")
+inputs = inputs.to("cuda:0", torch.float16)
+
+# autoregressively complete prompt
+output = model.generate(**inputs, max_new_tokens=100)
+print(processor.decode(output[0], skip_special_tokens=True))
+'user\n\nWhat is shown in this image?\nassistant\nThe image shows a radar chart, also known as a spider chart or a star chart, which is used to compare multiple quantitative variables. Each axis represents a different variable, and the chart is filled with'
+```
+
+### Multi image inference
+
+LLaVa-OneVision can perform inference with multiple images as input, where images either belong to the same prompt or different prompts (in batched inference). For that you have to use checkpoints with an "ov" suffix. For multi-image cases, we recommend using a **nested list of images** as input. Otherwise, every image will be patchified and consume a lot of memory. Here is how you can do it:
+
+```python
+import requests
+from PIL import Image
+import torch
+from transformers import AutoProcessor, LlavaOnevisionForConditionalGeneration
+
+# Load the model in half-precision
+model = LlavaOnevisionForConditionalGeneration.from_pretrained("llava-hf/llava-onevision-qwen2-7b-ov-hf", torch_dtype=torch.float16, device_map="auto")
+processor = AutoProcessor.from_pretrained("llava-hf/llava-onevision-qwen2-7b-ov-hf")
+
+# Prepare a batch of two prompts, where the first one is a multi-turn conversation and the second is not
+conversation_1 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "https://www.ilankelman.org/stopsigns/australia.jpg"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+ {
+ "role": "assistant",
+ "content": [
+ {"type": "text", "text": "There is a red stop sign in the image."},
+ ],
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "http://images.cocodataset.org/val2017/000000039769.jpg"},
+ {"type": "text", "text": "What about this image? How many cats do you see?"},
+ ],
+ },
+]
+
+conversation_2 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/snowman.jpg"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+]
+
+inputs = processor.apply_chat_template(
+ [conversation_1, conversation_2],
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ padding=True,
+ padding_side="left",
+ return_tensors="pt",
+).to(model.device, torch.float16)
+
+# Generate
+generate_ids = model.generate(**inputs, max_new_tokens=30)
+processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)
+['user\n\nWhat is shown in this image?\nassistant\nThere is a red stop sign in the image.\nuser\n\nWhat about this image? How many cats do you see?\nassistant\ntwo', 'user\n\nWhat is shown in this image?\nassistant\nThe image shows a whimsical scene of a snowman sitting by a campfire. The snowman is anthropomorphized, wearing a hat and']
+```
+
+### Video inference
+
+LLaVa-OneVision also can perform inference with videos as input, where video frames are treated as multiple images. Here is how you can do it:
+
+```python
+from huggingface_hub import hf_hub_download
+import torch
+from transformers import AutoProcessor, LlavaOnevisionForConditionalGeneration
+
+# Load the model in half-precision
+model = LlavaOnevisionForConditionalGeneration.from_pretrained("llava-hf/llava-onevision-qwen2-7b-ov-hf", torch_dtype=torch.float16, device_map="auto")
+processor = AutoProcessor.from_pretrained("llava-hf/llava-onevision-qwen2-7b-ov-hf")
+
+video_path = hf_hub_download(repo_id="raushan-testing-hf/videos-test", filename="sample_demo_1.mp4", repo_type="dataset")
+conversation = [
+ {
+
+ "role": "user",
+ "content": [
+ {"type": "video", "path": video_path},
+ {"type": "text", "text": "Why is this video funny?"},
+ ],
+ },
+]
+
+inputs = processor.apply_chat_template(
+ conversation,
+ num_frames=8
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+).to(model.device, torch.float16)
+
+out = model.generate(**inputs, max_new_tokens=60)
+processor.batch_decode(out, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+["user\n\nWhy is this video funny?\nassistant\nThe video appears to be humorous because it shows a young child, who is wearing glasses and holding a book, seemingly reading with a serious and focused expression. The child's glasses are a bit oversized for their face, which adds a comical touch, as it's a common trope to see children wearing"]
+```
+
+## Model optimization
+
+### Quantization using bitsandbytes
+
+The model can be loaded in 8 or 4 bits, greatly reducing the memory requirements while maintaining the performance of the original model. First make sure to install bitsandbytes, `pip install bitsandbytes` and make sure to have access to a GPU/accelerator that is supported by the library.
+
+
+
+bitsandbytes is being refactored to support multiple backends beyond CUDA. Currently, ROCm (AMD GPU) and Intel CPU implementations are mature, with Intel XPU in progress and Apple Silicon support expected by Q4/Q1. For installation instructions and the latest backend updates, visit [this link](https://huggingface.co/docs/bitsandbytes/main/en/installation#multi-backend).
+
+We value your feedback to help identify bugs before the full release! Check out [these docs](https://huggingface.co/docs/bitsandbytes/main/en/non_cuda_backends) for more details and feedback links.
+
+
+
+Simply change the snippet above with:
+
+```python
+from transformers import LlavaOnevisionForConditionalGeneration, BitsAndBytesConfig
+
+# specify how to quantize the model
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_compute_dtype=torch.float16,
+)
+
+model = LlavaOnevisionForConditionalGeneration.from_pretrained(model_id, quantization_config=quantization_config, device_map="auto")
+```
+
+### Use Flash-Attention 2 to further speed-up generation
+
+First make sure to install flash-attn. Refer to the [original repository of Flash Attention](https://github.com/Dao-AILab/flash-attention) regarding that package installation. Simply change the snippet above with:
+
+```python
+from transformers import LlavaOnevisionForConditionalGeneration
+
+model = LlavaOnevisionForConditionalGeneration.from_pretrained(
+ model_id,
+ torch_dtype=torch.float16,
+ use_flash_attention_2=True
+).to(0)
+```
+
+
+## LlavaOnevisionConfig
+
+[[autodoc]] LlavaOnevisionConfig
+
+## LlavaOnevisionProcessor
+
+[[autodoc]] LlavaOnevisionProcessor
+
+## LlavaOnevisionImageProcessor
+
+[[autodoc]] LlavaOnevisionImageProcessor
+ - preprocess
+
+## LlavaOnevisionImageProcessorFast
+
+[[autodoc]] LlavaOnevisionImageProcessorFast
+ - preprocess
+
+## LlavaOnevisionVideoProcessor
+
+[[autodoc]] LlavaOnevisionVideoProcessor
+
+## LlavaOnevisionModel
+
+[[autodoc]] LlavaOnevisionModel
+
+## LlavaOnevisionForConditionalGeneration
+
+[[autodoc]] LlavaOnevisionForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/longformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/longformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..7e0409a6a9f3f859bd447709bc84871f79dbc482
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/longformer.md
@@ -0,0 +1,202 @@
+
+*This model was released on 2020-04-10 and added to Hugging Face Transformers on 2020-11-16.*
+
+
+
+
+
+
+
+
+# Longformer
+
+[Longformer](https://huggingface.co/papers/2004.05150) is a transformer model designed for processing long documents. The self-attention operation usually scales quadratically with sequence length, preventing transformers from processing longer sequences. The Longformer attention mechanism overcomes this by scaling linearly with sequence length. It combines local windowed attention with task-specific global attention, enabling efficient processing of documents with thousands of tokens.
+
+You can find all the original Longformer checkpoints under the [Ai2](https://huggingface.co/allenai?search_models=longformer) organization.
+
+> [!TIP]
+> Click on the Longformer models in the right sidebar for more examples of how to apply Longformer to different language tasks.
+
+The example below demonstrates how to fill the `` token with [`Pipeline`], [`AutoModel`] and from the command line.
+
+
+
+
+```python
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="fill-mask",
+ model="allenai/longformer-base-4096",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("""San Francisco 49ers cornerback Shawntae Spencer will miss the rest of the with a torn ligament in his left knee.
+Spencer, a fifth-year pro, will be placed on injured reserve soon after undergoing surgery Wednesday to repair the ligament. He injured his knee late in the 49ers’ road victory at Seattle on Sept. 14, and missed last week’s victory over Detroit.
+Tarell Brown and Donald Strickland will compete to replace Spencer with the 49ers, who kept 12 defensive backs on their 53-man roster to start the season. Brown, a second-year pro, got his first career interception last weekend while filling in for Strickland, who also sat out with a knee injury.""")
+```
+
+
+
+
+```python
+import torch
+from transformers import AutoModelForMaskedLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("allenai/longformer-base-4096")
+model = AutoModelForMaskedLM.from_pretrained("allenai/longformer-base-4096")
+
+text = (
+"""
+San Francisco 49ers cornerback Shawntae Spencer will miss the rest of the with a torn ligament in his left knee.
+Spencer, a fifth-year pro, will be placed on injured reserve soon after undergoing surgery Wednesday to repair the ligament. He injured his knee late in the 49ers’ road victory at Seattle on Sept. 14, and missed last week’s victory over Detroit.
+Tarell Brown and Donald Strickland will compete to replace Spencer with the 49ers, who kept 12 defensive backs on their 53-man roster to start the season. Brown, a second-year pro, got his first career interception last weekend while filling in for Strickland, who also sat out with a knee injury.
+"""
+)
+
+input_ids = tokenizer([text], return_tensors="pt")["input_ids"]
+logits = model(input_ids).logits
+
+masked_index = (input_ids[0] == tokenizer.mask_token_id).nonzero().item()
+probs = logits[0, masked_index].softmax(dim=0)
+values, predictions = probs.topk(5)
+tokenizer.decode(predictions).split()
+```
+
+
+
+
+```bash
+echo -e "San Francisco 49ers cornerback Shawntae Spencer will miss the rest of the with a torn ligament in his left knee." | transformers run --task fill-mask --model allenai/longformer-base-4096 --device 0
+```
+
+
+
+
+
+## Notes
+
+- Longformer is based on [RoBERTa](https://huggingface.co/docs/transformers/en/model_doc/roberta) and doesn't have `token_type_ids`. You don't need to indicate which token belongs to which segment. You only need to separate the segments with the separation token `` or `tokenizer.sep_token`.
+- You can set which tokens can attend locally and which tokens attend globally with the `global_attention_mask` at inference (see this [example](https://huggingface.co/docs/transformers/en/model_doc/longformer#transformers.LongformerModel.forward.example) for more details). A value of `0` means a token attends locally and a value of `1` means a token attends globally.
+- [`LongformerForMaskedLM`] is trained like [`RobertaForMaskedLM`] and should be used as shown below.
+
+ ```py
+ input_ids = tokenizer.encode("This is a sentence from [MASK] training data", return_tensors="pt")
+ mlm_labels = tokenizer.encode("This is a sentence from the training data", return_tensors="pt")
+ loss = model(input_ids, labels=input_ids, masked_lm_labels=mlm_labels)[0]
+ ```
+
+## LongformerConfig
+
+[[autodoc]] LongformerConfig
+
+## LongformerTokenizer
+
+[[autodoc]] LongformerTokenizer
+
+## LongformerTokenizerFast
+
+[[autodoc]] LongformerTokenizerFast
+
+## Longformer specific outputs
+
+[[autodoc]] models.longformer.modeling_longformer.LongformerBaseModelOutput
+
+[[autodoc]] models.longformer.modeling_longformer.LongformerBaseModelOutputWithPooling
+
+[[autodoc]] models.longformer.modeling_longformer.LongformerMaskedLMOutput
+
+[[autodoc]] models.longformer.modeling_longformer.LongformerQuestionAnsweringModelOutput
+
+[[autodoc]] models.longformer.modeling_longformer.LongformerSequenceClassifierOutput
+
+[[autodoc]] models.longformer.modeling_longformer.LongformerMultipleChoiceModelOutput
+
+[[autodoc]] models.longformer.modeling_longformer.LongformerTokenClassifierOutput
+
+[[autodoc]] models.longformer.modeling_tf_longformer.TFLongformerBaseModelOutput
+
+[[autodoc]] models.longformer.modeling_tf_longformer.TFLongformerBaseModelOutputWithPooling
+
+[[autodoc]] models.longformer.modeling_tf_longformer.TFLongformerMaskedLMOutput
+
+[[autodoc]] models.longformer.modeling_tf_longformer.TFLongformerQuestionAnsweringModelOutput
+
+[[autodoc]] models.longformer.modeling_tf_longformer.TFLongformerSequenceClassifierOutput
+
+[[autodoc]] models.longformer.modeling_tf_longformer.TFLongformerMultipleChoiceModelOutput
+
+[[autodoc]] models.longformer.modeling_tf_longformer.TFLongformerTokenClassifierOutput
+
+## LongformerModel
+
+[[autodoc]] LongformerModel
+ - forward
+
+## LongformerForMaskedLM
+
+[[autodoc]] LongformerForMaskedLM
+ - forward
+
+## LongformerForSequenceClassification
+
+[[autodoc]] LongformerForSequenceClassification
+ - forward
+
+## LongformerForMultipleChoice
+
+[[autodoc]] LongformerForMultipleChoice
+ - forward
+
+## LongformerForTokenClassification
+
+[[autodoc]] LongformerForTokenClassification
+ - forward
+
+## LongformerForQuestionAnswering
+
+[[autodoc]] LongformerForQuestionAnswering
+ - forward
+
+## TFLongformerModel
+
+[[autodoc]] TFLongformerModel
+ - call
+
+## TFLongformerForMaskedLM
+
+[[autodoc]] TFLongformerForMaskedLM
+ - call
+
+## TFLongformerForQuestionAnswering
+
+[[autodoc]] TFLongformerForQuestionAnswering
+ - call
+
+## TFLongformerForSequenceClassification
+
+[[autodoc]] TFLongformerForSequenceClassification
+ - call
+
+## TFLongformerForTokenClassification
+
+[[autodoc]] TFLongformerForTokenClassification
+ - call
+
+## TFLongformerForMultipleChoice
+
+[[autodoc]] TFLongformerForMultipleChoice
+ - call
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/longt5.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/longt5.md
new file mode 100644
index 0000000000000000000000000000000000000000..ffaa9cfc12f3a36d8b8e8db1d70e7b8193e13aba
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/longt5.md
@@ -0,0 +1,146 @@
+
+*This model was released on 2021-12-15 and added to Hugging Face Transformers on 2022-06-13.*
+
+# LongT5
+
+
+
+
+
+
+## Overview
+
+The LongT5 model was proposed in [LongT5: Efficient Text-To-Text Transformer for Long Sequences](https://huggingface.co/papers/2112.07916)
+by Mandy Guo, Joshua Ainslie, David Uthus, Santiago Ontanon, Jianmo Ni, Yun-Hsuan Sung and Yinfei Yang. It's an
+encoder-decoder transformer pre-trained in a text-to-text denoising generative setting. LongT5 model is an extension of
+T5 model, and it enables using one of the two different efficient attention mechanisms - (1) Local attention, or (2)
+Transient-Global attention.
+
+
+The abstract from the paper is the following:
+
+*Recent work has shown that either (1) increasing the input length or (2) increasing model size can improve the
+performance of Transformer-based neural models. In this paper, we present a new model, called LongT5, with which we
+explore the effects of scaling both the input length and model size at the same time. Specifically, we integrated
+attention ideas from long-input transformers (ETC), and adopted pre-training strategies from summarization pre-training
+(PEGASUS) into the scalable T5 architecture. The result is a new attention mechanism we call {\em Transient Global}
+(TGlobal), which mimics ETC's local/global attention mechanism, but without requiring additional side-inputs. We are
+able to achieve state-of-the-art results on several summarization tasks and outperform the original T5 models on
+question answering tasks.*
+
+This model was contributed by [stancld](https://huggingface.co/stancld).
+The original code can be found [here](https://github.com/google-research/longt5).
+
+## Usage tips
+
+- [`LongT5ForConditionalGeneration`] is an extension of [`T5ForConditionalGeneration`] exchanging the traditional
+encoder *self-attention* layer with efficient either *local* attention or *transient-global* (*tglobal*) attention.
+- Unlike the T5 model, LongT5 does not use a task prefix. Furthermore, it uses a different pre-training objective
+inspired by the pre-training of [`PegasusForConditionalGeneration`].
+- LongT5 model is designed to work efficiently and very well on long-range *sequence-to-sequence* tasks where the
+input sequence exceeds commonly used 512 tokens. It is capable of handling input sequences of a length up to 16,384 tokens.
+- For *Local Attention*, the sparse sliding-window local attention operation allows a given token to attend only `r`
+tokens to the left and right of it (with `r=127` by default). *Local Attention* does not introduce any new parameters
+to the model. The complexity of the mechanism is linear in input sequence length `l`: `O(l*r)`.
+- *Transient Global Attention* is an extension of the *Local Attention*. It, furthermore, allows each input token to
+interact with all other tokens in the layer. This is achieved via splitting an input sequence into blocks of a fixed
+length `k` (with a default `k=16`). Then, a global token for such a block is obtained via summing and normalizing the embeddings of every token
+in the block. Thanks to this, the attention allows each token to attend to both nearby tokens like in Local attention, and
+also every global token like in the case of standard global attention (*transient* represents the fact the global tokens
+are constructed dynamically within each attention operation). As a consequence, *TGlobal* attention introduces
+a few new parameters -- global relative position biases and a layer normalization for global token's embedding.
+The complexity of this mechanism is `O(l(r + l/k))`.
+- An example showing how to evaluate a fine-tuned LongT5 model on the [pubmed dataset](https://huggingface.co/datasets/scientific_papers) is below.
+
+```python
+>>> import evaluate
+>>> from datasets import load_dataset
+>>> from transformers import AutoTokenizer, LongT5ForConditionalGeneration
+
+>>> dataset = load_dataset("scientific_papers", "pubmed", split="validation")
+>>> model = (
+... LongT5ForConditionalGeneration.from_pretrained("Stancld/longt5-tglobal-large-16384-pubmed-3k_steps")
+... .to("auto")
+... .half()
+... )
+>>> tokenizer = AutoTokenizer.from_pretrained("Stancld/longt5-tglobal-large-16384-pubmed-3k_steps")
+
+
+>>> def generate_answers(batch):
+... inputs_dict = tokenizer(
+... batch["article"], max_length=16384, padding="max_length", truncation=True, return_tensors="pt"
+... )
+... input_ids = inputs_dict.input_ids.to(model.device)
+... attention_mask = inputs_dict.attention_mask.to(model.device)
+... output_ids = model.generate(input_ids, attention_mask=attention_mask, max_length=512, num_beams=2)
+... batch["predicted_abstract"] = tokenizer.batch_decode(output_ids, skip_special_tokens=True)
+... return batch
+
+
+>>> result = dataset.map(generate_answer, batched=True, batch_size=2)
+>>> rouge = evaluate.load("rouge")
+>>> rouge.compute(predictions=result["predicted_abstract"], references=result["abstract"])
+```
+
+
+## Resources
+
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## LongT5Config
+
+[[autodoc]] LongT5Config
+
+
+
+
+## LongT5Model
+
+[[autodoc]] LongT5Model
+ - forward
+
+## LongT5ForConditionalGeneration
+
+[[autodoc]] LongT5ForConditionalGeneration
+ - forward
+
+## LongT5EncoderModel
+
+[[autodoc]] LongT5EncoderModel
+ - forward
+
+
+
+
+## FlaxLongT5Model
+
+[[autodoc]] FlaxLongT5Model
+ - __call__
+ - encode
+ - decode
+
+## FlaxLongT5ForConditionalGeneration
+
+[[autodoc]] FlaxLongT5ForConditionalGeneration
+ - __call__
+ - encode
+ - decode
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/luke.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/luke.md
new file mode 100644
index 0000000000000000000000000000000000000000..5eaadf79e96607c6a94a506f259c19a0f2936408
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/luke.md
@@ -0,0 +1,186 @@
+
+*This model was released on 2020-10-02 and added to Hugging Face Transformers on 2021-05-03.*
+
+# LUKE
+
+
+
+
+
+## Overview
+
+The LUKE model was proposed in [LUKE: Deep Contextualized Entity Representations with Entity-aware Self-attention](https://huggingface.co/papers/2010.01057) by Ikuya Yamada, Akari Asai, Hiroyuki Shindo, Hideaki Takeda and Yuji Matsumoto.
+It is based on RoBERTa and adds entity embeddings as well as an entity-aware self-attention mechanism, which helps
+improve performance on various downstream tasks involving reasoning about entities such as named entity recognition,
+extractive and cloze-style question answering, entity typing, and relation classification.
+
+The abstract from the paper is the following:
+
+*Entity representations are useful in natural language tasks involving entities. In this paper, we propose new
+pretrained contextualized representations of words and entities based on the bidirectional transformer. The proposed
+model treats words and entities in a given text as independent tokens, and outputs contextualized representations of
+them. Our model is trained using a new pretraining task based on the masked language model of BERT. The task involves
+predicting randomly masked words and entities in a large entity-annotated corpus retrieved from Wikipedia. We also
+propose an entity-aware self-attention mechanism that is an extension of the self-attention mechanism of the
+transformer, and considers the types of tokens (words or entities) when computing attention scores. The proposed model
+achieves impressive empirical performance on a wide range of entity-related tasks. In particular, it obtains
+state-of-the-art results on five well-known datasets: Open Entity (entity typing), TACRED (relation classification),
+CoNLL-2003 (named entity recognition), ReCoRD (cloze-style question answering), and SQuAD 1.1 (extractive question
+answering).*
+
+This model was contributed by [ikuyamada](https://huggingface.co/ikuyamada) and [nielsr](https://huggingface.co/nielsr). The original code can be found [here](https://github.com/studio-ousia/luke).
+
+## Usage tips
+
+- This implementation is the same as [`RobertaModel`] with the addition of entity embeddings as well
+ as an entity-aware self-attention mechanism, which improves performance on tasks involving reasoning about entities.
+- LUKE treats entities as input tokens; therefore, it takes `entity_ids`, `entity_attention_mask`,
+ `entity_token_type_ids` and `entity_position_ids` as extra input. You can obtain those using
+ [`LukeTokenizer`].
+- [`LukeTokenizer`] takes `entities` and `entity_spans` (character-based start and end
+ positions of the entities in the input text) as extra input. `entities` typically consist of [MASK] entities or
+ Wikipedia entities. The brief description when inputting these entities are as follows:
+
+ - *Inputting [MASK] entities to compute entity representations*: The [MASK] entity is used to mask entities to be
+ predicted during pretraining. When LUKE receives the [MASK] entity, it tries to predict the original entity by
+ gathering the information about the entity from the input text. Therefore, the [MASK] entity can be used to address
+ downstream tasks requiring the information of entities in text such as entity typing, relation classification, and
+ named entity recognition.
+ - *Inputting Wikipedia entities to compute knowledge-enhanced token representations*: LUKE learns rich information
+ (or knowledge) about Wikipedia entities during pretraining and stores the information in its entity embedding. By
+ using Wikipedia entities as input tokens, LUKE outputs token representations enriched by the information stored in
+ the embeddings of these entities. This is particularly effective for tasks requiring real-world knowledge, such as
+ question answering.
+
+- There are three head models for the former use case:
+
+ - [`LukeForEntityClassification`], for tasks to classify a single entity in an input text such as
+ entity typing, e.g. the [Open Entity dataset](https://www.cs.utexas.edu/~eunsol/html_pages/open_entity.html).
+ This model places a linear head on top of the output entity representation.
+ - [`LukeForEntityPairClassification`], for tasks to classify the relationship between two entities
+ such as relation classification, e.g. the [TACRED dataset](https://nlp.stanford.edu/projects/tacred/). This
+ model places a linear head on top of the concatenated output representation of the pair of given entities.
+ - [`LukeForEntitySpanClassification`], for tasks to classify the sequence of entity spans, such as
+ named entity recognition (NER). This model places a linear head on top of the output entity representations. You
+ can address NER using this model by inputting all possible entity spans in the text to the model.
+
+ [`LukeTokenizer`] has a `task` argument, which enables you to easily create an input to these
+ head models by specifying `task="entity_classification"`, `task="entity_pair_classification"`, or
+ `task="entity_span_classification"`. Please refer to the example code of each head models.
+
+Usage example:
+
+```python
+>>> from transformers import LukeTokenizer, LukeModel, LukeForEntityPairClassification
+
+>>> model = LukeModel.from_pretrained("studio-ousia/luke-base")
+>>> tokenizer = LukeTokenizer.from_pretrained("studio-ousia/luke-base")
+# Example 1: Computing the contextualized entity representation corresponding to the entity mention "Beyoncé"
+
+>>> text = "Beyoncé lives in Los Angeles."
+>>> entity_spans = [(0, 7)] # character-based entity span corresponding to "Beyoncé"
+>>> inputs = tokenizer(text, entity_spans=entity_spans, add_prefix_space=True, return_tensors="pt")
+>>> outputs = model(**inputs)
+>>> word_last_hidden_state = outputs.last_hidden_state
+>>> entity_last_hidden_state = outputs.entity_last_hidden_state
+# Example 2: Inputting Wikipedia entities to obtain enriched contextualized representations
+
+>>> entities = [
+... "Beyoncé",
+... "Los Angeles",
+... ] # Wikipedia entity titles corresponding to the entity mentions "Beyoncé" and "Los Angeles"
+>>> entity_spans = [(0, 7), (17, 28)] # character-based entity spans corresponding to "Beyoncé" and "Los Angeles"
+>>> inputs = tokenizer(text, entities=entities, entity_spans=entity_spans, add_prefix_space=True, return_tensors="pt")
+>>> outputs = model(**inputs)
+>>> word_last_hidden_state = outputs.last_hidden_state
+>>> entity_last_hidden_state = outputs.entity_last_hidden_state
+# Example 3: Classifying the relationship between two entities using LukeForEntityPairClassification head model
+
+>>> model = LukeForEntityPairClassification.from_pretrained("studio-ousia/luke-large-finetuned-tacred")
+>>> tokenizer = LukeTokenizer.from_pretrained("studio-ousia/luke-large-finetuned-tacred")
+>>> entity_spans = [(0, 7), (17, 28)] # character-based entity spans corresponding to "Beyoncé" and "Los Angeles"
+>>> inputs = tokenizer(text, entity_spans=entity_spans, return_tensors="pt")
+>>> outputs = model(**inputs)
+>>> logits = outputs.logits
+>>> predicted_class_idx = int(logits[0].argmax())
+>>> print("Predicted class:", model.config.id2label[predicted_class_idx])
+```
+
+## Resources
+
+- [A demo notebook on how to fine-tune [`LukeForEntityPairClassification`] for relation classification](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/LUKE)
+- [Notebooks showcasing how you to reproduce the results as reported in the paper with the HuggingFace implementation of LUKE](https://github.com/studio-ousia/luke/tree/master/notebooks)
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## LukeConfig
+
+[[autodoc]] LukeConfig
+
+## LukeTokenizer
+
+[[autodoc]] LukeTokenizer
+ - __call__
+ - save_vocabulary
+
+## LukeModel
+
+[[autodoc]] LukeModel
+ - forward
+
+## LukeForMaskedLM
+
+[[autodoc]] LukeForMaskedLM
+ - forward
+
+## LukeForEntityClassification
+
+[[autodoc]] LukeForEntityClassification
+ - forward
+
+## LukeForEntityPairClassification
+
+[[autodoc]] LukeForEntityPairClassification
+ - forward
+
+## LukeForEntitySpanClassification
+
+[[autodoc]] LukeForEntitySpanClassification
+ - forward
+
+## LukeForSequenceClassification
+
+[[autodoc]] LukeForSequenceClassification
+ - forward
+
+## LukeForMultipleChoice
+
+[[autodoc]] LukeForMultipleChoice
+ - forward
+
+## LukeForTokenClassification
+
+[[autodoc]] LukeForTokenClassification
+ - forward
+
+## LukeForQuestionAnswering
+
+[[autodoc]] LukeForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/lxmert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/lxmert.md
new file mode 100644
index 0000000000000000000000000000000000000000..93f0d212be2651803458eedbcb56e6440900eaff
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/lxmert.md
@@ -0,0 +1,124 @@
+
+*This model was released on 2019-08-20 and added to Hugging Face Transformers on 2020-11-16.*
+
+# LXMERT
+
+
+
+
+
+
+## Overview
+
+The LXMERT model was proposed in [LXMERT: Learning Cross-Modality Encoder Representations from Transformers](https://huggingface.co/papers/1908.07490) by Hao Tan & Mohit Bansal. It is a series of bidirectional transformer encoders
+(one for the vision modality, one for the language modality, and then one to fuse both modalities) pretrained using a
+combination of masked language modeling, visual-language text alignment, ROI-feature regression, masked
+visual-attribute modeling, masked visual-object modeling, and visual-question answering objectives. The pretraining
+consists of multiple multi-modal datasets: MSCOCO, Visual-Genome + Visual-Genome Question Answering, VQA 2.0, and GQA.
+
+The abstract from the paper is the following:
+
+*Vision-and-language reasoning requires an understanding of visual concepts, language semantics, and, most importantly,
+the alignment and relationships between these two modalities. We thus propose the LXMERT (Learning Cross-Modality
+Encoder Representations from Transformers) framework to learn these vision-and-language connections. In LXMERT, we
+build a large-scale Transformer model that consists of three encoders: an object relationship encoder, a language
+encoder, and a cross-modality encoder. Next, to endow our model with the capability of connecting vision and language
+semantics, we pre-train the model with large amounts of image-and-sentence pairs, via five diverse representative
+pretraining tasks: masked language modeling, masked object prediction (feature regression and label classification),
+cross-modality matching, and image question answering. These tasks help in learning both intra-modality and
+cross-modality relationships. After fine-tuning from our pretrained parameters, our model achieves the state-of-the-art
+results on two visual question answering datasets (i.e., VQA and GQA). We also show the generalizability of our
+pretrained cross-modality model by adapting it to a challenging visual-reasoning task, NLVR, and improve the previous
+best result by 22% absolute (54% to 76%). Lastly, we demonstrate detailed ablation studies to prove that both our novel
+model components and pretraining strategies significantly contribute to our strong results; and also present several
+attention visualizations for the different encoders*
+
+This model was contributed by [eltoto1219](https://huggingface.co/eltoto1219). The original code can be found [here](https://github.com/airsplay/lxmert).
+
+## Usage tips
+
+- Bounding boxes are not necessary to be used in the visual feature embeddings, any kind of visual-spacial features
+ will work.
+- Both the language hidden states and the visual hidden states that LXMERT outputs are passed through the
+ cross-modality layer, so they contain information from both modalities. To access a modality that only attends to
+ itself, select the vision/language hidden states from the first input in the tuple.
+- The bidirectional cross-modality encoder attention only returns attention values when the language modality is used
+ as the input and the vision modality is used as the context vector. Further, while the cross-modality encoder
+ contains self-attention for each respective modality and cross-attention, only the cross attention is returned and
+ both self attention outputs are disregarded.
+
+## Resources
+
+- [Question answering task guide](../tasks/question_answering)
+
+## LxmertConfig
+
+[[autodoc]] LxmertConfig
+
+## LxmertTokenizer
+
+[[autodoc]] LxmertTokenizer
+
+## LxmertTokenizerFast
+
+[[autodoc]] LxmertTokenizerFast
+
+## Lxmert specific outputs
+
+[[autodoc]] models.lxmert.modeling_lxmert.LxmertModelOutput
+
+[[autodoc]] models.lxmert.modeling_lxmert.LxmertForPreTrainingOutput
+
+[[autodoc]] models.lxmert.modeling_lxmert.LxmertForQuestionAnsweringOutput
+
+[[autodoc]] models.lxmert.modeling_tf_lxmert.TFLxmertModelOutput
+
+[[autodoc]] models.lxmert.modeling_tf_lxmert.TFLxmertForPreTrainingOutput
+
+
+
+
+## LxmertModel
+
+[[autodoc]] LxmertModel
+ - forward
+
+## LxmertForPreTraining
+
+[[autodoc]] LxmertForPreTraining
+ - forward
+
+## LxmertForQuestionAnswering
+
+[[autodoc]] LxmertForQuestionAnswering
+ - forward
+
+
+
+
+## TFLxmertModel
+
+[[autodoc]] TFLxmertModel
+ - call
+
+## TFLxmertForPreTraining
+
+[[autodoc]] TFLxmertForPreTraining
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/m2m_100.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/m2m_100.md
new file mode 100644
index 0000000000000000000000000000000000000000..f525e2ce7f7b15a0aa646cb8a10faf3775436157
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/m2m_100.md
@@ -0,0 +1,193 @@
+
+*This model was released on 2020-10-21 and added to Hugging Face Transformers on 2021-03-06.*
+
+# M2M100
+
+
+
+
+
+
+
+## Overview
+
+The M2M100 model was proposed in [Beyond English-Centric Multilingual Machine Translation](https://huggingface.co/papers/2010.11125) by Angela Fan, Shruti Bhosale, Holger Schwenk, Zhiyi Ma, Ahmed El-Kishky,
+Siddharth Goyal, Mandeep Baines, Onur Celebi, Guillaume Wenzek, Vishrav Chaudhary, Naman Goyal, Tom Birch, Vitaliy
+Liptchinsky, Sergey Edunov, Edouard Grave, Michael Auli, Armand Joulin.
+
+The abstract from the paper is the following:
+
+*Existing work in translation demonstrated the potential of massively multilingual machine translation by training a
+single model able to translate between any pair of languages. However, much of this work is English-Centric by training
+only on data which was translated from or to English. While this is supported by large sources of training data, it
+does not reflect translation needs worldwide. In this work, we create a true Many-to-Many multilingual translation
+model that can translate directly between any pair of 100 languages. We build and open source a training dataset that
+covers thousands of language directions with supervised data, created through large-scale mining. Then, we explore how
+to effectively increase model capacity through a combination of dense scaling and language-specific sparse parameters
+to create high quality models. Our focus on non-English-Centric models brings gains of more than 10 BLEU when directly
+translating between non-English directions while performing competitively to the best single systems of WMT. We
+open-source our scripts so that others may reproduce the data, evaluation, and final M2M-100 model.*
+
+This model was contributed by [valhalla](https://huggingface.co/valhalla).
+
+
+## Usage tips and examples
+
+M2M100 is a multilingual encoder-decoder (seq-to-seq) model primarily intended for translation tasks. As the model is
+multilingual it expects the sequences in a certain format: A special language id token is used as prefix in both the
+source and target text. The source text format is `[lang_code] X [eos]`, where `lang_code` is source language
+id for source text and target language id for target text, with `X` being the source or target text.
+
+> [!NOTE]
+> The `head_mask` argument is ignored when using all attention implementation other than "eager". If you have a `head_mask` and want it to have effect, load the model with `XXXModel.from_pretrained(model_id, attn_implementation="eager")`
+
+The [`M2M100Tokenizer`] depends on `sentencepiece` so be sure to install it before running the
+examples. To install `sentencepiece` run `pip install sentencepiece`.
+
+**Supervised Training**
+
+```python
+from transformers import M2M100Config, M2M100ForConditionalGeneration, M2M100Tokenizer
+
+model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M")
+tokenizer = M2M100Tokenizer.from_pretrained("facebook/m2m100_418M", src_lang="en", tgt_lang="fr")
+
+src_text = "Life is like a box of chocolates."
+tgt_text = "La vie est comme une boîte de chocolat."
+
+model_inputs = tokenizer(src_text, text_target=tgt_text, return_tensors="pt")
+
+loss = model(**model_inputs).loss # forward pass
+```
+
+**Generation**
+
+M2M100 uses the `eos_token_id` as the `decoder_start_token_id` for generation with the target language id
+being forced as the first generated token. To force the target language id as the first generated token, pass the
+*forced_bos_token_id* parameter to the *generate* method. The following example shows how to translate between
+Hindi to French and Chinese to English using the *facebook/m2m100_418M* checkpoint.
+
+```python
+>>> from transformers import M2M100ForConditionalGeneration, M2M100Tokenizer
+
+>>> hi_text = "जीवन एक चॉकलेट बॉक्स की तरह है।"
+>>> chinese_text = "生活就像一盒巧克力。"
+
+>>> model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M")
+>>> tokenizer = M2M100Tokenizer.from_pretrained("facebook/m2m100_418M")
+
+>>> # translate Hindi to French
+>>> tokenizer.src_lang = "hi"
+>>> encoded_hi = tokenizer(hi_text, return_tensors="pt")
+>>> generated_tokens = model.generate(**encoded_hi, forced_bos_token_id=tokenizer.get_lang_id("fr"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+"La vie est comme une boîte de chocolat."
+
+>>> # translate Chinese to English
+>>> tokenizer.src_lang = "zh"
+>>> encoded_zh = tokenizer(chinese_text, return_tensors="pt")
+>>> generated_tokens = model.generate(**encoded_zh, forced_bos_token_id=tokenizer.get_lang_id("en"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+"Life is like a box of chocolate."
+```
+
+## Resources
+
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## M2M100Config
+
+[[autodoc]] M2M100Config
+
+## M2M100Tokenizer
+
+[[autodoc]] M2M100Tokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## M2M100Model
+
+[[autodoc]] M2M100Model
+ - forward
+
+## M2M100ForConditionalGeneration
+
+[[autodoc]] M2M100ForConditionalGeneration
+ - forward
+
+## Using Flash Attention 2
+
+Flash Attention 2 is a faster, optimized version of the attention scores computation which relies on `cuda` kernels.
+
+### Installation
+
+First, check whether your hardware is compatible with Flash Attention 2. The latest list of compatible hardware can be found in the [official documentation](https://github.com/Dao-AILab/flash-attention#installation-and-features).
+
+Next, [install](https://github.com/Dao-AILab/flash-attention#installation-and-features) the latest version of Flash Attention 2:
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+### Usage
+
+To load a model using Flash Attention 2, we can pass the argument `attn_implementation="flash_attention_2"` to [`.from_pretrained`](https://huggingface.co/docs/transformers/main/en/main_classes/model#transformers.PreTrainedModel.from_pretrained). You can use either `torch.float16` or `torch.bfloat16` precision.
+
+```python
+>>> import torch
+>>> from transformers import M2M100ForConditionalGeneration, M2M100Tokenizer
+
+>>> model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M", torch_dtype=torch.float16, attn_implementation="flash_attention_2", device_map="auto").eval()
+>>> tokenizer = M2M100Tokenizer.from_pretrained("facebook/m2m100_418M")
+
+>>> # translate Hindi to French
+>>> hi_text = "जीवन एक चॉकलेट बॉक्स की तरह है।"
+>>> tokenizer.src_lang = "hi"
+>>> encoded_hi = tokenizer(hi_text, return_tensors="pt").to(model.device)
+>>> generated_tokens = model.generate(**encoded_hi, forced_bos_token_id=tokenizer.get_lang_id("fr"))
+>>> tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+"La vie est comme une boîte de chocolat."
+```
+
+### Expected speedups
+
+Below is an expected speedup diagram that compares pure inference time between the native implementation and the Flash Attention 2.
+
+
+
+
+
+## Using Scaled Dot Product Attention (SDPA)
+PyTorch includes a native scaled dot-product attention (SDPA) operator as part of `torch.nn.functional`. This function
+encompasses several implementations that can be applied depending on the inputs and the hardware in use. See the
+[official documentation](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)
+or the [GPU Inference](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)
+page for more information.
+
+SDPA is used by default for `torch>=2.1.1` when an implementation is available, but you may also set
+`attn_implementation="sdpa"` in `from_pretrained()` to explicitly request SDPA to be used.
+
+```python
+from transformers import M2M100ForConditionalGeneration
+model = M2M100ForConditionalGeneration.from_pretrained("facebook/m2m100_418M", torch_dtype=torch.float16, attn_implementation="sdpa")
+...
+```
+
+For the best speedups, we recommend loading the model in half-precision (e.g. `torch.float16` or `torch.bfloat16`).
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/madlad-400.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/madlad-400.md
new file mode 100644
index 0000000000000000000000000000000000000000..d43e0fb6ccdb9b070b7618a7e465d58c1f37aa3c
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/madlad-400.md
@@ -0,0 +1,76 @@
+
+*This model was released on 2023-09-09 and added to Hugging Face Transformers on 2023-11-28.*
+
+# MADLAD-400
+
+
+
+
+
+
+
+## Overview
+
+MADLAD-400 models were released in the paper [MADLAD-400: A Multilingual And Document-Level Large Audited Dataset](https://huggingface.co/papers/2309.04662).
+
+The abstract from the paper is the following:
+
+*We introduce MADLAD-400, a manually audited, general domain 3T token monolingual dataset based on CommonCrawl, spanning 419 languages. We discuss
+the limitations revealed by self-auditing MADLAD-400, and the role data auditing
+had in the dataset creation process. We then train and release a 10.7B-parameter
+multilingual machine translation model on 250 billion tokens covering over 450
+languages using publicly available data, and find that it is competitive with models
+that are significantly larger, and report the results on different domains. In addition, we train a 8B-parameter language model, and assess the results on few-shot
+translation. We make the baseline models 1
+available to the research community.*
+
+This model was added by [Juarez Bochi](https://huggingface.co/jbochi). The original checkpoints can be found [here](https://github.com/google-research/google-research/tree/master/madlad_400).
+
+This is a machine translation model that supports many low-resource languages, and that is competitive with models that are significantly larger.
+
+One can directly use MADLAD-400 weights without finetuning the model:
+
+```python
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("google/madlad400-3b-mt")
+>>> tokenizer = AutoTokenizer.from_pretrained("google/madlad400-3b-mt")
+
+>>> inputs = tokenizer("<2pt> I love pizza!", return_tensors="pt")
+>>> outputs = model.generate(**inputs)
+>>> print(tokenizer.batch_decode(outputs, skip_special_tokens=True))
+['Eu amo pizza!']
+```
+
+Google has released the following variants:
+
+- [google/madlad400-3b-mt](https://huggingface.co/google/madlad400-3b-mt)
+
+- [google/madlad400-7b-mt](https://huggingface.co/google/madlad400-7b-mt)
+
+- [google/madlad400-7b-mt-bt](https://huggingface.co/google/madlad400-7b-mt-bt)
+
+- [google/madlad400-10b-mt](https://huggingface.co/google/madlad400-10b-mt)
+
+The original checkpoints can be found [here](https://github.com/google-research/google-research/tree/master/madlad_400).
+
+
+
+Refer to [T5's documentation page](t5) for all API references, code examples, and notebooks. For more details regarding training and evaluation of the MADLAD-400, refer to the model card.
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mamba.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mamba.md
new file mode 100644
index 0000000000000000000000000000000000000000..08513b319cd354ba1068a19198246b652d0f64a4
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mamba.md
@@ -0,0 +1,139 @@
+
+*This model was released on 2023-12-01 and added to Hugging Face Transformers on 2024-03-05.*
+
+
+
+
+
+
+
+# Mamba
+
+[Mamba](https://huggingface.co/papers/2312.00752) is a selective structured state space model (SSMs) designed to work around Transformers computational inefficiency when dealing with long sequences. It is a completely attention-free architecture, and comprised of a combination of H3 and gated MLP blocks (Mamba block). Mamba's "content-based reasoning" allows it to focus on specific parts of an input depending on the current token. Mamba also uses a new hardware-aware parallel algorithm to compensate for the lack of convolutional operations. As a result, Mamba has fast inference and can scale to very long sequences.
+
+You can find all the original Mamba checkpoints under the [State Space Models](https://huggingface.co/state-spaces) organization.
+
+
+> [!TIP]
+> This model was contributed by [Molbap](https://huggingface.co/Molbap) and [AntonV](https://huggingface.co/AntonV).
+> Click on the Mamba models in the right sidebar for more examples of how to apply Mamba to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="text-generation",
+ model="state-spaces/mamba-130m-hf",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("Plants create energy through a process known as")
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("state-spaces/mamba-130m-hf")
+model = AutoModelForCausalLM.from_pretrained("state-spaces/mamba-130m-hf", torch_dtype=torch.float16, device_map="auto",)
+input_ids = tokenizer("Plants create energy through a process known as", return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids)
+print(tokenizer.decode(output[0], skip_special_tokens=True)
+```
+
+
+
+
+```bash
+echo -e "Plants create energy through a process known as" | transformers run --task text-generation --model state-spaces/mamba-130m-hf --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [torchao](../quantization/torchao) to only quantize the weights to 4-bit integers.
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, TorchAoConfig
+from torchao.quantization import Int4WeightOnlyConfig
+
+quantization_config = Int4WeightOnlyConfig(group_size=128)
+quantization_config = TorchAoConfig(quant_type=quant_config)
+tokenizer = AutoTokenizer.from_pretrained("state-spaces/mamba-2.8b-hf")
+model = AutoModelForCausalLM.from_pretrained("state-spaces/mamba-2.8b-hf", torch_dtype=torch.bfloat16, quantization_config=quantization_config, device_map="auto",)
+input_ids = tokenizer("Plants create energy through a process known as", return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids)
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+## Notes
+
+- The current implementation uses the original CUDA kernels. The FlashAttention equivalent implementation is hosted in the [mamba-ssm](https://github.com/state-spaces/mamba) and [causal_conv1d](https://github.com/Dao-AILab/causal-conv1d) repositories. Make sure to install them if your hardware supports it!
+- Mamba stacks `mixer` layers which are equivalent to `Attention` layers. You can find the main logic of Mamba in the `MambaMixer` class.
+- The example below demonstrates how to fine-tune Mamba with [PEFT](https://huggingface.co/docs/peft).
+
+ ```py
+ from datasets import load_dataset
+ from trl import SFTConfig, SFTTrainer
+ from peft import LoraConfig
+
+ model_id = "state-spaces/mamba-130m-hf"
+ dataset = load_dataset("Abirate/english_quotes", split="train")
+ training_args = SFTConfig(dataset_text_field="quote")
+ lora_config = LoraConfig(target_modules=["x_proj", "embeddings", "in_proj", "out_proj"])
+ trainer = SFTTrainer(
+ model=model_id,
+ args=training_args,
+ train_dataset=dataset,
+ peft_config=lora_config,
+ )
+ trainer.train()
+ ```
+
+## MambaCache
+
+[[autodoc]] MambaCache
+ - update_conv_state
+ - update_ssm_state
+ - reset
+
+## MambaConfig
+
+[[autodoc]] MambaConfig
+
+## MambaModel
+
+[[autodoc]] MambaModel
+ - forward
+
+## MambaLMHeadModel
+
+[[autodoc]] MambaForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mamba2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mamba2.md
new file mode 100644
index 0000000000000000000000000000000000000000..e7358ce3c9eb4cb662773e720fd1ca9d72eda58d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mamba2.md
@@ -0,0 +1,138 @@
+
+*This model was released on 2024-05-31 and added to Hugging Face Transformers on 2024-08-06.*
+
+
+
+
+
+
+# Mamba 2
+
+[Mamba 2](https://huggingface.co/papers/2405.21060) is based on the state space duality (SSD) framework which connects structured state space models (SSMs) and attention variants. It uses a more efficient SSD algorithm that is 2-8x faster than Mamba and modifies the architecture to enable tensor parallelism and a grouped-value attention (GVA) head structure.
+
+You can find all the original Mamba 2 checkpoints under the [State Space Models](https://huggingface.co/state-spaces) organization, but the examples shown below use [mistralai/Mamba-Codestral-7B-v0.1](https://huggingface.co/mistralai/Mamba-Codestral-7B-v0.1) because a Hugging Face implementation isn't supported yet for the original checkpoints.
+
+> [!TIP]
+> This model was contributed by [ArthurZ](https://huggingface.co/ArthurZ).
+> Click on the Mamba models in the right sidebar for more examples of how to apply Mamba to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`], [`AutoModel`], and from the command line.
+
+hfoptions id="usage">
+
+
+```python
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="text-generation",
+ model="mistralai/Mamba-Codestral-7B-v0.1",
+ torch_dtype=torch.bfloat16,
+ device=0
+)
+pipeline("Plants create energy through a process known as")
+```
+
+
+
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("mistralai/Mamba-Codestral-7B-v0.1")
+model = AutoModelForCausalLM.from_pretrained("mistralai/Mamba-Codestral-7B-v0.1", torch_dtype=torch.bfloat16, device_map="auto")
+input_ids = tokenizer("Plants create energy through a process known as", return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids)
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+echo -e "Plants create energy through a process known as" | transformers-cli run --task text-generation --model mistralai/Mamba-Codestral-7B-v0.1 --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [torchao](../quantization/torchao) to only quantize the weights to 4-bit integers.
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, TorchAoConfig
+
+quantization_config = TorchAoConfig("int4_weight_only", group_size=128)
+tokenizer = AutoTokenizer.from_pretrained("mistralai/Mamba-Codestral-7B-v0.1")
+model = AutoModelForCausalLM.from_pretrained("mistralai/Mamba-Codestral-7B-v0.1", torch_dtype=torch.bfloat16, quantization_config=quantization_config, device_map="auto")
+input_ids = tokenizer("Plants create energy through a process known as", return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids)
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+## Notes
+
+- Codestral Mamba has `groups=8` which are similar to the number of kv heads in an attention-based model.
+- Codestral Mamba has two different forward passes, `torch_forward` or `cuda_kernels_forward`, and their results are expected to be slightly different.
+ - `torch_forward` without compilation is 3-4x faster than `cuda_kernels_forward`.
+ - `cuda_kernels_forward` uses the original CUDA kernels if they're available in your environment. It is slower during prefill because it requires a "warmup run" due to the higher CPU overhead (see [these](https://github.com/state-spaces/mamba/issues/389#issuecomment-2171755306) [comments](https://github.com/state-spaces/mamba/issues/355#issuecomment-2147597457) for more details).
+
+- There are no positional embeddings in this model, but there is an `attention_mask` and a specific logic to mask out hidden states in two places in the case of batched generation (see this [comment](https://github.com/state-spaces/mamba/issues/66#issuecomment-1863563829) for more details). This (and the addition of the reimplemented Mamba 2 kernels) results in a slight discrepancy between batched and cached generation.
+
+- The SSM algorithm heavily relies on tensor contractions, which have matmul equivalents but the order of operations is slightly different. This makes the difference greater at smaller precisions.
+
+- Hidden states that correspond to padding tokens is shutdown in 2 places and is mostly tested with left-padding. Right-padding propagates noise down the line and is not guaranteed to yield satisfactory results. `tokenizer.padding_side = "left"` ensures you are using the correct padding side.
+
+- The example below demonstrates how to fine-tune Mamba 2 with [PEFT](https://huggingface.co/docs/peft).
+
+```python
+from datasets import load_dataset
+from peft import LoraConfig
+from trl import SFTConfig, SFTTrainer
+
+model_id = "mistralai/Mamba-Codestral-7B-v0.1"
+dataset = load_dataset("Abirate/english_quotes", split="train")
+training_args = SFTConfig(dataset_text_field="quote", gradient_checkpointing=True, per_device_train_batch_size=4)
+lora_config = LoraConfig(target_modules=["x_proj", "embeddings", "in_proj", "out_proj"])
+trainer = SFTTrainer(
+ model=model_id,
+ args=training_args,
+ train_dataset=dataset,
+ peft_config=lora_config,
+)
+trainer.train()
+```
+
+
+## Mamba2Config
+
+[[autodoc]] Mamba2Config
+
+## Mamba2Model
+
+[[autodoc]] Mamba2Model
+ - forward
+
+## Mamba2LMHeadModel
+
+[[autodoc]] Mamba2ForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/marian.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/marian.md
new file mode 100644
index 0000000000000000000000000000000000000000..d2a8b7c5b0a6b51d7df6d066c660187ff085df99
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/marian.md
@@ -0,0 +1,205 @@
+
+*This model was released on 2018-04-01 and added to Hugging Face Transformers on 2020-11-16.*
+
+
+
+
+
+
+
+
+
+
+
+# MarianMT
+
+
+
+[MarianMT](https://huggingface.co/papers/1804.00344) is a machine translation model trained with the Marian framework which is written in pure C++. The framework includes its own custom auto-differentiation engine and efficient meta-algorithms to train encoder-decoder models like BART.
+
+All MarianMT models are transformer encoder-decoders with 6 layers in each component, use static sinusoidal positional embeddings, don't have a layernorm embedding, and the model starts generating with the prefix `pad_token_id` instead of ``.
+
+
+
+You can find all the original MarianMT checkpoints under the [Language Technology Research Group at the University of Helsinki](https://huggingface.co/Helsinki-NLP/models?search=opus-mt) organization.
+
+
+> [!TIP]
+> This model was contributed by [sshleifer](https://huggingface.co/sshleifer).
+>
+> Click on the MarianMT models in the right sidebar for more examples of how to apply MarianMT to translation tasks.
+
+
+The example below demonstrates how to translate text using [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```python
+
+import torch
+from transformers import pipeline
+
+pipeline = pipeline("translation_en_to_de", model="Helsinki-NLP/opus-mt-en-de", torch_dtype=torch.float16, device=0)
+pipeline("Hello, how are you?")
+
+```
+
+
+
+
+
+```python
+
+import torch
+from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("Helsinki-NLP/opus-mt-en-de")
+model = AutoModelForSeq2SeqLM.from_pretrained("Helsinki-NLP/opus-mt-en-de", torch_dtype=torch.float16, attn_implementation="sdpa", device_map="auto")
+
+inputs = tokenizer("Hello, how are you?", return_tensors="pt").to("cuda")
+outputs = model.generate(**inputs, cache_implementation="static")
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+
+```
+
+
+
+
+
+Use the [AttentionMaskVisualizer](https://github.com/huggingface/transformers/blob/beb9b5b02246b9b7ee81ddf938f93f44cfeaad19/src/transformers/utils/attention_visualizer.py#L139) to better understand what tokens the model can and cannot attend to.
+
+```python
+from transformers.utils.attention_visualizer import AttentionMaskVisualizer
+
+visualizer = AttentionMaskVisualizer("Helsinki-NLP/opus-mt-en-de")
+visualizer("Hello, how are you?")
+```
+
+
+
+
+## Notes
+
+- MarianMT models are ~298MB on disk and there are more than 1000 models. Check this [list](https://huggingface.co/Helsinki-NLP) for supported language pairs. The language codes may be inconsistent. Two digit codes can be found [here](https://developers.google.com/admin-sdk/directory/v1/languages) while three digit codes may require further searching.
+- Models that require BPE preprocessing are not supported.
+- All model names use the following format: `Helsinki-NLP/opus-mt-{src}-{tgt}`. Language codes formatted like `es_AR` usually refer to the `code_{region}`. For example, `es_AR` refers to Spanish from Argentina.
+- If a model can output multiple languages, prepend the desired output language to `src_txt` as shown below. New multilingual models from the [Tatoeba-Challenge](https://github.com/Helsinki-NLP/Tatoeba-Challenge) require 3 character language codes.
+
+```python
+
+from transformers import MarianMTModel, MarianTokenizer
+
+# Model trained on multiple source languages → multiple target languages
+# Example: multilingual to Arabic (arb)
+model_name = "Helsinki-NLP/opus-mt-mul-mul" # Tatoeba Challenge model
+tokenizer = MarianTokenizer.from_pretrained(model_name)
+model = MarianMTModel.from_pretrained(model_name)
+
+# Prepend the desired output language code (3-letter ISO 639-3)
+src_texts = ["arb>> Hello, how are you today?"]
+
+# Tokenize and translate
+inputs = tokenizer(src_texts, return_tensors="pt", padding=True, truncation=True)
+translated = model.generate(**inputs)
+
+# Decode and print result
+translated_texts = tokenizer.batch_decode(translated, skip_special_tokens=True)
+print(translated_texts[0])
+
+```
+
+- Older multilingual models use 2 character language codes.
+
+```python
+
+from transformers import MarianMTModel, MarianTokenizer
+
+# Example: older multilingual model (like en → many)
+model_name = "Helsinki-NLP/opus-mt-en-ROMANCE" # English → French, Spanish, Italian, etc.
+tokenizer = MarianTokenizer.from_pretrained(model_name)
+model = MarianMTModel.from_pretrained(model_name)
+
+# Prepend the 2-letter ISO 639-1 target language code (older format)
+src_texts = [">>fr<< Hello, how are you today?"]
+
+# Tokenize and translate
+inputs = tokenizer(src_texts, return_tensors="pt", padding=True, truncation=True)
+translated = model.generate(**inputs)
+
+# Decode and print result
+translated_texts = tokenizer.batch_decode(translated, skip_special_tokens=True)
+print(translated_texts[0])
+
+```
+
+## MarianConfig
+
+[[autodoc]] MarianConfig
+
+## MarianTokenizer
+
+[[autodoc]] MarianTokenizer
+ - build_inputs_with_special_tokens
+
+
+
+
+## MarianModel
+
+[[autodoc]] MarianModel
+ - forward
+
+## MarianMTModel
+
+[[autodoc]] MarianMTModel
+ - forward
+
+## MarianForCausalLM
+
+[[autodoc]] MarianForCausalLM
+ - forward
+
+
+
+
+## TFMarianModel
+
+[[autodoc]] TFMarianModel
+ - call
+
+## TFMarianMTModel
+
+[[autodoc]] TFMarianMTModel
+ - call
+
+
+
+
+## FlaxMarianModel
+
+[[autodoc]] FlaxMarianModel
+ - __call__
+
+## FlaxMarianMTModel
+
+[[autodoc]] FlaxMarianMTModel
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/markuplm.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/markuplm.md
new file mode 100644
index 0000000000000000000000000000000000000000..897b97853bd8bd890a48f161ccc488a8230a58ff
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/markuplm.md
@@ -0,0 +1,258 @@
+
+*This model was released on 2021-10-16 and added to Hugging Face Transformers on 2022-09-30.*
+
+# MarkupLM
+
+
+
+
+
+## Overview
+
+The MarkupLM model was proposed in [MarkupLM: Pre-training of Text and Markup Language for Visually-rich Document
+Understanding](https://huggingface.co/papers/2110.08518) by Junlong Li, Yiheng Xu, Lei Cui, Furu Wei. MarkupLM is BERT, but
+applied to HTML pages instead of raw text documents. The model incorporates additional embedding layers to improve
+performance, similar to [LayoutLM](layoutlm).
+
+The model can be used for tasks like question answering on web pages or information extraction from web pages. It obtains
+state-of-the-art results on 2 important benchmarks:
+- [WebSRC](https://x-lance.github.io/WebSRC/), a dataset for Web-Based Structural Reading Comprehension (a bit like SQuAD but for web pages)
+- [SWDE](https://www.researchgate.net/publication/221299838_From_one_tree_to_a_forest_a_unified_solution_for_structured_web_data_extraction), a dataset
+for information extraction from web pages (basically named-entity recognition on web pages)
+
+The abstract from the paper is the following:
+
+*Multimodal pre-training with text, layout, and image has made significant progress for Visually-rich Document
+Understanding (VrDU), especially the fixed-layout documents such as scanned document images. While, there are still a
+large number of digital documents where the layout information is not fixed and needs to be interactively and
+dynamically rendered for visualization, making existing layout-based pre-training approaches not easy to apply. In this
+paper, we propose MarkupLM for document understanding tasks with markup languages as the backbone such as
+HTML/XML-based documents, where text and markup information is jointly pre-trained. Experiment results show that the
+pre-trained MarkupLM significantly outperforms the existing strong baseline models on several document understanding
+tasks. The pre-trained model and code will be publicly available.*
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found [here](https://github.com/microsoft/unilm/tree/master/markuplm).
+
+## Usage tips
+
+- In addition to `input_ids`, [`~MarkupLMModel.forward`] expects 2 additional inputs, namely `xpath_tags_seq` and `xpath_subs_seq`.
+These are the XPATH tags and subscripts respectively for each token in the input sequence.
+- One can use [`MarkupLMProcessor`] to prepare all data for the model. Refer to the [usage guide](#usage-markuplmprocessor) for more info.
+
+
+
+ MarkupLM architecture. Taken from the original paper.
+
+## Usage: MarkupLMProcessor
+
+The easiest way to prepare data for the model is to use [`MarkupLMProcessor`], which internally combines a feature extractor
+([`MarkupLMFeatureExtractor`]) and a tokenizer ([`MarkupLMTokenizer`] or [`MarkupLMTokenizerFast`]). The feature extractor is
+used to extract all nodes and xpaths from the HTML strings, which are then provided to the tokenizer, which turns them into the
+token-level inputs of the model (`input_ids` etc.). Note that you can still use the feature extractor and tokenizer separately,
+if you only want to handle one of the two tasks.
+
+```python
+from transformers import MarkupLMFeatureExtractor, MarkupLMTokenizerFast, MarkupLMProcessor
+
+feature_extractor = MarkupLMFeatureExtractor()
+tokenizer = MarkupLMTokenizerFast.from_pretrained("microsoft/markuplm-base")
+processor = MarkupLMProcessor(feature_extractor, tokenizer)
+```
+
+In short, one can provide HTML strings (and possibly additional data) to [`MarkupLMProcessor`],
+and it will create the inputs expected by the model. Internally, the processor first uses
+[`MarkupLMFeatureExtractor`] to get a list of nodes and corresponding xpaths. The nodes and
+xpaths are then provided to [`MarkupLMTokenizer`] or [`MarkupLMTokenizerFast`], which converts them
+to token-level `input_ids`, `attention_mask`, `token_type_ids`, `xpath_subs_seq`, `xpath_tags_seq`.
+Optionally, one can provide node labels to the processor, which are turned into token-level `labels`.
+
+[`MarkupLMFeatureExtractor`] uses [Beautiful Soup](https://www.crummy.com/software/BeautifulSoup/bs4/doc/), a Python library for
+pulling data out of HTML and XML files, under the hood. Note that you can still use your own parsing solution of
+choice, and provide the nodes and xpaths yourself to [`MarkupLMTokenizer`] or [`MarkupLMTokenizerFast`].
+
+In total, there are 5 use cases that are supported by the processor. Below, we list them all. Note that each of these
+use cases work for both batched and non-batched inputs (we illustrate them for non-batched inputs).
+
+**Use case 1: web page classification (training, inference) + token classification (inference), parse_html = True**
+
+This is the simplest case, in which the processor will use the feature extractor to get all nodes and xpaths from the HTML.
+
+```python
+>>> from transformers import MarkupLMProcessor
+
+>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
+
+>>> html_string = """
+...
+...
+...
+... Hello world
+...
+...
+...
Welcome
+...
Here is my website.
+...
+... """
+
+>>> # note that you can also add provide all tokenizer parameters here such as padding, truncation
+>>> encoding = processor(html_string, return_tensors="pt")
+>>> print(encoding.keys())
+dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'xpath_tags_seq', 'xpath_subs_seq'])
+```
+
+**Use case 2: web page classification (training, inference) + token classification (inference), parse_html=False**
+
+In case one already has obtained all nodes and xpaths, one doesn't need the feature extractor. In that case, one should
+provide the nodes and corresponding xpaths themselves to the processor, and make sure to set `parse_html` to `False`.
+
+```python
+>>> from transformers import MarkupLMProcessor
+
+>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
+>>> processor.parse_html = False
+
+>>> nodes = ["hello", "world", "how", "are"]
+>>> xpaths = ["/html/body/div/li[1]/div/span", "/html/body/div/li[1]/div/span", "html/body", "html/body/div"]
+>>> encoding = processor(nodes=nodes, xpaths=xpaths, return_tensors="pt")
+>>> print(encoding.keys())
+dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'xpath_tags_seq', 'xpath_subs_seq'])
+```
+
+**Use case 3: token classification (training), parse_html=False**
+
+For token classification tasks (such as [SWDE](https://paperswithcode.com/dataset/swde)), one can also provide the
+corresponding node labels in order to train a model. The processor will then convert these into token-level `labels`.
+By default, it will only label the first wordpiece of a word, and label the remaining wordpieces with -100, which is the
+`ignore_index` of PyTorch's CrossEntropyLoss. In case you want all wordpieces of a word to be labeled, you can
+initialize the tokenizer with `only_label_first_subword` set to `False`.
+
+```python
+>>> from transformers import MarkupLMProcessor
+
+>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
+>>> processor.parse_html = False
+
+>>> nodes = ["hello", "world", "how", "are"]
+>>> xpaths = ["/html/body/div/li[1]/div/span", "/html/body/div/li[1]/div/span", "html/body", "html/body/div"]
+>>> node_labels = [1, 2, 2, 1]
+>>> encoding = processor(nodes=nodes, xpaths=xpaths, node_labels=node_labels, return_tensors="pt")
+>>> print(encoding.keys())
+dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'xpath_tags_seq', 'xpath_subs_seq', 'labels'])
+```
+
+**Use case 4: web page question answering (inference), parse_html=True**
+
+For question answering tasks on web pages, you can provide a question to the processor. By default, the
+processor will use the feature extractor to get all nodes and xpaths, and create [CLS] question tokens [SEP] word tokens [SEP].
+
+```python
+>>> from transformers import MarkupLMProcessor
+
+>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
+
+>>> html_string = """
+...
+...
+...
+... Hello world
+...
+...
+...
Welcome
+...
My name is Niels.
+...
+... """
+
+>>> question = "What's his name?"
+>>> encoding = processor(html_string, questions=question, return_tensors="pt")
+>>> print(encoding.keys())
+dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'xpath_tags_seq', 'xpath_subs_seq'])
+```
+
+**Use case 5: web page question answering (inference), parse_html=False**
+
+For question answering tasks (such as WebSRC), you can provide a question to the processor. If you have extracted
+all nodes and xpaths yourself, you can provide them directly to the processor. Make sure to set `parse_html` to `False`.
+
+```python
+>>> from transformers import MarkupLMProcessor
+
+>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
+>>> processor.parse_html = False
+
+>>> nodes = ["hello", "world", "how", "are"]
+>>> xpaths = ["/html/body/div/li[1]/div/span", "/html/body/div/li[1]/div/span", "html/body", "html/body/div"]
+>>> question = "What's his name?"
+>>> encoding = processor(nodes=nodes, xpaths=xpaths, questions=question, return_tensors="pt")
+>>> print(encoding.keys())
+dict_keys(['input_ids', 'token_type_ids', 'attention_mask', 'xpath_tags_seq', 'xpath_subs_seq'])
+```
+
+## Resources
+
+- [Demo notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/MarkupLM)
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+
+## MarkupLMConfig
+
+[[autodoc]] MarkupLMConfig
+ - all
+
+## MarkupLMFeatureExtractor
+
+[[autodoc]] MarkupLMFeatureExtractor
+ - __call__
+
+## MarkupLMTokenizer
+
+[[autodoc]] MarkupLMTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## MarkupLMTokenizerFast
+
+[[autodoc]] MarkupLMTokenizerFast
+ - all
+
+## MarkupLMProcessor
+
+[[autodoc]] MarkupLMProcessor
+ - __call__
+
+## MarkupLMModel
+
+[[autodoc]] MarkupLMModel
+ - forward
+
+## MarkupLMForSequenceClassification
+
+[[autodoc]] MarkupLMForSequenceClassification
+ - forward
+
+## MarkupLMForTokenClassification
+
+[[autodoc]] MarkupLMForTokenClassification
+ - forward
+
+## MarkupLMForQuestionAnswering
+
+[[autodoc]] MarkupLMForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mask2former.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mask2former.md
new file mode 100644
index 0000000000000000000000000000000000000000..fc4b87f836dbb6d3cc752f33408d21e9eb9ed7cd
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mask2former.md
@@ -0,0 +1,89 @@
+
+*This model was released on 2021-12-02 and added to Hugging Face Transformers on 2023-01-16.*
+
+# Mask2Former
+
+
+
+
+
+## Overview
+
+The Mask2Former model was proposed in [Masked-attention Mask Transformer for Universal Image Segmentation](https://huggingface.co/papers/2112.01527) by Bowen Cheng, Ishan Misra, Alexander G. Schwing, Alexander Kirillov, Rohit Girdhar. Mask2Former is a unified framework for panoptic, instance and semantic segmentation and features significant performance and efficiency improvements over [MaskFormer](maskformer).
+
+The abstract from the paper is the following:
+
+*Image segmentation groups pixels with different semantics, e.g., category or instance membership. Each choice
+of semantics defines a task. While only the semantics of each task differ, current research focuses on designing specialized architectures for each task. We present Masked-attention Mask Transformer (Mask2Former), a new architecture capable of addressing any image segmentation task (panoptic, instance or semantic). Its key components include masked attention, which extracts localized features by constraining cross-attention within predicted mask regions. In addition to reducing the research effort by at least three times, it outperforms the best specialized architectures by a significant margin on four popular datasets. Most notably, Mask2Former sets a new state-of-the-art for panoptic segmentation (57.8 PQ on COCO), instance segmentation (50.1 AP on COCO) and semantic segmentation (57.7 mIoU on ADE20K).*
+
+
+
+ Mask2Former architecture. Taken from the original paper.
+
+This model was contributed by [Shivalika Singh](https://huggingface.co/shivi) and [Alara Dirik](https://huggingface.co/adirik). The original code can be found [here](https://github.com/facebookresearch/Mask2Former).
+
+## Usage tips
+
+- Mask2Former uses the same preprocessing and postprocessing steps as [MaskFormer](maskformer). Use [`Mask2FormerImageProcessor`] or [`AutoImageProcessor`] to prepare images and optional targets for the model.
+- To get the final segmentation, depending on the task, you can call [`~Mask2FormerImageProcessor.post_process_semantic_segmentation`] or [`~Mask2FormerImageProcessor.post_process_instance_segmentation`] or [`~Mask2FormerImageProcessor.post_process_panoptic_segmentation`]. All three tasks can be solved using [`Mask2FormerForUniversalSegmentation`] output, panoptic segmentation accepts an optional `label_ids_to_fuse` argument to fuse instances of the target object/s (e.g. sky) together.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Mask2Former.
+
+- Demo notebooks regarding inference + fine-tuning Mask2Former on custom data can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Mask2Former).
+- Scripts for finetuning [`Mask2Former`] with [`Trainer`] or [Accelerate](https://huggingface.co/docs/accelerate/index) can be found [here](https://github.com/huggingface/transformers/tree/main/examples/pytorch/instance-segmentation).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we will review it.
+The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## Mask2FormerConfig
+
+[[autodoc]] Mask2FormerConfig
+
+## MaskFormer specific outputs
+
+[[autodoc]] models.mask2former.modeling_mask2former.Mask2FormerModelOutput
+
+[[autodoc]] models.mask2former.modeling_mask2former.Mask2FormerForUniversalSegmentationOutput
+
+## Mask2FormerModel
+
+[[autodoc]] Mask2FormerModel
+ - forward
+
+## Mask2FormerForUniversalSegmentation
+
+[[autodoc]] Mask2FormerForUniversalSegmentation
+ - forward
+
+## Mask2FormerImageProcessor
+
+[[autodoc]] Mask2FormerImageProcessor
+ - preprocess
+ - encode_inputs
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## Mask2FormerImageProcessorFast
+
+[[autodoc]] Mask2FormerImageProcessorFast
+ - preprocess
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/maskformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/maskformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..17ef4c876e0851ee0ca858468929605b51e7092b
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/maskformer.md
@@ -0,0 +1,105 @@
+
+*This model was released on 2021-07-13 and added to Hugging Face Transformers on 2022-03-02.*
+
+# MaskFormer
+
+
+
+
+
+
+
+This is a recently introduced model so the API hasn't been tested extensively. There may be some bugs or slight
+breaking changes to fix it in the future. If you see something strange, file a [Github Issue](https://github.com/huggingface/transformers/issues/new?assignees=&labels=&template=bug-report.md&title).
+
+
+
+## Overview
+
+The MaskFormer model was proposed in [Per-Pixel Classification is Not All You Need for Semantic Segmentation](https://huggingface.co/papers/2107.06278) by Bowen Cheng, Alexander G. Schwing, Alexander Kirillov. MaskFormer addresses semantic segmentation with a mask classification paradigm instead of performing classic pixel-level classification.
+
+The abstract from the paper is the following:
+
+*Modern approaches typically formulate semantic segmentation as a per-pixel classification task, while instance-level segmentation is handled with an alternative mask classification. Our key insight: mask classification is sufficiently general to solve both semantic- and instance-level segmentation tasks in a unified manner using the exact same model, loss, and training procedure. Following this observation, we propose MaskFormer, a simple mask classification model which predicts a set of binary masks, each associated with a single global class label prediction. Overall, the proposed mask classification-based method simplifies the landscape of effective approaches to semantic and panoptic segmentation tasks and shows excellent empirical results. In particular, we observe that MaskFormer outperforms per-pixel classification baselines when the number of classes is large. Our mask classification-based method outperforms both current state-of-the-art semantic (55.6 mIoU on ADE20K) and panoptic segmentation (52.7 PQ on COCO) models.*
+
+The figure below illustrates the architecture of MaskFormer. Taken from the [original paper](https://huggingface.co/papers/2107.06278).
+
+
+
+This model was contributed by [francesco](https://huggingface.co/francesco). The original code can be found [here](https://github.com/facebookresearch/MaskFormer).
+
+## Usage tips
+
+- MaskFormer's Transformer decoder is identical to the decoder of [DETR](detr). During training, the authors of DETR did find it helpful to use auxiliary losses in the decoder, especially to help the model output the correct number of objects of each class. If you set the parameter `use_auxiliary_loss` of [`MaskFormerConfig`] to `True`, then prediction feedforward neural networks and Hungarian losses are added after each decoder layer (with the FFNs sharing parameters).
+- If you want to train the model in a distributed environment across multiple nodes, then one should update the
+ `get_num_masks` function inside in the `MaskFormerLoss` class of `modeling_maskformer.py`. When training on multiple nodes, this should be
+ set to the average number of target masks across all nodes, as can be seen in the original implementation [here](https://github.com/facebookresearch/MaskFormer/blob/da3e60d85fdeedcb31476b5edd7d328826ce56cc/mask_former/modeling/criterion.py#L169).
+- One can use [`MaskFormerImageProcessor`] to prepare images for the model and optional targets for the model.
+- To get the final segmentation, depending on the task, you can call [`~MaskFormerImageProcessor.post_process_semantic_segmentation`] or [`~MaskFormerImageProcessor.post_process_panoptic_segmentation`]. Both tasks can be solved using [`MaskFormerForInstanceSegmentation`] output, panoptic segmentation accepts an optional `label_ids_to_fuse` argument to fuse instances of the target object/s (e.g. sky) together.
+
+## Resources
+
+
+
+- All notebooks that illustrate inference as well as fine-tuning on custom data with MaskFormer can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/MaskFormer).
+- Scripts for finetuning [`MaskFormer`] with [`Trainer`] or [Accelerate](https://huggingface.co/docs/accelerate/index) can be found [here](https://github.com/huggingface/transformers/tree/main/examples/pytorch/instance-segmentation).
+
+## MaskFormer specific outputs
+
+[[autodoc]] models.maskformer.modeling_maskformer.MaskFormerModelOutput
+
+[[autodoc]] models.maskformer.modeling_maskformer.MaskFormerForInstanceSegmentationOutput
+
+## MaskFormerConfig
+
+[[autodoc]] MaskFormerConfig
+
+## MaskFormerImageProcessor
+
+[[autodoc]] MaskFormerImageProcessor
+ - preprocess
+ - encode_inputs
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## MaskFormerImageProcessorFast
+
+[[autodoc]] MaskFormerImageProcessorFast
+ - preprocess
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## MaskFormerFeatureExtractor
+
+[[autodoc]] MaskFormerFeatureExtractor
+ - __call__
+ - encode_inputs
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## MaskFormerModel
+
+[[autodoc]] MaskFormerModel
+ - forward
+
+## MaskFormerForInstanceSegmentation
+
+[[autodoc]] MaskFormerForInstanceSegmentation
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/matcha.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/matcha.md
new file mode 100644
index 0000000000000000000000000000000000000000..e6a73c58fd02dd87b63d3b8b5b457d5a0b6b1bea
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/matcha.md
@@ -0,0 +1,81 @@
+
+*This model was released on 2022-12-19 and added to Hugging Face Transformers on 2023-06-20.*
+
+# MatCha
+
+
+
+
+
+## Overview
+
+MatCha has been proposed in the paper [MatCha: Enhancing Visual Language Pretraining with Math Reasoning and Chart Derendering](https://huggingface.co/papers/2212.09662), from Fangyu Liu, Francesco Piccinno, Syrine Krichene, Chenxi Pang, Kenton Lee, Mandar Joshi, Yasemin Altun, Nigel Collier, Julian Martin Eisenschlos.
+
+The abstract of the paper states the following:
+
+*Visual language data such as plots, charts, and infographics are ubiquitous in the human world. However, state-of-the-art vision-language models do not perform well on these data. We propose MatCha (Math reasoning and Chart derendering pretraining) to enhance visual language models' capabilities in jointly modeling charts/plots and language data. Specifically, we propose several pretraining tasks that cover plot deconstruction and numerical reasoning which are the key capabilities in visual language modeling. We perform the MatCha pretraining starting from Pix2Struct, a recently proposed image-to-text visual language model. On standard benchmarks such as PlotQA and ChartQA, the MatCha model outperforms state-of-the-art methods by as much as nearly 20%. We also examine how well MatCha pretraining transfers to domains such as screenshots, textbook diagrams, and document figures and observe overall improvement, verifying the usefulness of MatCha pretraining on broader visual language tasks.*
+
+## Model description
+
+MatCha is a model that is trained using `Pix2Struct` architecture. You can find more information about `Pix2Struct` in the [Pix2Struct documentation](https://huggingface.co/docs/transformers/main/en/model_doc/pix2struct).
+MatCha is a Visual Question Answering subset of `Pix2Struct` architecture. It renders the input question on the image and predicts the answer.
+
+## Usage
+
+Currently 6 checkpoints are available for MatCha:
+
+- `google/matcha`: the base MatCha model, used to fine-tune MatCha on downstream tasks
+- `google/matcha-chartqa`: MatCha model fine-tuned on ChartQA dataset. It can be used to answer questions about charts.
+- `google/matcha-plotqa-v1`: MatCha model fine-tuned on PlotQA dataset. It can be used to answer questions about plots.
+- `google/matcha-plotqa-v2`: MatCha model fine-tuned on PlotQA dataset. It can be used to answer questions about plots.
+- `google/matcha-chart2text-statista`: MatCha model fine-tuned on Statista dataset.
+- `google/matcha-chart2text-pew`: MatCha model fine-tuned on Pew dataset.
+
+The models finetuned on `chart2text-pew` and `chart2text-statista` are more suited for summarization, whereas the models finetuned on `plotqa` and `chartqa` are more suited for question answering.
+
+You can use these models as follows (example on a ChatQA dataset):
+
+```python
+from transformers import AutoProcessor, Pix2StructForConditionalGeneration
+import requests
+from PIL import Image
+
+model = Pix2StructForConditionalGeneration.from_pretrained("google/matcha-chartqa").to(0)
+processor = AutoProcessor.from_pretrained("google/matcha-chartqa")
+url = "https://raw.githubusercontent.com/vis-nlp/ChartQA/main/ChartQA%20Dataset/val/png/20294671002019.png"
+image = Image.open(requests.get(url, stream=True).raw)
+
+inputs = processor(images=image, text="Is the sum of all 4 places greater than Laos?", return_tensors="pt").to(0)
+predictions = model.generate(**inputs, max_new_tokens=512)
+print(processor.decode(predictions[0], skip_special_tokens=True))
+```
+
+## Fine-tuning
+
+To fine-tune MatCha, refer to the pix2struct [fine-tuning notebook](https://github.com/huggingface/notebooks/blob/main/examples/image_captioning_pix2struct.ipynb). For `Pix2Struct` models, we have found out that fine-tuning the model with Adafactor and cosine learning rate scheduler leads to faster convergence:
+```python
+from transformers.optimization import Adafactor, get_cosine_schedule_with_warmup
+
+optimizer = Adafactor(self.parameters(), scale_parameter=False, relative_step=False, lr=0.01, weight_decay=1e-05)
+scheduler = get_cosine_schedule_with_warmup(optimizer, num_warmup_steps=1000, num_training_steps=40000)
+```
+
+
+
+MatCha is a model that is trained using `Pix2Struct` architecture. You can find more information about `Pix2Struct` in the [Pix2Struct documentation](https://huggingface.co/docs/transformers/main/en/model_doc/pix2struct).
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mbart.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mbart.md
new file mode 100644
index 0000000000000000000000000000000000000000..aa2663208e1d7adf5c2097b8299f4d0fdce9065d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mbart.md
@@ -0,0 +1,211 @@
+
+*This model was released on 2020-01-22 and added to Hugging Face Transformers on 2020-11-16.*
+
+
+
+
+
+
+
+
+
+
+
+# mBART
+
+[mBART](https://huggingface.co/papers/2001.08210) is a multilingual machine translation model that pretrains the entire translation model (encoder-decoder) unlike previous methods that only focused on parts of the model. The model is trained on a denoising objective which reconstructs the corrupted text. This allows mBART to handle the source language and the target text to translate to.
+
+[mBART-50](https://huggingface.co/paper/2008.00401) is pretrained on an additional 25 languages.
+
+You can find all the original mBART checkpoints under the [AI at Meta](https://huggingface.co/facebook?search_models=mbart) organization.
+
+> [!TIP]
+> Click on the mBART models in the right sidebar for more examples of applying mBART to different language tasks.
+
+> [!NOTE]
+> The `head_mask` argument is ignored when using all attention implementation other than "eager". If you have a `head_mask` and want it to have effect, load the model with `XXXModel.from_pretrained(model_id, attn_implementation="eager")`
+
+The example below demonstrates how to translate text with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="translation",
+ model="facebook/mbart-large-50-many-to-many-mmt",
+ device=0,
+ torch_dtype=torch.float16,
+ src_lang="en_XX",
+ tgt_lang="fr_XX",
+)
+print(pipeline("UN Chief Says There Is No Military Solution in Syria"))
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+article_en = "UN Chief Says There Is No Military Solution in Syria"
+
+model = AutoModelForSeq2SeqLM.from_pretrained("facebook/mbart-large-50-many-to-many-mmt", torch_dtype=torch.bfloat16, attn_implementation="sdpa", device_map="auto")
+tokenizer = AutoTokenizer.from_pretrained("facebook/mbart-large-50-many-to-many-mmt")
+
+tokenizer.src_lang = "en_XX"
+encoded_hi = tokenizer(article_en, return_tensors="pt").to(model.device)
+generated_tokens = model.generate(**encoded_hi, forced_bos_token_id=tokenizer.lang_code_to_id["fr_XX"], cache_implementation="static")
+print(tokenizer.batch_decode(generated_tokens, skip_special_tokens=True))
+```
+
+
+
+
+## Notes
+
+- You can check the full list of language codes via `tokenizer.lang_code_to_id.keys()`.
+- mBART requires a special language id token in the source and target text during training. The source text format is `X [eos, src_lang_code]` where `X` is the source text. The target text format is `[tgt_lang_code] X [eos]`. The `bos` token is never used. The [`~PreTrainedTokenizerBase._call_`] encodes the source text format passed as the first argument or with the `text` keyword. The target text format is passed with the `text_label` keyword.
+- Set the `decoder_start_token_id` to the target language id for mBART.
+
+ ```py
+ import torch
+ from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+ model = AutoModelForSeq2SeqLM.from_pretrained("facebook/mbart-large-en-ro", torch_dtype=torch.bfloat16, attn_implementation="sdpa", device_map="auto")
+ tokenizer = MBartTokenizer.from_pretrained("facebook/mbart-large-en-ro", src_lang="en_XX")
+
+ article = "UN Chief Says There Is No Military Solution in Syria"
+ inputs = tokenizer(article, return_tensors="pt")
+
+ translated_tokens = model.generate(**inputs, decoder_start_token_id=tokenizer.lang_code_to_id["ro_RO"])
+ tokenizer.batch_decode(translated_tokens, skip_special_tokens=True)[0]
+ ```
+
+- mBART-50 has a different text format. The language id token is used as the prefix for the source and target text. The text format is `[lang_code] X [eos]` where `lang_code` is the source language id for the source text and target language id for the target text. `X` is the source or target text respectively.
+- Set the `eos_token_id` as the `decoder_start_token_id` for mBART-50. The target language id is used as the first generated token by passing `forced_bos_token_id` to [`~GenerationMixin.generate`].
+
+ ```py
+ import torch
+ from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+ model = AutoModelForSeq2SeqLM.from_pretrained("facebook/mbart-large-50-many-to-many-mmt", torch_dtype=torch.bfloat16, attn_implementation="sdpa", device_map="auto")
+ tokenizer = MBartTokenizer.from_pretrained("facebook/mbart-large-50-many-to-many-mmt")
+
+ article_ar = "الأمين العام للأمم المتحدة يقول إنه لا يوجد حل عسكري في سوريا."
+ tokenizer.src_lang = "ar_AR"
+
+ encoded_ar = tokenizer(article_ar, return_tensors="pt")
+ generated_tokens = model.generate(**encoded_ar, forced_bos_token_id=tokenizer.lang_code_to_id["en_XX"])
+ tokenizer.batch_decode(generated_tokens, skip_special_tokens=True)
+ ```
+
+## MBartConfig
+
+[[autodoc]] MBartConfig
+
+## MBartTokenizer
+
+[[autodoc]] MBartTokenizer
+ - build_inputs_with_special_tokens
+
+## MBartTokenizerFast
+
+[[autodoc]] MBartTokenizerFast
+
+## MBart50Tokenizer
+
+[[autodoc]] MBart50Tokenizer
+
+## MBart50TokenizerFast
+
+[[autodoc]] MBart50TokenizerFast
+
+
+
+
+## MBartModel
+
+[[autodoc]] MBartModel
+
+## MBartForConditionalGeneration
+
+[[autodoc]] MBartForConditionalGeneration
+
+## MBartForQuestionAnswering
+
+[[autodoc]] MBartForQuestionAnswering
+
+## MBartForSequenceClassification
+
+[[autodoc]] MBartForSequenceClassification
+
+## MBartForCausalLM
+
+[[autodoc]] MBartForCausalLM
+ - forward
+
+
+
+
+## TFMBartModel
+
+[[autodoc]] TFMBartModel
+ - call
+
+## TFMBartForConditionalGeneration
+
+[[autodoc]] TFMBartForConditionalGeneration
+ - call
+
+
+
+
+## FlaxMBartModel
+
+[[autodoc]] FlaxMBartModel
+ - __call__
+ - encode
+ - decode
+
+## FlaxMBartForConditionalGeneration
+
+[[autodoc]] FlaxMBartForConditionalGeneration
+ - __call__
+ - encode
+ - decode
+
+## FlaxMBartForSequenceClassification
+
+[[autodoc]] FlaxMBartForSequenceClassification
+ - __call__
+ - encode
+ - decode
+
+## FlaxMBartForQuestionAnswering
+
+[[autodoc]] FlaxMBartForQuestionAnswering
+ - __call__
+ - encode
+ - decode
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mctct.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mctct.md
new file mode 100644
index 0000000000000000000000000000000000000000..c766b1a825d6c82243a71dd38f159cb109da8252
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mctct.md
@@ -0,0 +1,84 @@
+
+*This model was released on 2021-10-30 and added to Hugging Face Transformers on 2023-06-20.*
+
+# M-CTC-T
+
+
+
+
+
+
+
+This model is in maintenance mode only, so we won't accept any new PRs changing its code.
+
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.30.0.
+You can do so by running the following command: `pip install -U transformers==4.30.0`.
+
+
+
+## Overview
+
+The M-CTC-T model was proposed in [Pseudo-Labeling For Massively Multilingual Speech Recognition](https://huggingface.co/papers/2111.00161) by Loren Lugosch, Tatiana Likhomanenko, Gabriel Synnaeve, and Ronan Collobert. The model is a 1B-param transformer encoder, with a CTC head over 8065 character labels and a language identification head over 60 language ID labels. It is trained on Common Voice (version 6.1, December 2020 release) and VoxPopuli. After training on Common Voice and VoxPopuli, the model is trained on Common Voice only. The labels are unnormalized character-level transcripts (punctuation and capitalization are not removed). The model takes as input Mel filterbank features from a 16Khz audio signal.
+
+The abstract from the paper is the following:
+
+*Semi-supervised learning through pseudo-labeling has become a staple of state-of-the-art monolingual
+speech recognition systems. In this work, we extend pseudo-labeling to massively multilingual speech
+recognition with 60 languages. We propose a simple pseudo-labeling recipe that works well even
+with low-resource languages: train a supervised multilingual model, fine-tune it with semi-supervised
+learning on a target language, generate pseudo-labels for that language, and train a final model using
+pseudo-labels for all languages, either from scratch or by fine-tuning. Experiments on the labeled
+Common Voice and unlabeled VoxPopuli datasets show that our recipe can yield a model with better
+performance for many languages that also transfers well to LibriSpeech.*
+
+This model was contributed by [cwkeam](https://huggingface.co/cwkeam). The original code can be found [here](https://github.com/flashlight/wav2letter/tree/main/recipes/mling_pl).
+
+## Usage tips
+
+The PyTorch version of this model is only available in torch 1.9 and higher.
+
+## Resources
+
+- [Automatic speech recognition task guide](../tasks/asr)
+
+## MCTCTConfig
+
+[[autodoc]] MCTCTConfig
+
+## MCTCTFeatureExtractor
+
+[[autodoc]] MCTCTFeatureExtractor
+ - __call__
+
+## MCTCTProcessor
+
+[[autodoc]] MCTCTProcessor
+ - __call__
+ - from_pretrained
+ - save_pretrained
+ - batch_decode
+ - decode
+
+## MCTCTModel
+
+[[autodoc]] MCTCTModel
+ - forward
+
+## MCTCTForCTC
+
+[[autodoc]] MCTCTForCTC
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mega.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mega.md
new file mode 100644
index 0000000000000000000000000000000000000000..614df2435530641b3630cb74e7eff4f9fc0abb59
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mega.md
@@ -0,0 +1,97 @@
+
+*This model was released on 2022-09-21 and added to Hugging Face Transformers on 2023-06-20.*
+
+# MEGA
+
+
+
+
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The MEGA model was proposed in [Mega: Moving Average Equipped Gated Attention](https://huggingface.co/papers/2209.10655) by Xuezhe Ma, Chunting Zhou, Xiang Kong, Junxian He, Liangke Gui, Graham Neubig, Jonathan May, and Luke Zettlemoyer.
+MEGA proposes a new approach to self-attention with each encoder layer having a multi-headed exponential moving average in addition to a single head of standard dot-product attention, giving the attention mechanism
+stronger positional biases. This allows MEGA to perform competitively to Transformers on standard benchmarks including LRA
+while also having significantly fewer parameters. MEGA's compute efficiency allows it to scale to very long sequences, making it an
+attractive option for long-document NLP tasks.
+
+The abstract from the paper is the following:
+
+ *The design choices in the Transformer attention mechanism, including weak inductive bias and quadratic computational complexity, have limited its application for modeling long sequences. In this paper, we introduce Mega, a simple, theoretically grounded, single-head gated attention mechanism equipped with (exponential) moving average to incorporate inductive bias of position-aware local dependencies into the position-agnostic attention mechanism. We further propose a variant of Mega that offers linear time and space complexity yet yields only minimal quality loss, by efficiently splitting the whole sequence into multiple chunks with fixed length. Extensive experiments on a wide range of sequence modeling benchmarks, including the Long Range Arena, neural machine translation, auto-regressive language modeling, and image and speech classification, show that Mega achieves significant improvements over other sequence models, including variants of Transformers and recent state space models. *
+
+This model was contributed by [mnaylor](https://huggingface.co/mnaylor).
+The original code can be found [here](https://github.com/facebookresearch/mega).
+
+
+## Usage tips
+
+- MEGA can perform quite well with relatively few parameters. See Appendix D in the MEGA paper for examples of architectural specs which perform well in various settings. If using MEGA as a decoder, be sure to set `bidirectional=False` to avoid errors with default bidirectional.
+- Mega-chunk is a variant of mega that reduces time and spaces complexity from quadratic to linear. Utilize chunking with MegaConfig.use_chunking and control chunk size with MegaConfig.chunk_size
+
+
+## Implementation Notes
+
+- The original implementation of MEGA had an inconsistent expectation of attention masks for padding and causal self-attention between the softmax attention and Laplace/squared ReLU method. This implementation addresses that inconsistency.
+- The original implementation did not include token type embeddings; this implementation adds support for these, with the option controlled by MegaConfig.add_token_type_embeddings
+
+
+## MegaConfig
+
+[[autodoc]] MegaConfig
+
+## MegaModel
+
+[[autodoc]] MegaModel
+ - forward
+
+## MegaForCausalLM
+
+[[autodoc]] MegaForCausalLM
+ - forward
+
+## MegaForMaskedLM
+
+[[autodoc]] MegaForMaskedLM
+ - forward
+
+## MegaForSequenceClassification
+
+[[autodoc]] MegaForSequenceClassification
+ - forward
+
+## MegaForMultipleChoice
+
+[[autodoc]] MegaForMultipleChoice
+ - forward
+
+## MegaForTokenClassification
+
+[[autodoc]] MegaForTokenClassification
+ - forward
+
+## MegaForQuestionAnswering
+
+[[autodoc]] MegaForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/megatron-bert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/megatron-bert.md
new file mode 100644
index 0000000000000000000000000000000000000000..f8845556f8f1b48e8eeb0319cc991f16b71e4f21
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/megatron-bert.md
@@ -0,0 +1,146 @@
+
+*This model was released on 2019-09-17 and added to Hugging Face Transformers on 2021-04-08.*
+
+# MegatronBERT
+
+
+
+
+
+## Overview
+
+The MegatronBERT model was proposed in [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model
+Parallelism](https://huggingface.co/papers/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley,
+Jared Casper and Bryan Catanzaro.
+
+The abstract from the paper is the following:
+
+*Recent work in language modeling demonstrates that training large transformer models advances the state of the art in
+Natural Language Processing applications. However, very large models can be quite difficult to train due to memory
+constraints. In this work, we present our techniques for training very large transformer models and implement a simple,
+efficient intra-layer model parallel approach that enables training transformer models with billions of parameters. Our
+approach does not require a new compiler or library changes, is orthogonal and complimentary to pipeline model
+parallelism, and can be fully implemented with the insertion of a few communication operations in native PyTorch. We
+illustrate this approach by converging transformer based models up to 8.3 billion parameters using 512 GPUs. We sustain
+15.1 PetaFLOPs across the entire application with 76% scaling efficiency when compared to a strong single GPU baseline
+that sustains 39 TeraFLOPs, which is 30% of peak FLOPs. To demonstrate that large language models can further advance
+the state of the art (SOTA), we train an 8.3 billion parameter transformer language model similar to GPT-2 and a 3.9
+billion parameter model similar to BERT. We show that careful attention to the placement of layer normalization in
+BERT-like models is critical to achieving increased performance as the model size grows. Using the GPT-2 model we
+achieve SOTA results on the WikiText103 (10.8 compared to SOTA perplexity of 15.8) and LAMBADA (66.5% compared to SOTA
+accuracy of 63.2%) datasets. Our BERT model achieves SOTA results on the RACE dataset (90.9% compared to SOTA accuracy
+of 89.4%).*
+
+This model was contributed by [jdemouth](https://huggingface.co/jdemouth). The original code can be found [here](https://github.com/NVIDIA/Megatron-LM).
+That repository contains a multi-GPU and multi-node implementation of the Megatron Language models. In particular,
+it contains a hybrid model parallel approach using "tensor parallel" and "pipeline parallel" techniques.
+
+## Usage tips
+
+We have provided pretrained [BERT-345M](https://ngc.nvidia.com/catalog/models/nvidia:megatron_bert_345m) checkpoints
+for use to evaluate or finetuning downstream tasks.
+
+To access these checkpoints, first [sign up](https://ngc.nvidia.com/signup) for and setup the NVIDIA GPU Cloud (NGC)
+Registry CLI. Further documentation for downloading models can be found in the [NGC documentation](https://docs.nvidia.com/dgx/ngc-registry-cli-user-guide/index.html#topic_6_4_1).
+
+Alternatively, you can directly download the checkpoints using:
+
+BERT-345M-uncased:
+
+```bash
+wget --content-disposition https://api.ngc.nvidia.com/v2/models/nvidia/megatron_bert_345m/versions/v0.1_uncased/zip
+-O megatron_bert_345m_v0_1_uncased.zip
+```
+
+BERT-345M-cased:
+
+```bash
+wget --content-disposition https://api.ngc.nvidia.com/v2/models/nvidia/megatron_bert_345m/versions/v0.1_cased/zip -O
+megatron_bert_345m_v0_1_cased.zip
+```
+
+Once you have obtained the checkpoints from NVIDIA GPU Cloud (NGC), you have to convert them to a format that will
+easily be loaded by Hugging Face Transformers and our port of the BERT code.
+
+The following commands allow you to do the conversion. We assume that the folder `models/megatron_bert` contains
+`megatron_bert_345m_v0_1_{cased, uncased}.zip` and that the commands are run from inside that folder:
+
+```bash
+python3 $PATH_TO_TRANSFORMERS/models/megatron_bert/convert_megatron_bert_checkpoint.py megatron_bert_345m_v0_1_uncased.zip
+```
+
+```bash
+python3 $PATH_TO_TRANSFORMERS/models/megatron_bert/convert_megatron_bert_checkpoint.py megatron_bert_345m_v0_1_cased.zip
+```
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## MegatronBertConfig
+
+[[autodoc]] MegatronBertConfig
+
+## MegatronBertModel
+
+[[autodoc]] MegatronBertModel
+ - forward
+
+## MegatronBertForMaskedLM
+
+[[autodoc]] MegatronBertForMaskedLM
+ - forward
+
+## MegatronBertForCausalLM
+
+[[autodoc]] MegatronBertForCausalLM
+ - forward
+
+## MegatronBertForNextSentencePrediction
+
+[[autodoc]] MegatronBertForNextSentencePrediction
+ - forward
+
+## MegatronBertForPreTraining
+
+[[autodoc]] MegatronBertForPreTraining
+ - forward
+
+## MegatronBertForSequenceClassification
+
+[[autodoc]] MegatronBertForSequenceClassification
+ - forward
+
+## MegatronBertForMultipleChoice
+
+[[autodoc]] MegatronBertForMultipleChoice
+ - forward
+
+## MegatronBertForTokenClassification
+
+[[autodoc]] MegatronBertForTokenClassification
+ - forward
+
+## MegatronBertForQuestionAnswering
+
+[[autodoc]] MegatronBertForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/megatron_gpt2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/megatron_gpt2.md
new file mode 100644
index 0000000000000000000000000000000000000000..5ba4c712930610440015622dab2b714297ef6ee6
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/megatron_gpt2.md
@@ -0,0 +1,85 @@
+
+*This model was released on 2019-09-17 and added to Hugging Face Transformers on 2021-10-01.*
+
+# MegatronGPT2
+
+
+
+
+
+
+
+## Overview
+
+The MegatronGPT2 model was proposed in [Megatron-LM: Training Multi-Billion Parameter Language Models Using Model
+Parallelism](https://huggingface.co/papers/1909.08053) by Mohammad Shoeybi, Mostofa Patwary, Raul Puri, Patrick LeGresley,
+Jared Casper and Bryan Catanzaro.
+
+The abstract from the paper is the following:
+
+*Recent work in language modeling demonstrates that training large transformer models advances the state of the art in
+Natural Language Processing applications. However, very large models can be quite difficult to train due to memory
+constraints. In this work, we present our techniques for training very large transformer models and implement a simple,
+efficient intra-layer model parallel approach that enables training transformer models with billions of parameters. Our
+approach does not require a new compiler or library changes, is orthogonal and complimentary to pipeline model
+parallelism, and can be fully implemented with the insertion of a few communication operations in native PyTorch. We
+illustrate this approach by converging transformer based models up to 8.3 billion parameters using 512 GPUs. We sustain
+15.1 PetaFLOPs across the entire application with 76% scaling efficiency when compared to a strong single GPU baseline
+that sustains 39 TeraFLOPs, which is 30% of peak FLOPs. To demonstrate that large language models can further advance
+the state of the art (SOTA), we train an 8.3 billion parameter transformer language model similar to GPT-2 and a 3.9
+billion parameter model similar to BERT. We show that careful attention to the placement of layer normalization in
+BERT-like models is critical to achieving increased performance as the model size grows. Using the GPT-2 model we
+achieve SOTA results on the WikiText103 (10.8 compared to SOTA perplexity of 15.8) and LAMBADA (66.5% compared to SOTA
+accuracy of 63.2%) datasets. Our BERT model achieves SOTA results on the RACE dataset (90.9% compared to SOTA accuracy
+of 89.4%).*
+
+This model was contributed by [jdemouth](https://huggingface.co/jdemouth). The original code can be found [here](https://github.com/NVIDIA/Megatron-LM).
+That repository contains a multi-GPU and multi-node implementation of the Megatron Language models. In particular, it
+contains a hybrid model parallel approach using "tensor parallel" and "pipeline parallel" techniques.
+
+## Usage tips
+
+We have provided pretrained [GPT2-345M](https://ngc.nvidia.com/catalog/models/nvidia:megatron_lm_345m) checkpoints
+for use to evaluate or finetuning downstream tasks.
+
+To access these checkpoints, first [sign up](https://ngc.nvidia.com/signup) for and setup the NVIDIA GPU Cloud (NGC)
+Registry CLI. Further documentation for downloading models can be found in the [NGC documentation](https://docs.nvidia.com/dgx/ngc-registry-cli-user-guide/index.html#topic_6_4_1).
+
+Alternatively, you can directly download the checkpoints using:
+
+```bash
+wget --content-disposition https://api.ngc.nvidia.com/v2/models/nvidia/megatron_lm_345m/versions/v0.0/zip -O
+megatron_gpt2_345m_v0_0.zip
+```
+
+Once you have obtained the checkpoint from NVIDIA GPU Cloud (NGC), you have to convert it to a format that will easily
+be loaded by Hugging Face Transformers GPT2 implementation.
+
+The following command allows you to do the conversion. We assume that the folder `models/megatron_gpt2` contains
+`megatron_gpt2_345m_v0_0.zip` and that the command is run from that folder:
+
+```bash
+python3 $PATH_TO_TRANSFORMERS/models/megatron_gpt2/convert_megatron_gpt2_checkpoint.py megatron_gpt2_345m_v0_0.zip
+```
+
+
+
+ MegatronGPT2 architecture is the same as OpenAI GPT-2 . Refer to [GPT-2 documentation](gpt2) for information on
+ configuration classes and their parameters.
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mgp-str.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mgp-str.md
new file mode 100644
index 0000000000000000000000000000000000000000..d6706d7fa64fb4e597b47795664fc865e682212c
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mgp-str.md
@@ -0,0 +1,93 @@
+
+*This model was released on 2022-09-08 and added to Hugging Face Transformers on 2023-03-13.*
+
+# MGP-STR
+
+
+
+
+
+## Overview
+
+The MGP-STR model was proposed in [Multi-Granularity Prediction for Scene Text Recognition](https://huggingface.co/papers/2209.03592) by Peng Wang, Cheng Da, and Cong Yao. MGP-STR is a conceptually **simple** yet **powerful** vision Scene Text Recognition (STR) model, which is built upon the [Vision Transformer (ViT)](vit). To integrate linguistic knowledge, Multi-Granularity Prediction (MGP) strategy is proposed to inject information from the language modality into the model in an implicit way.
+
+The abstract from the paper is the following:
+
+*Scene text recognition (STR) has been an active research topic in computer vision for years. To tackle this challenging problem, numerous innovative methods have been successively proposed and incorporating linguistic knowledge into STR models has recently become a prominent trend. In this work, we first draw inspiration from the recent progress in Vision Transformer (ViT) to construct a conceptually simple yet powerful vision STR model, which is built upon ViT and outperforms previous state-of-the-art models for scene text recognition, including both pure vision models and language-augmented methods. To integrate linguistic knowledge, we further propose a Multi-Granularity Prediction strategy to inject information from the language modality into the model in an implicit way, i.e. , subword representations (BPE and WordPiece) widely-used in NLP are introduced into the output space, in addition to the conventional character level representation, while no independent language model (LM) is adopted. The resultant algorithm (termed MGP-STR) is able to push the performance envelop of STR to an even higher level. Specifically, it achieves an average recognition accuracy of 93.35% on standard benchmarks.*
+
+
+
+ MGP-STR architecture. Taken from the original paper.
+
+MGP-STR is trained on two synthetic datasets [MJSynth](http://www.robots.ox.ac.uk/~vgg/data/text/) (MJ) and [SynthText](http://www.robots.ox.ac.uk/~vgg/data/scenetext/) (ST) without fine-tuning on other datasets. It achieves state-of-the-art results on six standard Latin scene text benchmarks, including 3 regular text datasets (IC13, SVT, IIIT) and 3 irregular ones (IC15, SVTP, CUTE).
+This model was contributed by [yuekun](https://huggingface.co/yuekun). The original code can be found [here](https://github.com/AlibabaResearch/AdvancedLiterateMachinery/tree/main/OCR/MGP-STR).
+
+## Inference example
+
+[`MgpstrModel`] accepts images as input and generates three types of predictions, which represent textual information at different granularities.
+The three types of predictions are fused to give the final prediction result.
+
+The [`ViTImageProcessor`] class is responsible for preprocessing the input image and
+[`MgpstrTokenizer`] decodes the generated character tokens to the target string. The
+[`MgpstrProcessor`] wraps [`ViTImageProcessor`] and [`MgpstrTokenizer`]
+into a single instance to both extract the input features and decode the predicted token ids.
+
+- Step-by-step Optical Character Recognition (OCR)
+
+```py
+>>> from transformers import MgpstrProcessor, MgpstrForSceneTextRecognition
+>>> import requests
+>>> from PIL import Image
+
+>>> processor = MgpstrProcessor.from_pretrained('alibaba-damo/mgp-str-base')
+>>> model = MgpstrForSceneTextRecognition.from_pretrained('alibaba-damo/mgp-str-base')
+
+>>> # load image from the IIIT-5k dataset
+>>> url = "https://i.postimg.cc/ZKwLg2Gw/367-14.png"
+>>> image = Image.open(requests.get(url, stream=True).raw).convert("RGB")
+
+>>> pixel_values = processor(images=image, return_tensors="pt").pixel_values
+>>> outputs = model(pixel_values)
+
+>>> generated_text = processor.batch_decode(outputs.logits)['generated_text']
+```
+
+## MgpstrConfig
+
+[[autodoc]] MgpstrConfig
+
+## MgpstrTokenizer
+
+[[autodoc]] MgpstrTokenizer
+ - save_vocabulary
+
+## MgpstrProcessor
+
+[[autodoc]] MgpstrProcessor
+ - __call__
+ - batch_decode
+
+## MgpstrModel
+
+[[autodoc]] MgpstrModel
+ - forward
+
+## MgpstrForSceneTextRecognition
+
+[[autodoc]] MgpstrForSceneTextRecognition
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mimi.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mimi.md
new file mode 100644
index 0000000000000000000000000000000000000000..2d655aa5966081b0037310967c23d1e2a14a0cea
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mimi.md
@@ -0,0 +1,74 @@
+
+*This model was released on 2024-09-17 and added to Hugging Face Transformers on 2024-09-18.*
+
+
+
+
+
+
+
+
+
+# Mimi
+
+[Mimi](huggingface.co/papers/2410.00037) is a neural audio codec model with pretrained and quantized variants, designed for efficient speech representation and compression. The model operates at 1.1 kbps with a 12 Hz frame rate and uses a convolutional encoder-decoder architecture combined with a residual vector quantizer of 16 codebooks. Mimi outputs dual token streams i.e. semantic and acoustic to balance linguistic richness with high fidelity reconstruction. Key features include a causal streaming encoder for low-latency use, dual-path tokenization for flexible downstream generation, and integration readiness with large speech models like Moshi.
+
+You can find the original Mimi checkpoints under the [Kyutai](https://huggingface.co/kyutai/models?search=mimi) organization.
+
+>[!TIP]
+> This model was contributed by [ylacombe](https://huggingface.co/ylacombe).
+>
+> Click on the Mimi models in the right sidebar for more examples of how to apply Mimi.
+
+The example below demonstrates how to encode and decode audio with the [`AutoModel`] class.
+
+
+
+
+```python
+>>> from datasets import load_dataset, Audio
+>>> from transformers import MimiModel, AutoFeatureExtractor
+>>> librispeech_dummy = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+
+>>> # load model and feature extractor
+>>> model = MimiModel.from_pretrained("kyutai/mimi")
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("kyutai/mimi")
+
+>>> # load audio sample
+>>> librispeech_dummy = librispeech_dummy.cast_column("audio", Audio(sampling_rate=feature_extractor.sampling_rate))
+>>> audio_sample = librispeech_dummy[-1]["audio"]["array"]
+>>> inputs = feature_extractor(raw_audio=audio_sample, sampling_rate=feature_extractor.sampling_rate, return_tensors="pt")
+
+>>> encoder_outputs = model.encode(inputs["input_values"], inputs["padding_mask"])
+>>> audio_values = model.decode(encoder_outputs.audio_codes, inputs["padding_mask"])[0]
+>>> # or the equivalent with a forward pass
+>>> audio_values = model(inputs["input_values"], inputs["padding_mask"]).audio_values
+```
+
+
+
+
+## MimiConfig
+
+[[autodoc]] MimiConfig
+
+## MimiModel
+
+[[autodoc]] MimiModel
+ - decode
+ - encode
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/minimax.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/minimax.md
new file mode 100644
index 0000000000000000000000000000000000000000..4b96e567f572585673e9dc8702fea11123193caf
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/minimax.md
@@ -0,0 +1,190 @@
+
+*This model was released on 2025-01-14 and added to Hugging Face Transformers on 2025-06-04.*
+
+# MiniMax
+
+## Overview
+
+The MiniMax-Text-01 model was proposed in [MiniMax-01: Scaling Foundation Models with Lightning Attention](https://huggingface.co/papers/2501.08313) by MiniMax, Aonian Li, Bangwei Gong, Bo Yang, Boji Shan, Chang Liu, Cheng Zhu, Chunhao Zhang, Congchao Guo, Da Chen, Dong Li, Enwei Jiao, Gengxin Li, Guojun Zhang, Haohai Sun, Houze Dong, Jiadai Zhu, Jiaqi Zhuang, Jiayuan Song, Jin Zhu, Jingtao Han, Jingyang Li, Junbin Xie, Junhao Xu, Junjie Yan, Kaishun Zhang, Kecheng Xiao, Kexi Kang, Le Han, Leyang Wang, Lianfei Yu, Liheng Feng, Lin Zheng, Linbo Chai, Long Xing, Meizhi Ju, Mingyuan Chi, Mozhi Zhang, Peikai Huang, Pengcheng Niu, Pengfei Li, Pengyu Zhao, Qi Yang, Qidi Xu, Qiexiang Wang, Qin Wang, Qiuhui Li, Ruitao Leng, Shengmin Shi, Shuqi Yu, Sichen Li, Songquan Zhu, Tao Huang, Tianrun Liang, Weigao Sun, Weixuan Sun, Weiyu Cheng, Wenkai Li, Xiangjun Song, Xiao Su, Xiaodong Han, Xinjie Zhang, Xinzhu Hou, Xu Min, Xun Zou, Xuyang Shen, Yan Gong, Yingjie Zhu, Yipeng Zhou, Yiran Zhong, Yongyi Hu, Yuanxiang Fan, Yue Yu, Yufeng Yang, Yuhao Li, Yunan Huang, Yunji Li, Yunpeng Huang, Yunzhi Xu, Yuxin Mao, Zehan Li, Zekang Li, Zewei Tao, Zewen Ying, Zhaoyang Cong, Zhen Qin, Zhenhua Fan, Zhihang Yu, Zhuo Jiang, Zijia Wu.
+
+The abstract from the paper is the following:
+
+*We introduce MiniMax-01 series, including MiniMax-Text-01 and MiniMax-VL-01, which are comparable to top-tier models while offering superior capabilities in processing longer contexts. The core lies in lightning attention and its efficient scaling. To maximize computational capacity, we integrate it with Mixture of Experts (MoE), creating a model with 32 experts and 456 billion total parameters, of which 45.9 billion are activated for each token. We develop an optimized parallel strategy and highly efficient computation-communication overlap techniques for MoE and lightning attention. This approach enables us to conduct efficient training and inference on models with hundreds of billions of parameters across contexts spanning millions of tokens. The context window of MiniMax-Text-01 can reach up to 1 million tokens during training and extrapolate to 4 million tokens during inference at an affordable cost. Our vision-language model, MiniMax-VL-01 is built through continued training with 512 billion vision-language tokens. Experiments on both standard and in-house benchmarks show that our models match the performance of state-of-the-art models like GPT-4o and Claude-3.5-Sonnet while offering 20-32 times longer context window.*
+
+### Architectural details
+
+MiniMax is a powerful language model with 456 billion total parameters, of which 45.9 billion are activated per token. To better unlock the long context capabilities of the model, MiniMax adopts a hybrid architecture that combines Lightning Attention, Softmax Attention and Mixture-of-Experts (MoE). Leveraging advanced parallel strategies and innovative compute-communication overlap methods—such as Linear Attention Sequence Parallelism Plus (LASP+), varlen ring attention, Expert Tensor Parallel (ETP), etc., MiniMax's training context length is extended to 1 million tokens, and it can handle a context of up to 4 million tokens during the inference. On various academic benchmarks, MiniMax also demonstrates the performance of a top-tier model.
+
+The architecture of MiniMax is briefly described as follows:
+
+- Total Parameters: 456B
+- Activated Parameters per Token: 45.9B
+- Number Layers: 80
+- Hybrid Attention: a softmax attention is positioned after every 7 lightning attention.
+ - Number of attention heads: 64
+ - Attention head dimension: 128
+- Mixture of Experts:
+ - Number of experts: 32
+ - Expert hidden dimension: 9216
+ - Top-2 routing strategy
+- Positional Encoding: Rotary Position Embedding (RoPE) applied to half of the attention head dimension with a base frequency of 10,000,000
+- Hidden Size: 6144
+- Vocab Size: 200,064
+
+For more details refer to the [release blog post](https://www.minimaxi.com/en/news/minimax-01-series-2).
+
+### License
+
+`MiniMax` is released under the MINIMAX MODEL LICENSE AGREEMENT.
+
+## Usage tips
+
+The pre-trained model can be used as follows:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("MiniMaxAI/MiniMax-Text-01-hf", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("MiniMaxAI/MiniMax-Text-01-hf")
+
+>>> messages = [
+... {"role": "user", "content": "What is your favourite condiment?"},
+... {"role": "assistant", "content": "Well, I'm quite partial to a good squeeze of fresh lemon juice. It adds just the right amount of zesty flavour to whatever I'm cooking up in the kitchen!"},
+... {"role": "user", "content": "Do you have mayonnaise recipes?"}
+... ]
+
+>>> model_inputs = tokenizer.apply_chat_template(messages, return_tensors="pt").to(model.device)
+
+>>> generated_ids = model.generate(model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"Mayonnaise can be made as follows: (...)"
+```
+
+As can be seen, the instruction-tuned model requires a [chat template](../chat_templating) to be applied to make sure the inputs are prepared in the right format.
+
+## Speeding up MiniMax by using Flash Attention
+
+The code snippets above showcase inference without any optimization tricks. However, one can drastically speed up the model by leveraging [Flash Attention](../perf_train_gpu_one#flash-attention-2), which is a faster implementation of the attention mechanism used inside the model.
+
+First, make sure to install the latest version of Flash Attention 2 to include the sliding window attention feature.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Make also sure that you have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of the [flash attention repository](https://github.com/Dao-AILab/flash-attention). Make also sure to load your model in half-precision (e.g. `torch.float16`)
+
+To load and run a model using Flash Attention-2, refer to the snippet below:
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("MiniMaxAI/MiniMax-Text-01-hf", torch_dtype=torch.float16, attn_implementation="flash_attention_2", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("MiniMaxAI/MiniMax-Text-01-hf")
+
+>>> prompt = "My favourite condiment is"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to(model.device)
+>>> model.to(device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"The expected output"
+```
+
+### Sliding window Attention
+
+The current implementation supports the sliding window attention mechanism and memory efficient cache management.
+To enable sliding window attention, just make sure to have a `flash-attn` version that is compatible with sliding window attention (`>=2.3.0`).
+
+The Flash Attention-2 model uses also a more memory efficient cache slicing mechanism - as recommended per the official implementation of Mistral model that use rolling cache mechanism we keep the cache size fixed (`self.config.sliding_window`), support batched generation only for `padding_side="left"` and use the absolute position of the current token to compute the positional embedding.
+
+## Shrinking down MiniMax using quantization
+
+As the MiniMax model has 456 billion parameters, that would require about 912GB of GPU RAM in half precision (float16), since each parameter is stored in 2 bytes. However, one can shrink down the size of the model using [quantization](../quantization). If the model is quantized to 4 bits (or half a byte per parameter), about 228 GB of RAM is required.
+
+Quantizing a model is as simple as passing a `quantization_config` to the model. Below, we'll leverage the bitsandbytes quantization library (but refer to [this page](../quantization) for alternative quantization methods):
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+>>> # specify how to quantize the model
+>>> quantization_config = BitsAndBytesConfig(
+... load_in_4bit=True,
+... bnb_4bit_quant_type="nf4",
+... bnb_4bit_compute_dtype="torch.float16",
+... )
+
+>>> model = AutoModelForCausalLM.from_pretrained("MiniMaxAI/MiniMax-Text-01-hf", quantization_config=True, device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("MiniMaxAI/MiniMax-Text-01-hf")
+
+>>> prompt = "My favourite condiment is"
+
+>>> messages = [
+... {"role": "user", "content": "What is your favourite condiment?"},
+... {"role": "assistant", "content": "Well, I'm quite partial to a good squeeze of fresh lemon juice. It adds just the right amount of zesty flavour to whatever I'm cooking up in the kitchen!"},
+... {"role": "user", "content": "Do you have mayonnaise recipes?"}
+... ]
+
+>>> model_inputs = tokenizer.apply_chat_template(messages, return_tensors="pt").to(model.device)
+
+>>> generated_ids = model.generate(model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"The expected output"
+```
+
+This model was contributed by [geetu040](https://github.com/geetu040) and [Shakib-IO](https://github.com/Shakib-IO).
+The original code can be found [here](https://huggingface.co/MiniMaxAI/MiniMax-Text-01/blob/main/modeling_minimax_text_01.py).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with MiniMax. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- The [Alignment Handbook](https://github.com/huggingface/alignment-handbook) by Hugging Face includes scripts and recipes to perform supervised fine-tuning (SFT) and direct preference optimization with Mistral-7B. This includes scripts for full fine-tuning, QLoRa on a single GPU as well as multi-GPU fine-tuning.
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## MiniMaxConfig
+
+[[autodoc]] MiniMaxConfig
+
+## MiniMaxModel
+
+[[autodoc]] MiniMaxModel
+ - forward
+
+## MiniMaxForCausalLM
+
+[[autodoc]] MiniMaxForCausalLM
+ - forward
+
+## MiniMaxForSequenceClassification
+
+[[autodoc]] MiniMaxForSequenceClassification
+ - forward
+
+## MiniMaxForTokenClassification
+
+[[autodoc]] MiniMaxForTokenClassification
+ - forward
+
+## MiniMaxForQuestionAnswering
+[[autodoc]] MiniMaxForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mistral.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mistral.md
new file mode 100644
index 0000000000000000000000000000000000000000..dcda1f3983d4cf3843848c237d07f545095b5814
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mistral.md
@@ -0,0 +1,195 @@
+
+*This model was released on 2023-10-10 and added to Hugging Face Transformers on 2023-09-27.*
+
+
+
+
+
+
+
+
+
+
+
+
+# Mistral
+
+[Mistral](https://huggingface.co/papers/2310.06825) is a 7B parameter language model, available as a pretrained and instruction-tuned variant, focused on balancing
+the scaling costs of large models with performance and efficient inference. This model uses sliding window attention (SWA) trained with a 8K context length and a fixed cache size to handle longer sequences more effectively. Grouped-query attention (GQA) speeds up inference and reduces memory requirements. Mistral also features a byte-fallback BPE tokenizer to improve token handling and efficiency by ensuring characters are never mapped to out-of-vocabulary tokens.
+
+You can find all the original Mistral checkpoints under the [Mistral AI_](https://huggingface.co/mistralai) organization.
+
+> [!TIP]
+> Click on the Mistral models in the right sidebar for more examples of how to apply Mistral to different language tasks.
+
+The example below demonstrates how to chat with [`Pipeline`] or the [`AutoModel`], and from the command line.
+
+
+
+
+```python
+>>> import torch
+>>> from transformers import pipeline
+
+>>> messages = [
+... {"role": "user", "content": "What is your favourite condiment?"},
+... {"role": "assistant", "content": "Well, I'm quite partial to a good squeeze of fresh lemon juice. It adds just the right amount of zesty flavour to whatever I'm cooking up in the kitchen!"},
+... {"role": "user", "content": "Do you have mayonnaise recipes?"}
+... ]
+
+>>> chatbot = pipeline("text-generation", model="mistralai/Mistral-7B-Instruct-v0.3", torch_dtype=torch.bfloat16, device=0)
+>>> chatbot(messages)
+```
+
+
+
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-Instruct-v0.3", torch_dtype=torch.bfloat16, attn_implementation="sdpa", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-Instruct-v0.3")
+
+>>> messages = [
+... {"role": "user", "content": "What is your favourite condiment?"},
+... {"role": "assistant", "content": "Well, I'm quite partial to a good squeeze of fresh lemon juice. It adds just the right amount of zesty flavour to whatever I'm cooking up in the kitchen!"},
+... {"role": "user", "content": "Do you have mayonnaise recipes?"}
+... ]
+
+>>> model_inputs = tokenizer.apply_chat_template(messages, return_tensors="pt").to("cuda")
+
+>>> generated_ids = model.generate(model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"Mayonnaise can be made as follows: (...)"
+```
+
+
+
+
+```python
+echo -e "My favorite condiment is" | transformers chat mistralai/Mistral-7B-v0.3 --torch_dtype auto --device 0 --attn_implementation flash_attention_2
+```
+
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to 4-bits.
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+>>> # specify how to quantize the model
+>>> quantization_config = BitsAndBytesConfig(
+... load_in_4bit=True,
+... bnb_4bit_quant_type="nf4",
+... bnb_4bit_compute_dtype="torch.float16",
+... )
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mistral-7B-Instruct-v0.3", quantization_config=True, torch_dtype=torch.bfloat16, device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mistral-7B-Instruct-v0.3")
+
+>>> prompt = "My favourite condiment is"
+
+>>> messages = [
+... {"role": "user", "content": "What is your favourite condiment?"},
+... {"role": "assistant", "content": "Well, I'm quite partial to a good squeeze of fresh lemon juice. It adds just the right amount of zesty flavour to whatever I'm cooking up in the kitchen!"},
+... {"role": "user", "content": "Do you have mayonnaise recipes?"}
+... ]
+
+>>> model_inputs = tokenizer.apply_chat_template(messages, return_tensors="pt").to("cuda")
+
+>>> generated_ids = model.generate(model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"The expected output"
+```
+
+Use the [AttentionMaskVisualizer](https://github.com/huggingface/transformers/blob/beb9b5b02246b9b7ee81ddf938f93f44cfeaad19/src/transformers/utils/attention_visualizer.py#L139) to better understand what tokens the model can and cannot attend to.
+
+```py
+>>> from transformers.utils.attention_visualizer import AttentionMaskVisualizer
+
+>>> visualizer = AttentionMaskVisualizer("mistralai/Mistral-7B-Instruct-v0.3")
+>>> visualizer("Do you have mayonnaise recipes?")
+```
+
+
+
+# Mistral 3
+
+[Mistral 3](https://mistral.ai/news/mistral-small-3) is a latency optimized model with a lot fewer layers to reduce the time per forward pass. This model adds vision understanding and supports long context lengths of up to 128K tokens without compromising performance.
+
+You can find the original Mistral 3 checkpoints under the [Mistral AI](https://huggingface.co/mistralai/models?search=mistral-small-3) organization.
+
+
+> [!TIP]
+> This model was contributed by [cyrilvallez](https://huggingface.co/cyrilvallez) and [yonigozlan](https://huggingface.co/yonigozlan).
+> Click on the Mistral3 models in the right sidebar for more examples of how to apply Mistral3 to different tasks.
+
+The example below demonstrates how to generate text for an image with [`Pipeline`] and the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+messages = [
+ {"role": "user",
+ "content":[
+ {"type": "image",
+ "image": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg",},
+ {"type": "text", "text": "Describe this image."}
+ ,]
+ ,}
+,]
+
+pipeline = pipeline(
+ task="image-text-to-text",
+ model="mistralai/Mistral-Small-3.1-24B-Instruct-2503",
+ torch_dtype=torch.bfloat16,
+ device=0
+)
+outputs = pipeline(text=messages, max_new_tokens=50, return_full_text=False)
+
+outputs[0]["generated_text"]
+'The image depicts a vibrant and lush garden scene featuring a variety of wildflowers and plants. The central focus is on a large, pinkish-purple flower, likely a Greater Celandine (Chelidonium majus), with a'
+```
+
+
+
+```py
+import torch
+from transformers import AutoProcessor, AutoModelForImageTextToText, infer_device
+
+torch_device = infer_device()
+model_checkpoint = "mistralai/Mistral-Small-3.1-24B-Instruct-2503"
+processor = AutoProcessor.from_pretrained(model_checkpoint)
+model = AutoModelForImageTextToText.from_pretrained(
+ model_checkpoint,
+ device_map=torch_device,
+ torch_dtype=torch.bfloat16
+)
+
+messages = [
+ {"role": "user",
+ "content":[
+ {"type": "image",
+ "image": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg",},
+ {"type": "text", "text": "Describe this image."}
+ ,]
+ ,}
+,]
+
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True, return_dict=True,
+ return_tensors="pt").to(model.device, dtype=torch.bfloat16)
+
+generate_ids = model.generate(**inputs, max_new_tokens=20)
+decoded_output = processor.decode(generate_ids[0, inputs["input_ids"].shape[1] :], skip_special_tokens=True)
+
+decoded_output
+'The image depicts a vibrant and lush garden scene featuring a variety of wildflowers and plants. The central focus is on a large, pinkish-purple flower, likely a Greater Celandine (Chelidonium majus), with a'
+```
+
+
+
+## Notes
+
+- Mistral 3 supports text-only generation.
+```py
+import torch
+from transformers import AutoProcessor, AutoModelForImageTextToText, infer_device
+
+torch_device = infer_device()
+model_checkpoint = ".mistralai/Mistral-Small-3.1-24B-Instruct-2503"
+processor = AutoProcessor.from_pretrained(model_checkpoint)
+model = AutoModelForImageTextToText.from_pretrained(model_checkpoint, device_map=torch_device, torch_dtype=torch.bfloat16)
+
+SYSTEM_PROMPT = "You are a conversational agent that always answers straight to the point, always end your accurate response with an ASCII drawing of a cat."
+user_prompt = "Give me 5 non-formal ways to say 'See you later' in French."
+
+messages = [
+ {"role": "system", "content": SYSTEM_PROMPT},
+ {"role": "user", "content": user_prompt},
+]
+
+text = processor.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
+inputs = processor(text=text, return_tensors="pt").to(0, dtype=torch.float16)
+generate_ids = model.generate(**inputs, max_new_tokens=50, do_sample=False)
+decoded_output = processor.batch_decode(generate_ids[:, inputs["input_ids"].shape[1] :], skip_special_tokens=True)[0]
+
+print(decoded_output)
+"1. À plus tard!
+ 2. Salut, à plus!
+ 3. À toute!
+ 4. À la prochaine!
+ 5. Je me casse, à plus!
+
+```
+ /\_/\
+( o.o )
+ > ^ <
+```"
+````
+
+- Mistral 3 accepts batched image and text inputs.
+```py
+import torch
+from transformers import AutoProcessor, AutoModelForImageTextToText, infer_device
+
+torch_device = infer_device()
+model_checkpoint = "mistralai/Mistral-Small-3.1-24B-Instruct-2503"
+processor = AutoProcessor.from_pretrained(model_checkpoint)
+model = AutoModelForImageTextToText.from_pretrained(model_checkpoint, device_map=torch_device, torch_dtype=torch.bfloat16)
+
+messages = [
+ [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "https://llava-vl.github.io/static/images/view.jpg"},
+ {"type": "text", "text": "Write a haiku for this image"},
+ ],
+ },
+ ],
+ [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "https://www.ilankelman.org/stopsigns/australia.jpg"},
+ {"type": "text", "text": "Describe this image"},
+ ],
+ },
+ ],
+ ]
+
+
+ inputs = processor.apply_chat_template(messages, padding=True, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt").to(model.device, dtype=torch.bfloat16)
+
+ output = model.generate(**inputs, max_new_tokens=25)
+
+ decoded_outputs = processor.batch_decode(output, skip_special_tokens=True)
+ decoded_outputs
+["Write a haiku for this imageCalm waters reflect\nWhispers of the forest's breath\nPeace on wooden path"
+, "Describe this imageThe image depicts a vibrant street scene in what appears to be a Chinatown district. The focal point is a traditional Chinese"]
+```
+
+- Mistral 3 also supported batched image and text inputs with a different number of images for each text. The example below quantizes the model with bitsandbytes.
+
+```py
+import torch
+from transformers import AutoProcessor, AutoModelForImageTextToText, BitsAndBytesConfig, infer_device
+
+torch_device = infer_device()
+model_checkpoint = "mistralai/Mistral-Small-3.1-24B-Instruct-2503"
+processor = AutoProcessor.from_pretrained(model_checkpoint)
+quantization_config = BitsAndBytesConfig(load_in_4bit=True)
+model = AutoModelForImageTextToText.from_pretrained(
+ model_checkpoint, quantization_config=quantization_config
+ )
+
+messages = [
+ [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "https://llava-vl.github.io/static/images/view.jpg"},
+ {"type": "text", "text": "Write a haiku for this image"},
+ ],
+ },
+ ],
+ [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg"},
+ {"type": "image", "url": "https://thumbs.dreamstime.com/b/golden-gate-bridge-san-francisco-purple-flowers-california-echium-candicans-36805947.jpg"},
+ {"type": "text", "text": "These images depict two different landmarks. Can you identify them?"},
+ ],
+ },
+ ],
+ ]
+
+ inputs = processor.apply_chat_template(messages, padding=True, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt").to(model.device, dtype=torch.bfloat16)
+
+ output = model.generate(**inputs, max_new_tokens=25)
+
+ decoded_outputs = processor.batch_decode(output, skip_special_tokens=True)
+ decoded_outputs
+["Write a haiku for this imageSure, here is a haiku inspired by the image:\n\nCalm lake's wooden path\nSilent forest stands guard\n", "These images depict two different landmarks. Can you identify them? Certainly! The images depict two iconic landmarks:\n\n1. The first image shows the Statue of Liberty in New York City."]
+```
+
+## Mistral3Config
+
+[[autodoc]] Mistral3Config
+
+## MistralCommonTokenizer
+
+[[autodoc]] MistralCommonTokenizer
+
+## Mistral3Model
+
+[[autodoc]] Mistral3Model
+
+## Mistral3ForConditionalGeneration
+
+[[autodoc]] Mistral3ForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mixtral.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mixtral.md
new file mode 100644
index 0000000000000000000000000000000000000000..07a6ffe82bb65e7b037f32e86e53fef892aa4b11
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mixtral.md
@@ -0,0 +1,225 @@
+
+*This model was released on 2023-12-11 and added to Hugging Face Transformers on 2023-12-11.*
+
+# Mixtral
+
+
+
+
+
+
+
+
+## Overview
+
+[Mixtral-8x7B](https://huggingface.co/papers/2401.04088) was introduced in the [Mixtral of Experts blogpost](https://mistral.ai/news/mixtral-of-experts/) by Albert Jiang, Alexandre Sablayrolles, Arthur Mensch, Chris Bamford, Devendra Singh Chaplot, Diego de las Casas, Florian Bressand, Gianna Lengyel, Guillaume Lample, Lélio Renard Lavaud, Lucile Saulnier, Marie-Anne Lachaux, Pierre Stock, Teven Le Scao, Thibaut Lavril, Thomas Wang, Timothée Lacroix, William El Sayed.
+
+The introduction of the blog post says:
+
+*Today, the team is proud to release Mixtral 8x7B, a high-quality sparse mixture of experts models (SMoE) with open weights. Licensed under Apache 2.0. Mixtral outperforms Llama 2 70B on most benchmarks with 6x faster inference. It is the strongest open-weight model with a permissive license and the best model overall regarding cost/performance trade-offs. In particular, it matches or outperforms GPT3.5 on most standard benchmarks.*
+
+Mixtral-8x7B is the second large language model (LLM) released by [mistral.ai](https://mistral.ai/), after [Mistral-7B](mistral).
+
+### Architectural details
+
+Mixtral-8x7B is a decoder-only Transformer with the following architectural choices:
+
+- Mixtral is a Mixture of Experts (MoE) model with 8 experts per MLP, with a total of 45 billion parameters. To learn more about mixture-of-experts, refer to the [blog post](https://huggingface.co/blog/moe).
+- Despite the model having 45 billion parameters, the compute required for a single forward pass is the same as that of a 14 billion parameter model. This is because even though each of the experts have to be loaded in RAM (70B like ram requirement) each token from the hidden states are dispatched twice (top 2 routing) and thus the compute (the operation required at each forward computation) is just 2 X sequence_length.
+
+The following implementation details are shared with Mistral AI's first model [Mistral-7B](mistral):
+- Sliding Window Attention - Trained with 8k context length and fixed cache size, with a theoretical attention span of 128K tokens
+- GQA (Grouped Query Attention) - allowing faster inference and lower cache size.
+- Byte-fallback BPE tokenizer - ensures that characters are never mapped to out of vocabulary tokens.
+
+For more details refer to the [release blog post](https://mistral.ai/news/mixtral-of-experts/).
+
+### License
+
+`Mixtral-8x7B` is released under the Apache 2.0 license.
+
+## Usage tips
+
+The Mistral team has released 2 checkpoints:
+- a base model, [Mixtral-8x7B-v0.1](https://huggingface.co/mistralai/Mixtral-8x7B-v0.1), which has been pre-trained to predict the next token on internet-scale data.
+- an instruction tuned model, [Mixtral-8x7B-Instruct-v0.1](https://huggingface.co/mistralai/Mixtral-8x7B-Instruct-v0.1), which is the base model optimized for chat purposes using supervised fine-tuning (SFT) and direct preference optimization (DPO).
+
+The base model can be used as follows:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mixtral-8x7B-v0.1", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mixtral-8x7B-v0.1")
+
+>>> prompt = "My favourite condiment is"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to(model.device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"My favourite condiment is to ..."
+```
+
+The instruction tuned model can be used as follows:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mixtral-8x7B-Instruct-v0.1", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mixtral-8x7B-Instruct-v0.1")
+
+>>> messages = [
+... {"role": "user", "content": "What is your favourite condiment?"},
+... {"role": "assistant", "content": "Well, I'm quite partial to a good squeeze of fresh lemon juice. It adds just the right amount of zesty flavour to whatever I'm cooking up in the kitchen!"},
+... {"role": "user", "content": "Do you have mayonnaise recipes?"}
+... ]
+
+>>> model_inputs = tokenizer.apply_chat_template(messages, return_tensors="pt").to(model.device)
+
+>>> generated_ids = model.generate(model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"Mayonnaise can be made as follows: (...)"
+```
+
+As can be seen, the instruction-tuned model requires a [chat template](../chat_templating) to be applied to make sure the inputs are prepared in the right format.
+
+## Speeding up Mixtral by using Flash Attention
+
+The code snippets above showcase inference without any optimization tricks. However, one can drastically speed up the model by leveraging [Flash Attention](../perf_train_gpu_one#flash-attention-2), which is a faster implementation of the attention mechanism used inside the model.
+
+First, make sure to install the latest version of Flash Attention 2 to include the sliding window attention feature.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Make also sure that you have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of the [flash attention repository](https://github.com/Dao-AILab/flash-attention). Make also sure to load your model in half-precision (e.g. `torch.float16`)
+
+To load and run a model using Flash Attention-2, refer to the snippet below:
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mixtral-8x7B-v0.1", torch_dtype=torch.float16, attn_implementation="flash_attention_2", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mixtral-8x7B-v0.1")
+
+>>> prompt = "My favourite condiment is"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to(model.device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"The expected output"
+```
+
+### Expected speedups
+
+Below is a expected speedup diagram that compares pure inference time between the native implementation in transformers using `mistralai/Mixtral-8x7B-v0.1` checkpoint and the Flash Attention 2 version of the model.
+
+
+
+
+
+### Sliding window Attention
+
+The current implementation supports the sliding window attention mechanism and memory efficient cache management.
+To enable sliding window attention, just make sure to have a `flash-attn` version that is compatible with sliding window attention (`>=2.3.0`).
+
+The Flash Attention-2 model uses also a more memory efficient cache slicing mechanism - as recommended per the official implementation of Mistral model that use rolling cache mechanism we keep the cache size fixed (`self.config.sliding_window`), support batched generation only for `padding_side="left"` and use the absolute position of the current token to compute the positional embedding.
+
+## Shrinking down Mixtral using quantization
+
+As the Mixtral model has 45 billion parameters, that would require about 90GB of GPU RAM in half precision (float16), since each parameter is stored in 2 bytes. However, one can shrink down the size of the model using [quantization](../quantization). If the model is quantized to 4 bits (or half a byte per parameter), a single A100 with 40GB of RAM is enough to fit the entire model, as in that case only about 27 GB of RAM is required.
+
+Quantizing a model is as simple as passing a `quantization_config` to the model. Below, we'll leverage the bitsandbytes quantization library (but refer to [this page](../quantization) for alternative quantization methods):
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+>>> # specify how to quantize the model
+>>> quantization_config = BitsAndBytesConfig(
+... load_in_4bit=True,
+... bnb_4bit_quant_type="nf4",
+... bnb_4bit_compute_dtype="torch.float16",
+... )
+
+>>> model = AutoModelForCausalLM.from_pretrained("mistralai/Mixtral-8x7B-Instruct-v0.1", quantization_config=True, device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("mistralai/Mixtral-8x7B-Instruct-v0.1")
+
+>>> prompt = "My favourite condiment is"
+
+>>> messages = [
+... {"role": "user", "content": "What is your favourite condiment?"},
+... {"role": "assistant", "content": "Well, I'm quite partial to a good squeeze of fresh lemon juice. It adds just the right amount of zesty flavour to whatever I'm cooking up in the kitchen!"},
+... {"role": "user", "content": "Do you have mayonnaise recipes?"}
+... ]
+
+>>> model_inputs = tokenizer.apply_chat_template(messages, return_tensors="pt").to(model.device)
+
+>>> generated_ids = model.generate(model_inputs, max_new_tokens=100, do_sample=True)
+>>> tokenizer.batch_decode(generated_ids)[0]
+"The expected output"
+```
+
+This model was contributed by [Younes Belkada](https://huggingface.co/ybelkada) and [Arthur Zucker](https://huggingface.co/ArthurZ) .
+The original code can be found [here](https://github.com/mistralai/mistral-src).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Mixtral. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
+
+- A demo notebook to perform supervised fine-tuning (SFT) of Mixtral-8x7B can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/Mistral/Supervised_fine_tuning_(SFT)_of_an_LLM_using_Hugging_Face_tooling.ipynb). 🌎
+- A [blog post](https://medium.com/@prakharsaxena11111/finetuning-mixtral-7bx8-6071b0ebf114) on fine-tuning Mixtral-8x7B using PEFT. 🌎
+- The [Alignment Handbook](https://github.com/huggingface/alignment-handbook) by Hugging Face includes scripts and recipes to perform supervised fine-tuning (SFT) and direct preference optimization with Mistral-7B. This includes scripts for full fine-tuning, QLoRa on a single accelerator as well as multi-accelerator fine-tuning.
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## MixtralConfig
+
+[[autodoc]] MixtralConfig
+
+## MistralCommonTokenizer
+
+[[autodoc]] MistralCommonTokenizer
+
+## MixtralModel
+
+[[autodoc]] MixtralModel
+ - forward
+
+## MixtralForCausalLM
+
+[[autodoc]] MixtralForCausalLM
+ - forward
+
+## MixtralForSequenceClassification
+
+[[autodoc]] MixtralForSequenceClassification
+ - forward
+
+## MixtralForTokenClassification
+
+[[autodoc]] MixtralForTokenClassification
+ - forward
+
+## MixtralForQuestionAnswering
+[[autodoc]] MixtralForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mlcd.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mlcd.md
new file mode 100644
index 0000000000000000000000000000000000000000..1ce785ee76bb6f0d23df76b77cae59f65dbcc738
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mlcd.md
@@ -0,0 +1,82 @@
+
+*This model was released on 2024-07-24 and added to Hugging Face Transformers on 2025-04-15.*
+
+# MLCD
+
+
+
+
+
+
+## Overview
+
+The [MLCD](https://huggingface.co/papers/2407.17331) models were released by the DeepGlint-AI team in [unicom](https://github.com/deepglint/unicom), which focuses on building foundational visual models for large multimodal language models using large-scale datasets such as LAION400M and COYO700M, and employs sample-to-cluster contrastive learning to optimize performance. MLCD models are primarily used for multimodal visual large language models, such as LLaVA.
+
+🔥**MLCD-ViT-bigG**🔥 series is the state-of-the-art vision transformer model enhanced with 2D Rotary Position Embedding (RoPE2D), achieving superior performance on document understanding and visual question answering tasks. Developed by DeepGlint AI, this model demonstrates exceptional capabilities in processing complex visual-language interactions.
+
+Tips:
+
+- We adopted the official [LLaVA-NeXT](https://github.com/LLaVA-VL/LLaVA-NeXT) and the official training dataset [LLaVA-NeXT-Data](https://huggingface.co/datasets/lmms-lab/LLaVA-NeXT-Data) for evaluating the foundational visual models.
+
+- The language model is [Qwen2.5-7B](https://huggingface.co/Qwen/Qwen2.5-7B-Instruct).
+
+Result:
+
+| Vision Tower | RoPE2D | ChartQA | DocVQA | InfoVQA | OCRBench | MMMU |
+| :-------------------------------------------------------------------------------------------- | :----: | :-------- | :-------- | :-------- | :--------- | :-------- |
+| CLIP (ViT-L-14-336px) | × | 66.52 | 75.21 | 38.88 | 525.00 | 44.20 |
+| SigLIP (ViT-SO400M-384px) | × | 69.28 | 76.71 | 41.38 | 554.00 | 46.78 |
+| DFN5B (ViT-H-14-378px) | × | 64.36 | 70.87 | 38.59 | 473.00 | **48.00** |
+| **[MLCD (ViT-L-14-336px)](https://huggingface.co/DeepGlint-AI/mlcd-vit-large-patch14-336)** | × | 67.84 | 76.46 | 43.48 | 531.00 | 44.30 |
+| **[MLCD (ViT-bigG-14-336px)](https://huggingface.co/DeepGlint-AI/mlcd-vit-bigG-patch14-336)** | √ | 71.07 | 79.63 | 44.38 | 572.00 | 46.78 |
+| **[MLCD (ViT-bigG-14-448px)](https://huggingface.co/DeepGlint-AI/mlcd-vit-bigG-patch14-448)** | √ | **73.80** | **83.34** | **46.59** | **582.00** | 46.00 |
+
+
+## Usage
+
+```python
+import requests
+from PIL import Image
+from transformers import AutoProcessor, MLCDVisionModel
+
+# Load model and processor
+model = MLCDVisionModel.from_pretrained("DeepGlint-AI/mlcd-vit-bigG-patch14-448")
+processor = AutoProcessor.from_pretrained("DeepGlint-AI/mlcd-vit-bigG-patch14-448")
+
+# Process single image
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+inputs = processor(images=image, return_tensors="pt")
+
+# Generate outputs
+with torch.no_grad():
+ outputs = model(**inputs)
+
+# Get visual features
+features = outputs.last_hidden_state
+
+print(f"Extracted features shape: {features.shape}")
+```
+
+## MLCDVisionConfig
+
+[[autodoc]] MLCDVisionConfig
+
+## MLCDVisionModel
+
+[[autodoc]] MLCDVisionModel
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mllama.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mllama.md
new file mode 100644
index 0000000000000000000000000000000000000000..92af0c3aa385185140c1bc342efdbfef7b4f5849
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mllama.md
@@ -0,0 +1,146 @@
+
+*This model was released on 2024-09-25 and added to Hugging Face Transformers on 2024-09-25.*
+
+# Mllama
+
+
+
+
+
+## Overview
+
+The [Llama 3.2-Vision](https://ai.meta.com/blog/llama-3-2-connect-2024-vision-edge-mobile-devices/) collection of multimodal large language models (LLMs) is a collection of pretrained and instruction-tuned image reasoning generative models in 11B and 90B sizes (text \+ images in / text out). The Llama 3.2-Vision instruction-tuned models are optimized for visual recognition, image reasoning, captioning, and answering general questions about an image.
+
+**Model Architecture:** Llama 3.2-Vision is built on top of Llama 3.1 text-only model, which is an auto-regressive language model that uses an optimized transformer architecture. The tuned versions use supervised fine-tuning (SFT) and reinforcement learning with human feedback (RLHF) to align with human preferences for helpfulness and safety. To support image recognition tasks, the Llama 3.2-Vision model uses a separately trained vision adapter that integrates with the pre-trained Llama 3.1 language model. The adapter consists of a series of cross-attention layers that feed image encoder representations into the core LLM.
+
+## Usage Tips
+
+- For image+text and text inputs use `MllamaForConditionalGeneration`.
+- For text-only inputs use `MllamaForCausalLM` for generation to avoid loading vision tower.
+- Each sample can contain multiple images, and the number of images can vary between samples. The processor will pad the inputs to the maximum number of images across samples and to a maximum number of tiles within each image.
+- The text passed to the processor should have the `"<|image|>"` tokens where the images should be inserted.
+- The processor has its own `apply_chat_template` method to convert chat messages to text that can then be passed as text to the processor. If you're using `transformers>=4.49.0`, you can also get a vectorized output from `apply_chat_template`. See the **Usage Examples** below for more details on how to use it.
+
+
+
+
+
+Mllama has an extra token used as a placeholder for image positions in the text. It means that input ids and an input embedding layer will have an extra token. But since the weights for input and output embeddings are not tied, the `lm_head` layer has one less token and will fail if you want to calculate loss on image tokens or apply some logit processors. In case you are training, make sure to mask out special `"<|image|>"` tokens in the `labels` as the model should not be trained on predicting them.
+
+Otherwise if you see CUDA-side index errors when generating, use the below code to expand the `lm_head` by one more token.
+
+
+```python
+old_embeddings = model.get_output_embeddings()
+
+num_tokens = model.vocab_size + 1
+resized_embeddings = model._get_resized_lm_head(old_embeddings, new_num_tokens=num_tokens, mean_resizing=True)
+resized_embeddings.requires_grad_(old_embeddings.weight.requires_grad)
+model.set_output_embeddings(resized_embeddings)
+```
+
+
+
+## Usage Example
+
+#### Instruct model
+```python
+import torch
+from transformers import MllamaForConditionalGeneration, AutoProcessor
+
+model_id = "meta-llama/Llama-3.2-11B-Vision-Instruct"
+model = MllamaForConditionalGeneration.from_pretrained(model_id, device_map="auto", torch_dtype=torch.bfloat16)
+processor = AutoProcessor.from_pretrained(model_id)
+
+messages = [
+ [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "https://llava-vl.github.io/static/images/view.jpg"},
+ {"type": "text", "text": "What does the image show?"}
+ ]
+ }
+ ],
+]
+inputs = processor.apply_chat_template(messages, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt").to(model.device)
+output = model.generate(**inputs, max_new_tokens=25)
+print(processor.decode(output[0]))
+```
+
+#### Base model
+```python
+import requests
+import torch
+from PIL import Image
+from transformers import MllamaForConditionalGeneration, AutoProcessor
+
+model_id = "meta-llama/Llama-3.2-11B-Vision"
+model = MllamaForConditionalGeneration.from_pretrained(model_id, device_map="auto", torch_dtype=torch.bfloat16)
+processor = AutoProcessor.from_pretrained(model_id)
+
+prompt = "<|image|>If I had to write a haiku for this one"
+url = "https://llava-vl.github.io/static/images/view.jpg"
+raw_image = Image.open(requests.get(url, stream=True).raw)
+
+inputs = processor(text=prompt, images=raw_image, return_tensors="pt").to(model.device)
+output = model.generate(**inputs, do_sample=False, max_new_tokens=25)
+print(processor.decode(output[0], skip_special_tokens=True))
+```
+
+
+## MllamaConfig
+
+[[autodoc]] MllamaConfig
+
+## MllamaProcessor
+
+[[autodoc]] MllamaProcessor
+
+
+## MllamaImageProcessor
+
+[[autodoc]] MllamaImageProcessor
+
+## MllamaForConditionalGeneration
+
+[[autodoc]] MllamaForConditionalGeneration
+ - forward
+
+## MllamaForCausalLM
+
+[[autodoc]] MllamaForCausalLM
+ - forward
+
+## MllamaTextModel
+
+[[autodoc]] MllamaTextModel
+ - forward
+
+## MllamaModel
+
+[[autodoc]] MllamaModel
+
+## MllamaForCausalLM
+
+[[autodoc]] MllamaForCausalLM
+ - forward
+
+## MllamaVisionModel
+
+[[autodoc]] MllamaVisionModel
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mluke.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mluke.md
new file mode 100644
index 0000000000000000000000000000000000000000..f9310d6c22f9d5956bb0e5a01b1c3c7e31767857
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mluke.md
@@ -0,0 +1,76 @@
+
+*This model was released on 2021-10-15 and added to Hugging Face Transformers on 2021-12-07.*
+
+# mLUKE
+
+
+
+
+
+## Overview
+
+The mLUKE model was proposed in [mLUKE: The Power of Entity Representations in Multilingual Pretrained Language Models](https://huggingface.co/papers/2110.08151) by Ryokan Ri, Ikuya Yamada, and Yoshimasa Tsuruoka. It's a multilingual extension
+of the [LUKE model](https://huggingface.co/papers/2010.01057) trained on the basis of XLM-RoBERTa.
+
+It is based on XLM-RoBERTa and adds entity embeddings, which helps improve performance on various downstream tasks
+involving reasoning about entities such as named entity recognition, extractive question answering, relation
+classification, cloze-style knowledge completion.
+
+The abstract from the paper is the following:
+
+*Recent studies have shown that multilingual pretrained language models can be effectively improved with cross-lingual
+alignment information from Wikipedia entities. However, existing methods only exploit entity information in pretraining
+and do not explicitly use entities in downstream tasks. In this study, we explore the effectiveness of leveraging
+entity representations for downstream cross-lingual tasks. We train a multilingual language model with 24 languages
+with entity representations and show the model consistently outperforms word-based pretrained models in various
+cross-lingual transfer tasks. We also analyze the model and the key insight is that incorporating entity
+representations into the input allows us to extract more language-agnostic features. We also evaluate the model with a
+multilingual cloze prompt task with the mLAMA dataset. We show that entity-based prompt elicits correct factual
+knowledge more likely than using only word representations.*
+
+This model was contributed by [ryo0634](https://huggingface.co/ryo0634). The original code can be found [here](https://github.com/studio-ousia/luke).
+
+## Usage tips
+
+One can directly plug in the weights of mLUKE into a LUKE model, like so:
+
+```python
+from transformers import LukeModel
+
+model = LukeModel.from_pretrained("studio-ousia/mluke-base")
+```
+
+Note that mLUKE has its own tokenizer, [`MLukeTokenizer`]. You can initialize it as follows:
+
+```python
+from transformers import MLukeTokenizer
+
+tokenizer = MLukeTokenizer.from_pretrained("studio-ousia/mluke-base")
+```
+
+
+
+As mLUKE's architecture is equivalent to that of LUKE, one can refer to [LUKE's documentation page](luke) for all
+tips, code examples and notebooks.
+
+
+
+## MLukeTokenizer
+
+[[autodoc]] MLukeTokenizer
+ - __call__
+ - save_vocabulary
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mm-grounding-dino.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mm-grounding-dino.md
new file mode 100644
index 0000000000000000000000000000000000000000..e411ef5defb6be7cb225ebdd30586ea2889d7b0e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mm-grounding-dino.md
@@ -0,0 +1,125 @@
+
+*This model was released on 2024-01-04 and added to Hugging Face Transformers on 2025-08-01.*
+
+
+
+
+
+
+
+# MM Grounding DINO
+
+[MM Grounding DINO](https://huggingface.co/papers/2401.02361) model was proposed in [An Open and Comprehensive Pipeline for Unified Object Grounding and Detection](https://huggingface.co/papers/2401.02361) by Xiangyu Zhao, Yicheng Chen, Shilin Xu, Xiangtai Li, Xinjiang Wang, Yining Li, Haian Huang>.
+
+MM Grounding DINO improves upon the [Grounding DINO](https://huggingface.co/docs/transformers/model_doc/grounding-dino) by improving the contrastive class head and removing the parameter sharing in the decoder, improving zero-shot detection performance on both COCO (50.6(+2.2) AP) and LVIS (31.9(+11.8) val AP and 41.4(+12.6) minival AP).
+
+You can find all the original MM Grounding DINO checkpoints under the [MM Grounding DINO](https://huggingface.co/collections/openmmlab-community/mm-grounding-dino-688cbde05b814c4e2832f9df) collection. This model also supports LLMDet inference. You can find LLMDet checkpoints under the [LLMDet](https://huggingface.co/collections/iSEE-Laboratory/llmdet-688475906dc235d5f1dc678e) collection.
+
+> [!TIP]
+> Click on the MM Grounding DINO models in the right sidebar for more examples of how to apply MM Grounding DINO to different MM Grounding DINO tasks.
+
+The example below demonstrates how to generate text based on an image with the [`AutoModelForZeroShotObjectDetection`] class.
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForZeroShotObjectDetection, AutoProcessor, infer_device
+from transformers.image_utils import load_image
+
+
+# Prepare processor and model
+model_id = "openmmlab-community/mm_grounding_dino_tiny_o365v1_goldg_v3det"
+device = infer_device()
+processor = AutoProcessor.from_pretrained(model_id)
+model = AutoModelForZeroShotObjectDetection.from_pretrained(model_id).to(device)
+
+# Prepare inputs
+image_url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = load_image(image_url)
+text_labels = [["a cat", "a remote control"]]
+inputs = processor(images=image, text=text_labels, return_tensors="pt").to(device)
+
+# Run inference
+with torch.no_grad():
+ outputs = model(**inputs)
+
+# Postprocess outputs
+results = processor.post_process_grounded_object_detection(
+ outputs,
+ threshold=0.4,
+ target_sizes=[(image.height, image.width)]
+)
+
+# Retrieve the first image result
+result = results[0]
+for box, score, labels in zip(result["boxes"], result["scores"], result["labels"]):
+ box = [round(x, 2) for x in box.tolist()]
+ print(f"Detected {labels} with confidence {round(score.item(), 3)} at location {box}")
+```
+
+
+
+
+## Notes
+
+- Here's a table of models and their object detection performance results on COCO (results from [official repo](https://github.com/open-mmlab/mmdetection/blob/main/configs/mm_grounding_dino/README.md)):
+
+ | Model | Backbone | Pre-Train Data | Style | COCO mAP |
+ | ------------------------------------------------------------------------------------------------------------------------------ | -------- | ------------------------ | --------- | ---------- |
+ | [mm_grounding_dino_tiny_o365v1_goldg](https://huggingface.co/openmmlab-community/mm_grounding_dino_tiny_o365v1_goldg) | Swin-T | O365,GoldG | Zero-shot | 50.4(+2.3) |
+ | [mm_grounding_dino_tiny_o365v1_goldg_grit](https://huggingface.co/openmmlab-community/mm_grounding_dino_tiny_o365v1_goldg_grit) | Swin-T | O365,GoldG,GRIT | Zero-shot | 50.5(+2.1) |
+ | [mm_grounding_dino_tiny_o365v1_goldg_v3det](https://huggingface.co/openmmlab-community/mm_grounding_dino_tiny_o365v1_goldg_v3det) | Swin-T | O365,GoldG,V3Det | Zero-shot | 50.6(+2.2) |
+ | [mm_grounding_dino_tiny_o365v1_goldg_grit_v3det](https://huggingface.co/openmmlab-community/mm_grounding_dino_tiny_o365v1_goldg_grit_v3det) | Swin-T | O365,GoldG,GRIT,V3Det | Zero-shot | 50.4(+2.0) |
+ | [mm_grounding_dino_base_o365v1_goldg_v3det](https://huggingface.co/openmmlab-community/mm_grounding_dino_base_o365v1_goldg_v3det) | Swin-B | O365,GoldG,V3Det | Zero-shot | 52.5 |
+ | [mm_grounding_dino_base_all](https://huggingface.co/openmmlab-community/mm_grounding_dino_base_all) | Swin-B | O365,ALL | - | 59.5 |
+ | [mm_grounding_dino_large_o365v2_oiv6_goldg](https://huggingface.co/openmmlab-community/mm_grounding_dino_large_o365v2_oiv6_goldg) | Swin-L | O365V2,OpenImageV6,GoldG | Zero-shot | 53.0 |
+ | [mm_grounding_dino_large_all](https://huggingface.co/openmmlab-community/mm_grounding_dino_large_all) | Swin-L | O365V2,OpenImageV6,ALL | - | 60.3 |
+
+- Here's a table of MM Grounding DINO tiny models and their object detection performance on LVIS (results from [official repo](https://github.com/open-mmlab/mmdetection/blob/main/configs/mm_grounding_dino/README.md)):
+
+ | Model | Pre-Train Data | MiniVal APr | MiniVal APc | MiniVal APf | MiniVal AP | Val1.0 APr | Val1.0 APc | Val1.0 APf | Val1.0 AP |
+ | ------------------------------------------------------------------------------------------------------------------------------ | --------------------- | ----------- | ----------- | ----------- | ----------- | ---------- | ---------- | ---------- | ----------- |
+ | [mm_grounding_dino_tiny_o365v1_goldg](https://huggingface.co/openmmlab-community/mm_grounding_dino_tiny_o365v1_goldg) | O365,GoldG | 28.1 | 30.2 | 42.0 | 35.7(+6.9) | 17.1 | 22.4 | 36.5 | 27.0(+6.9) |
+ | [mm_grounding_dino_tiny_o365v1_goldg_grit](https://huggingface.co/openmmlab-community/mm_grounding_dino_tiny_o365v1_goldg_grit) | O365,GoldG,GRIT | 26.6 | 32.4 | 41.8 | 36.5(+7.7) | 17.3 | 22.6 | 36.4 | 27.1(+7.0) |
+ | [mm_grounding_dino_tiny_o365v1_goldg_v3det](https://huggingface.co/openmmlab-community/mm_grounding_dino_tiny_o365v1_goldg_v3det) | O365,GoldG,V3Det | 33.0 | 36.0 | 45.9 | 40.5(+11.7) | 21.5 | 25.5 | 40.2 | 30.6(+10.5) |
+ | [mm_grounding_dino_tiny_o365v1_goldg_grit_v3det](https://huggingface.co/openmmlab-community/mm_grounding_dino_tiny_o365v1_goldg_grit_v3det) | O365,GoldG,GRIT,V3Det | 34.2 | 37.4 | 46.2 | 41.4(+12.6) | 23.6 | 27.6 | 40.5 | 31.9(+11.8) |
+
+
+- This implementation also supports inference for [LLMDet](https://github.com/iSEE-Laboratory/LLMDet). Here's a table of LLMDet models and their performance on LVIS (results from [official repo](https://github.com/iSEE-Laboratory/LLMDet)):
+
+ | Model | Pre-Train Data | MiniVal APr | MiniVal APc | MiniVal APf | MiniVal AP | Val1.0 APr | Val1.0 APc | Val1.0 APf | Val1.0 AP |
+ | --------------------------------------------------------- | -------------------------------------------- | ------------ | ----------- | ----------- | ----------- | ---------- | ---------- | ---------- | ----------- |
+ | [llmdet_tiny](https://huggingface.co/iSEE-Laboratory/llmdet_tiny) | (O365,GoldG,GRIT,V3Det) + GroundingCap-1M | 44.7 | 37.3 | 39.5 | 50.7 | 34.9 | 26.0 | 30.1 | 44.3 |
+ | [llmdet_base](https://huggingface.co/iSEE-Laboratory/llmdet_base) | (O365,GoldG,V3Det) + GroundingCap-1M | 48.3 | 40.8 | 43.1 | 54.3 | 38.5 | 28.2 | 34.3 | 47.8 |
+ | [llmdet_large](https://huggingface.co/iSEE-Laboratory/llmdet_large) | (O365V2,OpenImageV6,GoldG) + GroundingCap-1M | 51.1 | 45.1 | 46.1 | 56.6 | 42.0 | 31.6 | 38.8 | 50.2 |
+
+
+## MMGroundingDinoConfig
+
+[[autodoc]] MMGroundingDinoConfig
+
+## MMGroundingDinoModel
+
+[[autodoc]] MMGroundingDinoModel
+ - forward
+
+## MMGroundingDinoForObjectDetection
+
+[[autodoc]] MMGroundingDinoForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mms.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mms.md
new file mode 100644
index 0000000000000000000000000000000000000000..2651e5af0326a7b7fef626f27fb2b1266a45ce9f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mms.md
@@ -0,0 +1,397 @@
+
+*This model was released on 2023-05-22 and added to Hugging Face Transformers on 2023-06-20.*
+
+# MMS
+
+
+
+
+
+
+
+## Overview
+
+The MMS model was proposed in [Scaling Speech Technology to 1,000+ Languages](https://huggingface.co/papers/2305.13516)
+by Vineel Pratap, Andros Tjandra, Bowen Shi, Paden Tomasello, Arun Babu, Sayani Kundu, Ali Elkahky, Zhaoheng Ni, Apoorv Vyas, Maryam Fazel-Zarandi, Alexei Baevski, Yossi Adi, Xiaohui Zhang, Wei-Ning Hsu, Alexis Conneau, Michael Auli
+
+The abstract from the paper is the following:
+
+*Expanding the language coverage of speech technology has the potential to improve access to information for many more people.
+However, current speech technology is restricted to about one hundred languages which is a small fraction of the over 7,000
+languages spoken around the world.
+The Massively Multilingual Speech (MMS) project increases the number of supported languages by 10-40x, depending on the task.
+The main ingredients are a new dataset based on readings of publicly available religious texts and effectively leveraging
+self-supervised learning. We built pre-trained wav2vec 2.0 models covering 1,406 languages,
+a single multilingual automatic speech recognition model for 1,107 languages, speech synthesis models
+for the same number of languages, as well as a language identification model for 4,017 languages.
+Experiments show that our multilingual speech recognition model more than halves the word error rate of
+Whisper on 54 languages of the FLEURS benchmark while being trained on a small fraction of the labeled data.*
+
+Here are the different models open sourced in the MMS project. The models and code are originally released [here](https://github.com/facebookresearch/fairseq/tree/main/examples/mms). We have add them to the `transformers` framework, making them easier to use.
+
+### Automatic Speech Recognition (ASR)
+
+The ASR model checkpoints can be found here : [mms-1b-fl102](https://huggingface.co/facebook/mms-1b-fl102), [mms-1b-l1107](https://huggingface.co/facebook/mms-1b-l1107), [mms-1b-all](https://huggingface.co/facebook/mms-1b-all). For best accuracy, use the `mms-1b-all` model.
+
+Tips:
+
+- All ASR models accept a float array corresponding to the raw waveform of the speech signal. The raw waveform should be pre-processed with [`Wav2Vec2FeatureExtractor`].
+- The models were trained using connectionist temporal classification (CTC) so the model output has to be decoded using
+ [`Wav2Vec2CTCTokenizer`].
+- You can load different language adapter weights for different languages via [`~Wav2Vec2PreTrainedModel.load_adapter`]. Language adapters only consists of roughly 2 million parameters
+ and can therefore be efficiently loaded on the fly when needed.
+
+#### Loading
+
+By default MMS loads adapter weights for English. If you want to load adapter weights of another language
+make sure to specify `target_lang=` as well as `"ignore_mismatched_sizes=True`.
+The `ignore_mismatched_sizes=True` keyword has to be passed to allow the language model head to be resized according
+to the vocabulary of the specified language.
+Similarly, the processor should be loaded with the same target language
+
+```py
+from transformers import Wav2Vec2ForCTC, AutoProcessor
+
+model_id = "facebook/mms-1b-all"
+target_lang = "fra"
+
+processor = AutoProcessor.from_pretrained(model_id, target_lang=target_lang)
+model = Wav2Vec2ForCTC.from_pretrained(model_id, target_lang=target_lang, ignore_mismatched_sizes=True)
+```
+
+
+
+You can safely ignore a warning such as:
+
+```text
+Some weights of Wav2Vec2ForCTC were not initialized from the model checkpoint at facebook/mms-1b-all and are newly initialized because the shapes did not match:
+- lm_head.bias: found shape torch.Size([154]) in the checkpoint and torch.Size([314]) in the model instantiated
+- lm_head.weight: found shape torch.Size([154, 1280]) in the checkpoint and torch.Size([314, 1280]) in the model instantiated
+You should probably TRAIN this model on a down-stream task to be able to use it for predictions and inference.
+```
+
+
+
+If you want to use the ASR pipeline, you can load your chosen target language as such:
+
+```py
+from transformers import pipeline
+
+model_id = "facebook/mms-1b-all"
+target_lang = "fra"
+
+pipe = pipeline(model=model_id, model_kwargs={"target_lang": "fra", "ignore_mismatched_sizes": True})
+```
+
+#### Inference
+
+Next, let's look at how we can run MMS in inference and change adapter layers after having called [`~PretrainedModel.from_pretrained`]
+First, we load audio data in different languages using the [Datasets](https://github.com/huggingface/datasets).
+
+```py
+from datasets import load_dataset, Audio
+
+# English
+stream_data = load_dataset("mozilla-foundation/common_voice_13_0", "en", split="test", streaming=True)
+stream_data = stream_data.cast_column("audio", Audio(sampling_rate=16000))
+en_sample = next(iter(stream_data))["audio"]["array"]
+
+# French
+stream_data = load_dataset("mozilla-foundation/common_voice_13_0", "fr", split="test", streaming=True)
+stream_data = stream_data.cast_column("audio", Audio(sampling_rate=16000))
+fr_sample = next(iter(stream_data))["audio"]["array"]
+```
+
+Next, we load the model and processor
+
+```py
+from transformers import Wav2Vec2ForCTC, AutoProcessor
+import torch
+
+model_id = "facebook/mms-1b-all"
+
+processor = AutoProcessor.from_pretrained(model_id)
+model = Wav2Vec2ForCTC.from_pretrained(model_id)
+```
+
+Now we process the audio data, pass the processed audio data to the model and transcribe the model output,
+just like we usually do for [`Wav2Vec2ForCTC`].
+
+```py
+inputs = processor(en_sample, sampling_rate=16_000, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs).logits
+
+ids = torch.argmax(outputs, dim=-1)[0]
+transcription = processor.decode(ids)
+# 'joe keton disapproved of films and buster also had reservations about the media'
+```
+
+We can now keep the same model in memory and simply switch out the language adapters by
+calling the convenient [`~Wav2Vec2ForCTC.load_adapter`] function for the model and [`~Wav2Vec2CTCTokenizer.set_target_lang`] for the tokenizer.
+We pass the target language as an input - `"fra"` for French.
+
+```py
+processor.tokenizer.set_target_lang("fra")
+model.load_adapter("fra")
+
+inputs = processor(fr_sample, sampling_rate=16_000, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs).logits
+
+ids = torch.argmax(outputs, dim=-1)[0]
+transcription = processor.decode(ids)
+# "ce dernier est volé tout au long de l'histoire romaine"
+```
+
+In the same way the language can be switched out for all other supported languages. Please have a look at:
+
+```py
+processor.tokenizer.vocab.keys()
+```
+
+to see all supported languages.
+
+To further improve performance from ASR models, language model decoding can be used. See the documentation [here](https://huggingface.co/facebook/mms-1b-all) for further details.
+
+### Speech Synthesis (TTS)
+
+MMS-TTS uses the same model architecture as VITS, which was added to 🤗 Transformers in v4.33. MMS trains a separate
+model checkpoint for each of the 1100+ languages in the project. All available checkpoints can be found on the Hugging
+Face Hub: [facebook/mms-tts](https://huggingface.co/models?sort=trending&search=facebook%2Fmms-tts), and the inference
+documentation under [VITS](https://huggingface.co/docs/transformers/main/en/model_doc/vits).
+
+#### Inference
+
+To use the MMS model, first update to the latest version of the Transformers library:
+
+```bash
+pip install --upgrade transformers accelerate
+```
+
+Since the flow-based model in VITS is non-deterministic, it is good practice to set a seed to ensure reproducibility of
+the outputs.
+
+- For languages with a Roman alphabet, such as English or French, the tokenizer can be used directly to
+pre-process the text inputs. The following code example runs a forward pass using the MMS-TTS English checkpoint:
+
+```python
+import torch
+from transformers import VitsTokenizer, VitsModel, set_seed
+
+tokenizer = VitsTokenizer.from_pretrained("facebook/mms-tts-eng")
+model = VitsModel.from_pretrained("facebook/mms-tts-eng")
+
+inputs = tokenizer(text="Hello - my dog is cute", return_tensors="pt")
+
+set_seed(555) # make deterministic
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+waveform = outputs.waveform[0]
+```
+
+The resulting waveform can be saved as a `.wav` file:
+
+```python
+import scipy
+
+scipy.io.wavfile.write("synthesized_speech.wav", rate=model.config.sampling_rate, data=waveform)
+```
+
+Or displayed in a Jupyter Notebook / Google Colab:
+
+```python
+from IPython.display import Audio
+
+Audio(waveform, rate=model.config.sampling_rate)
+```
+
+For certain languages with non-Roman alphabets, such as Arabic, Mandarin or Hindi, the [`uroman`](https://github.com/isi-nlp/uroman)
+perl package is required to pre-process the text inputs to the Roman alphabet.
+
+You can check whether you require the `uroman` package for your language by inspecting the `is_uroman` attribute of
+the pre-trained `tokenizer`:
+
+```python
+from transformers import VitsTokenizer
+
+tokenizer = VitsTokenizer.from_pretrained("facebook/mms-tts-eng")
+print(tokenizer.is_uroman)
+```
+
+If required, you should apply the uroman package to your text inputs **prior** to passing them to the `VitsTokenizer`,
+since currently the tokenizer does not support performing the pre-processing itself.
+
+To do this, first clone the uroman repository to your local machine and set the bash variable `UROMAN` to the local path:
+
+```bash
+git clone https://github.com/isi-nlp/uroman.git
+cd uroman
+export UROMAN=$(pwd)
+```
+
+You can then pre-process the text input using the following code snippet. You can either rely on using the bash variable
+`UROMAN` to point to the uroman repository, or you can pass the uroman directory as an argument to the `uromanize` function:
+
+```python
+import torch
+from transformers import VitsTokenizer, VitsModel, set_seed
+import os
+import subprocess
+
+tokenizer = VitsTokenizer.from_pretrained("facebook/mms-tts-kor")
+model = VitsModel.from_pretrained("facebook/mms-tts-kor")
+
+def uromanize(input_string, uroman_path):
+ """Convert non-Roman strings to Roman using the `uroman` perl package."""
+ script_path = os.path.join(uroman_path, "bin", "uroman.pl")
+
+ command = ["perl", script_path]
+
+ process = subprocess.Popen(command, stdin=subprocess.PIPE, stdout=subprocess.PIPE, stderr=subprocess.PIPE)
+ # Execute the perl command
+ stdout, stderr = process.communicate(input=input_string.encode())
+
+ if process.returncode != 0:
+ raise ValueError(f"Error {process.returncode}: {stderr.decode()}")
+
+ # Return the output as a string and skip the new-line character at the end
+ return stdout.decode()[:-1]
+
+text = "이봐 무슨 일이야"
+uromanized_text = uromanize(text, uroman_path=os.environ["UROMAN"])
+
+inputs = tokenizer(text=uromanized_text, return_tensors="pt")
+
+set_seed(555) # make deterministic
+with torch.no_grad():
+ outputs = model(inputs["input_ids"])
+
+waveform = outputs.waveform[0]
+```
+
+**Tips:**
+
+* The MMS-TTS checkpoints are trained on lower-cased, un-punctuated text. By default, the `VitsTokenizer` *normalizes* the inputs by removing any casing and punctuation, to avoid passing out-of-vocabulary characters to the model. Hence, the model is agnostic to casing and punctuation, so these should be avoided in the text prompt. You can disable normalisation by setting `normalize=False` in the call to the tokenizer, but this will lead to un-expected behaviour and is discouraged.
+* The speaking rate can be varied by setting the attribute `model.speaking_rate` to a chosen value. Likewise, the randomness of the noise is controlled by `model.noise_scale`:
+
+```python
+import torch
+from transformers import VitsTokenizer, VitsModel, set_seed
+
+tokenizer = VitsTokenizer.from_pretrained("facebook/mms-tts-eng")
+model = VitsModel.from_pretrained("facebook/mms-tts-eng")
+
+inputs = tokenizer(text="Hello - my dog is cute", return_tensors="pt")
+
+# make deterministic
+set_seed(555)
+
+# make speech faster and more noisy
+model.speaking_rate = 1.5
+model.noise_scale = 0.8
+
+with torch.no_grad():
+ outputs = model(**inputs)
+```
+
+### Language Identification (LID)
+
+Different LID models are available based on the number of languages they can recognize - [126](https://huggingface.co/facebook/mms-lid-126), [256](https://huggingface.co/facebook/mms-lid-256), [512](https://huggingface.co/facebook/mms-lid-512), [1024](https://huggingface.co/facebook/mms-lid-1024), [2048](https://huggingface.co/facebook/mms-lid-2048), [4017](https://huggingface.co/facebook/mms-lid-4017).
+
+#### Inference
+First, we install transformers and some other libraries
+
+```bash
+pip install torch accelerate datasets[audio]
+pip install --upgrade transformers
+````
+
+Next, we load a couple of audio samples via `datasets`. Make sure that the audio data is sampled to 16000 kHz.
+
+```py
+from datasets import load_dataset, Audio
+
+# English
+stream_data = load_dataset("mozilla-foundation/common_voice_13_0", "en", split="test", streaming=True)
+stream_data = stream_data.cast_column("audio", Audio(sampling_rate=16000))
+en_sample = next(iter(stream_data))["audio"]["array"]
+
+# Arabic
+stream_data = load_dataset("mozilla-foundation/common_voice_13_0", "ar", split="test", streaming=True)
+stream_data = stream_data.cast_column("audio", Audio(sampling_rate=16000))
+ar_sample = next(iter(stream_data))["audio"]["array"]
+```
+
+Next, we load the model and processor
+
+```py
+from transformers import Wav2Vec2ForSequenceClassification, AutoFeatureExtractor
+import torch
+
+model_id = "facebook/mms-lid-126"
+
+processor = AutoFeatureExtractor.from_pretrained(model_id)
+model = Wav2Vec2ForSequenceClassification.from_pretrained(model_id)
+```
+
+Now we process the audio data, pass the processed audio data to the model to classify it into a language, just like we usually do for Wav2Vec2 audio classification models such as [ehcalabres/wav2vec2-lg-xlsr-en-speech-emotion-recognition](https://huggingface.co/harshit345/xlsr-wav2vec-speech-emotion-recognition)
+
+```py
+# English
+inputs = processor(en_sample, sampling_rate=16_000, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs).logits
+
+lang_id = torch.argmax(outputs, dim=-1)[0].item()
+detected_lang = model.config.id2label[lang_id]
+# 'eng'
+
+# Arabic
+inputs = processor(ar_sample, sampling_rate=16_000, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs).logits
+
+lang_id = torch.argmax(outputs, dim=-1)[0].item()
+detected_lang = model.config.id2label[lang_id]
+# 'ara'
+```
+
+To see all the supported languages of a checkpoint, you can print out the language ids as follows:
+```py
+processor.id2label.values()
+```
+
+### Audio Pretrained Models
+
+Pretrained models are available for two different sizes - [300M](https://huggingface.co/facebook/mms-300m) ,
+[1Bil](https://huggingface.co/facebook/mms-1b).
+
+
+
+The MMS for ASR architecture is based on the Wav2Vec2 model, refer to [Wav2Vec2's documentation page](wav2vec2) for further
+details on how to finetune with models for various downstream tasks.
+
+MMS-TTS uses the same model architecture as VITS, refer to [VITS's documentation page](vits) for API reference.
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mobilebert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mobilebert.md
new file mode 100644
index 0000000000000000000000000000000000000000..e6c3783150f2b9673d736bd347b1f7449225d53e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mobilebert.md
@@ -0,0 +1,199 @@
+
+*This model was released on 2020-04-06 and added to Hugging Face Transformers on 2020-11-16.*
+
+
+
+
+
+
+
+
+
+# MobileBERT
+
+[MobileBERT](https://huggingface.co/papers/2004.02984) is a lightweight and efficient variant of BERT, specifically designed for resource-limited devices such as mobile phones. It retains BERT's architecture but significantly reduces model size and inference latency while maintaining strong performance on NLP tasks. MobileBERT achieves this through a bottleneck structure and carefully balanced self-attention and feedforward networks. The model is trained by knowledge transfer from a large BERT model with an inverted bottleneck structure.
+
+You can find the original MobileBERT checkpoint under the [Google](https://huggingface.co/google/mobilebert-uncased) organization.
+> [!TIP]
+> Click on the MobileBERT models in the right sidebar for more examples of how to apply MobileBERT to different language tasks.
+
+The example below demonstrates how to predict the `[MASK]` token with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="fill-mask",
+ model="google/mobilebert-uncased",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("The capital of France is [MASK].")
+```
+
+
+
+```py
+import torch
+from transformers import AutoModelForMaskedLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "google/mobilebert-uncased",
+)
+model = AutoModelForMaskedLM.from_pretrained(
+ "google/mobilebert-uncased",
+ torch_dtype=torch.float16,
+ device_map="auto",
+)
+inputs = tokenizer("The capital of France is [MASK].", return_tensors="pt").to("cuda")
+
+with torch.no_grad():
+ outputs = model(**inputs)
+ predictions = outputs.logits
+
+masked_index = torch.where(inputs['input_ids'] == tokenizer.mask_token_id)[1]
+predicted_token_id = predictions[0, masked_index].argmax(dim=-1)
+predicted_token = tokenizer.decode(predicted_token_id)
+
+print(f"The predicted token is: {predicted_token}")
+```
+
+
+
+
+```bash
+echo -e "The capital of France is [MASK]." | transformers run --task fill-mask --model google/mobilebert-uncased --device 0
+```
+
+
+
+
+
+## Notes
+
+- Inputs should be padded on the right because BERT uses absolute position embeddings.
+
+## MobileBertConfig
+
+[[autodoc]] MobileBertConfig
+
+## MobileBertTokenizer
+
+[[autodoc]] MobileBertTokenizer
+
+## MobileBertTokenizerFast
+
+[[autodoc]] MobileBertTokenizerFast
+
+## MobileBert specific outputs
+
+[[autodoc]] models.mobilebert.modeling_mobilebert.MobileBertForPreTrainingOutput
+
+[[autodoc]] models.mobilebert.modeling_tf_mobilebert.TFMobileBertForPreTrainingOutput
+
+
+
+
+## MobileBertModel
+
+[[autodoc]] MobileBertModel
+ - forward
+
+## MobileBertForPreTraining
+
+[[autodoc]] MobileBertForPreTraining
+ - forward
+
+## MobileBertForMaskedLM
+
+[[autodoc]] MobileBertForMaskedLM
+ - forward
+
+## MobileBertForNextSentencePrediction
+
+[[autodoc]] MobileBertForNextSentencePrediction
+ - forward
+
+## MobileBertForSequenceClassification
+
+[[autodoc]] MobileBertForSequenceClassification
+ - forward
+
+## MobileBertForMultipleChoice
+
+[[autodoc]] MobileBertForMultipleChoice
+ - forward
+
+## MobileBertForTokenClassification
+
+[[autodoc]] MobileBertForTokenClassification
+ - forward
+
+## MobileBertForQuestionAnswering
+
+[[autodoc]] MobileBertForQuestionAnswering
+ - forward
+
+
+
+
+## TFMobileBertModel
+
+[[autodoc]] TFMobileBertModel
+ - call
+
+## TFMobileBertForPreTraining
+
+[[autodoc]] TFMobileBertForPreTraining
+ - call
+
+## TFMobileBertForMaskedLM
+
+[[autodoc]] TFMobileBertForMaskedLM
+ - call
+
+## TFMobileBertForNextSentencePrediction
+
+[[autodoc]] TFMobileBertForNextSentencePrediction
+ - call
+
+## TFMobileBertForSequenceClassification
+
+[[autodoc]] TFMobileBertForSequenceClassification
+ - call
+
+## TFMobileBertForMultipleChoice
+
+[[autodoc]] TFMobileBertForMultipleChoice
+ - call
+
+## TFMobileBertForTokenClassification
+
+[[autodoc]] TFMobileBertForTokenClassification
+ - call
+
+## TFMobileBertForQuestionAnswering
+
+[[autodoc]] TFMobileBertForQuestionAnswering
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mobilenet_v1.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mobilenet_v1.md
new file mode 100644
index 0000000000000000000000000000000000000000..006835fe58ded0958d42f4018ebfc86d41678376
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mobilenet_v1.md
@@ -0,0 +1,132 @@
+
+*This model was released on 2017-04-17 and added to Hugging Face Transformers on 2022-11-21.*
+
+
+
+
+
+
+
+# MobileNet V1
+
+[MobileNet V1](https://huggingface.co/papers/1704.04861) is a family of efficient convolutional neural networks optimized for on-device or embedded vision tasks. It achieves this efficiency by using depth-wise separable convolutions instead of standard convolutions. The architecture allows for easy trade-offs between latency and accuracy using two main hyperparameters, a width multiplier (alpha) and an image resolution multiplier.
+
+You can all the original MobileNet checkpoints under the [Google](https://huggingface.co/google?search_models=mobilenet) organization.
+
+> [!TIP]
+> Click on the MobileNet V1 models in the right sidebar for more examples of how to apply MobileNet to different vision tasks.
+
+The example below demonstrates how to classify an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+
+```python
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="image-classification",
+ model="google/mobilenet_v1_1.0_224",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg")
+```
+
+
+
+
+```python
+import torch
+import requests
+from PIL import Image
+from transformers import AutoModelForImageClassification, AutoImageProcessor
+
+image_processor = AutoImageProcessor.from_pretrained(
+ "google/mobilenet_v1_1.0_224",
+)
+model = AutoModelForImageClassification.from_pretrained(
+ "google/mobilenet_v1_1.0_224",
+)
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+image = Image.open(requests.get(url, stream=True).raw)
+inputs = image_processor(image, return_tensors="pt")
+
+with torch.no_grad():
+ logits = model(**inputs).logits
+predicted_class_id = logits.argmax(dim=-1).item()
+
+class_labels = model.config.id2label
+predicted_class_label = class_labels[predicted_class_id]
+print(f"The predicted class label is: {predicted_class_label}")
+```
+
+
+
+
+
+
+
+
+## Notes
+
+- Checkpoint names follow the pattern `mobilenet_v1_{depth_multiplier}_{resolution}`, like `mobilenet_v1_1.0_224`. `1.0` is the depth multiplier and `224` is the image resolution.
+- While trained on images of a specific sizes, the model architecture works with images of different sizes (minimum 32x32). The [`MobileNetV1ImageProcessor`] handles the necessary preprocessing.
+- MobileNet is pretrained on [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k), a dataset with 1000 classes. However, the model actually predicts 1001 classes. The additional class is an extra "background" class (index 0).
+- The original TensorFlow checkpoints determines the padding amount at inference because it depends on the input image size. To use the native PyTorch padding behavior, set `tf_padding=False` in [`MobileNetV1Config`].
+ ```python
+ from transformers import MobileNetV1Config
+
+ config = MobileNetV1Config.from_pretrained("google/mobilenet_v1_1.0_224", tf_padding=True)
+ ```
+- The Transformers implementation does not support the following features.
+ - Uses global average pooling instead of the optional 7x7 average pooling with stride 2. For larger inputs, this gives a pooled output that is larger than a 1x1 pixel.
+ - Does not support other `output_stride` values (fixed at 32). For smaller `output_strides`, the original implementation uses dilated convolution to prevent spatial resolution from being reduced further. (which would require dilated convolutions).
+ - `output_hidden_states=True` returns *all* intermediate hidden states. It is not possible to extract the output from specific layers for other downstream purposes.
+ - Does not include the quantized models from the original checkpoints because they include "FakeQuantization" operations to unquantize the weights.
+
+## MobileNetV1Config
+
+[[autodoc]] MobileNetV1Config
+
+## MobileNetV1FeatureExtractor
+
+[[autodoc]] MobileNetV1FeatureExtractor
+ - preprocess
+
+## MobileNetV1ImageProcessor
+
+[[autodoc]] MobileNetV1ImageProcessor
+ - preprocess
+
+## MobileNetV1ImageProcessorFast
+
+[[autodoc]] MobileNetV1ImageProcessorFast
+ - preprocess
+
+## MobileNetV1Model
+
+[[autodoc]] MobileNetV1Model
+ - forward
+
+## MobileNetV1ForImageClassification
+
+[[autodoc]] MobileNetV1ForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mobilenet_v2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mobilenet_v2.md
new file mode 100644
index 0000000000000000000000000000000000000000..51d8d2267b4160781662d241ea2c31b71e3274aa
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mobilenet_v2.md
@@ -0,0 +1,139 @@
+
+*This model was released on 2018-01-13 and added to Hugging Face Transformers on 2022-11-14.*
+
+
+
+
+
+
+
+# MobileNet V2
+
+[MobileNet V2](https://huggingface.co/papers/1801.04381) improves performance on mobile devices with a more efficient architecture. It uses inverted residual blocks and linear bottlenecks to start with a smaller representation of the data, expands it for processing, and shrinks it again to reduce the number of computations. The model also removes non-linearities to maintain accuracy despite its simplified design. Like [MobileNet V1](./mobilenet_v1), it uses depthwise separable convolutions for efficiency.
+
+You can all the original MobileNet checkpoints under the [Google](https://huggingface.co/google?search_models=mobilenet) organization.
+
+> [!TIP]
+> Click on the MobileNet V2 models in the right sidebar for more examples of how to apply MobileNet to different vision tasks.
+
+
+The examples below demonstrate how to classify an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+
+```python
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="image-classification",
+ model="google/mobilenet_v2_1.4_224",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg")
+```
+
+
+
+
+```python
+import torch
+import requests
+from PIL import Image
+from transformers import AutoModelForImageClassification, AutoImageProcessor
+
+image_processor = AutoImageProcessor.from_pretrained(
+ "google/mobilenet_v2_1.4_224",
+)
+model = AutoModelForImageClassification.from_pretrained(
+ "google/mobilenet_v2_1.4_224",
+)
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+image = Image.open(requests.get(url, stream=True).raw)
+inputs = image_processor(image, return_tensors="pt")
+
+with torch.no_grad():
+ logits = model(**inputs).logits
+predicted_class_id = logits.argmax(dim=-1).item()
+
+class_labels = model.config.id2label
+predicted_class_label = class_labels[predicted_class_id]
+print(f"The predicted class label is: {predicted_class_label}")
+```
+
+
+
+
+
+## Notes
+
+- Classification checkpoint names follow the pattern `mobilenet_v2_{depth_multiplier}_{resolution}`, like `mobilenet_v2_1.4_224`. `1.4` is the depth multiplier and `224` is the image resolution. Segmentation checkpoint names follow the pattern `deeplabv3_mobilenet_v2_{depth_multiplier}_{resolution}`.
+- While trained on images of a specific sizes, the model architecture works with images of different sizes (minimum 32x32). The [`MobileNetV2ImageProcessor`] handles the necessary preprocessing.
+- MobileNet is pretrained on [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k), a dataset with 1000 classes. However, the model actually predicts 1001 classes. The additional class is an extra "background" class (index 0).
+- The segmentation models use a [DeepLabV3+](https://huggingface.co/papers/1802.02611) head which is often pretrained on datasets like [PASCAL VOC](https://huggingface.co/datasets/merve/pascal-voc).
+- The original TensorFlow checkpoints determines the padding amount at inference because it depends on the input image size. To use the native PyTorch padding behavior, set `tf_padding=False` in [`MobileNetV2Config`].
+ ```python
+ from transformers import MobileNetV2Config
+
+ config = MobileNetV2Config.from_pretrained("google/mobilenet_v2_1.4_224", tf_padding=True)
+ ```
+- The Transformers implementation does not support the following features.
+ - Uses global average pooling instead of the optional 7x7 average pooling with stride 2. For larger inputs, this gives a pooled output that is larger than a 1x1 pixel.
+ - `output_hidden_states=True` returns *all* intermediate hidden states. It is not possible to extract the output from specific layers for other downstream purposes.
+ - Does not include the quantized models from the original checkpoints because they include "FakeQuantization" operations to unquantize the weights.
+ - For segmentation models, the final convolution layer of the backbone is computed even though the DeepLabV3+ head doesn't use it.
+
+## MobileNetV2Config
+
+[[autodoc]] MobileNetV2Config
+
+## MobileNetV2FeatureExtractor
+
+[[autodoc]] MobileNetV2FeatureExtractor
+ - preprocess
+ - post_process_semantic_segmentation
+
+## MobileNetV2ImageProcessor
+
+[[autodoc]] MobileNetV2ImageProcessor
+ - preprocess
+ - post_process_semantic_segmentation
+
+## MobileNetV2ImageProcessorFast
+
+[[autodoc]] MobileNetV2ImageProcessorFast
+ - preprocess
+ - post_process_semantic_segmentation
+
+## MobileNetV2Model
+
+[[autodoc]] MobileNetV2Model
+ - forward
+
+## MobileNetV2ForImageClassification
+
+[[autodoc]] MobileNetV2ForImageClassification
+ - forward
+
+## MobileNetV2ForSemanticSegmentation
+
+[[autodoc]] MobileNetV2ForSemanticSegmentation
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mobilevit.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mobilevit.md
new file mode 100644
index 0000000000000000000000000000000000000000..2beae5b2e9f35cad7db52fcd2a874d9af75c224f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mobilevit.md
@@ -0,0 +1,172 @@
+
+*This model was released on 2021-10-05 and added to Hugging Face Transformers on 2022-06-29.*
+
+
+
+# MobileViT
+
+
+
+
+
+
+
+
+
+[MobileViT](https://huggingface.co/papers/2110.02178) is a lightweight vision transformer for mobile devices that merges CNNs's efficiency and inductive biases with transformers global context modeling. It treats transformers as convolutions, enabling global information processing without the heavy computational cost of standard ViTs.
+
+
+
+
+
+
+
+You can find all the original MobileViT checkpoints under the [Apple](https://huggingface.co/apple/models?search=mobilevit) organization.
+
+
+> [!TIP]
+> - This model was contributed by [matthijs](https://huggingface.co/Matthijs) and the TensorFlow version was contributed by [sayakpaul](https://huggingface.co/sayakpaul).
+>
+> Click on the MobileViT models in the right sidebar for more examples of how to apply MobileViT to different vision tasks.
+
+
+The example below demonstrates how to do [Image Classification] with [`Pipeline`] and the [`AutoModel`] class.
+
+
+
+
+```python
+
+import torch
+from transformers import pipeline
+
+classifier = pipeline(
+ task="image-classification",
+ model="apple/mobilevit-small",
+ torch_dtype=torch.float16, device=0,
+)
+
+preds = classifier("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg")
+print(f"Prediction: {preds}\n")
+```
+
+
+
+
+
+```python
+
+import torch
+import requests
+from PIL import Image
+from transformers import AutoImageProcessor, MobileViTForImageClassification
+
+image_processor = AutoImageProcessor.from_pretrained(
+ "apple/mobilevit-small",
+ use_fast=True,
+)
+model = MobileViTForImageClassification.from_pretrained("apple/mobilevit-small", device_map="auto")
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+image = Image.open(requests.get(url, stream=True).raw)
+inputs = image_processor(image, return_tensors="pt").to(model.device)
+
+with torch.no_grad():
+ logits = model(**inputs).logits
+predicted_class_id = logits.argmax(dim=-1).item()
+
+class_labels = model.config.id2label
+predicted_class_label = class_labels[predicted_class_id]
+print(f"The predicted class label is:{predicted_class_label}")
+```
+
+
+
+
+
+
+
+## Notes
+
+- Does **not** operate on sequential data, it's purely designed for image tasks.
+- Feature maps are used directly instead of token embeddings.
+- Use [`MobileViTImageProcessor`] to preprocess images.
+- If using custom preprocessing, ensure that images are in **BGR** format (not RGB), as expected by the pretrained weights.
+- The classification models are pretrained on [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k).
+- The segmentation models use a [DeepLabV3](https://huggingface.co/papers/1706.05587) head and are pretrained on [PASCAL VOC](http://host.robots.ox.ac.uk/pascal/VOC/).
+- TensorFlow versions are compatible with TensorFlow Lite, making them ideal for edge/mobile deployment.
+
+
+
+
+
+## MobileViTConfig
+
+[[autodoc]] MobileViTConfig
+
+## MobileViTFeatureExtractor
+
+[[autodoc]] MobileViTFeatureExtractor
+ - __call__
+ - post_process_semantic_segmentation
+
+## MobileViTImageProcessor
+
+[[autodoc]] MobileViTImageProcessor
+ - preprocess
+ - post_process_semantic_segmentation
+
+## MobileViTImageProcessorFast
+
+[[autodoc]] MobileViTImageProcessorFast
+ - preprocess
+ - post_process_semantic_segmentation
+
+
+
+
+## MobileViTModel
+
+[[autodoc]] MobileViTModel
+ - forward
+
+## MobileViTForImageClassification
+
+[[autodoc]] MobileViTForImageClassification
+ - forward
+
+## MobileViTForSemanticSegmentation
+
+[[autodoc]] MobileViTForSemanticSegmentation
+ - forward
+
+
+
+
+## TFMobileViTModel
+
+[[autodoc]] TFMobileViTModel
+ - call
+
+## TFMobileViTForImageClassification
+
+[[autodoc]] TFMobileViTForImageClassification
+ - call
+
+## TFMobileViTForSemanticSegmentation
+
+[[autodoc]] TFMobileViTForSemanticSegmentation
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mobilevitv2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mobilevitv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..7f6d952ad8ad62136eb35cd4fda44329e208be3d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mobilevitv2.md
@@ -0,0 +1,61 @@
+
+*This model was released on 2022-06-06 and added to Hugging Face Transformers on 2023-06-02.*
+
+# MobileViTV2
+
+
+
+
+
+## Overview
+
+The MobileViTV2 model was proposed in [Separable Self-attention for Mobile Vision Transformers](https://huggingface.co/papers/2206.02680) by Sachin Mehta and Mohammad Rastegari.
+
+MobileViTV2 is the second version of MobileViT, constructed by replacing the multi-headed self-attention in MobileViT with separable self-attention.
+
+The abstract from the paper is the following:
+
+*Mobile vision transformers (MobileViT) can achieve state-of-the-art performance across several mobile vision tasks, including classification and detection. Though these models have fewer parameters, they have high latency as compared to convolutional neural network-based models. The main efficiency bottleneck in MobileViT is the multi-headed self-attention (MHA) in transformers, which requires O(k2) time complexity with respect to the number of tokens (or patches) k. Moreover, MHA requires costly operations (e.g., batch-wise matrix multiplication) for computing self-attention, impacting latency on resource-constrained devices. This paper introduces a separable self-attention method with linear complexity, i.e. O(k). A simple yet effective characteristic of the proposed method is that it uses element-wise operations for computing self-attention, making it a good choice for resource-constrained devices. The improved model, MobileViTV2, is state-of-the-art on several mobile vision tasks, including ImageNet object classification and MS-COCO object detection. With about three million parameters, MobileViTV2 achieves a top-1 accuracy of 75.6% on the ImageNet dataset, outperforming MobileViT by about 1% while running 3.2× faster on a mobile device.*
+
+This model was contributed by [shehan97](https://huggingface.co/shehan97).
+The original code can be found [here](https://github.com/apple/ml-cvnets).
+
+## Usage tips
+
+- MobileViTV2 is more like a CNN than a Transformer model. It does not work on sequence data but on batches of images. Unlike ViT, there are no embeddings. The backbone model outputs a feature map.
+- One can use [`MobileViTImageProcessor`] to prepare images for the model. Note that if you do your own preprocessing, the pretrained checkpoints expect images to be in BGR pixel order (not RGB).
+- The available image classification checkpoints are pre-trained on [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k) (also referred to as ILSVRC 2012, a collection of 1.3 million images and 1,000 classes).
+- The segmentation model uses a [DeepLabV3](https://huggingface.co/papers/1706.05587) head. The available semantic segmentation checkpoints are pre-trained on [PASCAL VOC](http://host.robots.ox.ac.uk/pascal/VOC/).
+
+## MobileViTV2Config
+
+[[autodoc]] MobileViTV2Config
+
+## MobileViTV2Model
+
+[[autodoc]] MobileViTV2Model
+ - forward
+
+## MobileViTV2ForImageClassification
+
+[[autodoc]] MobileViTV2ForImageClassification
+ - forward
+
+## MobileViTV2ForSemanticSegmentation
+
+[[autodoc]] MobileViTV2ForSemanticSegmentation
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/modernbert-decoder.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/modernbert-decoder.md
new file mode 100644
index 0000000000000000000000000000000000000000..58c1252cb48b8d68fbea3a67e3312f9472df11a8
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/modernbert-decoder.md
@@ -0,0 +1,189 @@
+
+*This model was released on 2024-12-18 and added to Hugging Face Transformers on 2025-07-15.*
+
+
+
+
+
+
+
+
+
+# ModernBERT Decoder
+
+ModernBERT Decoder has the same architecture as [ModernBERT](https://huggingface.co/papers/2412.13663) but it is trained from scratch with a causal language modeling objective from the [Ettin paper](https://huggingface.co/papers/2507.11412). This allows for using the same architecture to compare encoders and decoders. This model is the decoder architecture implementation of ModernBERT, designed for autoregressive text generation tasks.
+
+ModernBERT Decoder uses sliding window attention and rotary positional embeddings for efficiency and to handle longer sequences.
+
+You can find all the original ModernBERT Decoder checkpoints under the [jhu-clsp](https://huggingface.co/collections/jhu-clsp/encoders-vs-decoders-the-ettin-suite-686303e16142257eed8e6aeb) collection.
+
+> [!TIP]
+> This model was contributed by [orionw](https://huggingface.co/orionweller).
+>
+> Click on the ModernBERT Decoder models in the right sidebar for more examples of how to apply ModernBERT Decoder to different text generation tasks.
+
+The example below demonstrates how to use ModernBERT Decoder for text generation with [`Pipeline`], [`AutoModel`] (with and without quantization), and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+generator = pipeline(
+ task="text-generation",
+ model="jhu-clsp/ettin-decoder-17m",
+ torch_dtype=torch.float16,
+ device=0
+)
+generator("The future of artificial intelligence is", max_length=50, num_return_sequences=1)
+
+# For sequence classification
+classifier = pipeline(
+ task="text-classification",
+ model="jhu-clsp/ettin-decoder-17m",
+ torch_dtype=torch.float16,
+ device=0
+)
+classifier("This movie is really great!")
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("jhu-clsp/ettin-decoder-17m")
+model = AutoModelForCausalLM.from_pretrained(
+ "jhu-clsp/ettin-decoder-17m",
+ torch_dtype=torch.float16,
+ device_map="auto",
+)
+
+prompt = "The future of artificial intelligence is"
+inputs = tokenizer(prompt, return_tensors="pt").to(model.device)
+
+with torch.no_grad():
+ outputs = model.generate(
+ **inputs,
+ max_length=50,
+ num_return_sequences=1,
+ temperature=0.7,
+ do_sample=True,
+ pad_token_id=tokenizer.eos_token_id
+ )
+
+generated_text = tokenizer.decode(outputs[0], skip_special_tokens=True)
+print(f"Generated text: {generated_text}")
+
+# For sequence classification
+from transformers import AutoModelForSequenceClassification
+
+classifier_model = AutoModelForSequenceClassification.from_pretrained(
+ "jhu-clsp/ettin-decoder-17m",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ num_labels=2
+)
+
+text = "This movie is really great!"
+inputs = tokenizer(text, return_tensors="pt").to(classifier_model.device)
+
+with torch.no_grad():
+ outputs = classifier_model(**inputs)
+ predictions = torch.nn.functional.softmax(outputs.logits, dim=-1)
+ predicted_class = torch.argmax(predictions, dim=-1)
+
+print(f"Predicted class: {predicted_class.item()}")
+print(f"Prediction probabilities: {predictions}")
+```
+
+
+
+
+
+```
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(
+ load_in_8bit=True,
+)
+
+tokenizer = AutoTokenizer.from_pretrained("jhu-clsp/ettin-decoder-1b")
+model = AutoModelForCausalLM.from_pretrained(
+ "jhu-clsp/ettin-decoder-1b",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+prompt = "The future of artificial intelligence is"
+inputs = tokenizer(prompt, return_tensors="pt").to(model.device)
+
+with torch.no_grad():
+ outputs = model.generate(
+ **inputs,
+ max_length=50,
+ num_return_sequences=1,
+ temperature=0.7,
+ do_sample=True,
+ pad_token_id=tokenizer.eos_token_id
+ )
+
+generated_text = tokenizer.decode(outputs[0], skip_special_tokens=True)
+print(f"Generated text: {generated_text}")
+```
+
+
+
+
+```bash
+echo "The future of artificial intelligence is" | transformers run --task text-generation --model jhu-clsp/ettin-decoder-17m --device 0
+```
+
+
+
+
+
+## ModernBertDecoderConfig
+
+[[autodoc]] ModernBertDecoderConfig
+
+
+
+
+## ModernBertDecoderModel
+
+[[autodoc]] ModernBertDecoderModel
+ - forward
+
+## ModernBertDecoderForCausalLM
+
+[[autodoc]] ModernBertDecoderForCausalLM
+ - forward
+
+## ModernBertDecoderForSequenceClassification
+
+[[autodoc]] ModernBertDecoderForSequenceClassification
+ - forward
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/modernbert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/modernbert.md
new file mode 100644
index 0000000000000000000000000000000000000000..399e7a57c6a70dd7097b318077b909a702bf5887
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/modernbert.md
@@ -0,0 +1,135 @@
+
+*This model was released on 2024-12-18 and added to Hugging Face Transformers on 2024-12-19.*
+
+
+
+
+
+
+
+
+
+# ModernBERT
+
+[ModernBERT](https://huggingface.co/papers/2412.13663) is a modernized version of [`BERT`] trained on 2T tokens. It brings many improvements to the original architecture such as rotary positional embeddings to support sequences of up to 8192 tokens, unpadding to avoid wasting compute on padding tokens, GeGLU layers, and alternating attention.
+
+You can find all the original ModernBERT checkpoints under the [ModernBERT](https://huggingface.co/collections/answerdotai/modernbert-67627ad707a4acbf33c41deb) collection.
+
+> [!TIP]
+> Click on the ModernBERT models in the right sidebar for more examples of how to apply ModernBERT to different language tasks.
+
+The example below demonstrates how to predict the `[MASK]` token with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="fill-mask",
+ model="answerdotai/ModernBERT-base",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("Plants create [MASK] through a process known as photosynthesis.")
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForMaskedLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "answerdotai/ModernBERT-base",
+)
+model = AutoModelForMaskedLM.from_pretrained(
+ "answerdotai/ModernBERT-base",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+inputs = tokenizer("Plants create [MASK] through a process known as photosynthesis.", return_tensors="pt").to(model.device)
+
+with torch.no_grad():
+ outputs = model(**inputs)
+ predictions = outputs.logits
+
+masked_index = torch.where(inputs['input_ids'] == tokenizer.mask_token_id)[1]
+predicted_token_id = predictions[0, masked_index].argmax(dim=-1)
+predicted_token = tokenizer.decode(predicted_token_id)
+
+print(f"The predicted token is: {predicted_token}")
+```
+
+
+
+
+```bash
+echo -e "Plants create [MASK] through a process known as photosynthesis." | transformers run --task fill-mask --model answerdotai/ModernBERT-base --device 0
+```
+
+
+
+
+## ModernBertConfig
+
+[[autodoc]] ModernBertConfig
+
+
+
+
+## ModernBertModel
+
+[[autodoc]] ModernBertModel
+ - forward
+
+## ModernBertForMaskedLM
+
+[[autodoc]] ModernBertForMaskedLM
+ - forward
+
+## ModernBertForSequenceClassification
+
+[[autodoc]] ModernBertForSequenceClassification
+ - forward
+
+## ModernBertForTokenClassification
+
+[[autodoc]] ModernBertForTokenClassification
+ - forward
+
+## ModernBertForMultipleChoice
+
+[[autodoc]] ModernBertForMultipleChoice
+ - forward
+
+## ModernBertForQuestionAnswering
+
+[[autodoc]] ModernBertForQuestionAnswering
+ - forward
+
+### Usage tips
+
+The ModernBert model can be fine-tuned using the HuggingFace Transformers library with its [official script](https://github.com/huggingface/transformers/blob/main/examples/pytorch/question-answering/run_qa.py) for question-answering tasks.
+
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/moonshine.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/moonshine.md
new file mode 100644
index 0000000000000000000000000000000000000000..4ce0f9a23a4c03b6d6d6db1199cad836e16f8ba8
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/moonshine.md
@@ -0,0 +1,104 @@
+
+*This model was released on 2024-10-21 and added to Hugging Face Transformers on 2025-01-10.*
+
+
+
+
+
+
+
+
+
+# Moonshine
+
+[Moonshine](https://huggingface.co/papers/2410.15608) is an encoder-decoder speech recognition model optimized for real-time transcription and recognizing voice command. Instead of using traditional absolute position embeddings, Moonshine uses Rotary Position Embedding (RoPE) to handle speech with varying lengths without using padding. This improves efficiency during inference, making it ideal for resource-constrained devices.
+
+You can find all the original Moonshine checkpoints under the [Useful Sensors](https://huggingface.co/UsefulSensors) organization.
+
+> [!TIP]
+> Click on the Moonshine models in the right sidebar for more examples of how to apply Moonshine to different speech recognition tasks.
+
+The example below demonstrates how to transcribe speech into text with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="automatic-speech-recognition",
+ model="UsefulSensors/moonshine-base",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/mlk.flac")
+```
+
+
+
+
+```py
+# pip install datasets
+import torch
+from datasets import load_dataset
+from transformers import AutoProcessor, MoonshineForConditionalGeneration
+
+processor = AutoProcessor.from_pretrained(
+ "UsefulSensors/moonshine-base",
+)
+model = MoonshineForConditionalGeneration.from_pretrained(
+ "UsefulSensors/moonshine-base",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+
+ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", split="validation")
+audio_sample = ds[0]["audio"]
+
+input_features = processor(
+ audio_sample["array"],
+ sampling_rate=audio_sample["sampling_rate"],
+ return_tensors="pt"
+)
+input_features = input_features.to(model.device, dtype=torch.float16)
+
+predicted_ids = model.generate(**input_features, cache_implementation="static")
+transcription = processor.batch_decode(predicted_ids, skip_special_tokens=True)
+transcription[0]
+```
+
+
+
+## MoonshineConfig
+
+[[autodoc]] MoonshineConfig
+
+## MoonshineModel
+
+[[autodoc]] MoonshineModel
+ - forward
+ - _mask_input_features
+
+## MoonshineForConditionalGeneration
+
+[[autodoc]] MoonshineForConditionalGeneration
+ - forward
+ - generate
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/moshi.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/moshi.md
new file mode 100644
index 0000000000000000000000000000000000000000..e17a1b7b8b14707a8fd028c4f889ce0fb58eabdf
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/moshi.md
@@ -0,0 +1,195 @@
+
+*This model was released on 2024-09-17 and added to Hugging Face Transformers on 2024-10-16.*
+
+# Moshi
+
+
+
+
+
+
+
+## Overview
+
+The Moshi model was proposed in [Moshi: a speech-text foundation model for real-time dialogue](https://huggingface.co/papers/2410.00037) by Alexandre Défossez, Laurent Mazaré, Manu Orsini, Amélie Royer, Patrick Pérez, Hervé Jégou, Edouard Grave and Neil Zeghidour.
+
+Moshi is a speech-text foundation model that casts spoken dialogue as speech-to-speech generation. Starting from a text language model backbone, Moshi generates speech as tokens from the residual quantizer of a neural audio codec, while modeling separately its own speech and that of the user into parallel streams. This allows for the removal of explicit speaker turns, and the modeling of arbitrary conversational dynamics. Moshi also predicts time-aligned text tokens as a prefix to audio tokens. This “Inner Monologue” method significantly improves the linguistic quality of generated speech and provides streaming speech recognition and text-to-speech. As a result, Moshi is the first real-time full-duplex spoken large language model, with a theoretical latency of 160ms, 200ms in practice.
+
+
+
+
+
+The abstract from the paper is the following:
+
+*We introduce Moshi, a speech-text foundation model and full-duplex spoken dialogue framework. Current systems for spoken dialogue rely on pipelines of independent components, namely voice activity detection, speech recognition, textual dialogue and text-to-speech. Such frameworks cannot emulate the experience of real conversations. First, their complexity induces a latency of several seconds between interactions. Second, text being the intermediate modality for dialogue, non-linguistic information that modifies meaning— such as emotion or non-speech sounds— is lost in the interaction. Finally, they rely on a segmentation into speaker turns, which does not take into account overlapping speech, interruptions and interjections. Moshi solves these independent issues altogether by casting spoken dialogue as speech-to-speech generation. Starting from a text language model backbone, Moshi generates speech as tokens from the residual quantizer of a neural audio codec, while modeling separately its own speech and that of the user into parallel streams. This allows for the removal of explicit speaker turns, and the modeling of arbitrary conversational dynamics. We moreover extend the hierarchical semantic-to-acoustic token generation of previous work to first predict time-aligned text tokens as a prefix to audio tokens. Not only this “Inner Monologue” method significantly improves the linguistic quality of generated speech, but we also illustrate how it can provide streaming speech recognition and text-to-speech. Our resulting model is the first real-time full-duplex spoken large language model, with a theoretical latency of 160ms, 200ms in practice, and is available at github.com/kyutai-labs/moshi.*
+
+Moshi deals with 3 streams of information:
+1. The user's audio
+2. Moshi's audio
+3. Moshi's textual output
+
+Similarly to [`~MusicgenModel`], audio is represented with audio codebooks, which can be interpreted like tokens. The main difference between text tokens and audio codebooks is that audio codebooks introduce an additional dimension of information.
+Text tokens are typically of dim `(batch_size, sequence_length)` but audio tokens are of dim `(batch_size, num_codebooks, sequence_length)`.
+
+Moshi's made of 3 components:
+
+**1. The main decoder (Helium in the paper)**
+
+It corresponds to [`MoshiForCausalLM`]. It is strictly a classic text LLM, that uses an architecture similar to [` ~GemmaForCausalLM`]. In other words, it takes text tokens, embeds them, pass them through the decoder and a language head, to get text logits.
+
+**2. The depth decoder**
+
+On its own, it's also a classic LLM, but this time, instead of generating over the time dimension, it generates over the codebook dimension.
+
+It also means that its context length is `num_codebooks`, thus it can't generate more than `num_codebooks`.
+
+Note that each timestamp - i.e each codebook - gets its own set of Linear Layers and Embeddings.
+
+**3. [`MimiModel`]**
+
+It's the audio encoder from Kyutai, that has recently been integrated to transformers, which is used to "tokenize" audio. It has the same use that [`~EncodecModel`] has in [`~MusicgenModel`].
+
+
+## Tips:
+
+The original checkpoints can be converted using the conversion script `src/transformers/models/moshi/convert_moshi_transformers.py`
+
+
+### How to use the model:
+
+This implementation has two main aims:
+1. quickly test model generation by simplifying the original API
+2. simplify training. A training guide will come soon, but user contributions are welcomed!
+
+
+
+It is designed for intermediate use. We strongly recommend using the original [implementation](https://github.com/kyutai-labs/moshi) to infer the model in real-time streaming.
+
+
+
+**1. Model generation**
+
+Moshi is a streaming auto-regressive model with two streams of audio. To put it differently, one audio stream corresponds to what the model said/will say and the other audio stream corresponds to what the user said/will say.
+
+[`MoshiForConditionalGeneration.generate`] thus needs 3 inputs:
+1. `input_ids` - corresponding to the text token history
+2. `moshi_input_values` or `moshi_audio_codes`- corresponding to the model audio history
+3. `user_input_values` or `user_audio_codes` - corresponding to the user audio history
+
+These three inputs must be synchronized. Meaning that their lengths must correspond to the same number of tokens.
+
+You can dynamically use the 3 inputs depending on what you want to test:
+1. Simply check the model response to an user prompt - in that case, `input_ids` can be filled with pad tokens and `user_input_values` can be a zero tensor of the same shape than the user prompt.
+2. Test more complex behaviour - in that case, you must be careful about how the input tokens are synchronized with the audios.
+
+
+
+The original model is synchronized text with audio by padding the text in between each token enunciation.
+
+To follow the example of the following image, `"Hello, I'm Moshi"` could be transformed to `"Hello,I'm Moshi"`.
+
+
+
+
+
+
+
+
+[`MoshiForConditionalGeneration.generate`] then auto-regressively feeds to itself its own audio stream, but since it doesn't have access to the user input stream while using `transformers`, it will thus **assume that the user is producing blank audio**.
+
+
+
+```python
+>>> from datasets import load_dataset, Audio
+>>> import torch, math
+>>> from transformers import MoshiForConditionalGeneration, AutoFeatureExtractor, AutoTokenizer, infer_device
+
+
+>>> librispeech_dummy = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("kyutai/moshiko-pytorch-bf16")
+>>> tokenizer = AutoTokenizer.from_pretrained("kyutai/moshiko-pytorch-bf16")
+>>> device = infer_device()
+>>> dtype = torch.bfloat16
+
+>>> # prepare user input audio
+>>> librispeech_dummy = librispeech_dummy.cast_column("audio", Audio(sampling_rate=feature_extractor.sampling_rate))
+>>> audio_sample = librispeech_dummy[-1]["audio"]["array"]
+>>> user_input_values = feature_extractor(raw_audio=audio_sample, sampling_rate=feature_extractor.sampling_rate, return_tensors="pt").to(device=device, dtype=dtype)
+
+>>> # prepare moshi input values - we suppose moshi didn't say anything while the user spoke
+>>> moshi_input_values = torch.zeros_like(user_input_values.input_values)
+
+>>> # prepare moshi input ids - we suppose moshi didn't say anything while the user spoke
+>>> num_tokens = math.ceil(moshi_input_values.shape[-1] * waveform_to_token_ratio)
+>>> input_ids = torch.ones((1, num_tokens), device=device, dtype=torch.int64) * tokenizer.encode("")[0]
+
+>>> # generate 25 new tokens (around 2s of audio)
+>>> output = model.generate(input_ids=input_ids, user_input_values=user_input_values.input_values, moshi_input_values=moshi_input_values, max_new_tokens=25)
+
+>>> text_tokens = output.sequences
+>>> audio_waveforms = output.audio_sequences
+```
+
+**2. Model training**
+
+Most of the work has to be done during data creation/pre-processing, because of the need to align/synchronize streams.
+
+Once it's done, you can simply forward `text_labels` and `audio_labels` to [`MoshiForConditionalGeneration.forward`], alongside the usual inputs, to get the model loss.
+
+A training guide will come soon, but user contributions are welcomed!
+
+### How does the model forward the inputs / generate:
+
+1. The input streams are embedded and combined into `inputs_embeds`.
+
+2. `inputs_embeds` is passed through the main decoder, which processes it like a normal LLM would.
+
+3. The main decoder outputs `text logits` but also its `last hidden state` which is called `temporal context` in the paper.
+
+3. The depth decoder switches the dimension on which we forward / generate (codebooks instead of time). It uses the token generated from `text logits` and the `temporal context` to auto-regressively generate audio codebooks.
+
+
+This model was contributed by [Yoach Lacombe (ylacombe)](https://huggingface.co/ylacombe).
+
+The original code can be found [here](https://github.com/kyutai-labs/moshi).
+
+
+
+## MoshiConfig
+
+[[autodoc]] MoshiConfig
+
+## MoshiDepthConfig
+
+[[autodoc]] MoshiDepthConfig
+
+## MoshiModel
+
+[[autodoc]] MoshiModel
+ - forward
+
+## MoshiForCausalLM
+
+[[autodoc]] MoshiForCausalLM
+ - forward
+
+## MoshiForConditionalGeneration
+
+[[autodoc]] MoshiForConditionalGeneration
+ - forward
+ - generate
+ - get_unconditional_inputs
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mpnet.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mpnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..4b1871165521dd8a0dbfdd0d5c57966706c8f84a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mpnet.md
@@ -0,0 +1,144 @@
+
+*This model was released on 2020-04-20 and added to Hugging Face Transformers on 2020-12-09.*
+
+# MPNet
+
+
+
+
+
+
+## Overview
+
+The MPNet model was proposed in [MPNet: Masked and Permuted Pre-training for Language Understanding](https://huggingface.co/papers/2004.09297) by Kaitao Song, Xu Tan, Tao Qin, Jianfeng Lu, Tie-Yan Liu.
+
+MPNet adopts a novel pre-training method, named masked and permuted language modeling, to inherit the advantages of
+masked language modeling and permuted language modeling for natural language understanding.
+
+The abstract from the paper is the following:
+
+*BERT adopts masked language modeling (MLM) for pre-training and is one of the most successful pre-training models.
+Since BERT neglects dependency among predicted tokens, XLNet introduces permuted language modeling (PLM) for
+pre-training to address this problem. However, XLNet does not leverage the full position information of a sentence and
+thus suffers from position discrepancy between pre-training and fine-tuning. In this paper, we propose MPNet, a novel
+pre-training method that inherits the advantages of BERT and XLNet and avoids their limitations. MPNet leverages the
+dependency among predicted tokens through permuted language modeling (vs. MLM in BERT), and takes auxiliary position
+information as input to make the model see a full sentence and thus reducing the position discrepancy (vs. PLM in
+XLNet). We pre-train MPNet on a large-scale dataset (over 160GB text corpora) and fine-tune on a variety of
+down-streaming tasks (GLUE, SQuAD, etc). Experimental results show that MPNet outperforms MLM and PLM by a large
+margin, and achieves better results on these tasks compared with previous state-of-the-art pre-trained methods (e.g.,
+BERT, XLNet, RoBERTa) under the same model setting.*
+
+The original code can be found [here](https://github.com/microsoft/MPNet).
+
+## Usage tips
+
+MPNet doesn't have `token_type_ids`, you don't need to indicate which token belongs to which segment. Just
+separate your segments with the separation token `tokenizer.sep_token` (or `[sep]`).
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## MPNetConfig
+
+[[autodoc]] MPNetConfig
+
+## MPNetTokenizer
+
+[[autodoc]] MPNetTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## MPNetTokenizerFast
+
+[[autodoc]] MPNetTokenizerFast
+
+
+
+
+## MPNetModel
+
+[[autodoc]] MPNetModel
+ - forward
+
+## MPNetForMaskedLM
+
+[[autodoc]] MPNetForMaskedLM
+ - forward
+
+## MPNetForSequenceClassification
+
+[[autodoc]] MPNetForSequenceClassification
+ - forward
+
+## MPNetForMultipleChoice
+
+[[autodoc]] MPNetForMultipleChoice
+ - forward
+
+## MPNetForTokenClassification
+
+[[autodoc]] MPNetForTokenClassification
+ - forward
+
+## MPNetForQuestionAnswering
+
+[[autodoc]] MPNetForQuestionAnswering
+ - forward
+
+
+
+
+## TFMPNetModel
+
+[[autodoc]] TFMPNetModel
+ - call
+
+## TFMPNetForMaskedLM
+
+[[autodoc]] TFMPNetForMaskedLM
+ - call
+
+## TFMPNetForSequenceClassification
+
+[[autodoc]] TFMPNetForSequenceClassification
+ - call
+
+## TFMPNetForMultipleChoice
+
+[[autodoc]] TFMPNetForMultipleChoice
+ - call
+
+## TFMPNetForTokenClassification
+
+[[autodoc]] TFMPNetForTokenClassification
+ - call
+
+## TFMPNetForQuestionAnswering
+
+[[autodoc]] TFMPNetForQuestionAnswering
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mpt.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mpt.md
new file mode 100644
index 0000000000000000000000000000000000000000..9482e6a91958dd6dc4ffe73d37fdc7be22d5b804
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mpt.md
@@ -0,0 +1,75 @@
+
+*This model was released on 2023-05-05 and added to Hugging Face Transformers on 2023-07-25.*
+
+# MPT
+
+
+
+
+
+## Overview
+
+The MPT model was proposed by the [MosaicML](https://www.mosaicml.com/) team and released with multiple sizes and finetuned variants. The MPT models are a series of open source and commercially usable LLMs pre-trained on 1T tokens.
+
+MPT models are GPT-style decoder-only transformers with several improvements: performance-optimized layer implementations, architecture changes that provide greater training stability, and the elimination of context length limits by replacing positional embeddings with ALiBi.
+
+- MPT base: MPT base pre-trained models on next token prediction
+- MPT instruct: MPT base models fine-tuned on instruction based tasks
+- MPT storywriter: MPT base models fine-tuned for 2500 steps on 65k-token excerpts of fiction books contained in the books3 corpus, this enables the model to handle very long sequences
+
+The original code is available at the [`llm-foundry`](https://github.com/mosaicml/llm-foundry/tree/main) repository.
+
+Read more about it [in the release blogpost](https://www.mosaicml.com/blog/mpt-7b)
+
+## Usage tips
+
+- Learn more about some techniques behind training of the model [in this section of llm-foundry repository](https://github.com/mosaicml/llm-foundry/blob/main/TUTORIAL.md#faqs)
+- If you want to use the advanced version of the model (triton kernels, direct flash attention integration), you can still use the original model implementation by adding `trust_remote_code=True` when calling `from_pretrained`.
+
+## Resources
+
+- [Fine-tuning Notebook](https://colab.research.google.com/drive/1HCpQkLL7UXW8xJUJJ29X7QAeNJKO0frZ?usp=sharing) on how to fine-tune MPT-7B on a free Google Colab instance to turn the model into a Chatbot.
+
+## MptConfig
+
+[[autodoc]] MptConfig
+ - all
+
+## MptModel
+
+[[autodoc]] MptModel
+ - forward
+
+## MptForCausalLM
+
+[[autodoc]] MptForCausalLM
+ - forward
+
+## MptForSequenceClassification
+
+[[autodoc]] MptForSequenceClassification
+ - forward
+
+## MptForTokenClassification
+
+[[autodoc]] MptForTokenClassification
+ - forward
+
+## MptForQuestionAnswering
+
+[[autodoc]] MptForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mra.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mra.md
new file mode 100644
index 0000000000000000000000000000000000000000..ed11d1d9e04f9ff1513ecb3aa423e740e77c5de9
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mra.md
@@ -0,0 +1,67 @@
+
+*This model was released on 2022-07-21 and added to Hugging Face Transformers on 2023-07-10.*
+
+# MRA
+
+
+
+
+
+## Overview
+
+The MRA model was proposed in [Multi Resolution Analysis (MRA) for Approximate Self-Attention](https://huggingface.co/papers/2207.10284) by Zhanpeng Zeng, Sourav Pal, Jeffery Kline, Glenn M Fung, and Vikas Singh.
+
+The abstract from the paper is the following:
+
+*Transformers have emerged as a preferred model for many tasks in natural language processing and vision. Recent efforts on training and deploying Transformers more efficiently have identified many strategies to approximate the self-attention matrix, a key module in a Transformer architecture. Effective ideas include various prespecified sparsity patterns, low-rank basis expansions and combinations thereof. In this paper, we revisit classical Multiresolution Analysis (MRA) concepts such as Wavelets, whose potential value in this setting remains underexplored thus far. We show that simple approximations based on empirical feedback and design choices informed by modern hardware and implementation challenges, eventually yield a MRA-based approach for self-attention with an excellent performance profile across most criteria of interest. We undertake an extensive set of experiments and demonstrate that this multi-resolution scheme outperforms most efficient self-attention proposals and is favorable for both short and long sequences. Code is available at https://github.com/mlpen/mra-attention.*
+
+This model was contributed by [novice03](https://huggingface.co/novice03).
+The original code can be found [here](https://github.com/mlpen/mra-attention).
+
+## MraConfig
+
+[[autodoc]] MraConfig
+
+## MraModel
+
+[[autodoc]] MraModel
+ - forward
+
+## MraForMaskedLM
+
+[[autodoc]] MraForMaskedLM
+ - forward
+
+## MraForSequenceClassification
+
+[[autodoc]] MraForSequenceClassification
+ - forward
+
+## MraForMultipleChoice
+
+[[autodoc]] MraForMultipleChoice
+ - forward
+
+## MraForTokenClassification
+
+[[autodoc]] MraForTokenClassification
+ - forward
+
+## MraForQuestionAnswering
+
+[[autodoc]] MraForQuestionAnswering
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mt5.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mt5.md
new file mode 100644
index 0000000000000000000000000000000000000000..088c5bf478d86c9a8a71ab3c5aa0993dbd51726f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mt5.md
@@ -0,0 +1,203 @@
+
+*This model was released on 2020-10-22 and added to Hugging Face Transformers on 2020-11-17.*
+
+
+
+
+
+
+
+
+
+# mT5
+
+[mT5](https://huggingface.co/papers/2010.11934) is a multilingual variant of [T5](./t5), training on 101 languages. It also incorporates a new "accidental translation" technique to prevent the model from incorrectly translating predictions into the wrong language.
+
+You can find all the original [mT5] checkpoints under the [mT5](https://huggingface.co/collections/google/mt5-release-65005f1a520f8d7b4d039509) collection.
+
+> [!TIP]
+> This model was contributed by [patrickvonplaten](https://huggingface.co/patrickvonplaten).
+>
+> Click on the mT5 models in the right sidebar for more examples of how to apply mT5 to different language tasks.
+
+The example below demonstrates how to summarize text with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```python
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="text2text-generation",
+ model="csebuetnlp/mT5_multilingual_XLSum",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("""Plants are remarkable organisms that produce their own food using a method called photosynthesis.
+This process involves converting sunlight, carbon dioxide, and water into glucose, which provides energy for growth.
+Plants play a crucial role in sustaining life on Earth by generating oxygen and serving as the foundation of most ecosystems.""")
+```
+
+
+
+
+```python
+import torch
+from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "csebuetnlp/mT5_multilingual_XLSum"
+)
+model = AutoModelForSeq2SeqLM.from_pretrained(
+ "csebuetnlp/mT5_multilingual_XLSum",
+ torch_dtype=torch.float16,
+ device_map="auto",
+)
+
+input_text = """Plants are remarkable organisms that produce their own food using a method called photosynthesis.
+This process involves converting sunlight, carbon dioxide, and water into glucose, which provides energy for growth.
+Plants play a crucial role in sustaining life on Earth by generating oxygen and serving as the foundation of most ecosystems."""
+input_ids = tokenizer(input_text, return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+echo -e "Plants are remarkable organisms that produce their own food using a method called photosynthesis." | transformers run --task text2text-generation --model csebuetnlp/mT5_multilingual_XLSum --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to int4.
+
+```python
+import torch
+from transformers import BitsAndBytesConfig, AutoModelForSeq2SeqLM, AutoTokenizer
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_compute_dtype=torch.bfloat16,
+ bnb_4bit_quant_type="nf4"
+)
+model = AutoModelForSeq2SeqLM.from_pretrained(
+ "csebuetnlp/mT5_multilingual_XLSum",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "csebuetnlp/mT5_multilingual_XLSum"
+)
+input_text = """Plants are remarkable organisms that produce their own food using a method called photosynthesis.
+This process involves converting sunlight, carbon dioxide, and water into glucose, which provides energy for growth.
+Plants play a crucial role in sustaining life on Earth by generating oxygen and serving as the foundation of most ecosystems."""
+input_ids = tokenizer(input_text, return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+## Notes
+
+- mT5 must be fine-tuned for downstream tasks because it was only pretrained on the [mc4](https://huggingface.co/datasets/mc4) dataset.
+
+## MT5Config
+
+[[autodoc]] MT5Config
+
+## MT5Tokenizer
+
+[[autodoc]] MT5Tokenizer
+
+See [`T5Tokenizer`] for all details.
+
+
+## MT5TokenizerFast
+
+[[autodoc]] MT5TokenizerFast
+
+See [`T5TokenizerFast`] for all details.
+
+
+
+
+## MT5Model
+
+[[autodoc]] MT5Model
+
+## MT5ForConditionalGeneration
+
+[[autodoc]] MT5ForConditionalGeneration
+
+## MT5EncoderModel
+
+[[autodoc]] MT5EncoderModel
+
+## MT5ForSequenceClassification
+
+[[autodoc]] MT5ForSequenceClassification
+
+## MT5ForTokenClassification
+
+[[autodoc]] MT5ForTokenClassification
+
+## MT5ForQuestionAnswering
+
+[[autodoc]] MT5ForQuestionAnswering
+
+
+
+
+## TFMT5Model
+
+[[autodoc]] TFMT5Model
+
+## TFMT5ForConditionalGeneration
+
+[[autodoc]] TFMT5ForConditionalGeneration
+
+## TFMT5EncoderModel
+
+[[autodoc]] TFMT5EncoderModel
+
+
+
+
+## FlaxMT5Model
+
+[[autodoc]] FlaxMT5Model
+
+## FlaxMT5ForConditionalGeneration
+
+[[autodoc]] FlaxMT5ForConditionalGeneration
+
+## FlaxMT5EncoderModel
+
+[[autodoc]] FlaxMT5EncoderModel
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/musicgen.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/musicgen.md
new file mode 100644
index 0000000000000000000000000000000000000000..7e91b2265fe324c0e243a17c4d968a15ccaf43e1
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/musicgen.md
@@ -0,0 +1,290 @@
+
+*This model was released on 2023-06-08 and added to Hugging Face Transformers on 2023-06-29.*
+
+# MusicGen
+
+
+
+
+
+
+
+## Overview
+
+The MusicGen model was proposed in the paper [Simple and Controllable Music Generation](https://huggingface.co/papers/2306.05284)
+by Jade Copet, Felix Kreuk, Itai Gat, Tal Remez, David Kant, Gabriel Synnaeve, Yossi Adi and Alexandre Défossez.
+
+MusicGen is a single stage auto-regressive Transformer model capable of generating high-quality music samples conditioned
+on text descriptions or audio prompts. The text descriptions are passed through a frozen text encoder model to obtain a
+sequence of hidden-state representations. MusicGen is then trained to predict discrete audio tokens, or *audio codes*,
+conditioned on these hidden-states. These audio tokens are then decoded using an audio compression model, such as EnCodec,
+to recover the audio waveform.
+
+Through an efficient token interleaving pattern, MusicGen does not require a self-supervised semantic representation of
+the text/audio prompts, thus eliminating the need to cascade multiple models to predict a set of codebooks (e.g.
+hierarchically or upsampling). Instead, it is able to generate all the codebooks in a single forward pass.
+
+The abstract from the paper is the following:
+
+*We tackle the task of conditional music generation. We introduce MusicGen, a single Language Model (LM) that operates
+over several streams of compressed discrete music representation, i.e., tokens. Unlike prior work, MusicGen is comprised
+of a single-stage transformer LM together with efficient token interleaving patterns, which eliminates the need for
+cascading several models, e.g., hierarchically or upsampling. Following this approach, we demonstrate how MusicGen
+can generate high-quality samples, while being conditioned on textual description or melodic features, allowing better
+controls over the generated output. We conduct extensive empirical evaluation, considering both automatic and human
+studies, showing the proposed approach is superior to the evaluated baselines on a standard text-to-music benchmark.
+Through ablation studies, we shed light over the importance of each of the components comprising MusicGen.*
+
+This model was contributed by [sanchit-gandhi](https://huggingface.co/sanchit-gandhi). The original code can be found
+[here](https://github.com/facebookresearch/audiocraft). The pre-trained checkpoints can be found on the
+[Hugging Face Hub](https://huggingface.co/models?sort=downloads&search=facebook%2Fmusicgen-).
+
+## Usage tips
+
+- After downloading the original checkpoints from [here](https://github.com/facebookresearch/audiocraft/blob/main/docs/MUSICGEN.md#importing--exporting-models) , you can convert them using the **conversion script** available at
+`src/transformers/models/musicgen/convert_musicgen_transformers.py` with the following command:
+
+```bash
+python src/transformers/models/musicgen/convert_musicgen_transformers.py \
+ --checkpoint small --pytorch_dump_folder /output/path --safe_serialization
+```
+
+> [!NOTE]
+> The `head_mask` argument is ignored when using all attention implementation other than "eager". If you have a `head_mask` and want it to have effect, load the model with `XXXModel.from_pretrained(model_id, attn_implementation="eager")`
+
+## Generation
+
+MusicGen is compatible with two generation modes: greedy and sampling. In practice, sampling leads to significantly
+better results than greedy, thus we encourage sampling mode to be used where possible. Sampling is enabled by default,
+and can be explicitly specified by setting `do_sample=True` in the call to [`MusicgenForConditionalGeneration.generate`],
+or by overriding the model's generation config (see below).
+
+Generation is limited by the sinusoidal positional embeddings to 30 second inputs. Meaning, MusicGen cannot generate more
+than 30 seconds of audio (1503 tokens), and input audio passed by Audio-Prompted Generation contributes to this limit so,
+given an input of 20 seconds of audio, MusicGen cannot generate more than 10 seconds of additional audio.
+
+Transformers supports both mono (1-channel) and stereo (2-channel) variants of MusicGen. The mono channel versions
+generate a single set of codebooks. The stereo versions generate 2 sets of codebooks, 1 for each channel (left/right),
+and each set of codebooks is decoded independently through the audio compression model. The audio streams for each
+channel are combined to give the final stereo output.
+
+### Unconditional Generation
+
+The inputs for unconditional (or 'null') generation can be obtained through the method
+[`MusicgenForConditionalGeneration.get_unconditional_inputs`]:
+
+```python
+>>> from transformers import MusicgenForConditionalGeneration
+
+>>> model = MusicgenForConditionalGeneration.from_pretrained("facebook/musicgen-small")
+>>> unconditional_inputs = model.get_unconditional_inputs(num_samples=1)
+
+>>> audio_values = model.generate(**unconditional_inputs, do_sample=True, max_new_tokens=256)
+```
+
+The audio outputs are a three-dimensional Torch tensor of shape `(batch_size, num_channels, sequence_length)`. To listen
+to the generated audio samples, you can either play them in an ipynb notebook:
+
+```python
+from IPython.display import Audio
+
+sampling_rate = model.config.audio_encoder.sampling_rate
+Audio(audio_values[0].numpy(), rate=sampling_rate)
+```
+
+Or save them as a `.wav` file using a third-party library, e.g. `scipy`:
+
+```python
+>>> import scipy
+
+>>> sampling_rate = model.config.audio_encoder.sampling_rate
+>>> scipy.io.wavfile.write("musicgen_out.wav", rate=sampling_rate, data=audio_values[0, 0].numpy())
+```
+
+### Text-Conditional Generation
+
+The model can generate an audio sample conditioned on a text prompt through use of the [`MusicgenProcessor`] to pre-process
+the inputs:
+
+```python
+>>> from transformers import AutoProcessor, MusicgenForConditionalGeneration
+
+>>> processor = AutoProcessor.from_pretrained("facebook/musicgen-small")
+>>> model = MusicgenForConditionalGeneration.from_pretrained("facebook/musicgen-small")
+
+>>> inputs = processor(
+... text=["80s pop track with bassy drums and synth", "90s rock song with loud guitars and heavy drums"],
+... padding=True,
+... return_tensors="pt",
+... )
+>>> audio_values = model.generate(**inputs, do_sample=True, guidance_scale=3, max_new_tokens=256)
+```
+
+The `guidance_scale` is used in classifier free guidance (CFG), setting the weighting between the conditional logits
+(which are predicted from the text prompts) and the unconditional logits (which are predicted from an unconditional or
+'null' prompt). Higher guidance scale encourages the model to generate samples that are more closely linked to the input
+prompt, usually at the expense of poorer audio quality. CFG is enabled by setting `guidance_scale > 1`. For best results,
+use `guidance_scale=3` (default).
+
+### Audio-Prompted Generation
+
+The same [`MusicgenProcessor`] can be used to pre-process an audio prompt that is used for audio continuation. In the
+following example, we load an audio file using the 🤗 Datasets library, which can be pip installed through the command
+below:
+
+```bash
+pip install --upgrade pip
+pip install datasets[audio]
+```
+
+```python
+>>> from transformers import AutoProcessor, MusicgenForConditionalGeneration
+>>> from datasets import load_dataset
+
+>>> processor = AutoProcessor.from_pretrained("facebook/musicgen-small")
+>>> model = MusicgenForConditionalGeneration.from_pretrained("facebook/musicgen-small")
+
+>>> dataset = load_dataset("sanchit-gandhi/gtzan", split="train", streaming=True)
+>>> sample = next(iter(dataset))["audio"]
+
+>>> # take the first half of the audio sample
+>>> sample["array"] = sample["array"][: len(sample["array"]) // 2]
+
+>>> inputs = processor(
+... audio=sample["array"],
+... sampling_rate=sample["sampling_rate"],
+... text=["80s blues track with groovy saxophone"],
+... padding=True,
+... return_tensors="pt",
+... )
+>>> audio_values = model.generate(**inputs, do_sample=True, guidance_scale=3, max_new_tokens=256)
+```
+
+For batched audio-prompted generation, the generated `audio_values` can be post-processed to remove padding by using the
+[`MusicgenProcessor`] class:
+
+```python
+>>> from transformers import AutoProcessor, MusicgenForConditionalGeneration
+>>> from datasets import load_dataset
+
+>>> processor = AutoProcessor.from_pretrained("facebook/musicgen-small")
+>>> model = MusicgenForConditionalGeneration.from_pretrained("facebook/musicgen-small")
+
+>>> dataset = load_dataset("sanchit-gandhi/gtzan", split="train", streaming=True)
+>>> sample = next(iter(dataset))["audio"]
+
+>>> # take the first quarter of the audio sample
+>>> sample_1 = sample["array"][: len(sample["array"]) // 4]
+
+>>> # take the first half of the audio sample
+>>> sample_2 = sample["array"][: len(sample["array"]) // 2]
+
+>>> inputs = processor(
+... audio=[sample_1, sample_2],
+... sampling_rate=sample["sampling_rate"],
+... text=["80s blues track with groovy saxophone", "90s rock song with loud guitars and heavy drums"],
+... padding=True,
+... return_tensors="pt",
+... )
+>>> audio_values = model.generate(**inputs, do_sample=True, guidance_scale=3, max_new_tokens=256)
+
+>>> # post-process to remove padding from the batched audio
+>>> audio_values = processor.batch_decode(audio_values, padding_mask=inputs.padding_mask)
+```
+
+### Generation Configuration
+
+The default parameters that control the generation process, such as sampling, guidance scale and number of generated
+tokens, can be found in the model's generation config, and updated as desired:
+
+```python
+>>> from transformers import MusicgenForConditionalGeneration
+
+>>> model = MusicgenForConditionalGeneration.from_pretrained("facebook/musicgen-small")
+
+>>> # inspect the default generation config
+>>> model.generation_config
+
+>>> # increase the guidance scale to 4.0
+>>> model.generation_config.guidance_scale = 4.0
+
+>>> # decrease the max length to 256 tokens
+>>> model.generation_config.max_length = 256
+```
+
+Note that any arguments passed to the generate method will **supersede** those in the generation config, so setting
+`do_sample=False` in the call to generate will supersede the setting of `model.generation_config.do_sample` in the
+generation config.
+
+## Model Structure
+
+The MusicGen model can be de-composed into three distinct stages:
+1. Text encoder: maps the text inputs to a sequence of hidden-state representations. The pre-trained MusicGen models use a frozen text encoder from either T5 or Flan-T5
+2. MusicGen decoder: a language model (LM) that auto-regressively generates audio tokens (or codes) conditional on the encoder hidden-state representations
+3. Audio encoder/decoder: used to encode an audio prompt to use as prompt tokens, and recover the audio waveform from the audio tokens predicted by the decoder
+
+Thus, the MusicGen model can either be used as a standalone decoder model, corresponding to the class [`MusicgenForCausalLM`],
+or as a composite model that includes the text encoder and audio encoder/decoder, corresponding to the class
+[`MusicgenForConditionalGeneration`]. If only the decoder needs to be loaded from the pre-trained checkpoint, it can be loaded by first
+specifying the correct config, or be accessed through the `.decoder` attribute of the composite model:
+
+```python
+>>> from transformers import AutoConfig, MusicgenForCausalLM, MusicgenForConditionalGeneration
+
+>>> # Option 1: get decoder config and pass to `.from_pretrained`
+>>> decoder_config = AutoConfig.from_pretrained("facebook/musicgen-small").decoder
+>>> decoder = MusicgenForCausalLM.from_pretrained("facebook/musicgen-small", **decoder_config)
+
+>>> # Option 2: load the entire composite model, but only return the decoder
+>>> decoder = MusicgenForConditionalGeneration.from_pretrained("facebook/musicgen-small").decoder
+```
+
+Since the text encoder and audio encoder/decoder models are frozen during training, the MusicGen decoder [`MusicgenForCausalLM`]
+can be trained standalone on a dataset of encoder hidden-states and audio codes. For inference, the trained decoder can
+be combined with the frozen text encoder and audio encoder/decoders to recover the composite [`MusicgenForConditionalGeneration`]
+model.
+
+Tips:
+* MusicGen is trained on the 32kHz checkpoint of Encodec. You should ensure you use a compatible version of the Encodec model.
+* Sampling mode tends to deliver better results than greedy - you can toggle sampling with the variable `do_sample` in the call to [`MusicgenForConditionalGeneration.generate`]
+
+## MusicgenDecoderConfig
+
+[[autodoc]] MusicgenDecoderConfig
+
+## MusicgenConfig
+
+[[autodoc]] MusicgenConfig
+
+## MusicgenProcessor
+
+[[autodoc]] MusicgenProcessor
+
+## MusicgenModel
+
+[[autodoc]] MusicgenModel
+ - forward
+
+## MusicgenForCausalLM
+
+[[autodoc]] MusicgenForCausalLM
+ - forward
+
+## MusicgenForConditionalGeneration
+
+[[autodoc]] MusicgenForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/musicgen_melody.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/musicgen_melody.md
new file mode 100644
index 0000000000000000000000000000000000000000..d2cd51bbcf2cb2ffcc8c53fb56c16dd1c22df132
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/musicgen_melody.md
@@ -0,0 +1,297 @@
+
+*This model was released on 2023-06-08 and added to Hugging Face Transformers on 2024-03-18.*
+
+# MusicGen Melody
+
+
+
+
+
+
+
+## Overview
+
+The MusicGen Melody model was proposed in [Simple and Controllable Music Generation](https://huggingface.co/papers/2306.05284) by Jade Copet, Felix Kreuk, Itai Gat, Tal Remez, David Kant, Gabriel Synnaeve, Yossi Adi and Alexandre Défossez.
+
+MusicGen Melody is a single stage auto-regressive Transformer model capable of generating high-quality music samples conditioned on text descriptions or audio prompts. The text descriptions are passed through a frozen text encoder model to obtain a sequence of hidden-state representations. MusicGen is then trained to predict discrete audio tokens, or *audio codes*, conditioned on these hidden-states. These audio tokens are then decoded using an audio compression model, such as EnCodec, to recover the audio waveform.
+
+Through an efficient token interleaving pattern, MusicGen does not require a self-supervised semantic representation of the text/audio prompts, thus eliminating the need to cascade multiple models to predict a set of codebooks (e.g. hierarchically or upsampling). Instead, it is able to generate all the codebooks in a single forward pass.
+
+The abstract from the paper is the following:
+
+*We tackle the task of conditional music generation. We introduce MusicGen, a single Language Model (LM) that operates over several streams of compressed discrete music representation, i.e., tokens. Unlike prior work, MusicGen is comprised of a single-stage transformer LM together with efficient token interleaving patterns, which eliminates the need for cascading several models, e.g., hierarchically or upsampling. Following this approach, we demonstrate how MusicGen can generate high-quality samples, while being conditioned on textual description or melodic features, allowing better controls over the generated output. We conduct extensive empirical evaluation, considering both automatic and human studies, showing the proposed approach is superior to the evaluated baselines on a standard text-to-music benchmark. Through ablation studies, we shed light over the importance of each of the components comprising MusicGen.*
+
+
+This model was contributed by [ylacombe](https://huggingface.co/ylacombe). The original code can be found [here](https://github.com/facebookresearch/audiocraft). The pre-trained checkpoints can be found on the [Hugging Face Hub](https://huggingface.co/models?sort=downloads&search=facebook%2Fmusicgen).
+
+
+## Difference with [MusicGen](https://huggingface.co/docs/transformers/main/en/model_doc/musicgen)
+
+There are two key differences with MusicGen:
+1. The audio prompt is used here as a conditional signal for the generated audio sample, whereas it's used for audio continuation in [MusicGen](https://huggingface.co/docs/transformers/main/en/model_doc/musicgen).
+2. Conditional text and audio signals are concatenated to the decoder's hidden states instead of being used as a cross-attention signal, as in MusicGen.
+
+> [!NOTE]
+> The `head_mask` argument is ignored when using all attention implementation other than "eager". If you have a `head_mask` and want it to have effect, load the model with `XXXModel.from_pretrained(model_id, attn_implementation="eager")`
+
+## Generation
+
+MusicGen Melody is compatible with two generation modes: greedy and sampling. In practice, sampling leads to significantly better results than greedy, thus we encourage sampling mode to be used where possible. Sampling is enabled by default, and can be explicitly specified by setting `do_sample=True` in the call to [`MusicgenMelodyForConditionalGeneration.generate`], or by overriding the model's generation config (see below).
+
+Transformers supports both mono (1-channel) and stereo (2-channel) variants of MusicGen Melody. The mono channel versions generate a single set of codebooks. The stereo versions generate 2 sets of codebooks, 1 for each channel (left/right), and each set of codebooks is decoded independently through the audio compression model. The audio streams for each channel are combined to give the final stereo output.
+
+
+#### Audio Conditional Generation
+
+The model can generate an audio sample conditioned on a text and an audio prompt through use of the [`MusicgenMelodyProcessor`] to pre-process the inputs.
+
+In the following examples, we load an audio file using the 🤗 Datasets library, which can be pip installed through the command below:
+
+```
+pip install --upgrade pip
+pip install datasets[audio]
+```
+
+The audio file we are about to use is loaded as follows:
+```python
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("sanchit-gandhi/gtzan", split="train", streaming=True)
+>>> sample = next(iter(dataset))["audio"]
+```
+
+The audio prompt should ideally be free of the low-frequency signals usually produced by instruments such as drums and bass. The [Demucs](https://github.com/adefossez/demucs/tree/main) model can be used to separate vocals and other signals from the drums and bass components.
+
+If you wish to use Demucs, you first need to follow the installation steps [here](https://github.com/adefossez/demucs/tree/main?tab=readme-ov-file#for-musicians) before using the following snippet:
+
+```python
+from demucs import pretrained
+from demucs.apply import apply_model
+from demucs.audio import convert_audio
+import torch
+
+
+wav = torch.tensor(sample["array"]).to(torch.float32)
+
+demucs = pretrained.get_model('htdemucs')
+
+wav = convert_audio(wav[None], sample["sampling_rate"], demucs.samplerate, demucs.audio_channels)
+wav = apply_model(demucs, wav[None])
+```
+
+You can then use the following snippet to generate music:
+
+```python
+>>> from transformers import AutoProcessor, MusicgenMelodyForConditionalGeneration
+
+>>> processor = AutoProcessor.from_pretrained("facebook/musicgen-melody")
+>>> model = MusicgenMelodyForConditionalGeneration.from_pretrained("facebook/musicgen-melody")
+
+>>> inputs = processor(
+... audio=wav,
+... sampling_rate=demucs.samplerate,
+... text=["80s blues track with groovy saxophone"],
+... padding=True,
+... return_tensors="pt",
+... )
+>>> audio_values = model.generate(**inputs, do_sample=True, guidance_scale=3, max_new_tokens=256)
+```
+
+You can also pass the audio signal directly without using Demucs, although the quality of the generation will probably be degraded:
+
+```python
+>>> from transformers import AutoProcessor, MusicgenMelodyForConditionalGeneration
+
+>>> processor = AutoProcessor.from_pretrained("facebook/musicgen-melody")
+>>> model = MusicgenMelodyForConditionalGeneration.from_pretrained("facebook/musicgen-melody")
+
+>>> inputs = processor(
+... audio=sample["array"],
+... sampling_rate=sample["sampling_rate"],
+... text=["80s blues track with groovy saxophone"],
+... padding=True,
+... return_tensors="pt",
+... )
+>>> audio_values = model.generate(**inputs, do_sample=True, guidance_scale=3, max_new_tokens=256)
+```
+
+The audio outputs are a three-dimensional Torch tensor of shape `(batch_size, num_channels, sequence_length)`. To listen to the generated audio samples, you can either play them in an ipynb notebook:
+
+```python
+from IPython.display import Audio
+
+sampling_rate = model.config.audio_encoder.sampling_rate
+Audio(audio_values[0].numpy(), rate=sampling_rate)
+```
+
+Or save them as a `.wav` file using a third-party library, e.g. `soundfile`:
+
+```python
+>>> import soundfile as sf
+
+>>> sampling_rate = model.config.audio_encoder.sampling_rate
+>>> sf.write("musicgen_out.wav", audio_values[0].T.numpy(), sampling_rate)
+```
+
+
+### Text-only Conditional Generation
+
+The same [`MusicgenMelodyProcessor`] can be used to pre-process a text-only prompt.
+
+```python
+>>> from transformers import AutoProcessor, MusicgenMelodyForConditionalGeneration
+
+>>> processor = AutoProcessor.from_pretrained("facebook/musicgen-melody")
+>>> model = MusicgenMelodyForConditionalGeneration.from_pretrained("facebook/musicgen-melody")
+
+>>> inputs = processor(
+... text=["80s pop track with bassy drums and synth", "90s rock song with loud guitars and heavy drums"],
+... padding=True,
+... return_tensors="pt",
+... )
+>>> audio_values = model.generate(**inputs, do_sample=True, guidance_scale=3, max_new_tokens=256)
+```
+
+The `guidance_scale` is used in classifier free guidance (CFG), setting the weighting between the conditional logits (which are predicted from the text prompts) and the unconditional logits (which are predicted from an unconditional or 'null' prompt). Higher guidance scale encourages the model to generate samples that are more closely linked to the input prompt, usually at the expense of poorer audio quality. CFG is enabled by setting `guidance_scale > 1`. For best results, use `guidance_scale=3` (default).
+
+
+You can also generate in batch:
+
+```python
+>>> from transformers import AutoProcessor, MusicgenMelodyForConditionalGeneration
+>>> from datasets import load_dataset
+
+>>> processor = AutoProcessor.from_pretrained("facebook/musicgen-melody")
+>>> model = MusicgenMelodyForConditionalGeneration.from_pretrained("facebook/musicgen-melody")
+
+>>> # take the first quarter of the audio sample
+>>> sample_1 = sample["array"][: len(sample["array"]) // 4]
+
+>>> # take the first half of the audio sample
+>>> sample_2 = sample["array"][: len(sample["array"]) // 2]
+
+>>> inputs = processor(
+... audio=[sample_1, sample_2],
+... sampling_rate=sample["sampling_rate"],
+... text=["80s blues track with groovy saxophone", "90s rock song with loud guitars and heavy drums"],
+... padding=True,
+... return_tensors="pt",
+... )
+>>> audio_values = model.generate(**inputs, do_sample=True, guidance_scale=3, max_new_tokens=256)
+```
+
+### Unconditional Generation
+
+The inputs for unconditional (or 'null') generation can be obtained through the method [`MusicgenMelodyProcessor.get_unconditional_inputs`]:
+
+```python
+>>> from transformers import MusicgenMelodyForConditionalGeneration, MusicgenMelodyProcessor
+
+>>> model = MusicgenMelodyForConditionalGeneration.from_pretrained("facebook/musicgen-melody")
+>>> unconditional_inputs = MusicgenMelodyProcessor.from_pretrained("facebook/musicgen-melody").get_unconditional_inputs(num_samples=1)
+
+>>> audio_values = model.generate(**unconditional_inputs, do_sample=True, max_new_tokens=256)
+```
+
+### Generation Configuration
+
+The default parameters that control the generation process, such as sampling, guidance scale and number of generated tokens, can be found in the model's generation config, and updated as desired:
+
+```python
+>>> from transformers import MusicgenMelodyForConditionalGeneration
+
+>>> model = MusicgenMelodyForConditionalGeneration.from_pretrained("facebook/musicgen-melody")
+
+>>> # inspect the default generation config
+>>> model.generation_config
+
+>>> # increase the guidance scale to 4.0
+>>> model.generation_config.guidance_scale = 4.0
+
+>>> # decrease the max length to 256 tokens
+>>> model.generation_config.max_length = 256
+```
+
+Note that any arguments passed to the generate method will **supersede** those in the generation config, so setting `do_sample=False` in the call to generate will supersede the setting of `model.generation_config.do_sample` in the generation config.
+
+## Model Structure
+
+The MusicGen model can be de-composed into three distinct stages:
+1. Text encoder: maps the text inputs to a sequence of hidden-state representations. The pre-trained MusicGen models use a frozen text encoder from either T5 or Flan-T5.
+2. MusicGen Melody decoder: a language model (LM) that auto-regressively generates audio tokens (or codes) conditional on the encoder hidden-state representations
+3. Audio decoder: used to recover the audio waveform from the audio tokens predicted by the decoder.
+
+Thus, the MusicGen model can either be used as a standalone decoder model, corresponding to the class [`MusicgenMelodyForCausalLM`], or as a composite model that includes the text encoder and audio encoder, corresponding to the class [`MusicgenMelodyForConditionalGeneration`]. If only the decoder needs to be loaded from the pre-trained checkpoint, it can be loaded by first specifying the correct config, or be accessed through the `.decoder` attribute of the composite model:
+
+```python
+>>> from transformers import AutoConfig, MusicgenMelodyForCausalLM, MusicgenMelodyForConditionalGeneration
+
+>>> # Option 1: get decoder config and pass to `.from_pretrained`
+>>> decoder_config = AutoConfig.from_pretrained("facebook/musicgen-melody").decoder
+>>> decoder = MusicgenMelodyForCausalLM.from_pretrained("facebook/musicgen-melody", **decoder_config.to_dict())
+
+>>> # Option 2: load the entire composite model, but only return the decoder
+>>> decoder = MusicgenMelodyForConditionalGeneration.from_pretrained("facebook/musicgen-melody").decoder
+```
+
+Since the text encoder and audio encoder models are frozen during training, the MusicGen decoder [`MusicgenMelodyForCausalLM`] can be trained standalone on a dataset of encoder hidden-states and audio codes. For inference, the trained decoder can be combined with the frozen text encoder and audio encoder to recover the composite [`MusicgenMelodyForConditionalGeneration`] model.
+
+## Checkpoint Conversion
+
+- After downloading the original checkpoints from [here](https://github.com/facebookresearch/audiocraft/blob/main/docs/MUSICGEN.md#importing--exporting-models), you can convert them using the **conversion script** available at `src/transformers/models/musicgen_melody/convert_musicgen_melody_transformers.py` with the following command:
+
+```bash
+python src/transformers/models/musicgen_melody/convert_musicgen_melody_transformers.py \
+ --checkpoint="facebook/musicgen-melody" --pytorch_dump_folder /output/path
+```
+
+Tips:
+* MusicGen is trained on the 32kHz checkpoint of Encodec. You should ensure you use a compatible version of the Encodec model.
+* Sampling mode tends to deliver better results than greedy - you can toggle sampling with the variable `do_sample` in the call to [`MusicgenMelodyForConditionalGeneration.generate`]
+
+
+## MusicgenMelodyDecoderConfig
+
+[[autodoc]] MusicgenMelodyDecoderConfig
+
+## MusicgenMelodyProcessor
+
+[[autodoc]] MusicgenMelodyProcessor
+ - get_unconditional_inputs
+
+## MusicgenMelodyFeatureExtractor
+
+[[autodoc]] MusicgenMelodyFeatureExtractor
+
+## MusicgenMelodyConfig
+
+[[autodoc]] MusicgenMelodyConfig
+
+## MusicgenMelodyModel
+
+[[autodoc]] MusicgenMelodyModel
+ - forward
+
+## MusicgenMelodyForCausalLM
+
+[[autodoc]] MusicgenMelodyForCausalLM
+ - forward
+
+## MusicgenMelodyForConditionalGeneration
+
+[[autodoc]] MusicgenMelodyForConditionalGeneration
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mvp.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mvp.md
new file mode 100644
index 0000000000000000000000000000000000000000..2cce9bd6cac16b16ee5f86007d571ee562d8cbb1
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mvp.md
@@ -0,0 +1,158 @@
+
+*This model was released on 2022-06-24 and added to Hugging Face Transformers on 2022-06-29.*
+
+# MVP
+
+
+
+
+
+## Overview
+
+The MVP model was proposed in [MVP: Multi-task Supervised Pre-training for Natural Language Generation](https://huggingface.co/papers/2206.12131) by Tianyi Tang, Junyi Li, Wayne Xin Zhao and Ji-Rong Wen.
+
+
+According to the abstract,
+
+- MVP follows a standard Transformer encoder-decoder architecture.
+- MVP is supervised pre-trained using labeled datasets.
+- MVP also has task-specific soft prompts to stimulate the model's capacity in performing a certain task.
+- MVP is specially designed for natural language generation and can be adapted to a wide range of generation tasks, including but not limited to summarization, data-to-text generation, open-ended dialogue system, story generation, question answering, question generation, task-oriented dialogue system, commonsense generation, paraphrase generation, text style transfer, and text simplification. Our model can also be adapted to natural language understanding tasks such as sequence classification and (extractive) question answering.
+
+This model was contributed by [Tianyi Tang](https://huggingface.co/StevenTang). The detailed information and instructions can be found [here](https://github.com/RUCAIBox/MVP).
+
+## Usage tips
+
+- We have released a series of models [here](https://huggingface.co/models?filter=mvp), including MVP, MVP with task-specific prompts, and multi-task pre-trained variants.
+- If you want to use a model without prompts (standard Transformer), you can load it through `MvpForConditionalGeneration.from_pretrained('RUCAIBox/mvp')`.
+- If you want to use a model with task-specific prompts, such as summarization, you can load it through `MvpForConditionalGeneration.from_pretrained('RUCAIBox/mvp-summarization')`.
+- Our model supports lightweight prompt tuning following [Prefix-tuning](https://huggingface.co/papers/2101.00190) with method `set_lightweight_tuning()`.
+
+## Usage examples
+
+For summarization, it is an example to use MVP and MVP with summarization-specific prompts.
+
+```python
+>>> from transformers import MvpTokenizer, MvpForConditionalGeneration
+
+>>> tokenizer = MvpTokenizer.from_pretrained("RUCAIBox/mvp")
+>>> model = MvpForConditionalGeneration.from_pretrained("RUCAIBox/mvp")
+>>> model_with_prompt = MvpForConditionalGeneration.from_pretrained("RUCAIBox/mvp-summarization")
+
+>>> inputs = tokenizer(
+... "Summarize: You may want to stick it to your boss and leave your job, but don't do it if these are your reasons.",
+... return_tensors="pt",
+... )
+>>> generated_ids = model.generate(**inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+["Why You Shouldn't Quit Your Job"]
+
+>>> generated_ids = model_with_prompt.generate(**inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+["Don't do it if these are your reasons"]
+```
+
+For data-to-text generation, it is an example to use MVP and multi-task pre-trained variants.
+```python
+>>> from transformers import MvpTokenizerFast, MvpForConditionalGeneration
+
+>>> tokenizer = MvpTokenizerFast.from_pretrained("RUCAIBox/mvp")
+>>> model = MvpForConditionalGeneration.from_pretrained("RUCAIBox/mvp")
+>>> model_with_mtl = MvpForConditionalGeneration.from_pretrained("RUCAIBox/mtl-data-to-text")
+
+>>> inputs = tokenizer(
+... "Describe the following data: Iron Man | instance of | Superhero [SEP] Stan Lee | creator | Iron Man",
+... return_tensors="pt",
+... )
+>>> generated_ids = model.generate(**inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+['Stan Lee created the character of Iron Man, a fictional superhero appearing in American comic']
+
+>>> generated_ids = model_with_mtl.generate(**inputs)
+>>> tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+['Iron Man is a fictional superhero appearing in American comic books published by Marvel Comics.']
+```
+
+For lightweight tuning, *i.e.*, fixing the model and only tuning prompts, you can load MVP with randomly initialized prompts or with task-specific prompts. Our code also supports Prefix-tuning with BART following the [original paper](https://huggingface.co/papers/2101.00190).
+
+```python
+>>> from transformers import MvpForConditionalGeneration
+
+>>> model = MvpForConditionalGeneration.from_pretrained("RUCAIBox/mvp", use_prompt=True)
+>>> # the number of trainable parameters (full tuning)
+>>> sum(p.numel() for p in model.parameters() if p.requires_grad)
+468116832
+
+>>> # lightweight tuning with randomly initialized prompts
+>>> model.set_lightweight_tuning()
+>>> # the number of trainable parameters (lightweight tuning)
+>>> sum(p.numel() for p in model.parameters() if p.requires_grad)
+61823328
+
+>>> # lightweight tuning with task-specific prompts
+>>> model = MvpForConditionalGeneration.from_pretrained("RUCAIBox/mtl-data-to-text")
+>>> model.set_lightweight_tuning()
+>>> # original lightweight Prefix-tuning
+>>> model = MvpForConditionalGeneration.from_pretrained("facebook/bart-large", use_prompt=True)
+>>> model.set_lightweight_tuning()
+```
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## MvpConfig
+
+[[autodoc]] MvpConfig
+
+## MvpTokenizer
+
+[[autodoc]] MvpTokenizer
+
+## MvpTokenizerFast
+
+[[autodoc]] MvpTokenizerFast
+
+## MvpModel
+
+[[autodoc]] MvpModel
+ - forward
+
+## MvpForConditionalGeneration
+
+[[autodoc]] MvpForConditionalGeneration
+ - forward
+
+## MvpForSequenceClassification
+
+[[autodoc]] MvpForSequenceClassification
+ - forward
+
+## MvpForQuestionAnswering
+
+[[autodoc]] MvpForQuestionAnswering
+ - forward
+
+## MvpForCausalLM
+
+[[autodoc]] MvpForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/myt5.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/myt5.md
new file mode 100644
index 0000000000000000000000000000000000000000..409735751252393820b26876e5c816c13a08812c
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/myt5.md
@@ -0,0 +1,47 @@
+
+*This model was released on 2024-03-15 and added to Hugging Face Transformers on 2024-10-06.*
+
+# myt5
+
+## Overview
+
+The myt5 model was proposed in [MYTE: Morphology-Driven Byte Encoding for Better and Fairer Multilingual Language Modeling](https://huggingface.co/papers/2403.10691) by Tomasz Limisiewicz, Terra Blevins, Hila Gonen, Orevaoghene Ahia, and Luke Zettlemoyer.
+MyT5 (**My**te **T5**) is a multilingual language model based on T5 architecture.
+The model uses a **m**orphologically-driven **byte** (**MYTE**) representation described in our paper.
+**MYTE** uses codepoints corresponding to morphemes in contrast to characters used in UTF-8 encoding.
+As a pre-requisite, we used unsupervised morphological segmentation ([Morfessor](https://aclanthology.org/E14-2006.pdf)) to obtain morpheme inventories for 99 languages.
+However, the morphological segmentation step is not needed when using the pre-defined morpheme inventory from the hub (see: [Tomli/myt5-base](https://huggingface.co/Tomlim/myt5-base)).
+
+The abstract from the paper is the following:
+
+*A major consideration in multilingual language modeling is how to best represent languages with diverse vocabularies and scripts. Although contemporary text encoding methods cover most of the world’s writing systems, they exhibit bias towards the high-resource languages of the Global West. As a result, texts of underrepresented languages tend to be segmented into long sequences of linguistically meaningless units. To address the disparities, we introduce a new paradigm that encodes the same information with segments of consistent size across diverse languages. Our encoding convention (MYTE) is based on morphemes, as their inventories are more balanced across languages than characters, which are used in previous methods. We show that MYTE produces shorter encodings for all 99 analyzed languages, with the most notable improvements for non-European languages and non-Latin scripts. This, in turn, improves multilingual LM performance and diminishes the perplexity gap throughout diverse languages.*
+
+This model was contributed by [Tomasz Limisiewicz](https://huggingface.co/Tomlim).
+The original code can be found [here](https://github.com/tomlimi/MYTE).
+
+## MyT5Tokenizer
+
+[[autodoc]] MyT5Tokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## MyT5Tokenizer
+
+[[autodoc]] MyT5Tokenizer
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nat.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nat.md
new file mode 100644
index 0000000000000000000000000000000000000000..dadcae6f17f0ddd76cf058b2949d6ecbb6e862c2
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nat.md
@@ -0,0 +1,100 @@
+
+*This model was released on 2022-04-14 and added to Hugging Face Transformers on 2023-06-20.*
+
+# Neighborhood Attention Transformer
+
+
+
+
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+NAT was proposed in [Neighborhood Attention Transformer](https://huggingface.co/papers/2204.07143)
+by Ali Hassani, Steven Walton, Jiachen Li, Shen Li, and Humphrey Shi.
+
+It is a hierarchical vision transformer based on Neighborhood Attention, a sliding-window self attention pattern.
+
+The abstract from the paper is the following:
+
+*We present Neighborhood Attention (NA), the first efficient and scalable sliding-window attention mechanism for vision.
+NA is a pixel-wise operation, localizing self attention (SA) to the nearest neighboring pixels, and therefore enjoys a
+linear time and space complexity compared to the quadratic complexity of SA. The sliding-window pattern allows NA's
+receptive field to grow without needing extra pixel shifts, and preserves translational equivariance, unlike
+Swin Transformer's Window Self Attention (WSA). We develop NATTEN (Neighborhood Attention Extension), a Python package
+with efficient C++ and CUDA kernels, which allows NA to run up to 40% faster than Swin's WSA while using up to 25% less
+memory. We further present Neighborhood Attention Transformer (NAT), a new hierarchical transformer design based on NA
+that boosts image classification and downstream vision performance. Experimental results on NAT are competitive;
+NAT-Tiny reaches 83.2% top-1 accuracy on ImageNet, 51.4% mAP on MS-COCO and 48.4% mIoU on ADE20K, which is 1.9%
+ImageNet accuracy, 1.0% COCO mAP, and 2.6% ADE20K mIoU improvement over a Swin model with similar size. *
+
+
+
+ Neighborhood Attention compared to other attention patterns.
+Taken from the original paper.
+
+This model was contributed by [Ali Hassani](https://huggingface.co/alihassanijr).
+The original code can be found [here](https://github.com/SHI-Labs/Neighborhood-Attention-Transformer).
+
+## Usage tips
+
+- One can use the [`AutoImageProcessor`] API to prepare images for the model.
+- NAT can be used as a *backbone*. When `output_hidden_states = True`,
+it will output both `hidden_states` and `reshaped_hidden_states`.
+The `reshaped_hidden_states` have a shape of `(batch, num_channels, height, width)` rather than
+`(batch_size, height, width, num_channels)`.
+
+Notes:
+- NAT depends on [NATTEN](https://github.com/SHI-Labs/NATTEN/)'s implementation of Neighborhood Attention.
+You can install it with pre-built wheels for Linux by referring to [shi-labs.com/natten](https://shi-labs.com/natten),
+or build on your system by running `pip install natten`.
+Note that the latter will likely take time to compile. NATTEN does not support Windows devices yet.
+- Patch size of 4 is only supported at the moment.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with NAT.
+
+
+
+- [`NatForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## NatConfig
+
+[[autodoc]] NatConfig
+
+## NatModel
+
+[[autodoc]] NatModel
+ - forward
+
+## NatForImageClassification
+
+[[autodoc]] NatForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nemotron.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nemotron.md
new file mode 100644
index 0000000000000000000000000000000000000000..84a5b71488b7e1a111baeeb2ec3ea03996505379
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nemotron.md
@@ -0,0 +1,153 @@
+
+*This model was released on 2024-02-26 and added to Hugging Face Transformers on 2024-08-06.*
+
+# Nemotron
+
+
+
+
+
+
+
+### License
+
+The use of this model is governed by the [NVIDIA AI Foundation Models Community License Agreement](https://developer.nvidia.com/downloads/nv-ai-foundation-models-license).
+
+### Description
+
+Nemotron-4 is a family of enterprise ready generative text models compatible with [NVIDIA NeMo Framework](https://www.nvidia.com/en-us/ai-data-science/generative-ai/nemo-framework/).
+
+NVIDIA NeMo is an end-to-end, cloud-native platform to build, customize, and deploy generative AI models anywhere. It includes training and inferencing frameworks, guardrailing toolkits, data curation tools, and pretrained models, offering enterprises an easy, cost-effective, and fast way to adopt generative AI. To get access to NeMo Framework, please sign up at [this link](https://developer.nvidia.com/nemo-framework/join).
+
+### References
+
+[Announcement Blog](https://developer.nvidia.com/blog/nvidia-ai-foundation-models-build-custom-enterprise-chatbots-and-co-pilots-with-production-ready-llms/)
+
+### Model Architecture
+
+**Architecture Type:** Transformer
+
+**Network Architecture:** Transformer Decoder (auto-regressive language model).
+
+## Minitron
+
+### Minitron 4B Base
+
+Minitron is a family of small language models (SLMs) obtained by pruning NVIDIA's [Nemotron-4 15B](https://huggingface.co/papers/2402.16819) model. We prune model embedding size, attention heads, and MLP intermediate dimension, following which, we perform continued training with distillation to arrive at the final models.
+
+Deriving the Minitron 8B and 4B models from the base 15B model using our approach requires up to **40x fewer training tokens** per model compared to training from scratch; this results in **compute cost savings of 1.8x** for training the full model family (15B, 8B, and 4B). Minitron models exhibit up to a 16% improvement in MMLU scores compared to training from scratch, perform comparably to other community models such as Mistral 7B, Gemma 7B and Llama-3 8B, and outperform state-of-the-art compression techniques from the literature. Please refer to our [arXiv paper](https://huggingface.co/papers/2407.14679) for more details.
+
+Minitron models are for research and development only.
+
+### HuggingFace Quickstart
+
+The following code provides an example of how to load the Minitron-4B model and use it to perform text generation.
+
+```python
+import torch
+from transformers import AutoTokenizer, AutoModelForCausalLM
+
+# Load the tokenizer and model
+model_path = 'nvidia/Minitron-4B-Base'
+tokenizer = AutoTokenizer.from_pretrained(model_path)
+
+device = 'cuda'
+dtype = torch.bfloat16
+model = AutoModelForCausalLM.from_pretrained(model_path, torch_dtype=dtype, device_map=device)
+
+# Prepare the input text
+prompt = 'Complete the paragraph: our solar system is'
+inputs = tokenizer.encode(prompt, return_tensors='pt').to(model.device)
+
+# Generate the output
+outputs = model.generate(inputs, max_length=20)
+
+# Decode and print the output
+output_text = tokenizer.decode(outputs[0])
+print(output_text)
+```
+
+### License
+
+Minitron is released under the [NVIDIA Open Model License Agreement](https://developer.download.nvidia.com/licenses/nvidia-open-model-license-agreement-june-2024.pdf).
+
+### Evaluation Results
+
+*5-shot performance.* Language Understanding evaluated using [Massive Multitask Language Understanding](https://huggingface.co/papers/2009.03300):
+
+| Average |
+| :---- |
+| 58.6 |
+
+*Zero-shot performance.* Evaluated using select datasets from the [LM Evaluation Harness](https://github.com/EleutherAI/lm-evaluation-harness) with additions:
+
+| HellaSwag | Winogrande | GSM8K| ARC-C | XLSum |
+| :------------- | :------------- | :------------- | :------------- | :------------- |
+| 75.0 | 74.0 | 24.1 | 50.9 | 29.5
+
+
+*Code generation performance*. Evaluated using [HumanEval](https://github.com/openai/human-eval):
+
+| p@1, 0-Shot |
+| :------------- |
+| 23.3 |
+
+Please refer to our [paper](https://huggingface.co/papers/2407.14679) for the full set of results.
+
+### Citation
+
+If you find our work helpful, please consider citing our paper:
+```
+@article{minitron2024,
+ title={Compact Language Models via Pruning and Knowledge Distillation},
+ author={Saurav Muralidharan and Sharath Turuvekere Sreenivas and Raviraj Joshi and Marcin Chochowski and Mostofa Patwary and Mohammad Shoeybi and Bryan Catanzaro and Jan Kautz and Pavlo Molchanov},
+ journal={arXiv preprint arXiv:2407.14679},
+ year={2024},
+ url={https://huggingface.co/papers/2407.14679},
+}
+```
+
+## NemotronConfig
+
+[[autodoc]] NemotronConfig
+
+
+## NemotronModel
+
+[[autodoc]] NemotronModel
+ - forward
+
+
+## NemotronForCausalLM
+
+[[autodoc]] NemotronForCausalLM
+ - forward
+
+## NemotronForSequenceClassification
+
+[[autodoc]] NemotronForSequenceClassification
+ - forward
+
+
+## NemotronForQuestionAnswering
+
+[[autodoc]] NemotronForQuestionAnswering
+ - forward
+
+
+## NemotronForTokenClassification
+
+[[autodoc]] NemotronForTokenClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nezha.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nezha.md
new file mode 100644
index 0000000000000000000000000000000000000000..37687fc25df508e7f8e058ceb5b2968a69693e3c
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nezha.md
@@ -0,0 +1,101 @@
+
+*This model was released on 2019-08-31 and added to Hugging Face Transformers on 2023-06-20.*
+
+# Nezha
+
+
+
+
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The Nezha model was proposed in [NEZHA: Neural Contextualized Representation for Chinese Language Understanding](https://huggingface.co/papers/1909.00204) by Junqiu Wei et al.
+
+The abstract from the paper is the following:
+
+*The pre-trained language models have achieved great successes in various natural language understanding (NLU) tasks
+due to its capacity to capture the deep contextualized information in text by pre-training on large-scale corpora.
+In this technical report, we present our practice of pre-training language models named NEZHA (NEural contextualiZed
+representation for CHinese lAnguage understanding) on Chinese corpora and finetuning for the Chinese NLU tasks.
+The current version of NEZHA is based on BERT with a collection of proven improvements, which include Functional
+Relative Positional Encoding as an effective positional encoding scheme, Whole Word Masking strategy,
+Mixed Precision Training and the LAMB Optimizer in training the models. The experimental results show that NEZHA
+achieves the state-of-the-art performances when finetuned on several representative Chinese tasks, including
+named entity recognition (People's Daily NER), sentence matching (LCQMC), Chinese sentiment classification (ChnSenti)
+and natural language inference (XNLI).*
+
+This model was contributed by [sijunhe](https://huggingface.co/sijunhe). The original code can be found [here](https://github.com/huawei-noah/Pretrained-Language-Model/tree/master/NEZHA-PyTorch).
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## NezhaConfig
+
+[[autodoc]] NezhaConfig
+
+## NezhaModel
+
+[[autodoc]] NezhaModel
+ - forward
+
+## NezhaForPreTraining
+
+[[autodoc]] NezhaForPreTraining
+ - forward
+
+## NezhaForMaskedLM
+
+[[autodoc]] NezhaForMaskedLM
+ - forward
+
+## NezhaForNextSentencePrediction
+
+[[autodoc]] NezhaForNextSentencePrediction
+ - forward
+
+## NezhaForSequenceClassification
+
+[[autodoc]] NezhaForSequenceClassification
+ - forward
+
+## NezhaForMultipleChoice
+
+[[autodoc]] NezhaForMultipleChoice
+ - forward
+
+## NezhaForTokenClassification
+
+[[autodoc]] NezhaForTokenClassification
+ - forward
+
+## NezhaForQuestionAnswering
+
+[[autodoc]] NezhaForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nllb-moe.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nllb-moe.md
new file mode 100644
index 0000000000000000000000000000000000000000..f1456ee402dd09c00eba8eee0ee9adf586a1bed6
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nllb-moe.md
@@ -0,0 +1,138 @@
+
+*This model was released on 2022-07-11 and added to Hugging Face Transformers on 2023-03-27.*
+
+# NLLB-MOE
+
+
+
+
+
+## Overview
+
+The NLLB model was presented in [No Language Left Behind: Scaling Human-Centered Machine Translation](https://huggingface.co/papers/2207.04672) by Marta R. Costa-jussà, James Cross, Onur Çelebi,
+Maha Elbayad, Kenneth Heafield, Kevin Heffernan, Elahe Kalbassi, Janice Lam, Daniel Licht, Jean Maillard, Anna Sun, Skyler Wang, Guillaume Wenzek, Al Youngblood, Bapi Akula,
+Loic Barrault, Gabriel Mejia Gonzalez, Prangthip Hansanti, John Hoffman, Semarley Jarrett, Kaushik Ram Sadagopan, Dirk Rowe, Shannon Spruit, Chau Tran, Pierre Andrews,
+Necip Fazil Ayan, Shruti Bhosale, Sergey Edunov, Angela Fan, Cynthia Gao, Vedanuj Goswami, Francisco Guzmán, Philipp Koehn, Alexandre Mourachko, Christophe Ropers,
+Safiyyah Saleem, Holger Schwenk, and Jeff Wang.
+
+The abstract of the paper is the following:
+
+*Driven by the goal of eradicating language barriers on a global scale, machine translation has solidified itself as a key focus of artificial intelligence research today.
+However, such efforts have coalesced around a small subset of languages, leaving behind the vast majority of mostly low-resource languages. What does it take to break the
+200 language barrier while ensuring safe, high quality results, all while keeping ethical considerations in mind? In No Language Left Behind, we took on this challenge by
+first contextualizing the need for low-resource language translation support through exploratory interviews with native speakers. Then, we created datasets and models aimed
+at narrowing the performance gap between low and high-resource languages. More specifically, we developed a conditional compute model based on Sparsely Gated Mixture of
+Experts that is trained on data obtained with novel and effective data mining techniques tailored for low-resource languages. We propose multiple architectural and training
+improvements to counteract overfitting while training on thousands of tasks. Critically, we evaluated the performance of over 40,000 different translation directions using
+a human-translated benchmark, Flores-200, and combined human evaluation with a novel toxicity benchmark covering all languages in Flores-200 to assess translation safety.
+Our model achieves an improvement of 44% BLEU relative to the previous state-of-the-art, laying important groundwork towards realizing a universal translation system.*
+
+This model was contributed by [Arthur Zucker](https://huggingface.co/ArthurZ).
+The original code can be found [here](https://github.com/facebookresearch/fairseq).
+
+## Usage tips
+
+- M2M100ForConditionalGeneration is the base model for both NLLB and NLLB MoE
+- The NLLB-MoE is very similar to the NLLB model, but it's feed forward layer is based on the implementation of SwitchTransformers.
+- The tokenizer is the same as the NLLB models.
+
+## Implementation differences with SwitchTransformers
+
+The biggest difference is the way the tokens are routed. NLLB-MoE uses a `top-2-gate` which means that for each input, only the top two experts are selected based on the
+highest predicted probabilities from the gating network, and the remaining experts are ignored. In `SwitchTransformers`, only the top-1 probabilities are computed,
+which means that tokens have less probability of being forwarded. Moreover, if a token is not routed to any expert, `SwitchTransformers` still adds its unmodified hidden
+states (kind of like a residual connection) while they are masked in `NLLB`'s top-2 routing mechanism.
+
+## Generating with NLLB-MoE
+
+The available checkpoints require around 350GB of storage. Make sure to use `accelerate` if you do not have enough RAM on your machine.
+
+While generating the target text set the `forced_bos_token_id` to the target language id. The following
+example shows how to translate English to French using the *facebook/nllb-200-distilled-600M* model.
+
+Note that we're using the BCP-47 code for French `fra_Latn`. See [here](https://github.com/facebookresearch/flores/blob/main/flores200/README.md#languages-in-flores-200)
+for the list of all BCP-47 in the Flores 200 dataset.
+
+```python
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/nllb-moe-54b")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/nllb-moe-54b")
+
+>>> article = "Previously, Ring's CEO, Jamie Siminoff, remarked the company started when his doorbell wasn't audible from his shop in his garage."
+>>> inputs = tokenizer(article, return_tensors="pt")
+
+>>> translated_tokens = model.generate(
+... **inputs, forced_bos_token_id=tokenizer.lang_code_to_id["fra_Latn"], max_length=50
+... )
+>>> tokenizer.batch_decode(translated_tokens, skip_special_tokens=True)[0]
+"Auparavant, le PDG de Ring, Jamie Siminoff, a fait remarquer que la société avait commencé lorsque sa sonnette n'était pas audible depuis son magasin dans son garage."
+```
+
+### Generating from any other language than English
+
+English (`eng_Latn`) is set as the default language from which to translate. In order to specify that you'd like to translate from a different language,
+you should specify the BCP-47 code in the `src_lang` keyword argument of the tokenizer initialization.
+
+See example below for a translation from romanian to german:
+
+```python
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("facebook/nllb-moe-54b", src_lang="ron_Latn")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/nllb-moe-54b")
+
+>>> article = "Şeful ONU spune că nu există o soluţie militară în Siria"
+>>> inputs = tokenizer(article, return_tensors="pt")
+
+>>> translated_tokens = model.generate(
+... **inputs, forced_bos_token_id=tokenizer.lang_code_to_id["deu_Latn"], max_length=30
+... )
+>>> tokenizer.batch_decode(translated_tokens, skip_special_tokens=True)[0]
+```
+
+## Resources
+
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+
+## NllbMoeConfig
+
+[[autodoc]] NllbMoeConfig
+
+## NllbMoeTop2Router
+
+[[autodoc]] NllbMoeTop2Router
+ - route_tokens
+ - forward
+
+## NllbMoeSparseMLP
+
+[[autodoc]] NllbMoeSparseMLP
+ - forward
+
+## NllbMoeModel
+
+[[autodoc]] NllbMoeModel
+ - forward
+
+## NllbMoeForConditionalGeneration
+
+[[autodoc]] NllbMoeForConditionalGeneration
+ - forward
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nllb.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nllb.md
new file mode 100644
index 0000000000000000000000000000000000000000..d4ffe509890b9736e1bf46e26e543c43ee3d6ba7
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nllb.md
@@ -0,0 +1,158 @@
+
+
+
+
+
+
+
+
+
+
+*This model was released on 2022-07-11 and added to Hugging Face Transformers on 2022-07-18.*
+
+
+# NLLB
+
+[NLLB: No Language Left Behind](https://huggingface.co/papers/2207.04672) is a multilingual translation model. It's trained on data using data mining techniques tailored for low-resource languages and supports over 200 languages. NLLB features a conditional compute architecture using a Sparsely Gated Mixture of Experts.
+
+
+You can find all the original NLLB checkpoints under the [AI at Meta](https://huggingface.co/facebook/models?search=nllb) organization.
+
+> [!TIP]
+> This model was contributed by [Lysandre](https://huggingface.co/lysandre).
+> Click on the NLLB models in the right sidebar for more examples of how to apply NLLB to different translation tasks.
+
+The example below demonstrates how to translate text with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```python
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(task="translation", model="facebook/nllb-200-distilled-600M", src_lang="eng_Latn", tgt_lang="fra_Latn", torch_dtype=torch.float16, device=0)
+pipeline("UN Chief says there is no military solution in Syria")
+```
+
+
+
+
+```python
+from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("facebook/nllb-200-distilled-600M")
+model = AutoModelForSeq2SeqLM.from_pretrained("facebook/nllb-200-distilled-600M", torch_dtype="auto", attn_implementaiton="sdpa")
+
+article = "UN Chief says there is no military solution in Syria"
+inputs = tokenizer(article, return_tensors="pt")
+
+translated_tokens = model.generate(
+ **inputs, forced_bos_token_id=tokenizer.convert_tokens_to_ids("fra_Latn"), max_length=30
+)
+print(tokenizer.batch_decode(translated_tokens, skip_special_tokens=True)[0])
+```
+
+
+
+
+```bash
+echo -e "UN Chief says there is no military solution in Syria" | transformers run --task "translation_en_to_fr" --model facebook/nllb-200-distilled-600M --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to quantize the weights to 8-bits.
+
+```python
+from transformers import AutoModelForSeq2SeqLM, AutoTokenizer, BitsAndBytesConfig
+
+bnb_config = BitsAndBytesConfig(load_in_8bit=True)
+model = AutoModelForSeq2SeqLM.from_pretrained("facebook/nllb-200-distilled-1.3B", quantization_config=bnb_config)
+tokenizer = AutoTokenizer.from_pretrained("facebook/nllb-200-distilled-1.3B")
+
+article = "UN Chief says there is no military solution in Syria"
+inputs = tokenizer(article, return_tensors="pt").to("cuda")
+translated_tokens = model.generate(
+ **inputs, forced_bos_token_id=tokenizer.convert_tokens_to_ids("fra_Latn"), max_length=30,
+)
+print(tokenizer.batch_decode(translated_tokens, skip_special_tokens=True)[0])
+```
+
+Use the [AttentionMaskVisualizer](https://github.com/huggingface/transformers/blob/main/src/transformers/utils/attention_visualizer.py#L139) to better understand what tokens the model can and cannot attend to.
+
+```python
+from transformers.utils.attention_visualizer import AttentionMaskVisualizer
+
+visualizer = AttentionMaskVisualizer("facebook/nllb-200-distilled-600M")
+visualizer("UN Chief says there is no military solution in Syria")
+```
+
+
+
+
+
+## Notes
+
+- The tokenizer was updated in April 2023 to prefix the source sequence with the source language rather than the target language. This prioritizes zero-shot performance at a minor cost to supervised performance.
+
+ ```python
+ >>> from transformers import NllbTokenizer
+
+ >>> tokenizer = NllbTokenizer.from_pretrained("facebook/nllb-200-distilled-600M")
+ >>> tokenizer("How was your day?").input_ids
+ [256047, 13374, 1398, 4260, 4039, 248130, 2]
+ ```
+
+ To revert to the legacy behavior, use the code example below.
+
+ ```python
+ >>> from transformers import NllbTokenizer
+
+ >>> tokenizer = NllbTokenizer.from_pretrained("facebook/nllb-200-distilled-600M", legacy_behaviour=True)
+ ```
+
+ - For non-English languages, specify the language's [BCP-47](https://github.com/facebookresearch/flores/blob/main/flores200/README.md#languages-in-flores-200) code with the `src_lang` keyword as shown below.
+
+ - See example below for a translation from Romanian to German.
+ ```python
+ >>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+ >>> tokenizer = AutoTokenizer.from_pretrained("facebook/nllb-200-distilled-600M")
+ >>> model = AutoModelForSeq2SeqLM.from_pretrained("facebook/nllb-200-distilled-600M")
+
+ >>> article = "UN Chief says there is no military solution in Syria"
+ >>> inputs = tokenizer(article, return_tensors="pt")
+
+ >>> translated_tokens = model.generate(
+ ... **inputs, forced_bos_token_id=tokenizer.convert_tokens_to_ids("fra_Latn"), max_length=30
+ ... )
+ >>> tokenizer.batch_decode(translated_tokens, skip_special_tokens=True)[0]
+ Le chef de l'ONU dit qu'il n'y a pas de solution militaire en Syrie
+ ```
+
+## NllbTokenizer
+
+[[autodoc]] NllbTokenizer
+ - build_inputs_with_special_tokens
+
+## NllbTokenizerFast
+
+[[autodoc]] NllbTokenizerFast
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nougat.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nougat.md
new file mode 100644
index 0000000000000000000000000000000000000000..0a189d9b6e596f0a55016f24f0b9b21e219ed41f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nougat.md
@@ -0,0 +1,128 @@
+
+*This model was released on 2023-08-25 and added to Hugging Face Transformers on 2023-09-26.*
+
+# Nougat
+
+
+
+
+
+
+
+## Overview
+
+The Nougat model was proposed in [Nougat: Neural Optical Understanding for Academic Documents](https://huggingface.co/papers/2308.13418) by
+Lukas Blecher, Guillem Cucurull, Thomas Scialom, Robert Stojnic. Nougat uses the same architecture as [Donut](donut), meaning an image Transformer
+encoder and an autoregressive text Transformer decoder to translate scientific PDFs to markdown, enabling easier access to them.
+
+The abstract from the paper is the following:
+
+*Scientific knowledge is predominantly stored in books and scientific journals, often in the form of PDFs. However, the PDF format leads to a loss of semantic information, particularly for mathematical expressions. We propose Nougat (Neural Optical Understanding for Academic Documents), a Visual Transformer model that performs an Optical Character Recognition (OCR) task for processing scientific documents into a markup language, and demonstrate the effectiveness of our model on a new dataset of scientific documents. The proposed approach offers a promising solution to enhance the accessibility of scientific knowledge in the digital age, by bridging the gap between human-readable documents and machine-readable text. We release the models and code to accelerate future work on scientific text recognition.*
+
+
+
+ Nougat high-level overview. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found
+[here](https://github.com/facebookresearch/nougat).
+
+## Usage tips
+
+- The quickest way to get started with Nougat is by checking the [tutorial
+ notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Nougat), which show how to use the model
+ at inference time as well as fine-tuning on custom data.
+- Nougat is always used within the [VisionEncoderDecoder](vision-encoder-decoder) framework. The model is identical to [Donut](donut) in terms of architecture.
+
+## Inference
+
+Nougat's [`VisionEncoderDecoder`] model accepts images as input and makes use of
+[`~generation.GenerationMixin.generate`] to autoregressively generate text given the input image.
+
+The [`NougatImageProcessor`] class is responsible for preprocessing the input image and
+[`NougatTokenizerFast`] decodes the generated target tokens to the target string. The
+[`NougatProcessor`] wraps [`NougatImageProcessor`] and [`NougatTokenizerFast`] classes
+into a single instance to both extract the input features and decode the predicted token ids.
+
+- Step-by-step PDF transcription
+
+```py
+>>> from huggingface_hub import hf_hub_download
+>>> import re
+>>> from PIL import Image
+
+>>> from transformers import NougatProcessor, VisionEncoderDecoderModel, infer_device
+>>> from datasets import load_dataset
+>>> import torch
+
+>>> processor = NougatProcessor.from_pretrained("facebook/nougat-base")
+>>> model = VisionEncoderDecoderModel.from_pretrained("facebook/nougat-base")
+
+>>> device = infer_device()
+>>> model.to(device) # doctest: +IGNORE_RESULT
+
+>>> # prepare PDF image for the model
+>>> filepath = hf_hub_download(repo_id="hf-internal-testing/fixtures_docvqa", filename="nougat_paper.png", repo_type="dataset")
+>>> image = Image.open(filepath)
+>>> pixel_values = processor(image, return_tensors="pt").pixel_values
+
+>>> # generate transcription (here we only generate 30 tokens)
+>>> outputs = model.generate(
+... pixel_values.to(device),
+... min_length=1,
+... max_new_tokens=30,
+... bad_words_ids=[[processor.tokenizer.unk_token_id]],
+... )
+
+>>> sequence = processor.batch_decode(outputs, skip_special_tokens=True)[0]
+>>> sequence = processor.post_process_generation(sequence, fix_markdown=False)
+>>> # note: we're using repr here such for the sake of printing the \n characters, feel free to just print the sequence
+>>> print(repr(sequence))
+'\n\n# Nougat: Neural Optical Understanding for Academic Documents\n\n Lukas Blecher\n\nCorrespondence to: lblecher@'
+```
+
+See the [model hub](https://huggingface.co/models?filter=nougat) to look for Nougat checkpoints.
+
+
+
+The model is identical to [Donut](donut) in terms of architecture.
+
+
+
+## NougatImageProcessor
+
+[[autodoc]] NougatImageProcessor
+ - preprocess
+
+## NougatImageProcessorFast
+
+[[autodoc]] NougatImageProcessorFast
+ - preprocess
+
+## NougatTokenizerFast
+
+[[autodoc]] NougatTokenizerFast
+
+## NougatProcessor
+
+[[autodoc]] NougatProcessor
+ - __call__
+ - from_pretrained
+ - save_pretrained
+ - batch_decode
+ - decode
+ - post_process_generation
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nystromformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nystromformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..c1c1407fec0c8cde3eb54798b2ebde4c42f82ac2
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/nystromformer.md
@@ -0,0 +1,85 @@
+
+*This model was released on 2021-02-07 and added to Hugging Face Transformers on 2022-01-11.*
+
+# Nyströmformer
+
+
+
+
+
+## Overview
+
+The Nyströmformer model was proposed in [*Nyströmformer: A Nyström-Based Algorithm for Approximating Self-Attention*](https://huggingface.co/papers/2102.03902) by Yunyang Xiong, Zhanpeng Zeng, Rudrasis Chakraborty, Mingxing Tan, Glenn
+Fung, Yin Li, and Vikas Singh.
+
+The abstract from the paper is the following:
+
+*Transformers have emerged as a powerful tool for a broad range of natural language processing tasks. A key component
+that drives the impressive performance of Transformers is the self-attention mechanism that encodes the influence or
+dependence of other tokens on each specific token. While beneficial, the quadratic complexity of self-attention on the
+input sequence length has limited its application to longer sequences -- a topic being actively studied in the
+community. To address this limitation, we propose Nyströmformer -- a model that exhibits favorable scalability as a
+function of sequence length. Our idea is based on adapting the Nyström method to approximate standard self-attention
+with O(n) complexity. The scalability of Nyströmformer enables application to longer sequences with thousands of
+tokens. We perform evaluations on multiple downstream tasks on the GLUE benchmark and IMDB reviews with standard
+sequence length, and find that our Nyströmformer performs comparably, or in a few cases, even slightly better, than
+standard self-attention. On longer sequence tasks in the Long Range Arena (LRA) benchmark, Nyströmformer performs
+favorably relative to other efficient self-attention methods. Our code is available at this https URL.*
+
+This model was contributed by [novice03](https://huggingface.co/novice03). The original code can be found [here](https://github.com/mlpen/Nystromformer).
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## NystromformerConfig
+
+[[autodoc]] NystromformerConfig
+
+## NystromformerModel
+
+[[autodoc]] NystromformerModel
+ - forward
+
+## NystromformerForMaskedLM
+
+[[autodoc]] NystromformerForMaskedLM
+ - forward
+
+## NystromformerForSequenceClassification
+
+[[autodoc]] NystromformerForSequenceClassification
+ - forward
+
+## NystromformerForMultipleChoice
+
+[[autodoc]] NystromformerForMultipleChoice
+ - forward
+
+## NystromformerForTokenClassification
+
+[[autodoc]] NystromformerForTokenClassification
+ - forward
+
+## NystromformerForQuestionAnswering
+
+[[autodoc]] NystromformerForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/olmo.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/olmo.md
new file mode 100644
index 0000000000000000000000000000000000000000..56165dcf450168b4e0dae28933cfa242609e16e4
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/olmo.md
@@ -0,0 +1,135 @@
+
+*This model was released on 2024-02-01 and added to Hugging Face Transformers on 2024-04-17.*
+
+
+
+
+
+
+
+
+
+
+# OLMo
+[OLMo](https://huggingface.co/papers/2402.00838) is a 7B-parameter dense language model. It uses SwiGLU activations, non-parametric layer normalization, rotary positional embeddings, and a BPE tokenizer that masks personally identifiable information. It is pretrained on [Dolma](https://huggingface.co/datasets/allenai/dolma), a 3T-token dataset. OLMo was released to provide complete transparency of not just the model weights but the training data, training code, and evaluation code to enable more research on language models.
+
+You can find all the original OLMo checkpoints under the [OLMo](https://huggingface.co/collections/allenai/olmo-suite-65aeaae8fe5b6b2122b46778) collection.
+
+> [!TIP]
+> This model was contributed by [shanearora](https://huggingface.co/shanearora).
+>
+> Click on the OLMo models in the right sidebar for more examples of how to apply OLMo to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipe = pipeline(
+ task="text-generation",
+ model="allenai/OLMo-7B-hf",
+ torch_dtype=torch.float16,
+ device=0,
+)
+
+result = pipe("Plants create energy through a process known as")
+print(result)
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "allenai/OLMo-7B-hf"
+)
+
+model = AutoModelForCausalLM.from_pretrained(
+ "allenai/OLMo-7B-hf",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+input_ids = tokenizer("Plants create energy through a process known as", return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, max_length=50, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+echo -e "Plants create energy through a process known as" | transformers run --task text-generation --model allenai/OLMo-7B-hf --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to 4-bits.
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_compute_dtype=torch.float16,
+ bnb_4bit_use_double_quant=True,
+ bnb_4bit_quant_type="nf4"
+)
+
+model = AutoModelForCausalLM.from_pretrained(
+ "allenai/OLMo-7B-hf",
+ attn_implementation="sdpa",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained("allenai/OLMo-7B-hf")
+
+inputs = tokenizer("Bitcoin is", return_tensors="pt")
+inputs = {k: v.to(model.device) for k, v in inputs.items()}
+
+output = model.generate(**inputs, max_length=64)
+
+print(tokenizer.decode(output[0]))
+```
+
+## OlmoConfig
+
+[[autodoc]] OlmoConfig
+
+## OlmoModel
+
+[[autodoc]] OlmoModel
+ - forward
+
+## OlmoForCausalLM
+
+[[autodoc]] OlmoForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/olmo2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/olmo2.md
new file mode 100644
index 0000000000000000000000000000000000000000..63dbe91e3f02f2d85edd8bff86d6f880005362f0
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/olmo2.md
@@ -0,0 +1,145 @@
+
+*This model was released on 2024-12-31 and added to Hugging Face Transformers on 2024-11-25.*
+
+
+
+
+
+
+
+
+
+# OLMo2
+[OLMo2](https://huggingface.co/papers/2501.00656) improves on [OLMo](./olmo) by changing the architecture and training recipes of the original models. This includes excluding all biases to improve training stability, non-parametric layer norm, SwiGLU activation function, rotary positional embeddings, and a modified BPE-based tokenizer that masks personal identifiable information. It is pretrained on [Dolma](https://huggingface.co/datasets/allenai/dolma), a dataset of 3T tokens.
+
+You can find all the original OLMo2 checkpoints under the [OLMo2](https://huggingface.co/collections/allenai/olmo-2-674117b93ab84e98afc72edc) collection.
+
+> [!TIP]
+> Click on the OLMo2 models in the right sidebar for more examples of how to apply OLMo2 to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`], [`AutoModel`] and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipe = pipeline(
+ task="text-generation",
+ model="allenai/OLMo-2-0425-1B",
+ torch_dtype=torch.float16,
+ device=0,
+)
+
+result = pipe("Plants create energy through a process known as")
+print(result)
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "allenai/OLMo-2-0425-1B"
+)
+
+model = AutoModelForCausalLM.from_pretrained(
+ "allenai/OLMo-2-0425-1B",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+input_ids = tokenizer("Plants create energy through a process known as", return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, max_length=50, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+echo -e "Plants create energy through a process known as" | transformers-cli run --task text-generation --model allenai/OLMo-2-0425-1B --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [torchao](../quantization/torchao) to only quantize the weights to 4-bits.
+```py
+
+#pip install torchao
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, TorchAoConfig
+
+torchao_config = TorchAoConfig(
+ "int4_weight_only",
+ group_size=128
+)
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "allenai/OLMo-2-0425-1B"
+)
+
+model = AutoModelForCausalLM.from_pretrained(
+ "allenai/OLMo-2-0425-1B",
+ quantization_config=torchao_config,
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+input_ids = tokenizer("Plants create energy through a process known as", return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, max_length=50, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+
+```
+
+
+## Notes
+
+- OLMo2 uses RMSNorm instead of standard layer norm. The RMSNorm is applied to attention queries and keys, and it is applied after the attention and feedforward layers rather than before.
+- OLMo2 requires Transformers v4.48 or higher.
+- Load specific intermediate checkpoints by adding the `revision` parameter to [`~PreTrainedModel.from_pretrained`].
+
+ ```py
+ from transformers import AutoModelForCausalLM
+
+ model = AutoModelForCausalLM.from_pretrained("allenai/OLMo-2-0425-1B", revision="stage1-step140000-tokens294B")
+ ```
+
+
+## Olmo2Config
+
+[[autodoc]] Olmo2Config
+
+## Olmo2Model
+
+[[autodoc]] Olmo2Model
+ - forward
+
+## Olmo2ForCausalLM
+
+[[autodoc]] Olmo2ForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/olmoe.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/olmoe.md
new file mode 100644
index 0000000000000000000000000000000000000000..9b97525dd0e13a7dee61b1e72902f2354dcd4709
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/olmoe.md
@@ -0,0 +1,114 @@
+
+*This model was released on 2024-09-03 and added to Hugging Face Transformers on 2024-09-03.*
+
+
+
+
+
+
+
+
+
+# OLMoE
+
+[OLMoE](https://huggingface.co/papers/2409.02060) is a sparse Mixture-of-Experts (MoE) language model with 7B parameters but only 1B parameters are used per input token. It has similar inference costs as dense models but trains ~3x faster. OLMoE uses fine-grained routing with 64 small experts in each layer and uses a dropless token-based routing algorithm.
+
+You can find all the original OLMoE checkpoints under the [OLMoE](https://huggingface.co/collections/allenai/olmoe-november-2024-66cf678c047657a30c8cd3da) collection.
+
+> [!TIP]
+> This model was contributed by [Muennighoff](https://huggingface.co/Muennighoff).
+>
+> Click on the OLMoE models in the right sidebar for more examples of how to apply OLMoE to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipe = pipeline(
+ task="text-generation",
+ model="allenai/OLMoE-1B-7B-0125",
+ torch_dtype=torch.float16,
+ device=0,
+)
+
+result = pipe("Dionysus is the god of")
+print(result)
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, infer_device
+
+device = infer_device()
+
+model = AutoModelForCausalLM.from_pretrained("allenai/OLMoE-1B-7B-0924", attn_implementation="sdpa", torch_dtype="auto", device_map="auto").to(device)
+tokenizer = AutoTokenizer.from_pretrained("allenai/OLMoE-1B-7B-0924")
+
+inputs = tokenizer("Bitcoin is", return_tensors="pt")
+inputs = {k: v.to(device) for k, v in inputs.items()}
+output = model.generate(**inputs, max_length=64)
+print(tokenizer.decode(output[0]))
+```
+
+## Quantization
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to 4-bits.
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, BitsAndBytesConfig, infer_device
+
+device = infer_device()
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_compute_dtype=torch.float16,
+ bnb_4bit_use_double_quant=True,
+ bnb_4bit_quant_type="nf4"
+)
+
+model = AutoModelForCausalLM.from_pretrained("allenai/OLMoE-1B-7B-0924", attn_implementation="sdpa", torch_dtype="auto", device_map="auto", quantization_config=quantization_config).to(device)
+tokenizer = AutoTokenizer.from_pretrained("allenai/OLMoE-1B-7B-0924")
+
+inputs = tokenizer("Bitcoin is", return_tensors="pt")
+inputs = {k: v.to(device) for k, v in inputs.items()}
+output = model.generate(**inputs, max_length=64)
+print(tokenizer.decode(output[0]))
+```
+
+## OlmoeConfig
+
+[[autodoc]] OlmoeConfig
+
+## OlmoeModel
+
+[[autodoc]] OlmoeModel
+ - forward
+
+## OlmoeForCausalLM
+
+[[autodoc]] OlmoeForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/omdet-turbo.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/omdet-turbo.md
new file mode 100644
index 0000000000000000000000000000000000000000..408e1b02f6452f013a54e4f9305c90460e43c12f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/omdet-turbo.md
@@ -0,0 +1,172 @@
+
+*This model was released on 2024-03-11 and added to Hugging Face Transformers on 2024-09-25.*
+
+# OmDet-Turbo
+
+
+
+
+
+## Overview
+
+The OmDet-Turbo model was proposed in [Real-time Transformer-based Open-Vocabulary Detection with Efficient Fusion Head](https://huggingface.co/papers/2403.06892) by Tiancheng Zhao, Peng Liu, Xuan He, Lu Zhang, Kyusong Lee. OmDet-Turbo incorporates components from RT-DETR and introduces a swift multimodal fusion module to achieve real-time open-vocabulary object detection capabilities while maintaining high accuracy. The base model achieves performance of up to 100.2 FPS and 53.4 AP on COCO zero-shot.
+
+The abstract from the paper is the following:
+
+*End-to-end transformer-based detectors (DETRs) have shown exceptional performance in both closed-set and open-vocabulary object detection (OVD) tasks through the integration of language modalities. However, their demanding computational requirements have hindered their practical application in real-time object detection (OD) scenarios. In this paper, we scrutinize the limitations of two leading models in the OVDEval benchmark, OmDet and Grounding-DINO, and introduce OmDet-Turbo. This novel transformer-based real-time OVD model features an innovative Efficient Fusion Head (EFH) module designed to alleviate the bottlenecks observed in OmDet and Grounding-DINO. Notably, OmDet-Turbo-Base achieves a 100.2 frames per second (FPS) with TensorRT and language cache techniques applied. Notably, in zero-shot scenarios on COCO and LVIS datasets, OmDet-Turbo achieves performance levels nearly on par with current state-of-the-art supervised models. Furthermore, it establishes new state-of-the-art benchmarks on ODinW and OVDEval, boasting an AP of 30.1 and an NMS-AP of 26.86, respectively. The practicality of OmDet-Turbo in industrial applications is underscored by its exceptional performance on benchmark datasets and superior inference speed, positioning it as a compelling choice for real-time object detection tasks.*
+
+
+
+ OmDet-Turbo architecture overview. Taken from the original paper.
+
+This model was contributed by [yonigozlan](https://huggingface.co/yonigozlan).
+The original code can be found [here](https://github.com/om-ai-lab/OmDet).
+
+## Usage tips
+
+One unique property of OmDet-Turbo compared to other zero-shot object detection models, such as [Grounding DINO](grounding-dino), is the decoupled classes and prompt embedding structure that allows caching of text embeddings. This means that the model needs both classes and task as inputs, where classes is a list of objects we want to detect and task is the grounded text used to guide open-vocabulary detection. This approach limits the scope of the open-vocabulary detection and makes the decoding process faster.
+
+[`OmDetTurboProcessor`] is used to prepare the classes, task and image triplet. The task input is optional, and when not provided, it will default to `"Detect [class1], [class2], [class3], ..."`. To process the results from the model, one can use `post_process_grounded_object_detection` from [`OmDetTurboProcessor`]. Notably, this function takes in the input classes, as unlike other zero-shot object detection models, the decoupling of classes and task embeddings means that no decoding of the predicted class embeddings is needed in the post-processing step, and the predicted classes can be matched to the inputted ones directly.
+
+## Usage example
+
+### Single image inference
+
+Here's how to load the model and prepare the inputs to perform zero-shot object detection on a single image:
+
+```python
+>>> import torch
+>>> import requests
+>>> from PIL import Image
+
+>>> from transformers import AutoProcessor, OmDetTurboForObjectDetection
+
+>>> processor = AutoProcessor.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+>>> model = OmDetTurboForObjectDetection.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> text_labels = ["cat", "remote"]
+>>> inputs = processor(image, text=text_labels, return_tensors="pt")
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> # convert outputs (bounding boxes and class logits)
+>>> results = processor.post_process_grounded_object_detection(
+... outputs,
+... target_sizes=[(image.height, image.width)],
+... text_labels=text_labels,
+... threshold=0.3,
+... nms_threshold=0.3,
+... )
+>>> result = results[0]
+>>> boxes, scores, text_labels = result["boxes"], result["scores"], result["text_labels"]
+>>> for box, score, text_label in zip(boxes, scores, text_labels):
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"Detected {text_label} with confidence {round(score.item(), 3)} at location {box}")
+Detected remote with confidence 0.768 at location [39.89, 70.35, 176.74, 118.04]
+Detected cat with confidence 0.72 at location [11.6, 54.19, 314.8, 473.95]
+Detected remote with confidence 0.563 at location [333.38, 75.77, 370.7, 187.03]
+Detected cat with confidence 0.552 at location [345.15, 23.95, 639.75, 371.67]
+```
+
+### Multi image inference
+
+OmDet-Turbo can perform batched multi-image inference, with support for different text prompts and classes in the same batch:
+
+```python
+>>> import torch
+>>> import requests
+>>> from io import BytesIO
+>>> from PIL import Image
+>>> from transformers import AutoProcessor, OmDetTurboForObjectDetection
+
+>>> processor = AutoProcessor.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+>>> model = OmDetTurboForObjectDetection.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+
+>>> url1 = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image1 = Image.open(BytesIO(requests.get(url1).content)).convert("RGB")
+>>> text_labels1 = ["cat", "remote"]
+>>> task1 = "Detect {}.".format(", ".join(text_labels1))
+
+>>> url2 = "http://images.cocodataset.org/train2017/000000257813.jpg"
+>>> image2 = Image.open(BytesIO(requests.get(url2).content)).convert("RGB")
+>>> text_labels2 = ["boat"]
+>>> task2 = "Detect everything that looks like a boat."
+
+>>> url3 = "https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg"
+>>> image3 = Image.open(BytesIO(requests.get(url3).content)).convert("RGB")
+>>> text_labels3 = ["statue", "trees"]
+>>> task3 = "Focus on the foreground, detect statue and trees."
+
+>>> inputs = processor(
+... images=[image1, image2, image3],
+... text=[text_labels1, text_labels2, text_labels3],
+... task=[task1, task2, task3],
+... return_tensors="pt",
+... )
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> # convert outputs (bounding boxes and class logits)
+>>> results = processor.post_process_grounded_object_detection(
+... outputs,
+... text_labels=[text_labels1, text_labels2, text_labels3],
+... target_sizes=[(image.height, image.width) for image in [image1, image2, image3]],
+... threshold=0.2,
+... nms_threshold=0.3,
+... )
+
+>>> for i, result in enumerate(results):
+... for score, text_label, box in zip(
+... result["scores"], result["text_labels"], result["boxes"]
+... ):
+... box = [round(i, 1) for i in box.tolist()]
+... print(
+... f"Detected {text_label} with confidence "
+... f"{round(score.item(), 2)} at location {box} in image {i}"
+... )
+Detected remote with confidence 0.77 at location [39.9, 70.4, 176.7, 118.0] in image 0
+Detected cat with confidence 0.72 at location [11.6, 54.2, 314.8, 474.0] in image 0
+Detected remote with confidence 0.56 at location [333.4, 75.8, 370.7, 187.0] in image 0
+Detected cat with confidence 0.55 at location [345.2, 24.0, 639.8, 371.7] in image 0
+Detected boat with confidence 0.32 at location [146.9, 219.8, 209.6, 250.7] in image 1
+Detected boat with confidence 0.3 at location [319.1, 223.2, 403.2, 238.4] in image 1
+Detected boat with confidence 0.27 at location [37.7, 220.3, 84.0, 235.9] in image 1
+Detected boat with confidence 0.22 at location [407.9, 207.0, 441.7, 220.2] in image 1
+Detected statue with confidence 0.73 at location [544.7, 210.2, 651.9, 502.8] in image 2
+Detected trees with confidence 0.25 at location [3.9, 584.3, 391.4, 785.6] in image 2
+Detected trees with confidence 0.25 at location [1.4, 621.2, 118.2, 787.8] in image 2
+Detected statue with confidence 0.2 at location [428.1, 205.5, 767.3, 759.5] in image 2
+
+```
+
+## OmDetTurboConfig
+
+[[autodoc]] OmDetTurboConfig
+
+## OmDetTurboProcessor
+
+[[autodoc]] OmDetTurboProcessor
+ - post_process_grounded_object_detection
+
+## OmDetTurboForObjectDetection
+
+[[autodoc]] OmDetTurboForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/oneformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/oneformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..c4b3bd142fe04b71100dad7d978f8387e296856d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/oneformer.md
@@ -0,0 +1,97 @@
+
+*This model was released on 2022-11-10 and added to Hugging Face Transformers on 2023-01-19.*
+
+# OneFormer
+
+
+
+
+
+## Overview
+
+The OneFormer model was proposed in [OneFormer: One Transformer to Rule Universal Image Segmentation](https://huggingface.co/papers/2211.06220) by Jitesh Jain, Jiachen Li, MangTik Chiu, Ali Hassani, Nikita Orlov, Humphrey Shi. OneFormer is a universal image segmentation framework that can be trained on a single panoptic dataset to perform semantic, instance, and panoptic segmentation tasks. OneFormer uses a task token to condition the model on the task in focus, making the architecture task-guided for training, and task-dynamic for inference.
+
+
+
+The abstract from the paper is the following:
+
+*Universal Image Segmentation is not a new concept. Past attempts to unify image segmentation in the last decades include scene parsing, panoptic segmentation, and, more recently, new panoptic architectures. However, such panoptic architectures do not truly unify image segmentation because they need to be trained individually on the semantic, instance, or panoptic segmentation to achieve the best performance. Ideally, a truly universal framework should be trained only once and achieve SOTA performance across all three image segmentation tasks. To that end, we propose OneFormer, a universal image segmentation framework that unifies segmentation with a multi-task train-once design. We first propose a task-conditioned joint training strategy that enables training on ground truths of each domain (semantic, instance, and panoptic segmentation) within a single multi-task training process. Secondly, we introduce a task token to condition our model on the task at hand, making our model task-dynamic to support multi-task training and inference. Thirdly, we propose using a query-text contrastive loss during training to establish better inter-task and inter-class distinctions. Notably, our single OneFormer model outperforms specialized Mask2Former models across all three segmentation tasks on ADE20k, CityScapes, and COCO, despite the latter being trained on each of the three tasks individually with three times the resources. With new ConvNeXt and DiNAT backbones, we observe even more performance improvement. We believe OneFormer is a significant step towards making image segmentation more universal and accessible.*
+
+The figure below illustrates the architecture of OneFormer. Taken from the [original paper](https://huggingface.co/papers/2211.06220).
+
+
+
+This model was contributed by [Jitesh Jain](https://huggingface.co/praeclarumjj3). The original code can be found [here](https://github.com/SHI-Labs/OneFormer).
+
+## Usage tips
+
+- OneFormer requires two inputs during inference: *image* and *task token*.
+- During training, OneFormer only uses panoptic annotations.
+- If you want to train the model in a distributed environment across multiple nodes, then one should update the
+ `get_num_masks` function inside in the `OneFormerLoss` class of `modeling_oneformer.py`. When training on multiple nodes, this should be
+ set to the average number of target masks across all nodes, as can be seen in the original implementation [here](https://github.com/SHI-Labs/OneFormer/blob/33ebb56ed34f970a30ae103e786c0cb64c653d9a/oneformer/modeling/criterion.py#L287).
+- One can use [`OneFormerProcessor`] to prepare input images and task inputs for the model and optional targets for the model. [`OneFormerProcessor`] wraps [`OneFormerImageProcessor`] and [`CLIPTokenizer`] into a single instance to both prepare the images and encode the task inputs.
+- To get the final segmentation, depending on the task, you can call [`~OneFormerProcessor.post_process_semantic_segmentation`] or [`~OneFormerImageProcessor.post_process_instance_segmentation`] or [`~OneFormerImageProcessor.post_process_panoptic_segmentation`]. All three tasks can be solved using [`OneFormerForUniversalSegmentation`] output, panoptic segmentation accepts an optional `label_ids_to_fuse` argument to fuse instances of the target object/s (e.g. sky) together.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with OneFormer.
+
+- Demo notebooks regarding inference + fine-tuning on custom data can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/OneFormer).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we will review it.
+The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## OneFormer specific outputs
+
+[[autodoc]] models.oneformer.modeling_oneformer.OneFormerModelOutput
+
+[[autodoc]] models.oneformer.modeling_oneformer.OneFormerForUniversalSegmentationOutput
+
+## OneFormerConfig
+
+[[autodoc]] OneFormerConfig
+
+## OneFormerImageProcessor
+
+[[autodoc]] OneFormerImageProcessor
+ - preprocess
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## OneFormerImageProcessorFast
+
+[[autodoc]] OneFormerImageProcessorFast
+ - preprocess
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## OneFormerProcessor
+
+[[autodoc]] OneFormerProcessor
+
+## OneFormerModel
+
+[[autodoc]] OneFormerModel
+ - forward
+
+## OneFormerForUniversalSegmentation
+
+[[autodoc]] OneFormerForUniversalSegmentation
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/open-llama.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/open-llama.md
new file mode 100644
index 0000000000000000000000000000000000000000..38954cd315d0c76fc4d1edd6d4080580eb25e8ba
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/open-llama.md
@@ -0,0 +1,66 @@
+
+*This model was released on 2023-04-16 and added to Hugging Face Transformers on 2023-06-20.*
+
+# Open-Llama
+
+
+
+
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.31.0.
+You can do so by running the following command: `pip install -U transformers==4.31.0`.
+
+
+
+
+
+This model differs from the [OpenLLaMA models](https://huggingface.co/models?search=openllama) on the Hugging Face Hub, which primarily use the [LLaMA](llama) architecture.
+
+
+
+## Overview
+
+The Open-Llama model was proposed in the open source Open-Llama project by community developer s-JoL.
+
+The model is mainly based on LLaMA with some modifications, incorporating memory-efficient attention from Xformers, stable embedding from Bloom, and shared input-output embedding from PaLM.
+And the model is pre-trained on both Chinese and English, which gives it better performance on Chinese language tasks.
+
+This model was contributed by [s-JoL](https://huggingface.co/s-JoL).
+The original code was released on GitHub by [s-JoL](https://github.com/s-JoL), but is now removed.
+
+## OpenLlamaConfig
+
+[[autodoc]] OpenLlamaConfig
+
+## OpenLlamaModel
+
+[[autodoc]] OpenLlamaModel
+ - forward
+
+## OpenLlamaForCausalLM
+
+[[autodoc]] OpenLlamaForCausalLM
+ - forward
+
+## OpenLlamaForSequenceClassification
+
+[[autodoc]] OpenLlamaForSequenceClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/openai-gpt.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/openai-gpt.md
new file mode 100644
index 0000000000000000000000000000000000000000..29957b5319ab0897f02e5827cfcbd20f222e423e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/openai-gpt.md
@@ -0,0 +1,137 @@
+
+*This model was released on 2018-06-11 and added to Hugging Face Transformers on 2023-06-20.*
+
+
+
+
+
+
+
+
+
+
+
+
+
+
+# GPT
+
+[GPT (Generative Pre-trained Transformer)](https://cdn.openai.com/research-covers/language-unsupervised/language_understanding_paper.pdf) ([blog post](https://openai.com/index/language-unsupervised/)) focuses on effectively learning text representations and transferring them to tasks. This model trains the Transformer decoder to predict the next word, and then fine-tuned on labeled data.
+
+GPT can generate high-quality text, making it well-suited for a variety of natural language understanding tasks such as textual entailment, question answering, semantic similarity, and document classification.
+
+You can find all the original GPT checkpoints under the [OpenAI community](https://huggingface.co/openai-community/openai-gpt) organization.
+
+> [!TIP]
+> Click on the GPT models in the right sidebar for more examples of how to apply GPT to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+
+
+
+```python
+import torch
+from transformers import pipeline
+
+generator = pipeline(task="text-generation", model="openai-community/gpt", torch_dtype=torch.float16, device=0)
+output = generator("The future of AI is", max_length=50, do_sample=True)
+print(output[0]["generated_text"])
+```
+
+
+
+
+```python
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt")
+model = AutoModelForCausalLM.from_pretrained("openai-community/openai-gpt", torch_dtype=torch.float16)
+
+inputs = tokenizer("The future of AI is", return_tensors="pt")
+outputs = model.generate(**inputs, max_length=50)
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+echo -e "The future of AI is" | transformers run --task text-generation --model openai-community/openai-gpt --device 0
+
+```
+
+
+
+## Notes
+
+- Inputs should be padded on the right because GPT uses absolute position embeddings.
+
+## OpenAIGPTConfig
+
+[[autodoc]] OpenAIGPTConfig
+
+## OpenAIGPTModel
+
+[[autodoc]] OpenAIGPTModel
+- forward
+
+## OpenAIGPTLMHeadModel
+
+[[autodoc]] OpenAIGPTLMHeadModel
+- forward
+
+## OpenAIGPTDoubleHeadsModel
+
+[[autodoc]] OpenAIGPTDoubleHeadsModel
+- forward
+
+## OpenAIGPTForSequenceClassification
+
+[[autodoc]] OpenAIGPTForSequenceClassification
+- forward
+
+## OpenAIGPTTokenizer
+
+[[autodoc]] OpenAIGPTTokenizer
+
+## OpenAIGPTTokenizerFast
+
+[[autodoc]] OpenAIGPTTokenizerFast
+
+## TFOpenAIGPTModel
+
+[[autodoc]] TFOpenAIGPTModel
+- call
+
+## TFOpenAIGPTLMHeadModel
+
+[[autodoc]] TFOpenAIGPTLMHeadModel
+- call
+
+## TFOpenAIGPTDoubleHeadsModel
+
+[[autodoc]] TFOpenAIGPTDoubleHeadsModel
+- call
+
+## TFOpenAIGPTForSequenceClassification
+
+[[autodoc]] TFOpenAIGPTForSequenceClassification
+- call
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/opt.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/opt.md
new file mode 100644
index 0000000000000000000000000000000000000000..d11f9cb3b41d5e2e1acf489cb997236b0d5d5d9e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/opt.md
@@ -0,0 +1,171 @@
+
+*This model was released on 2022-05-02 and added to Hugging Face Transformers on 2022-05-12.*
+
+
+
+
+
+
+
+
+
+
+
+# OPT
+
+[OPT](https://huggingface.co/papers/2205.01068) is a suite of open-source decoder-only pre-trained transformers whose parameters range from 125M to 175B. OPT models are designed for casual language modeling and aim to enable responsible and reproducible research at scale. OPT-175B is comparable in performance to GPT-3 with only 1/7th the carbon footprint.
+
+You can find all the original OPT checkpoints under the [OPT](https://huggingface.co/collections/facebook/opt-66ed00e15599f02966818844) collection.
+
+> [!TIP]
+> This model was contributed by [ArthurZ](https://huggingface.co/ArthurZ), [ybelkada](https://huggingface.co/ybelkada), and [patrickvonplaten](https://huggingface.co/patrickvonplaten).
+>
+> Click on the OPT models in the right sidebar for more examples of how to apply OPT to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(task="text-generation", model="facebook/opt-125m", torch_dtype=torch.float16, device=0)
+pipeline("Once upon a time, in a land far, far away,", max_length=50, num_return_sequences=1)
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+device = "cuda"
+
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-350m", torch_dtype=torch.float16, attn_implementation="sdpa")
+tokenizer = AutoTokenizer.from_pretrained("facebook/opt-350m")
+
+prompt = ("Once upon a time, in a land far, far away, ")
+
+model_inputs = tokenizer([prompt], return_tensors="pt").to(device)
+model.to(device)
+
+generated_ids = model.generate(**model_inputs, max_new_tokens=30, do_sample=False)
+tokenizer.batch_decode(generated_ids)[0]
+```
+
+
+
+```py
+echo -e "Plants create energy through a process known as" | transformers run --task text-generation --model facebook/opt-125m --device 0
+```
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](..quantization/bitsandbytes) to quantize the weights to 8-bits.
+
+```py
+import torch
+from transformers import BitsAndBytesConfig, AutoTokenizer, AutoModelForCausalLM
+
+device = "cuda"
+
+bnb_config = BitsAndBytesConfig(load_in_8bit=True)
+model = AutoModelForCausalLM.from_pretrained("facebook/opt-13b", torch_dtype=torch.float16, attn_implementation="sdpa", quantization_config=bnb_config)
+tokenizer = AutoTokenizer.from_pretrained("facebook/opt-13b")
+
+prompt = ("Once upon a time, in a land far, far away, ")
+
+model_inputs = tokenizer([prompt], return_tensors="pt").to(device)
+model.to(device)
+
+generated_ids = model.generate(**model_inputs, max_new_tokens=30, do_sample=False)
+tokenizer.batch_decode(generated_ids)[0]
+```
+
+## Notes
+
+- OPT adds an `EOS` token `` to the beginning of every prompt.
+
+- The `head_mask` argument is ignored if the attention implementation isn't `"eager"`. Set `attn_implementation="eager"` to enable the `head_mask`.
+
+## Resources
+
+- Refer to this [notebook](https://colab.research.google.com/drive/1jCkpikz0J2o20FBQmYmAGdiKmJGOMo-o?usp=sharing) for an example of fine-tuning OPT with PEFT, bitsandbytes, and Transformers.
+- The [How 🤗 Accelerate runs very large models thanks to PyTorch](https://huggingface.co/blog/accelerate-large-models) blog post demonstrates how to run OPT for inference.
+
+## OPTConfig
+
+[[autodoc]] OPTConfig
+
+
+
+
+## OPTModel
+
+[[autodoc]] OPTModel
+ - forward
+
+## OPTForCausalLM
+
+[[autodoc]] OPTForCausalLM
+ - forward
+
+## OPTForSequenceClassification
+
+[[autodoc]] OPTForSequenceClassification
+ - forward
+
+## OPTForQuestionAnswering
+
+[[autodoc]] OPTForQuestionAnswering
+ - forward
+
+
+
+
+## TFOPTModel
+
+[[autodoc]] TFOPTModel
+ - call
+
+## TFOPTForCausalLM
+
+[[autodoc]] TFOPTForCausalLM
+ - call
+
+
+
+
+## FlaxOPTModel
+
+[[autodoc]] FlaxOPTModel
+ - __call__
+
+## FlaxOPTForCausalLM
+
+[[autodoc]] FlaxOPTForCausalLM
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ovis2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ovis2.md
new file mode 100644
index 0000000000000000000000000000000000000000..d1fa44f150075fdb376d1423afc6de699ddca315
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ovis2.md
@@ -0,0 +1,107 @@
+
+
+# Ovis2
+
+## Overview
+
+The [Ovis2](https://github.com/AIDC-AI/Ovis) is an updated version of the [Ovis](https://arxiv.org/abs/2405.20797) model developed by the AIDC-AI team at Alibaba International Digital Commerce Group.
+
+Ovis2 is the latest advancement in multi-modal large language models (MLLMs), succeeding Ovis1.6. It retains the architectural design of the Ovis series, which focuses on aligning visual and textual embeddings, and introduces major improvements in data curation and training methods.
+
+
+
+ Ovis2 architecture.
+
+This model was contributed by [thisisiron](https://huggingface.co/thisisiron).
+
+## Usage example
+
+```python
+
+from PIL import Image
+import requests
+import torch
+from torchvision import io
+from typing import Dict
+from transformers.image_utils import load_images, load_video
+from transformers import AutoModelForVision2Seq, AutoTokenizer, AutoProcessor, infer_device
+
+device = f"{infer_device()}:0"
+
+model = AutoModelForVision2Seq.from_pretrained(
+ "thisisiron/Ovis2-2B-hf",
+ torch_dtype=torch.bfloat16,
+).eval().to(device)
+processor = AutoProcessor.from_pretrained("thisisiron/Ovis2-2B-hf")
+
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "Describe the image."},
+ ],
+ },
+]
+url = "http://images.cocodataset.org/val2014/COCO_val2014_000000537955.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+messages = processor.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
+print(messages)
+
+inputs = processor(
+ images=[image],
+ text=messages,
+ return_tensors="pt",
+)
+inputs = inputs.to(model.device)
+inputs['pixel_values'] = inputs['pixel_values'].to(torch.bfloat16)
+
+with torch.inference_mode():
+ output_ids = model.generate(**inputs, max_new_tokens=128, do_sample=False)
+ generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(inputs.input_ids, output_ids)]
+ output_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+ print(output_text)
+```
+
+## Ovis2Config
+
+[[autodoc]] Ovis2Config
+
+## Ovis2VisionConfig
+
+[[autodoc]] Ovis2VisionConfig
+
+## Ovis2Model
+
+[[autodoc]] Ovis2Model
+
+## Ovis2ForConditionalGeneration
+
+[[autodoc]] Ovis2ForConditionalGeneration
+ - forward
+
+## Ovis2ImageProcessor
+
+[[autodoc]] Ovis2ImageProcessor
+
+## Ovis2ImageProcessorFast
+
+[[autodoc]] Ovis2ImageProcessorFast
+
+## Ovis2Processor
+
+[[autodoc]] Ovis2Processor
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/owlv2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/owlv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..675dc1c9c0d5014e5d1c7ee295bf057d79d3dd28
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/owlv2.md
@@ -0,0 +1,145 @@
+
+*This model was released on 2023-06-16 and added to Hugging Face Transformers on 2023-10-13.*
+
+# OWLv2
+
+
+
+
+
+## Overview
+
+OWLv2 was proposed in [Scaling Open-Vocabulary Object Detection](https://huggingface.co/papers/2306.09683) by Matthias Minderer, Alexey Gritsenko, Neil Houlsby. OWLv2 scales up [OWL-ViT](owlvit) using self-training, which uses an existing detector to generate pseudo-box annotations on image-text pairs. This results in large gains over the previous state-of-the-art for zero-shot object detection.
+
+The abstract from the paper is the following:
+
+*Open-vocabulary object detection has benefited greatly from pretrained vision-language models, but is still limited by the amount of available detection training data. While detection training data can be expanded by using Web image-text pairs as weak supervision, this has not been done at scales comparable to image-level pretraining. Here, we scale up detection data with self-training, which uses an existing detector to generate pseudo-box annotations on image-text pairs. Major challenges in scaling self-training are the choice of label space, pseudo-annotation filtering, and training efficiency. We present the OWLv2 model and OWL-ST self-training recipe, which address these challenges. OWLv2 surpasses the performance of previous state-of-the-art open-vocabulary detectors already at comparable training scales (~10M examples). However, with OWL-ST, we can scale to over 1B examples, yielding further large improvement: With an L/14 architecture, OWL-ST improves AP on LVIS rare classes, for which the model has seen no human box annotations, from 31.2% to 44.6% (43% relative improvement). OWL-ST unlocks Web-scale training for open-world localization, similar to what has been seen for image classification and language modelling.*
+
+
+
+ OWLv2 high-level overview. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/google-research/scenic/tree/main/scenic/projects/owl_vit).
+
+## Usage example
+
+OWLv2 is, just like its predecessor [OWL-ViT](owlvit), a zero-shot text-conditioned object detection model. OWL-ViT uses [CLIP](clip) as its multi-modal backbone, with a ViT-like Transformer to get visual features and a causal language model to get the text features. To use CLIP for detection, OWL-ViT removes the final token pooling layer of the vision model and attaches a lightweight classification and box head to each transformer output token. Open-vocabulary classification is enabled by replacing the fixed classification layer weights with the class-name embeddings obtained from the text model. The authors first train CLIP from scratch and fine-tune it end-to-end with the classification and box heads on standard detection datasets using a bipartite matching loss. One or multiple text queries per image can be used to perform zero-shot text-conditioned object detection.
+
+[`Owlv2ImageProcessor`] can be used to resize (or rescale) and normalize images for the model and [`CLIPTokenizer`] is used to encode the text. [`Owlv2Processor`] wraps [`Owlv2ImageProcessor`] and [`CLIPTokenizer`] into a single instance to both encode the text and prepare the images. The following example shows how to perform object detection using [`Owlv2Processor`] and [`Owlv2ForObjectDetection`].
+
+```python
+>>> import requests
+>>> from PIL import Image
+>>> import torch
+
+>>> from transformers import Owlv2Processor, Owlv2ForObjectDetection
+
+>>> processor = Owlv2Processor.from_pretrained("google/owlv2-base-patch16-ensemble")
+>>> model = Owlv2ForObjectDetection.from_pretrained("google/owlv2-base-patch16-ensemble")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> text_labels = [["a photo of a cat", "a photo of a dog"]]
+>>> inputs = processor(text=text_labels, images=image, return_tensors="pt")
+>>> outputs = model(**inputs)
+
+>>> # Target image sizes (height, width) to rescale box predictions [batch_size, 2]
+>>> target_sizes = torch.tensor([(image.height, image.width)])
+>>> # Convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax)
+>>> results = processor.post_process_grounded_object_detection(
+... outputs=outputs, target_sizes=target_sizes, threshold=0.1, text_labels=text_labels
+... )
+>>> # Retrieve predictions for the first image for the corresponding text queries
+>>> result = results[0]
+>>> boxes, scores, text_labels = result["boxes"], result["scores"], result["text_labels"]
+>>> for box, score, text_label in zip(boxes, scores, text_labels):
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"Detected {text_label} with confidence {round(score.item(), 3)} at location {box}")
+Detected a photo of a cat with confidence 0.614 at location [341.67, 23.39, 642.32, 371.35]
+Detected a photo of a cat with confidence 0.665 at location [6.75, 51.96, 326.62, 473.13]
+```
+
+## Resources
+
+- A demo notebook on using OWLv2 for zero- and one-shot (image-guided) object detection can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/OWLv2).
+- [Zero-shot object detection task guide](../tasks/zero_shot_object_detection)
+
+
+
+The architecture of OWLv2 is identical to [OWL-ViT](owlvit), however the object detection head now also includes an objectness classifier, which predicts the (query-agnostic) likelihood that a predicted box contains an object (as opposed to background). The objectness score can be used to rank or filter predictions independently of text queries.
+Usage of OWLv2 is identical to [OWL-ViT](owlvit) with a new, updated image processor ([`Owlv2ImageProcessor`]).
+
+
+
+## Owlv2Config
+
+[[autodoc]] Owlv2Config
+ - from_text_vision_configs
+
+## Owlv2TextConfig
+
+[[autodoc]] Owlv2TextConfig
+
+## Owlv2VisionConfig
+
+[[autodoc]] Owlv2VisionConfig
+
+## Owlv2ImageProcessor
+
+[[autodoc]] Owlv2ImageProcessor
+ - preprocess
+ - post_process_object_detection
+ - post_process_image_guided_detection
+
+## Owlv2ImageProcessorFast
+
+[[autodoc]] Owlv2ImageProcessorFast
+ - preprocess
+ - post_process_object_detection
+ - post_process_image_guided_detection
+
+## Owlv2Processor
+
+[[autodoc]] Owlv2Processor
+ - __call__
+ - post_process_grounded_object_detection
+ - post_process_image_guided_detection
+
+## Owlv2Model
+
+[[autodoc]] Owlv2Model
+ - forward
+ - get_text_features
+ - get_image_features
+
+## Owlv2TextModel
+
+[[autodoc]] Owlv2TextModel
+ - forward
+
+## Owlv2VisionModel
+
+[[autodoc]] Owlv2VisionModel
+ - forward
+
+## Owlv2ForObjectDetection
+
+[[autodoc]] Owlv2ForObjectDetection
+ - forward
+ - image_guided_detection
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/owlvit.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/owlvit.md
new file mode 100644
index 0000000000000000000000000000000000000000..ceae23b4cf9f1a139b4061d76a0c1c45a697486d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/owlvit.md
@@ -0,0 +1,134 @@
+
+*This model was released on 2022-05-12 and added to Hugging Face Transformers on 2022-07-22.*
+
+# OWL-ViT
+
+
+
+
+
+## Overview
+
+The OWL-ViT (short for Vision Transformer for Open-World Localization) was proposed in [Simple Open-Vocabulary Object Detection with Vision Transformers](https://huggingface.co/papers/2205.06230) by Matthias Minderer, Alexey Gritsenko, Austin Stone, Maxim Neumann, Dirk Weissenborn, Alexey Dosovitskiy, Aravindh Mahendran, Anurag Arnab, Mostafa Dehghani, Zhuoran Shen, Xiao Wang, Xiaohua Zhai, Thomas Kipf, and Neil Houlsby. OWL-ViT is an open-vocabulary object detection network trained on a variety of (image, text) pairs. It can be used to query an image with one or multiple text queries to search for and detect target objects described in text.
+
+The abstract from the paper is the following:
+
+*Combining simple architectures with large-scale pre-training has led to massive improvements in image classification. For object detection, pre-training and scaling approaches are less well established, especially in the long-tailed and open-vocabulary setting, where training data is relatively scarce. In this paper, we propose a strong recipe for transferring image-text models to open-vocabulary object detection. We use a standard Vision Transformer architecture with minimal modifications, contrastive image-text pre-training, and end-to-end detection fine-tuning. Our analysis of the scaling properties of this setup shows that increasing image-level pre-training and model size yield consistent improvements on the downstream detection task. We provide the adaptation strategies and regularizations needed to attain very strong performance on zero-shot text-conditioned and one-shot image-conditioned object detection. Code and models are available on GitHub.*
+
+
+
+ OWL-ViT architecture. Taken from the original paper.
+
+This model was contributed by [adirik](https://huggingface.co/adirik). The original code can be found [here](https://github.com/google-research/scenic/tree/main/scenic/projects/owl_vit).
+
+## Usage tips
+
+OWL-ViT is a zero-shot text-conditioned object detection model. OWL-ViT uses [CLIP](clip) as its multi-modal backbone, with a ViT-like Transformer to get visual features and a causal language model to get the text features. To use CLIP for detection, OWL-ViT removes the final token pooling layer of the vision model and attaches a lightweight classification and box head to each transformer output token. Open-vocabulary classification is enabled by replacing the fixed classification layer weights with the class-name embeddings obtained from the text model. The authors first train CLIP from scratch and fine-tune it end-to-end with the classification and box heads on standard detection datasets using a bipartite matching loss. One or multiple text queries per image can be used to perform zero-shot text-conditioned object detection.
+
+[`OwlViTImageProcessor`] can be used to resize (or rescale) and normalize images for the model and [`CLIPTokenizer`] is used to encode the text. [`OwlViTProcessor`] wraps [`OwlViTImageProcessor`] and [`CLIPTokenizer`] into a single instance to both encode the text and prepare the images. The following example shows how to perform object detection using [`OwlViTProcessor`] and [`OwlViTForObjectDetection`].
+
+```python
+>>> import requests
+>>> from PIL import Image
+>>> import torch
+
+>>> from transformers import OwlViTProcessor, OwlViTForObjectDetection
+
+>>> processor = OwlViTProcessor.from_pretrained("google/owlvit-base-patch32")
+>>> model = OwlViTForObjectDetection.from_pretrained("google/owlvit-base-patch32")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> text_labels = [["a photo of a cat", "a photo of a dog"]]
+>>> inputs = processor(text=text_labels, images=image, return_tensors="pt")
+>>> outputs = model(**inputs)
+
+>>> # Target image sizes (height, width) to rescale box predictions [batch_size, 2]
+>>> target_sizes = torch.tensor([(image.height, image.width)])
+>>> # Convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax)
+>>> results = processor.post_process_grounded_object_detection(
+... outputs=outputs, target_sizes=target_sizes, threshold=0.1, text_labels=text_labels
+... )
+>>> # Retrieve predictions for the first image for the corresponding text queries
+>>> result = results[0]
+>>> boxes, scores, text_labels = result["boxes"], result["scores"], result["text_labels"]
+>>> for box, score, text_label in zip(boxes, scores, text_labels):
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"Detected {text_label} with confidence {round(score.item(), 3)} at location {box}")
+Detected a photo of a cat with confidence 0.707 at location [324.97, 20.44, 640.58, 373.29]
+Detected a photo of a cat with confidence 0.717 at location [1.46, 55.26, 315.55, 472.17]
+```
+
+## Resources
+
+A demo notebook on using OWL-ViT for zero- and one-shot (image-guided) object detection can be found [here](https://github.com/huggingface/notebooks/blob/main/examples/zeroshot_object_detection_with_owlvit.ipynb).
+
+## OwlViTConfig
+
+[[autodoc]] OwlViTConfig
+ - from_text_vision_configs
+
+## OwlViTTextConfig
+
+[[autodoc]] OwlViTTextConfig
+
+## OwlViTVisionConfig
+
+[[autodoc]] OwlViTVisionConfig
+
+## OwlViTImageProcessor
+
+[[autodoc]] OwlViTImageProcessor
+ - preprocess
+
+## OwlViTImageProcessorFast
+
+[[autodoc]] OwlViTImageProcessorFast
+ - preprocess
+ - post_process_object_detection
+ - post_process_image_guided_detection
+
+## OwlViTProcessor
+
+[[autodoc]] OwlViTProcessor
+ - __call__
+ - post_process_grounded_object_detection
+ - post_process_image_guided_detection
+
+## OwlViTModel
+
+[[autodoc]] OwlViTModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## OwlViTTextModel
+
+[[autodoc]] OwlViTTextModel
+ - forward
+
+## OwlViTVisionModel
+
+[[autodoc]] OwlViTVisionModel
+ - forward
+
+## OwlViTForObjectDetection
+
+[[autodoc]] OwlViTForObjectDetection
+ - forward
+ - image_guided_detection
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/paligemma.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/paligemma.md
new file mode 100644
index 0000000000000000000000000000000000000000..2ff64076d53a0f1fc199a2d678888f8548398e59
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/paligemma.md
@@ -0,0 +1,185 @@
+
+*This model was released on 2024-07-10 and added to Hugging Face Transformers on 2024-05-14.*
+
+
+
+
+
+
+
+
+
+# PaliGemma
+
+[PaliGemma](https://huggingface.co/papers/2407.07726) is a family of vision-language models (VLMs), combining [SigLIP](./siglip) with the [Gemma](./gemma) 2B model. PaliGemma is available in 3B, 10B, and 28B parameters. The main purpose of PaliGemma is to provide an adaptable base VLM that is easy to transfer to other tasks. The SigLIP vision encoder is a "shape optimized" contrastively pretrained [ViT](./vit) that converts an image into a sequence of tokens and prepended to an optional prompt. The Gemma 2B model is used as the decoder. PaliGemma uses full attention on all image and text tokens to maximize its capacity.
+
+[PaliGemma 2](https://huggingface.co/papers/2412.03555) improves on the first model by using Gemma 2 (2B, 9B, and 27B parameter variants) as the decoder. These are available as **pt** or **mix** variants. The **pt** checkpoints are intended for further fine-tuning and the **mix** checkpoints are ready for use out of the box.
+
+You can find all the original PaliGemma checkpoints under the [PaliGemma](https://huggingface.co/collections/google/paligemma-release-6643a9ffbf57de2ae0448dda), [PaliGemma 2](https://huggingface.co/collections/google/paligemma-2-release-67500e1e1dbfdd4dee27ba48), and [PaliGemma 2 Mix](https://huggingface.co/collections/google/paligemma-2-mix-67ac6a251aaf3ee73679dcc4) collections.
+
+> [!TIP]
+> Click on the PaliGemma models in the right sidebar for more examples of how to apply PaliGemma to different vision and language tasks.
+
+The example below demonstrates how to generate text based on an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="image-text-to-text",
+ model="google/paligemma2-3b-mix-224",
+ device=0,
+ torch_dtype=torch.bfloat16
+)
+pipeline(
+ "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg",
+ text="What is in this image?"
+)
+```
+
+
+
+
+```py
+import torch
+import requests
+from PIL import Image
+from transformers import AutoProcessor, PaliGemmaForConditionalGeneration
+
+model = PaliGemmaForConditionalGeneration.from_pretrained(
+ "google/paligemma2-3b-mix-224",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+processor = AutoProcessor.from_pretrained(
+ "google/paligemma2-3b-mix-224",
+)
+
+prompt = "What is in this image?"
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+image = Image.open(requests.get(url, stream=True).raw)
+inputs = processor(image, prompt, return_tensors="pt").to(model.device)
+
+output = model.generate(**inputs, max_new_tokens=50, cache_implementation="static")
+print(processor.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [torchao](../quantization/torchao) to only quantize the weights to int4.
+
+```py
+# pip install torchao
+import torch
+import requests
+from PIL import Image
+from transformers import TorchAoConfig, AutoProcessor, PaliGemmaForConditionalGeneration
+
+quantization_config = TorchAoConfig("int4_weight_only", group_size=128)
+model = PaliGemmaForConditionalGeneration.from_pretrained(
+ "google/paligemma2-28b-mix-224",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+processor = AutoProcessor.from_pretrained(
+ "google/paligemma2-28b-mix-224",
+)
+
+prompt = "What is in this image?"
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+image = Image.open(requests.get(url, stream=True).raw)
+inputs = processor(image, prompt, return_tensors="pt").to(model.device)
+
+output = model.generate(**inputs, max_new_tokens=50, cache_implementation="static")
+print(processor.decode(output[0], skip_special_tokens=True))
+```
+
+Use the [AttentionMaskVisualizer](https://github.com/huggingface/transformers/blob/beb9b5b02246b9b7ee81ddf938f93f44cfeaad19/src/transformers/utils/attention_visualizer.py#L139) to better understand what tokens the model can and cannot attend to.
+
+```py
+from transformers.utils.attention_visualizer import AttentionMaskVisualizer
+
+visualizer = AttentionMaskVisualizer("google/paligemma2-3b-mix-224")
+visualizer(" What is in this image?")
+```
+
+
+
+
+
+## Notes
+
+- PaliGemma is not a conversational model and works best when fine-tuned for specific downstream tasks such as image captioning, visual question answering (VQA), object detection, and document understanding.
+- [`PaliGemmaProcessor`] can prepare images, text, and optional labels for the model. Pass the `suffix` parameter to the processor to create labels for the model during fine-tuning.
+
+ ```py
+ prompt = "What is in this image?"
+ answer = "a pallas cat"
+ inputs = processor(images=image, text=prompt, suffix=answer, return_tensors="pt")
+ ```
+- PaliGemma can support multiple input images if it is fine-tuned to accept multiple images. For example, the [NLVR2](https://huggingface.co/google/paligemma-3b-ft-nlvr2-448) checkpoint supports multiple images. Pass the images as a list to the processor.
+
+ ```py
+ import torch
+ import requests
+ from PIL import Image
+ from transformers import TorchAoConfig, AutoProcessor, PaliGemmaForConditionalGeneration
+
+ model = PaliGemmaForConditionalGeneration.from_pretrained("google/paligemma-3b-ft-nlvr2-448")
+ processor = AutoProcessor.from_pretrained("google/paligemma-3b-ft-nlvr2-448")
+
+ prompt = "Are these two images the same?"
+ cat_image = Image.open(
+ requests.get("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg", stream=True).raw
+ )
+ cow_image = Image.open(
+ requests.get(
+ "https://media.istockphoto.com/id/1192867753/photo/cow-in-berchida-beach-siniscola.jpg?s=612x612&w=0&k=20&c=v0hjjniwsMNfJSuKWZuIn8pssmD5h5bSN1peBd1CmH4=", stream=True
+ ).raw
+ )
+
+ inputs = processor(images=[[cat_image, cow_image]], text=prompt, return_tensors="pt")
+
+ output = model.generate(**inputs, max_new_tokens=20, cache_implementation="static")
+ print(processor.decode(output[0], skip_special_tokens=True))
+ ```
+
+## PaliGemmaConfig
+
+[[autodoc]] PaliGemmaConfig
+
+## PaliGemmaProcessor
+
+[[autodoc]] PaliGemmaProcessor
+
+## PaliGemmaModel
+
+[[autodoc]] PaliGemmaModel
+
+## PaliGemmaForConditionalGeneration
+
+[[autodoc]] PaliGemmaForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/patchtsmixer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/patchtsmixer.md
new file mode 100644
index 0000000000000000000000000000000000000000..5541f4d80936d6b53f8fbc3645ddd4ad76f0b78f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/patchtsmixer.md
@@ -0,0 +1,99 @@
+
+*This model was released on 2023-06-14 and added to Hugging Face Transformers on 2023-12-05.*
+
+# PatchTSMixer
+
+
+
+
+
+## Overview
+
+The PatchTSMixer model was proposed in [TSMixer: Lightweight MLP-Mixer Model for Multivariate Time Series Forecasting](https://huggingface.co/papers/2306.09364) by Vijay Ekambaram, Arindam Jati, Nam Nguyen, Phanwadee Sinthong and Jayant Kalagnanam.
+
+
+PatchTSMixer is a lightweight time-series modeling approach based on the MLP-Mixer architecture. In this HuggingFace implementation, we provide PatchTSMixer's capabilities to effortlessly facilitate lightweight mixing across patches, channels, and hidden features for effective multivariate time-series modeling. It also supports various attention mechanisms starting from simple gated attention to more complex self-attention blocks that can be customized accordingly. The model can be pretrained and subsequently used for various downstream tasks such as forecasting, classification and regression.
+
+
+The abstract from the paper is the following:
+
+*TSMixer is a lightweight neural architecture exclusively composed of multi-layer perceptron (MLP) modules designed for multivariate forecasting and representation learning on patched time series. Our model draws inspiration from the success of MLP-Mixer models in computer vision. We demonstrate the challenges involved in adapting Vision MLP-Mixer for time series and introduce empirically validated components to enhance accuracy. This includes a novel design paradigm of attaching online reconciliation heads to the MLP-Mixer backbone, for explicitly modeling the time-series properties such as hierarchy and channel-correlations. We also propose a Hybrid channel modeling approach to effectively handle noisy channel interactions and generalization across diverse datasets, a common challenge in existing patch channel-mixing methods. Additionally, a simple gated attention mechanism is introduced in the backbone to prioritize important features. By incorporating these lightweight components, we significantly enhance the learning capability of simple MLP structures, outperforming complex Transformer models with minimal computing usage. Moreover, TSMixer's modular design enables compatibility with both supervised and masked self-supervised learning methods, making it a promising building block for time-series Foundation Models. TSMixer outperforms state-of-the-art MLP and Transformer models in forecasting by a considerable margin of 8-60%. It also outperforms the latest strong benchmarks of Patch-Transformer models (by 1-2%) with a significant reduction in memory and runtime (2-3X).*
+
+This model was contributed by [ajati](https://huggingface.co/ajati), [vijaye12](https://huggingface.co/vijaye12),
+[gsinthong](https://huggingface.co/gsinthong), [namctin](https://huggingface.co/namctin),
+[wmgifford](https://huggingface.co/wmgifford), [kashif](https://huggingface.co/kashif).
+
+## Usage example
+
+The code snippet below shows how to randomly initialize a PatchTSMixer model. The model is compatible with the [Trainer API](../trainer).
+
+```python
+
+from transformers import PatchTSMixerConfig, PatchTSMixerForPrediction
+from transformers import Trainer, TrainingArguments,
+
+
+config = PatchTSMixerConfig(context_length = 512, prediction_length = 96)
+model = PatchTSMixerForPrediction(config)
+trainer = Trainer(model=model, args=training_args,
+ train_dataset=train_dataset,
+ eval_dataset=valid_dataset)
+trainer.train()
+results = trainer.evaluate(test_dataset)
+```
+
+## Usage tips
+
+The model can also be used for time series classification and time series regression. See the respective [`PatchTSMixerForTimeSeriesClassification`] and [`PatchTSMixerForRegression`] classes.
+
+## Resources
+
+- A blog post explaining PatchTSMixer in depth can be found [here](https://huggingface.co/blog/patchtsmixer). The blog can also be opened in Google Colab.
+
+## PatchTSMixerConfig
+
+[[autodoc]] PatchTSMixerConfig
+
+
+## PatchTSMixerModel
+
+[[autodoc]] PatchTSMixerModel
+ - forward
+
+
+## PatchTSMixerForPrediction
+
+[[autodoc]] PatchTSMixerForPrediction
+ - forward
+
+
+## PatchTSMixerForTimeSeriesClassification
+
+[[autodoc]] PatchTSMixerForTimeSeriesClassification
+ - forward
+
+
+## PatchTSMixerForPretraining
+
+[[autodoc]] PatchTSMixerForPretraining
+ - forward
+
+
+## PatchTSMixerForRegression
+
+[[autodoc]] PatchTSMixerForRegression
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/patchtst.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/patchtst.md
new file mode 100644
index 0000000000000000000000000000000000000000..504da22f108bc8efe71f28e34b3aee8f00a260e8
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/patchtst.md
@@ -0,0 +1,73 @@
+
+*This model was released on 2022-11-27 and added to Hugging Face Transformers on 2023-11-13.*
+
+# PatchTST
+
+
+
+
+
+## Overview
+
+The PatchTST model was proposed in [A Time Series is Worth 64 Words: Long-term Forecasting with Transformers](https://huggingface.co/papers/2211.14730) by Yuqi Nie, Nam H. Nguyen, Phanwadee Sinthong and Jayant Kalagnanam.
+
+At a high level the model vectorizes time series into patches of a given size and encodes the resulting sequence of vectors via a Transformer that then outputs the prediction length forecast via an appropriate head. The model is illustrated in the following figure:
+
+
+
+The abstract from the paper is the following:
+
+*We propose an efficient design of Transformer-based models for multivariate time series forecasting and self-supervised representation learning. It is based on two key components: (i) segmentation of time series into subseries-level patches which are served as input tokens to Transformer; (ii) channel-independence where each channel contains a single univariate time series that shares the same embedding and Transformer weights across all the series. Patching design naturally has three-fold benefit: local semantic information is retained in the embedding; computation and memory usage of the attention maps are quadratically reduced given the same look-back window; and the model can attend longer history. Our channel-independent patch time series Transformer (PatchTST) can improve the long-term forecasting accuracy significantly when compared with that of SOTA Transformer-based models. We also apply our model to self-supervised pre-training tasks and attain excellent fine-tuning performance, which outperforms supervised training on large datasets. Transferring of masked pre-trained representation on one dataset to others also produces SOTA forecasting accuracy.*
+
+This model was contributed by [namctin](https://huggingface.co/namctin), [gsinthong](https://huggingface.co/gsinthong), [diepi](https://huggingface.co/diepi), [vijaye12](https://huggingface.co/vijaye12), [wmgifford](https://huggingface.co/wmgifford), and [kashif](https://huggingface.co/kashif). The original code can be found [here](https://github.com/yuqinie98/PatchTST).
+
+## Usage tips
+
+The model can also be used for time series classification and time series regression. See the respective [`PatchTSTForClassification`] and [`PatchTSTForRegression`] classes.
+
+## Resources
+
+- A blog post explaining PatchTST in depth can be found [here](https://huggingface.co/blog/patchtst). The blog can also be opened in Google Colab.
+
+## PatchTSTConfig
+
+[[autodoc]] PatchTSTConfig
+
+## PatchTSTModel
+
+[[autodoc]] PatchTSTModel
+ - forward
+
+## PatchTSTForPrediction
+
+[[autodoc]] PatchTSTForPrediction
+ - forward
+
+## PatchTSTForClassification
+
+[[autodoc]] PatchTSTForClassification
+ - forward
+
+## PatchTSTForPretraining
+
+[[autodoc]] PatchTSTForPretraining
+ - forward
+
+## PatchTSTForRegression
+
+[[autodoc]] PatchTSTForRegression
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pegasus.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pegasus.md
new file mode 100644
index 0000000000000000000000000000000000000000..a85b85fa01a3d523365a9a521bb7a15a311a2516
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pegasus.md
@@ -0,0 +1,194 @@
+
+*This model was released on 2019-12-18 and added to Hugging Face Transformers on 2020-11-16.*
+
+
+
+
+
+
+
+
+
+
+
+# Pegasus
+
+[Pegasus](https://huggingface.co/papers/1912.08777) is an encoder-decoder (sequence-to-sequence) transformer model pretrained on unlabeled text to perform abstractive summarization. Pegasus is trained jointly on two self-supervised objective functions, masked language modeling (MLM) and gap sentence generation (GSG). Whole sentences are masked and the model has to fill in the gaps in the document. It can be fine-tuned with good performance even on small datasets with only 1000 examples.
+
+You can find all the original Pegasus checkpoints under the [Google](https://huggingface.co/google?search_models=pegasus) organization.
+
+> [!TIP]
+> Click on the Pegasus models in the right sidebar for more examples of how to apply Pegasus to different language tasks.
+
+The example below demonstrates how to summarize text with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="summarization",
+ model="google/pegasus-xsum",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("""Plants are remarkable organisms that produce their own food using a method called photosynthesis.
+This process involves converting sunlight, carbon dioxide, and water into glucose, which provides energy for growth.
+Plants play a crucial role in sustaining life on Earth by generating oxygen and serving as the foundation of most ecosystems.""")
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "google/pegasus-xsum"
+)
+model = AutoModelForSeq2SeqLM.from_pretrained(
+ "google/pegasus-xsum",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+
+input_text = """Plants are remarkable organisms that produce their own food using a method called photosynthesis.
+This process involves converting sunlight, carbon dioxide, and water into glucose, which provides energy for growth.
+Plants play a crucial role in sustaining life on Earth by generating oxygen and serving as the foundation of most ecosystems."""
+input_ids = tokenizer(input_text, return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+echo -e "Plants are remarkable organisms that produce their own food using a method called photosynthesis. This process involves converting sunlight, carbon dioxide, and water into glucose, which provides energy for growth. Plants play a crucial role in sustaining life on Earth by generating oxygen and serving as the foundation of most ecosystems." | transformers-cli run --task summarization --model google/pegasus-xsum --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to int4.
+
+```py
+import torch
+from transformers import BitsAndBytesConfig, AutoModelForSeq2SeqLM, AutoTokenizer
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_compute_dtype=torch.bfloat16,
+ bnb_4bit_quant_type="nf4"
+)
+model = AutoModelForSeq2SeqLM.from_pretrained(
+ "google/pegasus-xsum",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "google/pegasus-xsum"
+)
+input_text = """Plants are remarkable organisms that produce their own food using a method called photosynthesis.
+This process involves converting sunlight, carbon dioxide, and water into glucose, which provides energy for growth.
+Plants play a crucial role in sustaining life on Earth by generating oxygen and serving as the foundation of most ecosystems."""
+input_ids = tokenizer(input_text, return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+## Notes
+
+- [`AdaFactor`] is the recommended optimizer for fine-tuning Pegasus.
+- This implementation of Pegasus inherits from [`BartForConditionalGeneration`] but it uses static/sinusoidal positional embeddings instead. Pegasus also starts generating with `pad_token_id` as the prefix and uses `num_beams=8`.
+
+## PegasusConfig
+
+[[autodoc]] PegasusConfig
+
+## PegasusTokenizer
+
+warning: `add_tokens` does not work at the moment.
+
+[[autodoc]] PegasusTokenizer
+
+## PegasusTokenizerFast
+
+[[autodoc]] PegasusTokenizerFast
+
+
+
+
+## PegasusModel
+
+[[autodoc]] PegasusModel
+ - forward
+
+## PegasusForConditionalGeneration
+
+[[autodoc]] PegasusForConditionalGeneration
+ - forward
+
+## PegasusForCausalLM
+
+[[autodoc]] PegasusForCausalLM
+ - forward
+
+
+
+
+## TFPegasusModel
+
+[[autodoc]] TFPegasusModel
+ - call
+
+## TFPegasusForConditionalGeneration
+
+[[autodoc]] TFPegasusForConditionalGeneration
+ - call
+
+
+
+
+## FlaxPegasusModel
+
+[[autodoc]] FlaxPegasusModel
+ - __call__
+ - encode
+ - decode
+
+## FlaxPegasusForConditionalGeneration
+
+[[autodoc]] FlaxPegasusForConditionalGeneration
+ - __call__
+ - encode
+ - decode
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pegasus_x.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pegasus_x.md
new file mode 100644
index 0000000000000000000000000000000000000000..b1c5c17d3fff30092377f1f006781956bdde1d52
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pegasus_x.md
@@ -0,0 +1,140 @@
+
+*This model was released on 2022-08-08 and added to Hugging Face Transformers on 2022-09-02.*
+
+
+
+
+
+
+
+
+# PEGASUS-X
+
+[PEGASUS-X](https://huggingface.co/papers/2208.04347) is an encoder-decoder (sequence-to-sequence) transformer model for long-input summarization. It extends the [Pegasus](./pegasus) model with staggered block-local attention, global encoder tokens, and additional pretraining on long text sequences, enabling it to handle inputs of up to 16,000 tokens. PEGASUS-X matches the performance of much larger models while using fewer parameters.
+
+You can find all the original PEGASUS-X checkpoints under the [Google](https://huggingface.co/google/models?search=pegasus-x) organization.
+
+> [!TIP]
+> This model was contributed by [zphang](https://huggingface.co/zphang).
+>
+> Click on the PEGASUS-X models in the right sidebar for more examples of how to apply PEGASUS-X to different language tasks.
+
+The example below demonstrates how to summarize text with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="summarization",
+ model="google/pegasus-x-large",
+ torch_dtype=torch.bfloat16,
+ device=0
+)
+pipeline("""Plants are among the most remarkable and essential life forms on Earth, possessing a unique ability to produce their own food through a process known as photosynthesis. This complex biochemical process is fundamental not only to plant life but to virtually all life on the planet.
+Through photosynthesis, plants capture energy from sunlight using a green pigment called chlorophyll, which is located in specialized cell structures called chloroplasts. In the presence of light, plants absorb carbon dioxide from the atmosphere through small pores in their leaves called stomata, and take in water from the soil through their root systems.
+These ingredients are then transformed into glucose, a type of sugar that serves as a source of chemical energy, and oxygen, which is released as a byproduct into the atmosphere. The glucose produced during photosynthesis is not just used immediately; plants also store it as starch or convert it into other organic compounds like cellulose, which is essential for building their cellular structure.
+This energy reserve allows them to grow, develop leaves, produce flowers, bear fruit, and carry out various physiological processes throughout their lifecycle.""")
+```
+
+
+
+```py
+import torch
+from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "google/pegasus-x-large"
+)
+model = AutoModelForSeq2SeqLM.from_pretrained(
+ "google/pegasus-x-large",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+)
+
+input_text = """Plants are among the most remarkable and essential life forms on Earth, possessing a unique ability to produce their own food through a process known as photosynthesis. This complex biochemical process is fundamental not only to plant life but to virtually all life on the planet.
+Through photosynthesis, plants capture energy from sunlight using a green pigment called chlorophyll, which is located in specialized cell structures called chloroplasts. In the presence of light, plants absorb carbon dioxide from the atmosphere through small pores in their leaves called stomata, and take in water from the soil through their root systems.
+These ingredients are then transformed into glucose, a type of sugar that serves as a source of chemical energy, and oxygen, which is released as a byproduct into the atmosphere. The glucose produced during photosynthesis is not just used immediately; plants also store it as starch or convert it into other organic compounds like cellulose, which is essential for building their cellular structure.
+This energy reserve allows them to grow, develop leaves, produce flowers, bear fruit, and carry out various physiological processes throughout their lifecycle."""
+input_ids = tokenizer(input_text, return_tensors="pt").to("cuda")
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+```bash
+echo -e "Plants are among the most remarkable and essential life forms on Earth, possessing a unique ability to produce their own food through a process known as photosynthesis. This complex biochemical process is fundamental not only to plant life but to virtually all life on the planet. Through photosynthesis, plants capture energy from sunlight using a green pigment called chlorophyll, which is located in specialized cell structures called chloroplasts." | transformers-cli run --task summarization --model google/pegasus-x-large --device 0
+```
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to int4.
+
+```py
+import torch
+from transformers import BitsAndBytesConfig, AutoModelForSeq2SeqLM, AutoTokenizer
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_compute_dtype=torch.bfloat16,
+ bnb_4bit_quant_type="nf4"
+)
+model = AutoModelForSeq2SeqLM.from_pretrained(
+ "google/pegasus-x-large",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "google/pegasus-x-large"
+)
+
+input_text = """Plants are among the most remarkable and essential life forms on Earth, possessing a unique ability to produce their own food through a process known as photosynthesis. This complex biochemical process is fundamental not only to plant life but to virtually all life on the planet.
+Through photosynthesis, plants capture energy from sunlight using a green pigment called chlorophyll, which is located in specialized cell structures called chloroplasts. In the presence of light, plants absorb carbon dioxide from the atmosphere through small pores in their leaves called stomata, and take in water from the soil through their root systems.
+These ingredients are then transformed into glucose, a type of sugar that serves as a source of chemical energy, and oxygen, which is released as a byproduct into the atmosphere. The glucose produced during photosynthesis is not just used immediately; plants also store it as starch or convert it into other organic compounds like cellulose, which is essential for building their cellular structure.
+This energy reserve allows them to grow, develop leaves, produce flowers, bear fruit, and carry out various physiological processes throughout their lifecycle."""
+input_ids = tokenizer(input_text, return_tensors="pt").to("cuda")
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+## Notes
+
+- PEGASUS-X also uses the [`PegasusTokenizer`].
+
+## PegasusXConfig
+
+[[autodoc]] PegasusXConfig
+
+## PegasusXModel
+
+[[autodoc]] PegasusXModel
+ - forward
+
+## PegasusXForConditionalGeneration
+
+[[autodoc]] PegasusXForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/perceiver.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/perceiver.md
new file mode 100644
index 0000000000000000000000000000000000000000..5414daf0f1a15eaf9ba3859d53294bc02b621a0a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/perceiver.md
@@ -0,0 +1,239 @@
+
+*This model was released on 2021-07-30 and added to Hugging Face Transformers on 2021-12-08.*
+
+# Perceiver
+
+
+
+
+
+## Overview
+
+The Perceiver IO model was proposed in [Perceiver IO: A General Architecture for Structured Inputs &
+Outputs](https://huggingface.co/papers/2107.14795) by Andrew Jaegle, Sebastian Borgeaud, Jean-Baptiste Alayrac, Carl Doersch,
+Catalin Ionescu, David Ding, Skanda Koppula, Daniel Zoran, Andrew Brock, Evan Shelhamer, Olivier Hénaff, Matthew M.
+Botvinick, Andrew Zisserman, Oriol Vinyals, João Carreira.
+
+Perceiver IO is a generalization of [Perceiver](https://huggingface.co/papers/2103.03206) to handle arbitrary outputs in
+addition to arbitrary inputs. The original Perceiver only produced a single classification label. In addition to
+classification labels, Perceiver IO can produce (for example) language, optical flow, and multimodal videos with audio.
+This is done using the same building blocks as the original Perceiver. The computational complexity of Perceiver IO is
+linear in the input and output size and the bulk of the processing occurs in the latent space, allowing us to process
+inputs and outputs that are much larger than can be handled by standard Transformers. This means, for example,
+Perceiver IO can do BERT-style masked language modeling directly using bytes instead of tokenized inputs.
+
+The abstract from the paper is the following:
+
+*The recently-proposed Perceiver model obtains good results on several domains (images, audio, multimodal, point
+clouds) while scaling linearly in compute and memory with the input size. While the Perceiver supports many kinds of
+inputs, it can only produce very simple outputs such as class scores. Perceiver IO overcomes this limitation without
+sacrificing the original's appealing properties by learning to flexibly query the model's latent space to produce
+outputs of arbitrary size and semantics. Perceiver IO still decouples model depth from data size and still scales
+linearly with data size, but now with respect to both input and output sizes. The full Perceiver IO model achieves
+strong results on tasks with highly structured output spaces, such as natural language and visual understanding,
+StarCraft II, and multi-task and multi-modal domains. As highlights, Perceiver IO matches a Transformer-based BERT
+baseline on the GLUE language benchmark without the need for input tokenization and achieves state-of-the-art
+performance on Sintel optical flow estimation.*
+
+Here's a TLDR explaining how Perceiver works:
+
+The main problem with the self-attention mechanism of the Transformer is that the time and memory requirements scale
+quadratically with the sequence length. Hence, models like BERT and RoBERTa are limited to a max sequence length of 512
+tokens. Perceiver aims to solve this issue by, instead of performing self-attention on the inputs, perform it on a set
+of latent variables, and only use the inputs for cross-attention. In this way, the time and memory requirements don't
+depend on the length of the inputs anymore, as one uses a fixed amount of latent variables, like 256 or 512. These are
+randomly initialized, after which they are trained end-to-end using backpropagation.
+
+Internally, [`PerceiverModel`] will create the latents, which is a tensor of shape `(batch_size, num_latents,
+d_latents)`. One must provide `inputs` (which could be text, images, audio, you name it!) to the model, which it will
+use to perform cross-attention with the latents. The output of the Perceiver encoder is a tensor of the same shape. One
+can then, similar to BERT, convert the last hidden states of the latents to classification logits by averaging along
+the sequence dimension, and placing a linear layer on top of that to project the `d_latents` to `num_labels`.
+
+This was the idea of the original Perceiver paper. However, it could only output classification logits. In a follow-up
+work, PerceiverIO, they generalized it to let the model also produce outputs of arbitrary size. How, you might ask? The
+idea is actually relatively simple: one defines outputs of an arbitrary size, and then applies cross-attention with the
+last hidden states of the latents, using the outputs as queries, and the latents as keys and values.
+
+So let's say one wants to perform masked language modeling (BERT-style) with the Perceiver. As the Perceiver's input
+length will not have an impact on the computation time of the self-attention layers, one can provide raw bytes,
+providing `inputs` of length 2048 to the model. If one now masks out certain of these 2048 tokens, one can define the
+`outputs` as being of shape: `(batch_size, 2048, 768)`. Next, one performs cross-attention with the final hidden states
+of the latents to update the `outputs` tensor. After cross-attention, one still has a tensor of shape `(batch_size,
+2048, 768)`. One can then place a regular language modeling head on top, to project the last dimension to the
+vocabulary size of the model, i.e. creating logits of shape `(batch_size, 2048, 262)` (as Perceiver uses a vocabulary
+size of 262 byte IDs).
+
+
+
+ Perceiver IO architecture. Taken from the original paper
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found
+[here](https://github.com/deepmind/deepmind-research/tree/master/perceiver).
+
+
+
+Perceiver does **not** work with `torch.nn.DataParallel` due to a bug in PyTorch, see [issue #36035](https://github.com/pytorch/pytorch/issues/36035)
+
+
+
+## Resources
+
+- The quickest way to get started with the Perceiver is by checking the [tutorial
+ notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Perceiver).
+- Refer to the [blog post](https://huggingface.co/blog/perceiver) if you want to fully understand how the model works and
+is implemented in the library. Note that the models available in the library only showcase some examples of what you can do
+with the Perceiver. There are many more use cases, including question answering, named-entity recognition, object detection,
+audio classification, video classification, etc.
+- [Text classification task guide](../tasks/sequence_classification)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Image classification task guide](../tasks/image_classification)
+
+## Perceiver specific outputs
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverModelOutput
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverDecoderOutput
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverMaskedLMOutput
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverClassifierOutput
+
+## PerceiverConfig
+
+[[autodoc]] PerceiverConfig
+
+## PerceiverTokenizer
+
+[[autodoc]] PerceiverTokenizer
+ - __call__
+
+## PerceiverFeatureExtractor
+
+[[autodoc]] PerceiverFeatureExtractor
+ - __call__
+
+## PerceiverImageProcessor
+
+[[autodoc]] PerceiverImageProcessor
+ - preprocess
+
+## PerceiverImageProcessorFast
+
+[[autodoc]] PerceiverImageProcessorFast
+ - preprocess
+
+## PerceiverTextPreprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverTextPreprocessor
+
+## PerceiverImagePreprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverImagePreprocessor
+
+## PerceiverOneHotPreprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverOneHotPreprocessor
+
+## PerceiverAudioPreprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverAudioPreprocessor
+
+## PerceiverMultimodalPreprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverMultimodalPreprocessor
+
+## PerceiverProjectionDecoder
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverProjectionDecoder
+
+## PerceiverBasicDecoder
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverBasicDecoder
+
+## PerceiverClassificationDecoder
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverClassificationDecoder
+
+## PerceiverOpticalFlowDecoder
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverOpticalFlowDecoder
+
+## PerceiverBasicVideoAutoencodingDecoder
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverBasicVideoAutoencodingDecoder
+
+## PerceiverMultimodalDecoder
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverMultimodalDecoder
+
+## PerceiverProjectionPostprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverProjectionPostprocessor
+
+## PerceiverAudioPostprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverAudioPostprocessor
+
+## PerceiverClassificationPostprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverClassificationPostprocessor
+
+## PerceiverMultimodalPostprocessor
+
+[[autodoc]] models.perceiver.modeling_perceiver.PerceiverMultimodalPostprocessor
+
+## PerceiverModel
+
+[[autodoc]] PerceiverModel
+ - forward
+
+## PerceiverForMaskedLM
+
+[[autodoc]] PerceiverForMaskedLM
+ - forward
+
+## PerceiverForSequenceClassification
+
+[[autodoc]] PerceiverForSequenceClassification
+ - forward
+
+## PerceiverForImageClassificationLearned
+
+[[autodoc]] PerceiverForImageClassificationLearned
+ - forward
+
+## PerceiverForImageClassificationFourier
+
+[[autodoc]] PerceiverForImageClassificationFourier
+ - forward
+
+## PerceiverForImageClassificationConvProcessing
+
+[[autodoc]] PerceiverForImageClassificationConvProcessing
+ - forward
+
+## PerceiverForOpticalFlow
+
+[[autodoc]] PerceiverForOpticalFlow
+ - forward
+
+## PerceiverForMultimodalAutoencoding
+
+[[autodoc]] PerceiverForMultimodalAutoencoding
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/perception_lm.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/perception_lm.md
new file mode 100644
index 0000000000000000000000000000000000000000..ee6b63fce6fda6f710682984dbf16c6538347526
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/perception_lm.md
@@ -0,0 +1,69 @@
+
+*This model was released on 2025-04-17 and added to Hugging Face Transformers on 2025-07-11.*
+
+# PerceptionLM
+
+## Overview
+
+The [PerceptionLM](https://huggingface.co/papers/2504.13180) model was proposed in [PerceptionLM: Open-Access Data and Models for Detailed Visual Understanding](https://ai.meta.com/research/publications/perceptionlm-open-access-data-and-models-for-detailed-visual-understanding/) by Jang Hyun Cho et al. It's a fully open, reproducible model for transparent research in image and video understanding. PLM consists of
+a vision encoder with a small scale (<8B parameters) LLM decoder.
+
+The abstract from the paper is the following:
+
+*Vision-language models are integral to computer vision research, yet many high-performing models
+remain closed-source, obscuring their data, design and training recipe. The research community
+has responded by using distillation from black-box models to label training data, achieving strong
+benchmark results, at the cost of measurable scientific progress. However, without knowing the details
+of the teacher model and its data sources, scientific progress remains difficult to measure. In this
+paper, we study building a Perception Language Model (PLM) in a fully open and reproducible
+framework for transparent research in image and video understanding. We analyze standard training
+pipelines without distillation from proprietary models and explore large-scale synthetic data to identify
+critical data gaps, particularly in detailed video understanding. To bridge these gaps, we release 2.8M
+human-labeled instances of fine-grained video question-answer pairs and spatio-temporally grounded
+video captions. Additionally, we introduce PLM–VideoBench, a suite for evaluating challenging video
+understanding tasks focusing on the ability to reason about “what”, “where”, “when”, and “how” of a
+video. We make our work fully reproducible by providing data, training recipes, code & models.*
+
+
+This model was contributed by [shumingh](https://huggingface.co/shumingh).
+The original code can be found [here](https://github.com/facebookresearch/perception_models).
+
+
+## PerceptionLMConfig
+
+[[autodoc]] PerceptionLMConfig
+
+## PerceptionLMProcessor
+
+[[autodoc]] PerceptionLMProcessor
+
+## PerceptionLMImageProcessorFast
+
+[[autodoc]] PerceptionLMImageProcessorFast
+
+## PerceptionLMVideoProcessor
+
+[[autodoc]] PerceptionLMVideoProcessor
+
+## PerceptionLMModel
+
+[[autodoc]] PerceptionLMModel
+
+## PerceptionLMForConditionalGeneration
+
+[[autodoc]] PerceptionLMForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/persimmon.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/persimmon.md
new file mode 100644
index 0000000000000000000000000000000000000000..23be6fac046220679f663cf956c3ea4f428f9517
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/persimmon.md
@@ -0,0 +1,108 @@
+
+*This model was released on 2023-09-07 and added to Hugging Face Transformers on 2023-09-12.*
+
+# Persimmon
+
+
+
+
+
+## Overview
+
+The Persimmon model was created by [ADEPT](https://www.adept.ai/blog/persimmon-8b), and authored by Erich Elsen, Augustus Odena, Maxwell Nye, Sağnak Taşırlar, Tri Dao, Curtis Hawthorne, Deepak Moparthi, Arushi Somani.
+
+The authors introduced Persimmon-8B, a decoder model based on the classic transformers architecture, with query and key normalization. Persimmon-8B is a fully permissively-licensed model with approximately 8 billion parameters, released under the Apache license. Some of the key attributes of Persimmon-8B are long context size (16K), performance, and capabilities for multimodal extensions.
+
+The authors showcase their approach to model evaluation, focusing on practical text generation, mirroring how users interact with language models. The work also includes a comparative analysis, pitting Persimmon-8B against other prominent models (MPT 7B Instruct and Llama 2 Base 7B 1-Shot), across various evaluation tasks. The results demonstrate Persimmon-8B's competitive performance, even with limited training data.
+
+In terms of model details, the work outlines the architecture and training methodology of Persimmon-8B, providing insights into its design choices, sequence length, and dataset composition. The authors present a fast inference code that outperforms traditional implementations through operator fusion and CUDA graph utilization while maintaining code coherence. They express their anticipation of how the community will leverage this contribution to drive innovation, hinting at further upcoming releases as part of an ongoing series of developments.
+
+This model was contributed by [ArthurZ](https://huggingface.co/ArthurZ).
+The original code can be found [here](https://github.com/persimmon-ai-labs/adept-inference).
+
+## Usage tips
+
+
+
+The `Persimmon` models were trained using `bfloat16`, but the original inference uses `float16` The checkpoints uploaded on the hub use `torch_dtype = 'float16'` which will be
+used by the `AutoModel` API to cast the checkpoints from `torch.float32` to `torch.float16`.
+
+The `dtype` of the online weights is mostly irrelevant, unless you are using `torch_dtype="auto"` when initializing a model using `model = AutoModelForCausalLM.from_pretrained("path", torch_dtype = "auto")`. The reason is that the model will first be downloaded ( using the `dtype` of the checkpoints online) then it will be cast to the default `dtype` of `torch` (becomes `torch.float32`). Users should specify the `torch_dtype` they want, and if they don't it will be `torch.float32`.
+
+Finetuning the model in `float16` is not recommended and known to produce `nan`, as such the model should be fine-tuned in `bfloat16`.
+
+
+
+
+Tips:
+
+- To convert the model, you need to clone the original repository using `git clone https://github.com/persimmon-ai-labs/adept-inference`, then get the checkpoints:
+
+```bash
+git clone https://github.com/persimmon-ai-labs/adept-inference
+wget https://axtkn4xl5cip.objectstorage.us-phoenix-1.oci.customer-oci.com/n/axtkn4xl5cip/b/adept-public-data/o/8b_base_model_release.tar
+tar -xvf 8b_base_model_release.tar
+python src/transformers/models/persimmon/convert_persimmon_weights_to_hf.py --input_dir /path/to/downloaded/persimmon/weights/ --output_dir /output/path \
+ --pt_model_path /path/to/8b_chat_model_release/iter_0001251/mp_rank_00/model_optim_rng.pt
+ --ada_lib_path /path/to/adept-inference
+```
+
+For the chat model:
+```bash
+wget https://axtkn4xl5cip.objectstorage.us-phoenix-1.oci.customer-oci.com/n/axtkn4xl5cip/b/adept-public-data/o/8b_chat_model_release.tar
+tar -xvf 8b_base_model_release.tar
+```
+
+Thereafter, models can be loaded via:
+
+```py
+from transformers import PersimmonForCausalLM, PersimmonTokenizer
+
+model = PersimmonForCausalLM.from_pretrained("/output/path")
+tokenizer = PersimmonTokenizer.from_pretrained("/output/path")
+```
+
+
+- Perismmon uses a `sentencepiece` based tokenizer, with a `Unigram` model. It supports bytefallback, which is only available in `tokenizers==0.14.0` for the fast tokenizer.
+The `LlamaTokenizer` is used as it is a standard wrapper around sentencepiece. The `chat` template will be updated with the templating functions in a follow up PR!
+
+- The authors suggest to use the following prompt format for the chat mode: `f"human: {prompt}\n\nadept:"`
+
+
+## PersimmonConfig
+
+[[autodoc]] PersimmonConfig
+
+## PersimmonModel
+
+[[autodoc]] PersimmonModel
+ - forward
+
+## PersimmonForCausalLM
+
+[[autodoc]] PersimmonForCausalLM
+ - forward
+
+## PersimmonForSequenceClassification
+
+[[autodoc]] PersimmonForSequenceClassification
+ - forward
+
+## PersimmonForTokenClassification
+
+[[autodoc]] PersimmonForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/phi.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/phi.md
new file mode 100644
index 0000000000000000000000000000000000000000..f16c56ad8f4073d2ff5bd95b2304d95e7a4aa1d5
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/phi.md
@@ -0,0 +1,148 @@
+
+*This model was released on 2023-06-20 and added to Hugging Face Transformers on 2023-11-10.*
+
+
+
+
+
+
+
+
+
+# Phi
+
+[Phi](https://huggingface.co/papers/2306.11644) is a 1.3B parameter transformer model optimized for Python code generation. It focuses on "textbook-quality" training data of code examples, exercises and synthetic Python problems rather than scaling the model size or compute.
+
+You can find all the original Phi checkpoints under the [Phi-1](https://huggingface.co/collections/microsoft/phi-1-6626e29134744e94e222d572) collection.
+
+> [!TIP]
+> Click on the Phi models in the right sidebar for more examples of how to apply Phi to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`], [`AutoModel`] and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(task="text-generation", model="microsoft/phi-1.5", device=0, torch_dtype=torch.bfloat16)
+pipeline("pipeline('''def print_prime(n): """ Print all primes between 1 and n"""''')")
+
+```
+
+
+
+
+
+```py
+import torch
+from transformers import AutoTokenizer, AutoModelForCausalLM
+
+tokenizer = AutoTokenizer.from_pretrained("microsoft/phi-1")
+model = AutoModelForCausalLM.from_pretrained("microsoft/phi-1", torch_dtype=torch.float16, device_map="auto", attn_implementation="sdpa")
+
+input_ids = tokenizer('''def print_prime(n):
+ """
+ Print all primes between 1 and n
+ """''', return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+echo -e "'''def print_prime(n): """ Print all primes between 1 and n"""'''" | transformers run --task text-classification --model microsoft/phi-1.5 --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](https://huggingface.co/docs/transformers/en/quantization/bitsandbytes) to only quantize the weights to 4-bits.
+
+```py
+import torch
+from transformers import BitsAndBytesConfig, AutoTokenizer, AutoModelForCausalLM
+
+bnb_config = BitsAndBytesConfig(load_in_4bit=True, bnb_4bit_compute_dtype=torch.bfloat16, bnb_4bit_quant_type="nf4", bnb_4bit_use_double_quant=True)
+tokenizer = AutoTokenizer.from_pretrained("microsoft/phi-1")
+model = AutoModelForCausalLM.from_pretrained("microsoft/phi-1", torch_dtype=torch.float16, device_map="auto", attn_implementation="sdpa", quantization_config=bnb_config)
+
+input_ids = tokenizer('''def print_prime(n):
+ """
+ Print all primes between 1 and n
+ """''', return_tensors="pt").to(model.device)
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+## Notes
+
+- If you're using Transformers < 4.37.0.dev, set `trust_remote_code=True` in [`~AutoModel.from_pretrained`]. Otherwise, make sure you update Transformers to the latest stable version.
+
+ ```py
+ import torch
+ from transformers import AutoTokenizer, AutoModelForCausalLM
+
+ tokenizer = AutoTokenizer.from_pretrained("microsoft/phi-1")
+ model = AutoModelForCausalLM.from_pretrained(
+ "microsoft/phi-1",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ trust_remote_code=True,
+ attn_implementation="sdpa")
+
+ input_ids = tokenizer('''def print_prime(n):
+ """
+ Print all primes between 1 and n
+ """''', return_tensors="pt").to(model.device)
+
+ output = model.generate(**input_ids, cache_implementation="static")
+ print(tokenizer.decode(output[0], skip_special_tokens=True))
+ ```
+
+## PhiConfig
+
+[[autodoc]] PhiConfig
+
+## PhiModel
+
+[[autodoc]] PhiModel
+ - forward
+
+## PhiForCausalLM
+
+[[autodoc]] PhiForCausalLM
+ - forward
+ - generate
+
+## PhiForSequenceClassification
+
+[[autodoc]] PhiForSequenceClassification
+ - forward
+
+## PhiForTokenClassification
+
+[[autodoc]] PhiForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/phi3.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/phi3.md
new file mode 100644
index 0000000000000000000000000000000000000000..81724728855471d708a9f725f541fd71f0d7a710
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/phi3.md
@@ -0,0 +1,100 @@
+
+*This model was released on 2024-04-22 and added to Hugging Face Transformers on 2024-04-24.*
+
+# Phi-3
+
+
+
+
+
+
+
+
+## Overview
+
+The Phi-3 model was proposed in [Phi-3 Technical Report: A Highly Capable Language Model Locally on Your Phone](https://huggingface.co/papers/2404.14219) by Microsoft.
+
+### Summary
+
+The abstract from the Phi-3 paper is the following:
+
+We introduce phi-3-mini, a 3.8 billion parameter language model trained on 3.3 trillion tokens, whose overall performance, as measured by both academic benchmarks and internal testing, rivals that of models such as Mixtral 8x7B and GPT-3.5 (e.g., phi-3-mini achieves 69% on MMLU and 8.38 on MT-bench), despite being small enough to be deployed on a phone. The innovation lies entirely in our dataset for training, a scaled-up version of the one used for phi-2, composed of heavily filtered web data and synthetic data. The model is also further aligned for robustness, safety, and chat format. We also provide some initial parameter-scaling results with a 7B and 14B models trained for 4.8T tokens, called phi-3-small and phi-3-medium, both significantly more capable than phi-3-mini (e.g., respectively 75% and 78% on MMLU, and 8.7 and 8.9 on MT-bench).
+
+The original code for Phi-3 can be found [here](https://huggingface.co/microsoft/Phi-3-mini-4k-instruct).
+
+## Usage tips
+
+- This model is very similar to `Llama` with the main difference of [`Phi3SuScaledRotaryEmbedding`] and [`Phi3YarnScaledRotaryEmbedding`], where they are used to extend the context of the rotary embeddings. The query, key and values are fused, and the MLP's up and gate projection layers are also fused.
+- The tokenizer used for this model is identical to the [`LlamaTokenizer`], with the exception of additional tokens.
+
+## How to use Phi-3
+
+
+
+Phi-3 has been integrated in the development version (4.40.0.dev) of `transformers`. Until the official version is released through `pip`, ensure that you are doing one of the following:
+
+* When loading the model, ensure that `trust_remote_code=True` is passed as an argument of the `from_pretrained()` function.
+
+* Update your local `transformers` to the development version: `pip uninstall -y transformers && pip install git+https://github.com/huggingface/transformers`. The previous command is an alternative to cloning and installing from the source.
+
+
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("microsoft/Phi-3-mini-4k-instruct")
+>>> tokenizer = AutoTokenizer.from_pretrained("microsoft/Phi-3-mini-4k-instruct")
+
+>>> messages = [{"role": "user", "content": "Can you provide ways to eat combinations of bananas and dragonfruits?"}]
+>>> inputs = tokenizer.apply_chat_template(messages, add_generation_prompt=True, return_tensors="pt")
+
+>>> outputs = model.generate(inputs, max_new_tokens=32)
+>>> text = tokenizer.batch_decode(outputs)[0]
+>>> print(text)
+<|user|> Can you provide ways to eat combinations of bananas and dragonfruits?<|end|><|assistant|> Certainly! Bananas and dragonfruits can be combined in various delicious ways. Here are some creative ideas for incorporating both fruits
+```
+
+## Phi3Config
+
+[[autodoc]] Phi3Config
+
+
+
+
+## Phi3Model
+
+[[autodoc]] Phi3Model
+ - forward
+
+## Phi3ForCausalLM
+
+[[autodoc]] Phi3ForCausalLM
+ - forward
+ - generate
+
+## Phi3ForSequenceClassification
+
+[[autodoc]] Phi3ForSequenceClassification
+ - forward
+
+## Phi3ForTokenClassification
+
+[[autodoc]] Phi3ForTokenClassification
+ - forward
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/phi4_multimodal.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/phi4_multimodal.md
new file mode 100644
index 0000000000000000000000000000000000000000..e2513e3a1458e07b4d9d38c4d88c41980d1e9ba1
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/phi4_multimodal.md
@@ -0,0 +1,182 @@
+
+*This model was released on 2025-03-03 and added to Hugging Face Transformers on 2025-03-25.*
+
+
+
+
+
+
+
+## Phi4 Multimodal
+
+[Phi4 Multimodal](https://huggingface.co/papers/2503.01743) is a multimodal model capable of text, image, and speech and audio inputs or any combination of these. It features a mixture of LoRA adapters for handling different inputs, and each input is routed to the appropriate encoder.
+
+You can find all the original Phi4 Multimodal checkpoints under the [Phi4](https://huggingface.co/collections/microsoft/phi-4-677e9380e514feb5577a40e4) collection.
+
+> [!TIP]
+> This model was contributed by [cyrilvallez](https://huggingface.co/cyrilvallez).
+>
+> Click on the Phi-4 Multimodal in the right sidebar for more examples of how to apply Phi-4 Multimodal to different tasks.
+
+The example below demonstrates how to generate text based on an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```python
+from transformers import pipeline
+generator = pipeline("text-generation", model="microsoft/Phi-4-multimodal-instruct", torch_dtype="auto", device=0)
+
+prompt = "Explain the concept of multimodal AI in simple terms."
+
+result = generator(prompt, max_length=50)
+print(result[0]['generated_text'])
+```
+
+
+
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoProcessor, GenerationConfig
+
+model_path = "microsoft/Phi-4-multimodal-instruct"
+device = "cuda:0"
+
+processor = AutoProcessor.from_pretrained(model_path)
+model = AutoModelForCausalLM.from_pretrained(model_path, device_map=device, torch_dtype=torch.float16)
+
+model.load_adapter(model_path, adapter_name="vision", device_map=device, adapter_kwargs={"subfolder": 'vision-lora'})
+
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "url": "https://www.ilankelman.org/stopsigns/australia.jpg"},
+ {"type": "text", "text": "What is shown in this image?"},
+ ],
+ },
+]
+
+model.set_adapter("vision")
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(device)
+
+generate_ids = model.generate(
+ **inputs,
+ max_new_tokens=1000,
+ do_sample=False,
+)
+generate_ids = generate_ids[:, inputs['input_ids'].shape[1]:]
+response = processor.batch_decode(
+ generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False
+)[0]
+print(f'>>> Response\n{response}')
+```
+
+
+
+
+## Notes
+
+The example below demonstrates inference with an audio and text input.
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoProcessor, GenerationConfig
+
+model_path = "microsoft/Phi-4-multimodal-instruct"
+device = "cuda:0"
+
+processor = AutoProcessor.from_pretrained(model_path)
+model = AutoModelForCausalLM.from_pretrained(model_path, device_map=device, torch_dtype=torch.float16)
+
+model.load_adapter(model_path, adapter_name="speech", device_map=device, adapter_kwargs={"subfolder": 'speech-lora'})
+model.set_adapter("speech")
+audio_url = "https://upload.wikimedia.org/wikipedia/commons/b/b0/Barbara_Sahakian_BBC_Radio4_The_Life_Scientific_29_May_2012_b01j5j24.flac"
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "audio", "url": audio_url},
+ {"type": "text", "text": "Transcribe the audio to text, and then translate the audio to French. Use as a separator between the origina transcript and the translation."},
+ ],
+ },
+]
+
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(device)
+
+generate_ids = model.generate(
+ **inputs,
+ max_new_tokens=1000,
+ do_sample=False,
+)
+generate_ids = generate_ids[:, inputs['input_ids'].shape[1]:]
+response = processor.batch_decode(
+ generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False
+)[0]
+print(f'>>> Response\n{response}')
+
+```
+
+## Phi4MultimodalFeatureExtractor
+
+[[autodoc]] Phi4MultimodalFeatureExtractor
+
+## Phi4MultimodalImageProcessorFast
+
+[[autodoc]] Phi4MultimodalImageProcessorFast
+
+## Phi4MultimodalProcessor
+
+[[autodoc]] Phi4MultimodalProcessor
+
+## Phi4MultimodalAudioConfig
+
+[[autodoc]] Phi4MultimodalAudioConfig
+
+## Phi4MultimodalVisionConfig
+
+[[autodoc]] Phi4MultimodalVisionConfig
+
+## Phi4MultimodalConfig
+
+[[autodoc]] Phi4MultimodalConfig
+
+## Phi4MultimodalAudioModel
+
+[[autodoc]] Phi4MultimodalAudioModel
+
+## Phi4MultimodalVisionModel
+
+[[autodoc]] Phi4MultimodalVisionModel
+
+## Phi4MultimodalModel
+
+[[autodoc]] Phi4MultimodalModel
+ - forward
+
+## Phi4MultimodalForCausalLM
+
+[[autodoc]] Phi4MultimodalForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/phimoe.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/phimoe.md
new file mode 100644
index 0000000000000000000000000000000000000000..0bc043556f8e646a8db45907398efa7ec8d83471
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/phimoe.md
@@ -0,0 +1,125 @@
+
+*This model was released on 2024-04-22 and added to Hugging Face Transformers on 2024-10-04.*
+
+# PhiMoE
+
+
+
+
+
+
+
+## Overview
+
+The PhiMoE model was proposed in [Phi-3 Technical Report: A Highly Capable Language Model Locally on Your Phone](https://huggingface.co/papers/2404.14219) by Microsoft.
+
+### Summary
+
+The abstract from the Phi-3 paper is the following:
+
+We introduce phi-3-mini, a 3.8 billion parameter language model trained on 3.3 trillion tokens, whose overall performance, as measured by both academic benchmarks and internal testing, rivals that of models such as Mixtral 8x7B and GPT-3.5 (e.g., phi-3-mini achieves 69% on MMLU and 8.38 on MT-bench), despite being small enough to be deployed on a phone. Our training dataset is a scaled-up version of the one used for phi-2, composed of heavily filtered publicly available web data and synthetic data. The model is also further aligned for robustness, safety, and chat format. We also provide parameter-scaling results with a 7B, 14B models trained for 4.8T tokens, called phi-3-small, phi-3-medium, both significantly more capable than phi-3-mini (e.g., respectively 75%, 78% on MMLU, and 8.7, 8.9 on MT-bench). To enhance multilingual, multimodal, and long-context capabilities, we introduce three models in the phi-3.5 series: phi-3.5-mini, phi-3.5-MoE, and phi-3.5-Vision. The phi-3.5-MoE, a 16 x 3.8B MoE model with 6.6 billion active parameters, achieves superior performance in language reasoning, math, and code tasks compared to other open-source models of similar scale, such as Llama 3.1 and the Mixtral series, and on par with Gemini-1.5-Flash and GPT-4o-mini. Meanwhile, phi-3.5-Vision, a 4.2 billion parameter model derived from phi-3.5-mini, excels in reasoning tasks and is adept at handling both single-image and text prompts, as well as multi-image and text prompts.
+
+The original code for PhiMoE can be found [here](https://huggingface.co/microsoft/Phi-3.5-MoE-instruct).
+
+## Usage tips
+
+- This model is very similar to `Mixtral` with the main difference of [`Phi3LongRoPEScaledRotaryEmbedding`], where they are used to extend the context of the rotary embeddings. The query, key and values are fused, and the MLP's up and gate projection layers are also fused.
+- The tokenizer used for this model is identical to the [`LlamaTokenizer`], with the exception of additional tokens.
+
+## How to use PhiMoE
+
+
+
+Phi-3.5-MoE-instruct has been integrated in the development version (4.44.2.dev) of `transformers`. Until the official version is released through `pip`, ensure that you are doing the following:
+* When loading the model, ensure that `trust_remote_code=True` is passed as an argument of the `from_pretrained()` function.
+
+The current `transformers` version can be verified with: `pip list | grep transformers`.
+
+Examples of required packages:
+```
+flash_attn==2.5.8
+torch==2.3.1
+accelerate==0.31.0
+transformers==4.43.0
+```
+
+
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, pipeline
+
+torch.random.manual_seed(0)
+
+model = AutoModelForCausalLM.from_pretrained(
+ "microsoft/Phi-3.5-MoE-instruct",
+ device_map="auto",
+ torch_dtype="auto",
+ trust_remote_code=True,
+)
+
+tokenizer = AutoTokenizer.from_pretrained("microsoft/Phi-3.5-MoE-instruct")
+
+messages = [
+ {"role": "system", "content": "You are a helpful AI assistant."},
+ {"role": "user", "content": "Can you provide ways to eat combinations of bananas and dragonfruits?"},
+ {"role": "assistant", "content": "Sure! Here are some ways to eat bananas and dragonfruits together: 1. Banana and dragonfruit smoothie: Blend bananas and dragonfruits together with some milk and honey. 2. Banana and dragonfruit salad: Mix sliced bananas and dragonfruits together with some lemon juice and honey."},
+ {"role": "user", "content": "What about solving an 2x + 3 = 7 equation?"},
+]
+
+pipe = pipeline(
+ "text-generation",
+ model=model,
+ tokenizer=tokenizer,
+)
+
+generation_args = {
+ "max_new_tokens": 500,
+ "return_full_text": False,
+ "temperature": 0.0,
+ "do_sample": False,
+}
+
+output = pipe(messages, **generation_args)
+print(output[0]['generated_text'])
+```
+
+## PhimoeConfig
+
+[[autodoc]] PhimoeConfig
+
+
+
+
+## PhimoeModel
+
+[[autodoc]] PhimoeModel
+ - forward
+
+## PhimoeForCausalLM
+
+[[autodoc]] PhimoeForCausalLM
+ - forward
+ - generate
+
+## PhimoeForSequenceClassification
+
+[[autodoc]] PhimoeForSequenceClassification
+ - forward
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/phobert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/phobert.md
new file mode 100644
index 0000000000000000000000000000000000000000..d01571aaeab0bf33f29bd8363e7d11e17b0d6f77
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/phobert.md
@@ -0,0 +1,72 @@
+
+*This model was released on 2020-03-02 and added to Hugging Face Transformers on 2020-11-16.*
+
+# PhoBERT
+
+
+
+
+
+
+
+## Overview
+
+The PhoBERT model was proposed in [PhoBERT: Pre-trained language models for Vietnamese](https://huggingface.co/papers/2003.00744) by Dat Quoc Nguyen, Anh Tuan Nguyen.
+
+The abstract from the paper is the following:
+
+*We present PhoBERT with two versions, PhoBERT-base and PhoBERT-large, the first public large-scale monolingual
+language models pre-trained for Vietnamese. Experimental results show that PhoBERT consistently outperforms the recent
+best pre-trained multilingual model XLM-R (Conneau et al., 2020) and improves the state-of-the-art in multiple
+Vietnamese-specific NLP tasks including Part-of-speech tagging, Dependency parsing, Named-entity recognition and
+Natural language inference.*
+
+This model was contributed by [dqnguyen](https://huggingface.co/dqnguyen). The original code can be found [here](https://github.com/VinAIResearch/PhoBERT).
+
+## Usage example
+
+```python
+>>> import torch
+>>> from transformers import AutoModel, AutoTokenizer
+
+>>> phobert = AutoModel.from_pretrained("vinai/phobert-base")
+>>> tokenizer = AutoTokenizer.from_pretrained("vinai/phobert-base")
+
+>>> # INPUT TEXT MUST BE ALREADY WORD-SEGMENTED!
+>>> line = "Tôi là sinh_viên trường đại_học Công_nghệ ."
+
+>>> input_ids = torch.tensor([tokenizer.encode(line)])
+
+>>> with torch.no_grad():
+... features = phobert(input_ids) # Models outputs are now tuples
+
+>>> # With TensorFlow 2.0+:
+>>> # from transformers import TFAutoModel
+>>> # phobert = TFAutoModel.from_pretrained("vinai/phobert-base")
+```
+
+
+
+PhoBERT implementation is the same as BERT, except for tokenization. Refer to [BERT documentation](bert) for information on
+configuration classes and their parameters. PhoBERT-specific tokenizer is documented below.
+
+
+
+## PhobertTokenizer
+
+[[autodoc]] PhobertTokenizer
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pix2struct.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pix2struct.md
new file mode 100644
index 0000000000000000000000000000000000000000..c43c9b3b92ed32c3186ac7f87ed0f2f84a575653
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pix2struct.md
@@ -0,0 +1,82 @@
+
+*This model was released on 2022-10-07 and added to Hugging Face Transformers on 2023-03-22.*
+
+# Pix2Struct
+
+
+
+
+
+## Overview
+
+The Pix2Struct model was proposed in [Pix2Struct: Screenshot Parsing as Pretraining for Visual Language Understanding](https://huggingface.co/papers/2210.03347) by Kenton Lee, Mandar Joshi, Iulia Turc, Hexiang Hu, Fangyu Liu, Julian Eisenschlos, Urvashi Khandelwal, Peter Shaw, Ming-Wei Chang, Kristina Toutanova.
+
+The abstract from the paper is the following:
+
+> Visually-situated language is ubiquitous -- sources range from textbooks with diagrams to web pages with images and tables, to mobile apps with buttons and forms. Perhaps due to this diversity, previous work has typically relied on domain-specific recipes with limited sharing of the underlying data, model architectures, and objectives. We present Pix2Struct, a pretrained image-to-text model for purely visual language understanding, which can be finetuned on tasks containing visually-situated language. Pix2Struct is pretrained by learning to parse masked screenshots of web pages into simplified HTML. The web, with its richness of visual elements cleanly reflected in the HTML structure, provides a large source of pretraining data well suited to the diversity of downstream tasks. Intuitively, this objective subsumes common pretraining signals such as OCR, language modeling, image captioning. In addition to the novel pretraining strategy, we introduce a variable-resolution input representation and a more flexible integration of language and vision inputs, where language prompts such as questions are rendered directly on top of the input image. For the first time, we show that a single pretrained model can achieve state-of-the-art results in six out of nine tasks across four domains: documents, illustrations, user interfaces, and natural images.
+
+Tips:
+
+Pix2Struct has been fine tuned on a variety of tasks and datasets, ranging from image captioning, visual question answering (VQA) over different inputs (books, charts, science diagrams), captioning UI components etc. The full list can be found in Table 1 of the paper.
+We therefore advise you to use these models for the tasks they have been fine tuned on. For instance, if you want to use Pix2Struct for UI captioning, you should use the model fine tuned on the UI dataset. If you want to use Pix2Struct for image captioning, you should use the model fine tuned on the natural images captioning dataset and so on.
+
+If you want to use the model to perform conditional text captioning, make sure to use the processor with `add_special_tokens=False`.
+
+This model was contributed by [ybelkada](https://huggingface.co/ybelkada).
+The original code can be found [here](https://github.com/google-research/pix2struct).
+
+## Resources
+
+- [Fine-tuning Notebook](https://github.com/huggingface/notebooks/blob/main/examples/image_captioning_pix2struct.ipynb)
+- [All models](https://huggingface.co/models?search=pix2struct)
+
+## Pix2StructConfig
+
+[[autodoc]] Pix2StructConfig
+ - from_text_vision_configs
+
+## Pix2StructTextConfig
+
+[[autodoc]] Pix2StructTextConfig
+
+## Pix2StructVisionConfig
+
+[[autodoc]] Pix2StructVisionConfig
+
+## Pix2StructProcessor
+
+[[autodoc]] Pix2StructProcessor
+
+## Pix2StructImageProcessor
+
+[[autodoc]] Pix2StructImageProcessor
+ - preprocess
+
+## Pix2StructTextModel
+
+[[autodoc]] Pix2StructTextModel
+ - forward
+
+## Pix2StructVisionModel
+
+[[autodoc]] Pix2StructVisionModel
+ - forward
+
+## Pix2StructForConditionalGeneration
+
+[[autodoc]] Pix2StructForConditionalGeneration
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pixtral.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pixtral.md
new file mode 100644
index 0000000000000000000000000000000000000000..4145db0ad3e88d30a258bb20a994a2dba18e9ecf
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pixtral.md
@@ -0,0 +1,111 @@
+
+*This model was released on 2024-09-17 and added to Hugging Face Transformers on 2024-09-14.*
+
+# Pixtral
+
+
+
+
+
+## Overview
+
+The [Pixtral](https://huggingface.co/papers/2410.07073) model was released by the Mistral AI team in a [blog post](https://mistral.ai/news/pixtral-12b/). Pixtral is a multimodal version of [Mistral](mistral), incorporating a 400 million parameter vision encoder trained from scratch.
+
+The intro from the blog says the following:
+
+*Pixtral is trained to understand both natural images and documents, achieving 52.5% on the MMMU reasoning benchmark, surpassing a number of larger models. The model shows strong abilities in tasks such as chart and figure understanding, document question answering, multimodal reasoning and instruction following. Pixtral is able to ingest images at their natural resolution and aspect ratio, giving the user flexibility on the number of tokens used to process an image. Pixtral is also able to process any number of images in its long context window of 128K tokens. Unlike previous open-source models, Pixtral does not compromise on text benchmark performance to excel in multimodal tasks.*
+
+
+
+ Pixtral architecture. Taken from the blog post.
+
+Tips:
+
+- Pixtral is a multimodal model, taking images and text as input, and producing text as output.
+- This model follows the [Llava](llava) architecture. The model uses [`PixtralVisionModel`] for its vision encoder, and [`MistralForCausalLM`] for its language decoder.
+- The main contribution is the 2d ROPE (rotary position embeddings) on the images, and support for arbitrary image sizes (the images are not padded together nor are they resized).
+- Similar to [Llava](llava), the model internally replaces the `[IMG]` token placeholders by image embeddings from the vision encoder. The format for one or multiple prompts is the following:
+```
+"[INST][IMG]\nWhat are the things I should be cautious about when I visit this place?[/INST]"
+```
+Then, the processor will replace each `[IMG]` token with a number of `[IMG]` tokens that depend on the height and the width of each image. Each *row* of the image is separated by an `[IMG_BREAK]` token, and each image is separated by an `[IMG_END]` token. It's advised to use the `apply_chat_template` method of the processor, which takes care of all of this and formats the text for you. If you're using `transformers>=4.49.0`, you can also get a vectorized output from `apply_chat_template`. See the [usage section](#usage) for more info.
+
+
+This model was contributed by [amyeroberts](https://huggingface.co/amyeroberts) and [ArthurZ](https://huggingface.co/ArthurZ). The original code can be found [here](https://github.com/vllm-project/vllm/pull/8377).
+
+
+## Usage
+
+At inference time, it's advised to use the processor's `apply_chat_template` method, which correctly formats the prompt for the model:
+
+```python
+from transformers import AutoProcessor, LlavaForConditionalGeneration
+
+model_id = "mistral-community/pixtral-12b"
+processor = AutoProcessor.from_pretrained(model_id)
+model = LlavaForConditionalGeneration.from_pretrained(model_id, device_map="auto")
+
+chat = [
+ {
+ "role": "user", "content": [
+ {"type": "text", "content": "Can this animal"},
+ {"type": "image", "url": "https://picsum.photos/id/237/200/300"},
+ {"type": "text", "content": "live here?"},
+ {"type": "image", "url": "https://picsum.photos/seed/picsum/200/300"}
+ ]
+ }
+]
+
+inputs = processor.apply_chat_template(
+ chat,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+).to(model.device)
+
+generate_ids = model.generate(**inputs, max_new_tokens=500)
+output = processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
+```
+
+## PixtralVisionConfig
+
+[[autodoc]] PixtralVisionConfig
+
+## MistralCommonTokenizer
+
+[[autodoc]] MistralCommonTokenizer
+
+## PixtralVisionModel
+
+[[autodoc]] PixtralVisionModel
+ - forward
+
+## PixtralImageProcessor
+
+[[autodoc]] PixtralImageProcessor
+ - preprocess
+
+## PixtralImageProcessorFast
+
+[[autodoc]] PixtralImageProcessorFast
+ - preprocess
+
+## PixtralProcessor
+
+[[autodoc]] PixtralProcessor
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/plbart.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/plbart.md
new file mode 100644
index 0000000000000000000000000000000000000000..d8ce330cb0f74271005361e70c3616d56c001f4f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/plbart.md
@@ -0,0 +1,123 @@
+
+*This model was released on 2021-03-10 and added to Hugging Face Transformers on 2022-02-18.*
+
+# PLBart
+
+
+
+
+
+
+
+## Overview
+
+The PLBART model was proposed in [Unified Pre-training for Program Understanding and Generation](https://huggingface.co/papers/2103.06333) by Wasi Uddin Ahmad, Saikat Chakraborty, Baishakhi Ray, Kai-Wei Chang.
+This is a BART-like model which can be used to perform code-summarization, code-generation, and code-translation tasks. The pre-trained model `plbart-base` has been trained using multilingual denoising task
+on Java, Python and English.
+
+According to the abstract
+
+*Code summarization and generation empower conversion between programming language (PL) and natural language (NL),
+while code translation avails the migration of legacy code from one PL to another. This paper introduces PLBART,
+a sequence-to-sequence model capable of performing a broad spectrum of program and language understanding and generation tasks.
+PLBART is pre-trained on an extensive collection of Java and Python functions and associated NL text via denoising autoencoding.
+Experiments on code summarization in the English language, code generation, and code translation in seven programming languages
+show that PLBART outperforms or rivals state-of-the-art models. Moreover, experiments on discriminative tasks, e.g., program
+repair, clone detection, and vulnerable code detection, demonstrate PLBART's effectiveness in program understanding.
+Furthermore, analysis reveals that PLBART learns program syntax, style (e.g., identifier naming convention), logical flow
+(e.g., if block inside an else block is equivalent to else if block) that are crucial to program semantics and thus excels
+even with limited annotations.*
+
+This model was contributed by [gchhablani](https://huggingface.co/gchhablani). The Authors' code can be found [here](https://github.com/wasiahmad/PLBART).
+
+## Usage examples
+
+PLBart is a multilingual encoder-decoder (sequence-to-sequence) model primarily intended for code-to-text, text-to-code, code-to-code tasks. As the
+model is multilingual it expects the sequences in a different format. A special language id token is added in both the
+source and target text. The source text format is `X [eos, src_lang_code]` where `X` is the source text. The
+target text format is `[tgt_lang_code] X [eos]`. `bos` is never used.
+
+However, for fine-tuning, in some cases no language token is provided in cases where a single language is used. Please refer to [the paper](https://huggingface.co/papers/2103.06333) to learn more about this.
+
+In cases where the language code is needed, the regular [`~PLBartTokenizer.__call__`] will encode source text format
+when you pass texts as the first argument or with the keyword argument `text`, and will encode target text format if
+it's passed with the `text_target` keyword argument.
+
+### Supervised training
+
+```python
+>>> from transformers import PLBartForConditionalGeneration, PLBartTokenizer
+
+>>> tokenizer = PLBartTokenizer.from_pretrained("uclanlp/plbart-base", src_lang="en_XX", tgt_lang="python")
+>>> example_python_phrase = "def maximum(a,b,c):NEW_LINE_INDENTreturn max([a,b,c])"
+>>> expected_translation_english = "Returns the maximum value of a b c."
+>>> inputs = tokenizer(example_python_phrase, text_target=expected_translation_english, return_tensors="pt")
+>>> model(**inputs)
+```
+
+### Generation
+
+ While generating the target text set the `decoder_start_token_id` to the target language id. The following
+ example shows how to translate Python to English using the `uclanlp/plbart-python-en_XX` model.
+
+```python
+>>> from transformers import PLBartForConditionalGeneration, PLBartTokenizer
+
+>>> tokenizer = PLBartTokenizer.from_pretrained("uclanlp/plbart-python-en_XX", src_lang="python", tgt_lang="en_XX")
+>>> example_python_phrase = "def maximum(a,b,c):NEW_LINE_INDENTreturn max([a,b,c])"
+>>> inputs = tokenizer(example_python_phrase, return_tensors="pt")
+>>> model = PLBartForConditionalGeneration.from_pretrained("uclanlp/plbart-python-en_XX")
+>>> translated_tokens = model.generate(**inputs, decoder_start_token_id=tokenizer.lang_code_to_id["en_XX"])
+>>> tokenizer.batch_decode(translated_tokens, skip_special_tokens=True)[0]
+"Returns the maximum value of a b c."
+```
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## PLBartConfig
+
+[[autodoc]] PLBartConfig
+
+## PLBartTokenizer
+
+[[autodoc]] PLBartTokenizer
+ - build_inputs_with_special_tokens
+
+## PLBartModel
+
+[[autodoc]] PLBartModel
+ - forward
+
+## PLBartForConditionalGeneration
+
+[[autodoc]] PLBartForConditionalGeneration
+ - forward
+
+## PLBartForSequenceClassification
+
+[[autodoc]] PLBartForSequenceClassification
+ - forward
+
+## PLBartForCausalLM
+
+[[autodoc]] PLBartForCausalLM
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/poolformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/poolformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..b4b378ff43d26f301752bed22524c6d48162cf0b
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/poolformer.md
@@ -0,0 +1,90 @@
+
+*This model was released on 2021-11-22 and added to Hugging Face Transformers on 2022-02-17.*
+
+# PoolFormer
+
+
+
+
+
+## Overview
+
+The PoolFormer model was proposed in [MetaFormer is Actually What You Need for Vision](https://huggingface.co/papers/2111.11418) by Sea AI Labs. Instead of designing complicated token mixer to achieve SOTA performance, the target of this work is to demonstrate the competence of transformer models largely stem from the general architecture MetaFormer.
+
+The abstract from the paper is the following:
+
+*Transformers have shown great potential in computer vision tasks. A common belief is their attention-based token mixer module contributes most to their competence. However, recent works show the attention-based module in transformers can be replaced by spatial MLPs and the resulted models still perform quite well. Based on this observation, we hypothesize that the general architecture of the transformers, instead of the specific token mixer module, is more essential to the model's performance. To verify this, we deliberately replace the attention module in transformers with an embarrassingly simple spatial pooling operator to conduct only the most basic token mixing. Surprisingly, we observe that the derived model, termed as PoolFormer, achieves competitive performance on multiple computer vision tasks. For example, on ImageNet-1K, PoolFormer achieves 82.1% top-1 accuracy, surpassing well-tuned vision transformer/MLP-like baselines DeiT-B/ResMLP-B24 by 0.3%/1.1% accuracy with 35%/52% fewer parameters and 48%/60% fewer MACs. The effectiveness of PoolFormer verifies our hypothesis and urges us to initiate the concept of "MetaFormer", a general architecture abstracted from transformers without specifying the token mixer. Based on the extensive experiments, we argue that MetaFormer is the key player in achieving superior results for recent transformer and MLP-like models on vision tasks. This work calls for more future research dedicated to improving MetaFormer instead of focusing on the token mixer modules. Additionally, our proposed PoolFormer could serve as a starting baseline for future MetaFormer architecture design.*
+
+The figure below illustrates the architecture of PoolFormer. Taken from the [original paper](https://huggingface.co/papers/2111.11418).
+
+
+
+This model was contributed by [heytanay](https://huggingface.co/heytanay). The original code can be found [here](https://github.com/sail-sg/poolformer).
+
+## Usage tips
+
+- PoolFormer has a hierarchical architecture, where instead of Attention, a simple Average Pooling layer is present. All checkpoints of the model can be found on the [hub](https://huggingface.co/models?other=poolformer).
+- One can use [`PoolFormerImageProcessor`] to prepare images for the model.
+- As most models, PoolFormer comes in different sizes, the details of which can be found in the table below.
+
+| **Model variant** | **Depths** | **Hidden sizes** | **Params (M)** | **ImageNet-1k Top 1** |
+| :---------------: | ------------- | ------------------- | :------------: | :-------------------: |
+| s12 | [2, 2, 6, 2] | [64, 128, 320, 512] | 12 | 77.2 |
+| s24 | [4, 4, 12, 4] | [64, 128, 320, 512] | 21 | 80.3 |
+| s36 | [6, 6, 18, 6] | [64, 128, 320, 512] | 31 | 81.4 |
+| m36 | [6, 6, 18, 6] | [96, 192, 384, 768] | 56 | 82.1 |
+| m48 | [8, 8, 24, 8] | [96, 192, 384, 768] | 73 | 82.5 |
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with PoolFormer.
+
+
+
+- [`PoolFormerForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## PoolFormerConfig
+
+[[autodoc]] PoolFormerConfig
+
+## PoolFormerFeatureExtractor
+
+[[autodoc]] PoolFormerFeatureExtractor
+ - __call__
+
+## PoolFormerImageProcessor
+
+[[autodoc]] PoolFormerImageProcessor
+ - preprocess
+
+## PoolFormerImageProcessorFast
+
+[[autodoc]] PoolFormerImageProcessorFast
+ - preprocess
+
+## PoolFormerModel
+
+[[autodoc]] PoolFormerModel
+ - forward
+
+## PoolFormerForImageClassification
+
+[[autodoc]] PoolFormerForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pop2piano.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pop2piano.md
new file mode 100644
index 0000000000000000000000000000000000000000..5f68b1805000fb26266520fd9716ace06cbbbc3b
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pop2piano.md
@@ -0,0 +1,193 @@
+
+*This model was released on 2022-11-02 and added to Hugging Face Transformers on 2023-08-21.*
+
+# Pop2Piano
+
+
+
+
+
+## Overview
+
+The Pop2Piano model was proposed in [Pop2Piano : Pop Audio-based Piano Cover Generation](https://huggingface.co/papers/2211.00895) by Jongho Choi and Kyogu Lee.
+
+Piano covers of pop music are widely enjoyed, but generating them from music is not a trivial task. It requires great
+expertise with playing piano as well as knowing different characteristics and melodies of a song. With Pop2Piano you
+can directly generate a cover from a song's audio waveform. It is the first model to directly generate a piano cover
+from pop audio without melody and chord extraction modules.
+
+Pop2Piano is an encoder-decoder Transformer model based on [T5](https://huggingface.co/papers/1910.10683). The input audio
+is transformed to its waveform and passed to the encoder, which transforms it to a latent representation. The decoder
+uses these latent representations to generate token ids in an autoregressive way. Each token id corresponds to one of four
+different token types: time, velocity, note and 'special'. The token ids are then decoded to their equivalent MIDI file.
+
+The abstract from the paper is the following:
+
+*Piano covers of pop music are enjoyed by many people. However, the
+task of automatically generating piano covers of pop music is still
+understudied. This is partly due to the lack of synchronized
+{Pop, Piano Cover} data pairs, which made it challenging to apply
+the latest data-intensive deep learning-based methods. To leverage
+the power of the data-driven approach, we make a large amount of
+paired and synchronized {Pop, Piano Cover} data using an automated
+pipeline. In this paper, we present Pop2Piano, a Transformer network
+that generates piano covers given waveforms of pop music. To the best
+of our knowledge, this is the first model to generate a piano cover
+directly from pop audio without using melody and chord extraction
+modules. We show that Pop2Piano, trained with our dataset, is capable
+of producing plausible piano covers.*
+
+This model was contributed by [Susnato Dhar](https://huggingface.co/susnato).
+The original code can be found [here](https://github.com/sweetcocoa/pop2piano).
+
+## Usage tips
+
+* To use Pop2Piano, you will need to install the 🤗 Transformers library, as well as the following third party modules:
+```bash
+pip install pretty-midi==0.2.9 essentia==2.1b6.dev1034 librosa scipy
+```
+Please note that you may need to restart your runtime after installation.
+* Pop2Piano is an Encoder-Decoder based model like T5.
+* Pop2Piano can be used to generate midi-audio files for a given audio sequence.
+* Choosing different composers in `Pop2PianoForConditionalGeneration.generate()` can lead to variety of different results.
+* Setting the sampling rate to 44.1 kHz when loading the audio file can give good performance.
+* Though Pop2Piano was mainly trained on Korean Pop music, it also does pretty well on other Western Pop or Hip Hop songs.
+
+## Examples
+
+- Example using HuggingFace Dataset:
+
+```python
+>>> from datasets import load_dataset
+>>> from transformers import Pop2PianoForConditionalGeneration, Pop2PianoProcessor
+
+>>> model = Pop2PianoForConditionalGeneration.from_pretrained("sweetcocoa/pop2piano")
+>>> processor = Pop2PianoProcessor.from_pretrained("sweetcocoa/pop2piano")
+>>> ds = load_dataset("sweetcocoa/pop2piano_ci", split="test")
+
+>>> inputs = processor(
+... audio=ds["audio"][0]["array"], sampling_rate=ds["audio"][0]["sampling_rate"], return_tensors="pt"
+... )
+>>> model_output = model.generate(input_features=inputs["input_features"], composer="composer1")
+>>> tokenizer_output = processor.batch_decode(
+... token_ids=model_output, feature_extractor_output=inputs
+... )["pretty_midi_objects"][0]
+>>> tokenizer_output.write("./Outputs/midi_output.mid")
+```
+
+- Example using your own audio file:
+
+```python
+>>> import librosa
+>>> from transformers import Pop2PianoForConditionalGeneration, Pop2PianoProcessor
+
+>>> audio, sr = librosa.load("", sr=44100) # feel free to change the sr to a suitable value.
+>>> model = Pop2PianoForConditionalGeneration.from_pretrained("sweetcocoa/pop2piano")
+>>> processor = Pop2PianoProcessor.from_pretrained("sweetcocoa/pop2piano")
+
+>>> inputs = processor(audio=audio, sampling_rate=sr, return_tensors="pt")
+>>> model_output = model.generate(input_features=inputs["input_features"], composer="composer1")
+>>> tokenizer_output = processor.batch_decode(
+... token_ids=model_output, feature_extractor_output=inputs
+... )["pretty_midi_objects"][0]
+>>> tokenizer_output.write("./Outputs/midi_output.mid")
+```
+
+- Example of processing multiple audio files in batch:
+
+```python
+>>> import librosa
+>>> from transformers import Pop2PianoForConditionalGeneration, Pop2PianoProcessor
+
+>>> # feel free to change the sr to a suitable value.
+>>> audio1, sr1 = librosa.load("", sr=44100)
+>>> audio2, sr2 = librosa.load("", sr=44100)
+>>> model = Pop2PianoForConditionalGeneration.from_pretrained("sweetcocoa/pop2piano")
+>>> processor = Pop2PianoProcessor.from_pretrained("sweetcocoa/pop2piano")
+
+>>> inputs = processor(audio=[audio1, audio2], sampling_rate=[sr1, sr2], return_attention_mask=True, return_tensors="pt")
+>>> # Since we now generating in batch(2 audios) we must pass the attention_mask
+>>> model_output = model.generate(
+... input_features=inputs["input_features"],
+... attention_mask=inputs["attention_mask"],
+... composer="composer1",
+... )
+>>> tokenizer_output = processor.batch_decode(
+... token_ids=model_output, feature_extractor_output=inputs
+... )["pretty_midi_objects"]
+
+>>> # Since we now have 2 generated MIDI files
+>>> tokenizer_output[0].write("./Outputs/midi_output1.mid")
+>>> tokenizer_output[1].write("./Outputs/midi_output2.mid")
+```
+
+
+- Example of processing multiple audio files in batch (Using `Pop2PianoFeatureExtractor` and `Pop2PianoTokenizer`):
+
+```python
+>>> import librosa
+>>> from transformers import Pop2PianoForConditionalGeneration, Pop2PianoFeatureExtractor, Pop2PianoTokenizer
+
+>>> # feel free to change the sr to a suitable value.
+>>> audio1, sr1 = librosa.load("", sr=44100)
+>>> audio2, sr2 = librosa.load("", sr=44100)
+>>> model = Pop2PianoForConditionalGeneration.from_pretrained("sweetcocoa/pop2piano")
+>>> feature_extractor = Pop2PianoFeatureExtractor.from_pretrained("sweetcocoa/pop2piano")
+>>> tokenizer = Pop2PianoTokenizer.from_pretrained("sweetcocoa/pop2piano")
+
+>>> inputs = feature_extractor(
+... audio=[audio1, audio2],
+... sampling_rate=[sr1, sr2],
+... return_attention_mask=True,
+... return_tensors="pt",
+... )
+>>> # Since we now generating in batch(2 audios) we must pass the attention_mask
+>>> model_output = model.generate(
+... input_features=inputs["input_features"],
+... attention_mask=inputs["attention_mask"],
+... composer="composer1",
+... )
+>>> tokenizer_output = tokenizer.batch_decode(
+... token_ids=model_output, feature_extractor_output=inputs
+... )["pretty_midi_objects"]
+
+>>> # Since we now have 2 generated MIDI files
+>>> tokenizer_output[0].write("./Outputs/midi_output1.mid")
+>>> tokenizer_output[1].write("./Outputs/midi_output2.mid")
+```
+
+
+## Pop2PianoConfig
+
+[[autodoc]] Pop2PianoConfig
+
+## Pop2PianoFeatureExtractor
+
+[[autodoc]] Pop2PianoFeatureExtractor
+ - __call__
+
+## Pop2PianoForConditionalGeneration
+
+[[autodoc]] Pop2PianoForConditionalGeneration
+ - forward
+ - generate
+
+## Pop2PianoTokenizer
+
+[[autodoc]] Pop2PianoTokenizer
+ - __call__
+
+## Pop2PianoProcessor
+
+[[autodoc]] Pop2PianoProcessor
+ - __call__
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/prompt_depth_anything.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/prompt_depth_anything.md
new file mode 100644
index 0000000000000000000000000000000000000000..84960a33ccec7b38c09a23655fc706e9aa45ac32
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/prompt_depth_anything.md
@@ -0,0 +1,97 @@
+
+*This model was released on 2024-12-18 and added to Hugging Face Transformers on 2025-03-21.*
+
+# Prompt Depth Anything
+
+## Overview
+
+The Prompt Depth Anything model was introduced in [Prompting Depth Anything for 4K Resolution Accurate Metric Depth Estimation](https://huggingface.co/papers/2412.14015) by Haotong Lin, Sida Peng, Jingxiao Chen, Songyou Peng, Jiaming Sun, Minghuan Liu, Hujun Bao, Jiashi Feng, Xiaowei Zhou, Bingyi Kang.
+
+
+The abstract from the paper is as follows:
+
+*Prompts play a critical role in unleashing the power of language and vision foundation models for specific tasks. For the first time, we introduce prompting into depth foundation models, creating a new paradigm for metric depth estimation termed Prompt Depth Anything. Specifically, we use a low-cost LiDAR as the prompt to guide the Depth Anything model for accurate metric depth output, achieving up to 4K resolution. Our approach centers on a concise prompt fusion design that integrates the LiDAR at multiple scales within the depth decoder. To address training challenges posed by limited datasets containing both LiDAR depth and precise GT depth, we propose a scalable data pipeline that includes synthetic data LiDAR simulation and real data pseudo GT depth generation. Our approach sets new state-of-the-arts on the ARKitScenes and ScanNet++ datasets and benefits downstream applications, including 3D reconstruction and generalized robotic grasping.*
+
+
+
+ Prompt Depth Anything overview. Taken from the original paper.
+
+## Usage example
+
+The Transformers library allows you to use the model with just a few lines of code:
+
+```python
+>>> import torch
+>>> import requests
+>>> import numpy as np
+
+>>> from PIL import Image
+>>> from transformers import AutoImageProcessor, AutoModelForDepthEstimation
+
+>>> url = "https://github.com/DepthAnything/PromptDA/blob/main/assets/example_images/image.jpg?raw=true"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> image_processor = AutoImageProcessor.from_pretrained("depth-anything/prompt-depth-anything-vits-hf")
+>>> model = AutoModelForDepthEstimation.from_pretrained("depth-anything/prompt-depth-anything-vits-hf")
+
+>>> prompt_depth_url = "https://github.com/DepthAnything/PromptDA/blob/main/assets/example_images/arkit_depth.png?raw=true"
+>>> prompt_depth = Image.open(requests.get(prompt_depth_url, stream=True).raw)
+>>> # the prompt depth can be None, and the model will output a monocular relative depth.
+
+>>> # prepare image for the model
+>>> inputs = image_processor(images=image, return_tensors="pt", prompt_depth=prompt_depth)
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> # interpolate to original size
+>>> post_processed_output = image_processor.post_process_depth_estimation(
+... outputs,
+... target_sizes=[(image.height, image.width)],
+... )
+
+>>> # visualize the prediction
+>>> predicted_depth = post_processed_output[0]["predicted_depth"]
+>>> depth = predicted_depth * 1000
+>>> depth = depth.detach().cpu().numpy()
+>>> depth = Image.fromarray(depth.astype("uint16")) # mm
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Prompt Depth Anything.
+
+- [Prompt Depth Anything Demo](https://huggingface.co/spaces/depth-anything/PromptDA)
+- [Prompt Depth Anything Interactive Results](https://promptda.github.io/interactive.html)
+
+If you are interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## PromptDepthAnythingConfig
+
+[[autodoc]] PromptDepthAnythingConfig
+
+## PromptDepthAnythingForDepthEstimation
+
+[[autodoc]] PromptDepthAnythingForDepthEstimation
+ - forward
+
+## PromptDepthAnythingImageProcessor
+
+[[autodoc]] PromptDepthAnythingImageProcessor
+ - preprocess
+ - post_process_depth_estimation
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/prophetnet.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/prophetnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..19131b75ce02b5de34c48afc4a866cb625b17ac6
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/prophetnet.md
@@ -0,0 +1,99 @@
+
+*This model was released on 2020-01-13 and added to Hugging Face Transformers on 2020-11-16.*
+
+# ProphetNet
+
+
+
+
+
+## Overview
+
+The ProphetNet model was proposed in [ProphetNet: Predicting Future N-gram for Sequence-to-Sequence Pre-training,](https://huggingface.co/papers/2001.04063) by Yu Yan, Weizhen Qi, Yeyun Gong, Dayiheng Liu, Nan Duan, Jiusheng Chen, Ruofei
+Zhang, Ming Zhou on 13 Jan, 2020.
+
+ProphetNet is an encoder-decoder model and can predict n-future tokens for "ngram" language modeling instead of just
+the next token.
+
+The abstract from the paper is the following:
+
+*In this paper, we present a new sequence-to-sequence pretraining model called ProphetNet, which introduces a novel
+self-supervised objective named future n-gram prediction and the proposed n-stream self-attention mechanism. Instead of
+the optimization of one-step ahead prediction in traditional sequence-to-sequence model, the ProphetNet is optimized by
+n-step ahead prediction which predicts the next n tokens simultaneously based on previous context tokens at each time
+step. The future n-gram prediction explicitly encourages the model to plan for the future tokens and prevent
+overfitting on strong local correlations. We pre-train ProphetNet using a base scale dataset (16GB) and a large scale
+dataset (160GB) respectively. Then we conduct experiments on CNN/DailyMail, Gigaword, and SQuAD 1.1 benchmarks for
+abstractive summarization and question generation tasks. Experimental results show that ProphetNet achieves new
+state-of-the-art results on all these datasets compared to the models using the same scale pretraining corpus.*
+
+The Authors' code can be found [here](https://github.com/microsoft/ProphetNet).
+
+## Usage tips
+
+- ProphetNet is a model with absolute position embeddings so it's usually advised to pad the inputs on the right rather than
+ the left.
+- The model architecture is based on the original Transformer, but replaces the “standard” self-attention mechanism in the decoder by a main self-attention mechanism and a self and n-stream (predict) self-attention mechanism.
+
+## Resources
+
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Translation task guide](../tasks/translation)
+- [Summarization task guide](../tasks/summarization)
+
+## ProphetNetConfig
+
+[[autodoc]] ProphetNetConfig
+
+## ProphetNetTokenizer
+
+[[autodoc]] ProphetNetTokenizer
+
+## ProphetNet specific outputs
+
+[[autodoc]] models.prophetnet.modeling_prophetnet.ProphetNetSeq2SeqLMOutput
+
+[[autodoc]] models.prophetnet.modeling_prophetnet.ProphetNetSeq2SeqModelOutput
+
+[[autodoc]] models.prophetnet.modeling_prophetnet.ProphetNetDecoderModelOutput
+
+[[autodoc]] models.prophetnet.modeling_prophetnet.ProphetNetDecoderLMOutput
+
+## ProphetNetModel
+
+[[autodoc]] ProphetNetModel
+ - forward
+
+## ProphetNetEncoder
+
+[[autodoc]] ProphetNetEncoder
+ - forward
+
+## ProphetNetDecoder
+
+[[autodoc]] ProphetNetDecoder
+ - forward
+
+## ProphetNetForConditionalGeneration
+
+[[autodoc]] ProphetNetForConditionalGeneration
+ - forward
+
+## ProphetNetForCausalLM
+
+[[autodoc]] ProphetNetForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pvt.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pvt.md
new file mode 100644
index 0000000000000000000000000000000000000000..e7902affe5f45c7afd46c77fc89b2e159d5e91c4
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pvt.md
@@ -0,0 +1,81 @@
+
+*This model was released on 2021-02-24 and added to Hugging Face Transformers on 2023-07-24.*
+
+# Pyramid Vision Transformer (PVT)
+
+
+
+
+
+## Overview
+
+The PVT model was proposed in
+[Pyramid Vision Transformer: A Versatile Backbone for Dense Prediction without Convolutions](https://huggingface.co/papers/2102.12122)
+by Wenhai Wang, Enze Xie, Xiang Li, Deng-Ping Fan, Kaitao Song, Ding Liang, Tong Lu, Ping Luo, Ling Shao. The PVT is a type of
+vision transformer that utilizes a pyramid structure to make it an effective backbone for dense prediction tasks. Specifically
+it allows for more fine-grained inputs (4 x 4 pixels per patch) to be used, while simultaneously shrinking the sequence length
+of the Transformer as it deepens - reducing the computational cost. Additionally, a spatial-reduction attention (SRA) layer
+is used to further reduce the resource consumption when learning high-resolution features.
+
+The abstract from the paper is the following:
+
+*Although convolutional neural networks (CNNs) have achieved great success in computer vision, this work investigates a
+simpler, convolution-free backbone network useful for many dense prediction tasks. Unlike the recently proposed Vision
+Transformer (ViT) that was designed for image classification specifically, we introduce the Pyramid Vision Transformer
+(PVT), which overcomes the difficulties of porting Transformer to various dense prediction tasks. PVT has several
+merits compared to current state of the arts. Different from ViT that typically yields low resolution outputs and
+incurs high computational and memory costs, PVT not only can be trained on dense partitions of an image to achieve high
+output resolution, which is important for dense prediction, but also uses a progressive shrinking pyramid to reduce the
+computations of large feature maps. PVT inherits the advantages of both CNN and Transformer, making it a unified
+backbone for various vision tasks without convolutions, where it can be used as a direct replacement for CNN backbones.
+We validate PVT through extensive experiments, showing that it boosts the performance of many downstream tasks, including
+object detection, instance and semantic segmentation. For example, with a comparable number of parameters, PVT+RetinaNet
+achieves 40.4 AP on the COCO dataset, surpassing ResNet50+RetinNet (36.3 AP) by 4.1 absolute AP (see Figure 2). We hope
+that PVT could serve as an alternative and useful backbone for pixel-level predictions and facilitate future research.*
+
+This model was contributed by [Xrenya](https://huggingface.co/Xrenya). The original code can be found [here](https://github.com/whai362/PVT).
+
+
+- PVTv1 on ImageNet-1K
+
+| **Model variant** |**Size** |**Acc@1**|**Params (M)**|
+|--------------------|:-------:|:-------:|:------------:|
+| PVT-Tiny | 224 | 75.1 | 13.2 |
+| PVT-Small | 224 | 79.8 | 24.5 |
+| PVT-Medium | 224 | 81.2 | 44.2 |
+| PVT-Large | 224 | 81.7 | 61.4 |
+
+
+## PvtConfig
+
+[[autodoc]] PvtConfig
+
+## PvtImageProcessor
+
+[[autodoc]] PvtImageProcessor
+ - preprocess
+
+## PvtImageProcessorFast
+
+[[autodoc]] PvtImageProcessorFast
+ - preprocess
+
+## PvtForImageClassification
+
+[[autodoc]] PvtForImageClassification
+ - forward
+
+## PvtModel
+
+[[autodoc]] PvtModel
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pvt_v2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pvt_v2.md
new file mode 100644
index 0000000000000000000000000000000000000000..0d0ee3cca7511f01eb7a2e58feb9b46789291f13
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/pvt_v2.md
@@ -0,0 +1,115 @@
+
+*This model was released on 2021-06-25 and added to Hugging Face Transformers on 2024-03-13.*
+
+# Pyramid Vision Transformer V2 (PVTv2)
+
+
+
+
+
+## Overview
+
+The PVTv2 model was proposed in
+[PVT v2: Improved Baselines with Pyramid Vision Transformer](https://huggingface.co/papers/2106.13797) by Wenhai Wang, Enze Xie, Xiang Li, Deng-Ping Fan, Kaitao Song, Ding Liang, Tong Lu, Ping Luo, and Ling Shao. As an improved variant of PVT, it eschews position embeddings, relying instead on positional information encoded through zero-padding and overlapping patch embeddings. This lack of reliance on position embeddings simplifies the architecture, and enables running inference at any resolution without needing to interpolate them.
+
+The PVTv2 encoder structure has been successfully deployed to achieve state-of-the-art scores in [Segformer](https://huggingface.co/papers/2105.15203) for semantic segmentation, [GLPN](https://huggingface.co/papers/2201.07436) for monocular depth, and [Panoptic Segformer](https://huggingface.co/papers/2109.03814) for panoptic segmentation.
+
+PVTv2 belongs to a family of models called [hierarchical transformers](https://natecibik.medium.com/the-rise-of-vision-transformers-f623c980419f) , which make adaptations to transformer layers in order to generate multi-scale feature maps. Unlike the columnal structure of Vision Transformer ([ViT](https://huggingface.co/papers/2010.11929)) which loses fine-grained detail, multi-scale feature maps are known preserve this detail and aid performance in dense prediction tasks. In the case of PVTv2, this is achieved by generating image patch tokens using 2D convolution with overlapping kernels in each encoder layer.
+
+The multi-scale features of hierarchical transformers allow them to be easily swapped in for traditional workhorse computer vision backbone models like ResNet in larger architectures. Both Segformer and Panoptic Segformer demonstrated that configurations using PVTv2 for a backbone consistently outperformed those with similarly sized ResNet backbones.
+
+Another powerful feature of the PVTv2 is the complexity reduction in the self-attention layers called Spatial Reduction Attention (SRA), which uses 2D convolution layers to project hidden states to a smaller resolution before attending to them with the queries, improving the $O(n^2)$ complexity of self-attention to $O(n^2/R)$, with $R$ being the spatial reduction ratio (`sr_ratio`, aka kernel size and stride in the 2D convolution).
+
+SRA was introduced in PVT, and is the default attention complexity reduction method used in PVTv2. However, PVTv2 also introduced the option of using a self-attention mechanism with linear complexity related to image size, which they called "Linear SRA". This method uses average pooling to reduce the hidden states to a fixed size that is invariant to their original resolution (although this is inherently more lossy than regular SRA). This option can be enabled by setting `linear_attention` to `True` in the PVTv2Config.
+
+### Abstract from the paper:
+
+*Transformer recently has presented encouraging progress in computer vision. In this work, we present new baselines by improving the original Pyramid Vision Transformer (PVT v1) by adding three designs, including (1) linear complexity attention layer, (2) overlapping patch embedding, and (3) convolutional feed-forward network. With these modifications, PVT v2 reduces the computational complexity of PVT v1 to linear and achieves significant improvements on fundamental vision tasks such as classification, detection, and segmentation. Notably, the proposed PVT v2 achieves comparable or better performances than recent works such as Swin Transformer. We hope this work will facilitate state-of-the-art Transformer researches in computer vision. Code is available at https://github.com/whai362/PVT.*
+
+This model was contributed by [FoamoftheSea](https://huggingface.co/FoamoftheSea). The original code can be found [here](https://github.com/whai362/PVT).
+
+## Usage tips
+
+- [PVTv2](https://huggingface.co/papers/2106.13797) is a hierarchical transformer model which has demonstrated powerful performance in image classification and multiple other tasks, used as a backbone for semantic segmentation in [Segformer](https://huggingface.co/papers/2105.15203), monocular depth estimation in [GLPN](https://huggingface.co/papers/2201.07436), and panoptic segmentation in [Panoptic Segformer](https://huggingface.co/papers/2109.03814), consistently showing higher performance than similar ResNet configurations.
+- Hierarchical transformers like PVTv2 achieve superior data and parameter efficiency on image data compared with pure transformer architectures by incorporating design elements of convolutional neural networks (CNNs) into their encoders. This creates a best-of-both-worlds architecture that infuses the useful inductive biases of CNNs like translation equivariance and locality into the network while still enjoying the benefits of dynamic data response and global relationship modeling provided by the self-attention mechanism of [transformers](https://huggingface.co/papers/1706.03762).
+- PVTv2 uses overlapping patch embeddings to create multi-scale feature maps, which are infused with location information using zero-padding and depth-wise convolutions.
+- To reduce the complexity in the attention layers, PVTv2 performs a spatial reduction on the hidden states using either strided 2D convolution (SRA) or fixed-size average pooling (Linear SRA). Although inherently more lossy, Linear SRA provides impressive performance with a linear complexity with respect to image size. To use Linear SRA in the self-attention layers, set `linear_attention=True` in the `PvtV2Config`.
+- [`PvtV2Model`] is the hierarchical transformer encoder (which is also often referred to as Mix Transformer or MiT in the literature). [`PvtV2ForImageClassification`] adds a simple classifier head on top to perform Image Classification. [`PvtV2Backbone`] can be used with the [`AutoBackbone`] system in larger architectures like Deformable DETR.
+- ImageNet pretrained weights for all model sizes can be found on the [hub](https://huggingface.co/models?other=pvt_v2).
+
+ The best way to get started with the PVTv2 is to load the pretrained checkpoint with the size of your choosing using `AutoModelForImageClassification`:
+```python
+import requests
+import torch
+
+from transformers import AutoModelForImageClassification, AutoImageProcessor
+from PIL import Image
+
+model = AutoModelForImageClassification.from_pretrained("OpenGVLab/pvt_v2_b0")
+image_processor = AutoImageProcessor.from_pretrained("OpenGVLab/pvt_v2_b0")
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+processed = image_processor(image)
+outputs = model(torch.tensor(processed["pixel_values"]))
+```
+
+To use the PVTv2 as a backbone for more complex architectures like DeformableDETR, you can use AutoBackbone (this model would need fine-tuning as you're replacing the backbone in the pretrained model):
+
+```python
+import requests
+import torch
+
+from transformers import AutoConfig, AutoModelForObjectDetection, AutoImageProcessor
+from PIL import Image
+
+model = AutoModelForObjectDetection.from_config(
+ config=AutoConfig.from_pretrained(
+ "SenseTime/deformable-detr",
+ backbone_config=AutoConfig.from_pretrained("OpenGVLab/pvt_v2_b5"),
+ use_timm_backbone=False
+ ),
+)
+
+image_processor = AutoImageProcessor.from_pretrained("SenseTime/deformable-detr")
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+processed = image_processor(image)
+outputs = model(torch.tensor(processed["pixel_values"]))
+```
+
+[PVTv2](https://github.com/whai362/PVT/tree/v2) performance on ImageNet-1K by model size (B0-B5):
+
+| Method | Size | Acc@1 | #Params (M) |
+|------------------|:----:|:-----:|:-----------:|
+| PVT-V2-B0 | 224 | 70.5 | 3.7 |
+| PVT-V2-B1 | 224 | 78.7 | 14.0 |
+| PVT-V2-B2-Linear | 224 | 82.1 | 22.6 |
+| PVT-V2-B2 | 224 | 82.0 | 25.4 |
+| PVT-V2-B3 | 224 | 83.1 | 45.2 |
+| PVT-V2-B4 | 224 | 83.6 | 62.6 |
+| PVT-V2-B5 | 224 | 83.8 | 82.0 |
+
+
+## PvtV2Config
+
+[[autodoc]] PvtV2Config
+
+## PvtForImageClassification
+
+[[autodoc]] PvtV2ForImageClassification
+ - forward
+
+## PvtModel
+
+[[autodoc]] PvtV2Model
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qdqbert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qdqbert.md
new file mode 100644
index 0000000000000000000000000000000000000000..76fe00c56388a324ff0b0151d2e7543da8c16bc9
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qdqbert.md
@@ -0,0 +1,181 @@
+
+*This model was released on 2020-04-20 and added to Hugging Face Transformers on 2023-06-20.*
+
+# QDQBERT
+
+
+
+
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The QDQBERT model can be referenced in [Integer Quantization for Deep Learning Inference: Principles and Empirical
+Evaluation](https://huggingface.co/papers/2004.09602) by Hao Wu, Patrick Judd, Xiaojie Zhang, Mikhail Isaev and Paulius
+Micikevicius.
+
+The abstract from the paper is the following:
+
+*Quantization techniques can reduce the size of Deep Neural Networks and improve inference latency and throughput by
+taking advantage of high throughput integer instructions. In this paper we review the mathematical aspects of
+quantization parameters and evaluate their choices on a wide range of neural network models for different application
+domains, including vision, speech, and language. We focus on quantization techniques that are amenable to acceleration
+by processors with high-throughput integer math pipelines. We also present a workflow for 8-bit quantization that is
+able to maintain accuracy within 1% of the floating-point baseline on all networks studied, including models that are
+more difficult to quantize, such as MobileNets and BERT-large.*
+
+This model was contributed by [shangz](https://huggingface.co/shangz).
+
+## Usage tips
+
+- QDQBERT model adds fake quantization operations (pair of QuantizeLinear/DequantizeLinear ops) to (i) linear layer
+ inputs and weights, (ii) matmul inputs, (iii) residual add inputs, in BERT model.
+- QDQBERT requires the dependency of [Pytorch Quantization Toolkit](https://github.com/NVIDIA/TensorRT/tree/master/tools/pytorch-quantization). To install `pip install pytorch-quantization --extra-index-url https://pypi.ngc.nvidia.com`
+- QDQBERT model can be loaded from any checkpoint of HuggingFace BERT model (for example *google-bert/bert-base-uncased*), and
+ perform Quantization Aware Training/Post Training Quantization.
+- A complete example of using QDQBERT model to perform Quatization Aware Training and Post Training Quantization for
+ SQUAD task can be found at https://github.com/huggingface/transformers-research-projects/tree/main/quantization-qdqbert.
+
+### Set default quantizers
+
+QDQBERT model adds fake quantization operations (pair of QuantizeLinear/DequantizeLinear ops) to BERT by
+`TensorQuantizer` in [Pytorch Quantization Toolkit](https://github.com/NVIDIA/TensorRT/tree/master/tools/pytorch-quantization). `TensorQuantizer` is the module
+for quantizing tensors, with `QuantDescriptor` defining how the tensor should be quantized. Refer to [Pytorch
+Quantization Toolkit userguide](https://docs.nvidia.com/deeplearning/tensorrt/pytorch-quantization-toolkit/docs/userguide.html) for more details.
+
+Before creating QDQBERT model, one has to set the default `QuantDescriptor` defining default tensor quantizers.
+
+Example:
+
+```python
+>>> import pytorch_quantization.nn as quant_nn
+>>> from pytorch_quantization.tensor_quant import QuantDescriptor
+
+>>> # The default tensor quantizer is set to use Max calibration method
+>>> input_desc = QuantDescriptor(num_bits=8, calib_method="max")
+>>> # The default tensor quantizer is set to be per-channel quantization for weights
+>>> weight_desc = QuantDescriptor(num_bits=8, axis=((0,)))
+>>> quant_nn.QuantLinear.set_default_quant_desc_input(input_desc)
+>>> quant_nn.QuantLinear.set_default_quant_desc_weight(weight_desc)
+```
+
+### Calibration
+
+Calibration is the terminology of passing data samples to the quantizer and deciding the best scaling factors for
+tensors. After setting up the tensor quantizers, one can use the following example to calibrate the model:
+
+```python
+>>> # Find the TensorQuantizer and enable calibration
+>>> for name, module in model.named_modules():
+... if name.endswith("_input_quantizer"):
+... module.enable_calib()
+... module.disable_quant() # Use full precision data to calibrate
+
+>>> # Feeding data samples
+>>> model(x)
+>>> # ...
+
+>>> # Finalize calibration
+>>> for name, module in model.named_modules():
+... if name.endswith("_input_quantizer"):
+... module.load_calib_amax()
+... module.enable_quant()
+
+>>> # If running on GPU, it needs to call .cuda() again because new tensors will be created by calibration process
+>>> model.cuda()
+
+>>> # Keep running the quantized model
+>>> # ...
+```
+
+### Export to ONNX
+
+The goal of exporting to ONNX is to deploy inference by [TensorRT](https://developer.nvidia.com/tensorrt). Fake
+quantization will be broken into a pair of QuantizeLinear/DequantizeLinear ONNX ops. After setting static member of
+TensorQuantizer to use Pytorch’s own fake quantization functions, fake quantized model can be exported to ONNX, follow
+the instructions in [torch.onnx](https://pytorch.org/docs/stable/onnx.html). Example:
+
+```python
+>>> from pytorch_quantization.nn import TensorQuantizer
+
+>>> TensorQuantizer.use_fb_fake_quant = True
+
+>>> # Load the calibrated model
+>>> ...
+>>> # ONNX export
+>>> torch.onnx.export(...)
+```
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## QDQBertConfig
+
+[[autodoc]] QDQBertConfig
+
+## QDQBertModel
+
+[[autodoc]] QDQBertModel
+ - forward
+
+## QDQBertLMHeadModel
+
+[[autodoc]] QDQBertLMHeadModel
+ - forward
+
+## QDQBertForMaskedLM
+
+[[autodoc]] QDQBertForMaskedLM
+ - forward
+
+## QDQBertForSequenceClassification
+
+[[autodoc]] QDQBertForSequenceClassification
+ - forward
+
+## QDQBertForNextSentencePrediction
+
+[[autodoc]] QDQBertForNextSentencePrediction
+ - forward
+
+## QDQBertForMultipleChoice
+
+[[autodoc]] QDQBertForMultipleChoice
+ - forward
+
+## QDQBertForTokenClassification
+
+[[autodoc]] QDQBertForTokenClassification
+ - forward
+
+## QDQBertForQuestionAnswering
+
+[[autodoc]] QDQBertForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2.md
new file mode 100644
index 0000000000000000000000000000000000000000..978b5abe64a3dbb2eb8e37ac2f5244d08afe7018
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2.md
@@ -0,0 +1,186 @@
+
+*This model was released on 2024-07-15 and added to Hugging Face Transformers on 2024-01-17.*
+
+
+
+
+
+
+
+
+
+
+# Qwen2
+
+[Qwen2](https://huggingface.co/papers/2407.10671) is a family of large language models (pretrained, instruction-tuned and mixture-of-experts) available in sizes from 0.5B to 72B parameters. The models are built on the Transformer architecture featuring enhancements like group query attention (GQA), rotary positional embeddings (RoPE), a mix of sliding window and full attention, and dual chunk attention with YARN for training stability. Qwen2 models support multiple languages and context lengths up to 131,072 tokens.
+
+You can find all the official Qwen2 checkpoints under the [Qwen2](https://huggingface.co/collections/Qwen/qwen2-6659360b33528ced941e557f) collection.
+
+> [!TIP]
+> Click on the Qwen2 models in the right sidebar for more examples of how to apply Qwen2 to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`], [`AutoModel`], and from the command line using the instruction-tuned models.
+
+
+
+
+```python
+import torch
+from transformers import pipeline
+
+pipe = pipeline(
+ task="text-generation",
+ model="Qwen/Qwen2-1.5B-Instruct",
+ torch_dtype=torch.bfloat16,
+ device_map=0
+)
+
+messages = [
+ {"role": "system", "content": "You are a helpful assistant."},
+ {"role": "user", "content": "Tell me about the Qwen2 model family."},
+]
+outputs = pipe(messages, max_new_tokens=256, do_sample=True, temperature=0.7, top_k=50, top_p=0.95)
+print(outputs[0]["generated_text"][-1]['content'])
+```
+
+
+
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained(
+ "Qwen/Qwen2-1.5B-Instruct",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen2-1.5B-Instruct")
+
+prompt = "Give me a short introduction to large language models."
+messages = [
+ {"role": "system", "content": "You are a helpful assistant."},
+ {"role": "user", "content": prompt}
+]
+text = tokenizer.apply_chat_template(
+ messages,
+ tokenize=False,
+ add_generation_prompt=True
+)
+model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
+
+generated_ids = model.generate(
+ model_inputs.input_ids,
+ cache_implementation="static",
+ max_new_tokens=512,
+ do_sample=True,
+ temperature=0.7,
+ top_k=50,
+ top_p=0.95
+)
+generated_ids = [
+ output_ids[len(input_ids):] for input_ids, output_ids in zip(model_inputs.input_ids, generated_ids)
+]
+
+response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+print(response)
+```
+
+
+
+
+```bash
+# pip install -U flash-attn --no-build-isolation
+transformers chat Qwen/Qwen2-7B-Instruct --torch_dtype auto --attn_implementation flash_attention_2 --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to quantize the weights to 4-bits.
+
+```python
+# pip install -U flash-attn --no-build-isolation
+import torch
+from transformers import AutoTokenizer, AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_compute_dtype=torch.bfloat16,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_use_double_quant=True,
+)
+
+tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen2-7B")
+model = AutoModelForCausalLM.from_pretrained(
+ "Qwen/Qwen2-7B",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config,
+ attn_implementation="flash_attention_2"
+)
+
+inputs = tokenizer("The Qwen2 model family is", return_tensors="pt").to(model.device)
+outputs = model.generate(**inputs, max_new_tokens=100)
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+
+## Notes
+
+- Ensure your Transformers library version is up-to-date. Qwen2 requires Transformers>=4.37.0 for full support.
+
+## Qwen2Config
+
+[[autodoc]] Qwen2Config
+
+## Qwen2Tokenizer
+
+[[autodoc]] Qwen2Tokenizer
+ - save_vocabulary
+
+## Qwen2TokenizerFast
+
+[[autodoc]] Qwen2TokenizerFast
+
+## Qwen2Model
+
+[[autodoc]] Qwen2Model
+ - forward
+
+## Qwen2ForCausalLM
+
+[[autodoc]] Qwen2ForCausalLM
+ - forward
+
+## Qwen2ForSequenceClassification
+
+[[autodoc]] Qwen2ForSequenceClassification
+ - forward
+
+## Qwen2ForTokenClassification
+
+[[autodoc]] Qwen2ForTokenClassification
+ - forward
+
+## Qwen2ForQuestionAnswering
+
+[[autodoc]] Qwen2ForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2_5_omni.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2_5_omni.md
new file mode 100644
index 0000000000000000000000000000000000000000..159e06918e15634262f22b7ffd53ad411afa54d7
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2_5_omni.md
@@ -0,0 +1,401 @@
+
+*This model was released on 2025-03-26 and added to Hugging Face Transformers on 2025-04-14.*
+
+# Qwen2.5-Omni
+
+
+
+
+
+
+
+## Overview
+
+The [Qwen2.5-Omni](https://qwenlm.github.io/blog/qwen2.5-omni/) model is a unified multiple modalities model proposed in [Qwen2.5-Omni Technical Report](https://huggingface.co/papers/2503.20215) from Qwen team, Alibaba Group.
+
+The abstract from the technical report is the following:
+
+*We present Qwen2.5-Omni, an end-to-end multimodal model designed to perceive diverse modalities, including text, images, audio, and video, while simultaneously generating text and natural speech responses in a streaming manner. To enable the streaming of multimodal information inputs, both audio and visual encoders utilize a block-wise processing approach. This strategy effectively decouples the handling of long sequences of multimodal data, assigning the perceptual responsibilities to the multimodal encoder and entrusting the modeling of extended sequences to a large language model. Such a division of labor enhances the fusion of different modalities via the shared attention mechanism. To synchronize the timestamps of video inputs with audio, we organized the audio and video sequentially in an interleaved manner and propose a novel position embedding approach, named TMRoPE (Time-aligned Multimodal RoPE). To concurrently generate text and speech while avoiding interference between the two modalities, we propose Thinker-Talker architecture. In this framework, Thinker functions as a large language model tasked with text generation, while Talker is a dual-track autoregressive model that directly utilizes the hidden representations from the Thinker to produce audio tokens as output. Both the Thinker and Talker models are designed to be trained and inferred in an end-to-end manner. For decoding audio tokens in a streaming manner, we introduce a sliding-window DiT that restricts the receptive field, aiming to reduce the initial package delay. Qwen2.5-Omni outperforms the similarly sized Qwen2-VL and Qwen2-Audio in both image and audio capabilities. Furthermore, Qwen2.5-Omni achieves state-of-the-art performance on multimodal benchmarks like Omni-Bench. Notably, Qwen2.5-Omni is the first open-source model to achieve a level of performance in end-to-end speech instruction following that is comparable to its capabilities with text inputs, as evidenced by benchmarks such as MMLU and GSM8K. As for speech generation, Qwen2.5-Omni’s streaming Talker outperform most existing streaming and non-streaming alternatives in robustness and naturalness.*
+
+
+
+## Notes
+
+- Use [`Qwen2_5OmniForConditionalGeneration`] to generate audio and text output. To generate only one output type, use [`Qwen2_5OmniThinkerForConditionalGeneration`] for text-only and [`Qwen2_5OmniTalkersForConditionalGeneration`] for audio-only outputs.
+- Audio generation with [`Qwen2_5OmniForConditionalGeneration`] supports only single batch size at the moment.
+- In case out out-of-memory errors hwen working with video input, decrease `processor.max_pixels`. By default the maximum is set to a very arge value and high resolution visuals will not be resized, unless resolution exceeds `processor.max_pixels`.
+- The processor has its own [`~ProcessorMixin.apply_chat_template`] method to convert chat messages to model inputs.
+
+
+## Usage example
+
+`Qwen2.5-Omni` can be found on the [Huggingface Hub](https://huggingface.co/Qwen).
+
+### Single Media inference
+
+The model can accept text, images, audio and videos as input. Here's an example code for inference.
+
+```python
+import soundfile as sf
+from transformers import Qwen2_5OmniForConditionalGeneration, Qwen2_5OmniProcessor
+
+model = Qwen2_5OmniForConditionalGeneration.from_pretrained(
+ "Qwen/Qwen2.5-Omni-7B",
+ torch_dtype="auto",
+ device_map="auto"
+)
+processor = Qwen2_5OmniProcessor.from_pretrained("Qwen/Qwen2.5-Omni-7B")
+
+conversations = [
+ {
+ "role": "system",
+ "content": [
+ {"type": "text", "text": "You are Qwen, a virtual human developed by the Qwen Team, Alibaba Group, capable of perceiving auditory and visual inputs, as well as generating text and speech."}
+ ],
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "video", "video": "/path/to/video.mp4"},
+ {"type": "text", "text": "What cant you hear and see in this video?"},
+ ],
+ },
+]
+
+inputs = processor.apply_chat_template(
+ conversations,
+ load_audio_from_video=True,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+ video_fps=1,
+
+ # kwargs to be passed to `Qwen2-5-OmniProcessor`
+ padding=True,
+ use_audio_in_video=True,
+).to(model.device)
+
+# Generation params for audio or text can be different and have to be prefixed with `thinker_` or `talker_`
+text_ids, audio = model.generate(**inputs, use_audio_in_video=True, thinker_do_sample=False, talker_do_sample=True)
+text = processor.batch_decode(text_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)
+
+sf.write(
+ "output.wav",
+ audio.reshape(-1).detach().cpu().numpy(),
+ samplerate=24000,
+)
+print(text)
+```
+
+### Text-only generation
+
+To generate only text output and save compute by not loading the audio generation model, we can use `Qwen2_5OmniThinkerForConditionalGeneration` model.
+
+```python
+from transformers import Qwen2_5OmniThinkerForConditionalGeneration, Qwen2_5OmniProcessor
+
+model = Qwen2_5OmniThinkerForConditionalGeneration.from_pretrained(
+ "Qwen/Qwen2.5-Omni-7B",
+ torch_dtype="auto",
+ device_map="auto",
+)
+processor = Qwen2_5OmniProcessor.from_pretrained("Qwen/Qwen2.5-Omni-7B")
+
+conversations = [
+ {
+ "role": "system",
+ "content": [
+ {"type": "text", "text": "You are Qwen, a virtual human developed by the Qwen Team, Alibaba Group, capable of perceiving auditory and visual inputs, as well as generating text and speech."}
+ ],
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "video", "video": "/path/to/video.mp4"},
+ {"type": "text", "text": "What cant you hear and see in this video?"},
+ ],
+ },
+]
+
+inputs = processor.apply_chat_template(
+ conversations,
+ load_audio_from_video=True,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+ video_fps=1,
+
+ # kwargs to be passed to `Qwen2-5-OmniProcessor`
+ padding=True,
+ use_audio_in_video=True,
+).to(model.device)
+
+
+text_ids = model.generate(**inputs, use_audio_in_video=True)
+text = processor.batch_decode(text_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)
+
+sf.write(
+ "output.wav",
+ audio.reshape(-1).detach().cpu().numpy(),
+ samplerate=24000,
+)
+print(text)
+```
+
+### Batch Mixed Media Inference
+
+The model can batch inputs composed of mixed samples of various types such as text, images, audio and videos as input when using `Qwen2_5OmniThinkerForConditionalGeneration` model. Here is an example.
+
+```python
+import soundfile as sf
+from transformers import Qwen2_5OmniForConditionalGeneration, Qwen2_5OmniProcessor
+
+model = Qwen2_5OmniForConditionalGeneration.from_pretrained(
+ "Qwen/Qwen2.5-Omni-7B",
+ torch_dtype="auto",
+ device_map="auto"
+)
+processor = Qwen2_5OmniProcessor.from_pretrained("Qwen/Qwen2.5-Omni-7B")
+
+# Conversation with video only
+conversation1 = [
+ {
+ "role": "system",
+ "content": [
+ {"type": "text", "text": "You are Qwen, a virtual human developed by the Qwen Team, Alibaba Group, capable of perceiving auditory and visual inputs, as well as generating text and speech."}
+ ],
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "video", "path": "/path/to/video.mp4"},
+ ]
+ }
+]
+
+# Conversation with audio only
+conversation2 = [
+ {
+ "role": "system",
+ "content": [
+ {"type": "text", "text": "You are Qwen, a virtual human developed by the Qwen Team, Alibaba Group, capable of perceiving auditory and visual inputs, as well as generating text and speech."}
+ ],
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "audio", "path": "/path/to/audio.wav"},
+ ]
+ }
+]
+
+# Conversation with pure text
+conversation3 = [
+ {
+ "role": "system",
+ "content": [
+ {"type": "text", "text": "You are Qwen, a virtual human developed by the Qwen Team, Alibaba Group, capable of perceiving auditory and visual inputs, as well as generating text and speech."}
+ ],
+ },
+ {
+ "role": "user",
+ "content": [{"type": "text", "text": "who are you?"}],
+ }
+]
+
+
+# Conversation with mixed media
+conversation4 = [
+ {
+ "role": "system",
+ "content": [
+ {"type": "text", "text": "You are Qwen, a virtual human developed by the Qwen Team, Alibaba Group, capable of perceiving auditory and visual inputs, as well as generating text and speech."}
+ ],
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "path": "/path/to/image.jpg"},
+ {"type": "video", "path": "/path/to/video.mp4"},
+ {"type": "audio", "path": "/path/to/audio.wav"},
+ {"type": "text", "text": "What are the elements can you see and hear in these medias?"},
+ ],
+ }
+]
+
+conversations = [conversation1, conversation2, conversation3, conversation4]
+
+inputs = processor.apply_chat_template(
+ conversations,
+ load_audio_from_video=True,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+ video_fps=1,
+
+ # kwargs to be passed to `Qwen2-5-OmniProcessor`
+ padding=True,
+ use_audio_in_video=True,
+).to(model.thinker.device)
+
+text_ids = model.generate(**inputs, use_audio_in_video=True)
+text = processor.batch_decode(text_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)
+
+print(text)
+```
+
+### Usage Tips
+
+#### Image Resolution trade-off
+
+The model supports a wide range of resolution inputs. By default, it uses the native resolution for input, but higher resolutions can enhance performance at the cost of more computation. Users can set the minimum and maximum number of pixels to achieve an optimal configuration for their needs.
+
+```python
+min_pixels = 128*28*28
+max_pixels = 768*28*28
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2.5-Omni-7B", min_pixels=min_pixels, max_pixels=max_pixels)
+```
+
+#### Prompt for audio output
+If users need audio output, the system prompt must be set as "You are Qwen, a virtual human developed by the Qwen Team, Alibaba Group, capable of perceiving auditory and visual inputs, as well as generating text and speech.", otherwise the audio output may not work as expected.
+```
+{
+ "role": "system",
+ "content": "You are Qwen, a virtual human developed by the Qwen Team, Alibaba Group, capable of perceiving auditory and visual inputs, as well as generating text and speech.",
+}
+```
+
+#### Use audio output or not
+
+The model supports both text and audio outputs, if users do not need audio outputs, they can set `enable_audio_output` in the `from_pretrained` function. This option will save about `~2GB` of GPU memory but the `return_audio` option for `generate` function will only allow to be set at `False`.
+```python
+model = Qwen2_5OmniForConditionalGeneration.from_pretrained(
+ "Qwen/Qwen2.5-Omni-7B",
+ torch_dtype="auto",
+ device_map="auto",
+ enable_audio_output=False,
+)
+```
+
+In order to obtain a flexible experience, we recommend that users set `enable_audio_output` at `True` when initializing the model through `from_pretrained` function, and then decide whether to return audio when `generate` function is called. When `return_audio` is set to `False`, the model will only return text outputs to get text responses faster.
+
+```python
+model = Qwen2_5OmniForConditionalGeneration.from_pretrained(
+ "Qwen/Qwen2.5-Omni-7B",
+ torch_dtype="auto",
+ device_map="auto",
+ enable_audio_output=True,
+)
+...
+text_ids = model.generate(**inputs, return_audio=False)
+```
+
+#### Change voice type of output audio
+Qwen2.5-Omni supports the ability to change the voice of the output audio. Users can use the `spk` parameter of `generate` function to specify the voice type. The `"Qwen/Qwen2.5-Omni-7B"` checkpoint support two voice types: `Chelsie` and `Ethan`, while `Chelsie` is a female voice and `Ethan` is a male voice. By default, if `spk` is not specified, the default voice type is `Chelsie`.
+
+```python
+text_ids, audio = model.generate(**inputs, spk="Chelsie")
+```
+
+```python
+text_ids, audio = model.generate(**inputs, spk="Ethan")
+```
+
+#### Flash-Attention 2 to speed up generation
+
+First, make sure to install the latest version of Flash Attention 2:
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Also, you should have hardware that is compatible with FlashAttention 2. Read more about it in the official documentation of the [flash attention repository](https://github.com/Dao-AILab/flash-attention). FlashAttention-2 can only be used when a model is loaded in `torch.float16` or `torch.bfloat16`.
+
+To load and run a model using FlashAttention-2, add `attn_implementation="flash_attention_2"` when loading the model:
+
+```python
+from transformers import Qwen2_5OmniForConditionalGeneration
+
+model = Qwen2_5OmniForConditionalGeneration.from_pretrained(
+ "Qwen/Qwen2.5-Omni-7B",
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+)
+```
+
+
+
+## Qwen2_5OmniConfig
+
+[[autodoc]] Qwen2_5OmniConfig
+
+## Qwen2_5OmniProcessor
+
+[[autodoc]] Qwen2_5OmniProcessor
+
+## Qwen2_5OmniForConditionalGeneration
+
+[[autodoc]] Qwen2_5OmniForConditionalGeneration
+ - forward
+
+## Qwen2_5OmniPreTrainedModelForConditionalGeneration
+
+[[autodoc]] Qwen2_5OmniPreTrainedModelForConditionalGeneration
+
+## Qwen2_5OmniThinkerConfig
+
+[[autodoc]] Qwen2_5OmniThinkerConfig
+
+## Qwen2_5OmniThinkerForConditionalGeneration
+
+[[autodoc]] Qwen2_5OmniThinkerForConditionalGeneration
+
+## Qwen2_5OmniThinkerTextModel
+
+[[autodoc]] Qwen2_5OmniThinkerTextModel
+
+## Qwen2_5OmniTalkerConfig
+
+[[autodoc]] Qwen2_5OmniTalkerConfig
+
+## Qwen2_5OmniTalkerForConditionalGeneration
+
+[[autodoc]] Qwen2_5OmniTalkerForConditionalGeneration
+
+## Qwen2_5OmniTalkerModel
+
+[[autodoc]] Qwen2_5OmniTalkerModel
+
+## Qwen2_5OmniToken2WavConfig
+
+[[autodoc]] Qwen2_5OmniToken2WavConfig
+
+## Qwen2_5OmniToken2WavModel
+
+[[autodoc]] Qwen2_5OmniToken2WavModel
+
+## Qwen2_5OmniToken2WavDiTModel
+
+[[autodoc]] Qwen2_5OmniToken2WavDiTModel
+
+## Qwen2_5OmniToken2WavBigVGANModel
+
+[[autodoc]] Qwen2_5OmniToken2WavBigVGANModel
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2_5_vl.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2_5_vl.md
new file mode 100644
index 0000000000000000000000000000000000000000..df4244ffa59f6b3d193177ea359df4bf7e55c7e4
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2_5_vl.md
@@ -0,0 +1,257 @@
+
+*This model was released on 2025-02-19 and added to Hugging Face Transformers on 2025-01-23.*
+
+
+
+
+
+
+
+
+# Qwen2.5-VL
+
+[Qwen2.5-VL](https://huggingface.co/papers/2502.13923) is a multimodal vision-language model, available in 3B, 7B, and 72B parameters, pretrained on 4.1T tokens. The model introduces window attention in the ViT encoder to accelerate training and inference, dynamic FPS sampling on the spatial and temporal dimensions for better video understanding across different sampling rates, and an upgraded MRoPE (multi-resolutional rotary positional encoding) mechanism to better capture and learn temporal dynamics.
+
+
+You can find all the original Qwen2.5-VL checkpoints under the [Qwen2.5-VL](https://huggingface.co/collections/Qwen/qwen25-vl-6795ffac22b334a837c0f9a5) collection.
+
+> [!TIP]
+> Click on the Qwen2.5-VL models in the right sidebar for more examples of how to apply Qwen2.5-VL to different vision and language tasks.
+
+The example below demonstrates how to generate text based on an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+pipe = pipeline(
+ task="image-text-to-text",
+ model="Qwen/Qwen2.5-VL-7B-Instruct",
+ device=0,
+ torch_dtype=torch.bfloat16
+)
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {
+ "type": "image",
+ "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg",
+ },
+ { "type": "text", "text": "Describe this image."},
+ ]
+ }
+]
+pipe(text=messages,max_new_tokens=20, return_full_text=False)
+
+```
+
+
+
+
+```py
+import torch
+from transformers import Qwen2_5_VLForConditionalGeneration, AutoProcessor
+
+model = Qwen2_5_VLForConditionalGeneration.from_pretrained(
+ "Qwen/Qwen2.5-VL-7B-Instruct",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2.5-VL-7B-Instruct")
+messages = [
+ {
+ "role":"user",
+ "content":[
+ {
+ "type":"image",
+ "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+ },
+ {
+ "type":"text",
+ "text":"Describe this image."
+ }
+ ]
+ }
+
+]
+
+inputs = processor.apply_chat_template(
+ messages,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+).to("cuda")
+
+generated_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids_trimmed = [
+ out_ids[len(in_ids) :] for in_ids, out_ids in zip(inputs.input_ids, generated_ids)
+]
+output_text = processor.batch_decode(
+ generated_ids_trimmed, skip_special_tokens=True, clean_up_tokenization_spaces=False
+)
+print(output_text)
+```
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [torchao](../quantization/torchao) to only quantize the weights to int4.
+
+```python
+import torch
+from transformers import TorchAoConfig, Qwen2_5_VLForConditionalGeneration, AutoProcessor
+
+quantization_config = TorchAoConfig("int4_weight_only", group_size=128)
+model = Qwen2_5_VLForConditionalGeneration.from_pretrained(
+ "Qwen/Qwen2.5-VL-7B-Instruct",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+```
+### Notes
+
+- Use Qwen2.5-VL for video inputs by setting `"type": "video"` as shown below.
+ ```python
+ conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "video", "path": "/path/to/video.mp4"},
+ {"type": "text", "text": "What happened in the video?"},
+ ],
+ }
+ ]
+
+ inputs = processor.apply_chat_template(
+ conversation,
+ video_fps=1,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+ ).to(model.device)
+
+ # Inference: Generation of the output
+ output_ids = model.generate(**inputs, max_new_tokens=128)
+ generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(inputs.input_ids, output_ids)]
+ output_text = processor.batch_decode(generated_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+ print(output_text)
+ ```
+- Use Qwen2.5-VL for a mixed batch of inputs (images, videos, text). Add labels when handling multiple images or videos for better reference
+ as show below.
+ ```python
+ import torch
+ from transformers import Qwen2_5_VLForConditionalGeneration, AutoProcessor
+
+ model = Qwen2_5_VLForConditionalGeneration.from_pretrained(
+ "Qwen/Qwen2.5-VL-7B-Instruct",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+ )
+ processor = AutoProcessor.from_pretrained("Qwen/Qwen2.5-VL-7B-Instruct")
+ conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "Hello, how are you?"}
+ ]
+ },
+ {
+ "role": "assistant",
+ "content": "I'm doing well, thank you for asking. How can I assist you today?"
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Can you describe these images and video?"},
+ {"type": "image"},
+ {"type": "image"},
+ {"type": "video"},
+ {"type": "text", "text": "These are from my vacation."}
+ ]
+ },
+ {
+ "role": "assistant",
+ "content": "I'd be happy to describe the images and video for you. Could you please provide more context about your vacation?"
+ },
+ {
+ "role": "user",
+ "content": "It was a trip to the mountains. Can you see the details in the images and video?"
+ }
+ ]
+
+ # default:
+ prompt_without_id = processor.apply_chat_template(conversation, add_generation_prompt=True)
+ # Excepted output: '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n<|im_start|>user\n<|vision_start|><|image_pad|><|vision_end|>Hello, how are you?<|im_end|>\n<|im_start|>assistant\nI'm doing well, thank you for asking. How can I assist you today?<|im_end|>\n<|im_start|>user\nCan you describe these images and video?<|vision_start|><|image_pad|><|vision_end|><|vision_start|><|image_pad|><|vision_end|><|vision_start|><|video_pad|><|vision_end|>These are from my vacation.<|im_end|>\n<|im_start|>assistant\nI'd be happy to describe the images and video for you. Could you please provide more context about your vacation?<|im_end|>\n<|im_start|>user\nIt was a trip to the mountains. Can you see the details in the images and video?<|im_end|>\n<|im_start|>assistant\n'
+
+
+ # add ids
+ prompt_with_id = processor.apply_chat_template(conversation, add_generation_prompt=True, add_vision_id=True)
+ # Excepted output: '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n<|im_start|>user\nPicture 1: <|vision_start|><|image_pad|><|vision_end|>Hello, how are you?<|im_end|>\n<|im_start|>assistant\nI'm doing well, thank you for asking. How can I assist you today?<|im_end|>\n<|im_start|>user\nCan you describe these images and video?Picture 2: <|vision_start|><|image_pad|><|vision_end|>Picture 3: <|vision_start|><|image_pad|><|vision_end|>Video 1: <|vision_start|><|video_pad|><|vision_end|>These are from my vacation.<|im_end|>\n<|im_start|>assistant\nI'd be happy to describe the images and video for you. Could you please provide more context about your vacation?<|im_end|>\n<|im_start|>user\nIt was a trip to the mountains. Can you see the details in the images and video?<|im_end|>\n<|im_start|>assistant\n'
+ ```
+
+- Use the `min_pixels` and `max_pixels` parameters in [`AutoProcessor`] to set the resolution.
+
+ ```python
+ min_pixels = 224*224
+ max_pixels = 2048*2048
+ processor = AutoProcessor.from_pretrained("Qwen/Qwen2.5-VL-7B-Instruct", min_pixels=min_pixels, max_pixels=max_pixels)
+ ```
+
+ Higher resolution can require more compute whereas reducing the resolution can save memory as follows:
+
+ ```python
+ min_pixels = 256*28*28
+ max_pixels = 1024*28*28
+ processor = AutoProcessor.from_pretrained("Qwen/Qwen2.5-VL-7B-Instruct", min_pixels=min_pixels, max_pixels=max_pixels)
+ ```
+## Qwen2_5_VLConfig
+
+[[autodoc]] Qwen2_5_VLConfig
+
+## Qwen2_5_VLTextConfig
+
+[[autodoc]] Qwen2_5_VLTextConfig
+
+## Qwen2_5_VLProcessor
+
+[[autodoc]] Qwen2_5_VLProcessor
+
+## Qwen2_5_VLTextModel
+
+[[autodoc]] Qwen2_5_VLTextModel
+ - forward
+
+## Qwen2_5_VLModel
+
+[[autodoc]] Qwen2_5_VLModel
+ - forward
+
+## Qwen2_5_VLForConditionalGeneration
+
+[[autodoc]] Qwen2_5_VLForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2_audio.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2_audio.md
new file mode 100644
index 0000000000000000000000000000000000000000..cd52b5bac3594005fc103662ba318fb575e8474d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2_audio.md
@@ -0,0 +1,244 @@
+
+*This model was released on 2024-07-15 and added to Hugging Face Transformers on 2024-08-08.*
+
+# Qwen2Audio
+
+
+
+
+
+
+
+## Overview
+
+The Qwen2-Audio is the new model series of large audio-language models from the Qwen team. Qwen2-Audio is capable of accepting various audio signal inputs and performing audio analysis or direct textual responses with regard to speech instructions. We introduce two distinct audio interaction modes:
+
+* voice chat: users can freely engage in voice interactions with Qwen2-Audio without text input
+* audio analysis: users could provide audio and text instructions for analysis during the interaction
+
+It was proposed in [Qwen2-Audio Technical Report](https://huggingface.co/papers/2407.10759) by Yunfei Chu, Jin Xu, Qian Yang, Haojie Wei, Xipin Wei, Zhifang Guo, Yichong Leng, Yuanjun Lv, Jinzheng He, Junyang Lin, Chang Zhou, Jingren Zhou.
+
+The abstract from the paper is the following:
+
+*We introduce the latest progress of Qwen-Audio, a large-scale audio-language model called Qwen2-Audio, which is capable of accepting various audio signal inputs and performing audio analysis or direct textual responses with regard to speech instructions. In contrast to complex hierarchical tags, we have simplified the pre-training process by utilizing natural language prompts for different data and tasks, and have further expanded the data volume. We have boosted the instruction-following capability of Qwen2-Audio and implemented two distinct audio interaction modes for voice chat and audio analysis. In the voice chat mode, users can freely engage in voice interactions with Qwen2-Audio without text input. In the audio analysis mode, users could provide audio and text instructions for analysis during the interaction. Note that we do not use any system prompts to switch between voice chat and audio analysis modes. Qwen2-Audio is capable of intelligently comprehending the content within audio and following voice commands to respond appropriately. For instance, in an audio segment that simultaneously contains sounds, multi-speaker conversations, and a voice command, Qwen2-Audio can directly understand the command and provide an interpretation and response to the audio. Additionally, DPO has optimized the model's performance in terms of factuality and adherence to desired behavior. According to the evaluation results from AIR-Bench, Qwen2-Audio outperformed previous SOTAs, such as Gemini-1.5-pro, in tests focused on audio-centric instruction-following capabilities. Qwen2-Audio is open-sourced with the aim of fostering the advancement of the multi-modal language community. *
+
+
+## Usage tips
+
+`Qwen2-Audio-7B` and `Qwen2-Audio-7B-Instruct` can be found on the [Huggingface Hub](https://huggingface.co/Qwen)
+
+> [!NOTE]
+> The `head_mask` argument is ignored when using all attention implementation other than "eager". If you have a `head_mask` and want it to have effect, load the model with `XXXModel.from_pretrained(model_id, attn_implementation="eager")`
+
+### Inference
+
+```python
+from io import BytesIO
+from urllib.request import urlopen
+import librosa
+from transformers import AutoProcessor, Qwen2AudioForConditionalGeneration
+
+model = Qwen2AudioForConditionalGeneration.from_pretrained("Qwen/Qwen2-Audio-7B", trust_remote_code=True, device_map="auto")
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-Audio-7B", trust_remote_code=True)
+
+prompt = "<|audio_bos|><|AUDIO|><|audio_eos|>Generate the caption in English:"
+url = "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-Audio/glass-breaking-151256.mp3"
+audio, sr = librosa.load(BytesIO(urlopen(url).read()), sr=processor.feature_extractor.sampling_rate)
+inputs = processor(text=prompt, audios=audio, return_tensors="pt").to(model.device)
+
+generate_ids = model.generate(**inputs, max_length=256)
+generate_ids = generate_ids[:, inputs.input_ids.size(1):]
+
+response = processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
+
+# We can also omit the audio_bos and audio_eos tokens
+prompt = "<|AUDIO|>Generate the caption in English:"
+inputs = processor(text=prompt, audios=audio, return_tensors="pt").to(model.device)
+
+generate_ids = model.generate(**inputs, max_length=256)
+generate_ids = generate_ids[:, inputs.input_ids.size(1):]
+
+response = processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
+```
+
+In the following, we demonstrate how to use `Qwen2-Audio-7B-Instruct` for the inference, supporting both voice chat and audio analysis modes. Note that we have used the ChatML format for dialog, in this demo we show how to leverage `apply_chat_template` for this purpose.
+
+### Voice Chat Inference
+In the voice chat mode, users can freely engage in voice interactions with Qwen2-Audio without text input:
+```python
+from io import BytesIO
+from urllib.request import urlopen
+import librosa
+from transformers import Qwen2AudioForConditionalGeneration, AutoProcessor
+
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-Audio-7B-Instruct")
+model = Qwen2AudioForConditionalGeneration.from_pretrained("Qwen/Qwen2-Audio-7B-Instruct", device_map="auto")
+
+conversation = [
+ {"role": "user", "content": [
+ {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/guess_age_gender.wav"},
+ ]},
+ {"role": "assistant", "content": "Yes, the speaker is female and in her twenties."},
+ {"role": "user", "content": [
+ {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/translate_to_chinese.wav"},
+ ]},
+]
+text = processor.apply_chat_template(conversation, add_generation_prompt=True, tokenize=False)
+audios = []
+for message in conversation:
+ if isinstance(message["content"], list):
+ for ele in message["content"]:
+ if ele["type"] == "audio":
+ audios.append(librosa.load(
+ BytesIO(urlopen(ele['audio_url']).read()),
+ sr=processor.feature_extractor.sampling_rate)[0]
+ )
+
+inputs = processor(text=text, audios=audios, return_tensors="pt", padding=True)
+inputs.input_ids = inputs.input_ids.to("cuda")
+
+generate_ids = model.generate(**inputs, max_length=256)
+generate_ids = generate_ids[:, inputs.input_ids.size(1):]
+
+response = processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
+```
+
+### Audio Analysis Inference
+In the audio analysis, users could provide both audio and text instructions for analysis:
+```python
+from io import BytesIO
+from urllib.request import urlopen
+import librosa
+from transformers import Qwen2AudioForConditionalGeneration, AutoProcessor
+
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-Audio-7B-Instruct")
+model = Qwen2AudioForConditionalGeneration.from_pretrained("Qwen/Qwen2-Audio-7B-Instruct", device_map="auto")
+
+conversation = [
+ {'role': 'system', 'content': 'You are a helpful assistant.'},
+ {"role": "user", "content": [
+ {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/glass-breaking-151256.mp3"},
+ {"type": "text", "text": "What's that sound?"},
+ ]},
+ {"role": "assistant", "content": "It is the sound of glass shattering."},
+ {"role": "user", "content": [
+ {"type": "text", "text": "What can you do when you hear that?"},
+ ]},
+ {"role": "assistant", "content": "Stay alert and cautious, and check if anyone is hurt or if there is any damage to property."},
+ {"role": "user", "content": [
+ {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/1272-128104-0000.flac"},
+ {"type": "text", "text": "What does the person say?"},
+ ]},
+]
+text = processor.apply_chat_template(conversation, add_generation_prompt=True, tokenize=False)
+audios = []
+for message in conversation:
+ if isinstance(message["content"], list):
+ for ele in message["content"]:
+ if ele["type"] == "audio":
+ audios.append(
+ librosa.load(
+ BytesIO(urlopen(ele['audio_url']).read()),
+ sr=processor.feature_extractor.sampling_rate)[0]
+ )
+
+inputs = processor(text=text, audios=audios, return_tensors="pt", padding=True)
+inputs.input_ids = inputs.input_ids.to("cuda")
+
+generate_ids = model.generate(**inputs, max_length=256)
+generate_ids = generate_ids[:, inputs.input_ids.size(1):]
+
+response = processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)[0]
+```
+
+### Batch Inference
+We also support batch inference:
+```python
+from io import BytesIO
+from urllib.request import urlopen
+import librosa
+from transformers import Qwen2AudioForConditionalGeneration, AutoProcessor
+
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-Audio-7B-Instruct")
+model = Qwen2AudioForConditionalGeneration.from_pretrained("Qwen/Qwen2-Audio-7B-Instruct", device_map="auto")
+
+conversation1 = [
+ {"role": "user", "content": [
+ {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/glass-breaking-151256.mp3"},
+ {"type": "text", "text": "What's that sound?"},
+ ]},
+ {"role": "assistant", "content": "It is the sound of glass shattering."},
+ {"role": "user", "content": [
+ {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/f2641_0_throatclearing.wav"},
+ {"type": "text", "text": "What can you hear?"},
+ ]}
+]
+
+conversation2 = [
+ {"role": "user", "content": [
+ {"type": "audio", "audio_url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen2-Audio/audio/1272-128104-0000.flac"},
+ {"type": "text", "text": "What does the person say?"},
+ ]},
+]
+
+conversations = [conversation1, conversation2]
+
+text = [processor.apply_chat_template(conversation, add_generation_prompt=True, tokenize=False) for conversation in conversations]
+
+audios = []
+for conversation in conversations:
+ for message in conversation:
+ if isinstance(message["content"], list):
+ for ele in message["content"]:
+ if ele["type"] == "audio":
+ audios.append(
+ librosa.load(
+ BytesIO(urlopen(ele['audio_url']).read()),
+ sr=processor.feature_extractor.sampling_rate)[0]
+ )
+
+inputs = processor(text=text, audios=audios, return_tensors="pt", padding=True)
+inputs['input_ids'] = inputs['input_ids'].to("cuda")
+inputs.input_ids = inputs.input_ids.to("cuda")
+
+generate_ids = model.generate(**inputs, max_length=256)
+generate_ids = generate_ids[:, inputs.input_ids.size(1):]
+
+response = processor.batch_decode(generate_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False)
+```
+
+## Qwen2AudioConfig
+
+[[autodoc]] Qwen2AudioConfig
+
+## Qwen2AudioEncoderConfig
+
+[[autodoc]] Qwen2AudioEncoderConfig
+
+## Qwen2AudioProcessor
+
+[[autodoc]] Qwen2AudioProcessor
+
+## Qwen2AudioEncoder
+
+[[autodoc]] Qwen2AudioEncoder
+ - forward
+
+## Qwen2AudioForConditionalGeneration
+
+[[autodoc]] Qwen2AudioForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2_moe.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2_moe.md
new file mode 100644
index 0000000000000000000000000000000000000000..fcef002c2614e45a0c42dcffd5fe80876479699f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2_moe.md
@@ -0,0 +1,166 @@
+
+*This model was released on 2024-07-15 and added to Hugging Face Transformers on 2024-03-27.*
+
+
+
+
+
+
+
+
+# Qwen2MoE
+
+
+[Qwen2MoE](https://huggingface.co/papers/2407.10671) is a Mixture-of-Experts (MoE) variant of [Qwen2](./qwen2), available as a base model and an aligned chat model. It uses SwiGLU activation, group query attention and a mixture of sliding window attention and full attention. The tokenizer can also be adapted to multiple languages and codes.
+
+The MoE architecture uses upcyled models from the dense language models. For example, Qwen1.5-MoE-A2.7B is upcycled from Qwen-1.8B. It has 14.3B parameters but only 2.7B parameters are activated during runtime.
+
+You can find all the original checkpoints in the [Qwen1.5](https://huggingface.co/collections/Qwen/qwen15-65c0a2f577b1ecb76d786524) collection.
+
+> [!TIP]
+> Click on the Qwen2MoE models in the right sidebar for more examples of how to apply Qwen2MoE to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipe = pipeline(
+ task="text-generation",
+ model="Qwen/Qwen1.5-MoE-A2.7B",
+ torch_dtype=torch.bfloat16,
+ device_map=0
+)
+
+messages = [
+ {"role": "system", "content": "You are a helpful assistant."},
+ {"role": "user", "content": "Tell me about the Qwen2 model family."},
+]
+outputs = pipe(messages, max_new_tokens=256, do_sample=True, temperature=0.7, top_k=50, top_p=0.95)
+print(outputs[0]["generated_text"][-1]['content'])
+```
+
+
+
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained(
+ "Qwen/Qwen1.5-MoE-A2.7B-Chat",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen1.5-MoE-A2.7B-Chat")
+
+prompt = "Give me a short introduction to large language models."
+messages = [
+ {"role": "system", "content": "You are a helpful assistant."},
+ {"role": "user", "content": prompt}
+]
+text = tokenizer.apply_chat_template(
+ messages,
+ tokenize=False,
+ add_generation_prompt=True
+)
+model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
+
+generated_ids = model.generate(
+ model_inputs.input_ids,
+ cache_implementation="static",
+ max_new_tokens=512,
+ do_sample=True,
+ temperature=0.7,
+ top_k=50,
+ top_p=0.95
+)
+generated_ids = [
+ output_ids[len(input_ids):] for input_ids, output_ids in zip(model_inputs.input_ids, generated_ids)
+]
+
+response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+print(response)
+```
+
+
+```bash
+transformers chat Qwen/Qwen1.5-MoE-A2.7B-Chat --torch_dtype auto --attn_implementation flash_attention_2
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to quantize the weights to 8-bits.
+
+```python
+# pip install -U flash-attn --no-build-isolation
+import torch
+from transformers import AutoTokenizer, AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(
+ load_in_8bit=True
+)
+
+tokenizer = AutoTokenizer.from_pretrained("Qwen/Qwen1.5-MoE-A2.7B-Chat")
+model = AutoModelForCausalLM.from_pretrained(
+ "Qwen/Qwen1.5-MoE-A2.7B-Chat",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config,
+ attn_implementation="flash_attention_2"
+)
+
+inputs = tokenizer("The Qwen2 model family is", return_tensors="pt").to(model.device)
+outputs = model.generate(**inputs, max_new_tokens=100)
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+## Qwen2MoeConfig
+
+[[autodoc]] Qwen2MoeConfig
+
+## Qwen2MoeModel
+
+[[autodoc]] Qwen2MoeModel
+ - forward
+
+## Qwen2MoeForCausalLM
+
+[[autodoc]] Qwen2MoeForCausalLM
+ - forward
+
+## Qwen2MoeForSequenceClassification
+
+[[autodoc]] Qwen2MoeForSequenceClassification
+ - forward
+
+## Qwen2MoeForTokenClassification
+
+[[autodoc]] Qwen2MoeForTokenClassification
+ - forward
+
+## Qwen2MoeForQuestionAnswering
+
+[[autodoc]] Qwen2MoeForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2_vl.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2_vl.md
new file mode 100644
index 0000000000000000000000000000000000000000..7b6a2910f85f7862875d1f65d6279efc03272661
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen2_vl.md
@@ -0,0 +1,319 @@
+
+*This model was released on 2024-08-29 and added to Hugging Face Transformers on 2024-08-26.*
+
+# Qwen2-VL
+
+
+
+
+
+
+
+## Overview
+
+The [Qwen2-VL](https://huggingface.co/papers/2409.12191) ([blog post](https://qwenlm.github.io/blog/qwen2-vl/)) model is a major update to [Qwen-VL](https://huggingface.co/papers/2308.12966) from the Qwen team at Alibaba Research.
+
+The abstract from the blog is the following:
+
+*This blog introduces Qwen2-VL, an advanced version of the Qwen-VL model that has undergone significant enhancements over the past year. Key improvements include enhanced image comprehension, advanced video understanding, integrated visual agent functionality, and expanded multilingual support. The model architecture has been optimized for handling arbitrary image resolutions through Naive Dynamic Resolution support and utilizes Multimodal Rotary Position Embedding (M-ROPE) to effectively process both 1D textual and multi-dimensional visual data. This updated model demonstrates competitive performance against leading AI systems like GPT-4o and Claude 3.5 Sonnet in vision-related tasks and ranks highly among open-source models in text capabilities. These advancements make Qwen2-VL a versatile tool for various applications requiring robust multimodal processing and reasoning abilities.*
+
+
+
+ Qwen2-VL architecture. Taken from the blog post.
+
+This model was contributed by [simonJJJ](https://huggingface.co/simonJJJ).
+
+## Usage example
+
+### Single Media inference
+
+The model can accept both images and videos as input. Here's an example code for inference.
+
+```python
+
+import torch
+from transformers import Qwen2VLForConditionalGeneration, AutoTokenizer, AutoProcessor
+
+# Load the model in half-precision on the available device(s)
+model = Qwen2VLForConditionalGeneration.from_pretrained("Qwen/Qwen2-VL-7B-Instruct", device_map="auto")
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-VL-7B-Instruct")
+
+
+conversation = [
+ {
+ "role":"user",
+ "content":[
+ {
+ "type":"image",
+ "url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-VL/assets/demo.jpeg"
+ },
+ {
+ "type":"text",
+ "text":"Describe this image."
+ }
+ ]
+ }
+]
+
+inputs = processor.apply_chat_template(
+ conversation,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+).to(model.device)
+
+# Inference: Generation of the output
+output_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(inputs.input_ids, output_ids)]
+output_text = processor.batch_decode(generated_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+print(output_text)
+
+
+
+# Video
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "video", "path": "/path/to/video.mp4"},
+ {"type": "text", "text": "What happened in the video?"},
+ ],
+ }
+]
+
+inputs = processor.apply_chat_template(
+ conversation,
+ video_fps=1,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+).to(model.device)
+
+
+# Inference: Generation of the output
+output_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(inputs.input_ids, output_ids)]
+output_text = processor.batch_decode(generated_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+print(output_text)
+```
+
+### Batch Mixed Media Inference
+
+The model can batch inputs composed of mixed samples of various types such as images, videos, and text. Here is an example.
+
+```python
+
+# Conversation for the first image
+conversation1 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "path": "/path/to/image1.jpg"},
+ {"type": "text", "text": "Describe this image."}
+ ]
+ }
+]
+
+# Conversation with two images
+conversation2 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "path": "/path/to/image2.jpg"},
+ {"type": "image", "path": "/path/to/image3.jpg"},
+ {"type": "text", "text": "What is written in the pictures?"}
+ ]
+ }
+]
+
+# Conversation with pure text
+conversation3 = [
+ {
+ "role": "user",
+ "content": "who are you?"
+ }
+]
+
+
+# Conversation with mixed midia
+conversation4 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "path": "/path/to/image3.jpg"},
+ {"type": "image", "path": "/path/to/image4.jpg"},
+ {"type": "video", "path": "/path/to/video.jpg"},
+ {"type": "text", "text": "What are the common elements in these medias?"},
+ ],
+ }
+]
+
+conversations = [conversation1, conversation2, conversation3, conversation4]
+# Preparation for batch inference
+ipnuts = processor.apply_chat_template(
+ conversations,
+ video_fps=1,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+).to(model.device)
+
+
+# Batch Inference
+output_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(inputs.input_ids, output_ids)]
+output_text = processor.batch_decode(generated_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+print(output_text)
+```
+
+### Usage Tips
+
+#### Image Resolution trade-off
+
+The model supports a wide range of resolution inputs. By default, it uses the native resolution for input, but higher resolutions can enhance performance at the cost of more computation. Users can set the minimum and maximum number of pixels to achieve an optimal configuration for their needs.
+
+```python
+min_pixels = 224*224
+max_pixels = 2048*2048
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-VL-7B-Instruct", min_pixels=min_pixels, max_pixels=max_pixels)
+```
+
+In case of limited GPU RAM, one can reduce the resolution as follows:
+
+```python
+min_pixels = 256*28*28
+max_pixels = 1024*28*28
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-VL-7B-Instruct", min_pixels=min_pixels, max_pixels=max_pixels)
+```
+This ensures each image gets encoded using a number between 256-1024 tokens. The 28 comes from the fact that the model uses a patch size of 14 and a temporal patch size of 2 (14 x 2 = 28).
+
+
+#### Multiple Image Inputs
+
+By default, images and video content are directly included in the conversation. When handling multiple images, it's helpful to add labels to the images and videos for better reference. Users can control this behavior with the following settings:
+
+```python
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "Hello, how are you?"}
+ ]
+ },
+ {
+ "role": "assistant",
+ "content": "I'm doing well, thank you for asking. How can I assist you today?"
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Can you describe these images and video?"},
+ {"type": "image"},
+ {"type": "image"},
+ {"type": "video"},
+ {"type": "text", "text": "These are from my vacation."}
+ ]
+ },
+ {
+ "role": "assistant",
+ "content": "I'd be happy to describe the images and video for you. Could you please provide more context about your vacation?"
+ },
+ {
+ "role": "user",
+ "content": "It was a trip to the mountains. Can you see the details in the images and video?"
+ }
+]
+
+# default:
+prompt_without_id = processor.apply_chat_template(conversation, add_generation_prompt=True)
+# Excepted output: '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n<|im_start|>user\n<|vision_start|><|image_pad|><|vision_end|>Hello, how are you?<|im_end|>\n<|im_start|>assistant\nI'm doing well, thank you for asking. How can I assist you today?<|im_end|>\n<|im_start|>user\nCan you describe these images and video?<|vision_start|><|image_pad|><|vision_end|><|vision_start|><|image_pad|><|vision_end|><|vision_start|><|video_pad|><|vision_end|>These are from my vacation.<|im_end|>\n<|im_start|>assistant\nI'd be happy to describe the images and video for you. Could you please provide more context about your vacation?<|im_end|>\n<|im_start|>user\nIt was a trip to the mountains. Can you see the details in the images and video?<|im_end|>\n<|im_start|>assistant\n'
+
+
+# add ids
+prompt_with_id = processor.apply_chat_template(conversation, add_generation_prompt=True, add_vision_id=True)
+# Excepted output: '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n<|im_start|>user\nPicture 1: <|vision_start|><|image_pad|><|vision_end|>Hello, how are you?<|im_end|>\n<|im_start|>assistant\nI'm doing well, thank you for asking. How can I assist you today?<|im_end|>\n<|im_start|>user\nCan you describe these images and video?Picture 2: <|vision_start|><|image_pad|><|vision_end|>Picture 3: <|vision_start|><|image_pad|><|vision_end|>Video 1: <|vision_start|><|video_pad|><|vision_end|>These are from my vacation.<|im_end|>\n<|im_start|>assistant\nI'd be happy to describe the images and video for you. Could you please provide more context about your vacation?<|im_end|>\n<|im_start|>user\nIt was a trip to the mountains. Can you see the details in the images and video?<|im_end|>\n<|im_start|>assistant\n'
+
+```
+
+#### Flash-Attention 2 to speed up generation
+
+First, make sure to install the latest version of Flash Attention 2:
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Also, you should have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of the [flash attention repository](https://github.com/Dao-AILab/flash-attention). FlashAttention-2 can only be used when a model is loaded in `torch.float16` or `torch.bfloat16`.
+
+To load and run a model using Flash Attention-2, simply add `attn_implementation="flash_attention_2"` when loading the model as follows:
+
+```python
+from transformers import Qwen2VLForConditionalGeneration
+
+model = Qwen2VLForConditionalGeneration.from_pretrained(
+ "Qwen/Qwen2-VL-7B-Instruct",
+ torch_dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+)
+```
+
+## Qwen2VLConfig
+
+[[autodoc]] Qwen2VLConfig
+
+## Qwen2VLTextConfig
+
+[[autodoc]] Qwen2VLTextConfig
+
+## Qwen2VLImageProcessor
+
+[[autodoc]] Qwen2VLImageProcessor
+ - preprocess
+
+## Qwen2VLVideoProcessor
+
+[[autodoc]] Qwen2VLVideoProcessor
+ - preprocess
+
+## Qwen2VLImageProcessorFast
+
+[[autodoc]] Qwen2VLImageProcessorFast
+ - preprocess
+
+## Qwen2VLProcessor
+
+[[autodoc]] Qwen2VLProcessor
+
+## Qwen2VLTextModel
+
+[[autodoc]] Qwen2VLTextModel
+ - forward
+
+## Qwen2VLModel
+
+[[autodoc]] Qwen2VLModel
+ - forward
+
+## Qwen2VLForConditionalGeneration
+
+[[autodoc]] Qwen2VLForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen3.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen3.md
new file mode 100644
index 0000000000000000000000000000000000000000..87e6ba500f969cbd1b5017e0cc6cb0776f3e97c2
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen3.md
@@ -0,0 +1,60 @@
+
+*This model was released on 2025-04-29 and added to Hugging Face Transformers on 2025-03-31.*
+
+# Qwen3
+
+## Overview
+
+[Qwen3](https://huggingface.co/papers/2505.09388) refers to the dense model architecture Qwen3-32B which was released with its mixture of experts variant [Qwen3MoE](qwen3_moe) ([blog post](https://qwenlm.github.io/blog/qwen3/)).
+
+### Model Details
+
+To be released with the official model launch.
+
+
+## Usage tips
+
+To be released with the official model launch.
+
+## Qwen3Config
+
+[[autodoc]] Qwen3Config
+
+## Qwen3Model
+
+[[autodoc]] Qwen3Model
+ - forward
+
+## Qwen3ForCausalLM
+
+[[autodoc]] Qwen3ForCausalLM
+ - forward
+
+## Qwen3ForSequenceClassification
+
+[[autodoc]] Qwen3ForSequenceClassification
+ - forward
+
+## Qwen3ForTokenClassification
+
+[[autodoc]] Qwen3ForTokenClassification
+ - forward
+
+## Qwen3ForQuestionAnswering
+
+[[autodoc]] Qwen3ForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen3_moe.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen3_moe.md
new file mode 100644
index 0000000000000000000000000000000000000000..2d1090f1e90a8598696cd07111479d6554c0ba63
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen3_moe.md
@@ -0,0 +1,59 @@
+
+*This model was released on 2025-04-29 and added to Hugging Face Transformers on 2025-03-31.*
+
+# Qwen3MoE
+
+## Overview
+
+[Qwen3MoE](https://huggingface.co/papers/2505.09388) refers to the mixture of experts model architecture Qwen3-235B-A22B which was released with its dense variant [Qwen3](qwen3) ([blog post](https://qwenlm.github.io/blog/qwen3/)).
+
+### Model Details
+
+To be released with the official model launch.
+
+## Usage tips
+
+To be released with the official model launch.
+
+## Qwen3MoeConfig
+
+[[autodoc]] Qwen3MoeConfig
+
+## Qwen3MoeModel
+
+[[autodoc]] Qwen3MoeModel
+ - forward
+
+## Qwen3MoeForCausalLM
+
+[[autodoc]] Qwen3MoeForCausalLM
+ - forward
+
+## Qwen3MoeForSequenceClassification
+
+[[autodoc]] Qwen3MoeForSequenceClassification
+ - forward
+
+## Qwen3MoeForTokenClassification
+
+[[autodoc]] Qwen3MoeForTokenClassification
+ - forward
+
+## Qwen3MoeForQuestionAnswering
+
+[[autodoc]] Qwen3MoeForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rag.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rag.md
new file mode 100644
index 0000000000000000000000000000000000000000..55de807ccd09e34cf99ff0a21cf2f5e5ba42754e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rag.md
@@ -0,0 +1,149 @@
+
+*This model was released on 2020-05-22 and added to Hugging Face Transformers on 2020-11-16.*
+
+# RAG
+
+
+
+
+
+
+
+
+
+[Retrieval-Augmented Generation (RAG)](https://huggingface.co/papers/2005.11401) combines a pretrained language model (parametric memory) with access to an external data source (non-parametric memory) by means of a pretrained neural retriever. RAG fetches relevant passages and conditions its generation on them during inference. This often makes the answers more factual and lets you update knowledge by changing the index instead of retraining the whole model.
+
+You can find all the original RAG checkpoints under the [AI at Meta](https://huggingface.co/facebook/models?search=rag) organization.
+
+> [!TIP]
+> This model was contributed by [ola13](https://huggingface.co/ola13).
+>
+> Click on the RAG models in the right sidebar for more examples of how to apply RAG to different language tasks.
+
+The examples below demonstrates how to generate text with [`AutoModel`].
+
+
+
+
+```py
+import torch
+from transformers import RagTokenizer, RagRetriever, RagSequenceForGeneration
+
+tokenizer = RagTokenizer.from_pretrained("facebook/rag-sequence-nq")
+retriever = RagRetriever.from_pretrained(
+ "facebook/dpr-ctx_encoder-single-nq-base", dataset="wiki_dpr", index_name="compressed"
+)
+
+model = RagSequenceForGeneration.from_pretrained(
+ "facebook/rag-token-nq",
+ retriever=retriever,
+ torch_dtype="auto",
+ attn_implementation="flash_attention_2",
+)
+input_dict = tokenizer.prepare_seq2seq_batch("How many people live in Paris?", return_tensors="pt")
+generated = model.generate(input_ids=input_dict["input_ids"])
+print(tokenizer.batch_decode(generated, skip_special_tokens=True)[0])
+```
+
+
+
+
+Quantization reduces memory by storing weights in lower precision. See the [Quantization](../quantization/overview) overview for supported backends.
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to quantize the weights to 4-bits.
+
+```py
+import torch
+from transformers import BitsAndBytesConfig, RagTokenizer, RagRetriever, RagSequenceForGeneration
+
+bnb = BitsAndBytesConfig(load_in_4bit=True, bnb_4bit_compute_dtype=torch.bfloat16)
+
+tokenizer = RagTokenizer.from_pretrained("facebook/rag-sequence-nq")
+retriever = RagRetriever.from_pretrained(
+ "facebook/dpr-ctx_encoder-single-nq-base", dataset="wiki_dpr", index_name="compressed"
+)
+
+model = RagSequenceForGeneration.from_pretrained(
+ "facebook/rag-token-nq",
+ retriever=retriever,
+ quantization_config=bnb, # quantizes generator weights
+ device_map="auto",
+)
+input_dict = tokenizer.prepare_seq2seq_batch("How many people live in Paris?", return_tensors="pt")
+generated = model.generate(input_ids=input_dict["input_ids"])
+print(tokenizer.batch_decode(generated, skip_special_tokens=True)[0])
+```
+
+## RagConfig
+
+[[autodoc]] RagConfig
+
+## RagTokenizer
+
+[[autodoc]] RagTokenizer
+
+## Rag specific outputs
+
+[[autodoc]] models.rag.modeling_rag.RetrievAugLMMarginOutput
+
+[[autodoc]] models.rag.modeling_rag.RetrievAugLMOutput
+
+## RagRetriever
+
+[[autodoc]] RagRetriever
+
+
+
+
+## RagModel
+
+[[autodoc]] RagModel
+ - forward
+
+## RagSequenceForGeneration
+
+[[autodoc]] RagSequenceForGeneration
+ - forward
+ - generate
+
+## RagTokenForGeneration
+
+[[autodoc]] RagTokenForGeneration
+ - forward
+ - generate
+
+
+
+
+## TFRagModel
+
+[[autodoc]] TFRagModel
+ - call
+
+## TFRagSequenceForGeneration
+
+[[autodoc]] TFRagSequenceForGeneration
+ - call
+ - generate
+
+## TFRagTokenForGeneration
+
+[[autodoc]] TFRagTokenForGeneration
+ - call
+ - generate
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/realm.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/realm.md
new file mode 100644
index 0000000000000000000000000000000000000000..da3d1c140f4c7ed068f383be4ea6f59de492eed5
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/realm.md
@@ -0,0 +1,102 @@
+
+*This model was released on 2020-02-10 and added to Hugging Face Transformers on 2023-06-20.*
+
+# REALM
+
+
+
+
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The REALM model was proposed in [REALM: Retrieval-Augmented Language Model Pre-Training](https://huggingface.co/papers/2002.08909) by Kelvin Guu, Kenton Lee, Zora Tung, Panupong Pasupat and Ming-Wei Chang. It's a
+retrieval-augmented language model that firstly retrieves documents from a textual knowledge corpus and then
+utilizes retrieved documents to process question answering tasks.
+
+The abstract from the paper is the following:
+
+*Language model pre-training has been shown to capture a surprising amount of world knowledge, crucial for NLP tasks
+such as question answering. However, this knowledge is stored implicitly in the parameters of a neural network,
+requiring ever-larger networks to cover more facts. To capture knowledge in a more modular and interpretable way, we
+augment language model pre-training with a latent knowledge retriever, which allows the model to retrieve and attend
+over documents from a large corpus such as Wikipedia, used during pre-training, fine-tuning and inference. For the
+first time, we show how to pre-train such a knowledge retriever in an unsupervised manner, using masked language
+modeling as the learning signal and backpropagating through a retrieval step that considers millions of documents. We
+demonstrate the effectiveness of Retrieval-Augmented Language Model pre-training (REALM) by fine-tuning on the
+challenging task of Open-domain Question Answering (Open-QA). We compare against state-of-the-art models for both
+explicit and implicit knowledge storage on three popular Open-QA benchmarks, and find that we outperform all previous
+methods by a significant margin (4-16% absolute accuracy), while also providing qualitative benefits such as
+interpretability and modularity.*
+
+This model was contributed by [qqaatw](https://huggingface.co/qqaatw). The original code can be found
+[here](https://github.com/google-research/language/tree/master/language/realm).
+
+## RealmConfig
+
+[[autodoc]] RealmConfig
+
+## RealmTokenizer
+
+[[autodoc]] RealmTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+ - batch_encode_candidates
+
+## RealmTokenizerFast
+
+[[autodoc]] RealmTokenizerFast
+ - batch_encode_candidates
+
+## RealmRetriever
+
+[[autodoc]] RealmRetriever
+
+## RealmEmbedder
+
+[[autodoc]] RealmEmbedder
+ - forward
+
+## RealmScorer
+
+[[autodoc]] RealmScorer
+ - forward
+
+## RealmKnowledgeAugEncoder
+
+[[autodoc]] RealmKnowledgeAugEncoder
+ - forward
+
+## RealmReader
+
+[[autodoc]] RealmReader
+ - forward
+
+## RealmForOpenQA
+
+[[autodoc]] RealmForOpenQA
+ - block_embedding_to
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/recurrent_gemma.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/recurrent_gemma.md
new file mode 100644
index 0000000000000000000000000000000000000000..1cd4e784a5bde18b897e06564c4dcf08186679a1
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/recurrent_gemma.md
@@ -0,0 +1,53 @@
+
+*This model was released on 2024-04-11 and added to Hugging Face Transformers on 2024-04-10.*
+
+# RecurrentGemma
+
+
+
+
+
+## Overview
+
+The Recurrent Gemma model was proposed in [RecurrentGemma: Moving Past Transformers for Efficient Open Language Models](https://huggingface.co/papers/2404.07839) by the Griffin, RLHF and Gemma Teams of Google.
+
+The abstract from the paper is the following:
+
+*We introduce RecurrentGemma, an open language model which uses Google’s novel Griffin architecture. Griffin combines linear recurrences with local attention to achieve excellent performance on language. It has a fixed-sized state, which reduces memory use and enables efficient inference on long sequences. We provide a pre-trained model with 2B non-embedding parameters, and an instruction tuned variant. Both models achieve comparable performance to Gemma-2B despite being trained on fewer tokens.*
+
+Tips:
+
+- The original checkpoints can be converted using the conversion script [`src/transformers/models/recurrent_gemma/convert_recurrent_gemma_weights_to_hf.py`](https://github.com/huggingface/transformers/blob/main/src/transformers/models/recurrent_gemma/convert_recurrent_gemma_to_hf.py).
+
+This model was contributed by [Arthur Zucker](https://huggingface.co/ArthurZ). The original code can be found [here](https://github.com/google-deepmind/recurrentgemma).
+
+
+## RecurrentGemmaConfig
+
+[[autodoc]] RecurrentGemmaConfig
+
+
+## RecurrentGemmaModel
+
+[[autodoc]] RecurrentGemmaModel
+ - forward
+
+## RecurrentGemmaForCausalLM
+
+[[autodoc]] RecurrentGemmaForCausalLM
+ - forward
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/reformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/reformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..1c01fa7c0569a19bdfded2b15ed7b7315cf61011
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/reformer.md
@@ -0,0 +1,195 @@
+
+*This model was released on 2020-01-13 and added to Hugging Face Transformers on 2020-11-16.*
+
+# Reformer
+
+
+
+
+
+## Overview
+
+The Reformer model was proposed in the paper [Reformer: The Efficient Transformer](https://huggingface.co/papers/2001.04451.pdf) by Nikita Kitaev, Łukasz Kaiser, Anselm Levskaya.
+
+The abstract from the paper is the following:
+
+*Large Transformer models routinely achieve state-of-the-art results on a number of tasks but training these models can
+be prohibitively costly, especially on long sequences. We introduce two techniques to improve the efficiency of
+Transformers. For one, we replace dot-product attention by one that uses locality-sensitive hashing, changing its
+complexity from O(L^2) to O(Llog(L)), where L is the length of the sequence. Furthermore, we use reversible residual
+layers instead of the standard residuals, which allows storing activations only once in the training process instead of
+N times, where N is the number of layers. The resulting model, the Reformer, performs on par with Transformer models
+while being much more memory-efficient and much faster on long sequences.*
+
+This model was contributed by [patrickvonplaten](https://huggingface.co/patrickvonplaten). The Authors' code can be
+found [here](https://github.com/google/trax/tree/master/trax/models/reformer).
+
+## Usage tips
+
+- Reformer does **not** work with *torch.nn.DataParallel* due to a bug in PyTorch, see [issue #36035](https://github.com/pytorch/pytorch/issues/36035).
+- Use Axial position encoding (see below for more details). It’s a mechanism to avoid having a huge positional encoding matrix (when the sequence length is very big) by factorizing it into smaller matrices.
+- Replace traditional attention by LSH (local-sensitive hashing) attention (see below for more details). It’s a technique to avoid computing the full product query-key in the attention layers.
+- Avoid storing the intermediate results of each layer by using reversible transformer layers to obtain them during the backward pass (subtracting the residuals from the input of the next layer gives them back) or recomputing them for results inside a given layer (less efficient than storing them but saves memory).
+- Compute the feedforward operations by chunks and not on the whole batch.
+
+### Axial Positional Encodings
+
+Axial Positional Encodings were first implemented in Google's [trax library](https://github.com/google/trax/blob/4d99ad4965bab1deba227539758d59f0df0fef48/trax/layers/research/position_encodings.py#L29)
+and developed by the authors of this model's paper. In models that are treating very long input sequences, the
+conventional position id encodings store an embeddings vector of size \\(d\\) being the `config.hidden_size` for
+every position \\(i, \ldots, n_s\\), with \\(n_s\\) being `config.max_embedding_size`. This means that having
+a sequence length of \\(n_s = 2^{19} \approx 0.5M\\) and a `config.hidden_size` of \\(d = 2^{10} \approx 1000\\)
+would result in a position encoding matrix:
+
+$$X_{i,j}, \text{ with } i \in \left[1,\ldots, d\right] \text{ and } j \in \left[1,\ldots, n_s\right]$$
+
+which alone has over 500M parameters to store. Axial positional encodings factorize \\(X_{i,j}\\) into two matrices:
+
+$$X^{1}_{i,j}, \text{ with } i \in \left[1,\ldots, d^1\right] \text{ and } j \in \left[1,\ldots, n_s^1\right]$$
+
+and
+
+$$X^{2}_{i,j}, \text{ with } i \in \left[1,\ldots, d^2\right] \text{ and } j \in \left[1,\ldots, n_s^2\right]$$
+
+with:
+
+$$d = d^1 + d^2 \text{ and } n_s = n_s^1 \times n_s^2 .$$
+
+Therefore the following holds:
+
+$$X_{i,j} = \begin{cases}
+X^{1}_{i, k}, & \text{if }\ i < d^1 \text{ with } k = j \mod n_s^1 \\
+X^{2}_{i - d^1, l}, & \text{if } i \ge d^1 \text{ with } l = \lfloor\frac{j}{n_s^1}\rfloor
+\end{cases}$$
+
+Intuitively, this means that a position embedding vector \\(x_j \in \mathbb{R}^{d}\\) is now the composition of two
+factorized embedding vectors: \\(x^1_{k, l} + x^2_{l, k}\\), where as the `config.max_embedding_size` dimension
+\\(j\\) is factorized into \\(k \text{ and } l\\). This design ensures that each position embedding vector
+\\(x_j\\) is unique.
+
+Using the above example again, axial position encoding with \\(d^1 = 2^9, d^2 = 2^9, n_s^1 = 2^9, n_s^2 = 2^{10}\\)
+can drastically reduced the number of parameters from 500 000 000 to \\(2^{18} + 2^{19} \approx 780 000\\) parameters, this means 85% less memory usage.
+
+In practice, the parameter `config.axial_pos_embds_dim` is set to a tuple \\((d^1, d^2)\\) which sum has to be
+equal to `config.hidden_size` and `config.axial_pos_shape` is set to a tuple \\((n_s^1, n_s^2)\\) which
+product has to be equal to `config.max_embedding_size`, which during training has to be equal to the *sequence
+length* of the `input_ids`.
+
+
+### LSH Self Attention
+
+In Locality sensitive hashing (LSH) self attention the key and query projection weights are tied. Therefore, the key
+query embedding vectors are also tied. LSH self attention uses the locality sensitive hashing mechanism proposed in
+[Practical and Optimal LSH for Angular Distance](https://huggingface.co/papers/1509.02897) to assign each of the tied key
+query embedding vectors to one of `config.num_buckets` possible buckets. The premise is that the more "similar"
+key query embedding vectors (in terms of *cosine similarity*) are to each other, the more likely they are assigned to
+the same bucket.
+
+The accuracy of the LSH mechanism can be improved by increasing `config.num_hashes` or directly the argument
+`num_hashes` of the forward function so that the output of the LSH self attention better approximates the output
+of the "normal" full self attention. The buckets are then sorted and chunked into query key embedding vector chunks
+each of length `config.lsh_chunk_length`. For each chunk, the query embedding vectors attend to its key vectors
+(which are tied to themselves) and to the key embedding vectors of `config.lsh_num_chunks_before` previous
+neighboring chunks and `config.lsh_num_chunks_after` following neighboring chunks.
+
+For more information, see the [original Paper](https://huggingface.co/papers/2001.04451) or this great [blog post](https://www.pragmatic.ml/reformer-deep-dive/).
+
+Note that `config.num_buckets` can also be factorized into a list \\((n_{\text{buckets}}^1,
+n_{\text{buckets}}^2)\\). This way instead of assigning the query key embedding vectors to one of \\((1,\ldots,
+n_{\text{buckets}})\\) they are assigned to one of \\((1-1,\ldots, n_{\text{buckets}}^1-1, \ldots,
+1-n_{\text{buckets}}^2, \ldots, n_{\text{buckets}}^1-n_{\text{buckets}}^2)\\). This is crucial for very long sequences to
+save memory.
+
+When training a model from scratch, it is recommended to leave `config.num_buckets=None`, so that depending on the
+sequence length a good value for `num_buckets` is calculated on the fly. This value will then automatically be
+saved in the config and should be reused for inference.
+
+Using LSH self attention, the memory and time complexity of the query-key matmul operation can be reduced from
+\\(\mathcal{O}(n_s \times n_s)\\) to \\(\mathcal{O}(n_s \times \log(n_s))\\), which usually represents the memory
+and time bottleneck in a transformer model, with \\(n_s\\) being the sequence length.
+
+
+### Local Self Attention
+
+Local self attention is essentially a "normal" self attention layer with key, query and value projections, but is
+chunked so that in each chunk of length `config.local_chunk_length` the query embedding vectors only attends to
+the key embedding vectors in its chunk and to the key embedding vectors of `config.local_num_chunks_before`
+previous neighboring chunks and `config.local_num_chunks_after` following neighboring chunks.
+
+Using Local self attention, the memory and time complexity of the query-key matmul operation can be reduced from
+\\(\mathcal{O}(n_s \times n_s)\\) to \\(\mathcal{O}(n_s \times \log(n_s))\\), which usually represents the memory
+and time bottleneck in a transformer model, with \\(n_s\\) being the sequence length.
+
+
+### Training
+
+During training, we must ensure that the sequence length is set to a value that can be divided by the least common
+multiple of `config.lsh_chunk_length` and `config.local_chunk_length` and that the parameters of the Axial
+Positional Encodings are correctly set as described above. Reformer is very memory efficient so that the model can
+easily be trained on sequences as long as 64000 tokens.
+
+For training, the [`ReformerModelWithLMHead`] should be used as follows:
+
+```python
+input_ids = tokenizer.encode("This is a sentence from the training data", return_tensors="pt")
+loss = model(input_ids, labels=input_ids)[0]
+```
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+
+## ReformerConfig
+
+[[autodoc]] ReformerConfig
+
+## ReformerTokenizer
+
+[[autodoc]] ReformerTokenizer
+ - save_vocabulary
+
+## ReformerTokenizerFast
+
+[[autodoc]] ReformerTokenizerFast
+
+## ReformerModel
+
+[[autodoc]] ReformerModel
+ - forward
+
+## ReformerModelWithLMHead
+
+[[autodoc]] ReformerModelWithLMHead
+ - forward
+
+## ReformerForMaskedLM
+
+[[autodoc]] ReformerForMaskedLM
+ - forward
+
+## ReformerForSequenceClassification
+
+[[autodoc]] ReformerForSequenceClassification
+ - forward
+
+## ReformerForQuestionAnswering
+
+[[autodoc]] ReformerForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/regnet.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/regnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..1f5de7645fe83f7a12625552e9f512e8c0275501
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/regnet.md
@@ -0,0 +1,98 @@
+
+*This model was released on 2020-03-30 and added to Hugging Face Transformers on 2022-04-07.*
+
+# RegNet
+
+
+
+
+
+
+
+## Overview
+
+The RegNet model was proposed in [Designing Network Design Spaces](https://huggingface.co/papers/2003.13678) by Ilija Radosavovic, Raj Prateek Kosaraju, Ross Girshick, Kaiming He, Piotr Dollár.
+
+The authors design search spaces to perform Neural Architecture Search (NAS). They first start from a high dimensional search space and iteratively reduce the search space by empirically applying constraints based on the best-performing models sampled by the current search space.
+
+The abstract from the paper is the following:
+
+*In this work, we present a new network design paradigm. Our goal is to help advance the understanding of network design and discover design principles that generalize across settings. Instead of focusing on designing individual network instances, we design network design spaces that parametrize populations of networks. The overall process is analogous to classic manual design of networks, but elevated to the design space level. Using our methodology we explore the structure aspect of network design and arrive at a low-dimensional design space consisting of simple, regular networks that we call RegNet. The core insight of the RegNet parametrization is surprisingly simple: widths and depths of good networks can be explained by a quantized linear function. We analyze the RegNet design space and arrive at interesting findings that do not match the current practice of network design. The RegNet design space provides simple and fast networks that work well across a wide range of flop regimes. Under comparable training settings and flops, the RegNet models outperform the popular EfficientNet models while being up to 5x faster on GPUs.*
+
+This model was contributed by [Francesco](https://huggingface.co/Francesco). The TensorFlow version of the model
+was contributed by [sayakpaul](https://huggingface.co/sayakpaul) and [ariG23498](https://huggingface.co/ariG23498).
+The original code can be found [here](https://github.com/facebookresearch/pycls).
+
+The huge 10B model from [Self-supervised Pretraining of Visual Features in the Wild](https://huggingface.co/papers/2103.01988),
+trained on one billion Instagram images, is available on the [hub](https://huggingface.co/facebook/regnet-y-10b-seer)
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with RegNet.
+
+
+
+- [`RegNetForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## RegNetConfig
+
+[[autodoc]] RegNetConfig
+
+
+
+
+## RegNetModel
+
+[[autodoc]] RegNetModel
+ - forward
+
+## RegNetForImageClassification
+
+[[autodoc]] RegNetForImageClassification
+ - forward
+
+
+
+
+## TFRegNetModel
+
+[[autodoc]] TFRegNetModel
+ - call
+
+## TFRegNetForImageClassification
+
+[[autodoc]] TFRegNetForImageClassification
+ - call
+
+
+
+
+## FlaxRegNetModel
+
+[[autodoc]] FlaxRegNetModel
+ - __call__
+
+## FlaxRegNetForImageClassification
+
+[[autodoc]] FlaxRegNetForImageClassification
+ - __call__
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rembert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rembert.md
new file mode 100644
index 0000000000000000000000000000000000000000..ffc9e0f91fe5e18cade553e686e016e35c6bcab8
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rembert.md
@@ -0,0 +1,156 @@
+
+*This model was released on 2020-10-24 and added to Hugging Face Transformers on 2021-07-24.*
+
+# RemBERT
+
+
+
+
+
+
+## Overview
+
+The RemBERT model was proposed in [Rethinking Embedding Coupling in Pre-trained Language Models](https://huggingface.co/papers/2010.12821) by Hyung Won Chung, Thibault Févry, Henry Tsai, Melvin Johnson, Sebastian Ruder.
+
+The abstract from the paper is the following:
+
+*We re-evaluate the standard practice of sharing weights between input and output embeddings in state-of-the-art
+pre-trained language models. We show that decoupled embeddings provide increased modeling flexibility, allowing us to
+significantly improve the efficiency of parameter allocation in the input embedding of multilingual models. By
+reallocating the input embedding parameters in the Transformer layers, we achieve dramatically better performance on
+standard natural language understanding tasks with the same number of parameters during fine-tuning. We also show that
+allocating additional capacity to the output embedding provides benefits to the model that persist through the
+fine-tuning stage even though the output embedding is discarded after pre-training. Our analysis shows that larger
+output embeddings prevent the model's last layers from overspecializing to the pre-training task and encourage
+Transformer representations to be more general and more transferable to other tasks and languages. Harnessing these
+findings, we are able to train models that achieve strong performance on the XTREME benchmark without increasing the
+number of parameters at the fine-tuning stage.*
+
+## Usage tips
+
+For fine-tuning, RemBERT can be thought of as a bigger version of mBERT with an ALBERT-like factorization of the
+embedding layer. The embeddings are not tied in pre-training, in contrast with BERT, which enables smaller input
+embeddings (preserved during fine-tuning) and bigger output embeddings (discarded at fine-tuning). The tokenizer is
+also similar to the Albert one rather than the BERT one.
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## RemBertConfig
+
+[[autodoc]] RemBertConfig
+
+## RemBertTokenizer
+
+[[autodoc]] RemBertTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## RemBertTokenizerFast
+
+[[autodoc]] RemBertTokenizerFast
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+
+
+
+## RemBertModel
+
+[[autodoc]] RemBertModel
+ - forward
+
+## RemBertForCausalLM
+
+[[autodoc]] RemBertForCausalLM
+ - forward
+
+## RemBertForMaskedLM
+
+[[autodoc]] RemBertForMaskedLM
+ - forward
+
+## RemBertForSequenceClassification
+
+[[autodoc]] RemBertForSequenceClassification
+ - forward
+
+## RemBertForMultipleChoice
+
+[[autodoc]] RemBertForMultipleChoice
+ - forward
+
+## RemBertForTokenClassification
+
+[[autodoc]] RemBertForTokenClassification
+ - forward
+
+## RemBertForQuestionAnswering
+
+[[autodoc]] RemBertForQuestionAnswering
+ - forward
+
+
+
+
+## TFRemBertModel
+
+[[autodoc]] TFRemBertModel
+ - call
+
+## TFRemBertForMaskedLM
+
+[[autodoc]] TFRemBertForMaskedLM
+ - call
+
+## TFRemBertForCausalLM
+
+[[autodoc]] TFRemBertForCausalLM
+ - call
+
+## TFRemBertForSequenceClassification
+
+[[autodoc]] TFRemBertForSequenceClassification
+ - call
+
+## TFRemBertForMultipleChoice
+
+[[autodoc]] TFRemBertForMultipleChoice
+ - call
+
+## TFRemBertForTokenClassification
+
+[[autodoc]] TFRemBertForTokenClassification
+ - call
+
+## TFRemBertForQuestionAnswering
+
+[[autodoc]] TFRemBertForQuestionAnswering
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/resnet.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/resnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..29551c87de39f78911789e25ac581806d7adb149
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/resnet.md
@@ -0,0 +1,99 @@
+
+*This model was released on 2015-12-10 and added to Hugging Face Transformers on 2022-03-14.*
+
+# ResNet
+
+
+
+
+
+
+
+## Overview
+
+The ResNet model was proposed in [Deep Residual Learning for Image Recognition](https://huggingface.co/papers/1512.03385) by Kaiming He, Xiangyu Zhang, Shaoqing Ren and Jian Sun. Our implementation follows the small changes made by [Nvidia](https://catalog.ngc.nvidia.com/orgs/nvidia/resources/resnet_50_v1_5_for_pytorch), we apply the `stride=2` for downsampling in bottleneck's `3x3` conv and not in the first `1x1`. This is generally known as "ResNet v1.5".
+
+ResNet introduced residual connections, they allow to train networks with an unseen number of layers (up to 1000). ResNet won the 2015 ILSVRC & COCO competition, one important milestone in deep computer vision.
+
+The abstract from the paper is the following:
+
+*Deeper neural networks are more difficult to train. We present a residual learning framework to ease the training of networks that are substantially deeper than those used previously. We explicitly reformulate the layers as learning residual functions with reference to the layer inputs, instead of learning unreferenced functions. We provide comprehensive empirical evidence showing that these residual networks are easier to optimize, and can gain accuracy from considerably increased depth. On the ImageNet dataset we evaluate residual nets with a depth of up to 152 layers---8x deeper than VGG nets but still having lower complexity. An ensemble of these residual nets achieves 3.57% error on the ImageNet test set. This result won the 1st place on the ILSVRC 2015 classification task. We also present analysis on CIFAR-10 with 100 and 1000 layers.
+The depth of representations is of central importance for many visual recognition tasks. Solely due to our extremely deep representations, we obtain a 28% relative improvement on the COCO object detection dataset. Deep residual nets are foundations of our submissions to ILSVRC & COCO 2015 competitions, where we also won the 1st places on the tasks of ImageNet detection, ImageNet localization, COCO detection, and COCO segmentation.*
+
+The figure below illustrates the architecture of ResNet. Taken from the [original paper](https://huggingface.co/papers/1512.03385).
+
+
+
+This model was contributed by [Francesco](https://huggingface.co/Francesco). The TensorFlow version of this model was added by [amyeroberts](https://huggingface.co/amyeroberts). The original code can be found [here](https://github.com/KaimingHe/deep-residual-networks).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with ResNet.
+
+
+
+- [`ResNetForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## ResNetConfig
+
+[[autodoc]] ResNetConfig
+
+
+
+
+## ResNetModel
+
+[[autodoc]] ResNetModel
+ - forward
+
+## ResNetForImageClassification
+
+[[autodoc]] ResNetForImageClassification
+ - forward
+
+
+
+
+## TFResNetModel
+
+[[autodoc]] TFResNetModel
+ - call
+
+## TFResNetForImageClassification
+
+[[autodoc]] TFResNetForImageClassification
+ - call
+
+
+
+
+## FlaxResNetModel
+
+[[autodoc]] FlaxResNetModel
+ - __call__
+
+## FlaxResNetForImageClassification
+
+[[autodoc]] FlaxResNetForImageClassification
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/retribert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/retribert.md
new file mode 100644
index 0000000000000000000000000000000000000000..871bdc6e8c86a70807b25073cd9025dc52861bc3
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/retribert.md
@@ -0,0 +1,58 @@
+
+*This model was released on 2020-06-12 and added to Hugging Face Transformers on 2023-06-20.*
+
+# RetriBERT
+
+
+
+
+
+
+
+This model is in maintenance mode only, so we won't accept any new PRs changing its code.
+
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.30.0.
+You can do so by running the following command: `pip install -U transformers==4.30.0`.
+
+
+
+## Overview
+
+The [RetriBERT](https://huggingface.co/yjernite/retribert-base-uncased/tree/main) model was proposed in the blog post [Explain Anything Like I'm Five: A Model for Open Domain Long Form
+Question Answering](https://yjernite.github.io/lfqa.html). RetriBERT is a small model that uses either a single or
+pair of BERT encoders with lower-dimension projection for dense semantic indexing of text.
+
+This model was contributed by [yjernite](https://huggingface.co/yjernite). Code to train and use the model can be
+found [here](https://github.com/huggingface/transformers/tree/main/examples/research-projects/distillation).
+
+
+## RetriBertConfig
+
+[[autodoc]] RetriBertConfig
+
+## RetriBertTokenizer
+
+[[autodoc]] RetriBertTokenizer
+
+## RetriBertTokenizerFast
+
+[[autodoc]] RetriBertTokenizerFast
+
+## RetriBertModel
+
+[[autodoc]] RetriBertModel
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/roberta-prelayernorm.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/roberta-prelayernorm.md
new file mode 100644
index 0000000000000000000000000000000000000000..60f3aa9cbfa5429203ba96034b5e7a7e8cb3cf8c
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/roberta-prelayernorm.md
@@ -0,0 +1,172 @@
+
+*This model was released on 2019-04-01 and added to Hugging Face Transformers on 2022-12-19.*
+
+# RoBERTa-PreLayerNorm
+
+
+
+
+
+
+
+## Overview
+
+The RoBERTa-PreLayerNorm model was proposed in [fairseq: A Fast, Extensible Toolkit for Sequence Modeling](https://huggingface.co/papers/1904.01038) by Myle Ott, Sergey Edunov, Alexei Baevski, Angela Fan, Sam Gross, Nathan Ng, David Grangier, Michael Auli.
+It is identical to using the `--encoder-normalize-before` flag in [fairseq](https://fairseq.readthedocs.io/).
+
+The abstract from the paper is the following:
+
+*fairseq is an open-source sequence modeling toolkit that allows researchers and developers to train custom models for translation, summarization, language modeling, and other text generation tasks. The toolkit is based on PyTorch and supports distributed training across multiple GPUs and machines. We also support fast mixed-precision training and inference on modern GPUs.*
+
+This model was contributed by [andreasmaden](https://huggingface.co/andreasmadsen).
+The original code can be found [here](https://github.com/princeton-nlp/DinkyTrain).
+
+## Usage tips
+
+- The implementation is the same as [Roberta](roberta) except instead of using _Add and Norm_ it does _Norm and Add_. _Add_ and _Norm_ refers to the Addition and LayerNormalization as described in [Attention Is All You Need](https://huggingface.co/papers/1706.03762).
+- This is identical to using the `--encoder-normalize-before` flag in [fairseq](https://fairseq.readthedocs.io/).
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Causal language modeling task guide](../tasks/language_modeling)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## RobertaPreLayerNormConfig
+
+[[autodoc]] RobertaPreLayerNormConfig
+
+
+
+
+## RobertaPreLayerNormModel
+
+[[autodoc]] RobertaPreLayerNormModel
+ - forward
+
+## RobertaPreLayerNormForCausalLM
+
+[[autodoc]] RobertaPreLayerNormForCausalLM
+ - forward
+
+## RobertaPreLayerNormForMaskedLM
+
+[[autodoc]] RobertaPreLayerNormForMaskedLM
+ - forward
+
+## RobertaPreLayerNormForSequenceClassification
+
+[[autodoc]] RobertaPreLayerNormForSequenceClassification
+ - forward
+
+## RobertaPreLayerNormForMultipleChoice
+
+[[autodoc]] RobertaPreLayerNormForMultipleChoice
+ - forward
+
+## RobertaPreLayerNormForTokenClassification
+
+[[autodoc]] RobertaPreLayerNormForTokenClassification
+ - forward
+
+## RobertaPreLayerNormForQuestionAnswering
+
+[[autodoc]] RobertaPreLayerNormForQuestionAnswering
+ - forward
+
+
+
+
+## TFRobertaPreLayerNormModel
+
+[[autodoc]] TFRobertaPreLayerNormModel
+ - call
+
+## TFRobertaPreLayerNormForCausalLM
+
+[[autodoc]] TFRobertaPreLayerNormForCausalLM
+ - call
+
+## TFRobertaPreLayerNormForMaskedLM
+
+[[autodoc]] TFRobertaPreLayerNormForMaskedLM
+ - call
+
+## TFRobertaPreLayerNormForSequenceClassification
+
+[[autodoc]] TFRobertaPreLayerNormForSequenceClassification
+ - call
+
+## TFRobertaPreLayerNormForMultipleChoice
+
+[[autodoc]] TFRobertaPreLayerNormForMultipleChoice
+ - call
+
+## TFRobertaPreLayerNormForTokenClassification
+
+[[autodoc]] TFRobertaPreLayerNormForTokenClassification
+ - call
+
+## TFRobertaPreLayerNormForQuestionAnswering
+
+[[autodoc]] TFRobertaPreLayerNormForQuestionAnswering
+ - call
+
+
+
+
+## FlaxRobertaPreLayerNormModel
+
+[[autodoc]] FlaxRobertaPreLayerNormModel
+ - __call__
+
+## FlaxRobertaPreLayerNormForCausalLM
+
+[[autodoc]] FlaxRobertaPreLayerNormForCausalLM
+ - __call__
+
+## FlaxRobertaPreLayerNormForMaskedLM
+
+[[autodoc]] FlaxRobertaPreLayerNormForMaskedLM
+ - __call__
+
+## FlaxRobertaPreLayerNormForSequenceClassification
+
+[[autodoc]] FlaxRobertaPreLayerNormForSequenceClassification
+ - __call__
+
+## FlaxRobertaPreLayerNormForMultipleChoice
+
+[[autodoc]] FlaxRobertaPreLayerNormForMultipleChoice
+ - __call__
+
+## FlaxRobertaPreLayerNormForTokenClassification
+
+[[autodoc]] FlaxRobertaPreLayerNormForTokenClassification
+ - __call__
+
+## FlaxRobertaPreLayerNormForQuestionAnswering
+
+[[autodoc]] FlaxRobertaPreLayerNormForQuestionAnswering
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/roberta.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/roberta.md
new file mode 100644
index 0000000000000000000000000000000000000000..7313d632cef07eef994a01176596ed5f79608915
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/roberta.md
@@ -0,0 +1,231 @@
+
+*This model was released on 2019-07-26 and added to Hugging Face Transformers on 2020-11-16.*
+
+
+
+
+
+
+
+
+
+
+# RoBERTa
+
+[RoBERTa](https://huggingface.co/papers/1907.11692) improves BERT with new pretraining objectives, demonstrating [BERT](./bert) was undertrained and training design is important. The pretraining objectives include dynamic masking, sentence packing, larger batches and a byte-level BPE tokenizer.
+
+You can find all the original RoBERTa checkpoints under the [Facebook AI](https://huggingface.co/FacebookAI) organization.
+
+
+> [!TIP]
+> Click on the RoBERTa models in the right sidebar for more examples of how to apply RoBERTa to different language tasks.
+
+The example below demonstrates how to predict the `` token with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="fill-mask",
+ model="FacebookAI/roberta-base",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("Plants create through a process known as photosynthesis.")
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForMaskedLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "FacebookAI/roberta-base",
+)
+model = AutoModelForMaskedLM.from_pretrained(
+ "FacebookAI/roberta-base",
+ torch_dtype=torch.float16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+inputs = tokenizer("Plants create through a process known as photosynthesis.", return_tensors="pt").to(model.device)
+
+with torch.no_grad():
+ outputs = model(**inputs)
+ predictions = outputs.logits
+
+masked_index = torch.where(inputs['input_ids'] == tokenizer.mask_token_id)[1]
+predicted_token_id = predictions[0, masked_index].argmax(dim=-1)
+predicted_token = tokenizer.decode(predicted_token_id)
+
+print(f"The predicted token is: {predicted_token}")
+```
+
+
+
+
+```bash
+echo -e "Plants create through a process known as photosynthesis." | transformers-cli run --task fill-mask --model FacebookAI/roberta-base --device 0
+```
+
+
+
+
+## Notes
+
+- RoBERTa doesn't have `token_type_ids` so you don't need to indicate which token belongs to which segment. Separate your segments with the separation token `tokenizer.sep_token` or ``.
+
+## RobertaConfig
+
+[[autodoc]] RobertaConfig
+
+## RobertaTokenizer
+
+[[autodoc]] RobertaTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## RobertaTokenizerFast
+
+[[autodoc]] RobertaTokenizerFast
+ - build_inputs_with_special_tokens
+
+
+
+
+## RobertaModel
+
+[[autodoc]] RobertaModel
+ - forward
+
+## RobertaForCausalLM
+
+[[autodoc]] RobertaForCausalLM
+ - forward
+
+## RobertaForMaskedLM
+
+[[autodoc]] RobertaForMaskedLM
+ - forward
+
+## RobertaForSequenceClassification
+
+[[autodoc]] RobertaForSequenceClassification
+ - forward
+
+## RobertaForMultipleChoice
+
+[[autodoc]] RobertaForMultipleChoice
+ - forward
+
+## RobertaForTokenClassification
+
+[[autodoc]] RobertaForTokenClassification
+ - forward
+
+## RobertaForQuestionAnswering
+
+[[autodoc]] RobertaForQuestionAnswering
+ - forward
+
+
+
+
+## TFRobertaModel
+
+[[autodoc]] TFRobertaModel
+ - call
+
+## TFRobertaForCausalLM
+
+[[autodoc]] TFRobertaForCausalLM
+ - call
+
+## TFRobertaForMaskedLM
+
+[[autodoc]] TFRobertaForMaskedLM
+ - call
+
+## TFRobertaForSequenceClassification
+
+[[autodoc]] TFRobertaForSequenceClassification
+ - call
+
+## TFRobertaForMultipleChoice
+
+[[autodoc]] TFRobertaForMultipleChoice
+ - call
+
+## TFRobertaForTokenClassification
+
+[[autodoc]] TFRobertaForTokenClassification
+ - call
+
+## TFRobertaForQuestionAnswering
+
+[[autodoc]] TFRobertaForQuestionAnswering
+ - call
+
+
+
+
+## FlaxRobertaModel
+
+[[autodoc]] FlaxRobertaModel
+ - __call__
+
+## FlaxRobertaForCausalLM
+
+[[autodoc]] FlaxRobertaForCausalLM
+ - __call__
+
+## FlaxRobertaForMaskedLM
+
+[[autodoc]] FlaxRobertaForMaskedLM
+ - __call__
+
+## FlaxRobertaForSequenceClassification
+
+[[autodoc]] FlaxRobertaForSequenceClassification
+ - __call__
+
+## FlaxRobertaForMultipleChoice
+
+[[autodoc]] FlaxRobertaForMultipleChoice
+ - __call__
+
+## FlaxRobertaForTokenClassification
+
+[[autodoc]] FlaxRobertaForTokenClassification
+ - __call__
+
+## FlaxRobertaForQuestionAnswering
+
+[[autodoc]] FlaxRobertaForQuestionAnswering
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/roc_bert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/roc_bert.md
new file mode 100644
index 0000000000000000000000000000000000000000..f56692c17e3e7dc4906c41da0ca728f5f91903d7
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/roc_bert.md
@@ -0,0 +1,142 @@
+
+*This model was released on 2022-05-27 and added to Hugging Face Transformers on 2022-11-08.*
+
+
+
+
+
+
+
+# RoCBert
+
+[RoCBert](https://aclanthology.org/2022.acl-long.65.pdf) is a pretrained Chinese [BERT](./bert) model designed against adversarial attacks like typos and synonyms. It is pretrained with a contrastive learning objective to align normal and adversarial text examples. The examples include different semantic, phonetic, and visual features of Chinese. This makes RoCBert more robust against manipulation.
+
+You can find all the original RoCBert checkpoints under the [weiweishi](https://huggingface.co/weiweishi) profile.
+
+> [!TIP]
+> This model was contributed by [weiweishi](https://huggingface.co/weiweishi).
+>
+> Click on the RoCBert models in the right sidebar for more examples of how to apply RoCBert to different Chinese language tasks.
+
+The example below demonstrates how to predict the [MASK] token with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="fill-mask",
+ model="weiweishi/roc-bert-base-zh",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("這家餐廳的拉麵是我[MASK]過的最好的拉麵之")
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForMaskedLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "weiweishi/roc-bert-base-zh",
+)
+model = AutoModelForMaskedLM.from_pretrained(
+ "weiweishi/roc-bert-base-zh",
+ torch_dtype=torch.float16,
+ device_map="auto",
+)
+inputs = tokenizer("這家餐廳的拉麵是我[MASK]過的最好的拉麵之", return_tensors="pt").to(model.device)
+
+with torch.no_grad():
+ outputs = model(**inputs)
+ predictions = outputs.logits
+
+masked_index = torch.where(inputs['input_ids'] == tokenizer.mask_token_id)[1]
+predicted_token_id = predictions[0, masked_index].argmax(dim=-1)
+predicted_token = tokenizer.decode(predicted_token_id)
+
+print(f"The predicted token is: {predicted_token}")
+```
+
+
+
+
+```bash
+echo -e "這家餐廳的拉麵是我[MASK]過的最好的拉麵之" | transformers-cli run --task fill-mask --model weiweishi/roc-bert-base-zh --device 0
+```
+
+
+
+
+## RoCBertConfig
+
+[[autodoc]] RoCBertConfig
+ - all
+
+## RoCBertTokenizer
+
+[[autodoc]] RoCBertTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## RoCBertModel
+
+[[autodoc]] RoCBertModel
+ - forward
+
+## RoCBertForPreTraining
+
+[[autodoc]] RoCBertForPreTraining
+ - forward
+
+## RoCBertForCausalLM
+
+[[autodoc]] RoCBertForCausalLM
+ - forward
+
+## RoCBertForMaskedLM
+
+[[autodoc]] RoCBertForMaskedLM
+ - forward
+
+## RoCBertForSequenceClassification
+
+[[autodoc]] transformers.RoCBertForSequenceClassification
+ - forward
+
+## RoCBertForMultipleChoice
+
+[[autodoc]] transformers.RoCBertForMultipleChoice
+ - forward
+
+## RoCBertForTokenClassification
+
+[[autodoc]] transformers.RoCBertForTokenClassification
+ - forward
+
+## RoCBertForQuestionAnswering
+
+[[autodoc]] RoCBertForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/roformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/roformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..06663ff49144f639eeb447af24c7f29bb42ff645
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/roformer.md
@@ -0,0 +1,218 @@
+
+*This model was released on 2021-04-20 and added to Hugging Face Transformers on 2021-05-20.*
+
+
+
+
+
+
+
+
+
+# RoFormer
+
+[RoFormer](https://huggingface.co/papers/2104.09864) introduces Rotary Position Embedding (RoPE) to encode token positions by rotating the inputs in 2D space. This allows a model to track absolute positions and model relative relationships. RoPE can scale to longer sequences, account for the natural decay of token dependencies, and works with the more efficient linear self-attention.
+
+You can find all the RoFormer checkpoints on the [Hub](https://huggingface.co/models?search=roformer).
+
+> [!TIP]
+> Click on the RoFormer models in the right sidebar for more examples of how to apply RoFormer to different language tasks.
+
+The example below demonstrates how to predict the `[MASK]` token with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```py
+# uncomment to install rjieba which is needed for the tokenizer
+# !pip install rjieba
+import torch
+from transformers import pipeline
+
+pipe = pipeline(
+ task="fill-mask",
+ model="junnyu/roformer_chinese_base",
+ torch_dtype=torch.float16,
+ device=0
+)
+output = pipe("水在零度时会[MASK]")
+print(output)
+```
+
+
+
+
+```py
+# uncomment to install rjieba which is needed for the tokenizer
+# !pip install rjieba
+import torch
+from transformers import AutoModelForMaskedLM, AutoTokenizer
+
+model = AutoModelForMaskedLM.from_pretrained(
+ "junnyu/roformer_chinese_base", torch_dtype=torch.float16
+)
+tokenizer = AutoTokenizer.from_pretrained("junnyu/roformer_chinese_base")
+
+input_ids = tokenizer("水在零度时会[MASK]", return_tensors="pt").to(model.device)
+outputs = model(**input_ids)
+decoded = tokenizer.batch_decode(outputs.logits.argmax(-1), skip_special_tokens=True)
+print(decoded)
+```
+
+
+
+
+```bash
+echo -e "水在零度时会[MASK]" | transformers-cli run --task fill-mask --model junnyu/roformer_chinese_base --device 0
+```
+
+
+
+
+## Notes
+
+- The current RoFormer implementation is an encoder-only model. The original code can be found in the [ZhuiyiTechnology/roformer](https://github.com/ZhuiyiTechnology/roformer) repository.
+
+## RoFormerConfig
+
+[[autodoc]] RoFormerConfig
+
+## RoFormerTokenizer
+
+[[autodoc]] RoFormerTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## RoFormerTokenizerFast
+
+[[autodoc]] RoFormerTokenizerFast
+ - build_inputs_with_special_tokens
+
+
+
+
+## RoFormerModel
+
+[[autodoc]] RoFormerModel
+ - forward
+
+## RoFormerForCausalLM
+
+[[autodoc]] RoFormerForCausalLM
+ - forward
+
+## RoFormerForMaskedLM
+
+[[autodoc]] RoFormerForMaskedLM
+ - forward
+
+## RoFormerForSequenceClassification
+
+[[autodoc]] RoFormerForSequenceClassification
+ - forward
+
+## RoFormerForMultipleChoice
+
+[[autodoc]] RoFormerForMultipleChoice
+ - forward
+
+## RoFormerForTokenClassification
+
+[[autodoc]] RoFormerForTokenClassification
+ - forward
+
+## RoFormerForQuestionAnswering
+
+[[autodoc]] RoFormerForQuestionAnswering
+ - forward
+
+
+
+
+## TFRoFormerModel
+
+[[autodoc]] TFRoFormerModel
+ - call
+
+## TFRoFormerForMaskedLM
+
+[[autodoc]] TFRoFormerForMaskedLM
+ - call
+
+## TFRoFormerForCausalLM
+
+[[autodoc]] TFRoFormerForCausalLM
+ - call
+
+## TFRoFormerForSequenceClassification
+
+[[autodoc]] TFRoFormerForSequenceClassification
+ - call
+
+## TFRoFormerForMultipleChoice
+
+[[autodoc]] TFRoFormerForMultipleChoice
+ - call
+
+## TFRoFormerForTokenClassification
+
+[[autodoc]] TFRoFormerForTokenClassification
+ - call
+
+## TFRoFormerForQuestionAnswering
+
+[[autodoc]] TFRoFormerForQuestionAnswering
+ - call
+
+
+
+
+## FlaxRoFormerModel
+
+[[autodoc]] FlaxRoFormerModel
+ - __call__
+
+## FlaxRoFormerForMaskedLM
+
+[[autodoc]] FlaxRoFormerForMaskedLM
+ - __call__
+
+## FlaxRoFormerForSequenceClassification
+
+[[autodoc]] FlaxRoFormerForSequenceClassification
+ - __call__
+
+## FlaxRoFormerForMultipleChoice
+
+[[autodoc]] FlaxRoFormerForMultipleChoice
+ - __call__
+
+## FlaxRoFormerForTokenClassification
+
+[[autodoc]] FlaxRoFormerForTokenClassification
+ - __call__
+
+## FlaxRoFormerForQuestionAnswering
+
+[[autodoc]] FlaxRoFormerForQuestionAnswering
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rt_detr.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rt_detr.md
new file mode 100644
index 0000000000000000000000000000000000000000..02accfd6d9f76c9efae44edabc9500a8f90a9d6d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rt_detr.md
@@ -0,0 +1,122 @@
+
+*This model was released on 2023-04-17 and added to Hugging Face Transformers on 2024-06-22.*
+
+# RT-DETR
+
+
+
+
+
+## Overview
+
+
+The RT-DETR model was proposed in [DETRs Beat YOLOs on Real-time Object Detection](https://huggingface.co/papers/2304.08069) by Wenyu Lv, Yian Zhao, Shangliang Xu, Jinman Wei, Guanzhong Wang, Cheng Cui, Yuning Du, Qingqing Dang, Yi Liu.
+
+RT-DETR is an object detection model that stands for "Real-Time DEtection Transformer." This model is designed to perform object detection tasks with a focus on achieving real-time performance while maintaining high accuracy. Leveraging the transformer architecture, which has gained significant popularity in various fields of deep learning, RT-DETR processes images to identify and locate multiple objects within them.
+
+The abstract from the paper is the following:
+
+*Recently, end-to-end transformer-based detectors (DETRs) have achieved remarkable performance. However, the issue of the high computational cost of DETRs has not been effectively addressed, limiting their practical application and preventing them from fully exploiting the benefits of no post-processing, such as non-maximum suppression (NMS). In this paper, we first analyze the influence of NMS in modern real-time object detectors on inference speed, and establish an end-to-end speed benchmark. To avoid the inference delay caused by NMS, we propose a Real-Time DEtection TRansformer (RT-DETR), the first real-time end-to-end object detector to our best knowledge. Specifically, we design an efficient hybrid encoder to efficiently process multi-scale features by decoupling the intra-scale interaction and cross-scale fusion, and propose IoU-aware query selection to improve the initialization of object queries. In addition, our proposed detector supports flexibly adjustment of the inference speed by using different decoder layers without the need for retraining, which facilitates the practical application of real-time object detectors. Our RT-DETR-L achieves 53.0% AP on COCO val2017 and 114 FPS on T4 GPU, while RT-DETR-X achieves 54.8% AP and 74 FPS, outperforming all YOLO detectors of the same scale in both speed and accuracy. Furthermore, our RT-DETR-R50 achieves 53.1% AP and 108 FPS, outperforming DINO-Deformable-DETR-R50 by 2.2% AP in accuracy and by about 21 times in FPS.*
+
+
+
+ RT-DETR performance relative to YOLO models. Taken from the original paper.
+
+The model version was contributed by [rafaelpadilla](https://huggingface.co/rafaelpadilla) and [sangbumchoi](https://github.com/SangbumChoi). The original code can be found [here](https://github.com/lyuwenyu/RT-DETR/).
+
+
+## Usage tips
+
+Initially, an image is processed using a pre-trained convolutional neural network, specifically a Resnet-D variant as referenced in the original code. This network extracts features from the final three layers of the architecture. Following this, a hybrid encoder is employed to convert the multi-scale features into a sequential array of image features. Then, a decoder, equipped with auxiliary prediction heads is used to refine the object queries. This process facilitates the direct generation of bounding boxes, eliminating the need for any additional post-processing to acquire the logits and coordinates for the bounding boxes.
+
+```py
+>>> import torch
+>>> import requests
+
+>>> from PIL import Image
+>>> from transformers import RTDetrForObjectDetection, RTDetrImageProcessor
+
+>>> url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> image_processor = RTDetrImageProcessor.from_pretrained("PekingU/rtdetr_r50vd")
+>>> model = RTDetrForObjectDetection.from_pretrained("PekingU/rtdetr_r50vd")
+
+>>> inputs = image_processor(images=image, return_tensors="pt")
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> results = image_processor.post_process_object_detection(outputs, target_sizes=torch.tensor([(image.height, image.width)]), threshold=0.3)
+
+>>> for result in results:
+... for score, label_id, box in zip(result["scores"], result["labels"], result["boxes"]):
+... score, label = score.item(), label_id.item()
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"{model.config.id2label[label]}: {score:.2f} {box}")
+sofa: 0.97 [0.14, 0.38, 640.13, 476.21]
+cat: 0.96 [343.38, 24.28, 640.14, 371.5]
+cat: 0.96 [13.23, 54.18, 318.98, 472.22]
+remote: 0.95 [40.11, 73.44, 175.96, 118.48]
+remote: 0.92 [333.73, 76.58, 369.97, 186.99]
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with RT-DETR.
+
+
+
+- Scripts for finetuning [`RTDetrForObjectDetection`] with [`Trainer`] or [Accelerate](https://huggingface.co/docs/accelerate/index) can be found [here](https://github.com/huggingface/transformers/tree/main/examples/pytorch/object-detection).
+- See also: [Object detection task guide](../tasks/object_detection).
+- Notebooks regarding inference and fine-tuning RT-DETR on a custom dataset can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/RT-DETR). 🌎
+
+## RTDetrConfig
+
+[[autodoc]] RTDetrConfig
+
+## RTDetrResNetConfig
+
+[[autodoc]] RTDetrResNetConfig
+
+## RTDetrImageProcessor
+
+[[autodoc]] RTDetrImageProcessor
+ - preprocess
+ - post_process_object_detection
+
+## RTDetrImageProcessorFast
+
+[[autodoc]] RTDetrImageProcessorFast
+ - preprocess
+ - post_process_object_detection
+
+## RTDetrModel
+
+[[autodoc]] RTDetrModel
+ - forward
+
+## RTDetrForObjectDetection
+
+[[autodoc]] RTDetrForObjectDetection
+ - forward
+
+## RTDetrResNetBackbone
+
+[[autodoc]] RTDetrResNetBackbone
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rt_detr_v2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rt_detr_v2.md
new file mode 100644
index 0000000000000000000000000000000000000000..f5eb54625c84a2337831097d640ed271080d615d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rt_detr_v2.md
@@ -0,0 +1,102 @@
+
+*This model was released on 2024-07-24 and added to Hugging Face Transformers on 2025-02-06.*
+
+# RT-DETRv2
+
+
+
+
+
+## Overview
+
+The RT-DETRv2 model was proposed in [RT-DETRv2: Improved Baseline with Bag-of-Freebies for Real-Time Detection Transformer](https://huggingface.co/papers/2407.17140) by Wenyu Lv, Yian Zhao, Qinyao Chang, Kui Huang, Guanzhong Wang, Yi Liu.
+
+RT-DETRv2 refines RT-DETR by introducing selective multi-scale feature extraction, a discrete sampling operator for broader deployment compatibility, and improved training strategies like dynamic data augmentation and scale-adaptive hyperparameters. These changes enhance flexibility and practicality while maintaining real-time performance.
+
+The abstract from the paper is the following:
+
+*In this report, we present RT-DETRv2, an improved Real-Time DEtection TRansformer (RT-DETR). RT-DETRv2 builds upon the previous state-of-the-art real-time detector, RT-DETR, and opens up a set of bag-of-freebies for flexibility and practicality, as well as optimizing the training strategy to achieve enhanced performance. To improve the flexibility, we suggest setting a distinct number of sampling points for features at different scales in the deformable attention to achieve selective multi-scale feature extraction by the decoder. To enhance practicality, we propose an optional discrete sampling operator to replace the grid_sample operator that is specific to RT-DETR compared to YOLOs. This removes the deployment constraints typically associated with DETRs. For the training strategy, we propose dynamic data augmentation and scale-adaptive hyperparameters customization to improve performance without loss of speed.*
+
+This model was contributed by [jadechoghari](https://huggingface.co/jadechoghari).
+The original code can be found [here](https://github.com/lyuwenyu/RT-DETR).
+
+## Usage tips
+
+This second version of RT-DETR improves how the decoder finds objects in an image.
+
+- **better sampling** – adjusts offsets so the model looks at the right areas
+- **flexible attention** – can use smooth (bilinear) or fixed (discrete) sampling
+- **optimized processing** – improves how attention weights mix information
+
+```py
+>>> import torch
+>>> import requests
+
+>>> from PIL import Image
+>>> from transformers import RTDetrV2ForObjectDetection, RTDetrImageProcessor
+
+>>> url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> image_processor = RTDetrImageProcessor.from_pretrained("PekingU/rtdetr_v2_r18vd")
+>>> model = RTDetrV2ForObjectDetection.from_pretrained("PekingU/rtdetr_v2_r18vd")
+
+>>> inputs = image_processor(images=image, return_tensors="pt")
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> results = image_processor.post_process_object_detection(outputs, target_sizes=torch.tensor([(image.height, image.width)]), threshold=0.5)
+
+>>> for result in results:
+... for score, label_id, box in zip(result["scores"], result["labels"], result["boxes"]):
+... score, label = score.item(), label_id.item()
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"{model.config.id2label[label]}: {score:.2f} {box}")
+cat: 0.97 [341.14, 25.11, 639.98, 372.89]
+cat: 0.96 [12.78, 56.35, 317.67, 471.34]
+remote: 0.95 [39.96, 73.12, 175.65, 117.44]
+sofa: 0.86 [-0.11, 2.97, 639.89, 473.62]
+sofa: 0.82 [-0.12, 1.78, 639.87, 473.52]
+remote: 0.79 [333.65, 76.38, 370.69, 187.48]
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with RT-DETRv2.
+
+
+
+- Scripts for finetuning [`RTDetrV2ForObjectDetection`] with [`Trainer`] or [Accelerate](https://huggingface.co/docs/accelerate/index) can be found [here](https://github.com/huggingface/transformers/tree/main/examples/pytorch/object-detection).
+- See also: [Object detection task guide](../tasks/object_detection).
+- Notebooks for [inference](https://github.com/qubvel/transformers-notebooks/blob/main/notebooks/RT_DETR_v2_inference.ipynb) and [fine-tuning](https://github.com/qubvel/transformers-notebooks/blob/main/notebooks/RT_DETR_v2_finetune_on_a_custom_dataset.ipynb) RT-DETRv2 on a custom dataset (🌎).
+
+
+## RTDetrV2Config
+
+[[autodoc]] RTDetrV2Config
+
+
+## RTDetrV2Model
+
+[[autodoc]] RTDetrV2Model
+ - forward
+
+## RTDetrV2ForObjectDetection
+
+[[autodoc]] RTDetrV2ForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rwkv.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rwkv.md
new file mode 100644
index 0000000000000000000000000000000000000000..4d9d6bbb886000c673cd48fa639acdec4a9b6c16
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rwkv.md
@@ -0,0 +1,155 @@
+
+*This model was released on 2022-08-17 and added to Hugging Face Transformers on 2023-05-09.*
+
+# RWKV
+
+
+
+
+
+## Overview
+
+The RWKV model (version 4) was proposed in [this repo](https://github.com/BlinkDL/RWKV-LM)
+
+It suggests a tweak in the traditional Transformer attention to make it linear. This way, the model can be used as recurrent network: passing inputs for timestamp 0 and timestamp 1 together is the same as passing inputs at timestamp 0, then inputs at timestamp 1 along with the state of timestamp 0 (see example below).
+
+This can be more efficient than a regular Transformer and can deal with sentence of any length (even if the model uses a fixed context length for training).
+
+This model was contributed by [sgugger](https://huggingface.co/sgugger).
+The original code can be found [here](https://github.com/BlinkDL/RWKV-LM).
+
+## Usage example
+
+```py
+import torch
+from transformers import AutoTokenizer, RwkvConfig, RwkvModel
+
+model = RwkvModel.from_pretrained("sgugger/rwkv-430M-pile")
+tokenizer = AutoTokenizer.from_pretrained("sgugger/rwkv-430M-pile")
+
+inputs = tokenizer("This is an example.", return_tensors="pt")
+# Feed everything to the model
+outputs = model(inputs["input_ids"])
+output_whole = outputs.last_hidden_state
+
+outputs = model(inputs["input_ids"][:, :2])
+output_one = outputs.last_hidden_state
+
+# Using the state computed on the first inputs, we will get the same output
+outputs = model(inputs["input_ids"][:, 2:], state=outputs.state)
+output_two = outputs.last_hidden_state
+
+torch.allclose(torch.cat([output_one, output_two], dim=1), output_whole, atol=1e-5)
+```
+
+If you want to make sure the model stops generating when `'\n\n'` is detected, we recommend using the following stopping criteria:
+
+```python
+from transformers import StoppingCriteria
+
+class RwkvStoppingCriteria(StoppingCriteria):
+ def __init__(self, eos_sequence = [187,187], eos_token_id = 537):
+ self.eos_sequence = eos_sequence
+ self.eos_token_id = eos_token_id
+
+ def __call__(self, input_ids: torch.LongTensor, scores: torch.FloatTensor, **kwargs) -> bool:
+ last_2_ids = input_ids[:,-2:].tolist()
+ return self.eos_sequence in last_2_ids
+
+
+output = model.generate(inputs["input_ids"], max_new_tokens=64, stopping_criteria = [RwkvStoppingCriteria()])
+```
+
+## RwkvConfig
+
+[[autodoc]] RwkvConfig
+
+## RwkvModel
+
+[[autodoc]] RwkvModel
+ - forward
+
+## RwkvLMHeadModel
+
+[[autodoc]] RwkvForCausalLM
+ - forward
+
+## Rwkv attention and the recurrent formulas
+
+In a traditional auto-regressive Transformer, attention is written as
+
+$$O = \hbox{softmax}(QK^{T} / \sqrt{d}) V$$
+
+with \\(Q\\), \\(K\\) and \\(V\\) are matrices of shape `seq_len x hidden_size` named query, key and value (they are actually bigger matrices with a batch dimension and an attention head dimension but we're only interested in the last two, which is where the matrix product is taken, so for the sake of simplicity we only consider those two). The product \\(QK^{T}\\) then has shape `seq_len x seq_len` and we can take the matrix product with \\(V\\) to get the output \\(O\\) of the same shape as the others.
+
+Replacing the softmax by its value gives:
+
+$$O_{i} = \frac{\sum_{j=1}^{i} e^{Q_{i} K_{j}^{T} / \sqrt{d}} V_{j}}{\sum_{j=1}^{i} e^{Q_{i} K_{j}^{T} / \sqrt{d}}}$$
+
+Note that the entries in \\(QK^{T}\\) corresponding to \\(j > i\\) are masked (the sum stops at j) because the attention is not allowed to look at future tokens (only past ones).
+
+In comparison, the RWKV attention is given by
+
+$$O_{i} = \sigma(R_{i}) \frac{\sum_{j=1}^{i} e^{W_{i-j} + K_{j}} V_{j}}{\sum_{j=1}^{i} e^{W_{i-j} + K_{j}}}$$
+
+where \\(R\\) is a new matrix called receptance by the author, \\(K\\) and \\(V\\) are still the key and value (\\(\sigma\\) here is the sigmoid function). \\(W\\) is a new vector that represents the position of the token and is given by
+
+$$W_{0} = u \hbox{ and } W_{k} = (k-1)w \hbox{ for } k \geq 1$$
+
+with \\(u\\) and \\(w\\) learnable parameters called in the code `time_first` and `time_decay` respectively. The numerator and denominator can both be expressed recursively. Naming them \\(N_{i}\\) and \\(D_{i}\\) we have:
+
+$$N_{i} = e^{u + K_{i}} V_{i} + \hat{N}_{i} \hbox{ where } \hat{N}_{i} = e^{K_{i-1}} V_{i-1} + e^{w + K_{i-2}} V_{i-2} \cdots + e^{(i-2)w + K_{1}} V_{1}$$
+
+so \\(\hat{N}_{i}\\) (called `numerator_state` in the code) satisfies
+
+$$\hat{N}_{0} = 0 \hbox{ and } \hat{N}_{j+1} = e^{K_{j}} V_{j} + e^{w} \hat{N}_{j}$$
+
+and
+
+$$D_{i} = e^{u + K_{i}} + \hat{D}_{i} \hbox{ where } \hat{D}_{i} = e^{K_{i-1}} + e^{w + K_{i-2}} \cdots + e^{(i-2)w + K_{1}}$$
+
+so \\(\hat{D}_{i}\\) (called `denominator_state` in the code) satisfies
+
+$$\hat{D}_{0} = 0 \hbox{ and } \hat{D}_{j+1} = e^{K_{j}} + e^{w} \hat{D}_{j}$$
+
+The actual recurrent formula used are a tiny bit more complex, as for numerical stability we don't want to compute exponentials of big numbers. Usually the softmax is not computed as is, but the exponential of the maximum term is divided of the numerator and denominator:
+
+$$\frac{e^{x_{i}}}{\sum_{j=1}^{n} e^{x_{j}}} = \frac{e^{x_{i} - M}}{\sum_{j=1}^{n} e^{x_{j} - M}}$$
+
+with \\(M\\) the maximum of all \\(x_{j}\\). So here on top of saving the numerator state (\\(\hat{N}\\)) and the denominator state (\\(\hat{D}\\)) we also keep track of the maximum of all terms encountered in the exponentials. So we actually use
+
+$$\tilde{N}_{i} = e^{-M_{i}} \hat{N}_{i} \hbox{ and } \tilde{D}_{i} = e^{-M_{i}} \hat{D}_{i}$$
+
+defined by the following recurrent formulas:
+
+$$\tilde{N}_{0} = 0 \hbox{ and } \tilde{N}_{j+1} = e^{K_{j} - q} V_{j} + e^{w + M_{j} - q} \tilde{N}_{j} \hbox{ where } q = \max(K_{j}, w + M_{j})$$
+
+and
+
+$$\tilde{D}_{0} = 0 \hbox{ and } \tilde{D}_{j+1} = e^{K_{j} - q} + e^{w + M_{j} - q} \tilde{D}_{j} \hbox{ where } q = \max(K_{j}, w + M_{j})$$
+
+and \\(M_{j+1} = q\\). With those, we can then compute
+
+$$N_{i} = e^{u + K_{i} - q} V_{i} + e^{M_{i}} \tilde{N}_{i} \hbox{ where } q = \max(u + K_{i}, M_{i})$$
+
+and
+
+$$D_{i} = e^{u + K_{i} - q} + e^{M_{i}} \tilde{D}_{i} \hbox{ where } q = \max(u + K_{i}, M_{i})$$
+
+which finally gives us
+
+$$O_{i} = \sigma(R_{i}) \frac{N_{i}}{D_{i}}$$
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sam.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sam.md
new file mode 100644
index 0000000000000000000000000000000000000000..b6d8bc295fe05dd39d9427ae73e53e3478a7545f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sam.md
@@ -0,0 +1,179 @@
+
+*This model was released on 2023-04-05 and added to Hugging Face Transformers on 2023-04-19.*
+
+# SAM
+
+
+
+
+
+
+## Overview
+
+SAM (Segment Anything Model) was proposed in [Segment Anything](https://huggingface.co/papers/2304.02643v1.pdf) by Alexander Kirillov, Eric Mintun, Nikhila Ravi, Hanzi Mao, Chloe Rolland, Laura Gustafson, Tete Xiao, Spencer Whitehead, Alex Berg, Wan-Yen Lo, Piotr Dollar, Ross Girshick.
+
+The model can be used to predict segmentation masks of any object of interest given an input image.
+
+
+
+The abstract from the paper is the following:
+
+*We introduce the Segment Anything (SA) project: a new task, model, and dataset for image segmentation. Using our efficient model in a data collection loop, we built the largest segmentation dataset to date (by far), with over 1 billion masks on 11M licensed and privacy respecting images. The model is designed and trained to be promptable, so it can transfer zero-shot to new image distributions and tasks. We evaluate its capabilities on numerous tasks and find that its zero-shot performance is impressive -- often competitive with or even superior to prior fully supervised results. We are releasing the Segment Anything Model (SAM) and corresponding dataset (SA-1B) of 1B masks and 11M images at [https://segment-anything.com](https://segment-anything.com) to foster research into foundation models for computer vision.*
+
+Tips:
+
+- The model predicts binary masks that states the presence or not of the object of interest given an image.
+- The model predicts much better results if input 2D points and/or input bounding boxes are provided
+- You can prompt multiple points for the same image, and predict a single mask.
+- Fine-tuning the model is not supported yet
+- According to the paper, textual input should be also supported. However, at this time of writing this seems not to be supported according to [the official repository](https://github.com/facebookresearch/segment-anything/issues/4#issuecomment-1497626844).
+
+
+This model was contributed by [ybelkada](https://huggingface.co/ybelkada) and [ArthurZ](https://huggingface.co/ArthurZ).
+The original code can be found [here](https://github.com/facebookresearch/segment-anything).
+
+Below is an example on how to run mask generation given an image and a 2D point:
+
+```python
+import torch
+from PIL import Image
+import requests
+from transformers import SamModel, SamProcessor, infer_device
+
+device = infer_device()
+model = SamModel.from_pretrained("facebook/sam-vit-huge").to(device)
+processor = SamProcessor.from_pretrained("facebook/sam-vit-huge")
+
+img_url = "https://huggingface.co/ybelkada/segment-anything/resolve/main/assets/car.png"
+raw_image = Image.open(requests.get(img_url, stream=True).raw).convert("RGB")
+input_points = [[[450, 600]]] # 2D location of a window in the image
+
+inputs = processor(raw_image, input_points=input_points, return_tensors="pt").to(device)
+with torch.no_grad():
+ outputs = model(**inputs)
+
+masks = processor.image_processor.post_process_masks(
+ outputs.pred_masks.cpu(), inputs["original_sizes"].cpu(), inputs["reshaped_input_sizes"].cpu()
+)
+scores = outputs.iou_scores
+```
+
+You can also process your own masks alongside the input images in the processor to be passed to the model.
+
+```python
+import torch
+from PIL import Image
+import requests
+from transformers import SamModel, SamProcessor, infer_device
+
+device = infer_device()
+model = SamModel.from_pretrained("facebook/sam-vit-huge").to(device)
+processor = SamProcessor.from_pretrained("facebook/sam-vit-huge")
+
+img_url = "https://huggingface.co/ybelkada/segment-anything/resolve/main/assets/car.png"
+raw_image = Image.open(requests.get(img_url, stream=True).raw).convert("RGB")
+mask_url = "https://huggingface.co/ybelkada/segment-anything/resolve/main/assets/car.png"
+segmentation_map = Image.open(requests.get(mask_url, stream=True).raw).convert("1")
+input_points = [[[450, 600]]] # 2D location of a window in the image
+
+inputs = processor(raw_image, input_points=input_points, segmentation_maps=segmentation_map, return_tensors="pt").to(device)
+with torch.no_grad():
+ outputs = model(**inputs)
+
+masks = processor.image_processor.post_process_masks(
+ outputs.pred_masks.cpu(), inputs["original_sizes"].cpu(), inputs["reshaped_input_sizes"].cpu()
+)
+scores = outputs.iou_scores
+```
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with SAM.
+
+- [Demo notebook](https://github.com/huggingface/notebooks/blob/main/examples/segment_anything.ipynb) for using the model.
+- [Demo notebook](https://github.com/huggingface/notebooks/blob/main/examples/automatic_mask_generation.ipynb) for using the automatic mask generation pipeline.
+- [Demo notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/SAM/Run_inference_with_MedSAM_using_HuggingFace_Transformers.ipynb) for inference with MedSAM, a fine-tuned version of SAM on the medical domain. 🌎
+- [Demo notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/SAM/Fine_tune_SAM_(segment_anything)_on_a_custom_dataset.ipynb) for fine-tuning the model on custom data. 🌎
+
+## SlimSAM
+
+SlimSAM, a pruned version of SAM, was proposed in [0.1% Data Makes Segment Anything Slim](https://huggingface.co/papers/2312.05284) by Zigeng Chen et al. SlimSAM reduces the size of the SAM models considerably while maintaining the same performance.
+
+Checkpoints can be found on the [hub](https://huggingface.co/models?other=slimsam), and they can be used as a drop-in replacement of SAM.
+
+## Grounded SAM
+
+One can combine [Grounding DINO](grounding-dino) with SAM for text-based mask generation as introduced in [Grounded SAM: Assembling Open-World Models for Diverse Visual Tasks](https://huggingface.co/papers/2401.14159). You can refer to this [demo notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/Grounding%20DINO/GroundingDINO_with_Segment_Anything.ipynb) 🌍 for details.
+
+
+
+ Grounded SAM overview. Taken from the original repository.
+
+## SamConfig
+
+[[autodoc]] SamConfig
+
+## SamVisionConfig
+
+[[autodoc]] SamVisionConfig
+
+## SamMaskDecoderConfig
+
+[[autodoc]] SamMaskDecoderConfig
+
+## SamPromptEncoderConfig
+
+[[autodoc]] SamPromptEncoderConfig
+
+
+## SamProcessor
+
+[[autodoc]] SamProcessor
+
+
+## SamImageProcessor
+
+[[autodoc]] SamImageProcessor
+
+
+## SamImageProcessorFast
+
+[[autodoc]] SamImageProcessorFast
+
+
+## SamVisionModel
+
+[[autodoc]] SamVisionModel
+ - forward
+
+
+## SamModel
+
+[[autodoc]] SamModel
+ - forward
+
+
+## TFSamVisionModel
+
+[[autodoc]] TFSamVisionModel
+ - call
+
+
+## TFSamModel
+
+[[autodoc]] TFSamModel
+ - call
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sam2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sam2.md
new file mode 100644
index 0000000000000000000000000000000000000000..6cf8e21587cda2e32ec7ab0c2e16201d85a3c4d6
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sam2.md
@@ -0,0 +1,349 @@
+
+
+
+
+
+
+
+
+
+# SAM2
+
+## Overview
+
+SAM2 (Segment Anything Model 2) was proposed in [Segment Anything in Images and Videos](https://ai.meta.com/research/publications/sam-2-segment-anything-in-images-and-videos/) by Nikhila Ravi, Valentin Gabeur, Yuan-Ting Hu, Ronghang Hu, Chaitanya Ryali, Tengyu Ma, Haitham Khedr, Roman Rädle, Chloe Rolland, Laura Gustafson, Eric Mintun, Junting Pan, Kalyan Vasudev Alwala, Nicolas Carion, Chao-Yuan Wu, Ross Girshick, Piotr Dollár, Christoph Feichtenhofer.
+
+The model can be used to predict segmentation masks of any object of interest given an input image or video, and input points or bounding boxes.
+
+
+
+The abstract from the paper is the following:
+
+*We present Segment Anything Model 2 (SAM 2), a foundation model towards solving promptable visual segmentation in images and videos. We build a data engine, which improves model and data via user interaction, to collect the largest video segmentation dataset to date. Our model is a simple transformer architecture with streaming memory for real-time video processing. SAM 2 trained on our data provides strong performance across a wide range of tasks. In video segmentation, we observe better accuracy, using 3x fewer interactions than prior approaches. In image segmentation, our model is more accurate and 6x faster than the Segment Anything Model (SAM). We believe that our data, model, and insights will serve as a significant milestone for video segmentation and related perception tasks. We are releasing a version of our model, the dataset and an interactive demo.*
+
+Tips:
+
+- Batch & Video Support: SAM2 natively supports batch processing and seamless video segmentation, while original SAM is designed for static images and simpler one-image-at-a-time workflows.
+- Accuracy & Generalization: SAM2 shows improved segmentation quality, robustness, and zero-shot generalization to new domains compared to the original SAM, especially with mixed prompts.
+
+This model was contributed by [sangbumchoi](https://github.com/SangbumChoi) and [yonigozlan](https://huggingface.co/yonigozlan).
+The original code can be found [here](https://github.com/facebookresearch/sam2/tree/main).
+
+## Usage example
+
+### Automatic Mask Generation with Pipeline
+
+SAM2 can be used for automatic mask generation to segment all objects in an image using the `mask-generation` pipeline:
+
+```python
+>>> from transformers import pipeline
+
+>>> generator = pipeline("mask-generation", model="facebook/sam2.1-hiera-large", device=0)
+>>> image_url = "https://huggingface.co/datasets/hf-internal-testing/sam2-fixtures/resolve/main/truck.jpg"
+>>> outputs = generator(image_url, points_per_batch=64)
+
+>>> len(outputs["masks"]) # Number of masks generated
+39
+```
+
+### Basic Image Segmentation
+
+#### Single Point Click
+
+You can segment objects by providing a single point click on the object you want to segment:
+
+```python
+>>> from transformers import Sam2Processor, Sam2Model
+>>> import torch
+>>> from PIL import Image
+>>> import requests
+
+>>> device = "cuda" if torch.cuda.is_available() else "cpu"
+
+>>> model = Sam2Model.from_pretrained("facebook/sam2.1-hiera-large").to(device)
+>>> processor = Sam2Processor.from_pretrained("facebook/sam2.1-hiera-large")
+
+>>> image_url = "https://huggingface.co/datasets/hf-internal-testing/sam2-fixtures/resolve/main/truck.jpg"
+>>> raw_image = Image.open(requests.get(image_url, stream=True).raw).convert("RGB")
+
+>>> input_points = [[[[500, 375]]]] # Single point click, 4 dimensions (image_dim, object_dim, point_per_object_dim, coordinates)
+>>> input_labels = [[[1]]] # 1 for positive click, 0 for negative click, 3 dimensions (image_dim, object_dim, point_label)
+
+>>> inputs = processor(images=raw_image, input_points=input_points, input_labels=input_labels, return_tensors="pt").to(device)
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> masks = processor.post_process_masks(outputs.pred_masks.cpu(), inputs["original_sizes"])[0]
+
+>>> # The model outputs multiple mask predictions ranked by quality score
+>>> print(f"Generated {masks.shape[1]} masks with shape {masks.shape}")
+Generated 3 masks with shape torch.Size(1, 3, 1500, 2250)
+```
+
+#### Multiple Points for Refinement
+
+You can provide multiple points to refine the segmentation:
+
+```python
+>>> # Add both positive and negative points to refine the mask
+>>> input_points = [[[[500, 375], [1125, 625]]]] # Multiple points for refinement
+>>> input_labels = [[[1, 1]]] # Both positive clicks
+
+>>> inputs = processor(images=raw_image, input_points=input_points, input_labels=input_labels, return_tensors="pt").to(device)
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> masks = processor.post_process_masks(outputs.pred_masks.cpu(), inputs["original_sizes"])[0]
+```
+
+#### Bounding Box Input
+
+SAM2 also supports bounding box inputs for segmentation:
+
+```python
+>>> # Define bounding box as [x_min, y_min, x_max, y_max]
+>>> input_boxes = [[[75, 275, 1725, 850]]]
+
+>>> inputs = processor(images=raw_image, input_boxes=input_boxes, return_tensors="pt").to(device)
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> masks = processor.post_process_masks(outputs.pred_masks.cpu(), inputs["original_sizes"])[0]
+```
+
+#### Multiple Objects Segmentation
+
+You can segment multiple objects simultaneously:
+
+```python
+>>> # Define points for two different objects
+>>> input_points = [[[[500, 375]], [[650, 750]]]] # Points for two objects in same image
+>>> input_labels = [[[1], [1]]] # Positive clicks for both objects
+
+>>> inputs = processor(images=raw_image, input_points=input_points, input_labels=input_labels, return_tensors="pt").to(device)
+
+>>> with torch.no_grad():
+... outputs = model(**inputs, multimask_output=False)
+
+>>> # Each object gets its own mask
+>>> masks = processor.post_process_masks(outputs.pred_masks.cpu(), inputs["original_sizes"])[0]
+>>> print(f"Generated masks for {masks.shape[0]} objects")
+Generated masks for 2 objects
+```
+
+### Batch Inference
+
+#### Batched Images
+
+Process multiple images simultaneously for improved efficiency:
+
+```python
+>>> from transformers import Sam2Processor, Sam2Model
+>>> import torch
+>>> from PIL import Image
+>>> import requests
+
+>>> device = "cuda" if torch.cuda.is_available() else "cpu"
+
+>>> model = Sam2Model.from_pretrained("facebook/sam2.1-hiera-large").to(device)
+>>> processor = Sam2Processor.from_pretrained("facebook/sam2.1-hiera-large")
+
+>>> # Load multiple images
+>>> image_urls = [
+... "https://huggingface.co/datasets/hf-internal-testing/sam2-fixtures/resolve/main/truck.jpg",
+... "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/model_doc/dog-sam.png"
+... ]
+>>> raw_images = [Image.open(requests.get(url, stream=True).raw).convert("RGB") for url in image_urls]
+
+>>> # Single point per image
+>>> input_points = [[[[500, 375]]], [[[770, 200]]]] # One point for each image
+>>> input_labels = [[[1]], [[1]]] # Positive clicks for both images
+
+>>> inputs = processor(images=raw_images, input_points=input_points, input_labels=input_labels, return_tensors="pt").to(device)
+
+>>> with torch.no_grad():
+... outputs = model(**inputs, multimask_output=False)
+
+>>> # Post-process masks for each image
+>>> all_masks = processor.post_process_masks(outputs.pred_masks.cpu(), inputs["original_sizes"])
+>>> print(f"Processed {len(all_masks)} images, each with {all_masks[0].shape[0]} objects")
+Processed 2 images, each with 1 objects
+```
+
+#### Batched Objects per Image
+
+Segment multiple objects within each image using batch inference:
+
+```python
+>>> # Multiple objects per image - different numbers of objects per image
+>>> input_points = [
+... [[[500, 375]], [[650, 750]]], # Truck image: 2 objects
+... [[[770, 200]]] # Dog image: 1 object
+... ]
+>>> input_labels = [
+... [[1], [1]], # Truck image: positive clicks for both objects
+... [[1]] # Dog image: positive click for the object
+... ]
+
+>>> inputs = processor(images=raw_images, input_points=input_points, input_labels=input_labels, return_tensors="pt").to(device)
+
+>>> with torch.no_grad():
+... outputs = model(**inputs, multimask_output=False)
+
+>>> all_masks = processor.post_process_masks(outputs.pred_masks.cpu(), inputs["original_sizes"])
+```
+
+#### Batched Images with Batched Objects and Multiple Points
+
+Handle complex batch scenarios with multiple points per object:
+
+```python
+>>> # Add groceries image for more complex example
+>>> groceries_url = "https://huggingface.co/datasets/hf-internal-testing/sam2-fixtures/resolve/main/groceries.jpg"
+>>> groceries_image = Image.open(requests.get(groceries_url, stream=True).raw).convert("RGB")
+>>> raw_images = [raw_images[0], groceries_image] # Use truck and groceries images
+
+>>> # Complex batching: multiple images, multiple objects, multiple points per object
+>>> input_points = [
+... [[[500, 375]], [[650, 750]]], # Truck image: 2 objects with 1 point each
+... [[[400, 300]], [[630, 300], [550, 300]]] # Groceries image: obj1 has 1 point, obj2 has 2 points
+... ]
+>>> input_labels = [
+... [[1], [1]], # Truck image: positive clicks
+... [[1], [1, 1]] # Groceries image: positive clicks for refinement
+... ]
+
+>>> inputs = processor(images=raw_images, input_points=input_points, input_labels=input_labels, return_tensors="pt").to(device)
+
+>>> with torch.no_grad():
+... outputs = model(**inputs, multimask_output=False)
+
+>>> all_masks = processor.post_process_masks(outputs.pred_masks.cpu(), inputs["original_sizes"])
+```
+
+#### Batched Bounding Boxes
+
+Process multiple images with bounding box inputs:
+
+```python
+>>> # Multiple bounding boxes per image (using truck and groceries images)
+>>> input_boxes = [
+... [[75, 275, 1725, 850], [425, 600, 700, 875], [1375, 550, 1650, 800], [1240, 675, 1400, 750]], # Truck image: 4 boxes
+... [[450, 170, 520, 350], [350, 190, 450, 350], [500, 170, 580, 350], [580, 170, 640, 350]] # Groceries image: 4 boxes
+... ]
+
+>>> # Update images for this example
+>>> raw_images = [raw_images[0], groceries_image] # truck and groceries
+
+>>> inputs = processor(images=raw_images, input_boxes=input_boxes, return_tensors="pt").to(device)
+
+>>> with torch.no_grad():
+... outputs = model(**inputs, multimask_output=False)
+
+>>> all_masks = processor.post_process_masks(outputs.pred_masks.cpu(), inputs["original_sizes"])
+>>> print(f"Processed {len(input_boxes)} images with {len(input_boxes[0])} and {len(input_boxes[1])} boxes respectively")
+Processed 2 images with 4 and 4 boxes respectively
+```
+
+### Using Previous Masks as Input
+
+SAM2 can use masks from previous predictions as input to refine segmentation:
+
+```python
+>>> # Get initial segmentation
+>>> input_points = [[[[500, 375]]]]
+>>> input_labels = [[[1]]]
+>>> inputs = processor(images=raw_image, input_points=input_points, input_labels=input_labels, return_tensors="pt").to(device)
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> # Use the best mask as input for refinement
+>>> mask_input = outputs.pred_masks[:, :, torch.argmax(outputs.iou_scores.squeeze())]
+
+>>> # Add additional points with the mask input
+>>> new_input_points = [[[[500, 375], [450, 300]]]]
+>>> new_input_labels = [[[1, 1]]]
+>>> inputs = processor(
+... input_points=new_input_points,
+... input_labels=new_input_labels,
+... original_sizes=inputs["original_sizes"],
+... return_tensors="pt",
+... ).to(device)
+
+>>> with torch.no_grad():
+... refined_outputs = model(
+... **inputs,
+... input_masks=mask_input,
+... image_embeddings=outputs.image_embeddings,
+... multimask_output=False,
+... )
+```
+
+
+
+
+
+## Sam2Config
+
+[[autodoc]] Sam2Config
+
+## Sam2HieraDetConfig
+
+[[autodoc]] Sam2HieraDetConfig
+
+## Sam2VisionConfig
+
+[[autodoc]] Sam2VisionConfig
+
+## Sam2MaskDecoderConfig
+
+[[autodoc]] Sam2MaskDecoderConfig
+
+## Sam2PromptEncoderConfig
+
+[[autodoc]] Sam2PromptEncoderConfig
+
+## Sam2Processor
+
+[[autodoc]] Sam2Processor
+ - __call__
+ - post_process_masks
+
+## Sam2ImageProcessorFast
+
+[[autodoc]] Sam2ImageProcessorFast
+
+## Sam2HieraDetModel
+
+[[autodoc]] Sam2HieraDetModel
+ - forward
+
+## Sam2VisionModel
+
+[[autodoc]] Sam2VisionModel
+ - forward
+
+## Sam2Model
+
+[[autodoc]] Sam2Model
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sam2_video.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sam2_video.md
new file mode 100644
index 0000000000000000000000000000000000000000..67d4584b48b143c179d88f1e097291b90851b33f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sam2_video.md
@@ -0,0 +1,315 @@
+
+
+
+
+
+
+
+
+
+# SAM2 Video
+
+## Overview
+
+SAM2 (Segment Anything Model 2) was proposed in [Segment Anything in Images and Videos](https://ai.meta.com/research/publications/sam-2-segment-anything-in-images-and-videos/) by Nikhila Ravi, Valentin Gabeur, Yuan-Ting Hu, Ronghang Hu, Chaitanya Ryali, Tengyu Ma, Haitham Khedr, Roman Rädle, Chloe Rolland, Laura Gustafson, Eric Mintun, Junting Pan, Kalyan Vasudev Alwala, Nicolas Carion, Chao-Yuan Wu, Ross Girshick, Piotr Dollár, Christoph Feichtenhofer.
+
+The model can be used to predict segmentation masks of any object of interest given an input image or video, and input points or bounding boxes.
+
+
+
+The abstract from the paper is the following:
+
+*We present Segment Anything Model 2 (SAM 2), a foundation model towards solving promptable visual segmentation in images and videos. We build a data engine, which improves model and data via user interaction, to collect the largest video segmentation dataset to date. Our model is a simple transformer architecture with streaming memory for real-time video processing. SAM 2 trained on our data provides strong performance across a wide range of tasks. In video segmentation, we observe better accuracy, using 3x fewer interactions than prior approaches. In image segmentation, our model is more accurate and 6x faster than the Segment Anything Model (SAM). We believe that our data, model, and insights will serve as a significant milestone for video segmentation and related perception tasks. We are releasing a version of our model, the dataset and an interactive demo.*
+
+Tips:
+
+- Batch & Video Support: SAM2 natively supports batch processing and seamless video segmentation, while original SAM is designed for static images and simpler one-image-at-a-time workflows.
+- Accuracy & Generalization: SAM2 shows improved segmentation quality, robustness, and zero-shot generalization to new domains compared to the original SAM, especially with mixed prompts.
+
+This model was contributed by [sangbumchoi](https://github.com/SangbumChoi) and [yonigozlan](https://huggingface.co/yonigozlan).
+The original code can be found [here](https://github.com/facebookresearch/sam2/tree/main).
+
+## Usage example
+
+### Video Segmentation and Tracking
+
+SAM2's key strength is its ability to track objects across video frames. Here's how to use it for video segmentation:
+
+#### Basic Video Tracking
+
+```python
+>>> from transformers import Sam2VideoModel, Sam2VideoProcessor, infer_device
+>>> import torch
+
+>>> device = infer_device()
+>>> model = Sam2VideoModel.from_pretrained("facebook/sam2.1-hiera-tiny").to(device, dtype=torch.bfloat16)
+>>> processor = Sam2VideoProcessor.from_pretrained("facebook/sam2.1-hiera-tiny")
+
+>>> # Load video frames (example assumes you have a list of PIL Images)
+>>> # video_frames = [Image.open(f"frame_{i:05d}.jpg") for i in range(num_frames)]
+
+>>> # For this example, we'll use the video loading utility
+>>> from transformers.video_utils import load_video
+>>> video_url = "https://huggingface.co/datasets/hf-internal-testing/sam2-fixtures/resolve/main/bedroom.mp4"
+>>> video_frames, _ = load_video(video_url)
+
+>>> # Initialize video inference session
+>>> inference_session = processor.init_video_session(
+... video=video_frames,
+... inference_device=device,
+... torch_dtype=torch.bfloat16,
+... )
+
+>>> # Add click on first frame to select object
+>>> ann_frame_idx = 0
+>>> ann_obj_id = 1
+>>> points = [[[[210, 350]]]]
+>>> labels = [[[1]]]
+
+>>> processor.add_inputs_to_inference_session(
+... inference_session=inference_session,
+... frame_idx=ann_frame_idx,
+... obj_ids=ann_obj_id,
+... input_points=points,
+... input_labels=labels,
+... )
+
+>>> # Segment the object on the first frame
+>>> outputs = model(
+... inference_session=inference_session,
+... frame_idx=ann_frame_idx,
+... )
+>>> video_res_masks = processor.post_process_masks(
+... [outputs.pred_masks], original_sizes=[[inference_session.video_height, inference_session.video_width]], binarize=False
+... )[0]
+>>> print(f"Segmentation shape: {video_res_masks.shape}")
+Segmentation shape: torch.Size([1, 1, 480, 854])
+
+>>> # Propagate through the entire video
+>>> video_segments = {}
+>>> for sam2_video_output in model.propagate_in_video_iterator(inference_session):
+... video_res_masks = processor.post_process_masks(
+... [sam2_video_output.pred_masks], original_sizes=[[inference_session.video_height, inference_session.video_width]], binarize=False
+... )[0]
+... video_segments[sam2_video_output.frame_idx] = video_res_masks
+
+>>> print(f"Tracked object through {len(video_segments)} frames")
+Tracked object through 180 frames
+```
+
+#### Multi-Object Video Tracking
+
+Track multiple objects simultaneously across video frames:
+
+```python
+>>> # Reset for new tracking session
+>>> inference_session.reset_inference_session()
+
+>>> # Add multiple objects on the first frame
+>>> ann_frame_idx = 0
+>>> obj_ids = [2, 3]
+>>> input_points = [[[[200, 300]], [[400, 150]]]] # Points for two objects (batched)
+>>> input_labels = [[[1], [1]]]
+
+>>> processor.add_inputs_to_inference_session(
+... inference_session=inference_session,
+... frame_idx=ann_frame_idx,
+... obj_ids=obj_ids,
+... input_points=input_points,
+... input_labels=input_labels,
+... )
+
+>>> # Get masks for both objects on first frame
+>>> outputs = model(
+... inference_session=inference_session,
+... frame_idx=ann_frame_idx,
+... )
+
+>>> # Propagate both objects through video
+>>> video_segments = {}
+>>> for sam2_video_output in model.propagate_in_video_iterator(inference_session):
+... video_res_masks = processor.post_process_masks(
+... [sam2_video_output.pred_masks], original_sizes=[[inference_session.video_height, inference_session.video_width]], binarize=False
+... )[0]
+... video_segments[sam2_video_output.frame_idx] = {
+... obj_id: video_res_masks[i]
+... for i, obj_id in enumerate(inference_session.obj_ids)
+... }
+
+>>> print(f"Tracked {len(inference_session.obj_ids)} objects through {len(video_segments)} frames")
+Tracked 2 objects through 180 frames
+```
+
+#### Refining Video Segmentation
+
+You can add additional clicks on any frame to refine the tracking:
+
+```python
+>>> # Add refinement click on a later frame
+>>> refine_frame_idx = 50
+>>> ann_obj_id = 2 # Refining first object
+>>> points = [[[[220, 280]]]] # Additional point
+>>> labels = [[[1]]] # Positive click
+
+>>> processor.add_inputs_to_inference_session(
+... inference_session=inference_session,
+... frame_idx=refine_frame_idx,
+... obj_ids=ann_obj_id,
+... input_points=points,
+... input_labels=labels,
+... )
+
+>>> # Re-propagate with the additional information
+>>> video_segments = {}
+>>> for sam2_video_output in model.propagate_in_video_iterator(inference_session):
+... video_res_masks = processor.post_process_masks(
+... [sam2_video_output.pred_masks], original_sizes=[[inference_session.video_height, inference_session.video_width]], binarize=False
+... )[0]
+... video_segments[sam2_video_output.frame_idx] = video_res_masks
+```
+
+### Streaming Video Inference
+
+For real-time applications, SAM2 supports processing video frames as they arrive:
+
+```python
+>>> # Initialize session for streaming
+>>> inference_session = processor.init_video_session(
+... inference_device=device,
+... torch_dtype=torch.bfloat16,
+... )
+
+>>> # Process frames one by one
+>>> for frame_idx, frame in enumerate(video_frames[:10]): # Process first 10 frames
+... inputs = processor(images=frame, device=device, return_tensors="pt")
+...
+... if frame_idx == 0:
+... # Add point input on first frame
+... processor.add_inputs_to_inference_session(
+... inference_session=inference_session,
+... frame_idx=0,
+... obj_ids=1,
+... input_points=[[[[210, 350], [250, 220]]]],
+... input_labels=[[[1, 1]]],
+... original_size=inputs.original_sizes[0], # need to be provided when using streaming video inference
+... )
+...
+... # Process current frame
+... sam2_video_output = model(inference_session=inference_session, frame=inputs.pixel_values[0])
+...
+... video_res_masks = processor.post_process_masks(
+... [sam2_video_output.pred_masks], original_sizes=inputs.original_sizes, binarize=False
+... )[0]
+... print(f"Frame {frame_idx}: mask shape {video_res_masks.shape}")
+```
+
+#### Video Batch Processing for Multiple Objects
+
+Track multiple objects simultaneously in video by adding them all at once:
+
+```python
+>>> # Initialize video session
+>>> inference_session = processor.init_video_session(
+... video=video_frames,
+... inference_device=device,
+... torch_dtype=torch.bfloat16,
+... )
+
+>>> # Add multiple objects on the first frame using batch processing
+>>> ann_frame_idx = 0
+>>> obj_ids = [2, 3] # Track two different objects
+>>> input_points = [
+... [[[200, 300], [230, 250], [275, 175]], [[400, 150]]]
+... ] # Object 2: 3 points (2 positive, 1 negative); Object 3: 1 point
+>>> input_labels = [
+... [[1, 1, 0], [1]]
+... ] # Object 2: positive, positive, negative; Object 3: positive
+
+>>> processor.add_inputs_to_inference_session(
+... inference_session=inference_session,
+... frame_idx=ann_frame_idx,
+... obj_ids=obj_ids,
+... input_points=input_points,
+... input_labels=input_labels,
+... )
+
+>>> # Get masks for all objects on the first frame
+>>> outputs = model(
+... inference_session=inference_session,
+... frame_idx=ann_frame_idx,
+... )
+>>> video_res_masks = processor.post_process_masks(
+... [outputs.pred_masks], original_sizes=[[inference_session.video_height, inference_session.video_width]], binarize=False
+... )[0]
+>>> print(f"Generated masks for {video_res_masks.shape[0]} objects")
+Generated masks for 2 objects
+
+>>> # Propagate all objects through the video
+>>> video_segments = {}
+>>> for sam2_video_output in model.propagate_in_video_iterator(inference_session):
+... video_res_masks = processor.post_process_masks(
+... [sam2_video_output.pred_masks], original_sizes=[[inference_session.video_height, inference_session.video_width]], binarize=False
+... )[0]
+... video_segments[sam2_video_output.frame_idx] = {
+... obj_id: video_res_masks[i]
+... for i, obj_id in enumerate(inference_session.obj_ids)
+... }
+
+>>> print(f"Tracked {len(inference_session.obj_ids)} objects through {len(video_segments)} frames")
+Tracked 2 objects through 180 frames
+```
+
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with SAM.
+
+- [Demo notebook 🌎](https://colab.research.google.com/drive/1Z0NGLE7p8qnc9UpuI8KBETHd2xBbOEhv?usp=sharing) for using the model, contributed by [Sangbum Choi](https://github.com/SangbumChoi).
+
+## Sam2VideoConfig
+
+[[autodoc]] Sam2VideoConfig
+
+## Sam2VideoMaskDecoderConfig
+
+[[autodoc]] Sam2VideoMaskDecoderConfig
+
+## Sam2VideoPromptEncoderConfig
+
+[[autodoc]] Sam2VideoPromptEncoderConfig
+
+## Sam2VideoProcessor
+
+[[autodoc]] Sam2VideoProcessor
+ - __call__
+ - post_process_masks
+ - init_video_session
+ - add_inputs_to_inference_session
+
+## Sam2VideoVideoProcessor
+
+[[autodoc]] Sam2VideoVideoProcessor
+
+## Sam2VideoInferenceSession
+
+[[autodoc]] Sam2VideoInferenceSession
+
+## Sam2VideoModel
+
+[[autodoc]] Sam2VideoModel
+ - forward
+ - propagate_in_video_iterator
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sam_hq.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sam_hq.md
new file mode 100644
index 0000000000000000000000000000000000000000..2bd14229c37c3bb1b4b9199c24949f56768f2156
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sam_hq.md
@@ -0,0 +1,144 @@
+
+*This model was released on 2023-06-02 and added to Hugging Face Transformers on 2025-04-28.*
+
+# SAM-HQ
+
+## Overview
+
+SAM-HQ (High-Quality Segment Anything Model) was proposed in [Segment Anything in High Quality](https://huggingface.co/papers/2306.01567) by Lei Ke, Mingqiao Ye, Martin Danelljan, Yifan Liu, Yu-Wing Tai, Chi-Keung Tang, Fisher Yu.
+
+The model is an enhancement to the original SAM model that produces significantly higher quality segmentation masks while maintaining SAM's original promptable design, efficiency, and zero-shot generalizability.
+
+
+
+
+SAM-HQ introduces several key improvements over the original SAM model:
+
+1. High-Quality Output Token: A learnable token injected into SAM's mask decoder for higher quality mask prediction
+2. Global-local Feature Fusion: Combines features from different stages of the model for improved mask details
+3. Training Data: Uses a carefully curated dataset of 44K high-quality masks instead of SA-1B
+4. Efficiency: Adds only 0.5% additional parameters while significantly improving mask quality
+5. Zero-shot Capability: Maintains SAM's strong zero-shot performance while improving accuracy
+
+The abstract from the paper is the following:
+
+*The recent Segment Anything Model (SAM) represents a big leap in scaling up segmentation models, allowing for powerful zero-shot capabilities and flexible prompting. Despite being trained with 1.1 billion masks, SAM's mask prediction quality falls short in many cases, particularly when dealing with objects that have intricate structures. We propose HQ-SAM, equipping SAM with the ability to accurately segment any object, while maintaining SAM's original promptable design, efficiency, and zero-shot generalizability. Our careful design reuses and preserves the pre-trained model weights of SAM, while only introducing minimal additional parameters and computation. We design a learnable High-Quality Output Token, which is injected into SAM's mask decoder and is responsible for predicting the high-quality mask. Instead of only applying it on mask-decoder features, we first fuse them with early and final ViT features for improved mask details. To train our introduced learnable parameters, we compose a dataset of 44K fine-grained masks from several sources. HQ-SAM is only trained on the introduced dataset of 44k masks, which takes only 4 hours on 8 GPUs.*
+
+Tips:
+
+- SAM-HQ produces higher quality masks than the original SAM model, particularly for objects with intricate structures and fine details
+- The model predicts binary masks with more accurate boundaries and better handling of thin structures
+- Like SAM, the model performs better with input 2D points and/or input bounding boxes
+- You can prompt multiple points for the same image and predict a single high-quality mask
+- The model maintains SAM's zero-shot generalization capabilities
+- SAM-HQ only adds ~0.5% additional parameters compared to SAM
+- Fine-tuning the model is not supported yet
+
+This model was contributed by [sushmanth](https://huggingface.co/sushmanth).
+The original code can be found [here](https://github.com/SysCV/SAM-HQ).
+
+Below is an example on how to run mask generation given an image and a 2D point:
+
+```python
+import torch
+from PIL import Image
+import requests
+from transformers import infer_device, SamHQModel, SamHQProcessor
+
+device = infer_device()
+model = SamHQModel.from_pretrained("syscv-community/sam-hq-vit-base").to(device)
+processor = SamHQProcessor.from_pretrained("syscv-community/sam-hq-vit-base")
+
+img_url = "https://huggingface.co/ybelkada/segment-anything/resolve/main/assets/car.png"
+raw_image = Image.open(requests.get(img_url, stream=True).raw).convert("RGB")
+input_points = [[[450, 600]]] # 2D location of a window in the image
+
+inputs = processor(raw_image, input_points=input_points, return_tensors="pt").to(model.device)
+with torch.no_grad():
+ outputs = model(**inputs)
+
+masks = processor.image_processor.post_process_masks(
+ outputs.pred_masks.cpu(), inputs["original_sizes"].cpu(), inputs["reshaped_input_sizes"].cpu()
+)
+scores = outputs.iou_scores
+```
+
+You can also process your own masks alongside the input images in the processor to be passed to the model:
+
+```python
+import torch
+from PIL import Image
+import requests
+from transformers import infer_device, SamHQModel, SamHQProcessor
+
+device = infer_device()
+model = SamHQModel.from_pretrained("syscv-community/sam-hq-vit-base").to(device)
+processor = SamHQProcessor.from_pretrained("syscv-community/sam-hq-vit-base")
+
+img_url = "https://huggingface.co/ybelkada/segment-anything/resolve/main/assets/car.png"
+raw_image = Image.open(requests.get(img_url, stream=True).raw).convert("RGB")
+mask_url = "https://huggingface.co/ybelkada/segment-anything/resolve/main/assets/car.png"
+segmentation_map = Image.open(requests.get(mask_url, stream=True).raw).convert("1")
+input_points = [[[450, 600]]] # 2D location of a window in the image
+
+inputs = processor(raw_image, input_points=input_points, segmentation_maps=segmentation_map, return_tensors="pt").to(model.device)
+with torch.no_grad():
+ outputs = model(**inputs)
+
+masks = processor.image_processor.post_process_masks(
+ outputs.pred_masks.cpu(), inputs["original_sizes"].cpu(), inputs["reshaped_input_sizes"].cpu()
+)
+scores = outputs.iou_scores
+```
+
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with SAM-HQ:
+
+- Demo notebook for using the model (coming soon)
+- Paper implementation and code: [SAM-HQ GitHub Repository](https://github.com/SysCV/SAM-HQ)
+
+## SamHQConfig
+
+[[autodoc]] SamHQConfig
+
+## SamHQVisionConfig
+
+[[autodoc]] SamHQVisionConfig
+
+## SamHQMaskDecoderConfig
+
+[[autodoc]] SamHQMaskDecoderConfig
+
+## SamHQPromptEncoderConfig
+
+[[autodoc]] SamHQPromptEncoderConfig
+
+## SamHQProcessor
+
+[[autodoc]] SamHQProcessor
+
+## SamHQVisionModel
+
+[[autodoc]] SamHQVisionModel
+
+
+## SamHQModel
+
+[[autodoc]] SamHQModel
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/seamless_m4t.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/seamless_m4t.md
new file mode 100644
index 0000000000000000000000000000000000000000..c6f3a56f9ba11e674331ac350c0581f3e0460ec8
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/seamless_m4t.md
@@ -0,0 +1,225 @@
+
+*This model was released on 2023-08-22 and added to Hugging Face Transformers on 2023-10-23.*
+
+# SeamlessM4T
+
+
+
+
+
+## Overview
+
+The SeamlessM4T model was proposed in [SeamlessM4T — Massively Multilingual & Multimodal Machine Translation](https://huggingface.co/papers/2308.11596) by the Seamless Communication team from Meta AI.
+
+This is the **version 1** release of the model. For the updated **version 2** release, refer to the [Seamless M4T v2 docs](https://huggingface.co/docs/transformers/main/model_doc/seamless_m4t_v2).
+
+SeamlessM4T is a collection of models designed to provide high quality translation, allowing people from different linguistic communities to communicate effortlessly through speech and text.
+
+SeamlessM4T enables multiple tasks without relying on separate models:
+
+- Speech-to-speech translation (S2ST)
+- Speech-to-text translation (S2TT)
+- Text-to-speech translation (T2ST)
+- Text-to-text translation (T2TT)
+- Automatic speech recognition (ASR)
+
+[`SeamlessM4TModel`] can perform all the above tasks, but each task also has its own dedicated sub-model.
+
+The abstract from the paper is the following:
+
+*What does it take to create the Babel Fish, a tool that can help individuals translate speech between any two languages? While recent breakthroughs in text-based models have pushed machine translation coverage beyond 200 languages, unified speech-to-speech translation models have yet to achieve similar strides. More specifically, conventional speech-to-speech translation systems rely on cascaded systems that perform translation progressively, putting high-performing unified systems out of reach. To address these gaps, we introduce SeamlessM4T, a single model that supports speech-to-speech translation, speech-to-text translation, text-to-speech translation, text-to-text translation, and automatic speech recognition for up to 100 languages. To build this, we used 1 million hours of open speech audio data to learn self-supervised speech representations with w2v-BERT 2.0. Subsequently, we created a multimodal corpus of automatically aligned speech translations. Filtered and combined with human-labeled and pseudo-labeled data, we developed the first multilingual system capable of translating from and into English for both speech and text. On FLEURS, SeamlessM4T sets a new standard for translations into multiple target languages, achieving an improvement of 20% BLEU over the previous SOTA in direct speech-to-text translation. Compared to strong cascaded models, SeamlessM4T improves the quality of into-English translation by 1.3 BLEU points in speech-to-text and by 2.6 ASR-BLEU points in speech-to-speech. Tested for robustness, our system performs better against background noises and speaker variations in speech-to-text tasks compared to the current SOTA model. Critically, we evaluated SeamlessM4T on gender bias and added toxicity to assess translation safety. Finally, all contributions in this work are open-sourced and accessible at https://github.com/facebookresearch/seamless_communication*
+
+## Usage
+
+First, load the processor and a checkpoint of the model:
+
+```python
+>>> from transformers import AutoProcessor, SeamlessM4TModel
+
+>>> processor = AutoProcessor.from_pretrained("facebook/hf-seamless-m4t-medium")
+>>> model = SeamlessM4TModel.from_pretrained("facebook/hf-seamless-m4t-medium")
+```
+
+You can seamlessly use this model on text or on audio, to generated either translated text or translated audio.
+
+Here is how to use the processor to process text and audio:
+
+```python
+>>> # let's load an audio sample from an Arabic speech corpus
+>>> from datasets import load_dataset
+>>> dataset = load_dataset("halabi2016/arabic_speech_corpus", split="test", streaming=True)
+>>> audio_sample = next(iter(dataset))["audio"]
+
+>>> # now, process it
+>>> audio_inputs = processor(audios=audio_sample["array"], return_tensors="pt")
+
+>>> # now, process some English test as well
+>>> text_inputs = processor(text = "Hello, my dog is cute", src_lang="eng", return_tensors="pt")
+```
+
+
+### Speech
+
+[`SeamlessM4TModel`] can *seamlessly* generate text or speech with few or no changes. Let's target Russian voice translation:
+
+```python
+>>> audio_array_from_text = model.generate(**text_inputs, tgt_lang="rus")[0].cpu().numpy().squeeze()
+>>> audio_array_from_audio = model.generate(**audio_inputs, tgt_lang="rus")[0].cpu().numpy().squeeze()
+```
+
+With basically the same code, I've translated English text and Arabic speech to Russian speech samples.
+
+### Text
+
+Similarly, you can generate translated text from audio files or from text with the same model. You only have to pass `generate_speech=False` to [`SeamlessM4TModel.generate`].
+This time, let's translate to French.
+
+```python
+>>> # from audio
+>>> output_tokens = model.generate(**audio_inputs, tgt_lang="fra", generate_speech=False)
+>>> translated_text_from_audio = processor.decode(output_tokens[0].tolist()[0], skip_special_tokens=True)
+
+>>> # from text
+>>> output_tokens = model.generate(**text_inputs, tgt_lang="fra", generate_speech=False)
+>>> translated_text_from_text = processor.decode(output_tokens[0].tolist()[0], skip_special_tokens=True)
+```
+
+### Tips
+
+
+#### 1. Use dedicated models
+
+[`SeamlessM4TModel`] is transformers top level model to generate speech and text, but you can also use dedicated models that perform the task without additional components, thus reducing the memory footprint.
+For example, you can replace the audio-to-audio generation snippet with the model dedicated to the S2ST task, the rest is exactly the same code:
+
+```python
+>>> from transformers import SeamlessM4TForSpeechToSpeech
+>>> model = SeamlessM4TForSpeechToSpeech.from_pretrained("facebook/hf-seamless-m4t-medium")
+```
+
+Or you can replace the text-to-text generation snippet with the model dedicated to the T2TT task, you only have to remove `generate_speech=False`.
+
+```python
+>>> from transformers import SeamlessM4TForTextToText
+>>> model = SeamlessM4TForTextToText.from_pretrained("facebook/hf-seamless-m4t-medium")
+```
+
+Feel free to try out [`SeamlessM4TForSpeechToText`] and [`SeamlessM4TForTextToSpeech`] as well.
+
+#### 2. Change the speaker identity
+
+You have the possibility to change the speaker used for speech synthesis with the `spkr_id` argument. Some `spkr_id` works better than other for some languages!
+
+#### 3. Change the generation strategy
+
+You can use different [generation strategies](./generation_strategies) for speech and text generation, e.g `.generate(input_ids=input_ids, text_num_beams=4, speech_do_sample=True)` which will successively perform beam-search decoding on the text model, and multinomial sampling on the speech model.
+
+#### 4. Generate speech and text at the same time
+
+Use `return_intermediate_token_ids=True` with [`SeamlessM4TModel`] to return both speech and text !
+
+## Model architecture
+
+
+SeamlessM4T features a versatile architecture that smoothly handles the sequential generation of text and speech. This setup comprises two sequence-to-sequence (seq2seq) models. The first model translates the input modality into translated text, while the second model generates speech tokens, known as "unit tokens," from the translated text.
+
+Each modality has its own dedicated encoder with a unique architecture. Additionally, for speech output, a vocoder inspired by the [HiFi-GAN](https://huggingface.co/papers/2010.05646) architecture is placed on top of the second seq2seq model.
+
+Here's how the generation process works:
+
+- Input text or speech is processed through its specific encoder.
+- A decoder creates text tokens in the desired language.
+- If speech generation is required, the second seq2seq model, following a standard encoder-decoder structure, generates unit tokens.
+- These unit tokens are then passed through the final vocoder to produce the actual speech.
+
+
+This model was contributed by [ylacombe](https://huggingface.co/ylacombe). The original code can be found [here](https://github.com/facebookresearch/seamless_communication).
+
+## SeamlessM4TModel
+
+[[autodoc]] SeamlessM4TModel
+ - generate
+
+
+## SeamlessM4TForTextToSpeech
+
+[[autodoc]] SeamlessM4TForTextToSpeech
+ - generate
+
+
+## SeamlessM4TForSpeechToSpeech
+
+[[autodoc]] SeamlessM4TForSpeechToSpeech
+ - generate
+
+
+## SeamlessM4TForTextToText
+
+[[autodoc]] transformers.SeamlessM4TForTextToText
+ - forward
+ - generate
+
+## SeamlessM4TForSpeechToText
+
+[[autodoc]] transformers.SeamlessM4TForSpeechToText
+ - forward
+ - generate
+
+## SeamlessM4TConfig
+
+[[autodoc]] SeamlessM4TConfig
+
+
+## SeamlessM4TTokenizer
+
+[[autodoc]] SeamlessM4TTokenizer
+ - __call__
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+
+## SeamlessM4TTokenizerFast
+
+[[autodoc]] SeamlessM4TTokenizerFast
+ - __call__
+
+## SeamlessM4TFeatureExtractor
+
+[[autodoc]] SeamlessM4TFeatureExtractor
+ - __call__
+
+## SeamlessM4TProcessor
+
+[[autodoc]] SeamlessM4TProcessor
+ - __call__
+
+## SeamlessM4TCodeHifiGan
+
+[[autodoc]] SeamlessM4TCodeHifiGan
+
+
+## SeamlessM4THifiGan
+
+[[autodoc]] SeamlessM4THifiGan
+
+## SeamlessM4TTextToUnitModel
+
+[[autodoc]] SeamlessM4TTextToUnitModel
+
+## SeamlessM4TTextToUnitForConditionalGeneration
+
+[[autodoc]] SeamlessM4TTextToUnitForConditionalGeneration
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/seamless_m4t_v2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/seamless_m4t_v2.md
new file mode 100644
index 0000000000000000000000000000000000000000..8a4ab82d2e980c9b932b829a08282ba364e86260
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/seamless_m4t_v2.md
@@ -0,0 +1,199 @@
+
+*This model was released on 2023-12-08 and added to Hugging Face Transformers on 2023-11-30.*
+
+# SeamlessM4T-v2
+
+
+
+
+
+## Overview
+
+The SeamlessM4T-v2 model was proposed in [Seamless: Multilingual Expressive and Streaming Speech Translation](https://huggingface.co/papers/2312.05187) by the Seamless Communication team from Meta AI.
+
+SeamlessM4T-v2 is a collection of models designed to provide high quality translation, allowing people from different linguistic communities to communicate effortlessly through speech and text. It is an improvement on the [previous version](https://huggingface.co/docs/transformers/main/model_doc/seamless_m4t). For more details on the differences between v1 and v2, refer to section [Difference with SeamlessM4T-v1](#difference-with-seamlessm4t-v1).
+
+SeamlessM4T-v2 enables multiple tasks without relying on separate models:
+
+- Speech-to-speech translation (S2ST)
+- Speech-to-text translation (S2TT)
+- Text-to-speech translation (T2ST)
+- Text-to-text translation (T2TT)
+- Automatic speech recognition (ASR)
+
+[`SeamlessM4Tv2Model`] can perform all the above tasks, but each task also has its own dedicated sub-model.
+
+The abstract from the paper is the following:
+
+*Recent advancements in automatic speech translation have dramatically expanded language coverage, improved multimodal capabilities, and enabled a wide range of tasks and functionalities. That said, large-scale automatic speech translation systems today lack key features that help machine-mediated communication feel seamless when compared to human-to-human dialogue. In this work, we introduce a family of models that enable end-to-end expressive and multilingual translations in a streaming fashion. First, we contribute an improved version of the massively multilingual and multimodal SeamlessM4T model—SeamlessM4T v2. This newer model, incorporating an updated UnitY2 framework, was trained on more low-resource language data. The expanded version of SeamlessAlign adds 114,800 hours of automatically aligned data for a total of 76 languages. SeamlessM4T v2 provides the foundation on which our two newest models, SeamlessExpressive and SeamlessStreaming, are initiated. SeamlessExpressive enables translation that preserves vocal styles and prosody. Compared to previous efforts in expressive speech research, our work addresses certain underexplored aspects of prosody, such as speech rate and pauses, while also preserving the style of one’s voice. As for SeamlessStreaming, our model leverages the Efficient Monotonic Multihead Attention (EMMA) mechanism to generate low-latency target translations without waiting for complete source utterances. As the first of its kind, SeamlessStreaming enables simultaneous speech-to-speech/text translation for multiple source and target languages. To understand the performance of these models, we combined novel and modified versions of existing automatic metrics to evaluate prosody, latency, and robustness. For human evaluations, we adapted existing protocols tailored for measuring the most relevant attributes in the preservation of meaning, naturalness, and expressivity. To ensure that our models can be used safely and responsibly, we implemented the first known red-teaming effort for multimodal machine translation, a system for the detection and mitigation of added toxicity, a systematic evaluation of gender bias, and an inaudible localized watermarking mechanism designed to dampen the impact of deepfakes. Consequently, we bring major components from SeamlessExpressive and SeamlessStreaming together to form Seamless, the first publicly available system that unlocks expressive cross-lingual communication in real-time. In sum, Seamless gives us a pivotal look at the technical foundation needed to turn the Universal Speech Translator from a science fiction concept into a real-world technology. Finally, contributions in this work—including models, code, and a watermark detector—are publicly released and accessible at the link below.*
+
+## Usage
+
+In the following example, we'll load an Arabic audio sample and an English text sample and convert them into Russian speech and French text.
+
+First, load the processor and a checkpoint of the model:
+
+```python
+>>> from transformers import AutoProcessor, SeamlessM4Tv2Model
+
+>>> processor = AutoProcessor.from_pretrained("facebook/seamless-m4t-v2-large")
+>>> model = SeamlessM4Tv2Model.from_pretrained("facebook/seamless-m4t-v2-large")
+```
+
+You can seamlessly use this model on text or on audio, to generated either translated text or translated audio.
+
+Here is how to use the processor to process text and audio:
+
+```python
+>>> # let's load an audio sample from an Arabic speech corpus
+>>> from datasets import load_dataset
+>>> dataset = load_dataset("halabi2016/arabic_speech_corpus", split="test", streaming=True)
+>>> audio_sample = next(iter(dataset))["audio"]
+
+>>> # now, process it
+>>> audio_inputs = processor(audios=audio_sample["array"], return_tensors="pt")
+
+>>> # now, process some English text as well
+>>> text_inputs = processor(text = "Hello, my dog is cute", src_lang="eng", return_tensors="pt")
+```
+
+
+### Speech
+
+[`SeamlessM4Tv2Model`] can *seamlessly* generate text or speech with few or no changes. Let's target Russian voice translation:
+
+```python
+>>> audio_array_from_text = model.generate(**text_inputs, tgt_lang="rus")[0].cpu().numpy().squeeze()
+>>> audio_array_from_audio = model.generate(**audio_inputs, tgt_lang="rus")[0].cpu().numpy().squeeze()
+```
+
+With basically the same code, I've translated English text and Arabic speech to Russian speech samples.
+
+### Text
+
+Similarly, you can generate translated text from audio files or from text with the same model. You only have to pass `generate_speech=False` to [`SeamlessM4Tv2Model.generate`].
+This time, let's translate to French.
+
+```python
+>>> # from audio
+>>> output_tokens = model.generate(**audio_inputs, tgt_lang="fra", generate_speech=False)
+>>> translated_text_from_audio = processor.decode(output_tokens[0].tolist()[0], skip_special_tokens=True)
+
+>>> # from text
+>>> output_tokens = model.generate(**text_inputs, tgt_lang="fra", generate_speech=False)
+>>> translated_text_from_text = processor.decode(output_tokens[0].tolist()[0], skip_special_tokens=True)
+```
+
+### Tips
+
+
+#### 1. Use dedicated models
+
+[`SeamlessM4Tv2Model`] is transformers top level model to generate speech and text, but you can also use dedicated models that perform the task without additional components, thus reducing the memory footprint.
+For example, you can replace the audio-to-audio generation snippet with the model dedicated to the S2ST task, the rest is exactly the same code:
+
+```python
+>>> from transformers import SeamlessM4Tv2ForSpeechToSpeech
+>>> model = SeamlessM4Tv2ForSpeechToSpeech.from_pretrained("facebook/seamless-m4t-v2-large")
+```
+
+Or you can replace the text-to-text generation snippet with the model dedicated to the T2TT task, you only have to remove `generate_speech=False`.
+
+```python
+>>> from transformers import SeamlessM4Tv2ForTextToText
+>>> model = SeamlessM4Tv2ForTextToText.from_pretrained("facebook/seamless-m4t-v2-large")
+```
+
+Feel free to try out [`SeamlessM4Tv2ForSpeechToText`] and [`SeamlessM4Tv2ForTextToSpeech`] as well.
+
+#### 2. Change the speaker identity
+
+You have the possibility to change the speaker used for speech synthesis with the `speaker_id` argument. Some `speaker_id` works better than other for some languages!
+
+#### 3. Change the generation strategy
+
+You can use different [generation strategies](../generation_strategies) for text generation, e.g `.generate(input_ids=input_ids, text_num_beams=4, text_do_sample=True)` which will perform multinomial beam-search decoding on the text model. Note that speech generation only supports greedy - by default - or multinomial sampling, which can be used with e.g. `.generate(..., speech_do_sample=True, speech_temperature=0.6)`.
+
+#### 4. Generate speech and text at the same time
+
+Use `return_intermediate_token_ids=True` with [`SeamlessM4Tv2Model`] to return both speech and text !
+
+## Model architecture
+
+SeamlessM4T-v2 features a versatile architecture that smoothly handles the sequential generation of text and speech. This setup comprises two sequence-to-sequence (seq2seq) models. The first model translates the input modality into translated text, while the second model generates speech tokens, known as "unit tokens," from the translated text.
+
+Each modality has its own dedicated encoder with a unique architecture. Additionally, for speech output, a vocoder inspired by the [HiFi-GAN](https://huggingface.co/papers/2010.05646) architecture is placed on top of the second seq2seq model.
+
+### Difference with SeamlessM4T-v1
+
+The architecture of this new version differs from the first in a few aspects:
+
+#### Improvements on the second-pass model
+
+The second seq2seq model, named text-to-unit model, is now non-auto regressive, meaning that it computes units in a **single forward pass**. This achievement is made possible by:
+- the use of **character-level embeddings**, meaning that each character of the predicted translated text has its own embeddings, which are then used to predict the unit tokens.
+- the use of an intermediate duration predictor, that predicts speech duration at the **character-level** on the predicted translated text.
+- the use of a new text-to-unit decoder mixing convolutions and self-attention to handle longer context.
+
+#### Difference in the speech encoder
+
+The speech encoder, which is used during the first-pass generation process to predict the translated text, differs mainly from the previous speech encoder through these mechanisms:
+- the use of chunked attention mask to prevent attention across chunks, ensuring that each position attends only to positions within its own chunk and a fixed number of previous chunks.
+- the use of relative position embeddings which only considers distance between sequence elements rather than absolute positions. Please refer to [Self-Attentionwith Relative Position Representations (Shaw et al.)](https://huggingface.co/papers/1803.02155) for more details.
+- the use of a causal depth-wise convolution instead of a non-causal one.
+
+### Generation process
+
+Here's how the generation process works:
+
+- Input text or speech is processed through its specific encoder.
+- A decoder creates text tokens in the desired language.
+- If speech generation is required, the second seq2seq model, generates unit tokens in an non auto-regressive way.
+- These unit tokens are then passed through the final vocoder to produce the actual speech.
+
+
+This model was contributed by [ylacombe](https://huggingface.co/ylacombe). The original code can be found [here](https://github.com/facebookresearch/seamless_communication).
+
+## SeamlessM4Tv2Model
+
+[[autodoc]] SeamlessM4Tv2Model
+ - generate
+
+
+## SeamlessM4Tv2ForTextToSpeech
+
+[[autodoc]] SeamlessM4Tv2ForTextToSpeech
+ - generate
+
+
+## SeamlessM4Tv2ForSpeechToSpeech
+
+[[autodoc]] SeamlessM4Tv2ForSpeechToSpeech
+ - generate
+
+
+## SeamlessM4Tv2ForTextToText
+
+[[autodoc]] transformers.SeamlessM4Tv2ForTextToText
+ - forward
+ - generate
+
+## SeamlessM4Tv2ForSpeechToText
+
+[[autodoc]] transformers.SeamlessM4Tv2ForSpeechToText
+ - forward
+ - generate
+
+## SeamlessM4Tv2Config
+
+[[autodoc]] SeamlessM4Tv2Config
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/segformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/segformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..4d434d1973d363503d24d47be3ef608596ea526a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/segformer.md
@@ -0,0 +1,185 @@
+
+*This model was released on 2021-05-31 and added to Hugging Face Transformers on 2021-10-28.*
+
+# SegFormer
+
+
+
+
+
+
+## Overview
+
+The SegFormer model was proposed in [SegFormer: Simple and Efficient Design for Semantic Segmentation with Transformers](https://huggingface.co/papers/2105.15203) by Enze Xie, Wenhai Wang, Zhiding Yu, Anima Anandkumar, Jose M. Alvarez, Ping
+Luo. The model consists of a hierarchical Transformer encoder and a lightweight all-MLP decode head to achieve great
+results on image segmentation benchmarks such as ADE20K and Cityscapes.
+
+The abstract from the paper is the following:
+
+*We present SegFormer, a simple, efficient yet powerful semantic segmentation framework which unifies Transformers with
+lightweight multilayer perception (MLP) decoders. SegFormer has two appealing features: 1) SegFormer comprises a novel
+hierarchically structured Transformer encoder which outputs multiscale features. It does not need positional encoding,
+thereby avoiding the interpolation of positional codes which leads to decreased performance when the testing resolution
+differs from training. 2) SegFormer avoids complex decoders. The proposed MLP decoder aggregates information from
+different layers, and thus combining both local attention and global attention to render powerful representations. We
+show that this simple and lightweight design is the key to efficient segmentation on Transformers. We scale our
+approach up to obtain a series of models from SegFormer-B0 to SegFormer-B5, reaching significantly better performance
+and efficiency than previous counterparts. For example, SegFormer-B4 achieves 50.3% mIoU on ADE20K with 64M parameters,
+being 5x smaller and 2.2% better than the previous best method. Our best model, SegFormer-B5, achieves 84.0% mIoU on
+Cityscapes validation set and shows excellent zero-shot robustness on Cityscapes-C.*
+
+The figure below illustrates the architecture of SegFormer. Taken from the [original paper](https://huggingface.co/papers/2105.15203).
+
+
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The TensorFlow version
+of the model was contributed by [sayakpaul](https://huggingface.co/sayakpaul). The original code can be found [here](https://github.com/NVlabs/SegFormer).
+
+## Usage tips
+
+- SegFormer consists of a hierarchical Transformer encoder, and a lightweight all-MLP decoder head.
+ [`SegformerModel`] is the hierarchical Transformer encoder (which in the paper is also referred to
+ as Mix Transformer or MiT). [`SegformerForSemanticSegmentation`] adds the all-MLP decoder head on
+ top to perform semantic segmentation of images. In addition, there's
+ [`SegformerForImageClassification`] which can be used to - you guessed it - classify images. The
+ authors of SegFormer first pre-trained the Transformer encoder on ImageNet-1k to classify images. Next, they throw
+ away the classification head, and replace it by the all-MLP decode head. Next, they fine-tune the model altogether on
+ ADE20K, Cityscapes and COCO-stuff, which are important benchmarks for semantic segmentation. All checkpoints can be
+ found on the [hub](https://huggingface.co/models?other=segformer).
+- The quickest way to get started with SegFormer is by checking the [example notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/SegFormer) (which showcase both inference and
+ fine-tuning on custom data). One can also check out the [blog post](https://huggingface.co/blog/fine-tune-segformer) introducing SegFormer and illustrating how it can be fine-tuned on custom data.
+- TensorFlow users should refer to [this repository](https://github.com/deep-diver/segformer-tf-transformers) that shows off-the-shelf inference and fine-tuning.
+- One can also check out [this interactive demo on Hugging Face Spaces](https://huggingface.co/spaces/chansung/segformer-tf-transformers)
+ to try out a SegFormer model on custom images.
+- SegFormer works on any input size, as it pads the input to be divisible by `config.patch_sizes`.
+- One can use [`SegformerImageProcessor`] to prepare images and corresponding segmentation maps
+ for the model. Note that this image processor is fairly basic and does not include all data augmentations used in
+ the original paper. The original preprocessing pipelines (for the ADE20k dataset for instance) can be found [here](https://github.com/NVlabs/SegFormer/blob/master/local_configs/_base_/datasets/ade20k_repeat.py). The most
+ important preprocessing step is that images and segmentation maps are randomly cropped and padded to the same size,
+ such as 512x512 or 640x640, after which they are normalized.
+- One additional thing to keep in mind is that one can initialize [`SegformerImageProcessor`] with
+ `do_reduce_labels` set to `True` or `False`. In some datasets (like ADE20k), the 0 index is used in the annotated
+ segmentation maps for background. However, ADE20k doesn't include the "background" class in its 150 labels.
+ Therefore, `do_reduce_labels` is used to reduce all labels by 1, and to make sure no loss is computed for the
+ background class (i.e. it replaces 0 in the annotated maps by 255, which is the *ignore_index* of the loss function
+ used by [`SegformerForSemanticSegmentation`]). However, other datasets use the 0 index as
+ background class and include this class as part of all labels. In that case, `do_reduce_labels` should be set to
+ `False`, as loss should also be computed for the background class.
+- As most models, SegFormer comes in different sizes, the details of which can be found in the table below
+ (taken from Table 7 of the [original paper](https://huggingface.co/papers/2105.15203)).
+
+| **Model variant** | **Depths** | **Hidden sizes** | **Decoder hidden size** | **Params (M)** | **ImageNet-1k Top 1** |
+| :---------------: | ------------- | ------------------- | :---------------------: | :------------: | :-------------------: |
+| MiT-b0 | [2, 2, 2, 2] | [32, 64, 160, 256] | 256 | 3.7 | 70.5 |
+| MiT-b1 | [2, 2, 2, 2] | [64, 128, 320, 512] | 256 | 14.0 | 78.7 |
+| MiT-b2 | [3, 4, 6, 3] | [64, 128, 320, 512] | 768 | 25.4 | 81.6 |
+| MiT-b3 | [3, 4, 18, 3] | [64, 128, 320, 512] | 768 | 45.2 | 83.1 |
+| MiT-b4 | [3, 8, 27, 3] | [64, 128, 320, 512] | 768 | 62.6 | 83.6 |
+| MiT-b5 | [3, 6, 40, 3] | [64, 128, 320, 512] | 768 | 82.0 | 83.8 |
+
+Note that MiT in the above table refers to the Mix Transformer encoder backbone introduced in SegFormer. For
+SegFormer's results on the segmentation datasets like ADE20k, refer to the [paper](https://huggingface.co/papers/2105.15203).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with SegFormer.
+
+
+
+- [`SegformerForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- [Image classification task guide](../tasks/image_classification)
+
+Semantic segmentation:
+
+- [`SegformerForSemanticSegmentation`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/semantic-segmentation).
+- A blog on fine-tuning SegFormer on a custom dataset can be found [here](https://huggingface.co/blog/fine-tune-segformer).
+- More demo notebooks on SegFormer (both inference + fine-tuning on a custom dataset) can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/SegFormer).
+- [`TFSegformerForSemanticSegmentation`] is supported by this [example notebook](https://github.com/huggingface/notebooks/blob/main/examples/semantic_segmentation-tf.ipynb).
+- [Semantic segmentation task guide](../tasks/semantic_segmentation)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## SegformerConfig
+
+[[autodoc]] SegformerConfig
+
+## SegformerFeatureExtractor
+
+[[autodoc]] SegformerFeatureExtractor
+ - __call__
+ - post_process_semantic_segmentation
+
+## SegformerImageProcessor
+
+[[autodoc]] SegformerImageProcessor
+ - preprocess
+ - post_process_semantic_segmentation
+
+## SegformerImageProcessorFast
+
+[[autodoc]] SegformerImageProcessorFast
+ - preprocess
+ - post_process_semantic_segmentation
+
+
+
+
+## SegformerModel
+
+[[autodoc]] SegformerModel
+ - forward
+
+## SegformerDecodeHead
+
+[[autodoc]] SegformerDecodeHead
+ - forward
+
+## SegformerForImageClassification
+
+[[autodoc]] SegformerForImageClassification
+ - forward
+
+## SegformerForSemanticSegmentation
+
+[[autodoc]] SegformerForSemanticSegmentation
+ - forward
+
+
+
+
+## TFSegformerDecodeHead
+
+[[autodoc]] TFSegformerDecodeHead
+ - call
+
+## TFSegformerModel
+
+[[autodoc]] TFSegformerModel
+ - call
+
+## TFSegformerForImageClassification
+
+[[autodoc]] TFSegformerForImageClassification
+ - call
+
+## TFSegformerForSemanticSegmentation
+
+[[autodoc]] TFSegformerForSemanticSegmentation
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/seggpt.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/seggpt.md
new file mode 100644
index 0000000000000000000000000000000000000000..9e8c08cf2d2e4dd7fb72244566034c1e347bbcad
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/seggpt.md
@@ -0,0 +1,96 @@
+
+*This model was released on 2023-04-06 and added to Hugging Face Transformers on 2024-02-26.*
+
+# SegGPT
+
+
+
+
+
+## Overview
+
+The SegGPT model was proposed in [SegGPT: Segmenting Everything In Context](https://huggingface.co/papers/2304.03284) by Xinlong Wang, Xiaosong Zhang, Yue Cao, Wen Wang, Chunhua Shen, Tiejun Huang. SegGPT employs a decoder-only Transformer that can generate a segmentation mask given an input image, a prompt image and its corresponding prompt mask. The model achieves remarkable one-shot results with 56.1 mIoU on COCO-20 and 85.6 mIoU on FSS-1000.
+
+The abstract from the paper is the following:
+
+*We present SegGPT, a generalist model for segmenting everything in context. We unify various segmentation tasks into a generalist in-context learning framework that accommodates different kinds of segmentation data by transforming them into the same format of images. The training of SegGPT is formulated as an in-context coloring problem with random color mapping for each data sample. The objective is to accomplish diverse tasks according to the context, rather than relying on specific colors. After training, SegGPT can perform arbitrary segmentation tasks in images or videos via in-context inference, such as object instance, stuff, part, contour, and text. SegGPT is evaluated on a broad range of tasks, including few-shot semantic segmentation, video object segmentation, semantic segmentation, and panoptic segmentation. Our results show strong capabilities in segmenting in-domain and out-of*
+
+Tips:
+- One can use [`SegGptImageProcessor`] to prepare image input, prompt and mask to the model.
+- One can either use segmentation maps or RGB images as prompt masks. If using the latter make sure to set `do_convert_rgb=False` in the `preprocess` method.
+- It's highly advisable to pass `num_labels` when using `segmentation_maps` (not considering background) during preprocessing and postprocessing with [`SegGptImageProcessor`] for your use case.
+- When doing inference with [`SegGptForImageSegmentation`] if your `batch_size` is greater than 1 you can use feature ensemble across your images by passing `feature_ensemble=True` in the forward method.
+
+Here's how to use the model for one-shot semantic segmentation:
+
+```python
+import torch
+from datasets import load_dataset
+from transformers import SegGptImageProcessor, SegGptForImageSegmentation
+
+checkpoint = "BAAI/seggpt-vit-large"
+image_processor = SegGptImageProcessor.from_pretrained(checkpoint)
+model = SegGptForImageSegmentation.from_pretrained(checkpoint)
+
+dataset_id = "EduardoPacheco/FoodSeg103"
+ds = load_dataset(dataset_id, split="train")
+# Number of labels in FoodSeg103 (not including background)
+num_labels = 103
+
+image_input = ds[4]["image"]
+ground_truth = ds[4]["label"]
+image_prompt = ds[29]["image"]
+mask_prompt = ds[29]["label"]
+
+inputs = image_processor(
+ images=image_input,
+ prompt_images=image_prompt,
+ segmentation_maps=mask_prompt,
+ num_labels=num_labels,
+ return_tensors="pt"
+)
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+target_sizes = [image_input.size[::-1]]
+mask = image_processor.post_process_semantic_segmentation(outputs, target_sizes, num_labels=num_labels)[0]
+```
+
+This model was contributed by [EduardoPacheco](https://huggingface.co/EduardoPacheco).
+The original code can be found [here]([(https://github.com/baaivision/Painter/tree/main)).
+
+
+## SegGptConfig
+
+[[autodoc]] SegGptConfig
+
+## SegGptImageProcessor
+
+[[autodoc]] SegGptImageProcessor
+ - preprocess
+ - post_process_semantic_segmentation
+
+## SegGptModel
+
+[[autodoc]] SegGptModel
+ - forward
+
+## SegGptForImageSegmentation
+
+[[autodoc]] SegGptForImageSegmentation
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sew-d.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sew-d.md
new file mode 100644
index 0000000000000000000000000000000000000000..f8c7190c364d96e551258e39a454b43437f905fe
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sew-d.md
@@ -0,0 +1,70 @@
+
+*This model was released on 2021-09-14 and added to Hugging Face Transformers on 2021-10-15.*
+
+# SEW-D
+
+
+
+
+
+## Overview
+
+SEW-D (Squeezed and Efficient Wav2Vec with Disentangled attention) was proposed in [Performance-Efficiency Trade-offs
+in Unsupervised Pre-training for Speech Recognition](https://huggingface.co/papers/2109.06870) by Felix Wu, Kwangyoun Kim,
+Jing Pan, Kyu Han, Kilian Q. Weinberger, Yoav Artzi.
+
+The abstract from the paper is the following:
+
+*This paper is a study of performance-efficiency trade-offs in pre-trained models for automatic speech recognition
+(ASR). We focus on wav2vec 2.0, and formalize several architecture designs that influence both the model performance
+and its efficiency. Putting together all our observations, we introduce SEW (Squeezed and Efficient Wav2vec), a
+pre-trained model architecture with significant improvements along both performance and efficiency dimensions across a
+variety of training setups. For example, under the 100h-960h semi-supervised setup on LibriSpeech, SEW achieves a 1.9x
+inference speedup compared to wav2vec 2.0, with a 13.5% relative reduction in word error rate. With a similar inference
+time, SEW reduces word error rate by 25-50% across different model sizes.*
+
+This model was contributed by [anton-l](https://huggingface.co/anton-l).
+
+## Usage tips
+
+- SEW-D is a speech model that accepts a float array corresponding to the raw waveform of the speech signal.
+- SEWDForCTC is fine-tuned using connectionist temporal classification (CTC) so the model output has to be decoded
+ using [`Wav2Vec2CTCTokenizer`].
+
+## Resources
+
+- [Audio classification task guide](../tasks/audio_classification)
+- [Automatic speech recognition task guide](../tasks/asr)
+
+## SEWDConfig
+
+[[autodoc]] SEWDConfig
+
+## SEWDModel
+
+[[autodoc]] SEWDModel
+ - forward
+
+## SEWDForCTC
+
+[[autodoc]] SEWDForCTC
+ - forward
+
+## SEWDForSequenceClassification
+
+[[autodoc]] SEWDForSequenceClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sew.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sew.md
new file mode 100644
index 0000000000000000000000000000000000000000..b52849f7c3517e9211f880fd18a3e2d64c09da03
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/sew.md
@@ -0,0 +1,75 @@
+
+*This model was released on 2021-09-14 and added to Hugging Face Transformers on 2021-10-15.*
+
+# SEW
+
+
+
+
+
+
+
+## Overview
+
+SEW (Squeezed and Efficient Wav2Vec) was proposed in [Performance-Efficiency Trade-offs in Unsupervised Pre-training
+for Speech Recognition](https://huggingface.co/papers/2109.06870) by Felix Wu, Kwangyoun Kim, Jing Pan, Kyu Han, Kilian Q.
+Weinberger, Yoav Artzi.
+
+The abstract from the paper is the following:
+
+*This paper is a study of performance-efficiency trade-offs in pre-trained models for automatic speech recognition
+(ASR). We focus on wav2vec 2.0, and formalize several architecture designs that influence both the model performance
+and its efficiency. Putting together all our observations, we introduce SEW (Squeezed and Efficient Wav2vec), a
+pre-trained model architecture with significant improvements along both performance and efficiency dimensions across a
+variety of training setups. For example, under the 100h-960h semi-supervised setup on LibriSpeech, SEW achieves a 1.9x
+inference speedup compared to wav2vec 2.0, with a 13.5% relative reduction in word error rate. With a similar inference
+time, SEW reduces word error rate by 25-50% across different model sizes.*
+
+This model was contributed by [anton-l](https://huggingface.co/anton-l).
+
+## Usage tips
+
+- SEW is a speech model that accepts a float array corresponding to the raw waveform of the speech signal.
+- SEWForCTC is fine-tuned using connectionist temporal classification (CTC) so the model output has to be decoded using
+ [`Wav2Vec2CTCTokenizer`].
+
+> [!NOTE]
+> The `head_mask` argument is ignored when using all attention implementation other than "eager". If you have a `head_mask` and want it to have effect, load the model with `XXXModel.from_pretrained(model_id, attn_implementation="eager")`
+
+## Resources
+
+- [Audio classification task guide](../tasks/audio_classification)
+- [Automatic speech recognition task guide](../tasks/asr)
+
+## SEWConfig
+
+[[autodoc]] SEWConfig
+
+## SEWModel
+
+[[autodoc]] SEWModel
+ - forward
+
+## SEWForCTC
+
+[[autodoc]] SEWForCTC
+ - forward
+
+## SEWForSequenceClassification
+
+[[autodoc]] SEWForSequenceClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/shieldgemma2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/shieldgemma2.md
new file mode 100644
index 0000000000000000000000000000000000000000..99ffde6288ffa6e9e109d143138bb72ebd7640e7
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/shieldgemma2.md
@@ -0,0 +1,101 @@
+
+
+*This model was released on 2025-04-01 and added to Hugging Face Transformers on 2025-03-20.*
+
+# ShieldGemma 2
+
+## Overview
+
+The ShieldGemma 2 model was proposed in a [technical report](https://huggingface.co/papers/2504.01081) by Google. ShieldGemma 2, built on [Gemma 3](https://ai.google.dev/gemma/docs/core/model_card_3), is a 4 billion (4B) parameter model that checks the safety of both synthetic and natural images against key categories to help you build robust datasets and models. With this addition to the Gemma family of models, researchers and developers can now easily minimize the risk of harmful content in their models across key areas of harm as defined below:
+
+- No Sexually Explicit content: The image shall not contain content that depicts explicit or graphic sexual acts (e.g., pornography, erotic nudity, depictions of rape or sexual assault).
+- No Dangerous Content: The image shall not contain content that facilitates or encourages activities that could cause real-world harm (e.g., building firearms and explosive devices, promotion of terrorism, instructions for suicide).
+- No Violence/Gore content: The image shall not contain content that depicts shocking, sensational, or gratuitous violence (e.g., excessive blood and gore, gratuitous violence against animals, extreme injury or moment of death).
+
+We recommend using ShieldGemma 2 as an input filter to vision language models, or as an output filter of image generation systems. To train a robust image safety model, we curated training datasets of natural and synthetic images and instruction-tuned Gemma 3 to demonstrate strong performance.
+
+This model was contributed by [Ryan Mullins](https://huggingface.co/RyanMullins).
+
+## Usage Example
+
+- ShieldGemma 2 provides a Processor that accepts a list of `images` and an optional list of `policies` as input, and constructs a batch of prompts as the product of these two lists using the provided chat template.
+- You can extend ShieldGemma's built-in in policies with the `custom_policies` argument to the Processor. Using the same key as one of the built-in policies will overwrite that policy with your custom definition.
+- ShieldGemma 2 does not support the image cropping capabilities used by Gemma 3.
+
+### Classification against Built-in Policies
+
+```python
+from PIL import Image
+import requests
+from transformers import AutoProcessor, ShieldGemma2ForImageClassification
+
+model_id = "google/shieldgemma-2-4b-it"
+model = ShieldGemma2ForImageClassification.from_pretrained(model_id, device_map="auto")
+processor = AutoProcessor.from_pretrained(model_id)
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+inputs = processor(images=[image], return_tensors="pt").to(model.device)
+
+output = model(**inputs)
+print(output.probabilities)
+```
+
+### Classification against Custom Policies
+
+```python
+from PIL import Image
+import requests
+from transformers import AutoProcessor, ShieldGemma2ForImageClassification
+
+model_id = "google/shieldgemma-2-4b-it"
+model = ShieldGemma2ForImageClassification.from_pretrained(model_id, device_map="auto")
+processor = AutoProcessor.from_pretrained(model_id)
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+custom_policies = {
+ "key_a": "descrition_a",
+ "key_b": "descrition_b",
+}
+
+inputs = processor(
+ images=[image],
+ custom_policies=custom_policies,
+ policies=["dangerous", "key_a", "key_b"],
+ return_tensors="pt",
+).to(model.device)
+
+output = model(**inputs)
+print(output.probabilities)
+```
+
+
+## ShieldGemma2Processor
+
+[[autodoc]] ShieldGemma2Processor
+
+## ShieldGemma2Config
+
+[[autodoc]] ShieldGemma2Config
+
+## ShieldGemma2ForImageClassification
+
+[[autodoc]] ShieldGemma2ForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/siglip.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/siglip.md
new file mode 100644
index 0000000000000000000000000000000000000000..9388f2673fac934c8a5cdffc3e966b2775415baf
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/siglip.md
@@ -0,0 +1,186 @@
+
+*This model was released on 2023-03-27 and added to Hugging Face Transformers on 2024-01-08.*
+
+
+
+
+
+
+
+
+
+# SigLIP
+
+[SigLIP](https://huggingface.co/papers/2303.15343) is a multimodal image-text model similar to [CLIP](clip). It uses separate image and text encoders to generate representations for both modalities.
+
+Unlike CLIP, SigLIP employs a pairwise sigmoid loss on image-text pairs during training. This training loss eliminates the need for a global view of all pairwise similarities between images and texts within a batch. Consequently, it enables more efficient scaling to larger batch sizes while also delivering superior performance with smaller batch sizes.
+
+You can find all the original SigLIP checkpoints under the [SigLIP](https://huggingface.co/collections/google/siglip-659d5e62f0ae1a57ae0e83ba) collection.
+
+
+> [!TIP]
+> Click on the SigLIP models in the right sidebar for more examples of how to apply SigLIP to different image and text tasks.
+
+The example below demonstrates how to generate similarity scores between texts and image(s) with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+image = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+candidate_labels = ["a Pallas cat", "a lion", "a Siberian tiger"]
+
+pipeline = pipeline(task="zero-shot-image-classification", model="google/siglip-base-patch16-224", device=0, torch_dtype=torch.bfloat16)
+pipeline(image, candidate_labels=candidate_labels)
+```
+
+
+
+
+```py
+import torch
+import requests
+from PIL import Image
+from transformers import AutoProcessor, AutoModel
+
+model = AutoModel.from_pretrained("google/siglip-base-patch16-224", torch_dtype=torch.float16, device_map="auto", attn_implementation="sdpa")
+processor = AutoProcessor.from_pretrained("google/siglip-base-patch16-224")
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+image = Image.open(requests.get(url, stream=True).raw)
+candidate_labels = ["a Pallas cat", "a lion", "a Siberian tiger"]
+texts = [f'This is a photo of {label}.' for label in candidate_labels]
+inputs = processor(text=texts, images=image, padding="max_length", return_tensors="pt").to("cuda")
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+logits_per_image = outputs.logits_per_image
+probs = torch.sigmoid(logits_per_image)
+print(f"{probs[0][0]:.1%} that image 0 is '{candidate_labels[0]}'")
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to int4.
+
+```py
+import torch
+import requests
+from PIL import Image
+from transformers import AutoProcessor, AutoModel, BitsAndBytesConfig
+
+bnb_config = BitsAndBytesConfig(load_in_4bit=True)
+model = AutoModel.from_pretrained("google/siglip-base-patch16-224", quantization_config=bnb_config, device_map="auto", attn_implementation="sdpa")
+processor = AutoProcessor.from_pretrained("google/siglip-base-patch16-224")
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+image = Image.open(requests.get(url, stream=True).raw)
+candidate_labels = ["a Pallas cat", "a lion", "a Siberian tiger"]
+texts = [f'This is a photo of {label}.' for label in candidate_labels]
+inputs = processor(text=texts, images=image, padding="max_length", return_tensors="pt").to("cuda")
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+logits_per_image = outputs.logits_per_image
+probs = torch.sigmoid(logits_per_image)
+print(f"{probs[0][0]:.1%} that image 0 is '{candidate_labels[0]}'")
+```
+## Notes
+
+- Training is supported for DDP and FSDP on single-node multi-GPU setups. However, it does not use [torch.distributed](https://pytorch.org/tutorials/beginner/dist_overview.html) utilities which may limit the scalability of batch size.
+- When using the standalone [`SiglipTokenizer`] or [`SiglipProcessor`], make sure to pass `padding="max_length"` because that is how the model was trained.
+- To get the same results as the [`Pipeline`], a prompt template of `"This is a photo of {label}."` should be passed to the processor.
+- Toggle the `attn_implementation` parameter to either `"sdpa"` or `"flash_attention_2"` to use a more memory-efficient attention.
+ ```py
+ # pip install -U flash-attn --no-build-isolation
+
+ from transformers import SiglipModel
+
+ model = SiglipModel.from_pretrained(
+ "google/siglip-so400m-patch14-384",
+ attn_implementation="flash_attention_2",
+ torch_dtype=torch.float16,
+ device_map=device,
+ )
+ ```
+
+
+## SiglipConfig
+
+[[autodoc]] SiglipConfig
+ - from_text_vision_configs
+
+## SiglipTextConfig
+
+[[autodoc]] SiglipTextConfig
+
+## SiglipVisionConfig
+
+[[autodoc]] SiglipVisionConfig
+
+## SiglipTokenizer
+
+[[autodoc]] SiglipTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## SiglipImageProcessor
+
+[[autodoc]] SiglipImageProcessor
+ - preprocess
+
+## SiglipImageProcessorFast
+
+[[autodoc]] SiglipImageProcessorFast
+ - preprocess
+
+## SiglipProcessor
+
+[[autodoc]] SiglipProcessor
+
+## SiglipModel
+
+[[autodoc]] SiglipModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## SiglipTextModel
+
+[[autodoc]] SiglipTextModel
+ - forward
+
+## SiglipVisionModel
+
+[[autodoc]] SiglipVisionModel
+ - forward
+
+
+## SiglipForImageClassification
+
+[[autodoc]] SiglipForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/siglip2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/siglip2.md
new file mode 100644
index 0000000000000000000000000000000000000000..f8fb56ffbb54eeacc59484315ec802cc09e60ed6
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/siglip2.md
@@ -0,0 +1,218 @@
+
+*This model was released on 2025-02-20 and added to Hugging Face Transformers on 2025-02-21.*
+
+
+
+
+
+
+
+
+
+# SigLIP2
+
+## Overview
+
+[SigLIP2](https://huggingface.co/papers/2502.14786) is a family of multilingual vision-language encoders that builds on the [SigLIP](./siglip) training recipe. It includes decoder-based pretraining, self-distillation, and masked prediction to improve dense prediction tasks (segmentation, depth estimation, etc.). This model is available in two variants:
+
+- NaFlex supports different resolutions and maintains the native image aspect ratio
+- FixRes supports fixed resolutions and is backwards compatible with [SigLIP](./siglip)
+
+
+You can find all the original SigLIP2 checkpoints under the [SigLIP2](https://huggingface.co/collections/google/siglip2-67b5dcef38c175486e240107) collection.
+
+> [!TIP]
+> Click on the SigLIP2 models in the right sidebar for more examples of how to apply SigLIP2 to different image and text tasks.
+
+The example below demonstrates zero-shot classification with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+image = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+candidate_labels = ["a Pallas cat", "a lion", "a Siberian tiger"]
+
+pipeline = pipeline(task="zero-shot-image-classification", model="google/siglip2-base-patch16-224", device=0, torch_dtype=torch.bfloat16)
+pipeline(image, candidate_labels=candidate_labels)
+```
+
+
+
+
+```py
+import torch
+import requests
+from PIL import Image
+from transformers import AutoProcessor, AutoModel
+
+model = AutoModel.from_pretrained("google/siglip2-base-patch16-224", torch_dtype=torch.float16, device_map="auto", attn_implementation="sdpa")
+processor = AutoProcessor.from_pretrained("google/siglip2-base-patch16-224")
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+image = Image.open(requests.get(url, stream=True).raw)
+candidate_labels = ["a Pallas cat", "a lion", "a Siberian tiger"]
+
+# follows the pipeline prompt template to get same results
+texts = [f'This is a photo of {label}.' for label in candidate_labels]
+
+# IMPORTANT: we pass `padding=max_length` and `max_length=64` since the model was trained with this
+inputs = processor(text=texts, images=image, padding="max_length", max_length=64, return_tensors="pt").to(model.device)
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+logits_per_image = outputs.logits_per_image
+probs = torch.sigmoid(logits_per_image)
+print(f"{probs[0][0]:.1%} that image 0 is '{candidate_labels[0]}'")
+```
+
+
+
+
+```py
+import torch
+import requests
+from PIL import Image
+from transformers import AutoProcessor, AutoModel
+
+model = AutoModel.from_pretrained("google/siglip2-base-patch16-naflex", torch_dtype=torch.float16, device_map="auto", attn_implementation="sdpa")
+processor = AutoProcessor.from_pretrained("google/siglip2-base-patch16-naflex")
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+image = Image.open(requests.get(url, stream=True).raw)
+candidate_labels = ["a Pallas cat", "a lion", "a Siberian tiger"]
+texts = [f'This is a photo of {label}.' for label in candidate_labels]
+
+# default value for `max_num_patches` is 256, but you can increase resulted image resolution providing higher values e.g. `max_num_patches=512`
+inputs = processor(text=texts, images=image, padding="max_length", max_num_patches=256, return_tensors="pt").to(model.device)
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+logits_per_image = outputs.logits_per_image
+probs = torch.sigmoid(logits_per_image)
+print(f"{probs[0][0]:.1%} that image 0 is '{candidate_labels[0]}'")
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to only quantize the weights to int4.
+
+```py
+import torch
+import requests
+from PIL import Image
+from transformers import AutoProcessor, AutoModel, BitsAndBytesConfig
+
+bnb_config = BitsAndBytesConfig(load_in_4bit=True)
+model = AutoModel.from_pretrained("google/siglip2-large-patch16-512", quantization_config=bnb_config, device_map="auto", attn_implementation="sdpa")
+processor = AutoProcessor.from_pretrained("google/siglip2-base-patch16-224")
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+image = Image.open(requests.get(url, stream=True).raw)
+candidate_labels = ["a Pallas cat", "a lion", "a Siberian tiger"]
+
+# follows the pipeline prompt template to get same results
+texts = [f'This is a photo of {label}.' for label in candidate_labels]
+
+# IMPORTANT: we pass `padding=max_length` and `max_length=64` since the model was trained with this
+inputs = processor(text=texts, images=image, padding="max_length", max_length=64, return_tensors="pt").to(model.device)
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+logits_per_image = outputs.logits_per_image
+probs = torch.sigmoid(logits_per_image)
+print(f"{probs[0][0]:.1%} that image 0 is '{candidate_labels[0]}'")
+```
+
+## Notes
+
+- Training is supported for DDP and FSDP on single-node multi-accelerator setups. However, it does not use [torch.distributed](https://pytorch.org/tutorials/beginner/dist_overview.html) utilities which may limit the scalability of batch size.
+- When using the standalone [`GemmaTokenizerFast`] make sure to pass `padding="max_length"` and `max_length=64` as that's how the model was trained.
+- Model was trained with *lowercased* text, so make sure your text labels are preprocessed the same way.
+- To get the same results as the [`Pipeline`], a prompt template of `"This is a photo of {label}."` should be passed to the processor.
+- The NaFlex variant processes different types of images at the appropriate resolution (using a larger resolution to process document images for example), while also minimizing the impact of aspect ratio distortion for certain inference tasks like OCR.
+
+ NaFlex resizes the input image so the height and width are multiples of the patch size after resizing. It keeps the aspect ratio distortion as low as possible and produces a sequence length of at most the desired target sequence length (`max_num_patches`). After resizing, the image is split into a sequence of patches and a mask with padding information is added.
+- Toggle the `attn_implementation` parameter to either `"sdpa"` or `"flash_attention_2"` to use a more memory-efficient attention.
+ ```py
+ # pip install -U flash-attn --no-build-isolation
+
+ from transformers import SiglipModel
+
+ model = SiglipModel.from_pretrained(
+ "google/siglip2-so400m-patch14-384",
+ attn_implementation="flash_attention_2",
+ torch_dtype=torch.float16,
+ device_map=device,
+ )
+ ```
+## Siglip2Config
+
+[[autodoc]] Siglip2Config
+
+## Siglip2TextConfig
+
+[[autodoc]] Siglip2TextConfig
+
+## Siglip2VisionConfig
+
+[[autodoc]] Siglip2VisionConfig
+
+## Siglip2ImageProcessor
+
+[[autodoc]] Siglip2ImageProcessor
+ - preprocess
+
+## Siglip2ImageProcessorFast
+
+[[autodoc]] Siglip2ImageProcessorFast
+ - preprocess
+
+## Siglip2Processor
+
+[[autodoc]] Siglip2Processor
+
+## Siglip2Model
+
+[[autodoc]] Siglip2Model
+ - forward
+ - get_text_features
+ - get_image_features
+
+## Siglip2TextModel
+
+[[autodoc]] Siglip2TextModel
+ - forward
+
+## Siglip2VisionModel
+
+[[autodoc]] Siglip2VisionModel
+ - forward
+
+## Siglip2ForImageClassification
+
+[[autodoc]] Siglip2ForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/smollm3.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/smollm3.md
new file mode 100644
index 0000000000000000000000000000000000000000..4303b8d7a7f81e1ed34ab83ac996461e12f892c3
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/smollm3.md
@@ -0,0 +1,174 @@
+
+*This model was released on 2025-07-08 and added to Hugging Face Transformers on 2025-06-25.*
+
+
+
+
+
+
+
+
+
+# SmolLM3
+
+[SmolLM3](https://huggingface.co/blog/smollm3) is a fully open, compact language model designed for efficient deployment while maintaining strong performance. It uses a Transformer decoder architecture with Grouped Query Attention (GQA) to reduce the kv cache, and no RoPE, enabling improved performance on long-context tasks. It is trained using a multi-stage training approach on high-quality public datasets across web, code, and math domains. The model is multilingual and supports very large context lengths. The instruct variant is optimized for reasoning and tool use.
+
+> [!TIP]
+> Click on the SmolLM3 models in the right sidebar for more examples of how to apply SmolLM3 to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`], [`AutoModel`], and from the command line using the instruction-tuned models.
+
+
+
+
+```python
+import torch
+from transformers import pipeline
+
+pipe = pipeline(
+ task="text-generation",
+ model="HuggingFaceTB/SmolLM3-3B",
+ torch_dtype=torch.bfloat16,
+ device_map=0
+)
+
+messages = [
+ {"role": "system", "content": "You are a helpful assistant."},
+ {"role": "user", "content": "Tell me about yourself."},
+]
+outputs = pipe(messages, max_new_tokens=256, do_sample=True, temperature=0.7, top_k=50, top_p=0.95)
+print(outputs[0]["generated_text"][-1]['content'])
+```
+
+
+
+
+```python
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained(
+ "HuggingFaceTB/SmolLM3-3B",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ attn_implementation="sdpa"
+)
+tokenizer = AutoTokenizer.from_pretrained("HuggingFaceTB/SmolLM3-3B")
+
+prompt = "Give me a short introduction to large language models."
+messages = [
+ {"role": "system", "content": "You are a helpful assistant."},
+ {"role": "user", "content": prompt}
+]
+text = tokenizer.apply_chat_template(
+ messages,
+ tokenize=False,
+ add_generation_prompt=True
+)
+model_inputs = tokenizer([text], return_tensors="pt").to(model.device)
+
+generated_ids = model.generate(
+ model_inputs.input_ids,
+ cache_implementation="static",
+ max_new_tokens=512,
+ do_sample=True,
+ temperature=0.7,
+ top_k=50,
+ top_p=0.95
+)
+generated_ids = [
+ output_ids[len(input_ids):] for input_ids, output_ids in zip(model_inputs.input_ids, generated_ids)
+]
+
+response = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)[0]
+print(response)
+```
+
+
+
+
+```bash
+# pip install -U flash-attn --no-build-isolation
+transformers chat HuggingFaceTB/SmolLM3-3B --torch_dtype auto --attn_implementation flash_attention_2 --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to quantize the weights to 4-bits.
+
+```python
+# pip install -U flash-attn --no-build-isolation
+import torch
+from transformers import AutoTokenizer, AutoModelForCausalLM, BitsAndBytesConfig
+
+quantization_config = BitsAndBytesConfig(
+ load_in_4bit=True,
+ bnb_4bit_compute_dtype=torch.bfloat16,
+ bnb_4bit_quant_type="nf4",
+ bnb_4bit_use_double_quant=True,
+)
+
+tokenizer = AutoTokenizer.from_pretrained("HuggingFaceTB/SmolLM3-3B")
+model = AutoModelForCausalLM.from_pretrained(
+ "HuggingFaceTB/SmolLM3-3B",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config,
+ attn_implementation="flash_attention_2"
+)
+
+inputs = tokenizer("Gravity is the force", return_tensors="pt").to(model.device)
+outputs = model.generate(**inputs, max_new_tokens=100)
+print(tokenizer.decode(outputs[0], skip_special_tokens=True))
+```
+
+
+## Notes
+
+- Ensure your Transformers library version is up-to-date. SmolLM3 requires Transformers>=4.53.0 for full support.
+
+## SmolLM3Config
+
+[[autodoc]] SmolLM3Config
+
+## SmolLM3Model
+
+[[autodoc]] SmolLM3Model
+ - forward
+
+## SmolLM3ForCausalLM
+
+[[autodoc]] SmolLM3ForCausalLM
+ - forward
+
+## SmolLM3ForSequenceClassification
+
+[[autodoc]] SmolLM3ForSequenceClassification
+ - forward
+
+## SmolLM3ForTokenClassification
+
+[[autodoc]] SmolLM3ForTokenClassification
+ - forward
+
+## SmolLM3ForQuestionAnswering
+
+[[autodoc]] SmolLM3ForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/smolvlm.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/smolvlm.md
new file mode 100644
index 0000000000000000000000000000000000000000..dc92ffb81a6829a6816c7640681ee7bf50b7c42b
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/smolvlm.md
@@ -0,0 +1,210 @@
+
+*This model was released on 2025-02-20 and added to Hugging Face Transformers on 2025-02-20.*
+
+# SmolVLM
+
+
+
+
+
+
+
+## Overview
+[SmolVLM2](https://huggingface.co/papers/2504.05299) ([blog post](https://huggingface.co/blog/smolvlm2)) is an adaptation of the Idefics3 model with two main differences:
+
+- It uses SmolLM2 for the text model.
+- It supports multi-image and video inputs
+
+## Usage tips
+
+Input images are processed either by upsampling (if resizing is enabled) or at their original resolution. The resizing behavior depends on two parameters: do_resize and size.
+
+Videos should not be upsampled.
+
+If `do_resize` is set to `True`, the model resizes images so that the longest edge is 4*512 pixels by default.
+The default resizing behavior can be customized by passing a dictionary to the `size` parameter. For example, `{"longest_edge": 4 * 512}` is the default, but you can change it to a different value if needed.
+
+Here’s how to control resizing and set a custom size:
+```python
+image_processor = SmolVLMImageProcessor(do_resize=True, size={"longest_edge": 2 * 512}, max_image_size=512)
+```
+
+Additionally, the `max_image_size` parameter, which controls the size of each square patch the image is decomposed into, is set to 512 by default but can be adjusted as needed. After resizing (if applicable), the image processor decomposes the images into square patches based on the `max_image_size` parameter.
+
+This model was contributed by [orrzohar](https://huggingface.co/orrzohar).
+
+
+
+## Usage example
+
+### Single Media inference
+
+The model can accept both images and videos as input, but you should use only one of the modalities at a time. Here's an example code for that.
+
+```python
+import torch
+from transformers import AutoProcessor, AutoModelForImageTextToText
+
+processor = AutoProcessor.from_pretrained("HuggingFaceTB/SmolVLM2-256M-Video-Instruct")
+model = AutoModelForImageTextToText.from_pretrained(
+ "HuggingFaceTB/SmolVLM2-256M-Video-Instruct",
+ torch_dtype=torch.bfloat16,
+ device_map="auto"
+)
+
+conversation = [
+ {
+ "role": "user",
+ "content":[
+ {"type": "image", "url": "http://images.cocodataset.org/val2017/000000039769.jpg"},
+ {"type": "text", "text": "Describe this image."}
+ ]
+ }
+]
+
+inputs = processor.apply_chat_template(
+ conversation,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device, dtype=torch.bfloat16)
+
+output_ids = model.generate(**inputs, max_new_tokens=128)
+generated_texts = processor.batch_decode(output_ids, skip_special_tokens=True)
+print(generated_texts)
+
+
+# Video
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "video", "path": "/path/to/video.mp4"},
+ {"type": "text", "text": "Describe this video in detail"}
+ ]
+ },
+]
+
+inputs = processor.apply_chat_template(
+ conversation,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device, dtype=torch.bfloat16)
+
+generated_ids = model.generate(**inputs, do_sample=False, max_new_tokens=100)
+generated_texts = processor.batch_decode(generated_ids, skip_special_tokens=True)
+print(generated_texts[0])
+```
+
+### Batch Mixed Media Inference
+
+The model can batch inputs composed of several images/videos and text. Here is an example.
+
+```python
+import torch
+from transformers import AutoProcessor, AutoModelForImageTextToText
+
+processor = AutoProcessor.from_pretrained("HuggingFaceTB/SmolVLM2-256M-Video-Instruct")
+model = AutoModelForImageTextToText.from_pretrained(
+ "HuggingFaceTB/SmolVLM2-256M-Video-Instruct",
+ torch_dtype=torch.bfloat16,
+ device_map="auto"
+)
+
+# Conversation for the first image
+conversation1 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "path": "/path/to/image.jpg"},
+ {"type": "text", "text": "Describe this image."}
+ ]
+ }
+]
+
+# Conversation with two images
+conversation2 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "path": "/path/to/image.jpg"},
+ {"type": "image", "path": "/path/to/image.jpg"},
+ {"type": "text", "text": "What is written in the pictures?"}
+ ]
+ }
+]
+
+# Conversation with pure text
+conversation3 = [
+ {"role": "user","content": "who are you?"}
+]
+
+
+conversations = [conversation1, conversation2, conversation3]
+inputs = processor.apply_chat_template(
+ conversation,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt",
+).to(model.device, dtype=torch.bfloat16)
+
+generated_ids = model.generate(**inputs, do_sample=False, max_new_tokens=100)
+generated_texts = processor.batch_decode(generated_ids, skip_special_tokens=True)
+print(generated_texts[0])
+```
+
+## SmolVLMConfig
+
+[[autodoc]] SmolVLMConfig
+
+## SmolVLMVisionConfig
+
+[[autodoc]] SmolVLMVisionConfig
+
+## Idefics3VisionTransformer
+
+[[autodoc]] SmolVLMVisionTransformer
+
+## SmolVLMModel
+
+[[autodoc]] SmolVLMModel
+ - forward
+
+## SmolVLMForConditionalGeneration
+
+[[autodoc]] SmolVLMForConditionalGeneration
+ - forward
+
+## SmolVLMImageProcessor
+[[autodoc]] SmolVLMImageProcessor
+ - preprocess
+
+## SmolVLMImageProcessorFast
+[[autodoc]] SmolVLMImageProcessorFast
+ - preprocess
+
+## SmolVLMVideoProcessor
+[[autodoc]] SmolVLMVideoProcessor
+ - preprocess
+
+## SmolVLMProcessor
+[[autodoc]] SmolVLMProcessor
+ - __call__
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/speech-encoder-decoder.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/speech-encoder-decoder.md
new file mode 100644
index 0000000000000000000000000000000000000000..91f64e6c51c0ba71d5309d7f846edba965d900f2
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/speech-encoder-decoder.md
@@ -0,0 +1,141 @@
+
+*This model was released on 2021-04-14 and added to Hugging Face Transformers on 2021-09-01.*
+
+# Speech Encoder Decoder Models
+
+
+
+
+
+
+
+
+The [`SpeechEncoderDecoderModel`] can be used to initialize a speech-to-text model
+with any pretrained speech autoencoding model as the encoder (*e.g.* [Wav2Vec2](wav2vec2), [Hubert](hubert)) and any pretrained autoregressive model as the decoder.
+
+The effectiveness of initializing speech-sequence-to-text-sequence models with pretrained checkpoints for speech
+recognition and speech translation has *e.g.* been shown in [Large-Scale Self- and Semi-Supervised Learning for Speech
+Translation](https://huggingface.co/papers/2104.06678) by Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli,
+Alexis Conneau.
+
+An example of how to use a [`SpeechEncoderDecoderModel`] for inference can be seen in [Speech2Text2](speech_to_text_2).
+
+## Randomly initializing `SpeechEncoderDecoderModel` from model configurations.
+
+[`SpeechEncoderDecoderModel`] can be randomly initialized from an encoder and a decoder config. In the following example, we show how to do this using the default [`Wav2Vec2Model`] configuration for the encoder
+and the default [`BertForCausalLM`] configuration for the decoder.
+
+```python
+>>> from transformers import BertConfig, Wav2Vec2Config, SpeechEncoderDecoderConfig, SpeechEncoderDecoderModel
+
+>>> config_encoder = Wav2Vec2Config()
+>>> config_decoder = BertConfig()
+
+>>> config = SpeechEncoderDecoderConfig.from_encoder_decoder_configs(config_encoder, config_decoder)
+>>> model = SpeechEncoderDecoderModel(config=config)
+```
+
+## Initialising `SpeechEncoderDecoderModel` from a pretrained encoder and a pretrained decoder.
+
+[`SpeechEncoderDecoderModel`] can be initialized from a pretrained encoder checkpoint and a pretrained decoder checkpoint. Note that any pretrained Transformer-based speech model, *e.g.* [Wav2Vec2](wav2vec2), [Hubert](hubert) can serve as the encoder and both pretrained auto-encoding models, *e.g.* BERT, pretrained causal language models, *e.g.* GPT2, as well as the pretrained decoder part of sequence-to-sequence models, *e.g.* decoder of BART, can be used as the decoder.
+Depending on which architecture you choose as the decoder, the cross-attention layers might be randomly initialized.
+Initializing [`SpeechEncoderDecoderModel`] from a pretrained encoder and decoder checkpoint requires the model to be fine-tuned on a downstream task, as has been shown in [the *Warm-starting-encoder-decoder blog post*](https://huggingface.co/blog/warm-starting-encoder-decoder).
+To do so, the `SpeechEncoderDecoderModel` class provides a [`SpeechEncoderDecoderModel.from_encoder_decoder_pretrained`] method.
+
+```python
+>>> from transformers import SpeechEncoderDecoderModel
+
+>>> model = SpeechEncoderDecoderModel.from_encoder_decoder_pretrained(
+... "facebook/hubert-large-ll60k", "google-bert/bert-base-uncased"
+... )
+```
+
+## Loading an existing `SpeechEncoderDecoderModel` checkpoint and perform inference.
+
+To load fine-tuned checkpoints of the `SpeechEncoderDecoderModel` class, [`SpeechEncoderDecoderModel`] provides the `from_pretrained(...)` method just like any other model architecture in Transformers.
+
+To perform inference, one uses the [`generate`] method, which allows to autoregressively generate text. This method supports various forms of decoding, such as greedy, beam search and multinomial sampling.
+
+```python
+>>> from transformers import Wav2Vec2Processor, SpeechEncoderDecoderModel
+>>> from datasets import load_dataset
+>>> import torch
+
+>>> # load a fine-tuned speech translation model and corresponding processor
+>>> model = SpeechEncoderDecoderModel.from_pretrained("facebook/wav2vec2-xls-r-300m-en-to-15")
+>>> processor = Wav2Vec2Processor.from_pretrained("facebook/wav2vec2-xls-r-300m-en-to-15")
+
+>>> # let's perform inference on a piece of English speech (which we'll translate to German)
+>>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+>>> input_values = processor(ds[0]["audio"]["array"], return_tensors="pt").input_values
+
+>>> # autoregressively generate transcription (uses greedy decoding by default)
+>>> generated_ids = model.generate(input_values)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+>>> print(generated_text)
+Mr. Quilter ist der Apostel der Mittelschicht und wir freuen uns, sein Evangelium willkommen heißen zu können.
+```
+
+## Training
+
+Once the model is created, it can be fine-tuned similar to BART, T5 or any other encoder-decoder model on a dataset of (speech, text) pairs.
+As you can see, only 2 inputs are required for the model in order to compute a loss: `input_values` (which are the
+speech inputs) and `labels` (which are the `input_ids` of the encoded target sequence).
+
+```python
+>>> from transformers import AutoTokenizer, AutoFeatureExtractor, SpeechEncoderDecoderModel
+>>> from datasets import load_dataset
+
+>>> encoder_id = "facebook/wav2vec2-base-960h" # acoustic model encoder
+>>> decoder_id = "google-bert/bert-base-uncased" # text decoder
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained(encoder_id)
+>>> tokenizer = AutoTokenizer.from_pretrained(decoder_id)
+>>> # Combine pre-trained encoder and pre-trained decoder to form a Seq2Seq model
+>>> model = SpeechEncoderDecoderModel.from_encoder_decoder_pretrained(encoder_id, decoder_id)
+
+>>> model.config.decoder_start_token_id = tokenizer.cls_token_id
+>>> model.config.pad_token_id = tokenizer.pad_token_id
+
+>>> # load an audio input and pre-process (normalise mean/std to 0/1)
+>>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+>>> input_values = feature_extractor(ds[0]["audio"]["array"], return_tensors="pt").input_values
+
+>>> # load its corresponding transcription and tokenize to generate labels
+>>> labels = tokenizer(ds[0]["text"], return_tensors="pt").input_ids
+
+>>> # the forward function automatically creates the correct decoder_input_ids
+>>> loss = model(input_values=input_values, labels=labels).loss
+>>> loss.backward()
+```
+
+## SpeechEncoderDecoderConfig
+
+[[autodoc]] SpeechEncoderDecoderConfig
+
+## SpeechEncoderDecoderModel
+
+[[autodoc]] SpeechEncoderDecoderModel
+ - forward
+ - from_encoder_decoder_pretrained
+
+## FlaxSpeechEncoderDecoderModel
+
+[[autodoc]] FlaxSpeechEncoderDecoderModel
+ - __call__
+ - from_encoder_decoder_pretrained
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/speech_to_text.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/speech_to_text.md
new file mode 100644
index 0000000000000000000000000000000000000000..ae81d7798571d5fd35089045147489e5c3c588ef
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/speech_to_text.md
@@ -0,0 +1,158 @@
+
+*This model was released on 2020-10-11 and added to Hugging Face Transformers on 2021-03-10.*
+
+# Speech2Text
+
+
+
+
+
+
+## Overview
+
+The Speech2Text model was proposed in [fairseq S2T: Fast Speech-to-Text Modeling with fairseq](https://huggingface.co/papers/2010.05171) by Changhan Wang, Yun Tang, Xutai Ma, Anne Wu, Dmytro Okhonko, Juan Pino. It's a
+transformer-based seq2seq (encoder-decoder) model designed for end-to-end Automatic Speech Recognition (ASR) and Speech
+Translation (ST). It uses a convolutional downsampler to reduce the length of speech inputs by 3/4th before they are
+fed into the encoder. The model is trained with standard autoregressive cross-entropy loss and generates the
+transcripts/translations autoregressively. Speech2Text has been fine-tuned on several datasets for ASR and ST:
+[LibriSpeech](http://www.openslr.org/12), [CoVoST 2](https://github.com/facebookresearch/covost), [MuST-C](https://ict.fbk.eu/must-c/).
+
+This model was contributed by [valhalla](https://huggingface.co/valhalla). The original code can be found [here](https://github.com/pytorch/fairseq/tree/master/examples/speech_to_text).
+
+## Inference
+
+Speech2Text is a speech model that accepts a float tensor of log-mel filter-bank features extracted from the speech
+signal. It's a transformer-based seq2seq model, so the transcripts/translations are generated autoregressively. The
+`generate()` method can be used for inference.
+
+The [`Speech2TextFeatureExtractor`] class is responsible for extracting the log-mel filter-bank
+features. The [`Speech2TextProcessor`] wraps [`Speech2TextFeatureExtractor`] and
+[`Speech2TextTokenizer`] into a single instance to both extract the input features and decode the
+predicted token ids.
+
+The feature extractor depends on `torchaudio` and the tokenizer depends on `sentencepiece` so be sure to
+install those packages before running the examples. You could either install those as extra speech dependencies with
+`pip install transformers"[speech, sentencepiece]"` or install the packages separately with `pip install torchaudio sentencepiece`. Also `torchaudio` requires the development version of the [libsndfile](http://www.mega-nerd.com/libsndfile/) package which can be installed via a system package manager. On Ubuntu it can
+be installed as follows: `apt install libsndfile1-dev`
+
+- ASR and Speech Translation
+
+```python
+>>> import torch
+>>> from transformers import Speech2TextProcessor, Speech2TextForConditionalGeneration
+>>> from datasets import load_dataset
+
+>>> model = Speech2TextForConditionalGeneration.from_pretrained("facebook/s2t-small-librispeech-asr")
+>>> processor = Speech2TextProcessor.from_pretrained("facebook/s2t-small-librispeech-asr")
+
+
+>>> ds = load_dataset("hf-internal-testing/librispeech_asr_demo", "clean", split="validation")
+
+>>> inputs = processor(ds[0]["audio"]["array"], sampling_rate=ds[0]["audio"]["sampling_rate"], return_tensors="pt")
+>>> generated_ids = model.generate(inputs["input_features"], attention_mask=inputs["attention_mask"])
+
+>>> transcription = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> transcription
+['mister quilter is the apostle of the middle classes and we are glad to welcome his gospel']
+```
+
+- Multilingual speech translation
+
+ For multilingual speech translation models, `eos_token_id` is used as the `decoder_start_token_id` and
+ the target language id is forced as the first generated token. To force the target language id as the first
+ generated token, pass the `forced_bos_token_id` parameter to the `generate()` method. The following
+ example shows how to translate English speech to French text using the *facebook/s2t-medium-mustc-multilingual-st*
+ checkpoint.
+
+```python
+>>> import torch
+>>> from transformers import Speech2TextProcessor, Speech2TextForConditionalGeneration
+>>> from datasets import load_dataset
+
+>>> model = Speech2TextForConditionalGeneration.from_pretrained("facebook/s2t-medium-mustc-multilingual-st")
+>>> processor = Speech2TextProcessor.from_pretrained("facebook/s2t-medium-mustc-multilingual-st")
+
+>>> ds = load_dataset("hf-internal-testing/librispeech_asr_demo", "clean", split="validation")
+
+>>> inputs = processor(ds[0]["audio"]["array"], sampling_rate=ds[0]["audio"]["sampling_rate"], return_tensors="pt")
+>>> generated_ids = model.generate(
+... inputs["input_features"],
+... attention_mask=inputs["attention_mask"],
+... forced_bos_token_id=processor.tokenizer.lang_code_to_id["fr"],
+... )
+
+>>> translation = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> translation
+["(Vidéo) Si M. Kilder est l'apossible des classes moyennes, et nous sommes heureux d'être accueillis dans son évangile."]
+```
+
+See the [model hub](https://huggingface.co/models?filter=speech_to_text) to look for Speech2Text checkpoints.
+
+## Speech2TextConfig
+
+[[autodoc]] Speech2TextConfig
+
+## Speech2TextTokenizer
+
+[[autodoc]] Speech2TextTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## Speech2TextFeatureExtractor
+
+[[autodoc]] Speech2TextFeatureExtractor
+ - __call__
+
+## Speech2TextProcessor
+
+[[autodoc]] Speech2TextProcessor
+ - __call__
+ - from_pretrained
+ - save_pretrained
+ - batch_decode
+ - decode
+
+
+
+
+## Speech2TextModel
+
+[[autodoc]] Speech2TextModel
+ - forward
+
+## Speech2TextForConditionalGeneration
+
+[[autodoc]] Speech2TextForConditionalGeneration
+ - forward
+
+
+
+
+## TFSpeech2TextModel
+
+[[autodoc]] TFSpeech2TextModel
+ - call
+
+## TFSpeech2TextForConditionalGeneration
+
+[[autodoc]] TFSpeech2TextForConditionalGeneration
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/speech_to_text_2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/speech_to_text_2.md
new file mode 100644
index 0000000000000000000000000000000000000000..a3d836455b19b1bccbffda7ee29fe769c7f02865
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/speech_to_text_2.md
@@ -0,0 +1,133 @@
+
+*This model was released on 2021-04-14 and added to Hugging Face Transformers on 2023-06-20.*
+
+# Speech2Text2
+
+
+
+ This model is in maintenance mode only, we don't accept any new PRs changing its code.
+ If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+ You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The Speech2Text2 model is used together with [Wav2Vec2](wav2vec2) for Speech Translation models proposed in
+[Large-Scale Self- and Semi-Supervised Learning for Speech Translation](https://huggingface.co/papers/2104.06678) by
+Changhan Wang, Anne Wu, Juan Pino, Alexei Baevski, Michael Auli, Alexis Conneau.
+
+Speech2Text2 is a *decoder-only* transformer model that can be used with any speech *encoder-only*, such as
+[Wav2Vec2](wav2vec2) or [HuBERT](hubert) for Speech-to-Text tasks. Please refer to the
+[SpeechEncoderDecoder](speech-encoder-decoder) class on how to combine Speech2Text2 with any speech *encoder-only*
+model.
+
+This model was contributed by [Patrick von Platen](https://huggingface.co/patrickvonplaten).
+
+The original code can be found [here](https://github.com/pytorch/fairseq/blob/1f7ef9ed1e1061f8c7f88f8b94c7186834398690/fairseq/models/wav2vec/wav2vec2_asr.py#L266).
+
+## Usage tips
+
+- Speech2Text2 achieves state-of-the-art results on the CoVoST Speech Translation dataset. For more information, see
+ the [official models](https://huggingface.co/models?other=speech2text2) .
+- Speech2Text2 is always used within the [SpeechEncoderDecoder](speech-encoder-decoder) framework.
+- Speech2Text2's tokenizer is based on [fastBPE](https://github.com/glample/fastBPE).
+
+## Inference
+
+Speech2Text2's [`SpeechEncoderDecoderModel`] model accepts raw waveform input values from speech and
+makes use of [`~generation.GenerationMixin.generate`] to translate the input speech
+autoregressively to the target language.
+
+The [`Wav2Vec2FeatureExtractor`] class is responsible for preprocessing the input speech and
+[`Speech2Text2Tokenizer`] decodes the generated target tokens to the target string. The
+[`Speech2Text2Processor`] wraps [`Wav2Vec2FeatureExtractor`] and
+[`Speech2Text2Tokenizer`] into a single instance to both extract the input features and decode the
+predicted token ids.
+
+- Step-by-step Speech Translation
+
+```python
+>>> from transformers import Speech2Text2Processor, SpeechEncoderDecoderModel
+>>> from datasets import load_dataset
+
+>>> model = SpeechEncoderDecoderModel.from_pretrained("facebook/s2t-wav2vec2-large-en-de")
+>>> processor = Speech2Text2Processor.from_pretrained("facebook/s2t-wav2vec2-large-en-de")
+
+
+>>> def map_to_array(example):
+... example["speech"] = example["audio"]["array"]
+... return example
+
+
+>>> ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+>>> ds = ds.map(map_to_array)
+
+>>> inputs = processor(ds["speech"][0], sampling_rate=16_000, return_tensors="pt")
+>>> generated_ids = model.generate(inputs=inputs["input_values"], attention_mask=inputs["attention_mask"])
+
+>>> transcription = processor.batch_decode(generated_ids)
+```
+
+- Speech Translation via Pipelines
+
+ The automatic speech recognition pipeline can also be used to translate speech in just a couple lines of code
+
+```python
+>>> from datasets import load_dataset
+>>> from transformers import pipeline
+
+>>> librispeech_en = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+>>> asr = pipeline(
+... "automatic-speech-recognition",
+... model="facebook/s2t-wav2vec2-large-en-de",
+... feature_extractor="facebook/s2t-wav2vec2-large-en-de",
+... )
+
+>>> translation_de = asr(librispeech_en[0]["file"])
+```
+
+See [model hub](https://huggingface.co/models?filter=speech2text2) to look for Speech2Text2 checkpoints.
+
+## Resources
+
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## Speech2Text2Config
+
+[[autodoc]] Speech2Text2Config
+
+## Speech2TextTokenizer
+
+[[autodoc]] Speech2Text2Tokenizer
+ - batch_decode
+ - decode
+ - save_vocabulary
+
+## Speech2Text2Processor
+
+[[autodoc]] Speech2Text2Processor
+ - __call__
+ - from_pretrained
+ - save_pretrained
+ - batch_decode
+ - decode
+
+## Speech2Text2ForCausalLM
+
+[[autodoc]] Speech2Text2ForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/speecht5.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/speecht5.md
new file mode 100644
index 0000000000000000000000000000000000000000..317bb6dee223924d2695825d25c30a136b732114
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/speecht5.md
@@ -0,0 +1,90 @@
+
+*This model was released on 2021-10-14 and added to Hugging Face Transformers on 2023-02-03.*
+
+# SpeechT5
+
+
+
+
+
+## Overview
+
+The SpeechT5 model was proposed in [SpeechT5: Unified-Modal Encoder-Decoder Pre-Training for Spoken Language Processing](https://huggingface.co/papers/2110.07205) by Junyi Ao, Rui Wang, Long Zhou, Chengyi Wang, Shuo Ren, Yu Wu, Shujie Liu, Tom Ko, Qing Li, Yu Zhang, Zhihua Wei, Yao Qian, Jinyu Li, Furu Wei.
+
+The abstract from the paper is the following:
+
+*Motivated by the success of T5 (Text-To-Text Transfer Transformer) in pre-trained natural language processing models, we propose a unified-modal SpeechT5 framework that explores the encoder-decoder pre-training for self-supervised speech/text representation learning. The SpeechT5 framework consists of a shared encoder-decoder network and six modal-specific (speech/text) pre/post-nets. After preprocessing the input speech/text through the pre-nets, the shared encoder-decoder network models the sequence-to-sequence transformation, and then the post-nets generate the output in the speech/text modality based on the output of the decoder. Leveraging large-scale unlabeled speech and text data, we pre-train SpeechT5 to learn a unified-modal representation, hoping to improve the modeling capability for both speech and text. To align the textual and speech information into this unified semantic space, we propose a cross-modal vector quantization approach that randomly mixes up speech/text states with latent units as the interface between encoder and decoder. Extensive evaluations show the superiority of the proposed SpeechT5 framework on a wide variety of spoken language processing tasks, including automatic speech recognition, speech synthesis, speech translation, voice conversion, speech enhancement, and speaker identification.*
+
+This model was contributed by [Matthijs](https://huggingface.co/Matthijs). The original code can be found [here](https://github.com/microsoft/SpeechT5).
+
+## SpeechT5Config
+
+[[autodoc]] SpeechT5Config
+
+## SpeechT5HifiGanConfig
+
+[[autodoc]] SpeechT5HifiGanConfig
+
+## SpeechT5Tokenizer
+
+[[autodoc]] SpeechT5Tokenizer
+ - __call__
+ - save_vocabulary
+ - decode
+ - batch_decode
+
+## SpeechT5FeatureExtractor
+
+[[autodoc]] SpeechT5FeatureExtractor
+ - __call__
+
+## SpeechT5Processor
+
+[[autodoc]] SpeechT5Processor
+ - __call__
+ - pad
+ - from_pretrained
+ - save_pretrained
+ - batch_decode
+ - decode
+
+## SpeechT5Model
+
+[[autodoc]] SpeechT5Model
+ - forward
+
+## SpeechT5ForSpeechToText
+
+[[autodoc]] SpeechT5ForSpeechToText
+ - forward
+
+## SpeechT5ForTextToSpeech
+
+[[autodoc]] SpeechT5ForTextToSpeech
+ - forward
+ - generate
+
+## SpeechT5ForSpeechToSpeech
+
+[[autodoc]] SpeechT5ForSpeechToSpeech
+ - forward
+ - generate_speech
+
+## SpeechT5HifiGan
+
+[[autodoc]] SpeechT5HifiGan
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/splinter.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/splinter.md
new file mode 100644
index 0000000000000000000000000000000000000000..c3ef982da915368ce1afa5b27bf08ee74004026a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/splinter.md
@@ -0,0 +1,92 @@
+
+*This model was released on 2021-01-02 and added to Hugging Face Transformers on 2021-08-17.*
+
+# Splinter
+
+
+
+
+
+## Overview
+
+The Splinter model was proposed in [Few-Shot Question Answering by Pretraining Span Selection](https://huggingface.co/papers/2101.00438) by Ori Ram, Yuval Kirstain, Jonathan Berant, Amir Globerson, Omer Levy. Splinter
+is an encoder-only transformer (similar to BERT) pretrained using the recurring span selection task on a large corpus
+comprising Wikipedia and the Toronto Book Corpus.
+
+The abstract from the paper is the following:
+
+In several question answering benchmarks, pretrained models have reached human parity through fine-tuning on an order
+of 100,000 annotated questions and answers. We explore the more realistic few-shot setting, where only a few hundred
+training examples are available, and observe that standard models perform poorly, highlighting the discrepancy between
+current pretraining objectives and question answering. We propose a new pretraining scheme tailored for question
+answering: recurring span selection. Given a passage with multiple sets of recurring spans, we mask in each set all
+recurring spans but one, and ask the model to select the correct span in the passage for each masked span. Masked spans
+are replaced with a special token, viewed as a question representation, that is later used during fine-tuning to select
+the answer span. The resulting model obtains surprisingly good results on multiple benchmarks (e.g., 72.7 F1 on SQuAD
+with only 128 training examples), while maintaining competitive performance in the high-resource setting.
+
+This model was contributed by [yuvalkirstain](https://huggingface.co/yuvalkirstain) and [oriram](https://huggingface.co/oriram). The original code can be found [here](https://github.com/oriram/splinter).
+
+## Usage tips
+
+- Splinter was trained to predict answers spans conditioned on a special [QUESTION] token. These tokens contextualize
+ to question representations which are used to predict the answers. This layer is called QASS, and is the default
+ behaviour in the [`SplinterForQuestionAnswering`] class. Therefore:
+- Use [`SplinterTokenizer`] (rather than [`BertTokenizer`]), as it already
+ contains this special token. Also, its default behavior is to use this token when two sequences are given (for
+ example, in the *run_qa.py* script).
+- If you plan on using Splinter outside *run_qa.py*, please keep in mind the question token - it might be important for
+ the success of your model, especially in a few-shot setting.
+- Please note there are two different checkpoints for each size of Splinter. Both are basically the same, except that
+ one also has the pretrained weights of the QASS layer (*tau/splinter-base-qass* and *tau/splinter-large-qass*) and one
+ doesn't (*tau/splinter-base* and *tau/splinter-large*). This is done to support randomly initializing this layer at
+ fine-tuning, as it is shown to yield better results for some cases in the paper.
+
+## Resources
+
+- [Question answering task guide](../tasks/question-answering)
+
+## SplinterConfig
+
+[[autodoc]] SplinterConfig
+
+## SplinterTokenizer
+
+[[autodoc]] SplinterTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## SplinterTokenizerFast
+
+[[autodoc]] SplinterTokenizerFast
+
+## SplinterModel
+
+[[autodoc]] SplinterModel
+ - forward
+
+## SplinterForQuestionAnswering
+
+[[autodoc]] SplinterForQuestionAnswering
+ - forward
+
+## SplinterForPreTraining
+
+[[autodoc]] SplinterForPreTraining
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/squeezebert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/squeezebert.md
new file mode 100644
index 0000000000000000000000000000000000000000..70e409daf717c99a8ff41fb1ff51f8e47da04a12
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/squeezebert.md
@@ -0,0 +1,104 @@
+
+*This model was released on 2020-06-19 and added to Hugging Face Transformers on 2020-11-16.*
+
+# SqueezeBERT
+
+
+
+
+
+## Overview
+
+The SqueezeBERT model was proposed in [SqueezeBERT: What can computer vision teach NLP about efficient neural networks?](https://huggingface.co/papers/2006.11316) by Forrest N. Iandola, Albert E. Shaw, Ravi Krishna, Kurt W. Keutzer. It's a
+bidirectional transformer similar to the BERT model. The key difference between the BERT architecture and the
+SqueezeBERT architecture is that SqueezeBERT uses [grouped convolutions](https://blog.yani.io/filter-group-tutorial)
+instead of fully-connected layers for the Q, K, V and FFN layers.
+
+The abstract from the paper is the following:
+
+*Humans read and write hundreds of billions of messages every day. Further, due to the availability of large datasets,
+large computing systems, and better neural network models, natural language processing (NLP) technology has made
+significant strides in understanding, proofreading, and organizing these messages. Thus, there is a significant
+opportunity to deploy NLP in myriad applications to help web users, social networks, and businesses. In particular, we
+consider smartphones and other mobile devices as crucial platforms for deploying NLP models at scale. However, today's
+highly-accurate NLP neural network models such as BERT and RoBERTa are extremely computationally expensive, with
+BERT-base taking 1.7 seconds to classify a text snippet on a Pixel 3 smartphone. In this work, we observe that methods
+such as grouped convolutions have yielded significant speedups for computer vision networks, but many of these
+techniques have not been adopted by NLP neural network designers. We demonstrate how to replace several operations in
+self-attention layers with grouped convolutions, and we use this technique in a novel network architecture called
+SqueezeBERT, which runs 4.3x faster than BERT-base on the Pixel 3 while achieving competitive accuracy on the GLUE test
+set. The SqueezeBERT code will be released.*
+
+This model was contributed by [forresti](https://huggingface.co/forresti).
+
+## Usage tips
+
+- SqueezeBERT is a model with absolute position embeddings so it's usually advised to pad the inputs on the right
+ rather than the left.
+- SqueezeBERT is similar to BERT and therefore relies on the masked language modeling (MLM) objective. It is therefore
+ efficient at predicting masked tokens and at NLU in general, but is not optimal for text generation. Models trained
+ with a causal language modeling (CLM) objective are better in that regard.
+- For best results when finetuning on sequence classification tasks, it is recommended to start with the
+ *squeezebert/squeezebert-mnli-headless* checkpoint.
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+- [Multiple choice task guide](../tasks/multiple_choice)
+
+## SqueezeBertConfig
+
+[[autodoc]] SqueezeBertConfig
+
+## SqueezeBertTokenizer
+
+[[autodoc]] SqueezeBertTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## SqueezeBertTokenizerFast
+
+[[autodoc]] SqueezeBertTokenizerFast
+
+## SqueezeBertModel
+
+[[autodoc]] SqueezeBertModel
+
+## SqueezeBertForMaskedLM
+
+[[autodoc]] SqueezeBertForMaskedLM
+
+## SqueezeBertForSequenceClassification
+
+[[autodoc]] SqueezeBertForSequenceClassification
+
+## SqueezeBertForMultipleChoice
+
+[[autodoc]] SqueezeBertForMultipleChoice
+
+## SqueezeBertForTokenClassification
+
+[[autodoc]] SqueezeBertForTokenClassification
+
+## SqueezeBertForQuestionAnswering
+
+[[autodoc]] SqueezeBertForQuestionAnswering
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/stablelm.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/stablelm.md
new file mode 100644
index 0000000000000000000000000000000000000000..9e6c63540ca3ca087bc422b1c35c9504ae26e33a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/stablelm.md
@@ -0,0 +1,118 @@
+
+*This model was released on 2023-09-05 and added to Hugging Face Transformers on 2024-02-14.*
+
+# StableLM
+
+
+
+
+
+
+
+## Overview
+
+StableLM 3B 4E1T ([blog post](https://stability.ai/news/stable-lm-3b-sustainable-high-performance-language-models-smart-devices)) was proposed in [StableLM 3B 4E1T: Technical Report](https://stability.wandb.io/stability-llm/stable-lm/reports/StableLM-3B-4E1T--VmlldzoyMjU4?accessToken=u3zujipenkx5g7rtcj9qojjgxpconyjktjkli2po09nffrffdhhchq045vp0wyfo) by Stability AI and is the first model in a series of multi-epoch pre-trained language models.
+
+### Model Details
+
+StableLM 3B 4E1T is a decoder-only base language model pre-trained on 1 trillion tokens of diverse English and code datasets for four epochs.
+The model architecture is transformer-based with partial Rotary Position Embeddings, SwiGLU activation, LayerNorm, etc.
+
+We also provide StableLM Zephyr 3B, an instruction fine-tuned version of the model that can be used for chat-based applications.
+
+### Usage Tips
+
+- The architecture is similar to LLaMA but with RoPE applied to 25% of head embedding dimensions, LayerNorm instead of RMSNorm, and optional QKV bias terms.
+- `StableLM 3B 4E1T`-based models uses the same tokenizer as [`GPTNeoXTokenizerFast`].
+
+`StableLM 3B 4E1T` and `StableLM Zephyr 3B` can be found on the [Huggingface Hub](https://huggingface.co/stabilityai)
+
+The following code snippet demonstrates how to use `StableLM 3B 4E1T` for inference:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, infer_device, set_seed
+>>> device = infer_device() # the device to load the model onto
+
+>>> set_seed(0)
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stabilityai/stablelm-3b-4e1t")
+>>> model = AutoModelForCausalLM.from_pretrained("stabilityai/stablelm-3b-4e1t")
+>>> model.to(device) # doctest: +IGNORE_RESULT
+
+>>> model_inputs = tokenizer("The weather is always wonderful in", return_tensors="pt").to(model.device)
+
+>>> generated_ids = model.generate(**model_inputs, max_length=32, do_sample=True)
+>>> responses = tokenizer.batch_decode(generated_ids, skip_special_tokens=True)
+>>> responses
+['The weather is always wonderful in Costa Rica, which makes it a prime destination for retirees. That’s where the Pensionado program comes in, offering']
+```
+
+## Combining StableLM and Flash Attention 2
+
+First, make sure to install the latest version of Flash Attention v2.
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Also make sure that your hardware is compatible with Flash-Attention 2. Read more about it in the official documentation of the [`flash-attn`](https://github.com/Dao-AILab/flash-attention) repository. Note: you must load your model in half-precision (e.g. `torch.bfloat16`).
+
+Now, to run the model with Flash Attention 2, refer to the snippet below:
+
+```python
+>>> import torch
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer, infer_device, set_seed
+>>> device = infer_device() # the device to load the model onto
+
+>>> set_seed(0)
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stabilityai/stablelm-3b-4e1t")
+>>> model = AutoModelForCausalLM.from_pretrained("stabilityai/stablelm-3b-4e1t", torch_dtype=torch.bfloat16, attn_implementation="flash_attention_2") # doctest: +SKIP
+>>> model.to(device) # doctest: +SKIP
+
+>>> model_inputs = tokenizer("The weather is always wonderful in", return_tensors="pt").to(model.device)
+
+>>> generated_ids = model.generate(**model_inputs, max_length=32, do_sample=True) # doctest: +SKIP
+>>> responses = tokenizer.batch_decode(generated_ids, skip_special_tokens=True) # doctest: +SKIP
+>>> responses # doctest: +SKIP
+['The weather is always wonderful in Costa Rica, which makes it a prime destination for retirees. That’s where the Pensionado program comes in, offering']
+```
+
+
+## StableLmConfig
+
+[[autodoc]] StableLmConfig
+
+## StableLmModel
+
+[[autodoc]] StableLmModel
+ - forward
+
+## StableLmForCausalLM
+
+[[autodoc]] StableLmForCausalLM
+ - forward
+
+## StableLmForSequenceClassification
+
+[[autodoc]] StableLmForSequenceClassification
+ - forward
+
+## StableLmForTokenClassification
+
+[[autodoc]] StableLmForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/starcoder2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/starcoder2.md
new file mode 100644
index 0000000000000000000000000000000000000000..2d27aed399cd5fdd91786af8f6ee06c4c3ca1b4d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/starcoder2.md
@@ -0,0 +1,81 @@
+
+*This model was released on 2024-02-29 and added to Hugging Face Transformers on 2024-02-28.*
+
+# Starcoder2
+
+
+
+
+
+
+
+
+## Overview
+
+StarCoder2 is a family of open LLMs for code and comes in 3 different sizes with 3B, 7B and 15B parameters. The flagship StarCoder2-15B model is trained on over 4 trillion tokens and 600+ programming languages from The Stack v2. All models use Grouped Query Attention, a context window of 16,384 tokens with a sliding window attention of 4,096 tokens, and were trained using the Fill-in-the-Middle objective. The models have been released with the paper [StarCoder 2 and The Stack v2: The Next Generation](https://huggingface.co/papers/2402.19173) by Anton Lozhkov, Raymond Li, Loubna Ben Allal, Federico Cassano, Joel Lamy-Poirier, Nouamane Tazi, Ao Tang, Dmytro Pykhtar, Jiawei Liu, Yuxiang Wei, Tianyang Liu, Max Tian, Denis Kocetkov, Arthur Zucker, Younes Belkada, Zijian Wang, Qian Liu, Dmitry Abulkhanov, Indraneil Paul, Zhuang Li, Wen-Ding Li, Megan Risdal, Jia Li, Jian Zhu, Terry Yue Zhuo, Evgenii Zheltonozhskii, Nii Osae Osae Dade, Wenhao Yu, Lucas Krauß, Naman Jain, Yixuan Su, Xuanli He, Manan Dey, Edoardo Abati, Yekun Chai, Niklas Muennighoff, Xiangru Tang, Muhtasham Oblokulov, Christopher Akiki, Marc Marone, Chenghao Mou, Mayank Mishra, Alex Gu, Binyuan Hui, Tri Dao, Armel Zebaze, Olivier Dehaene, Nicolas Patry, Canwen Xu, Julian McAuley, Han Hu, Torsten Scholak, Sebastien Paquet, Jennifer Robinson, Carolyn Jane Anderson, Nicolas Chapados, Mostofa Patwary, Nima Tajbakhsh, Yacine Jernite, Carlos Muñoz Ferrandis, Lingming Zhang, Sean Hughes, Thomas Wolf, Arjun Guha, Leandro von Werra, and Harm de Vries.
+
+The abstract of the paper is the following:
+
+> The BigCode project, an open-scientific collaboration focused on the responsible development of Large Language Models for Code (Code LLMs), introduces StarCoder2. In partnership with Software Heritage (SWH), we build The Stack v2 on top of the digital commons of their source code archive. Alongside the SWH repositories spanning 619 programming languages, we carefully select other high-quality data sources, such as GitHub pull requests, Kaggle notebooks, and code documentation. This results in a training set that is 4x larger than the first StarCoder dataset. We train StarCoder2 models with 3B, 7B, and 15B parameters on 3.3 to 4.3 trillion tokens and thoroughly evaluate them on a comprehensive set of Code LLM benchmarks. We find that our small model, StarCoder2-3B, outperforms other Code LLMs of similar size on most benchmarks, and also outperforms StarCoderBase-15B. Our large model, StarCoder2- 15B, significantly outperforms other models of comparable size. In addition, it matches or outperforms CodeLlama-34B, a model more than twice its size. Although DeepSeekCoder- 33B is the best-performing model at code completion for high-resource languages, we find that StarCoder2-15B outperforms it on math and code reasoning benchmarks, as well as several low-resource languages. We make the model weights available under an OpenRAIL license and ensure full transparency regarding the training data by releasing the SoftWare Heritage persistent IDentifiers (SWHIDs) of the source code data.
+## License
+
+The models are licensed under the [BigCode OpenRAIL-M v1 license agreement](https://huggingface.co/spaces/bigcode/bigcode-model-license-agreement).
+
+## Usage tips
+
+The StarCoder2 models can be found in the [HuggingFace hub](https://huggingface.co/collections/bigcode/starcoder2-65de6da6e87db3383572be1a). You can find some examples for inference and fine-tuning in StarCoder2's [GitHub repo](https://github.com/bigcode-project/starcoder2).
+
+These ready-to-use checkpoints can be downloaded and used via the HuggingFace Hub:
+
+```python
+>>> from transformers import AutoModelForCausalLM, AutoTokenizer
+
+>>> model = AutoModelForCausalLM.from_pretrained("bigcode/starcoder2-7b", device_map="auto")
+>>> tokenizer = AutoTokenizer.from_pretrained("bigcode/starcoder2-7b")
+
+>>> prompt = "def print_hello_world():"
+
+>>> model_inputs = tokenizer([prompt], return_tensors="pt").to(model.device)
+
+>>> generated_ids = model.generate(**model_inputs, max_new_tokens=10, do_sample=False)
+>>> tokenizer.batch_decode(generated_ids)[0]
+'def print_hello_world():\n print("Hello World!")\n\ndef print'
+```
+
+## Starcoder2Config
+
+[[autodoc]] Starcoder2Config
+
+## Starcoder2Model
+
+[[autodoc]] Starcoder2Model
+ - forward
+
+## Starcoder2ForCausalLM
+
+[[autodoc]] Starcoder2ForCausalLM
+ - forward
+
+## Starcoder2ForSequenceClassification
+
+[[autodoc]] Starcoder2ForSequenceClassification
+ - forward
+
+## Starcoder2ForTokenClassification
+
+[[autodoc]] Starcoder2ForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/superglue.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/superglue.md
new file mode 100644
index 0000000000000000000000000000000000000000..6e11ea31544bf207e174aa88d0c33cf8dc553e4d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/superglue.md
@@ -0,0 +1,143 @@
+
+*This model was released on 2019-11-26 and added to Hugging Face Transformers on 2025-01-20.*
+
+
+
+
+
+
+
+# SuperGlue
+
+[SuperGlue](https://huggingface.co/papers/1911.11763) is a neural network that matches two sets of local features by jointly finding correspondences and rejecting non-matchable points. Assignments are estimated by solving a differentiable optimal transport problem, whose costs are predicted by a graph neural network. SuperGlue introduces a flexible context aggregation mechanism based on attention, enabling it to reason about the underlying 3D scene and feature assignments jointly. Paired with the [SuperPoint model](https://huggingface.co/magic-leap-community/superpoint), it can be used to match two images and estimate the pose between them. This model is useful for tasks such as image matching, homography estimation, etc.
+
+You can find all the original SuperGlue checkpoints under the [Magic Leap Community](https://huggingface.co/magic-leap-community) organization.
+
+> [!TIP]
+> This model was contributed by [stevenbucaille](https://huggingface.co/stevenbucaille).
+>
+> Click on the SuperGlue models in the right sidebar for more examples of how to apply SuperGlue to different computer vision tasks.
+
+The example below demonstrates how to match keypoints between two images with the [`AutoModel`] class.
+
+
+
+
+```py
+from transformers import AutoImageProcessor, AutoModel
+import torch
+from PIL import Image
+import requests
+
+url_image1 = "https://raw.githubusercontent.com/magicleap/SuperGluePretrainedNetwork/refs/heads/master/assets/phototourism_sample_images/united_states_capitol_98169888_3347710852.jpg"
+image1 = Image.open(requests.get(url_image1, stream=True).raw)
+url_image2 = "https://raw.githubusercontent.com/magicleap/SuperGluePretrainedNetwork/refs/heads/master/assets/phototourism_sample_images/united_states_capitol_26757027_6717084061.jpg"
+image2 = Image.open(requests.get(url_image2, stream=True).raw)
+
+images = [image1, image2]
+
+processor = AutoImageProcessor.from_pretrained("magic-leap-community/superglue_outdoor")
+model = AutoModel.from_pretrained("magic-leap-community/superglue_outdoor")
+
+inputs = processor(images, return_tensors="pt")
+with torch.no_grad():
+ outputs = model(**inputs)
+
+# Post-process to get keypoints and matches
+image_sizes = [[(image.height, image.width) for image in images]]
+processed_outputs = processor.post_process_keypoint_matching(outputs, image_sizes, threshold=0.2)
+```
+
+
+
+
+## Notes
+
+- SuperGlue performs feature matching between two images simultaneously, requiring pairs of images as input.
+
+ ```python
+ from transformers import AutoImageProcessor, AutoModel
+ import torch
+ from PIL import Image
+ import requests
+
+ processor = AutoImageProcessor.from_pretrained("magic-leap-community/superglue_outdoor")
+ model = AutoModel.from_pretrained("magic-leap-community/superglue_outdoor")
+
+ # SuperGlue requires pairs of images
+ images = [image1, image2]
+ inputs = processor(images, return_tensors="pt")
+ outputs = model(**inputs)
+
+ # Extract matching information
+ keypoints0 = outputs.keypoints0 # Keypoints in first image
+ keypoints1 = outputs.keypoints1 # Keypoints in second image
+ matches = outputs.matches # Matching indices
+ matching_scores = outputs.matching_scores # Confidence scores
+ ```
+
+- The model outputs matching indices, keypoints, and confidence scores for each match.
+- For better visualization and analysis, use the [`SuperGlueImageProcessor.post_process_keypoint_matching`] method to get matches in a more readable format.
+
+ ```py
+ # Process outputs for visualization
+ image_sizes = [[(image.height, image.width) for image in images]]
+ processed_outputs = processor.post_process_keypoint_matching(outputs, image_sizes, threshold=0.2)
+
+ for i, output in enumerate(processed_outputs):
+ print(f"For the image pair {i}")
+ for keypoint0, keypoint1, matching_score in zip(
+ output["keypoints0"], output["keypoints1"], output["matching_scores"]
+ ):
+ print(f"Keypoint at {keypoint0.numpy()} matches with keypoint at {keypoint1.numpy()} with score {matching_score}")
+ ```
+
+- Visualize the matches between the images using the built-in plotting functionality.
+
+ ```py
+ # Easy visualization using the built-in plotting method
+ processor.visualize_keypoint_matching(images, processed_outputs)
+ ```
+
+
+
+
+
+## Resources
+
+- Refer to the [original SuperGlue repository](https://github.com/magicleap/SuperGluePretrainedNetwork) for more examples and implementation details.
+
+## SuperGlueConfig
+
+[[autodoc]] SuperGlueConfig
+
+## SuperGlueImageProcessor
+
+[[autodoc]] SuperGlueImageProcessor
+
+- preprocess
+- post_process_keypoint_matching
+- visualize_keypoint_matching
+
+
+
+## SuperGlueForKeypointMatching
+
+[[autodoc]] SuperGlueForKeypointMatching
+
+- forward
+
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/superpoint.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/superpoint.md
new file mode 100644
index 0000000000000000000000000000000000000000..b0502664146f2213065b9bf839f921f714ae330b
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/superpoint.md
@@ -0,0 +1,150 @@
+
+*This model was released on 2017-12-20 and added to Hugging Face Transformers on 2024-03-19.*
+
+
+
+
+
+
+
+# SuperPoint
+
+[SuperPoint](https://huggingface.co/papers/1712.07629) is the result of self-supervised training of a fully-convolutional network for interest point detection and description. The model is able to detect interest points that are repeatable under homographic transformations and provide a descriptor for each point. Usage on it's own is limited, but it can be used as a feature extractor for other tasks such as homography estimation and image matching.
+
+
+
+You can find all the original SuperPoint checkpoints under the [Magic Leap Community](https://huggingface.co/magic-leap-community) organization.
+
+> [!TIP]
+> This model was contributed by [stevenbucaille](https://huggingface.co/stevenbucaille).
+>
+> Click on the SuperPoint models in the right sidebar for more examples of how to apply SuperPoint to different computer vision tasks.
+
+
+
+The example below demonstrates how to detect interest points in an image with the [`AutoModel`] class.
+
+
+
+```py
+from transformers import AutoImageProcessor, SuperPointForKeypointDetection
+import torch
+from PIL import Image
+import requests
+
+url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+processor = AutoImageProcessor.from_pretrained("magic-leap-community/superpoint")
+model = SuperPointForKeypointDetection.from_pretrained("magic-leap-community/superpoint")
+
+inputs = processor(image, return_tensors="pt")
+with torch.no_grad():
+ outputs = model(**inputs)
+
+# Post-process to get keypoints, scores, and descriptors
+image_size = (image.height, image.width)
+processed_outputs = processor.post_process_keypoint_detection(outputs, [image_size])
+```
+
+
+
+
+## Notes
+
+- SuperPoint outputs a dynamic number of keypoints per image, which makes it suitable for tasks requiring variable-length feature representations.
+
+ ```py
+ from transformers import AutoImageProcessor, SuperPointForKeypointDetection
+ import torch
+ from PIL import Image
+ import requests
+ processor = AutoImageProcessor.from_pretrained("magic-leap-community/superpoint")
+ model = SuperPointForKeypointDetection.from_pretrained("magic-leap-community/superpoint")
+ url_image_1 = "http://images.cocodataset.org/val2017/000000039769.jpg"
+ image_1 = Image.open(requests.get(url_image_1, stream=True).raw)
+ url_image_2 = "http://images.cocodataset.org/test-stuff2017/000000000568.jpg"
+ image_2 = Image.open(requests.get(url_image_2, stream=True).raw)
+ images = [image_1, image_2]
+ inputs = processor(images, return_tensors="pt")
+ # Example of handling dynamic keypoint output
+ outputs = model(**inputs)
+ keypoints = outputs.keypoints # Shape varies per image
+ scores = outputs.scores # Confidence scores for each keypoint
+ descriptors = outputs.descriptors # 256-dimensional descriptors
+ mask = outputs.mask # Value of 1 corresponds to a keypoint detection
+ ```
+
+- The model provides both keypoint coordinates and their corresponding descriptors (256-dimensional vectors) in a single forward pass.
+- For batch processing with multiple images, you need to use the mask attribute to retrieve the respective information for each image. You can use the `post_process_keypoint_detection` from the `SuperPointImageProcessor` to retrieve the each image information.
+
+ ```py
+ # Batch processing example
+ images = [image1, image2, image3]
+ inputs = processor(images, return_tensors="pt")
+ outputs = model(**inputs)
+ image_sizes = [(img.height, img.width) for img in images]
+ processed_outputs = processor.post_process_keypoint_detection(outputs, image_sizes)
+ ```
+
+- You can then print the keypoints on the image of your choice to visualize the result:
+ ```py
+ import matplotlib.pyplot as plt
+ plt.axis("off")
+ plt.imshow(image_1)
+ plt.scatter(
+ outputs[0]["keypoints"][:, 0],
+ outputs[0]["keypoints"][:, 1],
+ c=outputs[0]["scores"] * 100,
+ s=outputs[0]["scores"] * 50,
+ alpha=0.8
+ )
+ plt.savefig(f"output_image.png")
+ ```
+
+
+
+
+
+## Resources
+
+- Refer to this [notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/SuperPoint/Inference_with_SuperPoint_to_detect_interest_points_in_an_image.ipynb) for an inference and visualization example.
+
+## SuperPointConfig
+
+[[autodoc]] SuperPointConfig
+
+## SuperPointImageProcessor
+
+[[autodoc]] SuperPointImageProcessor
+
+- preprocess
+
+## SuperPointImageProcessorFast
+
+[[autodoc]] SuperPointImageProcessorFast
+- preprocess
+- post_process_keypoint_detection
+
+
+
+## SuperPointForKeypointDetection
+
+[[autodoc]] SuperPointForKeypointDetection
+
+- forward
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/swiftformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/swiftformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..2ef242f70880c7e7f99f8367b780a35b877147d5
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/swiftformer.md
@@ -0,0 +1,60 @@
+
+*This model was released on 2023-03-27 and added to Hugging Face Transformers on 2023-05-12.*
+
+# SwiftFormer
+
+
+
+
+
+
+## Overview
+
+The SwiftFormer model was proposed in [SwiftFormer: Efficient Additive Attention for Transformer-based Real-time Mobile Vision Applications](https://huggingface.co/papers/2303.15446) by Abdelrahman Shaker, Muhammad Maaz, Hanoona Rasheed, Salman Khan, Ming-Hsuan Yang, Fahad Shahbaz Khan.
+
+The SwiftFormer paper introduces a novel efficient additive attention mechanism that effectively replaces the quadratic matrix multiplication operations in the self-attention computation with linear element-wise multiplications. A series of models called 'SwiftFormer' is built based on this, which achieves state-of-the-art performance in terms of both accuracy and mobile inference speed. Even their small variant achieves 78.5% top-1 ImageNet1K accuracy with only 0.8 ms latency on iPhone 14, which is more accurate and 2× faster compared to MobileViT-v2.
+
+The abstract from the paper is the following:
+
+*Self-attention has become a defacto choice for capturing global context in various vision applications. However, its quadratic computational complexity with respect to image resolution limits its use in real-time applications, especially for deployment on resource-constrained mobile devices. Although hybrid approaches have been proposed to combine the advantages of convolutions and self-attention for a better speed-accuracy trade-off, the expensive matrix multiplication operations in self-attention remain a bottleneck. In this work, we introduce a novel efficient additive attention mechanism that effectively replaces the quadratic matrix multiplication operations with linear element-wise multiplications. Our design shows that the key-value interaction can be replaced with a linear layer without sacrificing any accuracy. Unlike previous state-of-the-art methods, our efficient formulation of self-attention enables its usage at all stages of the network. Using our proposed efficient additive attention, we build a series of models called "SwiftFormer" which achieves state-of-the-art performance in terms of both accuracy and mobile inference speed. Our small variant achieves 78.5% top-1 ImageNet-1K accuracy with only 0.8 ms latency on iPhone 14, which is more accurate and 2x faster compared to MobileViT-v2.*
+
+This model was contributed by [shehan97](https://huggingface.co/shehan97). The TensorFlow version was contributed by [joaocmd](https://huggingface.co/joaocmd).
+The original code can be found [here](https://github.com/Amshaker/SwiftFormer).
+
+## SwiftFormerConfig
+
+[[autodoc]] SwiftFormerConfig
+
+## SwiftFormerModel
+
+[[autodoc]] SwiftFormerModel
+ - forward
+
+## SwiftFormerForImageClassification
+
+[[autodoc]] SwiftFormerForImageClassification
+ - forward
+
+## TFSwiftFormerModel
+
+[[autodoc]] TFSwiftFormerModel
+ - call
+
+## TFSwiftFormerForImageClassification
+
+[[autodoc]] TFSwiftFormerForImageClassification
+ - call
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/swin.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/swin.md
new file mode 100644
index 0000000000000000000000000000000000000000..22ab81488bf6600cc02243e2aa3bcd823182e7b2
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/swin.md
@@ -0,0 +1,132 @@
+
+*This model was released on 2021-03-25 and added to Hugging Face Transformers on 2022-01-21.*
+
+
+
+
+
+
+
+
+# Swin Transformer
+
+[Swin Transformer](https://huggingface.co/papers/2103.14030) is a hierarchical vision transformer. Images are processed in patches and windowed self-attention is used to capture local information. These windows are shifted across the image to allow for cross-window connections, capturing global information more efficiently. This hierarchical approach with shifted windows allows the Swin Transformer to process images effectively at different scales and achieve linear computational complexity relative to image size, making it a versatile backbone for various vision tasks like image classification and object detection.
+
+You can find all official Swin Transformer checkpoints under the [Microsoft](https://huggingface.co/microsoft?search_models=swin) organization.
+
+> [!TIP]
+> Click on the Swin Transformer models in the right sidebar for more examples of how to apply Swin Transformer to different image tasks.
+
+The example below demonstrates how to classify an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="image-classification",
+ model="microsoft/swin-tiny-patch4-window7-224",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg")
+```
+
+
+
+
+```py
+import torch
+import requests
+from PIL import Image
+from transformers import AutoModelForImageClassification, AutoImageProcessor
+
+image_processor = AutoImageProcessor.from_pretrained(
+ "microsoft/swin-tiny-patch4-window7-224",
+ use_fast=True,
+)
+model = AutoModelForImageClassification.from_pretrained(
+ "microsoft/swin-tiny-patch4-window7-224",
+ device_map="auto"
+)
+
+device = infer_device()
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+image = Image.open(requests.get(url, stream=True).raw)
+inputs = image_processor(image, return_tensors="pt").to(model.device)
+
+with torch.no_grad():
+ logits = model(**inputs).logits
+predicted_class_id = logits.argmax(dim=-1).item()
+
+class_labels = model.config.id2label
+predicted_class_label = class_labels[predicted_class_id]
+print(f"The predicted class label is: {predicted_class_label}")
+```
+
+
+
+## Notes
+
+- Swin can pad the inputs for any input height and width divisible by `32`.
+- Swin can be used as a [backbone](../backbones). When `output_hidden_states = True`, it outputs both `hidden_states` and `reshaped_hidden_states`. The `reshaped_hidden_states` have a shape of `(batch, num_channels, height, width)` rather than `(batch_size, sequence_length, num_channels)`.
+
+## SwinConfig
+
+[[autodoc]] SwinConfig
+
+
+
+
+## SwinModel
+
+[[autodoc]] SwinModel
+ - forward
+
+## SwinForMaskedImageModeling
+
+[[autodoc]] SwinForMaskedImageModeling
+ - forward
+
+## SwinForImageClassification
+
+[[autodoc]] transformers.SwinForImageClassification
+ - forward
+
+
+
+
+## TFSwinModel
+
+[[autodoc]] TFSwinModel
+ - call
+
+## TFSwinForMaskedImageModeling
+
+[[autodoc]] TFSwinForMaskedImageModeling
+ - call
+
+## TFSwinForImageClassification
+
+[[autodoc]] transformers.TFSwinForImageClassification
+ - call
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/swin2sr.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/swin2sr.md
new file mode 100644
index 0000000000000000000000000000000000000000..0837cf6fef3ff8bb12533332015c7e24fca3cda4
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/swin2sr.md
@@ -0,0 +1,71 @@
+
+*This model was released on 2022-09-22 and added to Hugging Face Transformers on 2022-12-16.*
+
+# Swin2SR
+
+
+
+
+
+## Overview
+
+The Swin2SR model was proposed in [Swin2SR: SwinV2 Transformer for Compressed Image Super-Resolution and Restoration](https://huggingface.co/papers/2209.11345) by Marcos V. Conde, Ui-Jin Choi, Maxime Burchi, Radu Timofte.
+Swin2SR improves the [SwinIR](https://github.com/JingyunLiang/SwinIR/) model by incorporating [Swin Transformer v2](swinv2) layers which mitigates issues such as training instability, resolution gaps between pre-training
+and fine-tuning, and hunger on data.
+
+The abstract from the paper is the following:
+
+*Compression plays an important role on the efficient transmission and storage of images and videos through band-limited systems such as streaming services, virtual reality or videogames. However, compression unavoidably leads to artifacts and the loss of the original information, which may severely degrade the visual quality. For these reasons, quality enhancement of compressed images has become a popular research topic. While most state-of-the-art image restoration methods are based on convolutional neural networks, other transformers-based methods such as SwinIR, show impressive performance on these tasks.
+In this paper, we explore the novel Swin Transformer V2, to improve SwinIR for image super-resolution, and in particular, the compressed input scenario. Using this method we can tackle the major issues in training transformer vision models, such as training instability, resolution gaps between pre-training and fine-tuning, and hunger on data. We conduct experiments on three representative tasks: JPEG compression artifacts removal, image super-resolution (classical and lightweight), and compressed image super-resolution. Experimental results demonstrate that our method, Swin2SR, can improve the training convergence and performance of SwinIR, and is a top-5 solution at the "AIM 2022 Challenge on Super-Resolution of Compressed Image and Video".*
+
+
+
+ Swin2SR architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/mv-lab/swin2sr).
+
+## Resources
+
+Demo notebooks for Swin2SR can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Swin2SR).
+
+A demo Space for image super-resolution with SwinSR can be found [here](https://huggingface.co/spaces/jjourney1125/swin2sr).
+
+## Swin2SRImageProcessor
+
+[[autodoc]] Swin2SRImageProcessor
+ - preprocess
+
+## Swin2SRImageProcessorFast
+
+[[autodoc]] Swin2SRImageProcessorFast
+ - preprocess
+
+## Swin2SRConfig
+
+[[autodoc]] Swin2SRConfig
+
+## Swin2SRModel
+
+[[autodoc]] Swin2SRModel
+ - forward
+
+## Swin2SRForImageSuperResolution
+
+[[autodoc]] Swin2SRForImageSuperResolution
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/swinv2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/swinv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..87de7aefa411d4459019644b201127eae2556985
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/swinv2.md
@@ -0,0 +1,104 @@
+
+*This model was released on 2021-11-18 and added to Hugging Face Transformers on 2022-07-27.*
+
+
+
+
+
+
+
+# Swin Transformer V2
+
+[Swin Transformer V2](https://huggingface.co/papers/2111.09883) is a 3B parameter model that focuses on how to scale a vision model to billions of parameters. It introduces techniques like residual-post-norm combined with cosine attention for improved training stability, log-spaced continuous position bias to better handle varying image resolutions between pre-training and fine-tuning, and a new pre-training method (SimMIM) to reduce the need for large amounts of labeled data. These improvements enable efficiently training very large models (up to 3 billion parameters) capable of processing high-resolution images.
+
+You can find official Swin Transformer V2 checkpoints under the [Microsoft](https://huggingface.co/microsoft?search_models=swinv2) organization.
+
+> [!TIP]
+> Click on the Swin Transformer V2 models in the right sidebar for more examples of how to apply Swin Transformer V2 to vision tasks.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="image-classification",
+ model="microsoft/swinv2-tiny-patch4-window8-256",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg")
+```
+
+
+
+
+
+```py
+import torch
+import requests
+from PIL import Image
+from transformers import AutoModelForImageClassification, AutoImageProcessor
+
+image_processor = AutoImageProcessor.from_pretrained(
+ "microsoft/swinv2-tiny-patch4-window8-256",
+)
+model = AutoModelForImageClassification.from_pretrained(
+ "microsoft/swinv2-tiny-patch4-window8-256",
+ device_map="auto"
+)
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/pipeline-cat-chonk.jpeg"
+image = Image.open(requests.get(url, stream=True).raw)
+inputs = image_processor(image, return_tensors="pt").to(model.device)
+
+with torch.no_grad():
+ logits = model(**inputs).logits
+
+predicted_class_id = logits.argmax(dim=-1).item()
+predicted_class_label = model.config.id2label[predicted_class_id]
+print(f"The predicted class label is: {predicted_class_label}")
+```
+
+
+
+
+## Notes
+
+- Swin Transformer V2 can pad the inputs for any input height and width divisible by `32`.
+- Swin Transformer V2 can be used as a [backbone](../backbones). When `output_hidden_states = True`, it outputs both `hidden_states` and `reshaped_hidden_states`. The `reshaped_hidden_states` have a shape of `(batch, num_channels, height, width)` rather than `(batch_size, sequence_length, num_channels)`.
+
+## Swinv2Config
+
+[[autodoc]] Swinv2Config
+
+## Swinv2Model
+
+[[autodoc]] Swinv2Model
+ - forward
+
+## Swinv2ForMaskedImageModeling
+
+[[autodoc]] Swinv2ForMaskedImageModeling
+ - forward
+
+## Swinv2ForImageClassification
+
+[[autodoc]] transformers.Swinv2ForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/switch_transformers.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/switch_transformers.md
new file mode 100644
index 0000000000000000000000000000000000000000..d15527a4781c5ba6af84f51b6aecca8a74c516df
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/switch_transformers.md
@@ -0,0 +1,131 @@
+
+*This model was released on 2021-01-11 and added to Hugging Face Transformers on 2022-11-15.*
+
+
+
+
+
+
+
+# Switch Transformers
+
+[Switch Transformers](https://huggingface.co/papers/2101.03961) is a sparse T5 model where the MLP layer is replaced by a Mixture-of-Experts (MoE). A routing mechanism associates each token with an expert and each expert is a dense MLP. Sparsity enables better scaling and the routing mechanism allows the model to select relevant weights on the fly which increases model capacity.
+
+You can find all the original Switch Transformers checkpoints under the [Switch Transformer](https://huggingface.co/collections/google/switch-transformers-release-6548c35c6507968374b56d1f) collection.
+
+
+> [!TIP]
+> This model was contributed by [ybelkada](https://huggingface.co/ybelkada) and [ArthurZ](https://huggingface.co/ArthurZ).
+>
+> Click on the Switch Transformers models in the right sidebar for more examples of how to apply Switch Transformers to different natural language tasks.
+
+The example below demonstrates how to predict the masked token with [`Pipeline`], [`AutoModel`], and from the command line.
+
+
+
+
+```python
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="text2text-generation",
+ model="google/switch-base-8",
+ torch_dtype=torch.float16,
+ device=0
+)
+print(pipeline("The capital of France is ."))
+```
+
+
+
+
+```python
+import torch
+from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained("google/switch-base-8")
+model = AutoModelForSeq2SeqLM.from_pretrained("google/switch-base-8", device_map="auto", torch_dtype=torch.float16)
+
+input_text = "The capital of France is ."
+input_ids = tokenizer(input_text, return_tensors="pt").input_ids.to(0)
+
+outputs = model.generate(input_ids)
+print(tokenizer.decode(outputs[0]))
+```
+
+
+
+
+```bash
+echo -e "The capital of France is ." | transformers run --task text2text-generation --model google/switch-base-8 --device 0
+# [{'generated_text': 'Paris.'}]
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes/) to only quantize the weights to 8-bits.
+
+```py
+# pip install bitsandbytes
+import torch
+from transformers import AutoModelForSeq2SeqLM, AutoTokenizer, BitsAndBytesConfig
+
+tokenizer = AutoTokenizer.from_pretrained("google/switch-base-8")
+quantization_config = BitsAndBytesConfig(load_in_8bit=True)
+model = AutoModelForSeq2SeqLM.from_pretrained("google/switch-base-8", device_map="auto", quantization_config=quantization_config)
+
+input_text = "The capital of France is ."
+input_ids = tokenizer(input_text, return_tensors="pt").input_ids.to(0)
+
+outputs = model.generate(input_ids)
+print(tokenizer.decode(outputs[0]))
+```
+
+
+## SwitchTransformersConfig
+
+[[autodoc]] SwitchTransformersConfig
+
+## SwitchTransformersTop1Router
+
+[[autodoc]] SwitchTransformersTop1Router
+ - _compute_router_probabilities
+ - forward
+
+## SwitchTransformersSparseMLP
+
+[[autodoc]] SwitchTransformersSparseMLP
+ - forward
+
+## SwitchTransformersModel
+
+[[autodoc]] SwitchTransformersModel
+ - forward
+
+## SwitchTransformersForConditionalGeneration
+
+[[autodoc]] SwitchTransformersForConditionalGeneration
+ - forward
+
+## SwitchTransformersEncoderModel
+
+[[autodoc]] SwitchTransformersEncoderModel
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/t5.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/t5.md
new file mode 100644
index 0000000000000000000000000000000000000000..a910cb525d13422ab5c3dfe9ef51762e983b22aa
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/t5.md
@@ -0,0 +1,207 @@
+
+*This model was released on 2019-10-23 and added to Hugging Face Transformers on 2020-11-16.*
+
+
+
+
+
+
+
+
+
+# T5
+
+[T5](https://huggingface.co/papers/1910.10683) is a encoder-decoder transformer available in a range of sizes from 60M to 11B parameters. It is designed to handle a wide range of NLP tasks by treating them all as text-to-text problems. This eliminates the need for task-specific architectures because T5 converts every NLP task into a text generation task.
+
+To formulate every task as text generation, each task is prepended with a task-specific prefix (e.g., translate English to German: ..., summarize: ...). This enables T5 to handle tasks like translation, summarization, question answering, and more.
+
+You can find all official T5 checkpoints under the [T5](https://huggingface.co/collections/google/t5-release-65005e7c520f8d7b4d037918) collection.
+
+> [!TIP]
+> Click on the T5 models in the right sidebar for more examples of how to apply T5 to different language tasks.
+
+The example below demonstrates how to generate text with [`Pipeline`], [`AutoModel`], and how to translate with T5 from the command line.
+
+
+
+
+```py
+import torch
+from transformers import pipeline
+
+pipeline = pipeline(
+ task="text2text-generation",
+ model="google-t5/t5-base",
+ torch_dtype=torch.float16,
+ device=0
+)
+pipeline("translate English to French: The weather is nice today.")
+```
+
+
+
+
+```py
+import torch
+from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+tokenizer = AutoTokenizer.from_pretrained(
+ "google-t5/t5-base"
+ )
+model = AutoModelForSeq2SeqLM.from_pretrained(
+ "google-t5/t5-base",
+ torch_dtype=torch.float16,
+ device_map="auto"
+ )
+
+input_ids = tokenizer("translate English to French: The weather is nice today.", return_tensors="pt").to("cuda")
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```bash
+echo -e "translate English to French: The weather is nice today." | transformers run --task text2text-generation --model google-t5/t5-base --device 0
+```
+
+
+
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [torchao](../quantization/torchao) to only quantize the weights to int4.
+
+```py
+# pip install torchao
+import torch
+from transformers import TorchAoConfig, AutoModelForSeq2SeqLM, AutoTokenizer
+
+quantization_config = TorchAoConfig("int4_weight_only", group_size=128)
+model = AutoModelForSeq2SeqLM.from_pretrained(
+ "google/t5-v1_1-xl",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained("google/t5-v1_1-xl")
+input_ids = tokenizer("translate English to French: The weather is nice today.", return_tensors="pt").to("cuda")
+
+output = model.generate(**input_ids, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+## Notes
+
+- You can pad the encoder inputs on the left or right because T5 uses relative scalar embeddings.
+- T5 models need a slightly higher learning rate than the default used in [`Trainer`]. Typically, values of `1e-4` and `3e-4` work well for most tasks.
+
+## T5Config
+
+[[autodoc]] T5Config
+
+## T5Tokenizer
+
+[[autodoc]] T5Tokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## T5TokenizerFast
+
+[[autodoc]] T5TokenizerFast
+
+
+
+
+## T5Model
+
+[[autodoc]] T5Model
+ - forward
+
+## T5ForConditionalGeneration
+
+[[autodoc]] T5ForConditionalGeneration
+ - forward
+
+## T5EncoderModel
+
+[[autodoc]] T5EncoderModel
+ - forward
+
+## T5ForSequenceClassification
+
+[[autodoc]] T5ForSequenceClassification
+ - forward
+
+## T5ForTokenClassification
+
+[[autodoc]] T5ForTokenClassification
+ - forward
+
+## T5ForQuestionAnswering
+
+[[autodoc]] T5ForQuestionAnswering
+ - forward
+
+
+
+
+## TFT5Model
+
+[[autodoc]] TFT5Model
+ - call
+
+## TFT5ForConditionalGeneration
+
+[[autodoc]] TFT5ForConditionalGeneration
+ - call
+
+## TFT5EncoderModel
+
+[[autodoc]] TFT5EncoderModel
+ - call
+
+
+
+
+## FlaxT5Model
+
+[[autodoc]] FlaxT5Model
+ - __call__
+ - encode
+ - decode
+
+## FlaxT5ForConditionalGeneration
+
+[[autodoc]] FlaxT5ForConditionalGeneration
+ - __call__
+ - encode
+ - decode
+
+## FlaxT5EncoderModel
+
+[[autodoc]] FlaxT5EncoderModel
+ - __call__
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/t5gemma.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/t5gemma.md
new file mode 100644
index 0000000000000000000000000000000000000000..66d5c2a5d00556c9dde64da752bcb6e461cd2c29
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/t5gemma.md
@@ -0,0 +1,126 @@
+
+
+*This model was released on 2025-04-08 and added to Hugging Face Transformers on 2025-06-25.*
+
+
+
+
+
+
+
+
+# T5Gemma
+
+T5Gemma (aka encoder-decoder Gemma) was proposed in a [research paper](https://huggingface.co/papers/2504.06225) by Google. It is a family of encoder-decoder large language models, developed by adapting pretrained decoder-only models into encoder-decoder. T5Gemma includes pretrained and instruction-tuned variants. The architecture is based on transformer encoder-decoder design following T5, with improvements from Gemma 2: GQA, RoPE, GeGLU activation, RMSNorm, and interleaved local/global attention.
+
+T5Gemma has two groups of model sizes: 1) [Gemma 2](https://ai.google.dev/gemma/docs/core/model_card_2) sizes (2B-2B, 9B-2B, and 9B-9B), which are based on the official Gemma 2 models (2B and 9B); and 2) [T5](https://huggingface.co/papers/1910.10683) sizes (Small, Base, Large, and XL), where are pretrained under the Gemma 2 framework following T5 configuration. In addition, we also provide a model at ML size (medium large, ~2B in total), which is in-between T5 Large and T5 XL.
+
+The pretrained variants are trained with two objectives: prefix language modeling with knowledge distillation (PrefixLM) and UL2, separately. We release both variants for each model size. The instruction-turned variants was post-trained with supervised fine-tuning and reinforcement learning.
+
+> [!TIP]
+> Click on the T5Gemma models in the right sidebar for more examples of how to apply T5Gemma to different language tasks.
+
+The example below demonstrates how to chat with the model with [`Pipeline`] or the [`AutoModel`] class, and from the command line.
+
+
+
+
+
+```python
+import torch
+from transformers import pipeline
+
+pipe = pipeline(
+ "text2text-generation",
+ model="google/t5gemma-2b-2b-prefixlm-it",
+ torch_dtype=torch.bfloat16,
+ device_map="auto",
+)
+
+messages = [
+ {"role": "user", "content": "Tell me an unknown interesting biology fact about the brain."},
+]
+prompt = pipe.tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
+
+pipe(prompt, max_new_tokens=32)
+```
+
+
+
+
+```python
+# pip install accelerate
+import torch
+from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+
+tokenizer = AutoTokenizer.from_pretrained("google/t5gemma-2b-2b-prefixlm-it")
+model = AutoModelForSeq2SeqLM.from_pretrained(
+ "google/t5gemma-2b-2b-prefixlm-it",
+ device_map="auto",
+ torch_dtype=torch.bfloat16,
+)
+
+messages = [
+ {"role": "user", "content": "Tell me an unknown interesting biology fact about the brain."},
+]
+input_ids = tokenizer.apply_chat_template(messages, return_tensors="pt", return_dict=True, add_generation_prompt=True).to(model.device)
+
+outputs = model.generate(**input_ids, max_new_tokens=32)
+print(tokenizer.decode(outputs[0]))
+```
+
+
+
+
+```
+echo -e "Write me a poem about Machine Learning. Answer:" | transformers run --task text2text-generation --model google/t5gemma-2b-2b-prefixlm --device 0
+```
+
+
+
+## T5GemmaConfig
+
+[[autodoc]] T5GemmaConfig
+
+## T5GemmaModuleConfig
+
+[[autodoc]] T5GemmaModuleConfig
+
+## T5GemmaModel
+
+[[autodoc]] T5GemmaModel
+ - forward
+
+## T5GemmaEncoderModel
+
+[[autodoc]] T5GemmaEncoderModel
+ - forward
+
+## T5GemmaForConditionalGeneration
+
+[[autodoc]] T5GemmaForConditionalGeneration
+ - forward
+
+## T5GemmaForSequenceClassification
+
+[[autodoc]] T5GemmaForSequenceClassification
+ - forward
+
+## T5GemmaForTokenClassification
+
+[[autodoc]] T5GemmaForTokenClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/t5v1.1.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/t5v1.1.md
new file mode 100644
index 0000000000000000000000000000000000000000..4b4ace6768a89c00f71080fe93af099a6159158a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/t5v1.1.md
@@ -0,0 +1,79 @@
+
+*This model was released on 2020-02-12 and added to Hugging Face Transformers on 2023-06-20.*
+
+# T5v1.1
+
+
+
+
+
+
+
+## Overview
+
+T5v1.1 was released in the [google-research/text-to-text-transfer-transformer](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511)
+repository by Colin Raffel et al. It's an improved version of the original T5 model.
+This model was contributed by [patrickvonplaten](https://huggingface.co/patrickvonplaten). The original code can be
+found [here](https://github.com/google-research/text-to-text-transfer-transformer/blob/main/released_checkpoints.md#t511).
+
+## Usage tips
+
+One can directly plug in the weights of T5v1.1 into a T5 model, like so:
+
+```python
+>>> from transformers import T5ForConditionalGeneration
+
+>>> model = T5ForConditionalGeneration.from_pretrained("google/t5-v1_1-base")
+```
+
+T5 Version 1.1 includes the following improvements compared to the original T5 model:
+
+- GEGLU activation in the feed-forward hidden layer, rather than ReLU. See [this paper](https://huggingface.co/papers/2002.05202).
+
+- Dropout was turned off in pre-training (quality win). Dropout should be re-enabled during fine-tuning.
+
+- Pre-trained on C4 only without mixing in the downstream tasks.
+
+- No parameter sharing between the embedding and classifier layer.
+
+- "xl" and "xxl" replace "3B" and "11B". The model shapes are a bit different - larger `d_model` and smaller
+ `num_heads` and `d_ff`.
+
+Note: T5 Version 1.1 was only pre-trained on [C4](https://huggingface.co/datasets/c4) excluding any supervised
+training. Therefore, this model has to be fine-tuned before it is usable on a downstream task, unlike the original T5
+model. Since t5v1.1 was pre-trained unsupervisedly, there's no real advantage to using a task prefix during single-task
+fine-tuning. If you are doing multi-task fine-tuning, you should use a prefix.
+
+Google has released the following variants:
+
+- [google/t5-v1_1-small](https://huggingface.co/google/t5-v1_1-small)
+
+- [google/t5-v1_1-base](https://huggingface.co/google/t5-v1_1-base)
+
+- [google/t5-v1_1-large](https://huggingface.co/google/t5-v1_1-large)
+
+- [google/t5-v1_1-xl](https://huggingface.co/google/t5-v1_1-xl)
+
+- [google/t5-v1_1-xxl](https://huggingface.co/google/t5-v1_1-xxl).
+
+
+
+
+Refer to [T5's documentation page](t5) for all API reference, tips, code examples and notebooks.
+
+
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/table-transformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/table-transformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..b35df2aec311d07b05fd7a5a55a6d9506320f6b8
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/table-transformer.md
@@ -0,0 +1,72 @@
+
+*This model was released on 2021-09-30 and added to Hugging Face Transformers on 2022-10-18.*
+
+# Table Transformer
+
+
+
+
+
+## Overview
+
+The Table Transformer model was proposed in [PubTables-1M: Towards comprehensive table extraction from unstructured documents](https://huggingface.co/papers/2110.00061) by
+Brandon Smock, Rohith Pesala, Robin Abraham. The authors introduce a new dataset, PubTables-1M, to benchmark progress in table extraction from unstructured documents,
+as well as table structure recognition and functional analysis. The authors train 2 [DETR](detr) models, one for table detection and one for table structure recognition, dubbed Table Transformers.
+
+The abstract from the paper is the following:
+
+*Recently, significant progress has been made applying machine learning to the problem of table structure inference and extraction from unstructured documents.
+However, one of the greatest challenges remains the creation of datasets with complete, unambiguous ground truth at scale. To address this, we develop a new, more
+comprehensive dataset for table extraction, called PubTables-1M. PubTables-1M contains nearly one million tables from scientific articles, supports multiple input
+modalities, and contains detailed header and location information for table structures, making it useful for a wide variety of modeling approaches. It also addresses a significant
+source of ground truth inconsistency observed in prior datasets called oversegmentation, using a novel canonicalization procedure. We demonstrate that these improvements lead to a
+significant increase in training performance and a more reliable estimate of model performance at evaluation for table structure recognition. Further, we show that transformer-based
+object detection models trained on PubTables-1M produce excellent results for all three tasks of detection, structure recognition, and functional analysis without the need for any
+special customization for these tasks.*
+
+
+
+ Table detection and table structure recognition clarified. Taken from the original paper.
+
+The authors released 2 models, one for [table detection](https://huggingface.co/microsoft/table-transformer-detection) in
+documents, one for [table structure recognition](https://huggingface.co/microsoft/table-transformer-structure-recognition)
+(the task of recognizing the individual rows, columns etc. in a table).
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be
+found [here](https://github.com/microsoft/table-transformer).
+
+## Resources
+
+
+
+- A demo notebook for the Table Transformer can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Table%20Transformer).
+- It turns out padding of images is quite important for detection. An interesting Github thread with replies from the authors can be found [here](https://github.com/microsoft/table-transformer/issues/68).
+
+## TableTransformerConfig
+
+[[autodoc]] TableTransformerConfig
+
+## TableTransformerModel
+
+[[autodoc]] TableTransformerModel
+ - forward
+
+## TableTransformerForObjectDetection
+
+[[autodoc]] TableTransformerForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/tapas.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/tapas.md
new file mode 100644
index 0000000000000000000000000000000000000000..744be7d6882031675ed76c44ecc690aa67651005
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/tapas.md
@@ -0,0 +1,640 @@
+
+*This model was released on 2020-04-05 and added to Hugging Face Transformers on 2020-12-15.*
+
+# TAPAS
+
+
+
+
+
+
+## Overview
+
+The TAPAS model was proposed in [TAPAS: Weakly Supervised Table Parsing via Pre-training](https://huggingface.co/papers/2004.02349)
+by Jonathan Herzig, Paweł Krzysztof Nowak, Thomas Müller, Francesco Piccinno and Julian Martin Eisenschlos. It's a BERT-based model specifically
+designed (and pre-trained) for answering questions about tabular data. Compared to BERT, TAPAS uses relative position embeddings and has 7
+token types that encode tabular structure. TAPAS is pre-trained on the masked language modeling (MLM) objective on a large dataset comprising
+millions of tables from English Wikipedia and corresponding texts.
+
+For question answering, TAPAS has 2 heads on top: a cell selection head and an aggregation head, for (optionally) performing aggregations (such as counting or summing) among selected cells. TAPAS has been fine-tuned on several datasets:
+- [SQA](https://www.microsoft.com/en-us/download/details.aspx?id=54253) (Sequential Question Answering by Microsoft)
+- [WTQ](https://github.com/ppasupat/WikiTableQuestions) (Wiki Table Questions by Stanford University)
+- [WikiSQL](https://github.com/salesforce/WikiSQL) (by Salesforce).
+
+It achieves state-of-the-art on both SQA and WTQ, while having comparable performance to SOTA on WikiSQL, with a much simpler architecture.
+
+The abstract from the paper is the following:
+
+*Answering natural language questions over tables is usually seen as a semantic parsing task. To alleviate the collection cost of full logical forms, one popular approach focuses on weak supervision consisting of denotations instead of logical forms. However, training semantic parsers from weak supervision poses difficulties, and in addition, the generated logical forms are only used as an intermediate step prior to retrieving the denotation. In this paper, we present TAPAS, an approach to question answering over tables without generating logical forms. TAPAS trains from weak supervision, and predicts the denotation by selecting table cells and optionally applying a corresponding aggregation operator to such selection. TAPAS extends BERT's architecture to encode tables as input, initializes from an effective joint pre-training of text segments and tables crawled from Wikipedia, and is trained end-to-end. We experiment with three different semantic parsing datasets, and find that TAPAS outperforms or rivals semantic parsing models by improving state-of-the-art accuracy on SQA from 55.1 to 67.2 and performing on par with the state-of-the-art on WIKISQL and WIKITQ, but with a simpler model architecture. We additionally find that transfer learning, which is trivial in our setting, from WIKISQL to WIKITQ, yields 48.7 accuracy, 4.2 points above the state-of-the-art.*
+
+In addition, the authors have further pre-trained TAPAS to recognize **table entailment**, by creating a balanced dataset of millions of automatically created training examples which are learned in an intermediate step prior to fine-tuning. The authors of TAPAS call this further pre-training intermediate pre-training (since TAPAS is first pre-trained on MLM, and then on another dataset). They found that intermediate pre-training further improves performance on SQA, achieving a new state-of-the-art as well as state-of-the-art on [TabFact](https://github.com/wenhuchen/Table-Fact-Checking), a large-scale dataset with 16k Wikipedia tables for table entailment (a binary classification task). For more details, see their follow-up paper: [Understanding tables with intermediate pre-training](https://www.aclweb.org/anthology/2020.findings-emnlp.27/) by Julian Martin Eisenschlos, Syrine Krichene and Thomas Müller.
+
+
+
+ TAPAS architecture. Taken from the original blog post.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The Tensorflow version of this model was contributed by [kamalkraj](https://huggingface.co/kamalkraj). The original code can be found [here](https://github.com/google-research/tapas).
+
+## Usage tips
+
+- TAPAS is a model that uses relative position embeddings by default (restarting the position embeddings at every cell of the table). Note that this is something that was added after the publication of the original TAPAS paper. According to the authors, this usually results in a slightly better performance, and allows you to encode longer sequences without running out of embeddings. This is reflected in the `reset_position_index_per_cell` parameter of [`TapasConfig`], which is set to `True` by default. The default versions of the models available on the [hub](https://huggingface.co/models?search=tapas) all use relative position embeddings. You can still use the ones with absolute position embeddings by passing in an additional argument `revision="no_reset"` when calling the `from_pretrained()` method. Note that it's usually advised to pad the inputs on the right rather than the left.
+- TAPAS is based on BERT, so `TAPAS-base` for example corresponds to a `BERT-base` architecture. Of course, `TAPAS-large` will result in the best performance (the results reported in the paper are from `TAPAS-large`). Results of the various sized models are shown on the [original GitHub repository](https://github.com/google-research/tapas).
+- TAPAS has checkpoints fine-tuned on SQA, which are capable of answering questions related to a table in a conversational set-up. This means that you can ask follow-up questions such as "what is his age?" related to the previous question. Note that the forward pass of TAPAS is a bit different in case of a conversational set-up: in that case, you have to feed every table-question pair one by one to the model, such that the `prev_labels` token type ids can be overwritten by the predicted `labels` of the model to the previous question. See "Usage" section for more info.
+- TAPAS is similar to BERT and therefore relies on the masked language modeling (MLM) objective. It is therefore efficient at predicting masked tokens and at NLU in general, but is not optimal for text generation. Models trained with a causal language modeling (CLM) objective are better in that regard. Note that TAPAS can be used as an encoder in the EncoderDecoderModel framework, to combine it with an autoregressive text decoder such as GPT-2.
+
+## Usage: fine-tuning
+
+Here we explain how you can fine-tune [`TapasForQuestionAnswering`] on your own dataset.
+
+**STEP 1: Choose one of the 3 ways in which you can use TAPAS - or experiment**
+
+Basically, there are 3 different ways in which one can fine-tune [`TapasForQuestionAnswering`], corresponding to the different datasets on which Tapas was fine-tuned:
+
+1. SQA: if you're interested in asking follow-up questions related to a table, in a conversational set-up. For example if you first ask "what's the name of the first actor?" then you can ask a follow-up question such as "how old is he?". Here, questions do not involve any aggregation (all questions are cell selection questions).
+2. WTQ: if you're not interested in asking questions in a conversational set-up, but rather just asking questions related to a table, which might involve aggregation, such as counting a number of rows, summing up cell values or averaging cell values. You can then for example ask "what's the total number of goals Cristiano Ronaldo made in his career?". This case is also called **weak supervision**, since the model itself must learn the appropriate aggregation operator (SUM/COUNT/AVERAGE/NONE) given only the answer to the question as supervision.
+3. WikiSQL-supervised: this dataset is based on WikiSQL with the model being given the ground truth aggregation operator during training. This is also called **strong supervision**. Here, learning the appropriate aggregation operator is much easier.
+
+To summarize:
+
+| **Task** | **Example dataset** | **Description** |
+|-------------------------------------|---------------------|---------------------------------------------------------------------------------------------------------|
+| Conversational | SQA | Conversational, only cell selection questions |
+| Weak supervision for aggregation | WTQ | Questions might involve aggregation, and the model must learn this given only the answer as supervision |
+| Strong supervision for aggregation | WikiSQL-supervised | Questions might involve aggregation, and the model must learn this given the gold aggregation operator |
+
+
+
+Initializing a model with a pre-trained base and randomly initialized classification heads from the hub can be done as shown below.
+
+```py
+>>> from transformers import TapasConfig, TapasForQuestionAnswering
+
+>>> # for example, the base sized model with default SQA configuration
+>>> model = TapasForQuestionAnswering.from_pretrained("google/tapas-base")
+
+>>> # or, the base sized model with WTQ configuration
+>>> config = TapasConfig.from_pretrained("google/tapas-base-finetuned-wtq")
+>>> model = TapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+
+>>> # or, the base sized model with WikiSQL configuration
+>>> config = TapasConfig("google-base-finetuned-wikisql-supervised")
+>>> model = TapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+```
+
+Of course, you don't necessarily have to follow one of these three ways in which TAPAS was fine-tuned. You can also experiment by defining any hyperparameters you want when initializing [`TapasConfig`], and then create a [`TapasForQuestionAnswering`] based on that configuration. For example, if you have a dataset that has both conversational questions and questions that might involve aggregation, then you can do it this way. Here's an example:
+
+```py
+>>> from transformers import TapasConfig, TapasForQuestionAnswering
+
+>>> # you can initialize the classification heads any way you want (see docs of TapasConfig)
+>>> config = TapasConfig(num_aggregation_labels=3, average_logits_per_cell=True)
+>>> # initializing the pre-trained base sized model with our custom classification heads
+>>> model = TapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+```
+
+
+Initializing a model with a pre-trained base and randomly initialized classification heads from the hub can be done as shown below. Be sure to have installed the [tensorflow_probability](https://github.com/tensorflow/probability) dependency:
+
+```py
+>>> from transformers import TapasConfig, TFTapasForQuestionAnswering
+
+>>> # for example, the base sized model with default SQA configuration
+>>> model = TFTapasForQuestionAnswering.from_pretrained("google/tapas-base")
+
+>>> # or, the base sized model with WTQ configuration
+>>> config = TapasConfig.from_pretrained("google/tapas-base-finetuned-wtq")
+>>> model = TFTapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+
+>>> # or, the base sized model with WikiSQL configuration
+>>> config = TapasConfig("google-base-finetuned-wikisql-supervised")
+>>> model = TFTapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+```
+
+Of course, you don't necessarily have to follow one of these three ways in which TAPAS was fine-tuned. You can also experiment by defining any hyperparameters you want when initializing [`TapasConfig`], and then create a [`TFTapasForQuestionAnswering`] based on that configuration. For example, if you have a dataset that has both conversational questions and questions that might involve aggregation, then you can do it this way. Here's an example:
+
+```py
+>>> from transformers import TapasConfig, TFTapasForQuestionAnswering
+
+>>> # you can initialize the classification heads any way you want (see docs of TapasConfig)
+>>> config = TapasConfig(num_aggregation_labels=3, average_logits_per_cell=True)
+>>> # initializing the pre-trained base sized model with our custom classification heads
+>>> model = TFTapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+```
+
+
+
+What you can also do is start from an already fine-tuned checkpoint. A note here is that the already fine-tuned checkpoint on WTQ has some issues due to the L2-loss which is somewhat brittle. See [here](https://github.com/google-research/tapas/issues/91#issuecomment-735719340) for more info.
+
+For a list of all pre-trained and fine-tuned TAPAS checkpoints available on HuggingFace's hub, see [here](https://huggingface.co/models?search=tapas).
+
+**STEP 2: Prepare your data in the SQA format**
+
+Second, no matter what you picked above, you should prepare your dataset in the [SQA](https://www.microsoft.com/en-us/download/details.aspx?id=54253) format. This format is a TSV/CSV file with the following columns:
+
+- `id`: optional, id of the table-question pair, for bookkeeping purposes.
+- `annotator`: optional, id of the person who annotated the table-question pair, for bookkeeping purposes.
+- `position`: integer indicating if the question is the first, second, third,... related to the table. Only required in case of conversational setup (SQA). You don't need this column in case you're going for WTQ/WikiSQL-supervised.
+- `question`: string
+- `table_file`: string, name of a csv file containing the tabular data
+- `answer_coordinates`: list of one or more tuples (each tuple being a cell coordinate, i.e. row, column pair that is part of the answer)
+- `answer_text`: list of one or more strings (each string being a cell value that is part of the answer)
+- `aggregation_label`: index of the aggregation operator. Only required in case of strong supervision for aggregation (the WikiSQL-supervised case)
+- `float_answer`: the float answer to the question, if there is one (np.nan if there isn't). Only required in case of weak supervision for aggregation (such as WTQ and WikiSQL)
+
+The tables themselves should be present in a folder, each table being a separate csv file. Note that the authors of the TAPAS algorithm used conversion scripts with some automated logic to convert the other datasets (WTQ, WikiSQL) into the SQA format. The author explains this [here](https://github.com/google-research/tapas/issues/50#issuecomment-705465960). A conversion of this script that works with HuggingFace's implementation can be found [here](https://github.com/NielsRogge/tapas_utils). Interestingly, these conversion scripts are not perfect (the `answer_coordinates` and `float_answer` fields are populated based on the `answer_text`), meaning that WTQ and WikiSQL results could actually be improved.
+
+**STEP 3: Convert your data into tensors using TapasTokenizer**
+
+
+
+Third, given that you've prepared your data in this TSV/CSV format (and corresponding CSV files containing the tabular data), you can then use [`TapasTokenizer`] to convert table-question pairs into `input_ids`, `attention_mask`, `token_type_ids` and so on. Again, based on which of the three cases you picked above, [`TapasForQuestionAnswering`] requires different
+inputs to be fine-tuned:
+
+| **Task** | **Required inputs** |
+|------------------------------------|---------------------------------------------------------------------------------------------------------------------|
+| Conversational | `input_ids`, `attention_mask`, `token_type_ids`, `labels` |
+| Weak supervision for aggregation | `input_ids`, `attention_mask`, `token_type_ids`, `labels`, `numeric_values`, `numeric_values_scale`, `float_answer` |
+| Strong supervision for aggregation | `input ids`, `attention mask`, `token type ids`, `labels`, `aggregation_labels` |
+
+[`TapasTokenizer`] creates the `labels`, `numeric_values` and `numeric_values_scale` based on the `answer_coordinates` and `answer_text` columns of the TSV file. The `float_answer` and `aggregation_labels` are already in the TSV file of step 2. Here's an example:
+
+```py
+>>> from transformers import TapasTokenizer
+>>> import pandas as pd
+
+>>> model_name = "google/tapas-base"
+>>> tokenizer = TapasTokenizer.from_pretrained(model_name)
+
+>>> data = {"Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"], "Number of movies": ["87", "53", "69"]}
+>>> queries = [
+... "What is the name of the first actor?",
+... "How many movies has George Clooney played in?",
+... "What is the total number of movies?",
+... ]
+>>> answer_coordinates = [[(0, 0)], [(2, 1)], [(0, 1), (1, 1), (2, 1)]]
+>>> answer_text = [["Brad Pitt"], ["69"], ["209"]]
+>>> table = pd.DataFrame.from_dict(data)
+>>> inputs = tokenizer(
+... table=table,
+... queries=queries,
+... answer_coordinates=answer_coordinates,
+... answer_text=answer_text,
+... padding="max_length",
+... return_tensors="pt",
+... )
+>>> inputs
+{'input_ids': tensor([[ ... ]]), 'attention_mask': tensor([[...]]), 'token_type_ids': tensor([[[...]]]),
+'numeric_values': tensor([[ ... ]]), 'numeric_values_scale: tensor([[ ... ]]), labels: tensor([[ ... ]])}
+```
+
+Note that [`TapasTokenizer`] expects the data of the table to be **text-only**. You can use `.astype(str)` on a dataframe to turn it into text-only data.
+Of course, this only shows how to encode a single training example. It is advised to create a dataloader to iterate over batches:
+
+```py
+>>> import torch
+>>> import pandas as pd
+
+>>> tsv_path = "your_path_to_the_tsv_file"
+>>> table_csv_path = "your_path_to_a_directory_containing_all_csv_files"
+
+
+>>> class TableDataset(torch.utils.data.Dataset):
+... def __init__(self, data, tokenizer):
+... self.data = data
+... self.tokenizer = tokenizer
+
+... def __getitem__(self, idx):
+... item = data.iloc[idx]
+... table = pd.read_csv(table_csv_path + item.table_file).astype(
+... str
+... ) # be sure to make your table data text only
+... encoding = self.tokenizer(
+... table=table,
+... queries=item.question,
+... answer_coordinates=item.answer_coordinates,
+... answer_text=item.answer_text,
+... truncation=True,
+... padding="max_length",
+... return_tensors="pt",
+... )
+... # remove the batch dimension which the tokenizer adds by default
+... encoding = {key: val.squeeze(0) for key, val in encoding.items()}
+... # add the float_answer which is also required (weak supervision for aggregation case)
+... encoding["float_answer"] = torch.tensor(item.float_answer)
+... return encoding
+
+... def __len__(self):
+... return len(self.data)
+
+
+>>> data = pd.read_csv(tsv_path, sep="\t")
+>>> train_dataset = TableDataset(data, tokenizer)
+>>> train_dataloader = torch.utils.data.DataLoader(train_dataset, batch_size=32)
+```
+
+
+Third, given that you've prepared your data in this TSV/CSV format (and corresponding CSV files containing the tabular data), you can then use [`TapasTokenizer`] to convert table-question pairs into `input_ids`, `attention_mask`, `token_type_ids` and so on. Again, based on which of the three cases you picked above, [`TFTapasForQuestionAnswering`] requires different
+inputs to be fine-tuned:
+
+| **Task** | **Required inputs** |
+|------------------------------------|---------------------------------------------------------------------------------------------------------------------|
+| Conversational | `input_ids`, `attention_mask`, `token_type_ids`, `labels` |
+| Weak supervision for aggregation | `input_ids`, `attention_mask`, `token_type_ids`, `labels`, `numeric_values`, `numeric_values_scale`, `float_answer` |
+| Strong supervision for aggregation | `input ids`, `attention mask`, `token type ids`, `labels`, `aggregation_labels` |
+
+[`TapasTokenizer`] creates the `labels`, `numeric_values` and `numeric_values_scale` based on the `answer_coordinates` and `answer_text` columns of the TSV file. The `float_answer` and `aggregation_labels` are already in the TSV file of step 2. Here's an example:
+
+```py
+>>> from transformers import TapasTokenizer
+>>> import pandas as pd
+
+>>> model_name = "google/tapas-base"
+>>> tokenizer = TapasTokenizer.from_pretrained(model_name)
+
+>>> data = {"Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"], "Number of movies": ["87", "53", "69"]}
+>>> queries = [
+... "What is the name of the first actor?",
+... "How many movies has George Clooney played in?",
+... "What is the total number of movies?",
+... ]
+>>> answer_coordinates = [[(0, 0)], [(2, 1)], [(0, 1), (1, 1), (2, 1)]]
+>>> answer_text = [["Brad Pitt"], ["69"], ["209"]]
+>>> table = pd.DataFrame.from_dict(data)
+>>> inputs = tokenizer(
+... table=table,
+... queries=queries,
+... answer_coordinates=answer_coordinates,
+... answer_text=answer_text,
+... padding="max_length",
+... return_tensors="tf",
+... )
+>>> inputs
+{'input_ids': tensor([[ ... ]]), 'attention_mask': tensor([[...]]), 'token_type_ids': tensor([[[...]]]),
+'numeric_values': tensor([[ ... ]]), 'numeric_values_scale: tensor([[ ... ]]), labels: tensor([[ ... ]])}
+```
+
+Note that [`TapasTokenizer`] expects the data of the table to be **text-only**. You can use `.astype(str)` on a dataframe to turn it into text-only data.
+Of course, this only shows how to encode a single training example. It is advised to create a dataloader to iterate over batches:
+
+```py
+>>> import tensorflow as tf
+>>> import pandas as pd
+
+>>> tsv_path = "your_path_to_the_tsv_file"
+>>> table_csv_path = "your_path_to_a_directory_containing_all_csv_files"
+
+
+>>> class TableDataset:
+... def __init__(self, data, tokenizer):
+... self.data = data
+... self.tokenizer = tokenizer
+
+... def __iter__(self):
+... for idx in range(self.__len__()):
+... item = self.data.iloc[idx]
+... table = pd.read_csv(table_csv_path + item.table_file).astype(
+... str
+... ) # be sure to make your table data text only
+... encoding = self.tokenizer(
+... table=table,
+... queries=item.question,
+... answer_coordinates=item.answer_coordinates,
+... answer_text=item.answer_text,
+... truncation=True,
+... padding="max_length",
+... return_tensors="tf",
+... )
+... # remove the batch dimension which the tokenizer adds by default
+... encoding = {key: tf.squeeze(val, 0) for key, val in encoding.items()}
+... # add the float_answer which is also required (weak supervision for aggregation case)
+... encoding["float_answer"] = tf.convert_to_tensor(item.float_answer, dtype=tf.float32)
+... yield encoding["input_ids"], encoding["attention_mask"], encoding["numeric_values"], encoding[
+... "numeric_values_scale"
+... ], encoding["token_type_ids"], encoding["labels"], encoding["float_answer"]
+
+... def __len__(self):
+... return len(self.data)
+
+
+>>> data = pd.read_csv(tsv_path, sep="\t")
+>>> train_dataset = TableDataset(data, tokenizer)
+>>> output_signature = (
+... tf.TensorSpec(shape=(512,), dtype=tf.int32),
+... tf.TensorSpec(shape=(512,), dtype=tf.int32),
+... tf.TensorSpec(shape=(512,), dtype=tf.float32),
+... tf.TensorSpec(shape=(512,), dtype=tf.float32),
+... tf.TensorSpec(shape=(512, 7), dtype=tf.int32),
+... tf.TensorSpec(shape=(512,), dtype=tf.int32),
+... tf.TensorSpec(shape=(512,), dtype=tf.float32),
+... )
+>>> train_dataloader = tf.data.Dataset.from_generator(train_dataset, output_signature=output_signature).batch(32)
+```
+
+
+
+Note that here, we encode each table-question pair independently. This is fine as long as your dataset is **not conversational**. In case your dataset involves conversational questions (such as in SQA), then you should first group together the `queries`, `answer_coordinates` and `answer_text` per table (in the order of their `position`
+index) and batch encode each table with its questions. This will make sure that the `prev_labels` token types (see docs of [`TapasTokenizer`]) are set correctly. See [this notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb) for more info. See [this notebook](https://github.com/kamalkraj/Tapas-Tutorial/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb) for more info regarding using the TensorFlow model.
+
+**STEP 4: Train (fine-tune) the model
+
+
+
+You can then fine-tune [`TapasForQuestionAnswering`] as follows (shown here for the weak supervision for aggregation case):
+
+```py
+>>> from transformers import TapasConfig, TapasForQuestionAnswering, AdamW
+
+>>> # this is the default WTQ configuration
+>>> config = TapasConfig(
+... num_aggregation_labels=4,
+... use_answer_as_supervision=True,
+... answer_loss_cutoff=0.664694,
+... cell_selection_preference=0.207951,
+... huber_loss_delta=0.121194,
+... init_cell_selection_weights_to_zero=True,
+... select_one_column=True,
+... allow_empty_column_selection=False,
+... temperature=0.0352513,
+... )
+>>> model = TapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+
+>>> optimizer = AdamW(model.parameters(), lr=5e-5)
+
+>>> model.train()
+>>> for epoch in range(2): # loop over the dataset multiple times
+... for batch in train_dataloader:
+... # get the inputs;
+... input_ids = batch["input_ids"]
+... attention_mask = batch["attention_mask"]
+... token_type_ids = batch["token_type_ids"]
+... labels = batch["labels"]
+... numeric_values = batch["numeric_values"]
+... numeric_values_scale = batch["numeric_values_scale"]
+... float_answer = batch["float_answer"]
+
+... # zero the parameter gradients
+... optimizer.zero_grad()
+
+... # forward + backward + optimize
+... outputs = model(
+... input_ids=input_ids,
+... attention_mask=attention_mask,
+... token_type_ids=token_type_ids,
+... labels=labels,
+... numeric_values=numeric_values,
+... numeric_values_scale=numeric_values_scale,
+... float_answer=float_answer,
+... )
+... loss = outputs.loss
+... loss.backward()
+... optimizer.step()
+```
+
+
+You can then fine-tune [`TFTapasForQuestionAnswering`] as follows (shown here for the weak supervision for aggregation case):
+
+```py
+>>> import tensorflow as tf
+>>> from transformers import TapasConfig, TFTapasForQuestionAnswering
+
+>>> # this is the default WTQ configuration
+>>> config = TapasConfig(
+... num_aggregation_labels=4,
+... use_answer_as_supervision=True,
+... answer_loss_cutoff=0.664694,
+... cell_selection_preference=0.207951,
+... huber_loss_delta=0.121194,
+... init_cell_selection_weights_to_zero=True,
+... select_one_column=True,
+... allow_empty_column_selection=False,
+... temperature=0.0352513,
+... )
+>>> model = TFTapasForQuestionAnswering.from_pretrained("google/tapas-base", config=config)
+
+>>> optimizer = tf.keras.optimizers.Adam(learning_rate=5e-5)
+
+>>> for epoch in range(2): # loop over the dataset multiple times
+... for batch in train_dataloader:
+... # get the inputs;
+... input_ids = batch[0]
+... attention_mask = batch[1]
+... token_type_ids = batch[4]
+... labels = batch[-1]
+... numeric_values = batch[2]
+... numeric_values_scale = batch[3]
+... float_answer = batch[6]
+
+... # forward + backward + optimize
+... with tf.GradientTape() as tape:
+... outputs = model(
+... input_ids=input_ids,
+... attention_mask=attention_mask,
+... token_type_ids=token_type_ids,
+... labels=labels,
+... numeric_values=numeric_values,
+... numeric_values_scale=numeric_values_scale,
+... float_answer=float_answer,
+... )
+... grads = tape.gradient(outputs.loss, model.trainable_weights)
+... optimizer.apply_gradients(zip(grads, model.trainable_weights))
+```
+
+
+
+## Usage: inference
+
+
+
+Here we explain how you can use [`TapasForQuestionAnswering`] or [`TFTapasForQuestionAnswering`] for inference (i.e. making predictions on new data). For inference, only `input_ids`, `attention_mask` and `token_type_ids` (which you can obtain using [`TapasTokenizer`]) have to be provided to the model to obtain the logits. Next, you can use the handy [`~models.tapas.tokenization_tapas.convert_logits_to_predictions`] method to convert these into predicted coordinates and optional aggregation indices.
+
+However, note that inference is **different** depending on whether or not the setup is conversational. In a non-conversational set-up, inference can be done in parallel on all table-question pairs of a batch. Here's an example of that:
+
+```py
+>>> from transformers import TapasTokenizer, TapasForQuestionAnswering
+>>> import pandas as pd
+
+>>> model_name = "google/tapas-base-finetuned-wtq"
+>>> model = TapasForQuestionAnswering.from_pretrained(model_name)
+>>> tokenizer = TapasTokenizer.from_pretrained(model_name)
+
+>>> data = {"Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"], "Number of movies": ["87", "53", "69"]}
+>>> queries = [
+... "What is the name of the first actor?",
+... "How many movies has George Clooney played in?",
+... "What is the total number of movies?",
+... ]
+>>> table = pd.DataFrame.from_dict(data)
+>>> inputs = tokenizer(table=table, queries=queries, padding="max_length", return_tensors="pt")
+>>> outputs = model(**inputs)
+>>> predicted_answer_coordinates, predicted_aggregation_indices = tokenizer.convert_logits_to_predictions(
+... inputs, outputs.logits.detach(), outputs.logits_aggregation.detach()
+... )
+
+>>> # let's print out the results:
+>>> id2aggregation = {0: "NONE", 1: "SUM", 2: "AVERAGE", 3: "COUNT"}
+>>> aggregation_predictions_string = [id2aggregation[x] for x in predicted_aggregation_indices]
+
+>>> answers = []
+>>> for coordinates in predicted_answer_coordinates:
+... if len(coordinates) == 1:
+... # only a single cell:
+... answers.append(table.iat[coordinates[0]])
+... else:
+... # multiple cells
+... cell_values = []
+... for coordinate in coordinates:
+... cell_values.append(table.iat[coordinate])
+... answers.append(", ".join(cell_values))
+
+>>> display(table)
+>>> print("")
+>>> for query, answer, predicted_agg in zip(queries, answers, aggregation_predictions_string):
+... print(query)
+... if predicted_agg == "NONE":
+... print("Predicted answer: " + answer)
+... else:
+... print("Predicted answer: " + predicted_agg + " > " + answer)
+What is the name of the first actor?
+Predicted answer: Brad Pitt
+How many movies has George Clooney played in?
+Predicted answer: COUNT > 69
+What is the total number of movies?
+Predicted answer: SUM > 87, 53, 69
+```
+
+
+Here we explain how you can use [`TFTapasForQuestionAnswering`] for inference (i.e. making predictions on new data). For inference, only `input_ids`, `attention_mask` and `token_type_ids` (which you can obtain using [`TapasTokenizer`]) have to be provided to the model to obtain the logits. Next, you can use the handy [`~models.tapas.tokenization_tapas.convert_logits_to_predictions`] method to convert these into predicted coordinates and optional aggregation indices.
+
+However, note that inference is **different** depending on whether or not the setup is conversational. In a non-conversational set-up, inference can be done in parallel on all table-question pairs of a batch. Here's an example of that:
+
+```py
+>>> from transformers import TapasTokenizer, TFTapasForQuestionAnswering
+>>> import pandas as pd
+
+>>> model_name = "google/tapas-base-finetuned-wtq"
+>>> model = TFTapasForQuestionAnswering.from_pretrained(model_name)
+>>> tokenizer = TapasTokenizer.from_pretrained(model_name)
+
+>>> data = {"Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"], "Number of movies": ["87", "53", "69"]}
+>>> queries = [
+... "What is the name of the first actor?",
+... "How many movies has George Clooney played in?",
+... "What is the total number of movies?",
+... ]
+>>> table = pd.DataFrame.from_dict(data)
+>>> inputs = tokenizer(table=table, queries=queries, padding="max_length", return_tensors="tf")
+>>> outputs = model(**inputs)
+>>> predicted_answer_coordinates, predicted_aggregation_indices = tokenizer.convert_logits_to_predictions(
+... inputs, outputs.logits, outputs.logits_aggregation
+... )
+
+>>> # let's print out the results:
+>>> id2aggregation = {0: "NONE", 1: "SUM", 2: "AVERAGE", 3: "COUNT"}
+>>> aggregation_predictions_string = [id2aggregation[x] for x in predicted_aggregation_indices]
+
+>>> answers = []
+>>> for coordinates in predicted_answer_coordinates:
+... if len(coordinates) == 1:
+... # only a single cell:
+... answers.append(table.iat[coordinates[0]])
+... else:
+... # multiple cells
+... cell_values = []
+... for coordinate in coordinates:
+... cell_values.append(table.iat[coordinate])
+... answers.append(", ".join(cell_values))
+
+>>> display(table)
+>>> print("")
+>>> for query, answer, predicted_agg in zip(queries, answers, aggregation_predictions_string):
+... print(query)
+... if predicted_agg == "NONE":
+... print("Predicted answer: " + answer)
+... else:
+... print("Predicted answer: " + predicted_agg + " > " + answer)
+What is the name of the first actor?
+Predicted answer: Brad Pitt
+How many movies has George Clooney played in?
+Predicted answer: COUNT > 69
+What is the total number of movies?
+Predicted answer: SUM > 87, 53, 69
+```
+
+
+
+In case of a conversational set-up, then each table-question pair must be provided **sequentially** to the model, such that the `prev_labels` token types can be overwritten by the predicted `labels` of the previous table-question pair. Again, more info can be found in [this notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb) (for PyTorch) and [this notebook](https://github.com/kamalkraj/Tapas-Tutorial/blob/master/TAPAS/Fine_tuning_TapasForQuestionAnswering_on_SQA.ipynb) (for TensorFlow).
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Masked language modeling task guide](../tasks/masked_language_modeling)
+
+## TAPAS specific outputs
+[[autodoc]] models.tapas.modeling_tapas.TableQuestionAnsweringOutput
+
+## TapasConfig
+[[autodoc]] TapasConfig
+
+## TapasTokenizer
+[[autodoc]] TapasTokenizer
+ - __call__
+ - convert_logits_to_predictions
+ - save_vocabulary
+
+
+
+
+## TapasModel
+[[autodoc]] TapasModel
+ - forward
+
+## TapasForMaskedLM
+[[autodoc]] TapasForMaskedLM
+ - forward
+
+## TapasForSequenceClassification
+[[autodoc]] TapasForSequenceClassification
+ - forward
+
+## TapasForQuestionAnswering
+[[autodoc]] TapasForQuestionAnswering
+ - forward
+
+
+
+
+## TFTapasModel
+[[autodoc]] TFTapasModel
+ - call
+
+## TFTapasForMaskedLM
+[[autodoc]] TFTapasForMaskedLM
+ - call
+
+## TFTapasForSequenceClassification
+[[autodoc]] TFTapasForSequenceClassification
+ - call
+
+## TFTapasForQuestionAnswering
+[[autodoc]] TFTapasForQuestionAnswering
+ - call
+
+
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/tapex.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/tapex.md
new file mode 100644
index 0000000000000000000000000000000000000000..ed9a64d96a1773264bce8ed3bcdef1410dc5ca67
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/tapex.md
@@ -0,0 +1,157 @@
+
+*This model was released on 2021-07-16 and added to Hugging Face Transformers on 2023-06-20.*
+
+# TAPEX
+
+
+
+
+
+
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.30.0.
+You can do so by running the following command: `pip install -U transformers==4.30.0`.
+
+
+
+## Overview
+
+The TAPEX model was proposed in [TAPEX: Table Pre-training via Learning a Neural SQL Executor](https://huggingface.co/papers/2107.07653) by Qian Liu,
+Bei Chen, Jiaqi Guo, Morteza Ziyadi, Zeqi Lin, Weizhu Chen, Jian-Guang Lou. TAPEX pre-trains a BART model to solve synthetic SQL queries, after
+which it can be fine-tuned to answer natural language questions related to tabular data, as well as performing table fact checking.
+
+TAPEX has been fine-tuned on several datasets:
+- [SQA](https://www.microsoft.com/en-us/download/details.aspx?id=54253) (Sequential Question Answering by Microsoft)
+- [WTQ](https://github.com/ppasupat/WikiTableQuestions) (Wiki Table Questions by Stanford University)
+- [WikiSQL](https://github.com/salesforce/WikiSQL) (by Salesforce)
+- [TabFact](https://tabfact.github.io/) (by USCB NLP Lab).
+
+The abstract from the paper is the following:
+
+*Recent progress in language model pre-training has achieved a great success via leveraging large-scale unstructured textual data. However, it is
+still a challenge to apply pre-training on structured tabular data due to the absence of large-scale high-quality tabular data. In this paper, we
+propose TAPEX to show that table pre-training can be achieved by learning a neural SQL executor over a synthetic corpus, which is obtained by automatically
+synthesizing executable SQL queries and their execution outputs. TAPEX addresses the data scarcity challenge via guiding the language model to mimic a SQL
+executor on the diverse, large-scale and high-quality synthetic corpus. We evaluate TAPEX on four benchmark datasets. Experimental results demonstrate that
+TAPEX outperforms previous table pre-training approaches by a large margin and achieves new state-of-the-art results on all of them. This includes improvements
+on the weakly-supervised WikiSQL denotation accuracy to 89.5% (+2.3%), the WikiTableQuestions denotation accuracy to 57.5% (+4.8%), the SQA denotation accuracy
+to 74.5% (+3.5%), and the TabFact accuracy to 84.2% (+3.2%). To our knowledge, this is the first work to exploit table pre-training via synthetic executable programs
+and to achieve new state-of-the-art results on various downstream tasks.*
+
+## Usage tips
+
+- TAPEX is a generative (seq2seq) model. One can directly plug in the weights of TAPEX into a BART model.
+- TAPEX has checkpoints on the hub that are either pre-trained only, or fine-tuned on WTQ, SQA, WikiSQL and TabFact.
+- Sentences + tables are presented to the model as `sentence + " " + linearized table`. The linearized table has the following format:
+ `col: col1 | col2 | col 3 row 1 : val1 | val2 | val3 row 2 : ...`.
+- TAPEX has its own tokenizer, that allows to prepare all data for the model easily. One can pass Pandas DataFrames and strings to the tokenizer,
+ and it will automatically create the `input_ids` and `attention_mask` (as shown in the usage examples below).
+
+### Usage: inference
+
+Below, we illustrate how to use TAPEX for table question answering. As one can see, one can directly plug in the weights of TAPEX into a BART model.
+We use the [Auto API](auto), which will automatically instantiate the appropriate tokenizer ([`TapexTokenizer`]) and model ([`BartForConditionalGeneration`]) for us,
+based on the configuration file of the checkpoint on the hub.
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSeq2SeqLM
+>>> import pandas as pd
+
+>>> tokenizer = AutoTokenizer.from_pretrained("microsoft/tapex-large-finetuned-wtq")
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("microsoft/tapex-large-finetuned-wtq")
+
+>>> # prepare table + question
+>>> data = {"Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"], "Number of movies": ["87", "53", "69"]}
+>>> table = pd.DataFrame.from_dict(data)
+>>> question = "how many movies does Leonardo Di Caprio have?"
+
+>>> encoding = tokenizer(table, question, return_tensors="pt")
+
+>>> # let the model generate an answer autoregressively
+>>> outputs = model.generate(**encoding)
+
+>>> # decode back to text
+>>> predicted_answer = tokenizer.batch_decode(outputs, skip_special_tokens=True)[0]
+>>> print(predicted_answer)
+53
+```
+
+Note that [`TapexTokenizer`] also supports batched inference. Hence, one can provide a batch of different tables/questions, or a batch of a single table
+and multiple questions, or a batch of a single query and multiple tables. Let's illustrate this:
+
+```python
+>>> # prepare table + question
+>>> data = {"Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"], "Number of movies": ["87", "53", "69"]}
+>>> table = pd.DataFrame.from_dict(data)
+>>> questions = [
+... "how many movies does Leonardo Di Caprio have?",
+... "which actor has 69 movies?",
+... "what's the first name of the actor who has 87 movies?",
+... ]
+>>> encoding = tokenizer(table, questions, padding=True, return_tensors="pt")
+
+>>> # let the model generate an answer autoregressively
+>>> outputs = model.generate(**encoding)
+
+>>> # decode back to text
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+[' 53', ' george clooney', ' brad pitt']
+```
+
+In case one wants to do table verification (i.e. the task of determining whether a given sentence is supported or refuted by the contents
+of a table), one can instantiate a [`BartForSequenceClassification`] model. TAPEX has checkpoints on the hub fine-tuned on TabFact, an important
+benchmark for table fact checking (it achieves 84% accuracy). The code example below again leverages the [Auto API](auto).
+
+```python
+>>> from transformers import AutoTokenizer, AutoModelForSequenceClassification
+
+>>> tokenizer = AutoTokenizer.from_pretrained("microsoft/tapex-large-finetuned-tabfact")
+>>> model = AutoModelForSequenceClassification.from_pretrained("microsoft/tapex-large-finetuned-tabfact")
+
+>>> # prepare table + sentence
+>>> data = {"Actors": ["Brad Pitt", "Leonardo Di Caprio", "George Clooney"], "Number of movies": ["87", "53", "69"]}
+>>> table = pd.DataFrame.from_dict(data)
+>>> sentence = "George Clooney has 30 movies"
+
+>>> encoding = tokenizer(table, sentence, return_tensors="pt")
+
+>>> # forward pass
+>>> outputs = model(**encoding)
+
+>>> # print prediction
+>>> predicted_class_idx = outputs.logits[0].argmax(dim=0).item()
+>>> print(model.config.id2label[predicted_class_idx])
+Refused
+```
+
+
+
+TAPEX architecture is the same as BART, except for tokenization. Refer to [BART documentation](bart) for information on
+configuration classes and their parameters. TAPEX-specific tokenizer is documented below.
+
+
+
+## TapexTokenizer
+
+[[autodoc]] TapexTokenizer
+ - __call__
+ - save_vocabulary
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/textnet.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/textnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..9c29a8b16bee103b4c7759bbff10b941a451231b
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/textnet.md
@@ -0,0 +1,65 @@
+
+*This model was released on 2021-11-03 and added to Hugging Face Transformers on 2025-01-08.*
+
+# TextNet
+
+
+
+
+
+## Overview
+
+The TextNet model was proposed in [FAST: Faster Arbitrarily-Shaped Text Detector with Minimalist Kernel Representation](https://huggingface.co/papers/2111.02394) by Zhe Chen, Jiahao Wang, Wenhai Wang, Guo Chen, Enze Xie, Ping Luo, Tong Lu. TextNet is a vision backbone useful for text detection tasks. It is the result of neural architecture search (NAS) on backbones with reward function as text detection task (to provide powerful features for text detection).
+
+
+
+ TextNet backbone as part of FAST. Taken from the original paper.
+
+This model was contributed by [Raghavan](https://huggingface.co/Raghavan), [jadechoghari](https://huggingface.co/jadechoghari) and [nielsr](https://huggingface.co/nielsr).
+
+## Usage tips
+
+TextNet is mainly used as a backbone network for the architecture search of text detection. Each stage of the backbone network is comprised of a stride-2 convolution and searchable blocks.
+Specifically, we present a layer-level candidate set, defined as {conv3×3, conv1×3, conv3×1, identity}. As the 1×3 and 3×1 convolutions have asymmetric kernels and oriented structure priors, they may help to capture the features of extreme aspect-ratio and rotated text lines.
+
+TextNet is the backbone for Fast, but can also be used as an efficient text/image classification, we add a `TextNetForImageClassification` as is it would allow people to train an image classifier on top of the pre-trained textnet weights
+
+## TextNetConfig
+
+[[autodoc]] TextNetConfig
+
+## TextNetImageProcessor
+
+[[autodoc]] TextNetImageProcessor
+ - preprocess
+
+## TextNetImageProcessorFast
+
+[[autodoc]] TextNetImageProcessorFast
+ - preprocess
+
+## TextNetModel
+
+[[autodoc]] TextNetModel
+ - forward
+
+## TextNetForImageClassification
+
+[[autodoc]] TextNetForImageClassification
+ - forward
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/time_series_transformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/time_series_transformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..c38671f00fb3e5295209e316f81b604ecc54e835
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/time_series_transformer.md
@@ -0,0 +1,77 @@
+
+*This model was released on 2022-12-01 and added to Hugging Face Transformers on 2022-09-30.*
+
+# Time Series Transformer
+
+
+
+
+
+## Overview
+
+The Time Series Transformer model is a vanilla encoder-decoder Transformer for time series forecasting.
+This model was contributed by [kashif](https://huggingface.co/kashif).
+
+## Usage tips
+
+- Similar to other models in the library, [`TimeSeriesTransformerModel`] is the raw Transformer without any head on top, and [`TimeSeriesTransformerForPrediction`]
+adds a distribution head on top of the former, which can be used for time-series forecasting. Note that this is a so-called probabilistic forecasting model, not a
+point forecasting model. This means that the model learns a distribution, from which one can sample. The model doesn't directly output values.
+- [`TimeSeriesTransformerForPrediction`] consists of 2 blocks: an encoder, which takes a `context_length` of time series values as input (called `past_values`),
+and a decoder, which predicts a `prediction_length` of time series values into the future (called `future_values`). During training, one needs to provide
+pairs of (`past_values` and `future_values`) to the model.
+- In addition to the raw (`past_values` and `future_values`), one typically provides additional features to the model. These can be the following:
+ - `past_time_features`: temporal features which the model will add to `past_values`. These serve as "positional encodings" for the Transformer encoder.
+ Examples are "day of the month", "month of the year", etc. as scalar values (and then stacked together as a vector).
+ e.g. if a given time-series value was obtained on the 11th of August, then one could have [11, 8] as time feature vector (11 being "day of the month", 8 being "month of the year").
+ - `future_time_features`: temporal features which the model will add to `future_values`. These serve as "positional encodings" for the Transformer decoder.
+ Examples are "day of the month", "month of the year", etc. as scalar values (and then stacked together as a vector).
+ e.g. if a given time-series value was obtained on the 11th of August, then one could have [11, 8] as time feature vector (11 being "day of the month", 8 being "month of the year").
+ - `static_categorical_features`: categorical features which are static over time (i.e., have the same value for all `past_values` and `future_values`).
+ An example here is the store ID or region ID that identifies a given time-series.
+ Note that these features need to be known for ALL data points (also those in the future).
+ - `static_real_features`: real-valued features which are static over time (i.e., have the same value for all `past_values` and `future_values`).
+ An example here is the image representation of the product for which you have the time-series values (like the [ResNet](resnet) embedding of a "shoe" picture,
+ if your time-series is about the sales of shoes).
+ Note that these features need to be known for ALL data points (also those in the future).
+- The model is trained using "teacher-forcing", similar to how a Transformer is trained for machine translation. This means that, during training, one shifts the
+`future_values` one position to the right as input to the decoder, prepended by the last value of `past_values`. At each time step, the model needs to predict the
+next target. So the set-up of training is similar to a GPT model for language, except that there's no notion of `decoder_start_token_id` (we just use the last value
+of the context as initial input for the decoder).
+- At inference time, we give the final value of the `past_values` as input to the decoder. Next, we can sample from the model to make a prediction at the next time step,
+which is then fed to the decoder in order to make the next prediction (also called autoregressive generation).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- Check out the Time Series Transformer blog-post in HuggingFace blog: [Probabilistic Time Series Forecasting with 🤗 Transformers](https://huggingface.co/blog/time-series-transformers)
+
+
+## TimeSeriesTransformerConfig
+
+[[autodoc]] TimeSeriesTransformerConfig
+
+## TimeSeriesTransformerModel
+
+[[autodoc]] TimeSeriesTransformerModel
+ - forward
+
+## TimeSeriesTransformerForPrediction
+
+[[autodoc]] TimeSeriesTransformerForPrediction
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/timesfm.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/timesfm.md
new file mode 100644
index 0000000000000000000000000000000000000000..7d4ccfe332cc6e930cf367a436ae70199436965c
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/timesfm.md
@@ -0,0 +1,88 @@
+
+*This model was released on 2023-10-14 and added to Hugging Face Transformers on 2025-04-16.*
+
+# TimesFM
+
+
+
+
+
+## Overview
+
+TimesFM (Time Series Foundation Model) is a pretrained time-series foundation model proposed in [A decoder-only foundation model for time-series forecasting](https://huggingface.co/papers/2310.10688) by Abhimanyu Das, Weihao Kong, Rajat Sen, and Yichen Zhou. It is a decoder only model that uses non-overlapping patches of time-series data as input and outputs some output patch length prediction in an autoregressive fashion.
+
+
+The abstract from the paper is the following:
+
+*Motivated by recent advances in large language models for Natural Language Processing (NLP), we design a time-series foundation model for forecasting whose out-of-the-box zero-shot performance on a variety of public datasets comes close to the accuracy of state-of-the-art supervised forecasting models for each individual dataset. Our model is based on pretraining a patched-decoder style attention model on a large time-series corpus, and can work well across different forecasting history lengths, prediction lengths and temporal granularities.*
+
+
+This model was contributed by [kashif](https://huggingface.co/kashif).
+The original code can be found [here](https://github.com/google-research/timesfm).
+
+
+To use the model:
+
+```python
+import numpy as np
+import torch
+from transformers import TimesFmModelForPrediction
+
+
+model = TimesFmModelForPrediction.from_pretrained(
+ "google/timesfm-2.0-500m-pytorch",
+ torch_dtype=torch.bfloat16,
+ attn_implementation="sdpa",
+ device_map="auto"
+)
+
+
+ # Create dummy inputs
+forecast_input = [
+ np.sin(np.linspace(0, 20, 100)),
+ np.sin(np.linspace(0, 20, 200)),
+ np.sin(np.linspace(0, 20, 400)),
+]
+frequency_input = [0, 1, 2]
+
+# Convert inputs to sequence of tensors
+forecast_input_tensor = [
+ torch.tensor(ts, dtype=torch.bfloat16).to(model.device)
+ for ts in forecast_input
+]
+frequency_input_tensor = torch.tensor(frequency_input, dtype=torch.long).to(model.device)
+
+# Get predictions from the pre-trained model
+with torch.no_grad():
+ outputs = model(past_values=forecast_input_tensor, freq=frequency_input_tensor, return_dict=True)
+ point_forecast_conv = outputs.mean_predictions.float().cpu().numpy()
+ quantile_forecast_conv = outputs.full_predictions.float().cpu().numpy()
+```
+
+## TimesFmConfig
+
+[[autodoc]] TimesFmConfig
+
+## TimesFmModel
+
+[[autodoc]] TimesFmModel
+ - forward
+
+## TimesFmModelForPrediction
+
+[[autodoc]] TimesFmModelForPrediction
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/timesformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/timesformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..59e9ee71817d3e0b1ec276eba0ddeadbcf7b8e49
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/timesformer.md
@@ -0,0 +1,57 @@
+
+*This model was released on 2021-02-09 and added to Hugging Face Transformers on 2022-12-02.*
+
+# TimeSformer
+
+
+
+
+
+## Overview
+
+The TimeSformer model was proposed in [TimeSformer: Is Space-Time Attention All You Need for Video Understanding?](https://huggingface.co/papers/2102.05095) by Facebook Research.
+This work is a milestone in action-recognition field being the first video transformer. It inspired many transformer based video understanding and classification papers.
+
+The abstract from the paper is the following:
+
+*We present a convolution-free approach to video classification built exclusively on self-attention over space and time. Our method, named "TimeSformer," adapts the standard Transformer architecture to video by enabling spatiotemporal feature learning directly from a sequence of frame-level patches. Our experimental study compares different self-attention schemes and suggests that "divided attention," where temporal attention and spatial attention are separately applied within each block, leads to the best video classification accuracy among the design choices considered. Despite the radically new design, TimeSformer achieves state-of-the-art results on several action recognition benchmarks, including the best reported accuracy on Kinetics-400 and Kinetics-600. Finally, compared to 3D convolutional networks, our model is faster to train, it can achieve dramatically higher test efficiency (at a small drop in accuracy), and it can also be applied to much longer video clips (over one minute long). Code and models are available at: [this https URL](https://github.com/facebookresearch/TimeSformer).*
+
+This model was contributed by [fcakyon](https://huggingface.co/fcakyon).
+The original code can be found [here](https://github.com/facebookresearch/TimeSformer).
+
+## Usage tips
+
+There are many pretrained variants. Select your pretrained model based on the dataset it is trained on. Moreover,
+the number of input frames per clip changes based on the model size so you should consider this parameter while selecting your pretrained model.
+
+## Resources
+
+- [Video classification task guide](../tasks/video_classification)
+
+## TimesformerConfig
+
+[[autodoc]] TimesformerConfig
+
+## TimesformerModel
+
+[[autodoc]] TimesformerModel
+ - forward
+
+## TimesformerForVideoClassification
+
+[[autodoc]] TimesformerForVideoClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/timm_wrapper.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/timm_wrapper.md
new file mode 100644
index 0000000000000000000000000000000000000000..8095a91054a5fc441e7da07fcd236713aaa98ef6
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/timm_wrapper.md
@@ -0,0 +1,82 @@
+
+
+# TimmWrapper
+
+
+
+
+
+## Overview
+
+Helper class to enable loading timm models to be used with the transformers library and its autoclasses.
+
+```python
+>>> import torch
+>>> from PIL import Image
+>>> from urllib.request import urlopen
+>>> from transformers import AutoModelForImageClassification, AutoImageProcessor
+
+>>> # Load image
+>>> image = Image.open(urlopen(
+... 'https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/beignets-task-guide.png'
+... ))
+
+>>> # Load model and image processor
+>>> checkpoint = "timm/resnet50.a1_in1k"
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint)
+>>> model = AutoModelForImageClassification.from_pretrained(checkpoint).eval()
+
+>>> # Preprocess image
+>>> inputs = image_processor(image)
+
+>>> # Forward pass
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+
+>>> # Get top 5 predictions
+>>> top5_probabilities, top5_class_indices = torch.topk(logits.softmax(dim=1) * 100, k=5)
+```
+
+## Resources:
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with TimmWrapper.
+
+
+
+- [Collection of Example Notebook](https://github.com/ariG23498/timm-wrapper-examples) 🌎
+
+> [!TIP]
+> For a more detailed overview please read the [official blog post](https://huggingface.co/blog/timm-transformers) on the timm integration.
+
+## TimmWrapperConfig
+
+[[autodoc]] TimmWrapperConfig
+
+## TimmWrapperImageProcessor
+
+[[autodoc]] TimmWrapperImageProcessor
+ - preprocess
+
+## TimmWrapperModel
+
+[[autodoc]] TimmWrapperModel
+ - forward
+
+## TimmWrapperForImageClassification
+
+[[autodoc]] TimmWrapperForImageClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/trajectory_transformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/trajectory_transformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..fba51b1811571f6233a3b2b515a6e63dc851b9d2
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/trajectory_transformer.md
@@ -0,0 +1,66 @@
+
+*This model was released on 2021-06-03 and added to Hugging Face Transformers on 2023-06-20.*
+
+# Trajectory Transformer
+
+
+
+
+
+
+
+This model is in maintenance mode only, so we won't accept any new PRs changing its code.
+
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.30.0.
+You can do so by running the following command: `pip install -U transformers==4.30.0`.
+
+
+
+## Overview
+
+The Trajectory Transformer model was proposed in [Offline Reinforcement Learning as One Big Sequence Modeling Problem](https://huggingface.co/papers/2106.02039) by Michael Janner, Qiyang Li, Sergey Levine.
+
+The abstract from the paper is the following:
+
+*Reinforcement learning (RL) is typically concerned with estimating stationary policies or single-step models,
+leveraging the Markov property to factorize problems in time. However, we can also view RL as a generic sequence
+modeling problem, with the goal being to produce a sequence of actions that leads to a sequence of high rewards.
+Viewed in this way, it is tempting to consider whether high-capacity sequence prediction models that work well
+in other domains, such as natural-language processing, can also provide effective solutions to the RL problem.
+To this end, we explore how RL can be tackled with the tools of sequence modeling, using a Transformer architecture
+to model distributions over trajectories and repurposing beam search as a planning algorithm. Framing RL as sequence
+modeling problem simplifies a range of design decisions, allowing us to dispense with many of the components common
+in offline RL algorithms. We demonstrate the flexibility of this approach across long-horizon dynamics prediction,
+imitation learning, goal-conditioned RL, and offline RL. Further, we show that this approach can be combined with
+existing model-free algorithms to yield a state-of-the-art planner in sparse-reward, long-horizon tasks.*
+
+This model was contributed by [CarlCochet](https://huggingface.co/CarlCochet). The original code can be found [here](https://github.com/jannerm/trajectory-transformer).
+
+## Usage tips
+
+This Transformer is used for deep reinforcement learning. To use it, you need to create sequences from
+actions, states and rewards from all previous timesteps. This model will treat all these elements together
+as one big sequence (a trajectory).
+
+## TrajectoryTransformerConfig
+
+[[autodoc]] TrajectoryTransformerConfig
+
+## TrajectoryTransformerModel
+
+[[autodoc]] TrajectoryTransformerModel
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/transfo-xl.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/transfo-xl.md
new file mode 100644
index 0000000000000000000000000000000000000000..a0427374697ceeebe4c27a2b76a4f772a7673240
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/transfo-xl.md
@@ -0,0 +1,168 @@
+
+*This model was released on 2019-01-09 and added to Hugging Face Transformers on 2023-06-20.*
+
+# Transformer XL
+
+
+
+
+
+
+
+
+This model is in maintenance mode only, so we won't accept any new PRs changing its code. This model was deprecated due to security issues linked to `pickle.load`.
+
+We recommend switching to more recent models for improved security.
+
+In case you would still like to use `TransfoXL` in your experiments, we recommend using the [Hub checkpoint](https://huggingface.co/transfo-xl/transfo-xl-wt103) with a specific revision to ensure you are downloading safe files from the Hub.
+
+You will need to set the environment variable `TRUST_REMOTE_CODE` to `True` in order to allow the
+usage of `pickle.load()`:
+
+```python
+import os
+from transformers import TransfoXLTokenizer, TransfoXLLMHeadModel
+
+os.environ["TRUST_REMOTE_CODE"] = "True"
+
+checkpoint = 'transfo-xl/transfo-xl-wt103'
+revision = '40a186da79458c9f9de846edfaea79c412137f97'
+
+tokenizer = TransfoXLTokenizer.from_pretrained(checkpoint, revision=revision)
+model = TransfoXLLMHeadModel.from_pretrained(checkpoint, revision=revision)
+```
+
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.35.0.
+You can do so by running the following command: `pip install -U transformers==4.35.0`.
+
+
+
+
+
+## Overview
+
+The Transformer-XL model was proposed in [Transformer-XL: Attentive Language Models Beyond a Fixed-Length Context](https://huggingface.co/papers/1901.02860) by Zihang Dai, Zhilin Yang, Yiming Yang, Jaime Carbonell, Quoc V. Le, Ruslan
+Salakhutdinov. It's a causal (uni-directional) transformer with relative positioning (sinusoïdal) embeddings which can
+reuse previously computed hidden-states to attend to longer context (memory). This model also uses adaptive softmax
+inputs and outputs (tied).
+
+The abstract from the paper is the following:
+
+*Transformers have a potential of learning longer-term dependency, but are limited by a fixed-length context in the
+setting of language modeling. We propose a novel neural architecture Transformer-XL that enables learning dependency
+beyond a fixed length without disrupting temporal coherence. It consists of a segment-level recurrence mechanism and a
+novel positional encoding scheme. Our method not only enables capturing longer-term dependency, but also resolves the
+context fragmentation problem. As a result, Transformer-XL learns dependency that is 80% longer than RNNs and 450%
+longer than vanilla Transformers, achieves better performance on both short and long sequences, and is up to 1,800+
+times faster than vanilla Transformers during evaluation. Notably, we improve the state-of-the-art results of
+bpc/perplexity to 0.99 on enwiki8, 1.08 on text8, 18.3 on WikiText-103, 21.8 on One Billion Word, and 54.5 on Penn
+Treebank (without finetuning). When trained only on WikiText-103, Transformer-XL manages to generate reasonably
+coherent, novel text articles with thousands of tokens.*
+
+This model was contributed by [thomwolf](https://huggingface.co/thomwolf). The original code can be found [here](https://github.com/kimiyoung/transformer-xl).
+
+## Usage tips
+
+- Transformer-XL uses relative sinusoidal positional embeddings. Padding can be done on the left or on the right. The
+ original implementation trains on SQuAD with padding on the left, therefore the padding defaults are set to left.
+- Transformer-XL is one of the few models that has no sequence length limit.
+- Same as a regular GPT model, but introduces a recurrence mechanism for two consecutive segments (similar to a regular RNNs with two consecutive inputs). In this context, a segment is a number of consecutive tokens (for instance 512) that may span across multiple documents, and segments are fed in order to the model.
+- Basically, the hidden states of the previous segment are concatenated to the current input to compute the attention scores. This allows the model to pay attention to information that was in the previous segment as well as the current one. By stacking multiple attention layers, the receptive field can be increased to multiple previous segments.
+- This changes the positional embeddings to positional relative embeddings (as the regular positional embeddings would give the same results in the current input and the current hidden state at a given position) and needs to make some adjustments in the way attention scores are computed.
+
+
+
+
+TransformerXL does **not** work with *torch.nn.DataParallel* due to a bug in PyTorch, see [issue #36035](https://github.com/pytorch/pytorch/issues/36035)
+
+
+
+## Resources
+
+- [Text classification task guide](../tasks/sequence_classification)
+- [Causal language modeling task guide](../tasks/language_modeling)
+
+## TransfoXLConfig
+
+[[autodoc]] TransfoXLConfig
+
+## TransfoXLTokenizer
+
+[[autodoc]] TransfoXLTokenizer
+ - save_vocabulary
+
+## TransfoXL specific outputs
+
+[[autodoc]] models.deprecated.transfo_xl.modeling_transfo_xl.TransfoXLModelOutput
+
+[[autodoc]] models.deprecated.transfo_xl.modeling_transfo_xl.TransfoXLLMHeadModelOutput
+
+[[autodoc]] models.deprecated.transfo_xl.modeling_tf_transfo_xl.TFTransfoXLModelOutput
+
+[[autodoc]] models.deprecated.transfo_xl.modeling_tf_transfo_xl.TFTransfoXLLMHeadModelOutput
+
+
+
+
+## TransfoXLModel
+
+[[autodoc]] TransfoXLModel
+ - forward
+
+## TransfoXLLMHeadModel
+
+[[autodoc]] TransfoXLLMHeadModel
+ - forward
+
+## TransfoXLForSequenceClassification
+
+[[autodoc]] TransfoXLForSequenceClassification
+ - forward
+
+
+
+
+## TFTransfoXLModel
+
+[[autodoc]] TFTransfoXLModel
+ - call
+
+## TFTransfoXLLMHeadModel
+
+[[autodoc]] TFTransfoXLLMHeadModel
+ - call
+
+## TFTransfoXLForSequenceClassification
+
+[[autodoc]] TFTransfoXLForSequenceClassification
+ - call
+
+
+
+
+## Internal Layers
+
+[[autodoc]] AdaptiveEmbedding
+
+[[autodoc]] TFAdaptiveEmbedding
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/trocr.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/trocr.md
new file mode 100644
index 0000000000000000000000000000000000000000..6346977dafa16df6e633dc2dfe21ae25303c7356
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/trocr.md
@@ -0,0 +1,133 @@
+
+*This model was released on 2021-09-21 and added to Hugging Face Transformers on 2021-10-13.*
+
+
+
+
+
+
+
+
+
+# TrOCR
+
+[TrOCR](https://huggingface.co/papers/2109.10282) is a text recognition model for both image understanding and text generation. It doesn't require separate models for image processing or character generation. TrOCR is a simple single end-to-end system that uses a transformer to handle visual understanding and text generation.
+
+You can find all the original TrOCR checkpoints under the [Microsoft](https://huggingface.co/microsoft/models?search=trocr) organization.
+
+
+ TrOCR architecture. Taken from the original paper.
+
+
+> [!TIP]
+> This model was contributed by [nielsr](https://huggingface.co/nielsr).
+>
+> Click on the TrOCR models in the right sidebar for more examples of how to apply TrOCR to different image and text tasks.
+
+
+The example below demonstrates how to perform optical character recognition (OCR) with the [`AutoModel`] class.
+
+
+
+
+```python
+from transformers import TrOCRProcessor, VisionEncoderDecoderModel
+import requests
+from PIL import Image
+
+processor = TrOCRProcessor.from_pretrained("microsoft/trocr-base-handwritten")
+model = VisionEncoderDecoderModel.from_pretrained("microsoft/trocr-base-handwritten")
+
+# load image from the IAM dataset
+url = "https://fki.tic.heia-fr.ch/static/img/a01-122-02.jpg"
+image = Image.open(requests.get(url, stream=True).raw).convert("RGB")
+
+pixel_values = processor(image, return_tensors="pt").pixel_values
+generated_ids = model.generate(pixel_values)
+
+generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+print(generated_text)
+```
+
+
+
+
+## Quantization
+
+Quantization reduces the memory burden of large models by representing the weights in a lower precision. Refer to the [Quantization](../quantization/overview) overview for more available quantization backends.
+
+The example below uses [bitsandbytes](../quantization/bitsandbytes) to quantize the weights to 8-bits.
+
+```python
+# pip install bitsandbytes accelerate
+from transformers import TrOCRProcessor, VisionEncoderDecoderModel, BitsandBytesConfig
+import requests
+from PIL import Image
+
+# Set up the quantization configuration
+quantization_config = BitsandBytesConfig(load_in_8bit=True)
+
+# Use a large checkpoint for a more noticeable impact
+processor = TrOCRProcessor.from_pretrained("microsoft/trocr-large-handwritten")
+model = VisionEncoderDecoderModel.from_pretrained(
+ "microsoft/trocr-large-handwritten",
+ quantization_config=quantization_config
+)
+
+# load image from the IAM dataset
+url = "[https://fki.tic.heia-fr.ch/static/img/a01-122-02.jpg](https://fki.tic.heia-fr.ch/static/img/a01-122-02.jpg)"
+image = Image.open(requests.get(url, stream=True).raw).convert("RGB")
+
+pixel_values = processor(image, return_tensors="pt").pixel_values
+generated_ids = model.generate(pixel_values)
+
+generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+print(generated_text)
+```
+
+## Notes
+
+- TrOCR wraps [`ViTImageProcessor`]/[`DeiTImageProcessor`] and [`RobertaTokenizer`]/[`XLMRobertaTokenizer`] into a single instance of [`TrOCRProcessor`] to handle images and text.
+- TrOCR is always used within the [VisionEncoderDecoder](vision-encoder-decoder) framework.
+
+## Resources
+
+- A blog post on [Accelerating Document AI](https://huggingface.co/blog/document-ai) with TrOCR.
+- A blog post on how to [Document AI](https://github.com/philschmid/document-ai-transformers) with TrOCR.
+- A notebook on how to [finetune TrOCR on IAM Handwriting Database using Seq2SeqTrainer](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TrOCR/Fine_tune_TrOCR_on_IAM_Handwriting_Database_using_Seq2SeqTrainer.ipynb).
+- An interactive-demo on [TrOCR handwritten character recognition](https://huggingface.co/spaces/nielsr/TrOCR-handwritten).
+- A notebook on [inference with TrOCR](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TrOCR/Inference_with_TrOCR_%2B_Gradio_demo.ipynb) and Gradio demo.
+- A notebook on [evaluating TrOCR on the IAM test set](https://colab.research.google.com/github/NielsRogge/Transformers-Tutorials/blob/master/TrOCR/Evaluating_TrOCR_base_handwritten_on_the_IAM_test_set.ipynb).
+
+
+## TrOCRConfig
+
+[[autodoc]] TrOCRConfig
+
+## TrOCRProcessor
+
+[[autodoc]] TrOCRProcessor
+ - __call__
+ - from_pretrained
+ - save_pretrained
+ - batch_decode
+ - decode
+
+## TrOCRForCausalLM
+
+[[autodoc]] TrOCRForCausalLM
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/tvlt.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/tvlt.md
new file mode 100644
index 0000000000000000000000000000000000000000..069978176865993816d46d842a93a372d0858df6
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/tvlt.md
@@ -0,0 +1,90 @@
+
+*This model was released on 2022-09-28 and added to Hugging Face Transformers on 2023-06-20.*
+
+# TVLT
+
+
+
+
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.40.2.
+You can do so by running the following command: `pip install -U transformers==4.40.2`.
+
+
+
+## Overview
+
+The TVLT model was proposed in [TVLT: Textless Vision-Language Transformer](https://huggingface.co/papers/2209.14156)
+by Zineng Tang, Jaemin Cho, Yixin Nie, Mohit Bansal (the first three authors contributed equally). The Textless Vision-Language Transformer (TVLT) is a model that uses raw visual and audio inputs for vision-and-language representation learning, without using text-specific modules such as tokenization or automatic speech recognition (ASR). It can perform various audiovisual and vision-language tasks like retrieval, question answering, etc.
+
+The abstract from the paper is the following:
+
+*In this work, we present the Textless Vision-Language Transformer (TVLT), where homogeneous transformer blocks take raw visual and audio inputs for vision-and-language representation learning with minimal modality-specific design, and do not use text-specific modules such as tokenization or automatic speech recognition (ASR). TVLT is trained by reconstructing masked patches of continuous video frames and audio spectrograms (masked autoencoding) and contrastive modeling to align video and audio. TVLT attains performance comparable to its text-based counterpart on various multimodal tasks, such as visual question answering, image retrieval, video retrieval, and multimodal sentiment analysis, with 28x faster inference speed and only 1/3 of the parameters. Our findings suggest the possibility of learning compact and efficient visual-linguistic representations from low-level visual and audio signals without assuming the prior existence of text.*
+
+
+
+
+
+ TVLT architecture. Taken from the original paper.
+
+The original code can be found [here](https://github.com/zinengtang/TVLT). This model was contributed by [Zineng Tang](https://huggingface.co/ZinengTang).
+
+## Usage tips
+
+- TVLT is a model that takes both `pixel_values` and `audio_values` as input. One can use [`TvltProcessor`] to prepare data for the model.
+ This processor wraps an image processor (for the image/video modality) and an audio feature extractor (for the audio modality) into one.
+- TVLT is trained with images/videos and audios of various sizes: the authors resize and crop the input images/videos to 224 and limit the length of audio spectrogram to 2048. To make batching of videos and audios possible, the authors use a `pixel_mask` that indicates which pixels are real/padding and `audio_mask` that indicates which audio values are real/padding.
+- The design of TVLT is very similar to that of a standard Vision Transformer (ViT) and masked autoencoder (MAE) as in [ViTMAE](vitmae). The difference is that the model includes embedding layers for the audio modality.
+- The PyTorch version of this model is only available in torch 1.10 and higher.
+
+## TvltConfig
+
+[[autodoc]] TvltConfig
+
+## TvltProcessor
+
+[[autodoc]] TvltProcessor
+ - __call__
+
+## TvltImageProcessor
+
+[[autodoc]] TvltImageProcessor
+ - preprocess
+
+## TvltFeatureExtractor
+
+[[autodoc]] TvltFeatureExtractor
+ - __call__
+
+## TvltModel
+
+[[autodoc]] TvltModel
+ - forward
+
+## TvltForPreTraining
+
+[[autodoc]] TvltForPreTraining
+ - forward
+
+## TvltForAudioVisualClassification
+
+[[autodoc]] TvltForAudioVisualClassification
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/tvp.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/tvp.md
new file mode 100644
index 0000000000000000000000000000000000000000..49a538ffa8c45753f237779bc9c41b5add0691b7
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/tvp.md
@@ -0,0 +1,196 @@
+
+*This model was released on 2023-03-09 and added to Hugging Face Transformers on 2023-11-22.*
+
+# TVP
+
+
+
+
+
+## Overview
+
+The text-visual prompting (TVP) framework was proposed in the paper [Text-Visual Prompting for Efficient 2D Temporal Video Grounding](https://huggingface.co/papers/2303.04995) by Yimeng Zhang, Xin Chen, Jinghan Jia, Sijia Liu, Ke Ding.
+
+The abstract from the paper is the following:
+
+*In this paper, we study the problem of temporal video grounding (TVG), which aims to predict the starting/ending time points of moments described by a text sentence within a long untrimmed video. Benefiting from fine-grained 3D visual features, the TVG techniques have achieved remarkable progress in recent years. However, the high complexity of 3D convolutional neural networks (CNNs) makes extracting dense 3D visual features time-consuming, which calls for intensive memory and computing resources. Towards efficient TVG, we propose a novel text-visual prompting (TVP) framework, which incorporates optimized perturbation patterns (that we call ‘prompts’) into both visual inputs and textual features of a TVG model. In sharp contrast to 3D CNNs, we show that TVP allows us to effectively co-train vision encoder and language encoder in a 2D TVG model and improves the performance of cross-modal feature fusion using only low-complexity sparse 2D visual features. Further, we propose a Temporal-Distance IoU (TDIoU) loss for efficient learning of TVG. Experiments on two benchmark datasets, Charades-STA and ActivityNet Captions datasets, empirically show that the proposed TVP significantly boosts the performance of 2D TVG (e.g., 9.79% improvement on Charades-STA and 30.77% improvement on ActivityNet Captions) and achieves 5× inference acceleration over TVG using 3D visual features.*
+
+This research addresses temporal video grounding (TVG), which is the process of pinpointing the start and end times of specific events in a long video, as described by a text sentence. Text-visual prompting (TVP), is proposed to enhance TVG. TVP involves integrating specially designed patterns, known as 'prompts', into both the visual (image-based) and textual (word-based) input components of a TVG model. These prompts provide additional spatial-temporal context, improving the model's ability to accurately determine event timings in the video. The approach employs 2D visual inputs in place of 3D ones. Although 3D inputs offer more spatial-temporal detail, they are also more time-consuming to process. The use of 2D inputs with the prompting method aims to provide similar levels of context and accuracy more efficiently.
+
+
+
+ TVP architecture. Taken from the original paper.
+
+This model was contributed by [Jiqing Feng](https://huggingface.co/Jiqing). The original code can be found [here](https://github.com/intel/TVP).
+
+## Usage tips and examples
+
+Prompts are optimized perturbation patterns, which would be added to input video frames or text features. Universal set refers to using the same exact set of prompts for any input, this means that these prompts are added consistently to all video frames and text features, regardless of the input's content.
+
+TVP consists of a visual encoder and cross-modal encoder. A universal set of visual prompts and text prompts to be integrated into sampled video frames and textual features, respectively. Specially, a set of different visual prompts are applied to uniformly-sampled frames of one untrimmed video in order.
+
+The goal of this model is to incorporate trainable prompts into both visual inputs and textual features to temporal video grounding(TVG) problems.
+In principle, one can apply any visual, cross-modal encoder in the proposed architecture.
+
+The [`TvpProcessor`] wraps [`BertTokenizer`] and [`TvpImageProcessor`] into a single instance to both
+encode the text and prepare the images respectively.
+
+The following example shows how to run temporal video grounding using [`TvpProcessor`] and [`TvpForVideoGrounding`].
+```python
+import av
+import cv2
+import numpy as np
+import torch
+from huggingface_hub import hf_hub_download
+from transformers import AutoProcessor, TvpForVideoGrounding
+
+
+def pyav_decode(container, sampling_rate, num_frames, clip_idx, num_clips, target_fps):
+ '''
+ Convert the video from its original fps to the target_fps and decode the video with PyAV decoder.
+ Args:
+ container (container): pyav container.
+ sampling_rate (int): frame sampling rate (interval between two sampled frames).
+ num_frames (int): number of frames to sample.
+ clip_idx (int): if clip_idx is -1, perform random temporal sampling.
+ If clip_idx is larger than -1, uniformly split the video to num_clips
+ clips, and select the clip_idx-th video clip.
+ num_clips (int): overall number of clips to uniformly sample from the given video.
+ target_fps (int): the input video may have different fps, convert it to
+ the target video fps before frame sampling.
+ Returns:
+ frames (tensor): decoded frames from the video. Return None if the no
+ video stream was found.
+ fps (float): the number of frames per second of the video.
+ '''
+ video = container.streams.video[0]
+ fps = float(video.average_rate)
+ clip_size = sampling_rate * num_frames / target_fps * fps
+ delta = max(num_frames - clip_size, 0)
+ start_idx = delta * clip_idx / num_clips
+ end_idx = start_idx + clip_size - 1
+ timebase = video.duration / num_frames
+ video_start_pts = int(start_idx * timebase)
+ video_end_pts = int(end_idx * timebase)
+ seek_offset = max(video_start_pts - 1024, 0)
+ container.seek(seek_offset, any_frame=False, backward=True, stream=video)
+ frames = {}
+ for frame in container.decode(video=0):
+ if frame.pts < video_start_pts:
+ continue
+ frames[frame.pts] = frame
+ if frame.pts > video_end_pts:
+ break
+ frames = [frames[pts] for pts in sorted(frames)]
+ return frames, fps
+
+
+def decode(container, sampling_rate, num_frames, clip_idx, num_clips, target_fps):
+ '''
+ Decode the video and perform temporal sampling.
+ Args:
+ container (container): pyav container.
+ sampling_rate (int): frame sampling rate (interval between two sampled frames).
+ num_frames (int): number of frames to sample.
+ clip_idx (int): if clip_idx is -1, perform random temporal sampling.
+ If clip_idx is larger than -1, uniformly split the video to num_clips
+ clips, and select the clip_idx-th video clip.
+ num_clips (int): overall number of clips to uniformly sample from the given video.
+ target_fps (int): the input video may have different fps, convert it to
+ the target video fps before frame sampling.
+ Returns:
+ frames (tensor): decoded frames from the video.
+ '''
+ assert clip_idx >= -2, "Not a valid clip_idx {}".format(clip_idx)
+ frames, fps = pyav_decode(container, sampling_rate, num_frames, clip_idx, num_clips, target_fps)
+ clip_size = sampling_rate * num_frames / target_fps * fps
+ index = np.linspace(0, clip_size - 1, num_frames)
+ index = np.clip(index, 0, len(frames) - 1).astype(np.int64)
+ frames = np.array([frames[idx].to_rgb().to_ndarray() for idx in index])
+ frames = frames.transpose(0, 3, 1, 2)
+ return frames
+
+
+file = hf_hub_download(repo_id="Intel/tvp_demo", filename="AK2KG.mp4", repo_type="dataset")
+model = TvpForVideoGrounding.from_pretrained("Intel/tvp-base")
+
+decoder_kwargs = dict(
+ container=av.open(file, metadata_errors="ignore"),
+ sampling_rate=1,
+ num_frames=model.config.num_frames,
+ clip_idx=0,
+ num_clips=1,
+ target_fps=3,
+)
+raw_sampled_frms = decode(**decoder_kwargs)
+
+text = "a person is sitting on a bed."
+processor = AutoProcessor.from_pretrained("Intel/tvp-base")
+model_inputs = processor(
+ text=[text], videos=list(raw_sampled_frms), return_tensors="pt", max_text_length=100#, size=size
+)
+
+model_inputs["pixel_values"] = model_inputs["pixel_values"].to(model.dtype)
+output = model(**model_inputs)
+
+def get_video_duration(filename):
+ cap = cv2.VideoCapture(filename)
+ if cap.isOpened():
+ rate = cap.get(5)
+ frame_num = cap.get(7)
+ duration = frame_num/rate
+ return duration
+ return -1
+
+duration = get_video_duration(file)
+start, end = processor.post_process_video_grounding(output.logits, duration)
+
+print(f"The time slot of the video corresponding to the text \"{text}\" is from {start}s to {end}s")
+```
+
+Tips:
+
+- This implementation of TVP uses [`BertTokenizer`] to generate text embeddings and Resnet-50 model to compute visual embeddings.
+- Checkpoints for pre-trained [tvp-base](https://huggingface.co/Intel/tvp-base) is released.
+- Please refer to [Table 2](https://huggingface.co/papers/2303.04995) for TVP's performance on Temporal Video Grounding task.
+
+
+## TvpConfig
+
+[[autodoc]] TvpConfig
+
+## TvpImageProcessor
+
+[[autodoc]] TvpImageProcessor
+ - preprocess
+
+## TvpImageProcessorFast
+
+[[autodoc]] TvpImageProcessorFast
+ - preprocess
+
+## TvpProcessor
+
+[[autodoc]] TvpProcessor
+ - __call__
+
+## TvpModel
+
+[[autodoc]] TvpModel
+ - forward
+
+## TvpForVideoGrounding
+
+[[autodoc]] TvpForVideoGrounding
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/udop.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/udop.md
new file mode 100644
index 0000000000000000000000000000000000000000..eb400cc39d5f49f0283a3c61c7adb9dbe4bc585a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/udop.md
@@ -0,0 +1,118 @@
+
+*This model was released on 2022-12-05 and added to Hugging Face Transformers on 2024-03-04.*
+
+# UDOP
+
+
+
+
+
+## Overview
+
+The UDOP model was proposed in [Unifying Vision, Text, and Layout for Universal Document Processing](https://huggingface.co/papers/2212.02623) by Zineng Tang, Ziyi Yang, Guoxin Wang, Yuwei Fang, Yang Liu, Chenguang Zhu, Michael Zeng, Cha Zhang, Mohit Bansal.
+UDOP adopts an encoder-decoder Transformer architecture based on [T5](t5) for document AI tasks like document image classification, document parsing and document visual question answering.
+
+The abstract from the paper is the following:
+
+We propose Universal Document Processing (UDOP), a foundation Document AI model which unifies text, image, and layout modalities together with varied task formats, including document understanding and generation. UDOP leverages the spatial correlation between textual content and document image to model image, text, and layout modalities with one uniform representation. With a novel Vision-Text-Layout Transformer, UDOP unifies pretraining and multi-domain downstream tasks into a prompt-based sequence generation scheme. UDOP is pretrained on both large-scale unlabeled document corpora using innovative self-supervised objectives and diverse labeled data. UDOP also learns to generate document images from text and layout modalities via masked image reconstruction. To the best of our knowledge, this is the first time in the field of document AI that one model simultaneously achieves high-quality neural document editing and content customization. Our method sets the state-of-the-art on 9 Document AI tasks, e.g., document understanding and QA, across diverse data domains like finance reports, academic papers, and websites. UDOP ranks first on the leaderboard of the Document Understanding Benchmark (DUE).*
+
+
+
+ UDOP architecture. Taken from the original paper.
+
+## Usage tips
+
+- In addition to *input_ids*, [`UdopForConditionalGeneration`] also expects the input `bbox`, which are
+ the bounding boxes (i.e. 2D-positions) of the input tokens. These can be obtained using an external OCR engine such
+ as Google's [Tesseract](https://github.com/tesseract-ocr/tesseract) (there's a [Python wrapper](https://pypi.org/project/pytesseract/) available). Each bounding box should be in (x0, y0, x1, y1) format, where (x0, y0) corresponds to the position of the upper left corner in the bounding box, and (x1, y1) represents the
+ position of the lower right corner. Note that one first needs to normalize the bounding boxes to be on a 0-1000
+ scale. To normalize, you can use the following function:
+
+```python
+def normalize_bbox(bbox, width, height):
+ return [
+ int(1000 * (bbox[0] / width)),
+ int(1000 * (bbox[1] / height)),
+ int(1000 * (bbox[2] / width)),
+ int(1000 * (bbox[3] / height)),
+ ]
+```
+
+Here, `width` and `height` correspond to the width and height of the original document in which the token
+occurs. Those can be obtained using the Python Image Library (PIL) library for example, as follows:
+
+```python
+from PIL import Image
+
+# Document can be a png, jpg, etc. PDFs must be converted to images.
+image = Image.open(name_of_your_document).convert("RGB")
+
+width, height = image.size
+```
+
+One can use [`UdopProcessor`] to prepare images and text for the model, which takes care of all of this. By default, this class uses the Tesseract engine to extract a list of words and boxes (coordinates) from a given document. Its functionality is equivalent to that of [`LayoutLMv3Processor`], hence it supports passing either `apply_ocr=False` in case you prefer to use your own OCR engine or `apply_ocr=True` in case you want the default OCR engine to be used. Refer to the [usage guide of LayoutLMv2](layoutlmv2#usage-layoutlmv2processor) regarding all possible use cases (the functionality of `UdopProcessor` is identical).
+
+- If using an own OCR engine of choice, one recommendation is Azure's [Read API](https://learn.microsoft.com/en-us/azure/ai-services/computer-vision/how-to/call-read-api), which supports so-called line segments. Use of segment position embeddings typically results in better performance.
+- At inference time, it's recommended to use the `generate` method to autoregressively generate text given a document image.
+- The model has been pre-trained on both self-supervised and supervised objectives. One can use the various task prefixes (prompts) used during pre-training to test out the out-of-the-box capabilities. For instance, the model can be prompted with "Question answering. What is the date?", as "Question answering." is the task prefix used during pre-training for DocVQA. Refer to the [paper](https://huggingface.co/papers/2212.02623) (table 1) for all task prefixes.
+- One can also fine-tune [`UdopEncoderModel`], which is the encoder-only part of UDOP, which can be seen as a LayoutLMv3-like Transformer encoder. For discriminative tasks, one can just add a linear classifier on top of it and fine-tune it on a labeled dataset.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/microsoft/UDOP).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with UDOP. If
+you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll
+review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- Demo notebooks regarding UDOP can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/UDOP) that show how
+to fine-tune UDOP on a custom dataset as well as inference. 🌎
+- [Document question answering task guide](../tasks/document_question_answering)
+
+## UdopConfig
+
+[[autodoc]] UdopConfig
+
+## UdopTokenizer
+
+[[autodoc]] UdopTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## UdopTokenizerFast
+
+[[autodoc]] UdopTokenizerFast
+
+## UdopProcessor
+
+[[autodoc]] UdopProcessor
+ - __call__
+
+## UdopModel
+
+[[autodoc]] UdopModel
+ - forward
+
+## UdopForConditionalGeneration
+
+[[autodoc]] UdopForConditionalGeneration
+ - forward
+
+## UdopEncoderModel
+
+[[autodoc]] UdopEncoderModel
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ul2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ul2.md
new file mode 100644
index 0000000000000000000000000000000000000000..ca0bacbc43f18e37366947ba8c4230f394d9359f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ul2.md
@@ -0,0 +1,51 @@
+
+*This model was released on 2022-05-10 and added to Hugging Face Transformers on 2023-06-20.*
+
+# UL2
+
+
+
+
+
+
+
+## Overview
+
+The T5 model was presented in [Unifying Language Learning Paradigms](https://huggingface.co/papers/2205.05131) by Yi Tay, Mostafa Dehghani, Vinh Q. Tran, Xavier Garcia, Dara Bahri, Tal Schuster, Huaixiu Steven Zheng, Neil Houlsby, Donald Metzler.
+
+The abstract from the paper is the following:
+
+*Existing pre-trained models are generally geared towards a particular class of problems. To date, there seems to be still no consensus on what the right architecture and pre-training setup should be. This paper presents a unified framework for pre-training models that are universally effective across datasets and setups. We begin by disentangling architectural archetypes with pre-training objectives -- two concepts that are commonly conflated. Next, we present a generalized and unified perspective for self-supervision in NLP and show how different pre-training objectives can be cast as one another and how interpolating between different objectives can be effective. We then propose Mixture-of-Denoisers (MoD), a pre-training objective that combines diverse pre-training paradigms together. We furthermore introduce a notion of mode switching, wherein downstream fine-tuning is associated with specific pre-training schemes. We conduct extensive ablative experiments to compare multiple pre-training objectives and find that our method pushes the Pareto-frontier by outperforming T5 and/or GPT-like models across multiple diverse setups. Finally, by scaling our model up to 20B parameters, we achieve SOTA performance on 50 well-established supervised NLP tasks ranging from language generation (with automated and human evaluation), language understanding, text classification, question answering, commonsense reasoning, long text reasoning, structured knowledge grounding and information retrieval. Our model also achieve strong results at in-context learning, outperforming 175B GPT-3 on zero-shot SuperGLUE and tripling the performance of T5-XXL on one-shot summarization.*
+
+This model was contributed by [DanielHesslow](https://huggingface.co/Seledorn). The original code can be found [here](https://github.com/google-research/google-research/tree/master/ul2).
+
+## Usage tips
+
+- UL2 is an encoder-decoder model pre-trained on a mixture of denoising functions as well as fine-tuned on an array of downstream tasks.
+- UL2 has the same architecture as [T5v1.1](t5v1.1) but uses the Gated-SiLU activation function instead of Gated-GELU.
+- The authors release checkpoints of one architecture which can be seen [here](https://huggingface.co/google/ul2)
+
+
+
+As UL2 has the same architecture as T5v1.1, refer to [T5's documentation page](t5) for API reference, tips, code examples and notebooks.
+
+
+
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/umt5.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/umt5.md
new file mode 100644
index 0000000000000000000000000000000000000000..b0e5f02de461fbc6d2e44a6bac4f3c159009d101
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/umt5.md
@@ -0,0 +1,108 @@
+
+*This model was released on 2023-04-18 and added to Hugging Face Transformers on 2023-07-03.*
+
+# UMT5
+
+
+
+
+
+## Overview
+
+The UMT5 model was proposed in [UniMax: Fairer and More Effective Language Sampling for Large-Scale Multilingual Pretraining](https://arxiv.org/pdf/2304.09151) by Hyung Won Chung, Xavier Garcia, Adam Roberts, Yi Tay, Orhan Firat, Sharan Narang, Noah Constant.
+
+The abstract from the paper is the following:
+
+*Pretrained multilingual large language models have typically used heuristic temperature-based sampling to balance between different languages. However previous work has not systematically evaluated the efficacy of different pretraining language distributions across model scales. In this paper, we propose a new sampling method, UniMax, that delivers more uniform coverage of head languages while mitigating overfitting on tail languages by explicitly capping the number of repeats over each language's corpus. We perform an extensive series of ablations testing a range of sampling strategies on a suite of multilingual benchmarks, while varying model scale. We find that UniMax outperforms standard temperature-based sampling, and the benefits persist as scale increases. As part of our contribution, we release: (i) an improved and refreshed mC4 multilingual corpus consisting of 29 trillion characters across 107 languages, and (ii) a suite of pretrained umT5 model checkpoints trained with UniMax sampling.*
+
+Google has released the following variants:
+
+- [google/umt5-small](https://huggingface.co/google/umt5-small)
+- [google/umt5-base](https://huggingface.co/google/umt5-base)
+- [google/umt5-xl](https://huggingface.co/google/umt5-xl)
+- [google/umt5-xxl](https://huggingface.co/google/umt5-xxl).
+
+This model was contributed by [agemagician](https://huggingface.co/agemagician) and [stefan-it](https://huggingface.co/stefan-it). The original code can be
+found [here](https://github.com/google-research/t5x).
+
+## Usage tips
+
+- UMT5 was only pre-trained on [mC4](https://huggingface.co/datasets/mc4) excluding any supervised training.
+Therefore, this model has to be fine-tuned before it is usable on a downstream task, unlike the original T5 model.
+- Since umT5 was pre-trained in an unsupervised manner, there's no real advantage to using a task prefix during single-task
+fine-tuning. If you are doing multi-task fine-tuning, you should use a prefix.
+
+## Differences with mT5?
+`UmT5` is based on mT5, with a non-shared relative positional bias that is computed for each layer. This means that the model set `has_relative_bias` for each layer.
+The conversion script is also different because the model was saved in t5x's latest checkpointing format.
+
+# Sample usage
+
+```python
+>>> from transformers import AutoModelForSeq2SeqLM, AutoTokenizer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("google/umt5-small")
+>>> tokenizer = AutoTokenizer.from_pretrained("google/umt5-small")
+
+>>> inputs = tokenizer(
+... "A walks into a bar and orders a with pinch of .",
+... return_tensors="pt",
+... )
+>>> outputs = model.generate(**inputs)
+>>> print(tokenizer.batch_decode(outputs))
+['nyone who drink a alcohol A A. This I']
+```
+
+
+
+Refer to [T5's documentation page](t5) for more tips, code examples and notebooks.
+
+
+## UMT5Config
+
+[[autodoc]] UMT5Config
+
+## UMT5Model
+
+[[autodoc]] UMT5Model
+ - forward
+
+## UMT5ForConditionalGeneration
+
+[[autodoc]] UMT5ForConditionalGeneration
+ - forward
+
+## UMT5EncoderModel
+
+[[autodoc]] UMT5EncoderModel
+ - forward
+
+## UMT5ForSequenceClassification
+
+[[autodoc]] UMT5ForSequenceClassification
+ - forward
+
+## UMT5ForTokenClassification
+
+[[autodoc]] UMT5ForTokenClassification
+ - forward
+
+## UMT5ForQuestionAnswering
+
+[[autodoc]] UMT5ForQuestionAnswering
+ - forward
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/unispeech-sat.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/unispeech-sat.md
new file mode 100644
index 0000000000000000000000000000000000000000..308155bbfe21db88c3438925a3070eb6123f4f6c
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/unispeech-sat.md
@@ -0,0 +1,102 @@
+
+*This model was released on 2021-10-12 and added to Hugging Face Transformers on 2021-10-26.*
+
+# UniSpeech-SAT
+
+
+
+
+
+
+
+## Overview
+
+The UniSpeech-SAT model was proposed in [UniSpeech-SAT: Universal Speech Representation Learning with Speaker Aware
+Pre-Training](https://huggingface.co/papers/2110.05752) by Sanyuan Chen, Yu Wu, Chengyi Wang, Zhengyang Chen, Zhuo Chen,
+Shujie Liu, Jian Wu, Yao Qian, Furu Wei, Jinyu Li, Xiangzhan Yu .
+
+The abstract from the paper is the following:
+
+*Self-supervised learning (SSL) is a long-standing goal for speech processing, since it utilizes large-scale unlabeled
+data and avoids extensive human labeling. Recent years witness great successes in applying self-supervised learning in
+speech recognition, while limited exploration was attempted in applying SSL for modeling speaker characteristics. In
+this paper, we aim to improve the existing SSL framework for speaker representation learning. Two methods are
+introduced for enhancing the unsupervised speaker information extraction. First, we apply the multi-task learning to
+the current SSL framework, where we integrate the utterance-wise contrastive loss with the SSL objective function.
+Second, for better speaker discrimination, we propose an utterance mixing strategy for data augmentation, where
+additional overlapped utterances are created unsupervisedly and incorporate during training. We integrate the proposed
+methods into the HuBERT framework. Experiment results on SUPERB benchmark show that the proposed system achieves
+state-of-the-art performance in universal representation learning, especially for speaker identification oriented
+tasks. An ablation study is performed verifying the efficacy of each proposed method. Finally, we scale up training
+dataset to 94 thousand hours public audio data and achieve further performance improvement in all SUPERB tasks.*
+
+This model was contributed by [patrickvonplaten](https://huggingface.co/patrickvonplaten). The Authors' code can be
+found [here](https://github.com/microsoft/UniSpeech/tree/main/UniSpeech-SAT).
+
+## Usage tips
+
+- UniSpeechSat is a speech model that accepts a float array corresponding to the raw waveform of the speech signal.
+ Please use [`Wav2Vec2Processor`] for the feature extraction.
+- UniSpeechSat model can be fine-tuned using connectionist temporal classification (CTC) so the model output has to be
+ decoded using [`Wav2Vec2CTCTokenizer`].
+- UniSpeechSat performs especially well on speaker verification, speaker identification, and speaker diarization tasks.
+
+> [!NOTE]
+> The `head_mask` argument is ignored when using all attention implementation other than "eager". If you have a `head_mask` and want it to have effect, load the model with `XXXModel.from_pretrained(model_id, attn_implementation="eager")`
+
+## Resources
+
+- [Audio classification task guide](../tasks/audio_classification)
+- [Automatic speech recognition task guide](../tasks/asr)
+
+## UniSpeechSatConfig
+
+[[autodoc]] UniSpeechSatConfig
+
+## UniSpeechSat specific outputs
+
+[[autodoc]] models.unispeech_sat.modeling_unispeech_sat.UniSpeechSatForPreTrainingOutput
+
+## UniSpeechSatModel
+
+[[autodoc]] UniSpeechSatModel
+ - forward
+
+## UniSpeechSatForCTC
+
+[[autodoc]] UniSpeechSatForCTC
+ - forward
+
+## UniSpeechSatForSequenceClassification
+
+[[autodoc]] UniSpeechSatForSequenceClassification
+ - forward
+
+## UniSpeechSatForAudioFrameClassification
+
+[[autodoc]] UniSpeechSatForAudioFrameClassification
+ - forward
+
+## UniSpeechSatForXVector
+
+[[autodoc]] UniSpeechSatForXVector
+ - forward
+
+## UniSpeechSatForPreTraining
+
+[[autodoc]] UniSpeechSatForPreTraining
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/unispeech.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/unispeech.md
new file mode 100644
index 0000000000000000000000000000000000000000..98348b560db76da6e7dc32e5b15e728b0bac1e80
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/unispeech.md
@@ -0,0 +1,87 @@
+
+*This model was released on 2021-01-19 and added to Hugging Face Transformers on 2021-10-26.*
+
+# UniSpeech
+
+
+
+
+
+
+
+## Overview
+
+The UniSpeech model was proposed in [UniSpeech: Unified Speech Representation Learning with Labeled and Unlabeled Data](https://huggingface.co/papers/2101.07597) by Chengyi Wang, Yu Wu, Yao Qian, Kenichi Kumatani, Shujie Liu, Furu Wei, Michael
+Zeng, Xuedong Huang .
+
+The abstract from the paper is the following:
+
+*In this paper, we propose a unified pre-training approach called UniSpeech to learn speech representations with both
+unlabeled and labeled data, in which supervised phonetic CTC learning and phonetically-aware contrastive
+self-supervised learning are conducted in a multi-task learning manner. The resultant representations can capture
+information more correlated with phonetic structures and improve the generalization across languages and domains. We
+evaluate the effectiveness of UniSpeech for cross-lingual representation learning on public CommonVoice corpus. The
+results show that UniSpeech outperforms self-supervised pretraining and supervised transfer learning for speech
+recognition by a maximum of 13.4% and 17.8% relative phone error rate reductions respectively (averaged over all
+testing languages). The transferability of UniSpeech is also demonstrated on a domain-shift speech recognition task,
+i.e., a relative word error rate reduction of 6% against the previous approach.*
+
+This model was contributed by [patrickvonplaten](https://huggingface.co/patrickvonplaten). The Authors' code can be
+found [here](https://github.com/microsoft/UniSpeech/tree/main/UniSpeech).
+
+## Usage tips
+
+- UniSpeech is a speech model that accepts a float array corresponding to the raw waveform of the speech signal. Please
+ use [`Wav2Vec2Processor`] for the feature extraction.
+- UniSpeech model can be fine-tuned using connectionist temporal classification (CTC) so the model output has to be
+ decoded using [`Wav2Vec2CTCTokenizer`].
+
+> [!NOTE]
+> The `head_mask` argument is ignored when using all attention implementation other than "eager". If you have a `head_mask` and want it to have effect, load the model with `XXXModel.from_pretrained(model_id, attn_implementation="eager")`
+
+## Resources
+
+- [Audio classification task guide](../tasks/audio_classification)
+- [Automatic speech recognition task guide](../tasks/asr)
+
+## UniSpeechConfig
+
+[[autodoc]] UniSpeechConfig
+
+## UniSpeech specific outputs
+
+[[autodoc]] models.unispeech.modeling_unispeech.UniSpeechForPreTrainingOutput
+
+## UniSpeechModel
+
+[[autodoc]] UniSpeechModel
+ - forward
+
+## UniSpeechForCTC
+
+[[autodoc]] UniSpeechForCTC
+ - forward
+
+## UniSpeechForSequenceClassification
+
+[[autodoc]] UniSpeechForSequenceClassification
+ - forward
+
+## UniSpeechForPreTraining
+
+[[autodoc]] UniSpeechForPreTraining
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/univnet.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/univnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..e20bc5c405e8caa9eca879c1e481e6c608be4934
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/univnet.md
@@ -0,0 +1,85 @@
+
+*This model was released on 2021-06-15 and added to Hugging Face Transformers on 2023-11-22.*
+
+# UnivNet
+
+
+
+
+
+## Overview
+
+The UnivNet model was proposed in [UnivNet: A Neural Vocoder with Multi-Resolution Spectrogram Discriminators for High-Fidelity Waveform Generation](https://huggingface.co/papers/2106.07889) by Won Jang, Dan Lim, Jaesam Yoon, Bongwan Kin, and Juntae Kim.
+The UnivNet model is a generative adversarial network (GAN) trained to synthesize high fidelity speech waveforms. The UnivNet model shared in `transformers` is the *generator*, which maps a conditioning log-mel spectrogram and optional noise sequence to a speech waveform (e.g. a vocoder). Only the generator is required for inference. The *discriminator* used to train the `generator` is not implemented.
+
+The abstract from the paper is the following:
+
+*Most neural vocoders employ band-limited mel-spectrograms to generate waveforms. If full-band spectral features are used as the input, the vocoder can be provided with as much acoustic information as possible. However, in some models employing full-band mel-spectrograms, an over-smoothing problem occurs as part of which non-sharp spectrograms are generated. To address this problem, we propose UnivNet, a neural vocoder that synthesizes high-fidelity waveforms in real time. Inspired by works in the field of voice activity detection, we added a multi-resolution spectrogram discriminator that employs multiple linear spectrogram magnitudes computed using various parameter sets. Using full-band mel-spectrograms as input, we expect to generate high-resolution signals by adding a discriminator that employs spectrograms of multiple resolutions as the input. In an evaluation on a dataset containing information on hundreds of speakers, UnivNet obtained the best objective and subjective results among competing models for both seen and unseen speakers. These results, including the best subjective score for text-to-speech, demonstrate the potential for fast adaptation to new speakers without a need for training from scratch.*
+
+Tips:
+
+- The `noise_sequence` argument for [`UnivNetModel.forward`] should be standard Gaussian noise (such as from `torch.randn`) of shape `([batch_size], noise_length, model.config.model_in_channels)`, where `noise_length` should match the length dimension (dimension 1) of the `input_features` argument. If not supplied, it will be randomly generated; a `torch.Generator` can be supplied to the `generator` argument so that the forward pass can be reproduced. (Note that [`UnivNetFeatureExtractor`] will return generated noise by default, so it shouldn't be necessary to generate `noise_sequence` manually.)
+- Padding added by [`UnivNetFeatureExtractor`] can be removed from the [`UnivNetModel`] output through the [`UnivNetFeatureExtractor.batch_decode`] method, as shown in the usage example below.
+- Padding the end of each waveform with silence can reduce artifacts at the end of the generated audio sample. This can be done by supplying `pad_end = True` to [`UnivNetFeatureExtractor.__call__`]. See [this issue](https://github.com/seungwonpark/melgan/issues/8) for more details.
+
+Usage Example:
+
+```python
+import torch
+from scipy.io.wavfile import write
+from datasets import Audio, load_dataset
+
+from transformers import UnivNetFeatureExtractor, UnivNetModel
+
+model_id_or_path = "dg845/univnet-dev"
+model = UnivNetModel.from_pretrained(model_id_or_path)
+feature_extractor = UnivNetFeatureExtractor.from_pretrained(model_id_or_path)
+
+ds = load_dataset("hf-internal-testing/librispeech_asr_dummy", "clean", split="validation")
+# Resample the audio to the model and feature extractor's sampling rate.
+ds = ds.cast_column("audio", Audio(sampling_rate=feature_extractor.sampling_rate))
+# Pad the end of the converted waveforms to reduce artifacts at the end of the output audio samples.
+inputs = feature_extractor(
+ ds[0]["audio"]["array"], sampling_rate=ds[0]["audio"]["sampling_rate"], pad_end=True, return_tensors="pt"
+)
+
+with torch.no_grad():
+ audio = model(**inputs)
+
+# Remove the extra padding at the end of the output.
+audio = feature_extractor.batch_decode(**audio)[0]
+# Convert to wav file
+write("sample_audio.wav", feature_extractor.sampling_rate, audio)
+```
+
+This model was contributed by [dg845](https://huggingface.co/dg845).
+To the best of my knowledge, there is no official code release, but an unofficial implementation can be found at [maum-ai/univnet](https://github.com/maum-ai/univnet) with pretrained checkpoints [here](https://github.com/maum-ai/univnet#pre-trained-model).
+
+
+## UnivNetConfig
+
+[[autodoc]] UnivNetConfig
+
+## UnivNetFeatureExtractor
+
+[[autodoc]] UnivNetFeatureExtractor
+ - __call__
+
+## UnivNetModel
+
+[[autodoc]] UnivNetModel
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/upernet.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/upernet.md
new file mode 100644
index 0000000000000000000000000000000000000000..2c2e50fc560d99d095a848b95dedd338282d554b
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/upernet.md
@@ -0,0 +1,84 @@
+
+*This model was released on 2018-07-26 and added to Hugging Face Transformers on 2023-01-16.*
+
+# UPerNet
+
+
+
+
+
+## Overview
+
+The UPerNet model was proposed in [Unified Perceptual Parsing for Scene Understanding](https://huggingface.co/papers/1807.10221)
+by Tete Xiao, Yingcheng Liu, Bolei Zhou, Yuning Jiang, Jian Sun. UPerNet is a general framework to effectively segment
+a wide range of concepts from images, leveraging any vision backbone like [ConvNeXt](convnext) or [Swin](swin).
+
+The abstract from the paper is the following:
+
+*Humans recognize the visual world at multiple levels: we effortlessly categorize scenes and detect objects inside, while also identifying the textures and surfaces of the objects along with their different compositional parts. In this paper, we study a new task called Unified Perceptual Parsing, which requires the machine vision systems to recognize as many visual concepts as possible from a given image. A multi-task framework called UPerNet and a training strategy are developed to learn from heterogeneous image annotations. We benchmark our framework on Unified Perceptual Parsing and show that it is able to effectively segment a wide range of concepts from images. The trained networks are further applied to discover visual knowledge in natural scenes.*
+
+
+
+ UPerNet framework. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code is based on OpenMMLab's mmsegmentation [here](https://github.com/open-mmlab/mmsegmentation/blob/master/mmseg/models/decode_heads/uper_head.py).
+
+## Usage examples
+
+UPerNet is a general framework for semantic segmentation. It can be used with any vision backbone, like so:
+
+```py
+from transformers import SwinConfig, UperNetConfig, UperNetForSemanticSegmentation
+
+backbone_config = SwinConfig(out_features=["stage1", "stage2", "stage3", "stage4"])
+
+config = UperNetConfig(backbone_config=backbone_config)
+model = UperNetForSemanticSegmentation(config)
+```
+
+To use another vision backbone, like [ConvNeXt](convnext), simply instantiate the model with the appropriate backbone:
+
+```py
+from transformers import ConvNextConfig, UperNetConfig, UperNetForSemanticSegmentation
+
+backbone_config = ConvNextConfig(out_features=["stage1", "stage2", "stage3", "stage4"])
+
+config = UperNetConfig(backbone_config=backbone_config)
+model = UperNetForSemanticSegmentation(config)
+```
+
+Note that this will randomly initialize all the weights of the model.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with UPerNet.
+
+- Demo notebooks for UPerNet can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/UPerNet).
+- [`UperNetForSemanticSegmentation`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/semantic-segmentation) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/semantic_segmentation.ipynb).
+- See also: [Semantic segmentation task guide](../tasks/semantic_segmentation)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## UperNetConfig
+
+[[autodoc]] UperNetConfig
+
+## UperNetForSemanticSegmentation
+
+[[autodoc]] UperNetForSemanticSegmentation
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/van.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/van.md
new file mode 100644
index 0000000000000000000000000000000000000000..0e07e314bee979cf180bfcb1e636fd63d9049647
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/van.md
@@ -0,0 +1,77 @@
+
+*This model was released on 2022-02-20 and added to Hugging Face Transformers on 2023-06-20.*
+
+# VAN
+
+
+
+
+
+
+
+This model is in maintenance mode only, we don't accept any new PRs changing its code.
+
+If you run into any issues running this model, please reinstall the last version that supported this model: v4.30.0.
+You can do so by running the following command: `pip install -U transformers==4.30.0`.
+
+
+
+## Overview
+
+The VAN model was proposed in [Visual Attention Network](https://huggingface.co/papers/2202.09741) by Meng-Hao Guo, Cheng-Ze Lu, Zheng-Ning Liu, Ming-Ming Cheng, Shi-Min Hu.
+
+This paper introduces a new attention layer based on convolution operations able to capture both local and distant relationships. This is done by combining normal and large kernel convolution layers. The latter uses a dilated convolution to capture distant correlations.
+
+The abstract from the paper is the following:
+
+*While originally designed for natural language processing tasks, the self-attention mechanism has recently taken various computer vision areas by storm. However, the 2D nature of images brings three challenges for applying self-attention in computer vision. (1) Treating images as 1D sequences neglects their 2D structures. (2) The quadratic complexity is too expensive for high-resolution images. (3) It only captures spatial adaptability but ignores channel adaptability. In this paper, we propose a novel large kernel attention (LKA) module to enable self-adaptive and long-range correlations in self-attention while avoiding the above issues. We further introduce a novel neural network based on LKA, namely Visual Attention Network (VAN). While extremely simple, VAN outperforms the state-of-the-art vision transformers and convolutional neural networks with a large margin in extensive experiments, including image classification, object detection, semantic segmentation, instance segmentation, etc. Code is available at [this https URL](https://github.com/Visual-Attention-Network/VAN-Classification).*
+
+Tips:
+
+- VAN does not have an embedding layer, thus the `hidden_states` will have a length equal to the number of stages.
+
+The figure below illustrates the architecture of a Visual Attention Layer. Taken from the [original paper](https://huggingface.co/papers/2202.09741).
+
+
+
+This model was contributed by [Francesco](https://huggingface.co/Francesco). The original code can be found [here](https://github.com/Visual-Attention-Network/VAN-Classification).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with VAN.
+
+
+
+- [`VanForImageClassification`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/image-classification) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+- See also: [Image classification task guide](../tasks/image_classification)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## VanConfig
+
+[[autodoc]] VanConfig
+
+## VanModel
+
+[[autodoc]] VanModel
+ - forward
+
+## VanForImageClassification
+
+[[autodoc]] VanForImageClassification
+ - forward
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/video_llava.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/video_llava.md
new file mode 100644
index 0000000000000000000000000000000000000000..bda72643694194415cdb1cfaab7a6ca148aea3c5
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/video_llava.md
@@ -0,0 +1,231 @@
+
+*This model was released on 2023-11-16 and added to Hugging Face Transformers on 2024-05-15.*
+
+# Video-LLaVA
+
+
+
+
+
+
+
+## Overview
+
+Video-LLaVa is an open-source multimodal LLM trained by fine-tuning LlamA/Vicuna on multimodal instruction-following data generated by Llava1.5 and VideChat. It is an auto-regressive language model, based on the transformer architecture. Video-LLaVa unifies visual representations to the language feature space, and enables an LLM to perform visual reasoning capabilities on both images and videos simultaneously.
+
+
+The Video-LLaVA model was proposed in [Video-LLaVA: Learning United Visual Representation by Alignment Before Projection](https://huggingface.co/papers/2311.10122) by Bin Lin, Yang Ye, Bin Zhu, Jiaxi Cui, Munang Ning, Peng Jin, Li Yuan.
+
+The abstract from the paper is the following:
+
+*The Large Vision-Language Model (LVLM) has enhanced the performance of various downstream tasks in
+visual-language understanding. Most existing approaches
+encode images and videos into separate feature spaces,
+which are then fed as inputs to large language models.
+However, due to the lack of unified tokenization for images and videos, namely misalignment before projection, it
+becomes challenging for a Large Language Model (LLM)
+to learn multi-modal interactions from several poor projection layers. In this work, we unify visual representation into the language feature space to advance the foundational LLM towards a unified LVLM. As a result, we establish a simple but robust LVLM baseline, Video-LLaVA,
+which learns from a mixed dataset of images and videos,
+mutually enhancing each other. Video-LLaVA achieves superior performances on a broad range of 9 image benchmarks across 5 image question-answering datasets and 4
+image benchmark toolkits. Additionally, our Video-LLaVA
+also outperforms Video-ChatGPT by 5.8%, 9.9%, 18.6%,
+and 10.1% on MSRVTT, MSVD, TGIF, and ActivityNet, respectively. Notably, extensive experiments demonstrate that
+Video-LLaVA mutually benefits images and videos within
+a unified visual representation, outperforming models designed specifically for images or videos. We aim for this
+work to provide modest insights into the multi-modal inputs
+for the LLM*
+
+## Usage tips:
+
+- We advise users to use padding_side="left" when computing batched generation as it leads to more accurate results. Simply make sure to call processor.tokenizer.padding_side = "left" before generating.
+
+- Note the model has not been explicitly trained to process multiple images/videos in the same prompt, although this is technically possible, you may experience inaccurate results.
+
+- Note that the video inputs should have exactly 8 frames at the input, since the models were trained in that setting.
+
+This model was contributed by [RaushanTurganbay](https://huggingface.co/RaushanTurganbay).
+The original code can be found [here](https://github.com/PKU-YuanGroup/Video-LLaVA).
+
+
+> [!NOTE]
+> LLaVA models after release v4.46 will raise warnings about adding `processor.patch_size = {{patch_size}}`, `processor.num_additional_image_tokens = {{num_additional_image_tokens}}` and processor.vision_feature_select_strategy = {{vision_feature_select_strategy}}`. It is strongly recommended to add the attributes to the processor if you own the model checkpoint, or open a PR if it is not owned by you.
+Adding these attributes means that LLaVA will try to infer the number of image tokens required per image and expand the text with as many `` placeholders as there will be tokens. Usually it is around 500 tokens per image, so make sure that the text is not truncated as otherwise there will be failure when merging the embeddings.
+The attributes can be obtained from model config, as `model.config.vision_config.patch_size` or `model.config.vision_feature_select_strategy`. The `num_additional_image_tokens` should be `1` if the vision backbone adds a CLS token or `0` if nothing extra is added to the vision patches.
+
+
+## Usage example
+
+### Single Media Mode
+
+The model can accept both images and videos as input. Here's an example code for inference in half-precision (`torch.float16`):
+
+```python
+import av
+import torch
+import numpy as np
+from transformers import VideoLlavaForConditionalGeneration, VideoLlavaProcessor
+
+def read_video_pyav(container, indices):
+ '''
+ Decode the video with PyAV decoder.
+ Args:
+ container (`av.container.input.InputContainer`): PyAV container.
+ indices (`list[int]`): List of frame indices to decode.
+ Returns:
+ result (np.ndarray): np array of decoded frames of shape (num_frames, height, width, 3).
+ '''
+ frames = []
+ container.seek(0)
+ start_index = indices[0]
+ end_index = indices[-1]
+ for i, frame in enumerate(container.decode(video=0)):
+ if i > end_index:
+ break
+ if i >= start_index and i in indices:
+ frames.append(frame)
+ return np.stack([x.to_ndarray(format="rgb24") for x in frames])
+
+# Load the model in half-precision
+model = VideoLlavaForConditionalGeneration.from_pretrained("LanguageBind/Video-LLaVA-7B-hf", torch_dtype=torch.float16, device_map="auto")
+processor = VideoLlavaProcessor.from_pretrained("LanguageBind/Video-LLaVA-7B-hf")
+
+# Load the video as an np.arrau, sampling uniformly 8 frames
+video_path = hf_hub_download(repo_id="raushan-testing-hf/videos-test", filename="sample_demo_1.mp4", repo_type="dataset")
+container = av.open(video_path)
+total_frames = container.streams.video[0].frames
+indices = np.arange(0, total_frames, total_frames / 8).astype(int)
+video = read_video_pyav(container, indices)
+
+# For better results, we recommend to prompt the model in the following format
+prompt = "USER:
+
+
+```py
+import torch
+from transformers import TorchAoConfig, AutoModelForCausalLM, AutoTokenizer
+from torchao.quantization import Int4WeightOnlyConfig
+from torchao.dtypes import MarlinSparseLayout
+
+quant_config = Int4WeightOnlyConfig(layout=MarlinSparseLayout())
+quantization_config = TorchAoConfig(quant_type=quant_config)
+
+# Load and quantize the model with sparsity. A sparse checkpoint is needed to accelerate without accuracy loss
+quantized_model = AutoModelForCausalLM.from_pretrained(
+ "RedHatAI/Sparse-Llama-3.1-8B-2of4",
+ torch_dtype=torch.float16,
+ device_map="cuda",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained("RedHatAI/Sparse-Llama-3.1-8B-2of4")
+input_text = "What are we having for dinner?"
+input_ids = tokenizer(input_text, return_tensors="pt").to("cuda")
+
+# auto-compile the quantized model with `cache_implementation="static"` to get speed up
+output = quantized_model.generate(**input_ids, max_new_tokens=10, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+### A100 GPU
+
+
+
+```py
+import torch
+from transformers import TorchAoConfig, AutoModelForCausalLM, AutoTokenizer
+from torchao.quantization import Int8DynamicActivationInt8WeightConfig, Int8WeightOnlyConfig
+
+quant_config = Int8DynamicActivationInt8WeightConfig()
+# or int8 weight only quantization
+# quant_config = Int8WeightOnlyConfig()
+quantization_config = TorchAoConfig(quant_type=quant_config)
+
+# Load and quantize the model
+quantized_model = AutoModelForCausalLM.from_pretrained(
+ "meta-llama/Llama-3.1-8B-Instruct",
+ torch_dtype="auto",
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained("meta-llama/Llama-3.1-8B-Instruct")
+input_text = "What are we having for dinner?"
+input_ids = tokenizer(input_text, return_tensors="pt").to("cuda")
+
+# auto-compile the quantized model with `cache_implementation="static"` to get speed up
+output = quantized_model.generate(**input_ids, max_new_tokens=10, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```py
+import torch
+from transformers import TorchAoConfig, AutoModelForCausalLM, AutoTokenizer
+from torchao.quantization import GemliteUIntXWeightOnlyConfig, Int4WeightOnlyConfig
+
+# For batch size N, we recommend gemlite, which may require autotuning
+# default is 4 bit, 8 bit is also supported by passing `bit_width=8`
+quant_config = GemliteUIntXWeightOnlyConfig(group_size=128)
+
+# For batch size 1, we also have custom tinygemm kernel that's only optimized for this
+# We can set `use_hqq` to `True` for better accuracy
+# quant_config = Int4WeightOnlyConfig(group_size=128, use_hqq=True)
+
+quantization_config = TorchAoConfig(quant_type=quant_config)
+
+# Load and quantize the model
+quantized_model = AutoModelForCausalLM.from_pretrained(
+ "meta-llama/Llama-3.1-8B-Instruct",
+ torch_dtype="auto",
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained("meta-llama/Llama-3.1-8B-Instruct")
+input_text = "What are we having for dinner?"
+input_ids = tokenizer(input_text, return_tensors="pt").to("cuda")
+
+# auto-compile the quantized model with `cache_implementation="static"` to get speed up
+output = quantized_model.generate(**input_ids, max_new_tokens=10, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+
+
+```py
+import torch
+from transformers import TorchAoConfig, AutoModelForCausalLM, AutoTokenizer
+from torchao.quantization import Int4WeightOnlyConfig
+from torchao.dtypes import MarlinSparseLayout
+
+quant_config = Int4WeightOnlyConfig(layout=MarlinSparseLayout())
+quantization_config = TorchAoConfig(quant_type=quant_config)
+
+# Load and quantize the model with sparsity. A sparse checkpoint is needed to accelerate without accuracy loss
+quantized_model = AutoModelForCausalLM.from_pretrained(
+ "RedHatAI/Sparse-Llama-3.1-8B-2of4",
+ torch_dtype=torch.float16,
+ device_map="cuda",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained("RedHatAI/Sparse-Llama-3.1-8B-2of4")
+input_text = "What are we having for dinner?"
+input_ids = tokenizer(input_text, return_tensors="pt").to("cuda")
+
+# auto-compile the quantized model with `cache_implementation="static"` to get speed up
+output = quantized_model.generate(**input_ids, max_new_tokens=10, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+### Intel XPU
+
+
+
+```py
+import torch
+from transformers import TorchAoConfig, AutoModelForCausalLM, AutoTokenizer
+from torchao.quantization import Int8DynamicActivationInt8WeightConfig, Int8WeightOnlyConfig
+
+quant_config = Int8DynamicActivationInt8WeightConfig()
+# or int8 weight only quantization
+# quant_config = Int8WeightOnlyConfig()
+quantization_config = TorchAoConfig(quant_type=quant_config)
+
+# Load and quantize the model
+quantized_model = AutoModelForCausalLM.from_pretrained(
+ "meta-llama/Llama-3.1-8B-Instruct",
+ torch_dtype="auto",
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained("meta-llama/Llama-3.1-8B-Instruct")
+input_text = "What are we having for dinner?"
+input_ids = tokenizer(input_text, return_tensors="pt").to("xpu")
+
+# auto-compile the quantized model with `cache_implementation="static"` to get speed up
+output = quantized_model.generate(**input_ids, max_new_tokens=10, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+```py
+import torch
+from transformers import TorchAoConfig, AutoModelForCausalLM, AutoTokenizer
+from torchao.quantization import Int4WeightOnlyConfig
+from torchao.dtypes import Int4XPULayout
+from torchao.quantization.quant_primitives import ZeroPointDomain
+
+
+quant_config = Int4WeightOnlyConfig(group_size=128, layout=Int4XPULayout(), zero_point_domain=ZeroPointDomain.INT)
+quantization_config = TorchAoConfig(quant_type=quant_config)
+
+# Load and quantize the model
+quantized_model = AutoModelForCausalLM.from_pretrained(
+ "meta-llama/Llama-3.1-8B-Instruct",
+ torch_dtype="auto",
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained("meta-llama/Llama-3.1-8B-Instruct")
+input_text = "What are we having for dinner?"
+input_ids = tokenizer(input_text, return_tensors="pt").to("xpu")
+
+# auto-compile the quantized model with `cache_implementation="static"` to get speed up
+output = quantized_model.generate(**input_ids, max_new_tokens=10, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+
+### CPU
+
+
+
+```py
+import torch
+from transformers import TorchAoConfig, AutoModelForCausalLM, AutoTokenizer
+from torchao.quantization import Int8DynamicActivationInt8WeightConfig, Int8WeightOnlyConfig
+
+quant_config = Int8DynamicActivationInt8WeightConfig()
+# quant_config = Int8WeightOnlyConfig()
+quantization_config = TorchAoConfig(quant_type=quant_config)
+
+# Load and quantize the model
+quantized_model = AutoModelForCausalLM.from_pretrained(
+ "meta-llama/Llama-3.1-8B-Instruct",
+ torch_dtype="auto",
+ device_map="cpu",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained("meta-llama/Llama-3.1-8B-Instruct")
+input_text = "What are we having for dinner?"
+input_ids = tokenizer(input_text, return_tensors="pt")
+
+# auto-compile the quantized model with `cache_implementation="static"` to get speed up
+output = quantized_model.generate(**input_ids, max_new_tokens=10, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+> [!TIP]
+> Run the quantized model on a CPU by changing `device_map` to `"cpu"` and `layout` to `Int4CPULayout()`.
+
+```py
+import torch
+from transformers import TorchAoConfig, AutoModelForCausalLM, AutoTokenizer
+from torchao.quantization import Int4WeightOnlyConfig
+from torchao.dtypes import Int4CPULayout
+
+quant_config = Int4WeightOnlyConfig(group_size=128, layout=Int4CPULayout())
+quantization_config = TorchAoConfig(quant_type=quant_config)
+
+# Load and quantize the model
+quantized_model = AutoModelForCausalLM.from_pretrained(
+ "meta-llama/Llama-3.1-8B-Instruct",
+ torch_dtype="auto",
+ device_map="cpu",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained("meta-llama/Llama-3.1-8B-Instruct")
+input_text = "What are we having for dinner?"
+input_ids = tokenizer(input_text, return_tensors="pt")
+
+# auto-compile the quantized model with `cache_implementation="static"` to get speed up
+output = quantized_model.generate(**input_ids, max_new_tokens=10, cache_implementation="static")
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+
+### Per Module Quantization
+#### 1. Skip quantization for certain layers
+With `ModuleFqnToConfig` we can specify a default configuration for all layers while skipping quantization for certain layers.
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, TorchAoConfig
+
+model_id = "meta-llama/Llama-3.1-8B-Instruct"
+
+from torchao.quantization import Int4WeightOnlyConfig, ModuleFqnToConfig
+config = Int4WeightOnlyConfig(group_size=128)
+
+# set default to int4 (for linears), and skip quantizing `model.layers.0.self_attn.q_proj`
+quant_config = ModuleFqnToConfig({"_default": config, "model.layers.0.self_attn.q_proj": None})
+quantization_config = TorchAoConfig(quant_type=quant_config)
+quantized_model = AutoModelForCausalLM.from_pretrained(model_id, device_map="auto", torch_dtype=torch.bfloat16, quantization_config=quantization_config)
+# lm_head is not quantized and model.layers.0.self_attn.q_proj is not quantized
+print("quantized model:", quantized_model)
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+
+# Manual Testing
+prompt = "Hey, are you conscious? Can you talk to me?"
+inputs = tokenizer(prompt, return_tensors="pt").to(quantized_model.device.type)
+generated_ids = quantized_model.generate(**inputs, max_new_tokens=128)
+output_text = tokenizer.batch_decode(
+ generated_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False
+)
+print(output_text)
+```
+
+#### 2. Quantizing different layers with different quantization configs
+```py
+import torch
+from transformers import AutoModelForCausalLM, AutoTokenizer, TorchAoConfig
+
+model_id = "facebook/opt-125m"
+
+from torchao.quantization import Int4WeightOnlyConfig, ModuleFqnToConfig, Int8DynamicActivationInt4WeightConfig, IntxWeightOnlyConfig, PerAxis, MappingType
+
+weight_dtype = torch.int8
+granularity = PerAxis(0)
+mapping_type = MappingType.ASYMMETRIC
+embedding_config = IntxWeightOnlyConfig(
+ weight_dtype=weight_dtype,
+ granularity=granularity,
+ mapping_type=mapping_type,
+)
+linear_config = Int8DynamicActivationInt4WeightConfig(group_size=128)
+quant_config = ModuleFqnToConfig({"_default": linear_config, "model.decoder.embed_tokens": embedding_config, "model.decoder.embed_positions": None})
+# set `include_embedding` to True in order to include embedding in quantization
+# when `include_embedding` is True, we'll remove input embedding from `modules_not_to_convert` as well
+quantization_config = TorchAoConfig(quant_type=quant_config, include_embedding=True)
+quantized_model = AutoModelForCausalLM.from_pretrained(model_id, device_map="cpu", torch_dtype=torch.bfloat16, quantization_config=quantization_config)
+print("quantized model:", quantized_model)
+# make sure embedding is quantized
+print("embed_tokens weight:", quantized_model.model.decoder.embed_tokens.weight)
+tokenizer = AutoTokenizer.from_pretrained(model_id)
+
+# Manual Testing
+prompt = "Hey, are you conscious? Can you talk to me?"
+inputs = tokenizer(prompt, return_tensors="pt").to("cpu")
+generated_ids = quantized_model.generate(**inputs, max_new_tokens=128, cache_implementation="static")
+output_text = tokenizer.batch_decode(
+ generated_ids, skip_special_tokens=True, clean_up_tokenization_spaces=False
+)
+print(output_text)
+```
+
+### Autoquant
+
+If you want to automatically choose a quantization type for quantizable layers (`nn.Linear`) you can use the [autoquant](https://pytorch.org/ao/stable/generated/torchao.quantization.autoquant.html#torchao.quantization.autoquant) API.
+
+The `autoquant` API automatically chooses a quantization type by micro-benchmarking on input type and shape and compiling a single linear layer.
+
+Note: autoquant is for GPU only right now.
+
+Create a [`TorchAoConfig`] and set to `"autoquant"`. Set the `cache_implementation` to `"static"` to automatically [torch.compile](https://pytorch.org/tutorials/intermediate/torch_compile_tutorial.html) the forward method. Finally, call `finalize_autoquant` on the quantized model to finalize the quantization and log the input shapes.
+
+
+```py
+import torch
+from transformers import TorchAoConfig, AutoModelForCausalLM, AutoTokenizer
+
+quantization_config = TorchAoConfig("autoquant", min_sqnr=None)
+quantized_model = AutoModelForCausalLM.from_pretrained(
+ "meta-llama/Llama-3.1-8B-Instruct",
+ torch_dtype="auto",
+ device_map="auto",
+ quantization_config=quantization_config
+)
+
+tokenizer = AutoTokenizer.from_pretrained("meta-llama/Llama-3.1-8B-Instruct")
+input_text = "What are we having for dinner?"
+input_ids = tokenizer(input_text, return_tensors="pt").to(quantized_model.device.type)
+
+# auto-compile the quantized model with `cache_implementation="static"` to get speed up
+output = quantized_model.generate(**input_ids, max_new_tokens=10, cache_implementation="static")
+# explicitly call `finalize_autoquant` (may be refactored and removed in the future)
+quantized_model.finalize_autoquant()
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+```
+
+
+## Serialization
+
+torchao implements [torch.Tensor subclasses](https://pytorch.org/docs/stable/notes/extending.html#subclassing-torch-tensor) for maximum flexibility in supporting new quantized torch.Tensor formats. [Safetensors](https://huggingface.co/docs/safetensors/en/index) serialization and deserialization does not work with torchao.
+
+To avoid arbitrary user code execution, torchao sets `weights_only=True` in [torch.load](https://pytorch.org/docs/stable/generated/torch.load.html) to ensure only tensors are loaded. Any known user functions can be whitelisted with [add_safe_globals](https://pytorch.org/docs/stable/notes/serialization.html#torch.serialization.add_safe_globals).
+
+
+
+
+```py
+# don't serialize model with Safetensors
+output_dir = "llama3-8b-int4wo-128"
+quantized_model.save_pretrained("llama3-8b-int4wo-128", safe_serialization=False)
+```
+
+
+
+```py
+# don't serialize model with Safetensors
+USER_ID = "your_huggingface_user_id"
+REPO_ID = "llama3-8b-int4wo-128"
+quantized_model.push_to_hub(f"{USER_ID}/llama3-8b-int4wo-128", safe_serialization=False)
+tokenizer.push_to_hub(f"{USER_ID}/llama3-8b-int4wo-128")
+```
+
+
+
+
+## Loading quantized models
+
+Loading a quantized model depends on the quantization scheme. For quantization schemes, like int8 and float8, you can quantize the model on any device and also load it on any device. The example below demonstrates quantizing a model on the CPU and then loading it on CUDA or XPU.
+```py
+import torch
+from transformers import TorchAoConfig, AutoModelForCausalLM, AutoTokenizer
+from torchao.quantization import Int8WeightOnlyConfig
+
+quant_config = Int8WeightOnlyConfig(group_size=128)
+quantization_config = TorchAoConfig(quant_type=quant_config)
+
+# Load and quantize the model
+quantized_model = AutoModelForCausalLM.from_pretrained(
+ "meta-llama/Llama-3.1-8B-Instruct",
+ torch_dtype="auto",
+ device_map="cpu",
+ quantization_config=quantization_config
+)
+# save the quantized model
+output_dir = "llama-3.1-8b-torchao-int8"
+quantized_model.save_pretrained(output_dir, safe_serialization=False)
+
+# reload the quantized model
+reloaded_model = AutoModelForCausalLM.from_pretrained(
+ output_dir,
+ device_map="auto",
+ torch_dtype=torch.bfloat16
+)
+tokenizer = AutoTokenizer.from_pretrained("meta-llama/Llama-3.1-8B-Instruct")
+input_text = "What are we having for dinner?"
+input_ids = tokenizer(input_text, return_tensors="pt").to(reloaded_model.device.type)
+
+output = reloaded_model.generate(**input_ids, max_new_tokens=10)
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+
+```
+For int4, the model can only be loaded on the same device it was quantized on because the layout is specific to the device. The example below demonstrates quantizing and loading a model on the CPU.
+
+```py
+import torch
+from transformers import TorchAoConfig, AutoModelForCausalLM, AutoTokenizer
+from torchao.quantization import Int4WeightOnlyConfig
+from torchao.dtypes import Int4CPULayout
+
+quant_config = Int4WeightOnlyConfig(group_size=128, layout=Int4CPULayout())
+quantization_config = TorchAoConfig(quant_type=quant_config)
+
+# Load and quantize the model
+quantized_model = AutoModelForCausalLM.from_pretrained(
+ "meta-llama/Llama-3.1-8B-Instruct",
+ torch_dtype="auto",
+ device_map="cpu",
+ quantization_config=quantization_config
+)
+# save the quantized model
+output_dir = "llama-3.1-8b-torchao-int4-cpu"
+quantized_model.save_pretrained(output_dir, safe_serialization=False)
+
+# reload the quantized model
+reloaded_model = AutoModelForCausalLM.from_pretrained(
+ output_dir,
+ device_map="cpu",
+ torch_dtype=torch.bfloat16
+)
+tokenizer = AutoTokenizer.from_pretrained("meta-llama/Llama-3.1-8B-Instruct")
+input_text = "What are we having for dinner?"
+input_ids = tokenizer(input_text, return_tensors="pt")
+
+output = reloaded_model.generate(**input_ids, max_new_tokens=10)
+print(tokenizer.decode(output[0], skip_special_tokens=True))
+
+```
+
+## ⚠️ Deprecation Notice
+
+> Starting with version 0.10.0, the string-based API for quantization configuration (e.g., `TorchAoConfig("int4_weight_only", group_size=128)`) is **deprecated** and will be removed in a future release.
+>
+> Please use the new `AOBaseConfig`-based approach instead:
+>
+> ```python
+> # Old way (deprecated)
+> quantization_config = TorchAoConfig("int4_weight_only", group_size=128)
+>
+> # New way (recommended)
+> from torchao.quantization import Int4WeightOnlyConfig
+> quant_config = Int4WeightOnlyConfig(group_size=128)
+> quantization_config = TorchAoConfig(quant_type=quant_config)
+> ```
+>
+> The new API offers greater flexibility, better type safety, and access to the full range of features available in torchao.
+>
+> [Migration Guide](#migration-guide)
+>
+> Here's how to migrate from common string identifiers to their `AOBaseConfig` equivalents:
+>
+> | Old String API | New `AOBaseConfig` API |
+> |----------------|------------------------|
+> | `"int4_weight_only"` | `Int4WeightOnlyConfig()` |
+> | `"int8_weight_only"` | `Int8WeightOnlyConfig()` |
+> | `"int8_dynamic_activation_int8_weight"` | `Int8DynamicActivationInt8WeightConfig()` |
+>
+> All configuration objects accept parameters for customization (e.g., `group_size`, `scheme`, `layout`).
+
+
+
+## Resources
+
+For a better sense of expected performance, view the [benchmarks](https://github.com/pytorch/ao/tree/main/torchao/quantization#benchmarks) for various models with CUDA and XPU backends. You can also run the code below to benchmark a model yourself.
+
+```py
+from torch._inductor.utils import do_bench_using_profiling
+from typing import Callable
+
+def benchmark_fn(func: Callable, *args, **kwargs) -> float:
+ """Thin wrapper around do_bench_using_profiling"""
+ no_args = lambda: func(*args, **kwargs)
+ time = do_bench_using_profiling(no_args)
+ return time * 1e3
+
+MAX_NEW_TOKENS = 1000
+print("int4wo-128 model:", benchmark_fn(quantized_model.generate, **input_ids, max_new_tokens=MAX_NEW_TOKENS, cache_implementation="static"))
+
+bf16_model = AutoModelForCausalLM.from_pretrained(model_name, device_map="auto", torch_dtype=torch.bfloat16)
+output = bf16_model.generate(**input_ids, max_new_tokens=10, cache_implementation="static") # auto-compile
+print("bf16 model:", benchmark_fn(bf16_model.generate, **input_ids, max_new_tokens=MAX_NEW_TOKENS, cache_implementation="static"))
+```
+
+> [!TIP]
+> For best performance, you can use recommended settings by calling `torchao.quantization.utils.recommended_inductor_config_setter()`
+
+Refer to [Other Available Quantization Techniques](https://github.com/pytorch/ao/tree/main/torchao/quantization#other-available-quantization-techniques) for more examples and documentation.
+
+## Issues
+
+If you encounter any issues with the Transformers integration, please open an issue on the [Transformers](https://github.com/huggingface/transformers/issues) repository. For issues directly related to torchao, please open an issue on the [torchao](https://github.com/pytorch/ao/issues) repository.
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/quantization/vptq.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/quantization/vptq.md
new file mode 100644
index 0000000000000000000000000000000000000000..392895e0ea14f54d6cb9bf8469f587d0f8a56e1d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/quantization/vptq.md
@@ -0,0 +1,72 @@
+
+
+# VPTQ
+
+[Vector Post-Training Quantization (VPTQ)](https://github.com/microsoft/VPTQ) is a Post-Training Quantization (PTQ) method that leverages vector quantization to quantize LLMs at an extremely low bit-width (<2-bit). VPTQ can compress a 70B, even a 405B model, to 1-2 bits without retraining and still maintain a high-degree of accuracy. It is a lightweight quantization algorithm that takes ~17 hours to quantize a 405B model. VPTQ features agile quantization inference with low decoding overhead and high throughput and Time To First Token (TTFT).
+
+Run the command below to install VPTQ which provides efficient kernels for inference on NVIDIA and AMD GPUs.
+
+```bash
+pip install vptq
+```
+
+The [VPTQ-community](https://huggingface.co/VPTQ-community) provides a collection of VPTQ-quantized models. The model name contains information about its bitwidth (excluding cookbook, parameter, and padding overhead). Consider the [Meta-Llama-3.1-70B-Instruct-v8-k65536-256-woft] model as an example.
+
+- The model name is Meta-Llama-3.1-70B-Instruct.
+- The number of centroids is given by 65536 (2^16).
+- The number of residual centroids is given by 256 (2^8).
+
+The equivalent bit-width calculation is given by the following.
+
+- index: log2(65536) = 16 / 8 = 2-bits
+- residual index: log2(256) = 8 / 8 = 1-bit
+- total bit-width: 2 + 1 = 3-bits
+
+From here, estimate the model size by multiplying 70B * 3-bits / 8-bits/byte for a total of 26.25GB.
+
+Load a VPTQ quantized model with [`~PreTrainedModel.from_pretrained`].
+
+```py
+from transformers import AutoTokenizer, AutoModelForCausalLM
+
+quantized_model = AutoModelForCausalLM.from_pretrained(
+ "VPTQ-community/Meta-Llama-3.1-70B-Instruct-v16-k65536-65536-woft",
+ torch_dtype="auto",
+ device_map="auto"
+)
+```
+
+To quantize your own model, refer to the [VPTQ Quantization Algorithm Tutorial](https://github.com/microsoft/VPTQ/blob/algorithm/algorithm.md) tutorial.
+
+## Benchmarks
+
+VPTQ achieves better accuracy and higher throughput with lower quantization overhead across models of different sizes. The following experimental results are for reference only; VPTQ can achieve better outcomes under reasonable parameters, especially in terms of model accuracy and inference speed.
+
+| Model | bitwidth | W2↓ | C4↓ | AvgQA↑ | tok/s↑ | mem(GB) | cost/h↓ |
+| ----------- | -------- | ---- | ---- | ------ | ------ | ------- | ------- |
+| LLaMA-2 7B | 2.02 | 6.13 | 8.07 | 58.2 | 39.9 | 2.28 | 2 |
+| | 2.26 | 5.95 | 7.87 | 59.4 | 35.7 | 2.48 | 3.1 |
+| LLaMA-2 13B | 2.02 | 5.32 | 7.15 | 62.4 | 26.9 | 4.03 | 3.2 |
+| | 2.18 | 5.28 | 7.04 | 63.1 | 18.5 | 4.31 | 3.6 |
+| LLaMA-2 70B | 2.07 | 3.93 | 5.72 | 68.6 | 9.7 | 19.54 | 19 |
+| | 2.11 | 3.92 | 5.71 | 68.7 | 9.7 | 20.01 | 19 |
+
+## Resources
+
+See an example demo of VPTQ on the VPTQ Online Demo [Space](https://huggingface.co/spaces/microsoft/VPTQ) or try running the VPTQ inference [notebook](https://colab.research.google.com/github/microsoft/VPTQ/blob/main/notebooks/vptq_example.ipynb).
+
+For more information, read the VPTQ [paper](https://huggingface.co/papers/2409.17066).
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/quicktour.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/quicktour.md
new file mode 100644
index 0000000000000000000000000000000000000000..18e273651c1f128b94f65caa978af35eeec8642a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/quicktour.md
@@ -0,0 +1,361 @@
+
+
+# Quickstart
+
+[[open-in-colab]]
+
+Transformers is designed to be fast and easy to use so that everyone can start learning or building with transformer models.
+
+The number of user-facing abstractions is limited to only three classes for instantiating a model, and two APIs for inference or training. This quickstart introduces you to Transformers' key features and shows you how to:
+
+- load a pretrained model
+- run inference with [`Pipeline`]
+- fine-tune a model with [`Trainer`]
+
+## Set up
+
+To start, we recommend creating a Hugging Face [account](https://hf.co/join). An account lets you host and access version controlled models, datasets, and [Spaces](https://hf.co/spaces) on the Hugging Face [Hub](https://hf.co/docs/hub/index), a collaborative platform for discovery and building.
+
+Create a [User Access Token](https://hf.co/docs/hub/security-tokens#user-access-tokens) and log in to your account.
+
+
+
+
+Paste your User Access Token into [`~huggingface_hub.notebook_login`] when prompted to log in.
+
+```py
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+
+
+
+Make sure the [huggingface_hub[cli]](https://huggingface.co/docs/huggingface_hub/guides/cli#getting-started) package is installed and run the command below. Paste your User Access Token when prompted to log in.
+
+```bash
+hf auth login
+```
+
+
+
+
+Install a machine learning framework.
+
+
+
+
+```bash
+!pip install torch
+```
+
+
+
+
+```bash
+!pip install tensorflow
+```
+
+
+
+
+Then install an up-to-date version of Transformers and some additional libraries from the Hugging Face ecosystem for accessing datasets and vision models, evaluating training, and optimizing training for large models.
+
+```bash
+!pip install -U transformers datasets evaluate accelerate timm
+```
+
+## Pretrained models
+
+Each pretrained model inherits from three base classes.
+
+| **Class** | **Description** |
+|---|---|
+| [`PretrainedConfig`] | A file that specifies a models attributes such as the number of attention heads or vocabulary size. |
+| [`PreTrainedModel`] | A model (or architecture) defined by the model attributes from the configuration file. A pretrained model only returns the raw hidden states. For a specific task, use the appropriate model head to convert the raw hidden states into a meaningful result (for example, [`LlamaModel`] versus [`LlamaForCausalLM`]). |
+| Preprocessor | A class for converting raw inputs (text, images, audio, multimodal) into numerical inputs to the model. For example, [`PreTrainedTokenizer`] converts text into tensors and [`ImageProcessingMixin`] converts pixels into tensors. |
+
+We recommend using the [AutoClass](./model_doc/auto) API to load models and preprocessors because it automatically infers the appropriate architecture for each task and machine learning framework based on the name or path to the pretrained weights and configuration file.
+
+Use [`~PreTrainedModel.from_pretrained`] to load the weights and configuration file from the Hub into the model and preprocessor class.
+
+
+
+
+When you load a model, configure the following parameters to ensure the model is optimally loaded.
+
+- `device_map="auto"` automatically allocates the model weights to your fastest device first.
+- `torch_dtype="auto"` directly initializes the model weights in the data type they're stored in, which can help avoid loading the weights twice (PyTorch loads weights in `torch.float32` by default).
+
+```py
+from transformers import AutoModelForCausalLM, AutoTokenizer
+
+model = AutoModelForCausalLM.from_pretrained("meta-llama/Llama-2-7b-hf", torch_dtype="auto", device_map="auto")
+tokenizer = AutoTokenizer.from_pretrained("meta-llama/Llama-2-7b-hf")
+```
+
+Tokenize the text and return PyTorch tensors with the tokenizer. Move the model to an accelerator if it's available to accelerate inference.
+
+```py
+model_inputs = tokenizer(["The secret to baking a good cake is "], return_tensors="pt").to(model.device)
+```
+
+The model is now ready for inference or training.
+
+For inference, pass the tokenized inputs to [`~GenerationMixin.generate`] to generate text. Decode the token ids back into text with [`~PreTrainedTokenizerBase.batch_decode`].
+
+```py
+generated_ids = model.generate(**model_inputs, max_length=30)
+tokenizer.batch_decode(generated_ids)[0]
+' The secret to baking a good cake is 100% in the preparation. There are so many recipes out there,'
+```
+
+
+
+
+```py
+from transformers import TFAutoModelForCausalLM, AutoTokenizer
+
+model = TFAutoModelForCausalLM.from_pretrained("openai-community/gpt2-xl")
+tokenizer = AutoTokenizer.from_pretrained("openai-community/gpt2-xl")
+```
+
+Tokenize the text and return TensorFlow tensors with the tokenizer.
+
+```py
+model_inputs = tokenizer(["The secret to baking a good cake is "], return_tensors="tf")
+```
+
+The model is now ready for inference or training.
+
+For inference, pass the tokenized inputs to [`~GenerationMixin.generate`] to generate text. Decode the token ids back into text with [`~PreTrainedTokenizerBase.batch_decode`].
+
+```py
+generated_ids = model.generate(**model_inputs, max_length=30)
+tokenizer.batch_decode(generated_ids)[0]
+'The secret to baking a good cake is \xa0to use the right ingredients. \xa0The secret to baking a good cake is to use the right'
+```
+
+
+
+
+> [!TIP]
+> Skip ahead to the [Trainer](#trainer-api) section to learn how to fine-tune a model.
+
+## Pipeline
+
+The [`Pipeline`] class is the most convenient way to inference with a pretrained model. It supports many tasks such as text generation, image segmentation, automatic speech recognition, document question answering, and more.
+
+> [!TIP]
+> Refer to the [Pipeline](./main_classes/pipelines) API reference for a complete list of available tasks.
+
+Create a [`Pipeline`] object and select a task. By default, [`Pipeline`] downloads and caches a default pretrained model for a given task. Pass the model name to the `model` parameter to choose a specific model.
+
+
+
+
+Use [`~infer_device`] to automatically detect an available accelerator for inference.
+
+```py
+from transformers import pipeline, infer_device
+
+device = infer_device()
+
+pipeline = pipeline("text-generation", model="meta-llama/Llama-2-7b-hf", device=device)
+```
+
+Prompt [`Pipeline`] with some initial text to generate more text.
+
+```py
+pipeline("The secret to baking a good cake is ", max_length=50)
+[{'generated_text': 'The secret to baking a good cake is 100% in the batter. The secret to a great cake is the icing.\nThis is why we’ve created the best buttercream frosting reci'}]
+```
+
+
+
+
+Use [`~infer_device`] to automatically detect an available accelerator for inference.
+
+```py
+from transformers import pipeline, infer_device
+
+device = infer_device()
+
+pipeline = pipeline("image-segmentation", model="facebook/detr-resnet-50-panoptic", device=device)
+```
+
+Pass an image - a URL or local path to the image - to [`Pipeline`].
+
+
+
+
+
+```py
+segments = pipeline("https://huggingface.co/datasets/Narsil/image_dummy/raw/main/parrots.png")
+segments[0]["label"]
+'bird'
+segments[1]["label"]
+'bird'
+```
+
+
+
+
+Use [`~infer_device`] to automatically detect an available accelerator for inference.
+
+```py
+from transformers import pipeline, infer_device
+
+device = infer_device()
+
+pipeline = pipeline("automatic-speech-recognition", model="openai/whisper-large-v3", device=device)
+```
+
+Pass an audio file to [`Pipeline`].
+
+```py
+pipeline("https://huggingface.co/datasets/Narsil/asr_dummy/resolve/main/1.flac")
+{'text': ' He hoped there would be stew for dinner, turnips and carrots and bruised potatoes and fat mutton pieces to be ladled out in thick, peppered flour-fatten sauce.'}
+```
+
+
+
+
+## Trainer
+
+[`Trainer`] is a complete training and evaluation loop for PyTorch models. It abstracts away a lot of the boilerplate usually involved in manually writing a training loop, so you can start training faster and focus on training design choices. You only need a model, dataset, a preprocessor, and a data collator to build batches of data from the dataset.
+
+Use the [`TrainingArguments`] class to customize the training process. It provides many options for training, evaluation, and more. Experiment with training hyperparameters and features like batch size, learning rate, mixed precision, torch.compile, and more to meet your training needs. You could also use the default training parameters to quickly produce a baseline.
+
+Load a model, tokenizer, and dataset for training.
+
+```py
+from transformers import AutoModelForSequenceClassification, AutoTokenizer
+from datasets import load_dataset
+
+model = AutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+dataset = load_dataset("rotten_tomatoes")
+```
+
+Create a function to tokenize the text and convert it into PyTorch tensors. Apply this function to the whole dataset with the [`~datasets.Dataset.map`] method.
+
+```py
+def tokenize_dataset(dataset):
+ return tokenizer(dataset["text"])
+dataset = dataset.map(tokenize_dataset, batched=True)
+```
+
+Load a data collator to create batches of data and pass the tokenizer to it.
+
+```py
+from transformers import DataCollatorWithPadding
+
+data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
+```
+
+Next, set up [`TrainingArguments`] with the training features and hyperparameters.
+
+```py
+from transformers import TrainingArguments
+
+training_args = TrainingArguments(
+ output_dir="distilbert-rotten-tomatoes",
+ learning_rate=2e-5,
+ per_device_train_batch_size=8,
+ per_device_eval_batch_size=8,
+ num_train_epochs=2,
+ push_to_hub=True,
+)
+```
+
+Finally, pass all these separate components to [`Trainer`] and call [`~Trainer.train`] to start.
+
+```py
+from transformers import Trainer
+
+trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=dataset["train"],
+ eval_dataset=dataset["test"],
+ tokenizer=tokenizer,
+ data_collator=data_collator,
+)
+
+trainer.train()
+```
+
+Share your model and tokenizer to the Hub with [`~Trainer.push_to_hub`].
+
+```py
+trainer.push_to_hub()
+```
+
+Congratulations, you just trained your first model with Transformers!
+
+### TensorFlow
+
+> [!WARNING]
+> Not all pretrained models are available in TensorFlow. Refer to a models API doc to check whether a TensorFlow implementation is supported.
+
+[`Trainer`] doesn't work with TensorFlow models, but you can still train a Transformers model implemented in TensorFlow with [Keras](https://keras.io/). Transformers TensorFlow models are a standard [tf.keras.Model](https://www.tensorflow.org/api_docs/python/tf/keras/Model), which is compatible with Keras' [compile](https://keras.io/api/models/model_training_apis/#compile-method) and [fit](https://keras.io/api/models/model_training_apis/#fit-method) methods.
+
+Load a model, tokenizer, and dataset for training.
+
+```py
+from transformers import TFAutoModelForSequenceClassification, AutoTokenizer
+
+model = TFAutoModelForSequenceClassification.from_pretrained("distilbert/distilbert-base-uncased")
+tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Create a function to tokenize the text and convert it into TensorFlow tensors. Apply this function to the whole dataset with the [`~datasets.Dataset.map`] method.
+
+```py
+def tokenize_dataset(dataset):
+ return tokenizer(dataset["text"])
+dataset = dataset.map(tokenize_dataset)
+```
+
+Transformers provides the [`~TFPreTrainedModel.prepare_tf_dataset`] method to collate and batch a dataset.
+
+```py
+tf_dataset = model.prepare_tf_dataset(
+ dataset["train"], batch_size=16, shuffle=True, tokenizer=tokenizer
+)
+```
+
+Finally, call [compile](https://keras.io/api/models/model_training_apis/#compile-method) to configure the model for training and [fit](https://keras.io/api/models/model_training_apis/#fit-method) to start.
+
+```py
+from tensorflow.keras.optimizers import Adam
+
+model.compile(optimizer="adam")
+model.fit(tf_dataset)
+```
+
+## Next steps
+
+Now that you have a better understanding of Transformers and what it offers, it's time to keep exploring and learning what interests you the most.
+
+- **Base classes**: Learn more about the configuration, model and processor classes. This will help you understand how to create and customize models, preprocess different types of inputs (audio, images, multimodal), and how to share your model.
+- **Inference**: Explore the [`Pipeline`] further, inference and chatting with LLMs, agents, and how to optimize inference with your machine learning framework and hardware.
+- **Training**: Study the [`Trainer`] in more detail, as well as distributed training and optimizing training on specific hardware.
+- **Quantization**: Reduce memory and storage requirements with quantization and speed up inference by representing weights with fewer bits.
+- **Resources**: Looking for end-to-end recipes for how to train and inference with a model for a specific task? Check out the task recipes!
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/reference/environment_variables.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/reference/environment_variables.md
new file mode 100644
index 0000000000000000000000000000000000000000..fc20c08f9e6a359e103cc285b7426e684fca08dd
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/reference/environment_variables.md
@@ -0,0 +1,58 @@
+
+
+# Environment Variables
+
+## HF_ENABLE_PARALLEL_LOADING
+
+By default this is disabled. Enables the loading of torch and safetensor based weights to be loaded in parallel. Can decrease the time to load large models significantly, often times producing speed ups around ~50%.
+
+Can be set to a string equal to `"false"` or `"true"`. e.g. `os.environ["HF_ENABLE_PARALLEL_LOADING"] = "true"`.
+
+e.g. `facebook/opt-30b` on an AWS EC2 g4dn.metal instance can be made to load in ~30s with this enabled vs ~55s without it.
+
+Profile before committing to using this environment variable, this will not produce speed ups for smaller models.
+
+```py
+import os
+
+os.environ["HF_ENABLE_PARALLEL_LOADING"] = "true"
+
+from transformers import pipeline
+
+model = pipeline(task="text-generation", model="facebook/opt-30b", device_map="auto")
+```
+
+## HF_PARALLEL_LOADING_WORKERS
+
+Determines how many threads should be used when parallel loading is enabled. Default is `8`.
+
+If the number of files that are being loaded is less than the number of threads specified, the number that is actually spawned will be equal to the number of files.
+
+e.g. If you specify 8 workers, and there are only 2 files, only 2 workers will be spawned.
+
+Tune as you see fit.
+
+```py
+import os
+
+os.environ["HF_ENABLE_PARALLEL_LOADING"] = "true"
+os.environ["HF_PARALLEL_LOADING_WORKERS"] = "4"
+
+from transformers import pipeline
+
+model = pipeline(task="text-generation", model="facebook/opt-30b", device_map="auto")
+```
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/run_scripts.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/run_scripts.md
new file mode 100644
index 0000000000000000000000000000000000000000..37e00c9974c35458eaa5e79585919898c94aa0bb
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/run_scripts.md
@@ -0,0 +1,211 @@
+
+
+# Training scripts
+
+Transformers provides many example training scripts for deep learning frameworks (PyTorch, TensorFlow, Flax) and tasks in [transformers/examples](https://github.com/huggingface/transformers/tree/main/examples). There are additional scripts in [transformers/research projects](https://github.com/huggingface/transformers-research-projects/) and [transformers/legacy](https://github.com/huggingface/transformers/tree/main/examples/legacy), but these aren't actively maintained and requires a specific version of Transformers.
+
+Example scripts are only examples and you may need to adapt the script to your use-case. To help you with this, most scripts are very transparent in how data is preprocessed, allowing you to edit it as necessary.
+
+For any feature you'd like to implement in an example script, please discuss it on the [forum](https://discuss.huggingface.co/) or in an [issue](https://github.com/huggingface/transformers/issues) before submitting a pull request. While we welcome contributions, it is unlikely a pull request that adds more functionality is added at the cost of readability.
+
+This guide will show you how to run an example summarization training script in [PyTorch](https://github.com/huggingface/transformers/tree/main/examples/pytorch/summarization) and [TensorFlow](https://github.com/huggingface/transformers/tree/main/examples/tensorflow/summarization).
+
+## Setup
+
+Install Transformers from source in a new virtual environment to run the latest version of the example script.
+
+```bash
+git clone https://github.com/huggingface/transformers
+cd transformers
+pip install .
+```
+
+Run the command below to checkout a script from a specific or older version of Transformers.
+
+```bash
+git checkout tags/v3.5.1
+```
+
+After you've setup the correct version, navigate to the example folder of your choice and install the example specific requirements.
+
+```bash
+pip install -r requirements.txt
+```
+
+## Run a script
+
+Start with a smaller dataset by including the `max_train_samples`, `max_eval_samples`, and `max_predict_samples` parameters to truncate the dataset to a maximum number of samples. This helps ensure training works as expected before committing to the entire dataset which can take hours to complete.
+
+> [!WARNING]
+> Not all example scripts support the `max_predict_samples` parameter. Run the command below to check whether a script supports it or not.
+> ```bash
+> examples/pytorch/summarization/run_summarization.py -h
+> ```
+
+The example below fine-tunes [T5-small](https://huggingface.co/google-t5/t5-small) on the [CNN/DailyMail](https://huggingface.co/datasets/abisee/cnn_dailymail) dataset. T5 requires an additional `source_prefix` parameter to prompt it to summarize.
+
+
+
+
+The example script downloads and preprocesses a dataset, and then fine-tunes it with [`Trainer`] with a supported model architecture.
+
+Resuming training from a checkpoint is very useful if training is interrupted because you don't have to start over again. There are two ways to resume training from a checkpoint.
+
+* `--output dir previous_output_dir` resumes training from the latest checkpoint stored in `output_dir`. Remove the `--overwrite_output_dir` parameter if you're using this method.
+* `--resume_from_checkpoint path_to_specific_checkpoint` resumes training from a specific checkpoint folder.
+
+Share your model on the [Hub](https://huggingface.co/) with the `--push_to_hub` parameter. It creates a repository and uploads the model to the folder name specified in `--output_dir`. You could also use the `--push_to_hub_model_id` parameter to specify the repository name.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ # remove the `max_train_samples`, `max_eval_samples` and `max_predict_samples` if everything works
+ --max_train_samples 50 \
+ --max_eval_samples 50 \
+ --max_predict_samples 50 \
+ --do_train \
+ --do_eval \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --push_to_hub \
+ --push_to_hub_model_id finetuned-t5-cnn_dailymail \
+ # remove if using `output_dir previous_output_dir`
+ # --overwrite_output_dir \
+ --output_dir previous_output_dir \
+ # --resume_from_checkpoint path_to_specific_checkpoint \
+ --predict_with_generate \
+```
+
+For mixed precision and distributed training, include the following parameters and launch training with [torchrun](https://pytorch.org/docs/stable/elastic/run.html).
+
+* Add the `fp16` or `bf16` parameters to enable mixed precision training. XPU devices only supports `bf16`.
+* Add the `nproc_per_node` parameter to set number of GPUs to train with.
+
+```bash
+torchrun \
+ --nproc_per_node 8 pytorch/summarization/run_summarization.py \
+ --fp16 \
+ ...
+ ...
+```
+
+PyTorch supports TPUs, hardware designed to accelerate performance, through the [PyTorch/XLA](https://github.com/pytorch/xla/blob/master/README.md) package. Launch the `xla_spawn.py` script and use `num _cores` to set the number of TPU cores to train with.
+
+```bash
+python xla_spawn.py --num_cores 8 pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ ...
+ ...
+```
+
+
+
+
+```bash
+python examples/tensorflow/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ # remove the `max_train_samples`, `max_eval_samples` and `max_predict_samples` if everything works
+ --max_train_samples 50 \
+ --max_eval_samples 50 \
+ --max_predict_samples 50 \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --output_dir /tmp/tst-summarization \
+ --per_device_train_batch_size 8 \
+ --per_device_eval_batch_size 16 \
+ --num_train_epochs 3 \
+ --do_train \
+ --do_eval \
+```
+
+TensorFlow uses the [MirroredStrategy](https://www.tensorflow.org/guide/distributed_training#mirroredstrategy) for distributed training and doesn't require adding any additional parameters. The script uses multiple GPUs by default if they are available.
+
+For TPU training, TensorFlow scripts use the [TPUStrategy](https://www.tensorflow.org/guide/distributed_training#tpustrategy). Pass the TPU resource name to the `--tpu` parameter.
+
+```bash
+python run_summarization.py \
+ --tpu name_of_tpu_resource \
+ ...
+ ...
+```
+
+
+
+
+## Accelerate
+
+[Accelerate](https://huggingface.co/docs/accelerate) is designed to simplify distributed training while offering complete visibility into the PyTorch training loop. If you're planning on training with a script with Accelerate, use the `_no_trainer.py` version of the script.
+
+Install Accelerate from source to ensure you have the latest version.
+
+```bash
+pip install git+https://github.com/huggingface/accelerate
+```
+
+Run the [accelerate config](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-config) command to answer a few questions about your training setup. This creates and saves a config file about your system.
+
+```bash
+accelerate config
+```
+
+You can use [accelerate test](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-test) to ensure your system is properly configured.
+
+```bash
+accelerate test
+```
+
+Run [accelerate launch](https://huggingface.co/docs/accelerate/package_reference/cli#accelerate-launch) to start training.
+
+```bash
+accelerate launch run_summarization_no_trainer.py \
+ --model_name_or_path google-t5/t5-small \
+ --dataset_name cnn_dailymail \
+ --dataset_config "3.0.0" \
+ --source_prefix "summarize: " \
+ --output_dir ~/tmp/tst-summarization \
+```
+
+## Custom dataset
+
+The summarization scripts supports custom datasets as long as they are a CSV or JSONL file. When using your own dataset, you need to specify the following additional parameters.
+
+* `train_file` and `validation_file` specify the path to your training and validation files.
+* `text_column` is the input text to summarize.
+* `summary_column` is the target text to output.
+
+An example command for summarizing a custom dataset is shown below.
+
+```bash
+python examples/pytorch/summarization/run_summarization.py \
+ --model_name_or_path google-t5/t5-small \
+ --do_train \
+ --do_eval \
+ --train_file path_to_csv_or_jsonlines_file \
+ --validation_file path_to_csv_or_jsonlines_file \
+ --text_column text_column_name \
+ --summary_column summary_column_name \
+ --source_prefix "summarize: " \
+ --output_dir /tmp/tst-summarization \
+ --overwrite_output_dir \
+ --per_device_train_batch_size=4 \
+ --per_device_eval_batch_size=4 \
+ --predict_with_generate \
+```
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/serialization.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/serialization.md
new file mode 100644
index 0000000000000000000000000000000000000000..b62b76d1f0632a86f92c52ce6c1dd4b58adc674c
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/serialization.md
@@ -0,0 +1,99 @@
+
+
+# ONNX
+
+[ONNX](http://onnx.ai) is an open standard that defines a common set of operators and a file format to represent deep learning models in different frameworks, including PyTorch and TensorFlow. When a model is exported to ONNX, the operators construct a computational graph (or *intermediate representation*) which represents the flow of data through the model. Standardized operators and data types makes it easy to switch between frameworks.
+
+The [Optimum](https://huggingface.co/docs/optimum/index) library exports a model to ONNX with configuration objects which are supported for [many architectures](https://huggingface.co/docs/optimum/exporters/onnx/overview) and can be easily extended. If a model isn't supported, feel free to make a [contribution](https://huggingface.co/docs/optimum/exporters/onnx/usage_guides/contribute) to Optimum.
+
+The benefits of exporting to ONNX include the following.
+
+- [Graph optimization](https://huggingface.co/docs/optimum/onnxruntime/usage_guides/optimization) and [quantization](https://huggingface.co/docs/optimum/onnxruntime/usage_guides/quantization) for improving inference.
+- Use the [`~optimum.onnxruntime.ORTModel`] API to run a model with [ONNX Runtime](https://onnxruntime.ai/).
+- Use [optimized inference pipelines](https://huggingface.co/docs/optimum/main/en/onnxruntime/usage_guides/pipelines) for ONNX models.
+
+Export a Transformers model to ONNX with the Optimum CLI or the `optimum.onnxruntime` module.
+
+## Optimum CLI
+
+Run the command below to install Optimum and the [exporters](https://huggingface.co/docs/optimum/exporters/overview) module.
+
+```bash
+pip install optimum[exporters]
+```
+
+> [!TIP]
+> Refer to the [Export a model to ONNX with optimum.exporters.onnx](https://huggingface.co/docs/optimum/exporters/onnx/usage_guides/export_a_model#exporting-a-model-to-onnx-using-the-cli) guide for all available arguments or with the command below.
+> ```bash
+> optimum-cli export onnx --help
+> ```
+
+Set the `--model` argument to export a PyTorch or TensorFlow model from the Hub.
+
+```bash
+optimum-cli export onnx --model distilbert/distilbert-base-uncased-distilled-squad distilbert_base_uncased_squad_onnx/
+```
+
+You should see logs indicating the progress and showing where the resulting `model.onnx` is saved.
+
+```bash
+Validating ONNX model distilbert_base_uncased_squad_onnx/model.onnx...
+ -[✓] ONNX model output names match reference model (start_logits, end_logits)
+ - Validating ONNX Model output "start_logits":
+ -[✓] (2, 16) matches (2, 16)
+ -[✓] all values close (atol: 0.0001)
+ - Validating ONNX Model output "end_logits":
+ -[✓] (2, 16) matches (2, 16)
+ -[✓] all values close (atol: 0.0001)
+The ONNX export succeeded and the exported model was saved at: distilbert_base_uncased_squad_onnx
+```
+
+For local models, make sure the model weights and tokenizer files are saved in the same directory, for example `local_path`. Pass the directory to the `--model` argument and use `--task` to indicate the [task](https://huggingface.co/docs/optimum/exporters/task_manager) a model can perform. If `--task` isn't provided, the model architecture without a task-specific head is used.
+
+```bash
+optimum-cli export onnx --model local_path --task question-answering distilbert_base_uncased_squad_onnx/
+```
+
+The `model.onnx` file can be deployed with any [accelerator](https://onnx.ai/supported-tools.html#deployModel) that supports ONNX. The example below demonstrates loading and running a model with ONNX Runtime.
+
+```python
+>>> from transformers import AutoTokenizer
+>>> from optimum.onnxruntime import ORTModelForQuestionAnswering
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert_base_uncased_squad_onnx")
+>>> model = ORTModelForQuestionAnswering.from_pretrained("distilbert_base_uncased_squad_onnx")
+>>> inputs = tokenizer("What am I using?", "Using DistilBERT with ONNX Runtime!", return_tensors="pt")
+>>> outputs = model(**inputs)
+```
+
+## optimum.onnxruntime
+
+The `optimum.onnxruntime` module supports programmatically exporting a Transformers model. Instantiate a [`~optimum.onnxruntime.ORTModel`] for a task and set `export=True`. Use [`~OptimizedModel.save_pretrained`] to save the ONNX model.
+
+```python
+>>> from optimum.onnxruntime import ORTModelForSequenceClassification
+>>> from transformers import AutoTokenizer
+
+>>> model_checkpoint = "distilbert/distilbert-base-uncased-distilled-squad"
+>>> save_directory = "onnx/"
+
+>>> ort_model = ORTModelForSequenceClassification.from_pretrained(model_checkpoint, export=True)
+>>> tokenizer = AutoTokenizer.from_pretrained(model_checkpoint)
+
+>>> ort_model.save_pretrained(save_directory)
+>>> tokenizer.save_pretrained(save_directory)
+```
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/serving.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/serving.md
new file mode 100644
index 0000000000000000000000000000000000000000..218cb18682e31296f01f625d3a009f41727ca226
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/serving.md
@@ -0,0 +1,371 @@
+
+
+# Serving
+
+Transformer models can be efficiently deployed using libraries such as vLLM, Text Generation Inference (TGI), and others. These libraries are designed for production-grade user-facing services, and can scale to multiple servers and millions of concurrent users. Refer to [Transformers as Backend for Inference Servers](./transformers_as_backends) for usage examples.
+
+> [!TIP]
+> Responses API is now supported as an experimental API! Read more about it [here](#responses-api).
+
+Apart from that you can also serve transformer models easily using the `transformers serve` CLI. This is ideal for experimentation purposes, or to run models locally for personal and private use.
+
+In this document, we dive into the different supported endpoints and modalities; we also cover the setup of several user interfaces that can be used on top of `transformers serve` in the following guides:
+- [Jan (text and MCP user interface)](./jan.md)
+- [Cursor (IDE)](./cursor.md)
+- [Open WebUI (text, image, speech user interface)](./open_webui.md)
+- [Tiny-Agents (text and MCP CLI tool)](./tiny_agents.md)
+
+## Serve CLI
+
+> [!WARNING]
+> This section is experimental and subject to change in future versions
+
+You can serve models of diverse modalities supported by `transformers` with the `transformers serve` CLI. It spawns a local server that offers compatibility with the OpenAI SDK, which is the _de facto_ standard for LLM conversations and other related tasks. This way, you can use the server from many third party applications, or test it using the `transformers chat` CLI ([docs](conversations.md#chat-cli)).
+
+The server supports the following REST APIs:
+- `/v1/chat/completions`
+- `/v1/responses`
+- `/v1/audio/transcriptions`
+- `/v1/models`
+
+To launch a server, simply use the `transformers serve` CLI command:
+
+```shell
+transformers serve
+```
+
+The simplest way to interact with the server is through our `transformers chat` CLI
+
+```shell
+transformers chat localhost:8000 --model-name-or-path Qwen/Qwen3-4B
+```
+
+or by sending an HTTP request, like we'll see below.
+
+## Chat Completions - text-based
+
+See below for examples for text-based requests. Both LLMs and VLMs should handle
+
+
+
+
+```shell
+curl -X POST http://localhost:8000/v1/chat/completions -H "Content-Type: application/json" -d '{"messages": [{"role": "system", "content": "hello"}], "temperature": 0.9, "max_tokens": 1000, "stream": true, "model": "Qwen/Qwen2.5-0.5B-Instruct"}'
+```
+
+from which you'll receive multiple chunks in the Completions API format
+
+```shell
+data: {"object": "chat.completion.chunk", "id": "req_0", "created": 1751377863, "model": "Qwen/Qwen2.5-0.5B-Instruct", "system_fingerprint": "", "choices": [{"delta": {"role": "assistant", "content": "", "tool_call_id": null, "tool_calls": null}, "index": 0, "finish_reason": null, "logprobs": null}]}
+
+(...)
+```
+
+
+
+
+```python
+import asyncio
+from huggingface_hub import AsyncInferenceClient
+
+messages = [{"role": "user", "content": "What is the Transformers library known for?"}]
+client = AsyncInferenceClient("http://localhost:8000")
+
+async def responses_api_test_async():
+ async for chunk in (await client.chat_completion(messages, model="Qwen/Qwen2.5-0.5B-Instruct", max_tokens=256, stream=True)):
+ token = chunk.choices[0].delta.content
+ if token:
+ print(token, end='')
+
+asyncio.run(responses_api_test_async())
+asyncio.run(client.close())
+```
+
+From which you should get an iterative string printed:
+
+```shell
+The Transformers library is primarily known for its ability to create and manipulate large-scale language models [...]
+```
+
+
+
+
+```python
+from openai import OpenAI
+
+client = OpenAI(base_url="http://localhost:8000/v1", api_key="")
+
+completion = client.chat.completions.create(
+ model="Qwen/Qwen2.5-0.5B-Instruct",
+ messages=[
+ {
+ "role": "user",
+ "content": "What is the Transformers library known for?"
+ }
+ ],
+ stream=True
+)
+
+for chunk in completion:
+ token = chunk.choices[0].delta.content
+ if token:
+ print(token, end='')
+```
+
+From which you should get an iterative string printed:
+
+```shell
+The Transformers library is primarily known for its ability to create and manipulate large-scale language models [...]
+```
+
+
+
+
+## Chat Completions - VLMs
+
+The Chat Completion API also supports images; see below for examples for text-and-image-based requests.
+
+
+
+
+```shell
+curl http://localhost:8000/v1/chat/completions \
+ -H "Content-Type: application/json" \
+ -d '{
+ "model": "Qwen/Qwen2.5-VL-7B-Instruct",
+ "stream": true,
+ "messages": [
+ {
+ "role": "user",
+ "content": [
+ {
+ "type": "text",
+ "text": "What is in this image?"
+ },
+ {
+ "type": "image_url",
+ "image_url": {
+ "url": "https://upload.wikimedia.org/wikipedia/commons/thumb/d/dd/Gfp-wisconsin-madison-the-nature-boardwalk.jpg/2560px-Gfp-wisconsin-madison-the-nature-boardwalk.jpg"
+ }
+ }
+ ]
+ }
+ ],
+ "max_tokens": 300
+ }'
+
+```
+
+from which you'll receive multiple chunks in the Completions API format
+
+```shell
+data: {"id":"req_0","choices":[{"delta":{"role":"assistant"},"index":0}],"created":1753366665,"model":"Qwen/Qwen2.5-VL-7B-Instruct@main","object":"chat.completion.chunk","system_fingerprint":""}
+
+data: {"id":"req_0","choices":[{"delta":{"content":"The "},"index":0}],"created":1753366701,"model":"Qwen/Qwen2.5-VL-7B-Instruct@main","object":"chat.completion.chunk","system_fingerprint":""}
+
+data: {"id":"req_0","choices":[{"delta":{"content":"image "},"index":0}],"created":1753366701,"model":"Qwen/Qwen2.5-VL-7B-Instruct@main","object":"chat.completion.chunk","system_fingerprint":""}
+```
+
+
+
+
+```python
+import asyncio
+from huggingface_hub import AsyncInferenceClient
+
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "What's in this image?"},
+ {
+ "type": "image_url",
+ "image_url": {
+ "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/astronaut.jpg",
+ }
+ },
+ ],
+ }
+]
+client = AsyncInferenceClient("http://localhost:8000")
+
+async def responses_api_test_async():
+ async for chunk in (await client.chat_completion(messages, model="Qwen/Qwen2.5-VL-7B-Instruct", max_tokens=256, stream=True)):
+ token = chunk.choices[0].delta.content
+ if token:
+ print(token, end='')
+
+asyncio.run(responses_api_test_async())
+asyncio.run(client.close())
+```
+
+From which you should get an iterative string printed:
+
+```xmp
+The image depicts an astronaut in a space suit standing on what appears to be the surface of the moon, given the barren, rocky landscape and the dark sky in the background. The astronaut is holding a large egg that has cracked open, revealing a small creature inside. The scene is imaginative and playful, combining elements of space exploration with a whimsical twist involving the egg and the creature.
+```
+
+
+
+
+```python
+from openai import OpenAI
+
+client = OpenAI(base_url="http://localhost:8000/v1", api_key="")
+
+completion = client.chat.completions.create(
+ model="Qwen/Qwen2.5-VL-7B-Instruct",
+ messages=[
+ {
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "What's in this image?"},
+ {
+ "type": "image_url",
+ "image_url": {
+ "url": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/diffusers/astronaut.jpg",
+ }
+ },
+ ],
+ }
+ ],
+ stream=True
+)
+
+for chunk in completion:
+ token = chunk.choices[0].delta.content
+ if token:
+ print(token, end='')
+```
+
+From which you should get an iterative string printed:
+
+```xmp
+The image depicts an astronaut in a space suit standing on what appears to be the surface of the moon, given the barren, rocky landscape and the dark sky in the background. The astronaut is holding a large egg that has cracked open, revealing a small creature inside. The scene is imaginative and playful, combining elements of space exploration with a whimsical twist involving the egg and the creature.
+```
+
+
+
+
+## Responses API
+
+The Responses API is the newest addition to the supported APIs of `transformers serve`.
+
+> [!TIP]
+> This API is still experimental: expect bug patches and additition of new features in the coming weeks.
+> If you run into any issues, please let us know and we'll work on fixing them ASAP.
+
+Instead of the previous `/v1/chat/completions` path, the Responses API lies behind the `/v1/responses` path.
+See below for examples interacting with our Responses endpoint with `curl`, as well as the Python OpenAI client.
+
+So far, this endpoint only supports text and therefore only LLMs. VLMs to come!
+
+
+
+
+```shell
+curl http://localhost:8000/v1/responses \
+ -H "Content-Type: application/json" \
+ -d '{
+ "model": "Qwen/Qwen2.5-0.5B-Instruct",
+ "stream": true,
+ "input": "Tell me a three sentence bedtime story about a unicorn."
+ }'
+```
+
+from which you'll receive multiple chunks in the Responses API format
+
+```shell
+data: {"response":{"id":"resp_req_0","created_at":1754059817.783648,"model":"Qwen/Qwen2.5-0.5B-Instruct@main","object":"response","output":[],"parallel_tool_calls":false,"tool_choice":"auto","tools":[],"status":"queued","text":{"format":{"type":"text"}}},"sequence_number":0,"type":"response.created"}
+
+data: {"response":{"id":"resp_req_0","created_at":1754059817.783648,"model":"Qwen/Qwen2.5-0.5B-Instruct@main","object":"response","output":[],"parallel_tool_calls":false,"tool_choice":"auto","tools":[],"status":"in_progress","text":{"format":{"type":"text"}}},"sequence_number":1,"type":"response.in_progress"}
+
+data: {"item":{"id":"msg_req_0","content":[],"role":"assistant","status":"in_progress","type":"message"},"output_index":0,"sequence_number":2,"type":"response.output_item.added"}
+
+data: {"content_index":0,"item_id":"msg_req_0","output_index":0,"part":{"annotations":[],"text":"","type":"output_text"},"sequence_number":3,"type":"response.content_part.added"}
+
+data: {"content_index":0,"delta":"","item_id":"msg_req_0","output_index":0,"sequence_number":4,"type":"response.output_text.delta"}
+
+data: {"content_index":0,"delta":"Once ","item_id":"msg_req_0","output_index":0,"sequence_number":5,"type":"response.output_text.delta"}
+
+data: {"content_index":0,"delta":"upon ","item_id":"msg_req_0","output_index":0,"sequence_number":6,"type":"response.output_text.delta"}
+
+data: {"content_index":0,"delta":"a ","item_id":"msg_req_0","output_index":0,"sequence_number":7,"type":"response.output_text.delta"}
+```
+
+
+
+
+```python
+from openai import OpenAI
+
+client = OpenAI(base_url="http://localhost:8000/v1", api_key="")
+
+response = client.responses.create(
+ model="Qwen/Qwen2.5-0.5B-Instruct",
+ instructions="You are a helpful assistant.",
+ input="Hello!",
+ stream=True,
+ metadata={"foo": "bar"},
+)
+
+for event in response:
+ print(event)
+```
+
+From which you should get events printed out successively.
+
+```shell
+ResponseCreatedEvent(response=Response(id='resp_req_0', created_at=1754060400.3718212, error=None, incomplete_details=None, instructions='You are a helpful assistant.', metadata={'foo': 'bar'}, model='Qwen/Qwen2.5-0.5B-Instruct@main', object='response', output=[], parallel_tool_calls=False, temperature=None, tool_choice='auto', tools=[], top_p=None, background=None, max_output_tokens=None, max_tool_calls=None, previous_response_id=None, prompt=None, reasoning=None, service_tier=None, status='queued', text=ResponseTextConfig(format=ResponseFormatText(type='text')), top_logprobs=None, truncation=None, usage=None, user=None), sequence_number=0, type='response.created')
+ResponseInProgressEvent(response=Response(id='resp_req_0', created_at=1754060400.3718212, error=None, incomplete_details=None, instructions='You are a helpful assistant.', metadata={'foo': 'bar'}, model='Qwen/Qwen2.5-0.5B-Instruct@main', object='response', output=[], parallel_tool_calls=False, temperature=None, tool_choice='auto', tools=[], top_p=None, background=None, max_output_tokens=None, max_tool_calls=None, previous_response_id=None, prompt=None, reasoning=None, service_tier=None, status='in_progress', text=ResponseTextConfig(format=ResponseFormatText(type='text')), top_logprobs=None, truncation=None, usage=None, user=None), sequence_number=1, type='response.in_progress')
+ResponseOutputItemAddedEvent(item=ResponseOutputMessage(id='msg_req_0', content=[], role='assistant', status='in_progress', type='message'), output_index=0, sequence_number=2, type='response.output_item.added')
+ResponseContentPartAddedEvent(content_index=0, item_id='msg_req_0', output_index=0, part=ResponseOutputText(annotations=[], text='', type='output_text', logprobs=None), sequence_number=3, type='response.content_part.added')
+ResponseTextDeltaEvent(content_index=0, delta='', item_id='msg_req_0', output_index=0, sequence_number=4, type='response.output_text.delta')
+ResponseTextDeltaEvent(content_index=0, delta='', item_id='msg_req_0', output_index=0, sequence_number=5, type='response.output_text.delta')
+ResponseTextDeltaEvent(content_index=0, delta='Hello! ', item_id='msg_req_0', output_index=0, sequence_number=6, type='response.output_text.delta')
+ResponseTextDeltaEvent(content_index=0, delta='How ', item_id='msg_req_0', output_index=0, sequence_number=7, type='response.output_text.delta')
+ResponseTextDeltaEvent(content_index=0, delta='can ', item_id='msg_req_0', output_index=0, sequence_number=8, type='response.output_text.delta')
+ResponseTextDeltaEvent(content_index=0, delta='I ', item_id='msg_req_0', output_index=0, sequence_number=9, type='response.output_text.delta')
+ResponseTextDeltaEvent(content_index=0, delta='assist ', item_id='msg_req_0', output_index=0, sequence_number=10, type='response.output_text.delta')
+ResponseTextDeltaEvent(content_index=0, delta='you ', item_id='msg_req_0', output_index=0, sequence_number=11, type='response.output_text.delta')
+ResponseTextDeltaEvent(content_index=0, delta='', item_id='msg_req_0', output_index=0, sequence_number=12, type='response.output_text.delta')
+ResponseTextDeltaEvent(content_index=0, delta='', item_id='msg_req_0', output_index=0, sequence_number=13, type='response.output_text.delta')
+ResponseTextDeltaEvent(content_index=0, delta='today?', item_id='msg_req_0', output_index=0, sequence_number=14, type='response.output_text.delta')
+ResponseTextDoneEvent(content_index=0, item_id='msg_req_0', output_index=0, sequence_number=15, text='Hello! How can I assist you today?', type='response.output_text.done')
+ResponseContentPartDoneEvent(content_index=0, item_id='msg_req_0', output_index=0, part=ResponseOutputText(annotations=[], text='Hello! How can I assist you today?', type='output_text', logprobs=None), sequence_number=16, type='response.content_part.done')
+ResponseOutputItemDoneEvent(item=ResponseOutputMessage(id='msg_req_0', content=[ResponseOutputText(annotations=[], text='Hello! How can I assist you today?', type='output_text', logprobs=None)], role='assistant', status='completed', type='message', annotations=[]), output_index=0, sequence_number=17, type='response.output_item.done')
+ResponseCompletedEvent(response=Response(id='resp_req_0', created_at=1754060400.3718212, error=None, incomplete_details=None, instructions='You are a helpful assistant.', metadata={'foo': 'bar'}, model='Qwen/Qwen2.5-0.5B-Instruct@main', object='response', output=[ResponseOutputMessage(id='msg_req_0', content=[ResponseOutputText(annotations=[], text='Hello! How can I assist you today?', type='output_text', logprobs=None)], role='assistant', status='completed', type='message', annotations=[])], parallel_tool_calls=False, temperature=None, tool_choice='auto', tools=[], top_p=None, background=None, max_output_tokens=None, max_tool_calls=None, previous_response_id=None, prompt=None, reasoning=None, service_tier=None, status='completed', text=ResponseTextConfig(format=ResponseFormatText(type='text')), top_logprobs=None, truncation=None, usage=None, user=None), sequence_number=18, type='response.completed')
+```
+
+
+
+
+
+## MCP integration
+
+The `transformers serve` server is also an MCP client, so it can interact with MCP tools in agentic use cases. This, of course, requires the use of an LLM that is designed to use tools.
+
+> [!TIP]
+> At the moment, MCP tool usage in `transformers` is limited to the `qwen` family of models.
+
+
+
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/asr.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/asr.md
new file mode 100644
index 0000000000000000000000000000000000000000..760f701cf5cc2d5dc29b55e6041d3efa96adb9cd
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/asr.md
@@ -0,0 +1,371 @@
+
+
+# Automatic speech recognition
+
+[[open-in-colab]]
+
+
+
+Automatic speech recognition (ASR) converts a speech signal to text, mapping a sequence of audio inputs to text outputs. Virtual assistants like Siri and Alexa use ASR models to help users every day, and there are many other useful user-facing applications like live captioning and note-taking during meetings.
+
+This guide will show you how to:
+
+1. Fine-tune [Wav2Vec2](https://huggingface.co/facebook/wav2vec2-base) on the [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) dataset to transcribe audio to text.
+2. Use your fine-tuned model for inference.
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/automatic-speech-recognition)
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate jiwer
+```
+
+We encourage you to login to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to login:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load MInDS-14 dataset
+
+Start by loading a smaller subset of the [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) dataset from the 🤗 Datasets library. This will give you a chance to experiment and make sure everything works before spending more time training on the full dataset.
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> minds = load_dataset("PolyAI/minds14", name="en-US", split="train[:100]")
+```
+
+Split the dataset's `train` split into a train and test set with the [`~Dataset.train_test_split`] method:
+
+```py
+>>> minds = minds.train_test_split(test_size=0.2)
+```
+
+Then take a look at the dataset:
+
+```py
+>>> minds
+DatasetDict({
+ train: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 16
+ })
+ test: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 4
+ })
+})
+```
+
+While the dataset contains a lot of useful information, like `lang_id` and `english_transcription`, this guide focuses on the `audio` and `transcription`. Remove the other columns with the [`~datasets.Dataset.remove_columns`] method:
+
+```py
+>>> minds = minds.remove_columns(["english_transcription", "intent_class", "lang_id"])
+```
+
+Review the example again:
+
+```py
+>>> minds["train"][0]
+{'audio': {'array': array([-0.00024414, 0. , 0. , ..., 0.00024414,
+ 0.00024414, 0.00024414], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'sampling_rate': 8000},
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'transcription': "hi I'm trying to use the banking app on my phone and currently my checking and savings account balance is not refreshing"}
+```
+
+There are two fields:
+
+- `audio`: a 1-dimensional `array` of the speech signal that must be called to load and resample the audio file.
+- `transcription`: the target text.
+
+## Preprocess
+
+The next step is to load a Wav2Vec2 processor to process the audio signal:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("facebook/wav2vec2-base")
+```
+
+The MInDS-14 dataset has a sampling rate of 8000Hz (you can find this information in its [dataset card](https://huggingface.co/datasets/PolyAI/minds14)), which means you'll need to resample the dataset to 16000Hz to use the pretrained Wav2Vec2 model:
+
+```py
+>>> minds = minds.cast_column("audio", Audio(sampling_rate=16_000))
+>>> minds["train"][0]
+{'audio': {'array': array([-2.38064706e-04, -1.58618059e-04, -5.43987835e-06, ...,
+ 2.78103951e-04, 2.38446111e-04, 1.18740834e-04], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'sampling_rate': 16000},
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602ba9e2963e11ccd901cd4f.wav',
+ 'transcription': "hi I'm trying to use the banking app on my phone and currently my checking and savings account balance is not refreshing"}
+```
+
+As you can see in the `transcription` above, the text contains a mix of uppercase and lowercase characters. The Wav2Vec2 tokenizer is only trained on uppercase characters so you'll need to make sure the text matches the tokenizer's vocabulary:
+
+```py
+>>> def uppercase(example):
+... return {"transcription": example["transcription"].upper()}
+
+
+>>> minds = minds.map(uppercase)
+```
+
+Now create a preprocessing function that:
+
+1. Calls the `audio` column to load and resample the audio file.
+2. Extracts the `input_values` from the audio file and tokenize the `transcription` column with the processor.
+
+```py
+>>> def prepare_dataset(batch):
+... audio = batch["audio"]
+... batch = processor(audio["array"], sampling_rate=audio["sampling_rate"], text=batch["transcription"])
+... batch["input_length"] = len(batch["input_values"][0])
+... return batch
+```
+
+To apply the preprocessing function over the entire dataset, use 🤗 Datasets [`~datasets.Dataset.map`] function. You can speed up `map` by increasing the number of processes with the `num_proc` parameter. Remove the columns you don't need with the [`~datasets.Dataset.remove_columns`] method:
+
+```py
+>>> encoded_minds = minds.map(prepare_dataset, remove_columns=minds.column_names["train"], num_proc=4)
+```
+
+🤗 Transformers doesn't have a data collator for ASR, so you'll need to adapt the [`DataCollatorWithPadding`] to create a batch of examples. It'll also dynamically pad your text and labels to the length of the longest element in its batch (instead of the entire dataset) so they are a uniform length. While it is possible to pad your text in the `tokenizer` function by setting `padding=True`, dynamic padding is more efficient.
+
+Unlike other data collators, this specific data collator needs to apply a different padding method to `input_values` and `labels`:
+
+```py
+>>> import torch
+
+>>> from dataclasses import dataclass, field
+>>> from typing import Any, Dict, List, Optional, Union
+
+
+>>> @dataclass
+... class DataCollatorCTCWithPadding:
+... processor: AutoProcessor
+... padding: Union[bool, str] = "longest"
+
+... def __call__(self, features: list[dict[str, Union[list[int], torch.Tensor]]]) -> dict[str, torch.Tensor]:
+... # split inputs and labels since they have to be of different lengths and need
+... # different padding methods
+... input_features = [{"input_values": feature["input_values"][0]} for feature in features]
+... label_features = [{"input_ids": feature["labels"]} for feature in features]
+
+... batch = self.processor.pad(input_features, padding=self.padding, return_tensors="pt")
+
+... labels_batch = self.processor.pad(labels=label_features, padding=self.padding, return_tensors="pt")
+
+... # replace padding with -100 to ignore loss correctly
+... labels = labels_batch["input_ids"].masked_fill(labels_batch.attention_mask.ne(1), -100)
+
+... batch["labels"] = labels
+
+... return batch
+```
+
+Now instantiate your `DataCollatorForCTCWithPadding`:
+
+```py
+>>> data_collator = DataCollatorCTCWithPadding(processor=processor, padding="longest")
+```
+
+## Evaluate
+
+Including a metric during training is often helpful for evaluating your model's performance. You can quickly load an evaluation method with the 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) library. For this task, load the [word error rate](https://huggingface.co/spaces/evaluate-metric/wer) (WER) metric (refer to the 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour) to learn more about loading and computing metrics):
+
+```py
+>>> import evaluate
+
+>>> wer = evaluate.load("wer")
+```
+
+Then create a function that passes your predictions and labels to [`~evaluate.EvaluationModule.compute`] to calculate the WER:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(pred):
+... pred_logits = pred.predictions
+... pred_ids = np.argmax(pred_logits, axis=-1)
+
+... pred.label_ids[pred.label_ids == -100] = processor.tokenizer.pad_token_id
+
+... pred_str = processor.batch_decode(pred_ids)
+... label_str = processor.batch_decode(pred.label_ids, group_tokens=False)
+
+... wer = wer.compute(predictions=pred_str, references=label_str)
+
+... return {"wer": wer}
+```
+
+Your `compute_metrics` function is ready to go now, and you'll return to it when you setup your training.
+
+## Train
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#train-with-pytorch-trainer)!
+
+
+
+You are now ready to start training your model! Load Wav2Vec2 with [`AutoModelForCTC`]. Specify the reduction to apply with the `ctc_loss_reduction` parameter. It is often better to use the average instead of the default summation:
+
+```py
+>>> from transformers import AutoModelForCTC, TrainingArguments, Trainer
+
+>>> model = AutoModelForCTC.from_pretrained(
+... "facebook/wav2vec2-base",
+... ctc_loss_reduction="mean",
+... pad_token_id=processor.tokenizer.pad_token_id,
+... )
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`TrainingArguments`]. The only required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model). At the end of each epoch, the [`Trainer`] will evaluate the WER and save the training checkpoint.
+2. Pass the training arguments to [`Trainer`] along with the model, dataset, tokenizer, data collator, and `compute_metrics` function.
+3. Call [`~Trainer.train`] to fine-tune your model.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_asr_mind_model",
+... per_device_train_batch_size=8,
+... gradient_accumulation_steps=2,
+... learning_rate=1e-5,
+... warmup_steps=500,
+... max_steps=2000,
+... gradient_checkpointing=True,
+... fp16=True,
+... group_by_length=True,
+... eval_strategy="steps",
+... per_device_eval_batch_size=8,
+... save_steps=1000,
+... eval_steps=1000,
+... logging_steps=25,
+... load_best_model_at_end=True,
+... metric_for_best_model="wer",
+... greater_is_better=False,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=encoded_minds["train"],
+... eval_dataset=encoded_minds["test"],
+... processing_class=processor,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so it can be accessible to everyone:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+For a more in-depth example of how to fine-tune a model for automatic speech recognition, take a look at this blog [post](https://huggingface.co/blog/fine-tune-wav2vec2-english) for English ASR and this [post](https://huggingface.co/blog/fine-tune-xlsr-wav2vec2) for multilingual ASR.
+
+
+
+## Inference
+
+Great, now that you've fine-tuned a model, you can use it for inference!
+
+Load an audio file you'd like to run inference on. Remember to resample the sampling rate of the audio file to match the sampling rate of the model if you need to!
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", "en-US", split="train")
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
+>>> sampling_rate = dataset.features["audio"].sampling_rate
+>>> audio_file = dataset[0]["audio"]["path"]
+```
+
+The simplest way to try out your fine-tuned model for inference is to use it in a [`pipeline`]. Instantiate a `pipeline` for automatic speech recognition with your model, and pass your audio file to it:
+
+```py
+>>> from transformers import pipeline
+
+>>> transcriber = pipeline("automatic-speech-recognition", model="stevhliu/my_awesome_asr_minds_model")
+>>> transcriber(audio_file)
+{'text': 'I WOUD LIKE O SET UP JOINT ACOUNT WTH Y PARTNER'}
+```
+
+
+
+The transcription is decent, but it could be better! Try finetuning your model on more examples to get even better results!
+
+
+
+You can also manually replicate the results of the `pipeline` if you'd like:
+
+
+
+Load a processor to preprocess the audio file and transcription and return the `input` as PyTorch tensors:
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained("stevhliu/my_awesome_asr_mind_model")
+>>> inputs = processor(dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
+```
+
+Pass your inputs to the model and return the logits:
+
+```py
+>>> from transformers import AutoModelForCTC
+
+>>> model = AutoModelForCTC.from_pretrained("stevhliu/my_awesome_asr_mind_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+Get the predicted `input_ids` with the highest probability, and use the processor to decode the predicted `input_ids` back into text:
+
+```py
+>>> import torch
+
+>>> predicted_ids = torch.argmax(logits, dim=-1)
+>>> transcription = processor.batch_decode(predicted_ids)
+>>> transcription
+['I WOUL LIKE O SET UP JOINT ACOUNT WTH Y PARTNER']
+```
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/audio_classification.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/audio_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..973f95e1e9555dd77e3a5a6b48a5131598dfa2df
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/audio_classification.md
@@ -0,0 +1,324 @@
+
+
+# Audio classification
+
+[[open-in-colab]]
+
+
+
+Audio classification - just like with text - assigns a class label as output from the input data. The only difference is instead of text inputs, you have raw audio waveforms. Some practical applications of audio classification include identifying speaker intent, language classification, and even animal species by their sounds.
+
+This guide will show you how to:
+
+1. Fine-tune [Wav2Vec2](https://huggingface.co/facebook/wav2vec2-base) on the [MInDS-14](https://huggingface.co/datasets/PolyAI/minds14) dataset to classify speaker intent.
+2. Use your fine-tuned model for inference.
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/audio-classification)
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+We encourage you to login to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to login:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load MInDS-14 dataset
+
+Start by loading the MInDS-14 dataset from the 🤗 Datasets library:
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> minds = load_dataset("PolyAI/minds14", name="en-US", split="train")
+```
+
+Split the dataset's `train` split into a smaller train and test set with the [`~datasets.Dataset.train_test_split`] method. This will give you a chance to experiment and make sure everything works before spending more time on the full dataset.
+
+```py
+>>> minds = minds.train_test_split(test_size=0.2)
+```
+
+Then take a look at the dataset:
+
+```py
+>>> minds
+DatasetDict({
+ train: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 450
+ })
+ test: Dataset({
+ features: ['path', 'audio', 'transcription', 'english_transcription', 'intent_class', 'lang_id'],
+ num_rows: 113
+ })
+})
+```
+
+While the dataset contains a lot of useful information, like `lang_id` and `english_transcription`, you will focus on the `audio` and `intent_class` in this guide. Remove the other columns with the [`~datasets.Dataset.remove_columns`] method:
+
+```py
+>>> minds = minds.remove_columns(["path", "transcription", "english_transcription", "lang_id"])
+```
+
+Here's an example:
+
+```py
+>>> minds["train"][0]
+{'audio': {'array': array([ 0. , 0. , 0. , ..., -0.00048828,
+ -0.00024414, -0.00024414], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602b9a5fbb1e6d0fbce91f52.wav',
+ 'sampling_rate': 8000},
+ 'intent_class': 2}
+```
+
+There are two fields:
+
+- `audio`: a 1-dimensional `array` of the speech signal that must be called to load and resample the audio file.
+- `intent_class`: represents the class id of the speaker's intent.
+
+To make it easier for the model to get the label name from the label id, create a dictionary that maps the label name to an integer and vice versa:
+
+```py
+>>> labels = minds["train"].features["intent_class"].names
+>>> label2id, id2label = dict(), dict()
+>>> for i, label in enumerate(labels):
+... label2id[label] = str(i)
+... id2label[str(i)] = label
+```
+
+Now you can convert the label id to a label name:
+
+```py
+>>> id2label[str(2)]
+'app_error'
+```
+
+## Preprocess
+
+The next step is to load a Wav2Vec2 feature extractor to process the audio signal:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("facebook/wav2vec2-base")
+```
+
+The MInDS-14 dataset has a sampling rate of 8kHz (you can find this information in its [dataset card](https://huggingface.co/datasets/PolyAI/minds14)), which means you'll need to resample the dataset to 16kHz to use the pretrained Wav2Vec2 model:
+
+```py
+>>> minds = minds.cast_column("audio", Audio(sampling_rate=16_000))
+>>> minds["train"][0]
+{'audio': {'array': array([ 2.2098757e-05, 4.6582241e-05, -2.2803260e-05, ...,
+ -2.8419291e-04, -2.3305941e-04, -1.1425107e-04], dtype=float32),
+ 'path': '/root/.cache/huggingface/datasets/downloads/extracted/f14948e0e84be638dd7943ac36518a4cf3324e8b7aa331c5ab11541518e9368c/en-US~APP_ERROR/602b9a5fbb1e6d0fbce91f52.wav',
+ 'sampling_rate': 16000},
+ 'intent_class': 2}
+```
+
+Now create a preprocessing function that:
+
+1. Calls the `audio` column to load, and if necessary, resample the audio file.
+2. Checks if the sampling rate of the audio file matches the sampling rate of the audio data a model was pretrained with. You can find this information in the Wav2Vec2 [model card](https://huggingface.co/facebook/wav2vec2-base).
+3. Set a maximum input length to batch longer inputs without truncating them.
+
+```py
+>>> def preprocess_function(examples):
+... audio_arrays = [x["array"] for x in examples["audio"]]
+... inputs = feature_extractor(
+... audio_arrays, sampling_rate=feature_extractor.sampling_rate, max_length=16000, truncation=True
+... )
+... return inputs
+```
+
+To apply the preprocessing function over the entire dataset, use 🤗 Datasets [`~datasets.Dataset.map`] function. You can speed up `map` by setting `batched=True` to process multiple elements of the dataset at once. Remove unnecessary columns and rename `intent_class` to `label`, as required by the model:
+
+```py
+>>> encoded_minds = minds.map(preprocess_function, remove_columns="audio", batched=True)
+>>> encoded_minds = encoded_minds.rename_column("intent_class", "label")
+```
+
+## Evaluate
+
+Including a metric during training is often helpful for evaluating your model's performance. You can quickly load an evaluation method with the 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) library. For this task, load the [accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) metric (see the 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour) to learn more about how to load and compute a metric):
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+Then create a function that passes your predictions and labels to [`~evaluate.EvaluationModule.compute`] to calculate the accuracy:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions = np.argmax(eval_pred.predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=eval_pred.label_ids)
+```
+
+Your `compute_metrics` function is ready to go now, and you'll return to it when you setup your training.
+
+## Train
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#train-with-pytorch-trainer)!
+
+
+
+You're ready to start training your model now! Load Wav2Vec2 with [`AutoModelForAudioClassification`] along with the number of expected labels, and the label mappings:
+
+```py
+>>> from transformers import AutoModelForAudioClassification, TrainingArguments, Trainer
+
+>>> num_labels = len(id2label)
+>>> model = AutoModelForAudioClassification.from_pretrained(
+... "facebook/wav2vec2-base", num_labels=num_labels, label2id=label2id, id2label=id2label
+... )
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`TrainingArguments`]. The only required parameter is `output_dir`, which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model). At the end of each epoch, the [`Trainer`] will evaluate the accuracy and save the training checkpoint.
+2. Pass the training arguments to [`Trainer`] along with the model, dataset, tokenizer, data collator, and `compute_metrics` function.
+3. Call [`~Trainer.train`] to fine-tune your model.
+
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_mind_model",
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... learning_rate=3e-5,
+... per_device_train_batch_size=32,
+... gradient_accumulation_steps=4,
+... per_device_eval_batch_size=32,
+... num_train_epochs=10,
+... warmup_ratio=0.1,
+... logging_steps=10,
+... load_best_model_at_end=True,
+... metric_for_best_model="accuracy",
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=encoded_minds["train"],
+... eval_dataset=encoded_minds["test"],
+... processing_class=feature_extractor,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+For a more in-depth example of how to fine-tune a model for audio classification, take a look at the corresponding [PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/audio_classification.ipynb).
+
+
+
+## Inference
+
+Great, now that you've fine-tuned a model, you can use it for inference!
+
+Load an audio file for inference. Remember to resample the sampling rate of the audio file to match the model's sampling rate, if necessary.
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("PolyAI/minds14", name="en-US", split="train")
+>>> dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
+>>> sampling_rate = dataset.features["audio"].sampling_rate
+>>> audio_file = dataset[0]["audio"]["path"]
+```
+
+The simplest way to try out your fine-tuned model for inference is to use it in a [`pipeline`]. Instantiate a `pipeline` for audio classification with your model, and pass your audio file to it:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("audio-classification", model="stevhliu/my_awesome_minds_model")
+>>> classifier(audio_file)
+[
+ {'score': 0.09766869246959686, 'label': 'cash_deposit'},
+ {'score': 0.07998877018690109, 'label': 'app_error'},
+ {'score': 0.0781070664525032, 'label': 'joint_account'},
+ {'score': 0.07667109370231628, 'label': 'pay_bill'},
+ {'score': 0.0755252093076706, 'label': 'balance'}
+]
+```
+
+You can also manually replicate the results of the `pipeline` if you'd like:
+
+
+
+Load a feature extractor to preprocess the audio file and return the `input` as PyTorch tensors:
+
+```py
+>>> from transformers import AutoFeatureExtractor
+
+>>> feature_extractor = AutoFeatureExtractor.from_pretrained("stevhliu/my_awesome_minds_model")
+>>> inputs = feature_extractor(dataset[0]["audio"]["array"], sampling_rate=sampling_rate, return_tensors="pt")
+```
+
+Pass your inputs to the model and return the logits:
+
+```py
+>>> from transformers import AutoModelForAudioClassification
+
+>>> model = AutoModelForAudioClassification.from_pretrained("stevhliu/my_awesome_minds_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+Get the class with the highest probability, and use the model's `id2label` mapping to convert it to a label:
+
+```py
+>>> import torch
+
+>>> predicted_class_ids = torch.argmax(logits).item()
+>>> predicted_label = model.config.id2label[predicted_class_ids]
+>>> predicted_label
+'cash_deposit'
+```
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/document_question_answering.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/document_question_answering.md
new file mode 100644
index 0000000000000000000000000000000000000000..d83e025c409019330f762b551f17e944a50de23b
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/document_question_answering.md
@@ -0,0 +1,492 @@
+
+
+# Document Question Answering
+
+[[open-in-colab]]
+
+Document Question Answering, also referred to as Document Visual Question Answering, is a task that involves providing
+answers to questions posed about document images. The input to models supporting this task is typically a combination of an image and
+a question, and the output is an answer expressed in natural language. These models utilize multiple modalities, including
+text, the positions of words (bounding boxes), and the image itself.
+
+This guide illustrates how to:
+
+- Fine-tune [LayoutLMv2](../model_doc/layoutlmv2) on the [DocVQA dataset](https://huggingface.co/datasets/nielsr/docvqa_1200_examples_donut).
+- Use your fine-tuned model for inference.
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/image-to-text)
+
+
+
+LayoutLMv2 solves the document question-answering task by adding a question-answering head on top of the final hidden
+states of the tokens, to predict the positions of the start and end tokens of the
+answer. In other words, the problem is treated as extractive question answering: given the context, extract which piece
+of information answers the question. The context comes from the output of an OCR engine, here it is Google's Tesseract.
+
+Before you begin, make sure you have all the necessary libraries installed. LayoutLMv2 depends on detectron2, torchvision and tesseract.
+
+```bash
+pip install -q transformers datasets
+```
+
+```bash
+pip install 'git+https://github.com/facebookresearch/detectron2.git'
+pip install torchvision
+```
+
+```bash
+sudo apt install tesseract-ocr
+pip install -q pytesseract
+```
+
+Once you have installed all of the dependencies, restart your runtime.
+
+We encourage you to share your model with the community. Log in to your Hugging Face account to upload it to the 🤗 Hub.
+When prompted, enter your token to log in:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+Let's define some global variables.
+
+```py
+>>> model_checkpoint = "microsoft/layoutlmv2-base-uncased"
+>>> batch_size = 4
+```
+
+## Load the data
+
+In this guide we use a small sample of preprocessed DocVQA that you can find on 🤗 Hub. If you'd like to use the full
+DocVQA dataset, you can register and download it on [DocVQA homepage](https://rrc.cvc.uab.es/?ch=17). If you do so, to
+proceed with this guide check out [how to load files into a 🤗 dataset](https://huggingface.co/docs/datasets/loading#local-and-remote-files).
+
+```py
+>>> from datasets import load_dataset
+
+>>> dataset = load_dataset("nielsr/docvqa_1200_examples")
+>>> dataset
+DatasetDict({
+ train: Dataset({
+ features: ['id', 'image', 'query', 'answers', 'words', 'bounding_boxes', 'answer'],
+ num_rows: 1000
+ })
+ test: Dataset({
+ features: ['id', 'image', 'query', 'answers', 'words', 'bounding_boxes', 'answer'],
+ num_rows: 200
+ })
+})
+```
+
+As you can see, the dataset is split into train and test sets already. Take a look at a random example to familiarize
+yourself with the features.
+
+```py
+>>> dataset["train"].features
+```
+
+Here's what the individual fields represent:
+* `id`: the example's id
+* `image`: a PIL.Image.Image object containing the document image
+* `query`: the question string - natural language asked question, in several languages
+* `answers`: a list of correct answers provided by human annotators
+* `words` and `bounding_boxes`: the results of OCR, which we will not use here
+* `answer`: an answer matched by a different model which we will not use here
+
+Let's leave only English questions, and drop the `answer` feature which appears to contain predictions by another model.
+We'll also take the first of the answers from the set provided by the annotators. Alternatively, you can randomly sample it.
+
+```py
+>>> updated_dataset = dataset.map(lambda example: {"question": example["query"]["en"]}, remove_columns=["query"])
+>>> updated_dataset = updated_dataset.map(
+... lambda example: {"answer": example["answers"][0]}, remove_columns=["answer", "answers"]
+... )
+```
+
+Note that the LayoutLMv2 checkpoint that we use in this guide has been trained with `max_position_embeddings = 512` (you can
+find this information in the [checkpoint's `config.json` file](https://huggingface.co/microsoft/layoutlmv2-base-uncased/blob/main/config.json#L18)).
+We can truncate the examples but to avoid the situation where the answer might be at the end of a large document and end up truncated,
+here we'll remove the few examples where the embedding is likely to end up longer than 512.
+If most of the documents in your dataset are long, you can implement a sliding window strategy - check out [this notebook](https://github.com/huggingface/notebooks/blob/main/examples/question_answering.ipynb) for details.
+
+```py
+>>> updated_dataset = updated_dataset.filter(lambda x: len(x["words"]) + len(x["question"].split()) < 512)
+```
+
+At this point let's also remove the OCR features from this dataset. These are a result of OCR for fine-tuning a different
+model. They would still require some processing if we wanted to use them, as they do not match the input requirements
+of the model we use in this guide. Instead, we can use the [`LayoutLMv2Processor`] on the original data for both OCR and
+tokenization. This way we'll get the inputs that match model's expected input. If you want to process images manually,
+check out the [`LayoutLMv2` model documentation](../model_doc/layoutlmv2) to learn what input format the model expects.
+
+```py
+>>> updated_dataset = updated_dataset.remove_columns("words")
+>>> updated_dataset = updated_dataset.remove_columns("bounding_boxes")
+```
+
+Finally, the data exploration won't be complete if we don't peek at an image example.
+
+```py
+>>> updated_dataset["train"][11]["image"]
+```
+
+
+
+
+
+## Preprocess the data
+
+The Document Question Answering task is a multimodal task, and you need to make sure that the inputs from each modality
+are preprocessed according to the model's expectations. Let's start by loading the [`LayoutLMv2Processor`], which internally combines an image processor that can handle image data and a tokenizer that can encode text data.
+
+```py
+>>> from transformers import AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained(model_checkpoint)
+```
+
+### Preprocessing document images
+
+First, let's prepare the document images for the model with the help of the `image_processor` from the processor.
+By default, image processor resizes the images to 224x224, makes sure they have the correct order of color channels,
+applies OCR with tesseract to get words and normalized bounding boxes. In this tutorial, all of these defaults are exactly what we need.
+Write a function that applies the default image processing to a batch of images and returns the results of OCR.
+
+```py
+>>> image_processor = processor.image_processor
+
+
+>>> def get_ocr_words_and_boxes(examples):
+... images = [image.convert("RGB") for image in examples["image"]]
+... encoded_inputs = image_processor(images)
+
+... examples["image"] = encoded_inputs.pixel_values
+... examples["words"] = encoded_inputs.words
+... examples["boxes"] = encoded_inputs.boxes
+
+... return examples
+```
+
+To apply this preprocessing to the entire dataset in a fast way, use [`~datasets.Dataset.map`].
+
+```py
+>>> dataset_with_ocr = updated_dataset.map(get_ocr_words_and_boxes, batched=True, batch_size=2)
+```
+
+### Preprocessing text data
+
+Once we have applied OCR to the images, we need to encode the text part of the dataset to prepare it for the model.
+This involves converting the words and boxes that we got in the previous step to token-level `input_ids`, `attention_mask`,
+`token_type_ids` and `bbox`. For preprocessing text, we'll need the `tokenizer` from the processor.
+
+```py
+>>> tokenizer = processor.tokenizer
+```
+
+On top of the preprocessing mentioned above, we also need to add the labels for the model. For `xxxForQuestionAnswering` models
+in 🤗 Transformers, the labels consist of the `start_positions` and `end_positions`, indicating which token is at the
+start and which token is at the end of the answer.
+
+Let's start with that. Define a helper function that can find a sublist (the answer split into words) in a larger list (the words list).
+
+This function will take two lists as input, `words_list` and `answer_list`. It will then iterate over the `words_list` and check
+if the current word in the `words_list` (words_list[i]) is equal to the first word of answer_list (answer_list[0]) and if
+the sublist of `words_list` starting from the current word and of the same length as `answer_list` is equal `to answer_list`.
+If this condition is true, it means that a match has been found, and the function will record the match, its starting index (idx),
+and its ending index (idx + len(answer_list) - 1). If more than one match was found, the function will return only the first one.
+If no match is found, the function returns (`None`, 0, and 0).
+
+```py
+>>> def subfinder(words_list, answer_list):
+... matches = []
+... start_indices = []
+... end_indices = []
+... for idx, i in enumerate(range(len(words_list))):
+... if words_list[i] == answer_list[0] and words_list[i : i + len(answer_list)] == answer_list:
+... matches.append(answer_list)
+... start_indices.append(idx)
+... end_indices.append(idx + len(answer_list) - 1)
+... if matches:
+... return matches[0], start_indices[0], end_indices[0]
+... else:
+... return None, 0, 0
+```
+
+To illustrate how this function finds the position of the answer, let's use it on an example:
+
+```py
+>>> example = dataset_with_ocr["train"][1]
+>>> words = [word.lower() for word in example["words"]]
+>>> match, word_idx_start, word_idx_end = subfinder(words, example["answer"].lower().split())
+>>> print("Question: ", example["question"])
+>>> print("Words:", words)
+>>> print("Answer: ", example["answer"])
+>>> print("start_index", word_idx_start)
+>>> print("end_index", word_idx_end)
+Question: Who is in cc in this letter?
+Words: ['wie', 'baw', 'brown', '&', 'williamson', 'tobacco', 'corporation', 'research', '&', 'development', 'internal', 'correspondence', 'to:', 'r.', 'h.', 'honeycutt', 'ce:', 't.f.', 'riehl', 'from:', '.', 'c.j.', 'cook', 'date:', 'may', '8,', '1995', 'subject:', 'review', 'of', 'existing', 'brainstorming', 'ideas/483', 'the', 'major', 'function', 'of', 'the', 'product', 'innovation', 'graup', 'is', 'to', 'develop', 'marketable', 'nove!', 'products', 'that', 'would', 'be', 'profitable', 'to', 'manufacture', 'and', 'sell.', 'novel', 'is', 'defined', 'as:', 'of', 'a', 'new', 'kind,', 'or', 'different', 'from', 'anything', 'seen', 'or', 'known', 'before.', 'innovation', 'is', 'defined', 'as:', 'something', 'new', 'or', 'different', 'introduced;', 'act', 'of', 'innovating;', 'introduction', 'of', 'new', 'things', 'or', 'methods.', 'the', 'products', 'may', 'incorporate', 'the', 'latest', 'technologies,', 'materials', 'and', 'know-how', 'available', 'to', 'give', 'then', 'a', 'unique', 'taste', 'or', 'look.', 'the', 'first', 'task', 'of', 'the', 'product', 'innovation', 'group', 'was', 'to', 'assemble,', 'review', 'and', 'categorize', 'a', 'list', 'of', 'existing', 'brainstorming', 'ideas.', 'ideas', 'were', 'grouped', 'into', 'two', 'major', 'categories', 'labeled', 'appearance', 'and', 'taste/aroma.', 'these', 'categories', 'are', 'used', 'for', 'novel', 'products', 'that', 'may', 'differ', 'from', 'a', 'visual', 'and/or', 'taste/aroma', 'point', 'of', 'view', 'compared', 'to', 'canventional', 'cigarettes.', 'other', 'categories', 'include', 'a', 'combination', 'of', 'the', 'above,', 'filters,', 'packaging', 'and', 'brand', 'extensions.', 'appearance', 'this', 'category', 'is', 'used', 'for', 'novel', 'cigarette', 'constructions', 'that', 'yield', 'visually', 'different', 'products', 'with', 'minimal', 'changes', 'in', 'smoke', 'chemistry', 'two', 'cigarettes', 'in', 'cne.', 'emulti-plug', 'te', 'build', 'yaur', 'awn', 'cigarette.', 'eswitchable', 'menthol', 'or', 'non', 'menthol', 'cigarette.', '*cigarettes', 'with', 'interspaced', 'perforations', 'to', 'enable', 'smoker', 'to', 'separate', 'unburned', 'section', 'for', 'future', 'smoking.', '«short', 'cigarette,', 'tobacco', 'section', '30', 'mm.', '«extremely', 'fast', 'buming', 'cigarette.', '«novel', 'cigarette', 'constructions', 'that', 'permit', 'a', 'significant', 'reduction', 'iretobacco', 'weight', 'while', 'maintaining', 'smoking', 'mechanics', 'and', 'visual', 'characteristics.', 'higher', 'basis', 'weight', 'paper:', 'potential', 'reduction', 'in', 'tobacco', 'weight.', '«more', 'rigid', 'tobacco', 'column;', 'stiffing', 'agent', 'for', 'tobacco;', 'e.g.', 'starch', '*colored', 'tow', 'and', 'cigarette', 'papers;', 'seasonal', 'promotions,', 'e.g.', 'pastel', 'colored', 'cigarettes', 'for', 'easter', 'or', 'in', 'an', 'ebony', 'and', 'ivory', 'brand', 'containing', 'a', 'mixture', 'of', 'all', 'black', '(black', 'paper', 'and', 'tow)', 'and', 'ail', 'white', 'cigarettes.', '499150498']
+Answer: T.F. Riehl
+start_index 17
+end_index 18
+```
+
+Once examples are encoded, however, they will look like this:
+
+```py
+>>> encoding = tokenizer(example["question"], example["words"], example["boxes"])
+>>> tokenizer.decode(encoding["input_ids"])
+[CLS] who is in cc in this letter? [SEP] wie baw brown & williamson tobacco corporation research & development ...
+```
+
+We'll need to find the position of the answer in the encoded input.
+* `token_type_ids` tells us which tokens are part of the question, and which ones are part of the document's words.
+* `tokenizer.cls_token_id` will help find the special token at the beginning of the input.
+* `word_ids` will help match the answer found in the original `words` to the same answer in the full encoded input and determine
+the start/end position of the answer in the encoded input.
+
+With that in mind, let's create a function to encode a batch of examples in the dataset:
+
+```py
+>>> def encode_dataset(examples, max_length=512):
+... questions = examples["question"]
+... words = examples["words"]
+... boxes = examples["boxes"]
+... answers = examples["answer"]
+
+... # encode the batch of examples and initialize the start_positions and end_positions
+... encoding = tokenizer(questions, words, boxes, max_length=max_length, padding="max_length", truncation=True)
+... start_positions = []
+... end_positions = []
+
+... # loop through the examples in the batch
+... for i in range(len(questions)):
+... cls_index = encoding["input_ids"][i].index(tokenizer.cls_token_id)
+
+... # find the position of the answer in example's words
+... words_example = [word.lower() for word in words[i]]
+... answer = answers[i]
+... match, word_idx_start, word_idx_end = subfinder(words_example, answer.lower().split())
+
+... if match:
+... # if match is found, use `token_type_ids` to find where words start in the encoding
+... token_type_ids = encoding["token_type_ids"][i]
+... token_start_index = 0
+... while token_type_ids[token_start_index] != 1:
+... token_start_index += 1
+
+... token_end_index = len(encoding["input_ids"][i]) - 1
+... while token_type_ids[token_end_index] != 1:
+... token_end_index -= 1
+
+... word_ids = encoding.word_ids(i)[token_start_index : token_end_index + 1]
+... start_position = cls_index
+... end_position = cls_index
+
+... # loop over word_ids and increase `token_start_index` until it matches the answer position in words
+... # once it matches, save the `token_start_index` as the `start_position` of the answer in the encoding
+... for id in word_ids:
+... if id == word_idx_start:
+... start_position = token_start_index
+... else:
+... token_start_index += 1
+
+... # similarly loop over `word_ids` starting from the end to find the `end_position` of the answer
+... for id in word_ids[::-1]:
+... if id == word_idx_end:
+... end_position = token_end_index
+... else:
+... token_end_index -= 1
+
+... start_positions.append(start_position)
+... end_positions.append(end_position)
+
+... else:
+... start_positions.append(cls_index)
+... end_positions.append(cls_index)
+
+... encoding["image"] = examples["image"]
+... encoding["start_positions"] = start_positions
+... encoding["end_positions"] = end_positions
+
+... return encoding
+```
+
+Now that we have this preprocessing function, we can encode the entire dataset:
+
+```py
+>>> encoded_train_dataset = dataset_with_ocr["train"].map(
+... encode_dataset, batched=True, batch_size=2, remove_columns=dataset_with_ocr["train"].column_names
+... )
+>>> encoded_test_dataset = dataset_with_ocr["test"].map(
+... encode_dataset, batched=True, batch_size=2, remove_columns=dataset_with_ocr["test"].column_names
+... )
+```
+
+Let's check what the features of the encoded dataset look like:
+
+```py
+>>> encoded_train_dataset.features
+{'image': Sequence(feature=Sequence(feature=Sequence(feature=Value(dtype='uint8', id=None), length=-1, id=None), length=-1, id=None), length=-1, id=None),
+ 'input_ids': Sequence(feature=Value(dtype='int32', id=None), length=-1, id=None),
+ 'token_type_ids': Sequence(feature=Value(dtype='int8', id=None), length=-1, id=None),
+ 'attention_mask': Sequence(feature=Value(dtype='int8', id=None), length=-1, id=None),
+ 'bbox': Sequence(feature=Sequence(feature=Value(dtype='int64', id=None), length=-1, id=None), length=-1, id=None),
+ 'start_positions': Value(dtype='int64', id=None),
+ 'end_positions': Value(dtype='int64', id=None)}
+```
+
+## Evaluation
+
+Evaluation for document question answering requires a significant amount of postprocessing. To avoid taking up too much
+of your time, this guide skips the evaluation step. The [`Trainer`] still calculates the evaluation loss during training so
+you're not completely in the dark about your model's performance. Extractive question answering is typically evaluated using F1/exact match.
+If you'd like to implement it yourself, check out the [Question Answering chapter](https://huggingface.co/course/chapter7/7?fw=pt#postprocessing)
+of the Hugging Face course for inspiration.
+
+## Train
+
+Congratulations! You've successfully navigated the toughest part of this guide and now you are ready to train your own model.
+Training involves the following steps:
+* Load the model with [`AutoModelForDocumentQuestionAnswering`] using the same checkpoint as in the preprocessing.
+* Define your training hyperparameters in [`TrainingArguments`].
+* Define a function to batch examples together, here the [`DefaultDataCollator`] will do just fine
+* Pass the training arguments to [`Trainer`] along with the model, dataset, and data collator.
+* Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> from transformers import AutoModelForDocumentQuestionAnswering
+
+>>> model = AutoModelForDocumentQuestionAnswering.from_pretrained(model_checkpoint)
+```
+
+In the [`TrainingArguments`] use `output_dir` to specify where to save your model, and configure hyperparameters as you see fit.
+If you wish to share your model with the community, set `push_to_hub` to `True` (you must be signed in to Hugging Face to upload your model).
+In this case the `output_dir` will also be the name of the repo where your model checkpoint will be pushed.
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> # REPLACE THIS WITH YOUR REPO ID
+>>> repo_id = "MariaK/layoutlmv2-base-uncased_finetuned_docvqa"
+
+>>> training_args = TrainingArguments(
+... output_dir=repo_id,
+... per_device_train_batch_size=4,
+... num_train_epochs=20,
+... save_steps=200,
+... logging_steps=50,
+... eval_strategy="steps",
+... learning_rate=5e-5,
+... save_total_limit=2,
+... remove_unused_columns=False,
+... push_to_hub=True,
+... )
+```
+
+Define a simple data collator to batch examples together.
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator()
+```
+
+Finally, bring everything together, and call [`~Trainer.train`]:
+
+```py
+>>> from transformers import Trainer
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... data_collator=data_collator,
+... train_dataset=encoded_train_dataset,
+... eval_dataset=encoded_test_dataset,
+... processing_class=processor,
+... )
+
+>>> trainer.train()
+```
+
+To add the final model to 🤗 Hub, create a model card and call `push_to_hub`:
+
+```py
+>>> trainer.create_model_card()
+>>> trainer.push_to_hub()
+```
+
+## Inference
+
+Now that you have finetuned a LayoutLMv2 model, and uploaded it to the 🤗 Hub, you can use it for inference. The simplest
+way to try out your finetuned model for inference is to use it in a [`Pipeline`].
+
+Let's take an example:
+```py
+>>> example = dataset["test"][2]
+>>> question = example["query"]["en"]
+>>> image = example["image"]
+>>> print(question)
+>>> print(example["answers"])
+'Who is ‘presiding’ TRRF GENERAL SESSION (PART 1)?'
+['TRRF Vice President', 'lee a. waller']
+```
+
+Next, instantiate a pipeline for
+document question answering with your model, and pass the image + question combination to it.
+
+```py
+>>> from transformers import pipeline
+
+>>> qa_pipeline = pipeline("document-question-answering", model="MariaK/layoutlmv2-base-uncased_finetuned_docvqa")
+>>> qa_pipeline(image, question)
+[{'score': 0.9949808120727539,
+ 'answer': 'Lee A. Waller',
+ 'start': 55,
+ 'end': 57}]
+```
+
+You can also manually replicate the results of the pipeline if you'd like:
+1. Take an image and a question, prepare them for the model using the processor from your model.
+2. Forward the result or preprocessing through the model.
+3. The model returns `start_logits` and `end_logits`, which indicate which token is at the start of the answer and
+which token is at the end of the answer. Both have shape (batch_size, sequence_length).
+4. Take an argmax on the last dimension of both the `start_logits` and `end_logits` to get the predicted `start_idx` and `end_idx`.
+5. Decode the answer with the tokenizer.
+
+```py
+>>> import torch
+>>> from transformers import AutoProcessor
+>>> from transformers import AutoModelForDocumentQuestionAnswering
+
+>>> processor = AutoProcessor.from_pretrained("MariaK/layoutlmv2-base-uncased_finetuned_docvqa")
+>>> model = AutoModelForDocumentQuestionAnswering.from_pretrained("MariaK/layoutlmv2-base-uncased_finetuned_docvqa")
+
+>>> with torch.no_grad():
+... encoding = processor(image.convert("RGB"), question, return_tensors="pt")
+... outputs = model(**encoding)
+... start_logits = outputs.start_logits
+... end_logits = outputs.end_logits
+... predicted_start_idx = start_logits.argmax(-1).item()
+... predicted_end_idx = end_logits.argmax(-1).item()
+
+>>> processor.tokenizer.decode(encoding.input_ids.squeeze()[predicted_start_idx : predicted_end_idx + 1])
+'lee a. waller'
+```
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/idefics.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/idefics.md
new file mode 100644
index 0000000000000000000000000000000000000000..81ab60fecd0cb87beaccaa1362f39855c4c4892f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/idefics.md
@@ -0,0 +1,423 @@
+
+
+# Image tasks with IDEFICS
+
+[[open-in-colab]]
+
+While individual tasks can be tackled by fine-tuning specialized models, an alternative approach
+that has recently emerged and gained popularity is to use large models for a diverse set of tasks without fine-tuning.
+For instance, large language models can handle such NLP tasks as summarization, translation, classification, and more.
+This approach is no longer limited to a single modality, such as text, and in this guide, we will illustrate how you can
+solve image-text tasks with a large multimodal model called IDEFICS.
+
+[IDEFICS](../model_doc/idefics) is an open-access vision and language model based on [Flamingo](https://huggingface.co/papers/2204.14198),
+a state-of-the-art visual language model initially developed by DeepMind. The model accepts arbitrary sequences of image
+and text inputs and generates coherent text as output. It can answer questions about images, describe visual content,
+create stories grounded in multiple images, and so on. IDEFICS comes in two variants - [80 billion parameters](https://huggingface.co/HuggingFaceM4/idefics-80b)
+and [9 billion parameters](https://huggingface.co/HuggingFaceM4/idefics-9b), both of which are available on the 🤗 Hub. For each variant, you can also find fine-tuned instructed
+versions of the model adapted for conversational use cases.
+
+This model is exceptionally versatile and can be used for a wide range of image and multimodal tasks. However,
+being a large model means it requires significant computational resources and infrastructure. It is up to you to decide whether
+this approach suits your use case better than fine-tuning specialized models for each individual task.
+
+In this guide, you'll learn how to:
+- [Load IDEFICS](#loading-the-model) and [load the quantized version of the model](#quantized-model)
+- Use IDEFICS for:
+ - [Image captioning](#image-captioning)
+ - [Prompted image captioning](#prompted-image-captioning)
+ - [Few-shot prompting](#few-shot-prompting)
+ - [Visual question answering](#visual-question-answering)
+ - [Image classification](#image-classification)
+ - [Image-guided text generation](#image-guided-text-generation)
+- [Run inference in batch mode](#running-inference-in-batch-mode)
+- [Run IDEFICS instruct for conversational use](#idefics-instruct-for-conversational-use)
+
+Before you begin, make sure you have all the necessary libraries installed.
+
+```bash
+pip install -q bitsandbytes sentencepiece accelerate transformers
+```
+
+
+To run the following examples with a non-quantized version of the model checkpoint you will need at least 20GB of GPU memory.
+
+
+## Loading the model
+
+Let's start by loading the model's 9 billion parameters checkpoint:
+
+```py
+>>> checkpoint = "HuggingFaceM4/idefics-9b"
+```
+
+Just like for other Transformers models, you need to load a processor and the model itself from the checkpoint.
+The IDEFICS processor wraps a [`LlamaTokenizer`] and IDEFICS image processor into a single processor to take care of
+preparing text and image inputs for the model.
+
+```py
+>>> import torch
+
+>>> from transformers import IdeficsForVisionText2Text, AutoProcessor
+
+>>> processor = AutoProcessor.from_pretrained(checkpoint)
+
+>>> model = IdeficsForVisionText2Text.from_pretrained(checkpoint, torch_dtype=torch.bfloat16, device_map="auto")
+```
+
+Setting `device_map` to `"auto"` will automatically determine how to load and store the model weights in the most optimized
+manner given existing devices.
+
+### Quantized model
+
+If high-memory device availability is an issue, you can load the quantized version of the model. To load the model and the
+processor in 4bit precision, pass a `BitsAndBytesConfig` to the `from_pretrained` method and the model will be compressed
+on the fly while loading.
+
+```py
+>>> import torch
+>>> from transformers import IdeficsForVisionText2Text, AutoProcessor, BitsAndBytesConfig
+
+>>> quantization_config = BitsAndBytesConfig(
+... load_in_4bit=True,
+... bnb_4bit_compute_dtype=torch.float16,
+... )
+
+>>> processor = AutoProcessor.from_pretrained(checkpoint)
+
+>>> model = IdeficsForVisionText2Text.from_pretrained(
+... checkpoint,
+... quantization_config=quantization_config,
+... device_map="auto"
+... )
+```
+
+Now that you have the model loaded in one of the suggested ways, let's move on to exploring tasks that you can use IDEFICS for.
+
+## Image captioning
+Image captioning is the task of predicting a caption for a given image. A common application is to aid visually impaired
+people navigate through different situations, for instance, explore image content online.
+
+To illustrate the task, get an image to be captioned, e.g.:
+
+
+
+
+
+Photo by [Hendo Wang](https://unsplash.com/@hendoo).
+
+IDEFICS accepts text and image prompts. However, to caption an image, you do not have to provide a text prompt to the
+model, only the preprocessed input image. Without a text prompt, the model will start generating text from the
+BOS (beginning-of-sequence) token thus creating a caption.
+
+As image input to the model, you can use either an image object (`PIL.Image`) or a url from which the image can be retrieved.
+
+```py
+>>> prompt = [
+... "https://images.unsplash.com/photo-1583160247711-2191776b4b91?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3542&q=80",
+... ]
+
+>>> inputs = processor(prompt, return_tensors="pt").to(model.device)
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+A puppy in a flower bed
+```
+
+
+
+It is a good idea to include the `bad_words_ids` in the call to `generate` to avoid errors arising when increasing
+the `max_new_tokens`: the model will want to generate a new `` or `` token when there
+is no image being generated by the model.
+You can set it on-the-fly as in this guide, or store in the `GenerationConfig` as described in the [Text generation strategies](../generation_strategies) guide.
+
+
+## Prompted image captioning
+
+You can extend image captioning by providing a text prompt, which the model will continue given the image. Let's take
+another image to illustrate:
+
+
+
+
+
+Photo by [Denys Nevozhai](https://unsplash.com/@dnevozhai).
+
+Textual and image prompts can be passed to the model's processor as a single list to create appropriate inputs.
+
+```py
+>>> prompt = [
+... "https://images.unsplash.com/photo-1543349689-9a4d426bee8e?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3501&q=80",
+... "This is an image of ",
+... ]
+
+>>> inputs = processor(prompt, return_tensors="pt").to(model.device)
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+This is an image of the Eiffel Tower in Paris, France.
+```
+
+## Few-shot prompting
+
+While IDEFICS demonstrates great zero-shot results, your task may require a certain format of the caption, or come with
+other restrictions or requirements that increase task's complexity. Few-shot prompting can be used to enable in-context learning.
+By providing examples in the prompt, you can steer the model to generate results that mimic the format of given examples.
+
+Let's use the previous image of the Eiffel Tower as an example for the model and build a prompt that demonstrates to the model
+that in addition to learning what the object in an image is, we would also like to get some interesting information about it.
+Then, let's see, if we can get the same response format for an image of the Statue of Liberty:
+
+
+
+
+
+Photo by [Juan Mayobre](https://unsplash.com/@jmayobres).
+
+```py
+>>> prompt = ["User:",
+... "https://images.unsplash.com/photo-1543349689-9a4d426bee8e?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3501&q=80",
+... "Describe this image.\nAssistant: An image of the Eiffel Tower at night. Fun fact: the Eiffel Tower is the same height as an 81-storey building.\n",
+... "User:",
+... "https://images.unsplash.com/photo-1524099163253-32b7f0256868?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3387&q=80",
+... "Describe this image.\nAssistant:"
+... ]
+
+>>> inputs = processor(prompt, return_tensors="pt").to(model.device)
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=30, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+User: Describe this image.
+Assistant: An image of the Eiffel Tower at night. Fun fact: the Eiffel Tower is the same height as an 81-storey building.
+User: Describe this image.
+Assistant: An image of the Statue of Liberty. Fun fact: the Statue of Liberty is 151 feet tall.
+```
+
+Notice that just from a single example (i.e., 1-shot) the model has learned how to perform the task. For more complex tasks,
+feel free to experiment with a larger number of examples (e.g., 3-shot, 5-shot, etc.).
+
+## Visual question answering
+
+Visual Question Answering (VQA) is the task of answering open-ended questions based on an image. Similar to image
+captioning it can be used in accessibility applications, but also in education (reasoning about visual materials), customer
+service (questions about products based on images), and image retrieval.
+
+Let's get a new image for this task:
+
+
+
+
+
+Photo by [Jarritos Mexican Soda](https://unsplash.com/@jarritos).
+
+You can steer the model from image captioning to visual question answering by prompting it with appropriate instructions:
+
+```py
+>>> prompt = [
+... "Instruction: Provide an answer to the question. Use the image to answer.\n",
+... "https://images.unsplash.com/photo-1623944889288-cd147dbb517c?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "Question: Where are these people and what's the weather like? Answer:"
+... ]
+
+>>> inputs = processor(prompt, return_tensors="pt").to(model.device)
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=20, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+Instruction: Provide an answer to the question. Use the image to answer.
+ Question: Where are these people and what's the weather like? Answer: They're in a park in New York City, and it's a beautiful day.
+```
+
+## Image classification
+
+IDEFICS is capable of classifying images into different categories without being explicitly trained on data containing
+labeled examples from those specific categories. Given a list of categories and using its image and text understanding
+capabilities, the model can infer which category the image likely belongs to.
+
+Say, we have this image of a vegetable stand:
+
+
+
+
+
+Photo by [Peter Wendt](https://unsplash.com/@peterwendt).
+
+We can instruct the model to classify the image into one of the categories that we have:
+
+```py
+>>> categories = ['animals','vegetables', 'city landscape', 'cars', 'office']
+>>> prompt = [f"Instruction: Classify the following image into a single category from the following list: {categories}.\n",
+... "https://images.unsplash.com/photo-1471193945509-9ad0617afabf?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "Category: "
+... ]
+
+>>> inputs = processor(prompt, return_tensors="pt").to(model.device)
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=6, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+Instruction: Classify the following image into a single category from the following list: ['animals', 'vegetables', 'city landscape', 'cars', 'office'].
+Category: Vegetables
+```
+
+In the example above we instruct the model to classify the image into a single category, however, you can also prompt the model to do rank classification.
+
+## Image-guided text generation
+
+For more creative applications, you can use image-guided text generation to generate text based on an image. This can be
+useful to create descriptions of products, ads, descriptions of a scene, etc.
+
+Let's prompt IDEFICS to write a story based on a simple image of a red door:
+
+
+
+
+
+Photo by [Craig Tidball](https://unsplash.com/@devonshiremedia).
+
+```py
+>>> prompt = ["Instruction: Use the image to write a story. \n",
+... "https://images.unsplash.com/photo-1517086822157-2b0358e7684a?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=2203&q=80",
+... "Story: \n"]
+
+>>> inputs = processor(prompt, return_tensors="pt").to(model.device)
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, num_beams=2, max_new_tokens=200, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> print(generated_text[0])
+Instruction: Use the image to write a story.
+ Story:
+Once upon a time, there was a little girl who lived in a house with a red door. She loved her red door. It was the prettiest door in the whole world.
+
+One day, the little girl was playing in her yard when she noticed a man standing on her doorstep. He was wearing a long black coat and a top hat.
+
+The little girl ran inside and told her mother about the man.
+
+Her mother said, “Don’t worry, honey. He’s just a friendly ghost.”
+
+The little girl wasn’t sure if she believed her mother, but she went outside anyway.
+
+When she got to the door, the man was gone.
+
+The next day, the little girl was playing in her yard again when she noticed the man standing on her doorstep.
+
+He was wearing a long black coat and a top hat.
+
+The little girl ran
+```
+
+Looks like IDEFICS noticed the pumpkin on the doorstep and went with a spooky Halloween story about a ghost.
+
+
+
+For longer outputs like this, you will greatly benefit from tweaking the text generation strategy. This can help
+you significantly improve the quality of the generated output. Check out [Text generation strategies](../generation_strategies)
+to learn more.
+
+
+## Running inference in batch mode
+
+All of the earlier sections illustrated IDEFICS for a single example. In a very similar fashion, you can run inference
+for a batch of examples by passing a list of prompts:
+
+```py
+>>> prompts = [
+... [ "https://images.unsplash.com/photo-1543349689-9a4d426bee8e?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3501&q=80",
+... "This is an image of ",
+... ],
+... [ "https://images.unsplash.com/photo-1623944889288-cd147dbb517c?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "This is an image of ",
+... ],
+... [ "https://images.unsplash.com/photo-1471193945509-9ad0617afabf?ixlib=rb-4.0.3&ixid=M3wxMjA3fDB8MHxwaG90by1wYWdlfHx8fGVufDB8fHx8fA%3D%3D&auto=format&fit=crop&w=3540&q=80",
+... "This is an image of ",
+... ],
+... ]
+
+>>> inputs = processor(prompts, return_tensors="pt").to(model.device)
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, max_new_tokens=10, bad_words_ids=bad_words_ids)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> for i,t in enumerate(generated_text):
+... print(f"{i}:\n{t}\n")
+0:
+This is an image of the Eiffel Tower in Paris, France.
+
+1:
+This is an image of a couple on a picnic blanket.
+
+2:
+This is an image of a vegetable stand.
+```
+
+## IDEFICS instruct for conversational use
+
+For conversational use cases, you can find fine-tuned instructed versions of the model on the 🤗 Hub:
+`HuggingFaceM4/idefics-80b-instruct` and `HuggingFaceM4/idefics-9b-instruct`.
+
+These checkpoints are the result of fine-tuning the respective base models on a mixture of supervised and instruction
+fine-tuning datasets, which boosts the downstream performance while making the models more usable in conversational settings.
+
+The use and prompting for the conversational use is very similar to using the base models:
+
+```py
+>>> import torch
+>>> from transformers import IdeficsForVisionText2Text, AutoProcessor
+
+>>> checkpoint = "HuggingFaceM4/idefics-9b-instruct"
+>>> model = IdeficsForVisionText2Text.from_pretrained(checkpoint, torch_dtype=torch.bfloat16, device_map="auto")
+>>> processor = AutoProcessor.from_pretrained(checkpoint)
+
+>>> prompts = [
+... [
+... "User: What is in this image?",
+... "https://upload.wikimedia.org/wikipedia/commons/8/86/Id%C3%A9fix.JPG",
+... "",
+
+... "\nAssistant: This picture depicts Idefix, the dog of Obelix in Asterix and Obelix. Idefix is running on the ground.",
+
+... "\nUser:",
+... "https://static.wikia.nocookie.net/asterix/images/2/25/R22b.gif/revision/latest?cb=20110815073052",
+... "And who is that?",
+
+... "\nAssistant:",
+... ],
+... ]
+
+>>> # --batched mode
+>>> inputs = processor(prompts, add_end_of_utterance_token=False, return_tensors="pt").to(model.device)
+>>> # --single sample mode
+>>> # inputs = processor(prompts[0], return_tensors="pt").to(model.device)
+
+>>> # Generation args
+>>> exit_condition = processor.tokenizer("", add_special_tokens=False).input_ids
+>>> bad_words_ids = processor.tokenizer(["", ""], add_special_tokens=False).input_ids
+
+>>> generated_ids = model.generate(**inputs, eos_token_id=exit_condition, bad_words_ids=bad_words_ids, max_length=100)
+>>> generated_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+>>> for i, t in enumerate(generated_text):
+... print(f"{i}:\n{t}\n")
+```
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/image_captioning.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/image_captioning.md
new file mode 100644
index 0000000000000000000000000000000000000000..f9716f29a20447152c78eb8af7b25f3e16d57bc8
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/image_captioning.md
@@ -0,0 +1,277 @@
+
+
+
+# Image captioning
+
+[[open-in-colab]]
+
+Image captioning is the task of predicting a caption for a given image. Common real world applications of it include
+aiding visually impaired people that can help them navigate through different situations. Therefore, image captioning
+helps to improve content accessibility for people by describing images to them.
+
+This guide will show you how to:
+
+* Fine-tune an image captioning model.
+* Use the fine-tuned model for inference.
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate -q
+pip install jiwer -q
+```
+
+We encourage you to log in to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to log in:
+
+
+```python
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+## Load the Pokémon BLIP captions dataset
+
+Use the 🤗 Dataset library to load a dataset that consists of {image-caption} pairs. To create your own image captioning dataset
+in PyTorch, you can follow [this notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/GIT/Fine_tune_GIT_on_an_image_captioning_dataset.ipynb).
+
+
+```python
+from datasets import load_dataset
+
+ds = load_dataset("lambdalabs/pokemon-blip-captions")
+ds
+```
+```bash
+DatasetDict({
+ train: Dataset({
+ features: ['image', 'text'],
+ num_rows: 833
+ })
+})
+```
+
+The dataset has two features, `image` and `text`.
+
+
+
+Many image captioning datasets contain multiple captions per image. In those cases, a common strategy is to randomly sample a caption amongst the available ones during training.
+
+
+
+Split the dataset’s train split into a train and test set with the [`~datasets.Dataset.train_test_split`] method:
+
+
+```python
+ds = ds["train"].train_test_split(test_size=0.1)
+train_ds = ds["train"]
+test_ds = ds["test"]
+```
+
+Let's visualize a couple of samples from the training set.
+
+
+```python
+from textwrap import wrap
+import matplotlib.pyplot as plt
+import numpy as np
+
+
+def plot_images(images, captions):
+ plt.figure(figsize=(20, 20))
+ for i in range(len(images)):
+ ax = plt.subplot(1, len(images), i + 1)
+ caption = captions[i]
+ caption = "\n".join(wrap(caption, 12))
+ plt.title(caption)
+ plt.imshow(images[i])
+ plt.axis("off")
+
+
+sample_images_to_visualize = [np.array(train_ds[i]["image"]) for i in range(5)]
+sample_captions = [train_ds[i]["text"] for i in range(5)]
+plot_images(sample_images_to_visualize, sample_captions)
+```
+
+
+
+
+
+## Preprocess the dataset
+
+Since the dataset has two modalities (image and text), the pre-processing pipeline will preprocess images and the captions.
+
+To do so, load the processor class associated with the model you are about to fine-tune.
+
+```python
+from transformers import AutoProcessor
+
+checkpoint = "microsoft/git-base"
+processor = AutoProcessor.from_pretrained(checkpoint)
+```
+
+The processor will internally pre-process the image (which includes resizing, and pixel scaling) and tokenize the caption.
+
+```python
+def transforms(example_batch):
+ images = [x for x in example_batch["image"]]
+ captions = [x for x in example_batch["text"]]
+ inputs = processor(images=images, text=captions, padding="max_length")
+ inputs.update({"labels": inputs["input_ids"]})
+ return inputs
+
+
+train_ds.set_transform(transforms)
+test_ds.set_transform(transforms)
+```
+
+With the dataset ready, you can now set up the model for fine-tuning.
+
+## Load a base model
+
+Load the ["microsoft/git-base"](https://huggingface.co/microsoft/git-base) into a [`AutoModelForCausalLM`](https://huggingface.co/docs/transformers/model_doc/auto#transformers.AutoModelForCausalLM) object.
+
+
+```python
+from transformers import AutoModelForCausalLM
+
+model = AutoModelForCausalLM.from_pretrained(checkpoint)
+```
+
+## Evaluate
+
+Image captioning models are typically evaluated with the [Rouge Score](https://huggingface.co/spaces/evaluate-metric/rouge) or [Word Error Rate](https://huggingface.co/spaces/evaluate-metric/wer). For this guide, you will use the Word Error Rate (WER).
+
+We use the 🤗 Evaluate library to do so. For potential limitations and other gotchas of the WER, refer to [this guide](https://huggingface.co/spaces/evaluate-metric/wer).
+
+
+```python
+from evaluate import load
+import torch
+
+wer = load("wer")
+
+
+def compute_metrics(eval_pred):
+ logits, labels = eval_pred
+ predicted = logits.argmax(-1)
+ decoded_labels = processor.batch_decode(labels, skip_special_tokens=True)
+ decoded_predictions = processor.batch_decode(predicted, skip_special_tokens=True)
+ wer_score = wer.compute(predictions=decoded_predictions, references=decoded_labels)
+ return {"wer_score": wer_score}
+```
+
+## Train!
+
+Now, you are ready to start fine-tuning the model. You will use the 🤗 [`Trainer`] for this.
+
+First, define the training arguments using [`TrainingArguments`].
+
+
+```python
+from transformers import TrainingArguments, Trainer
+
+model_name = checkpoint.split("/")[1]
+
+training_args = TrainingArguments(
+ output_dir=f"{model_name}-pokemon",
+ learning_rate=5e-5,
+ num_train_epochs=50,
+ fp16=True,
+ per_device_train_batch_size=32,
+ per_device_eval_batch_size=32,
+ gradient_accumulation_steps=2,
+ save_total_limit=3,
+ eval_strategy="steps",
+ eval_steps=50,
+ save_strategy="steps",
+ save_steps=50,
+ logging_steps=50,
+ remove_unused_columns=False,
+ push_to_hub=True,
+ label_names=["labels"],
+ load_best_model_at_end=True,
+)
+```
+
+Then pass them along with the datasets and the model to 🤗 Trainer.
+
+```python
+trainer = Trainer(
+ model=model,
+ args=training_args,
+ train_dataset=train_ds,
+ eval_dataset=test_ds,
+ compute_metrics=compute_metrics,
+)
+```
+
+To start training, simply call [`~Trainer.train`] on the [`Trainer`] object.
+
+```python
+trainer.train()
+```
+
+You should see the training loss drop smoothly as training progresses.
+
+Once training is completed, share your model to the Hub with the [`~Trainer.push_to_hub`] method so everyone can use your model:
+
+
+```python
+trainer.push_to_hub()
+```
+
+## Inference
+
+Take a sample image from `test_ds` to test the model.
+
+
+```python
+from PIL import Image
+import requests
+
+url = "https://huggingface.co/datasets/sayakpaul/sample-datasets/resolve/main/pokemon.png"
+image = Image.open(requests.get(url, stream=True).raw)
+image
+```
+
+
+
+
+
+Prepare image for the model.
+
+```python
+from transformers import infer_device
+
+device = infer_device()
+inputs = processor(images=image, return_tensors="pt").to(device)
+pixel_values = inputs.pixel_values
+```
+
+Call [`generate`] and decode the predictions.
+
+```python
+generated_ids = model.generate(pixel_values=pixel_values, max_length=50)
+generated_caption = processor.batch_decode(generated_ids, skip_special_tokens=True)[0]
+print(generated_caption)
+```
+```bash
+a drawing of a pink and blue pokemon
+```
+
+Looks like the fine-tuned model generated a pretty good caption!
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/image_classification.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/image_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..49fdc9db60d4d7650a4ef85c506f7fb4a3f2f0ef
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/image_classification.md
@@ -0,0 +1,542 @@
+
+
+# Image classification
+
+[[open-in-colab]]
+
+
+
+Image classification assigns a label or class to an image. Unlike text or audio classification, the inputs are the
+pixel values that comprise an image. There are many applications for image classification, such as detecting damage
+after a natural disaster, monitoring crop health, or helping screen medical images for signs of disease.
+
+This guide illustrates how to:
+
+1. Fine-tune [ViT](../model_doc/vit) on the [Food-101](https://huggingface.co/datasets/food101) dataset to classify a food item in an image.
+2. Use your fine-tuned model for inference.
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/image-classification)
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate accelerate pillow torchvision scikit-learn
+```
+
+We encourage you to log in to your Hugging Face account to upload and share your model with the community. When prompted, enter your token to log in:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load Food-101 dataset
+
+Start by loading a smaller subset of the Food-101 dataset from the 🤗 Datasets library. This will give you a chance to
+experiment and make sure everything works before spending more time training on the full dataset.
+
+```py
+>>> from datasets import load_dataset
+
+>>> food = load_dataset("food101", split="train[:5000]")
+```
+
+Split the dataset's `train` split into a train and test set with the [`~datasets.Dataset.train_test_split`] method:
+
+```py
+>>> food = food.train_test_split(test_size=0.2)
+```
+
+Then take a look at an example:
+
+```py
+>>> food["train"][0]
+{'image': ,
+ 'label': 79}
+```
+
+Each example in the dataset has two fields:
+
+- `image`: a PIL image of the food item
+- `label`: the label class of the food item
+
+To make it easier for the model to get the label name from the label id, create a dictionary that maps the label name
+to an integer and vice versa:
+
+```py
+>>> labels = food["train"].features["label"].names
+>>> label2id, id2label = dict(), dict()
+>>> for i, label in enumerate(labels):
+... label2id[label] = str(i)
+... id2label[str(i)] = label
+```
+
+Now you can convert the label id to a label name:
+
+```py
+>>> id2label[str(79)]
+'prime_rib'
+```
+
+## Preprocess
+
+The next step is to load a ViT image processor to process the image into a tensor:
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> checkpoint = "google/vit-base-patch16-224-in21k"
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint)
+```
+
+
+
+Apply some image transformations to the images to make the model more robust against overfitting. Here you'll use torchvision's [`transforms`](https://pytorch.org/vision/stable/transforms.html) module, but you can also use any image library you like.
+
+Crop a random part of the image, resize it, and normalize it with the image mean and standard deviation:
+
+```py
+>>> from torchvision.transforms import RandomResizedCrop, Compose, Normalize, ToTensor
+
+>>> normalize = Normalize(mean=image_processor.image_mean, std=image_processor.image_std)
+>>> size = (
+... image_processor.size["shortest_edge"]
+... if "shortest_edge" in image_processor.size
+... else (image_processor.size["height"], image_processor.size["width"])
+... )
+>>> _transforms = Compose([RandomResizedCrop(size), ToTensor(), normalize])
+```
+
+Then create a preprocessing function to apply the transforms and return the `pixel_values` - the inputs to the model - of the image:
+
+```py
+>>> def transforms(examples):
+... examples["pixel_values"] = [_transforms(img.convert("RGB")) for img in examples["image"]]
+... del examples["image"]
+... return examples
+```
+
+To apply the preprocessing function over the entire dataset, use 🤗 Datasets [`~datasets.Dataset.with_transform`] method. The transforms are applied on the fly when you load an element of the dataset:
+
+```py
+>>> food = food.with_transform(transforms)
+```
+
+Now create a batch of examples using [`DefaultDataCollator`]. Unlike other data collators in 🤗 Transformers, the `DefaultDataCollator` does not apply additional preprocessing such as padding.
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator()
+```
+
+
+
+
+
+
+
+To avoid overfitting and to make the model more robust, add some data augmentation to the training part of the dataset.
+Here we use Keras preprocessing layers to define the transformations for the training data (includes data augmentation),
+and transformations for the validation data (only center cropping, resizing and normalizing). You can use `tf.image`or
+any other library you prefer.
+
+```py
+>>> from tensorflow import keras
+>>> from tensorflow.keras import layers
+
+>>> size = (image_processor.size["height"], image_processor.size["width"])
+
+>>> train_data_augmentation = keras.Sequential(
+... [
+... layers.RandomCrop(size[0], size[1]),
+... layers.Rescaling(scale=1.0 / 127.5, offset=-1),
+... layers.RandomFlip("horizontal"),
+... layers.RandomRotation(factor=0.02),
+... layers.RandomZoom(height_factor=0.2, width_factor=0.2),
+... ],
+... name="train_data_augmentation",
+... )
+
+>>> val_data_augmentation = keras.Sequential(
+... [
+... layers.CenterCrop(size[0], size[1]),
+... layers.Rescaling(scale=1.0 / 127.5, offset=-1),
+... ],
+... name="val_data_augmentation",
+... )
+```
+
+Next, create functions to apply appropriate transformations to a batch of images, instead of one image at a time.
+
+```py
+>>> import numpy as np
+>>> import tensorflow as tf
+>>> from PIL import Image
+
+
+>>> def convert_to_tf_tensor(image: Image):
+... np_image = np.array(image)
+... tf_image = tf.convert_to_tensor(np_image)
+... # `expand_dims()` is used to add a batch dimension since
+... # the TF augmentation layers operates on batched inputs.
+... return tf.expand_dims(tf_image, 0)
+
+
+>>> def preprocess_train(example_batch):
+... """Apply train_transforms across a batch."""
+... images = [
+... train_data_augmentation(convert_to_tf_tensor(image.convert("RGB"))) for image in example_batch["image"]
+... ]
+... example_batch["pixel_values"] = [tf.transpose(tf.squeeze(image)) for image in images]
+... return example_batch
+
+
+... def preprocess_val(example_batch):
+... """Apply val_transforms across a batch."""
+... images = [
+... val_data_augmentation(convert_to_tf_tensor(image.convert("RGB"))) for image in example_batch["image"]
+... ]
+... example_batch["pixel_values"] = [tf.transpose(tf.squeeze(image)) for image in images]
+... return example_batch
+```
+
+Use 🤗 Datasets [`~datasets.Dataset.set_transform`] to apply the transformations on the fly:
+
+```py
+food["train"].set_transform(preprocess_train)
+food["test"].set_transform(preprocess_val)
+```
+
+As a final preprocessing step, create a batch of examples using `DefaultDataCollator`. Unlike other data collators in 🤗 Transformers, the
+`DefaultDataCollator` does not apply additional preprocessing, such as padding.
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+```
+
+
+
+## Evaluate
+
+Including a metric during training is often helpful for evaluating your model's performance. You can quickly load an
+evaluation method with the 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) library. For this task, load
+the [accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) metric (see the 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour) to learn more about how to load and compute a metric):
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+Then create a function that passes your predictions and labels to [`~evaluate.EvaluationModule.compute`] to calculate the accuracy:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... predictions = np.argmax(predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=labels)
+```
+
+Your `compute_metrics` function is ready to go now, and you'll return to it when you set up your training.
+
+## Train
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#train-with-pytorch-trainer)!
+
+
+
+You're ready to start training your model now! Load ViT with [`AutoModelForImageClassification`]. Specify the number of labels along with the number of expected labels, and the label mappings:
+
+```py
+>>> from transformers import AutoModelForImageClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForImageClassification.from_pretrained(
+... checkpoint,
+... num_labels=len(labels),
+... id2label=id2label,
+... label2id=label2id,
+... )
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`TrainingArguments`]. It is important you don't remove unused columns because that'll drop the `image` column. Without the `image` column, you can't create `pixel_values`. Set `remove_unused_columns=False` to prevent this behavior! The only other required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model). At the end of each epoch, the [`Trainer`] will evaluate the accuracy and save the training checkpoint.
+2. Pass the training arguments to [`Trainer`] along with the model, dataset, tokenizer, data collator, and `compute_metrics` function.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_food_model",
+... remove_unused_columns=False,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... learning_rate=5e-5,
+... per_device_train_batch_size=16,
+... gradient_accumulation_steps=4,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... warmup_ratio=0.1,
+... logging_steps=10,
+... load_best_model_at_end=True,
+... metric_for_best_model="accuracy",
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... data_collator=data_collator,
+... train_dataset=food["train"],
+... eval_dataset=food["test"],
+... processing_class=image_processor,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+
+
+
+If you are unfamiliar with fine-tuning a model with Keras, check out the [basic tutorial](./training#train-a-tensorflow-model-with-keras) first!
+
+
+
+To fine-tune a model in TensorFlow, follow these steps:
+1. Define the training hyperparameters, and set up an optimizer and a learning rate schedule.
+2. Instantiate a pre-trained model.
+3. Convert a 🤗 Dataset to a `tf.data.Dataset`.
+4. Compile your model.
+5. Add callbacks and use the `fit()` method to run the training.
+6. Upload your model to 🤗 Hub to share with the community.
+
+Start by defining the hyperparameters, optimizer and learning rate schedule:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_epochs = 5
+>>> num_train_steps = len(food["train"]) * num_epochs
+>>> learning_rate = 3e-5
+>>> weight_decay_rate = 0.01
+
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=learning_rate,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=weight_decay_rate,
+... num_warmup_steps=0,
+... )
+```
+
+Then, load ViT with [`TFAutoModelForImageClassification`] along with the label mappings:
+
+```py
+>>> from transformers import TFAutoModelForImageClassification
+
+>>> model = TFAutoModelForImageClassification.from_pretrained(
+... checkpoint,
+... id2label=id2label,
+... label2id=label2id,
+... )
+```
+
+Convert your datasets to the `tf.data.Dataset` format using the [`~datasets.Dataset.to_tf_dataset`] and your `data_collator`:
+
+```py
+>>> # converting our train dataset to tf.data.Dataset
+>>> tf_train_dataset = food["train"].to_tf_dataset(
+... columns="pixel_values", label_cols="label", shuffle=True, batch_size=batch_size, collate_fn=data_collator
+... )
+
+>>> # converting our test dataset to tf.data.Dataset
+>>> tf_eval_dataset = food["test"].to_tf_dataset(
+... columns="pixel_values", label_cols="label", shuffle=True, batch_size=batch_size, collate_fn=data_collator
+... )
+```
+
+Configure the model for training with `compile()`:
+
+```py
+>>> from tensorflow.keras.losses import SparseCategoricalCrossentropy
+
+>>> loss = tf.keras.losses.SparseCategoricalCrossentropy(from_logits=True)
+>>> model.compile(optimizer=optimizer, loss=loss)
+```
+
+To compute the accuracy from the predictions and push your model to the 🤗 Hub, use [Keras callbacks](../main_classes/keras_callbacks).
+Pass your `compute_metrics` function to [KerasMetricCallback](../main_classes/keras_callbacks#transformers.KerasMetricCallback),
+and use the [PushToHubCallback](../main_classes/keras_callbacks#transformers.PushToHubCallback) to upload the model:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback, PushToHubCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_eval_dataset)
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="food_classifier",
+... tokenizer=image_processor,
+... save_strategy="no",
+... )
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+Finally, you are ready to train your model! Call `fit()` with your training and validation datasets, the number of epochs,
+and your callbacks to fine-tune the model:
+
+```py
+>>> model.fit(tf_train_dataset, validation_data=tf_eval_dataset, epochs=num_epochs, callbacks=callbacks)
+Epoch 1/5
+250/250 [==============================] - 313s 1s/step - loss: 2.5623 - val_loss: 1.4161 - accuracy: 0.9290
+Epoch 2/5
+250/250 [==============================] - 265s 1s/step - loss: 0.9181 - val_loss: 0.6808 - accuracy: 0.9690
+Epoch 3/5
+250/250 [==============================] - 252s 1s/step - loss: 0.3910 - val_loss: 0.4303 - accuracy: 0.9820
+Epoch 4/5
+250/250 [==============================] - 251s 1s/step - loss: 0.2028 - val_loss: 0.3191 - accuracy: 0.9900
+Epoch 5/5
+250/250 [==============================] - 238s 949ms/step - loss: 0.1232 - val_loss: 0.3259 - accuracy: 0.9890
+```
+
+Congratulations! You have fine-tuned your model and shared it on the 🤗 Hub. You can now use it for inference!
+
+
+
+
+
+
+For a more in-depth example of how to finetune a model for image classification, take a look at the corresponding [PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/image_classification.ipynb).
+
+
+
+## Inference
+
+Great, now that you've fine-tuned a model, you can use it for inference!
+
+Load an image you'd like to run inference on:
+
+```py
+>>> ds = load_dataset("food101", split="validation[:10]")
+>>> image = ds["image"][0]
+```
+
+
+
+
+
+The simplest way to try out your finetuned model for inference is to use it in a [`pipeline`]. Instantiate a `pipeline` for image classification with your model, and pass your image to it:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("image-classification", model="my_awesome_food_model")
+>>> classifier(image)
+[{'score': 0.31856709718704224, 'label': 'beignets'},
+ {'score': 0.015232225880026817, 'label': 'bruschetta'},
+ {'score': 0.01519392803311348, 'label': 'chicken_wings'},
+ {'score': 0.013022331520915031, 'label': 'pork_chop'},
+ {'score': 0.012728818692266941, 'label': 'prime_rib'}]
+```
+
+You can also manually replicate the results of the `pipeline` if you'd like:
+
+
+
+Load an image processor to preprocess the image and return the `input` as PyTorch tensors:
+
+```py
+>>> from transformers import AutoImageProcessor
+>>> import torch
+
+>>> image_processor = AutoImageProcessor.from_pretrained("my_awesome_food_model")
+>>> inputs = image_processor(image, return_tensors="pt")
+```
+
+Pass your inputs to the model and return the logits:
+
+```py
+>>> from transformers import AutoModelForImageClassification
+
+>>> model = AutoModelForImageClassification.from_pretrained("my_awesome_food_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+Get the predicted label with the highest probability, and use the model's `id2label` mapping to convert it to a label:
+
+```py
+>>> predicted_label = logits.argmax(-1).item()
+>>> model.config.id2label[predicted_label]
+'beignets'
+```
+
+
+
+
+
+Load an image processor to preprocess the image and return the `input` as TensorFlow tensors:
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> image_processor = AutoImageProcessor.from_pretrained("MariaK/food_classifier")
+>>> inputs = image_processor(image, return_tensors="tf")
+```
+
+Pass your inputs to the model and return the logits:
+
+```py
+>>> from transformers import TFAutoModelForImageClassification
+
+>>> model = TFAutoModelForImageClassification.from_pretrained("MariaK/food_classifier")
+>>> logits = model(**inputs).logits
+```
+
+Get the predicted label with the highest probability, and use the model's `id2label` mapping to convert it to a label:
+
+```py
+>>> predicted_class_id = int(tf.math.argmax(logits, axis=-1)[0])
+>>> model.config.id2label[predicted_class_id]
+'beignets'
+```
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/image_feature_extraction.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/image_feature_extraction.md
new file mode 100644
index 0000000000000000000000000000000000000000..455a2b425d412b199374f79c3b04be50bee968e3
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/image_feature_extraction.md
@@ -0,0 +1,134 @@
+
+
+# Image Feature Extraction
+
+[[open-in-colab]]
+
+Image feature extraction is the task of extracting semantically meaningful features given an image. This has many use cases, including image similarity and image retrieval. Moreover, most computer vision models can be used for image feature extraction, where one can remove the task-specific head (image classification, object detection etc) and get the features. These features are very useful on a higher level: edge detection, corner detection and so on. They may also contain information about the real world (e.g. what a cat looks like) depending on how deep the model is. Therefore, these outputs can be used to train new classifiers on a specific dataset.
+
+In this guide, you will:
+
+- Learn to build a simple image similarity system on top of the `image-feature-extraction` pipeline.
+- Accomplish the same task with bare model inference.
+
+## Image Similarity using `image-feature-extraction` Pipeline
+
+We have two images of cats sitting on top of fish nets, one of them is generated.
+
+```python
+from PIL import Image
+import requests
+
+img_urls = ["https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/cats.png", "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/cats.jpeg"]
+image_real = Image.open(requests.get(img_urls[0], stream=True).raw).convert("RGB")
+image_gen = Image.open(requests.get(img_urls[1], stream=True).raw).convert("RGB")
+```
+
+Let's see the pipeline in action. First, initialize the pipeline. If you don't pass any model to it, the pipeline will be automatically initialized with [google/vit-base-patch16-224](google/vit-base-patch16-224). If you'd like to calculate similarity, set `pool` to True.
+
+```python
+import torch
+from transformers import pipeline, infer_device
+# automatically detects the underlying device type (CUDA, CPU, XPU, MPS, etc.)
+DEVICE = infer_device()
+pipe = pipeline(task="image-feature-extraction", model_name="google/vit-base-patch16-384", device=DEVICE, pool=True)
+```
+
+To infer with `pipe` pass both images to it.
+
+```python
+outputs = pipe([image_real, image_gen])
+```
+
+The output contains pooled embeddings of those two images.
+
+```python
+# get the length of a single output
+print(len(outputs[0][0]))
+# show outputs
+print(outputs)
+
+# 768
+# [[[-0.03909236937761307, 0.43381670117378235, -0.06913255900144577,
+```
+
+To get the similarity score, we need to pass them to a similarity function.
+
+```python
+from torch.nn.functional import cosine_similarity
+
+similarity_score = cosine_similarity(torch.Tensor(outputs[0]),
+ torch.Tensor(outputs[1]), dim=1)
+
+print(similarity_score)
+
+# tensor([0.6043])
+```
+
+If you want to get the last hidden states before pooling, avoid passing any value for the `pool` parameter, as it is set to `False` by default. These hidden states are useful for training new classifiers or models based on the features from the model.
+
+```python
+pipe = pipeline(task="image-feature-extraction", model_name="google/vit-base-patch16-224", device=DEVICE)
+outputs = pipe(image_real)
+```
+
+Since the outputs are unpooled, we get the last hidden states where the first dimension is the batch size, and the last two are the embedding shape.
+
+```python
+import numpy as np
+print(np.array(outputs).shape)
+# (1, 197, 768)
+```
+
+## Getting Features and Similarities using `AutoModel`
+
+We can also use `AutoModel` class of transformers to get the features. `AutoModel` loads any transformers model with no task-specific head, and we can use this to get the features.
+
+```python
+from transformers import AutoImageProcessor, AutoModel
+
+processor = AutoImageProcessor.from_pretrained("google/vit-base-patch16-224")
+model = AutoModel.from_pretrained("google/vit-base-patch16-224").to(DEVICE)
+```
+
+Let's write a simple function for inference. We will pass the inputs to the `processor` first and pass its outputs to the `model`.
+
+```python
+def infer(image):
+ inputs = processor(image, return_tensors="pt").to(DEVICE)
+ outputs = model(**inputs)
+ return outputs.pooler_output
+```
+
+We can pass the images directly to this function and get the embeddings.
+
+```python
+embed_real = infer(image_real)
+embed_gen = infer(image_gen)
+```
+
+We can get the similarity again over the embeddings.
+
+```python
+from torch.nn.functional import cosine_similarity
+
+similarity_score = cosine_similarity(embed_real, embed_gen, dim=1)
+print(similarity_score)
+
+# tensor([0.6061], device='cuda:0', grad_fn=)
+```
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/image_text_to_text.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/image_text_to_text.md
new file mode 100644
index 0000000000000000000000000000000000000000..a98b1e5509cc3f0f925c666429fcc5f10cf2b158
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/image_text_to_text.md
@@ -0,0 +1,315 @@
+
+
+# Image-text-to-text
+
+[[open-in-colab]]
+
+Image-text-to-text models, also known as vision language models (VLMs), are language models that take an image input. These models can tackle various tasks, from visual question answering to image segmentation. This task shares many similarities with image-to-text, but with some overlapping use cases like image captioning. Image-to-text models only take image inputs and often accomplish a specific task, whereas VLMs take open-ended text and image inputs and are more generalist models.
+
+In this guide, we provide a brief overview of VLMs and show how to use them with Transformers for inference.
+
+To begin with, there are multiple types of VLMs:
+- base models used for fine-tuning
+- chat fine-tuned models for conversation
+- instruction fine-tuned models
+
+This guide focuses on inference with an instruction-tuned model.
+
+Let's begin installing the dependencies.
+
+```bash
+pip install -q transformers accelerate flash_attn
+```
+
+Let's initialize the model and the processor.
+
+```python
+from transformers import AutoProcessor, AutoModelForImageTextToText
+import torch
+
+device = torch.device("cuda")
+model = AutoModelForImageTextToText.from_pretrained(
+ "HuggingFaceM4/idefics2-8b",
+ torch_dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+).to(device)
+
+processor = AutoProcessor.from_pretrained("HuggingFaceM4/idefics2-8b")
+```
+
+This model has a [chat template](./chat_templating) that helps user parse chat outputs. Moreover, the model can also accept multiple images as input in a single conversation or message. We will now prepare the inputs.
+
+The image inputs look like the following.
+
+
+
+
+
+
+
+
+
+
+```python
+from PIL import Image
+import requests
+
+img_urls =["https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/cats.png",
+ "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg"]
+images = [Image.open(requests.get(img_urls[0], stream=True).raw),
+ Image.open(requests.get(img_urls[1], stream=True).raw)]
+```
+
+Below is an example of the chat template. We can feed conversation turns and the last message as an input by appending it at the end of the template.
+
+
+```python
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "What do we see in this image?"},
+ ]
+ },
+ {
+ "role": "assistant",
+ "content": [
+ {"type": "text", "text": "In this image we can see two cats on the nets."},
+ ]
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "And how about this image?"},
+ ]
+ },
+]
+```
+
+We will now call the processors' [`~ProcessorMixin.apply_chat_template`] method to preprocess its output along with the image inputs.
+
+```python
+prompt = processor.apply_chat_template(messages, add_generation_prompt=True)
+inputs = processor(text=prompt, images=[images[0], images[1]], return_tensors="pt").to(device)
+```
+
+We can now pass the preprocessed inputs to the model.
+
+```python
+with torch.no_grad():
+ generated_ids = model.generate(**inputs, max_new_tokens=500)
+generated_texts = processor.batch_decode(generated_ids, skip_special_tokens=True)
+
+print(generated_texts)
+## ['User: What do we see in this image? \nAssistant: In this image we can see two cats on the nets. \nUser: And how about this image? \nAssistant: In this image we can see flowers, plants and insect.']
+```
+
+## Pipeline
+
+The fastest way to get started is to use the [`Pipeline`] API. Specify the `"image-text-to-text"` task and the model you want to use.
+
+```python
+from transformers import pipeline
+pipe = pipeline("image-text-to-text", model="llava-hf/llava-interleave-qwen-0.5b-hf")
+```
+
+The example below uses chat templates to format the text inputs.
+
+```python
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {
+ "type": "image",
+ "image": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg",
+ },
+ {"type": "text", "text": "Describe this image."},
+ ],
+ },
+ {
+ "role": "assistant",
+ "content": [
+ {"type": "text", "text": "There's a pink flower"},
+ ],
+ },
+ ]
+```
+
+Pass the chat template formatted text and image to [`Pipeline`] and set `return_full_text=False` to remove the input from the generated output.
+
+```python
+outputs = pipe(text=messages, max_new_tokens=20, return_full_text=False)
+outputs[0]["generated_text"]
+# with a yellow center in the foreground. The flower is surrounded by red and white flowers with green stems
+```
+
+If you prefer, you can also load the images separately and pass them to the pipeline like so:
+
+```python
+pipe = pipeline("image-text-to-text", model="HuggingFaceTB/SmolVLM-256M-Instruct")
+
+img_urls = [
+ "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/cats.png",
+ "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg",
+]
+images = [
+ Image.open(requests.get(img_urls[0], stream=True).raw),
+ Image.open(requests.get(img_urls[1], stream=True).raw),
+]
+
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "image"},
+ {"type": "text", "text": "What do you see in these images?"},
+ ],
+ }
+]
+outputs = pipe(text=messages, images=images, max_new_tokens=50, return_full_text=False)
+outputs[0]["generated_text"]
+" In the first image, there are two cats sitting on a plant. In the second image, there are flowers with a pinkish hue."
+```
+
+The images will still be included in the `"input_text"` field of the output:
+
+```python
+outputs[0]['input_text']
+"""
+[{'role': 'user',
+ 'content': [{'type': 'image',
+ 'image': },
+ {'type': 'image',
+ 'image': },
+ {'type': 'text', 'text': 'What do you see in these images?'}]}]## Streaming
+"""
+```
+
+We can use [text streaming](./generation_strategies#streaming) for a better generation experience. Transformers supports streaming with the [`TextStreamer`] or [`TextIteratorStreamer`] classes. We will use the [`TextIteratorStreamer`] with IDEFICS-8B.
+
+Assume we have an application that keeps chat history and takes in the new user input. We will preprocess the inputs as usual and initialize [`TextIteratorStreamer`] to handle the generation in a separate thread. This allows you to stream the generated text tokens in real-time. Any generation arguments can be passed to [`TextIteratorStreamer`].
+
+
+```python
+import time
+from transformers import TextIteratorStreamer
+from threading import Thread
+
+def model_inference(
+ user_prompt,
+ chat_history,
+ max_new_tokens,
+ images
+):
+ user_prompt = {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": user_prompt},
+ ]
+ }
+ chat_history.append(user_prompt)
+ streamer = TextIteratorStreamer(
+ processor.tokenizer,
+ skip_prompt=True,
+ timeout=5.0,
+ )
+
+ generation_args = {
+ "max_new_tokens": max_new_tokens,
+ "streamer": streamer,
+ "do_sample": False
+ }
+
+ # add_generation_prompt=True makes model generate bot response
+ prompt = processor.apply_chat_template(chat_history, add_generation_prompt=True)
+ inputs = processor(
+ text=prompt,
+ images=images,
+ return_tensors="pt",
+ ).to(device)
+ generation_args.update(inputs)
+
+ thread = Thread(
+ target=model.generate,
+ kwargs=generation_args,
+ )
+ thread.start()
+
+ acc_text = ""
+ for text_token in streamer:
+ time.sleep(0.04)
+ acc_text += text_token
+ if acc_text.endswith(""):
+ acc_text = acc_text[:-18]
+ yield acc_text
+
+ thread.join()
+```
+
+Now let's call the `model_inference` function we created and stream the values.
+
+```python
+generator = model_inference(
+ user_prompt="And what is in this image?",
+ chat_history=messages[:2],
+ max_new_tokens=100,
+ images=images
+)
+
+for value in generator:
+ print(value)
+
+# In
+# In this
+# In this image ...
+```
+
+## Fit models in smaller hardware
+
+VLMs are often large and need to be optimized to fit on smaller hardware. Transformers supports many model quantization libraries, and here we will only show int8 quantization with [Quanto](./quantization/quanto#quanto). int8 quantization offers memory improvements up to 75 percent (if all weights are quantized). However it is no free lunch, since 8-bit is not a CUDA-native precision, the weights are quantized back and forth on the fly, which adds up to latency.
+
+First, install dependencies.
+
+```bash
+pip install -U quanto bitsandbytes
+```
+
+To quantize a model during loading, we need to first create [`QuantoConfig`]. Then load the model as usual, but pass `quantization_config` during model initialization.
+
+```python
+from transformers import AutoModelForImageTextToText, QuantoConfig
+
+model_id = "HuggingFaceM4/idefics2-8b"
+quantization_config = QuantoConfig(weights="int8")
+quantized_model = AutoModelForImageTextToText.from_pretrained(
+ model_id, device_map="cuda", quantization_config=quantization_config
+)
+```
+
+And that's it, we can use the model the same way with no changes.
+
+## Further Reading
+
+Here are some more resources for the image-text-to-text task.
+
+- [Image-text-to-text task page](https://huggingface.co/tasks/image-text-to-text) covers model types, use cases, datasets, and more.
+- [Vision Language Models Explained](https://huggingface.co/blog/vlms) is a blog post that covers everything about vision language models and supervised fine-tuning using [TRL](https://huggingface.co/docs/trl/en/index).
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/image_to_image.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/image_to_image.md
new file mode 100644
index 0000000000000000000000000000000000000000..da6a57ac9aa99e8122a0779dcd76fd2ed40e916e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/image_to_image.md
@@ -0,0 +1,133 @@
+
+
+# Image-to-Image Task Guide
+
+[[open-in-colab]]
+
+Image-to-Image task is the task where an application receives an image and outputs another image. This has various subtasks, including image enhancement (super resolution, low light enhancement, deraining and so on), image inpainting, and more.
+
+This guide will show you how to:
+- Use an image-to-image pipeline for super resolution task,
+- Run image-to-image models for same task without a pipeline.
+
+Note that as of the time this guide is released, `image-to-image` pipeline only supports super resolution task.
+
+Let's begin by installing the necessary libraries.
+
+```bash
+pip install transformers
+```
+
+We can now initialize the pipeline with a [Swin2SR model](https://huggingface.co/caidas/swin2SR-lightweight-x2-64). We can then infer with the pipeline by calling it with an image. As of now, only [Swin2SR models](https://huggingface.co/models?sort=trending&search=swin2sr) are supported in this pipeline.
+
+```python
+from transformers import pipeline, infer_device
+import torch
+# automatically detects the underlying device type (CUDA, CPU, XPU, MPS, etc.)
+device = infer_device()
+pipe = pipeline(task="image-to-image", model="caidas/swin2SR-lightweight-x2-64", device=device)
+```
+
+Now, let's load an image.
+
+```python
+from PIL import Image
+import requests
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/cat.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+
+print(image.size)
+```
+```bash
+# (532, 432)
+```
+
+
+
+
+We can now do inference with the pipeline. We will get an upscaled version of the cat image.
+
+```python
+upscaled = pipe(image)
+print(upscaled.size)
+```
+```bash
+# (1072, 880)
+```
+
+If you wish to do inference yourself with no pipeline, you can use the `Swin2SRForImageSuperResolution` and `Swin2SRImageProcessor` classes of transformers. We will use the same model checkpoint for this. Let's initialize the model and the processor.
+
+```python
+from transformers import Swin2SRForImageSuperResolution, Swin2SRImageProcessor
+
+model = Swin2SRForImageSuperResolution.from_pretrained("caidas/swin2SR-lightweight-x2-64").to(device)
+processor = Swin2SRImageProcessor("caidas/swin2SR-lightweight-x2-64")
+```
+
+`pipeline` abstracts away the preprocessing and postprocessing steps that we have to do ourselves, so let's preprocess the image. We will pass the image to the processor and then move the pixel values to GPU.
+
+```python
+pixel_values = processor(image, return_tensors="pt").pixel_values
+print(pixel_values.shape)
+
+pixel_values = pixel_values.to(device)
+```
+
+We can now infer the image by passing pixel values to the model.
+
+```python
+import torch
+
+with torch.no_grad():
+ outputs = model(pixel_values)
+```
+Output is an object of type `ImageSuperResolutionOutput` that looks like below 👇
+
+```
+(loss=None, reconstruction=tensor([[[[0.8270, 0.8269, 0.8275, ..., 0.7463, 0.7446, 0.7453],
+ [0.8287, 0.8278, 0.8283, ..., 0.7451, 0.7448, 0.7457],
+ [0.8280, 0.8273, 0.8269, ..., 0.7447, 0.7446, 0.7452],
+ ...,
+ [0.5923, 0.5933, 0.5924, ..., 0.0697, 0.0695, 0.0706],
+ [0.5926, 0.5932, 0.5926, ..., 0.0673, 0.0687, 0.0705],
+ [0.5927, 0.5914, 0.5922, ..., 0.0664, 0.0694, 0.0718]]]],
+ device='cuda:0'), hidden_states=None, attentions=None)
+```
+We need to get the `reconstruction` and post-process it for visualization. Let's see how it looks like.
+
+```python
+outputs.reconstruction.data.shape
+# torch.Size([1, 3, 880, 1072])
+```
+
+We need to squeeze the output and get rid of axis 0, clip the values, then convert it to be numpy float. Then we will arrange axes to have the shape [1072, 880], and finally, bring the output back to range [0, 255].
+
+```python
+import numpy as np
+
+# squeeze, take to CPU and clip the values
+output = outputs.reconstruction.data.squeeze().cpu().clamp_(0, 1).numpy()
+# rearrange the axes
+output = np.moveaxis(output, source=0, destination=-1)
+# bring values back to pixel values range
+output = (output * 255.0).round().astype(np.uint8)
+Image.fromarray(output)
+```
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/keypoint_detection.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/keypoint_detection.md
new file mode 100644
index 0000000000000000000000000000000000000000..3a5871d01a2b8f47230768d0e9ead22b5eb38ecf
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/keypoint_detection.md
@@ -0,0 +1,154 @@
+
+
+# Keypoint Detection
+
+[[open-in-colab]]
+
+Keypoint detection identifies and locates specific points of interest within an image. These keypoints, also known as landmarks, represent meaningful features of objects, such as facial features or object parts. These models take an image input and return the following outputs:
+
+- **Keypoints and Scores**: Points of interest and their confidence scores.
+- **Descriptors**: A representation of the image region surrounding each keypoint, capturing its texture, gradient, orientation and other properties.
+
+In this guide, we will show how to extract keypoints from images.
+
+For this tutorial, we will use [SuperPoint](./model_doc/superpoint), a foundation model for keypoint detection.
+
+```python
+from transformers import AutoImageProcessor, SuperPointForKeypointDetection
+processor = AutoImageProcessor.from_pretrained("magic-leap-community/superpoint")
+model = SuperPointForKeypointDetection.from_pretrained("magic-leap-community/superpoint")
+```
+
+Let's test the model on the images below.
+
+
+
+
+
+
+
+```python
+import torch
+from PIL import Image
+import requests
+import cv2
+
+
+url_image_1 = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg"
+image_1 = Image.open(requests.get(url_image_1, stream=True).raw)
+url_image_2 = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/cats.png"
+image_2 = Image.open(requests.get(url_image_2, stream=True).raw)
+
+images = [image_1, image_2]
+```
+
+We can now process our inputs and infer.
+
+```python
+inputs = processor(images,return_tensors="pt").to(model.device, model.dtype)
+outputs = model(**inputs)
+```
+
+The model output has relative keypoints, descriptors, masks and scores for each item in the batch. The mask highlights areas of the image where keypoints are present.
+
+```python
+SuperPointKeypointDescriptionOutput(loss=None, keypoints=tensor([[[0.0437, 0.0167],
+ [0.0688, 0.0167],
+ [0.0172, 0.0188],
+ ...,
+ [0.5984, 0.9812],
+ [0.6953, 0.9812]]]),
+ scores=tensor([[0.0056, 0.0053, 0.0079, ..., 0.0125, 0.0539, 0.0377],
+ [0.0206, 0.0058, 0.0065, ..., 0.0000, 0.0000, 0.0000]],
+ grad_fn=), descriptors=tensor([[[-0.0807, 0.0114, -0.1210, ..., -0.1122, 0.0899, 0.0357],
+ [-0.0807, 0.0114, -0.1210, ..., -0.1122, 0.0899, 0.0357],
+ [-0.0807, 0.0114, -0.1210, ..., -0.1122, 0.0899, 0.0357],
+ ...],
+ grad_fn=), mask=tensor([[1, 1, 1, ..., 1, 1, 1],
+ [1, 1, 1, ..., 0, 0, 0]], dtype=torch.int32), hidden_states=None)
+```
+
+To plot actual keypoints in the image, we need to postprocess the output. To do so, we have to pass the actual image sizes to `post_process_keypoint_detection` along with outputs.
+
+```python
+image_sizes = [(image.size[1], image.size[0]) for image in images]
+outputs = processor.post_process_keypoint_detection(outputs, image_sizes)
+```
+
+The outputs are now a list of dictionaries where each dictionary is a processed output of keypoints, scores and descriptors.
+
+```python
+[{'keypoints': tensor([[ 226, 57],
+ [ 356, 57],
+ [ 89, 64],
+ ...,
+ [3604, 3391]], dtype=torch.int32),
+ 'scores': tensor([0.0056, 0.0053, ...], grad_fn=),
+ 'descriptors': tensor([[-0.0807, 0.0114, -0.1210, ..., -0.1122, 0.0899, 0.0357],
+ [-0.0807, 0.0114, -0.1210, ..., -0.1122, 0.0899, 0.0357]],
+ grad_fn=)},
+ {'keypoints': tensor([[ 46, 6],
+ [ 78, 6],
+ [422, 6],
+ [206, 404]], dtype=torch.int32),
+ 'scores': tensor([0.0206, 0.0058, 0.0065, 0.0053, 0.0070, ...,grad_fn=),
+ 'descriptors': tensor([[-0.0525, 0.0726, 0.0270, ..., 0.0389, -0.0189, -0.0211],
+ [-0.0525, 0.0726, 0.0270, ..., 0.0389, -0.0189, -0.0211]}]
+```
+
+We can use these to plot the keypoints.
+
+```python
+import matplotlib.pyplot as plt
+import torch
+
+for i in range(len(images)):
+ keypoints = outputs[i]["keypoints"]
+ scores = outputs[i]["scores"]
+ descriptors = outputs[i]["descriptors"]
+ keypoints = outputs[i]["keypoints"].detach().numpy()
+ scores = outputs[i]["scores"].detach().numpy()
+ image = images[i]
+ image_width, image_height = image.size
+
+ plt.axis('off')
+ plt.imshow(image)
+ plt.scatter(
+ keypoints[:, 0],
+ keypoints[:, 1],
+ s=scores * 100,
+ c='cyan',
+ alpha=0.4
+ )
+ plt.show()
+```
+
+Below you can see the outputs.
+
+
+
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/knowledge_distillation_for_image_classification.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/knowledge_distillation_for_image_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..7c4a684d3c057f7c23616d94dcfcffe42739609c
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/knowledge_distillation_for_image_classification.md
@@ -0,0 +1,185 @@
+
+# Knowledge Distillation for Computer Vision
+
+[[open-in-colab]]
+
+Knowledge distillation is a technique used to transfer knowledge from a larger, more complex model (teacher) to a smaller, simpler model (student). To distill knowledge from one model to another, we take a pre-trained teacher model trained on a certain task (image classification for this case) and randomly initialize a student model to be trained on image classification. Next, we train the student model to minimize the difference between its outputs and the teacher's outputs, thus making it mimic the behavior. It was first introduced in [Distilling the Knowledge in a Neural Network by Hinton et al](https://huggingface.co/papers/1503.02531). In this guide, we will do task-specific knowledge distillation. We will use the [beans dataset](https://huggingface.co/datasets/beans) for this.
+
+This guide demonstrates how you can distill a [fine-tuned ViT model](https://huggingface.co/merve/vit-mobilenet-beans-224) (teacher model) to a [MobileNet](https://huggingface.co/google/mobilenet_v2_1.4_224) (student model) using the [Trainer API](https://huggingface.co/docs/transformers/en/main_classes/trainer#trainer) of 🤗 Transformers.
+
+Let's install the libraries needed for distillation and evaluating the process.
+
+```bash
+pip install transformers datasets accelerate tensorboard evaluate --upgrade
+```
+
+In this example, we are using the `merve/beans-vit-224` model as teacher model. It's an image classification model, based on `google/vit-base-patch16-224-in21k` fine-tuned on beans dataset. We will distill this model to a randomly initialized MobileNetV2.
+
+We will now load the dataset.
+
+```python
+from datasets import load_dataset
+
+dataset = load_dataset("beans")
+```
+
+We can use an image processor from either of the models, as in this case they return the same output with same resolution. We will use the `map()` method of `dataset` to apply the preprocessing to every split of the dataset.
+
+```python
+from transformers import AutoImageProcessor
+teacher_processor = AutoImageProcessor.from_pretrained("merve/beans-vit-224")
+
+def process(examples):
+ processed_inputs = teacher_processor(examples["image"])
+ return processed_inputs
+
+processed_datasets = dataset.map(process, batched=True)
+```
+
+Essentially, we want the student model (a randomly initialized MobileNet) to mimic the teacher model (fine-tuned vision transformer). To achieve this, we first get the logits output from the teacher and the student. Then, we divide each of them by the parameter `temperature` which controls the importance of each soft target. A parameter called `lambda` weighs the importance of the distillation loss. In this example, we will use `temperature=5` and `lambda=0.5`. We will use the Kullback-Leibler Divergence loss to compute the divergence between the student and teacher. Given two data P and Q, KL Divergence explains how much extra information we need to represent P using Q. If two are identical, their KL divergence is zero, as there's no other information needed to explain P from Q. Thus, in the context of knowledge distillation, KL divergence is useful.
+
+
+```python
+from transformers import TrainingArguments, Trainer, infer_device
+import torch
+import torch.nn as nn
+import torch.nn.functional as F
+
+class ImageDistilTrainer(Trainer):
+ def __init__(self, teacher_model=None, student_model=None, temperature=None, lambda_param=None, *args, **kwargs):
+ super().__init__(model=student_model, *args, **kwargs)
+ self.teacher = teacher_model
+ self.student = student_model
+ self.loss_function = nn.KLDivLoss(reduction="batchmean")
+ device = infer_device()
+ self.teacher.to(device)
+ self.teacher.eval()
+ self.temperature = temperature
+ self.lambda_param = lambda_param
+
+ def compute_loss(self, student, inputs, return_outputs=False):
+ student_output = self.student(**inputs)
+
+ with torch.no_grad():
+ teacher_output = self.teacher(**inputs)
+
+ # Compute soft targets for teacher and student
+ soft_teacher = F.softmax(teacher_output.logits / self.temperature, dim=-1)
+ soft_student = F.log_softmax(student_output.logits / self.temperature, dim=-1)
+
+ # Compute the loss
+ distillation_loss = self.loss_function(soft_student, soft_teacher) * (self.temperature ** 2)
+
+ # Compute the true label loss
+ student_target_loss = student_output.loss
+
+ # Calculate final loss
+ loss = (1. - self.lambda_param) * student_target_loss + self.lambda_param * distillation_loss
+ return (loss, student_output) if return_outputs else loss
+```
+
+We will now login to Hugging Face Hub so we can push our model to the Hugging Face Hub through the `Trainer`.
+
+```python
+from huggingface_hub import notebook_login
+
+notebook_login()
+```
+
+Let's set the `TrainingArguments`, the teacher model and the student model.
+
+```python
+from transformers import AutoModelForImageClassification, MobileNetV2Config, MobileNetV2ForImageClassification
+
+training_args = TrainingArguments(
+ output_dir="my-awesome-model",
+ num_train_epochs=30,
+ fp16=True,
+ logging_dir=f"{repo_name}/logs",
+ logging_strategy="epoch",
+ eval_strategy="epoch",
+ save_strategy="epoch",
+ load_best_model_at_end=True,
+ metric_for_best_model="accuracy",
+ report_to="tensorboard",
+ push_to_hub=True,
+ hub_strategy="every_save",
+ hub_model_id=repo_name,
+ )
+
+num_labels = len(processed_datasets["train"].features["labels"].names)
+
+# initialize models
+teacher_model = AutoModelForImageClassification.from_pretrained(
+ "merve/beans-vit-224",
+ num_labels=num_labels,
+ ignore_mismatched_sizes=True
+)
+
+# training MobileNetV2 from scratch
+student_config = MobileNetV2Config()
+student_config.num_labels = num_labels
+student_model = MobileNetV2ForImageClassification(student_config)
+```
+
+We can use `compute_metrics` function to evaluate our model on the test set. This function will be used during the training process to compute the `accuracy` & `f1` of our model.
+
+```python
+import evaluate
+import numpy as np
+
+accuracy = evaluate.load("accuracy")
+
+def compute_metrics(eval_pred):
+ predictions, labels = eval_pred
+ acc = accuracy.compute(references=labels, predictions=np.argmax(predictions, axis=1))
+ return {"accuracy": acc["accuracy"]}
+```
+
+Let's initialize the `Trainer` with the training arguments we defined. We will also initialize our data collator.
+
+```python
+from transformers import DefaultDataCollator
+
+data_collator = DefaultDataCollator()
+trainer = ImageDistilTrainer(
+ student_model=student_model,
+ teacher_model=teacher_model,
+ training_args=training_args,
+ train_dataset=processed_datasets["train"],
+ eval_dataset=processed_datasets["validation"],
+ data_collator=data_collator,
+ processing_class=teacher_processor,
+ compute_metrics=compute_metrics,
+ temperature=5,
+ lambda_param=0.5
+)
+```
+
+We can now train our model.
+
+```python
+trainer.train()
+```
+
+We can evaluate the model on the test set.
+
+```python
+trainer.evaluate(processed_datasets["test"])
+```
+
+On test set, our model reaches 72 percent accuracy. To have a sanity check over efficiency of distillation, we also trained MobileNet on the beans dataset from scratch with the same hyperparameters and observed 63 percent accuracy on the test set. We invite the readers to try different pre-trained teacher models, student architectures, distillation parameters and report their findings. The training logs and checkpoints for distilled model can be found in [this repository](https://huggingface.co/merve/vit-mobilenet-beans-224), and MobileNetV2 trained from scratch can be found in this [repository](https://huggingface.co/merve/resnet-mobilenet-beans-5).
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/language_modeling.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/language_modeling.md
new file mode 100644
index 0000000000000000000000000000000000000000..f6e71fe117677f87612f148470584b1014a228bd
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/language_modeling.md
@@ -0,0 +1,429 @@
+
+
+# Causal language modeling
+
+[[open-in-colab]]
+
+There are two types of language modeling, causal and masked. This guide illustrates causal language modeling.
+Causal language models are frequently used for text generation. You can use these models for creative applications like
+choosing your own text adventure or an intelligent coding assistant like Copilot or CodeParrot.
+
+
+
+Causal language modeling predicts the next token in a sequence of tokens, and the model can only attend to tokens on
+the left. This means the model cannot see future tokens. GPT-2 is an example of a causal language model.
+
+This guide will show you how to:
+
+1. Finetune [DistilGPT2](https://huggingface.co/distilbert/distilgpt2) on the [r/askscience](https://www.reddit.com/r/askscience/) subset of the [ELI5](https://huggingface.co/datasets/dany0407/eli5_category) dataset.
+2. Use your finetuned model for inference.
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/text-generation)
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+We encourage you to log in to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to log in:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load ELI5 dataset
+
+Start by loading the first 5000 examples from the [ELI5-Category](https://huggingface.co/datasets/dany0407/eli5_category) dataset with the 🤗 Datasets library. This'll give you a chance to experiment and make sure everything works before spending more time training on the full dataset.
+
+```py
+>>> from datasets import load_dataset
+
+>>> eli5 = load_dataset("dany0407/eli5_category", split="train[:5000]")
+```
+
+Split the dataset's `train` split into a train and test set with the [`~datasets.Dataset.train_test_split`] method:
+
+```py
+>>> eli5 = eli5.train_test_split(test_size=0.2)
+```
+
+Then take a look at an example:
+
+```py
+>>> eli5["train"][0]
+{'q_id': '7h191n',
+ 'title': 'What does the tax bill that was passed today mean? How will it affect Americans in each tax bracket?',
+ 'selftext': '',
+ 'category': 'Economics',
+ 'subreddit': 'explainlikeimfive',
+ 'answers': {'a_id': ['dqnds8l', 'dqnd1jl', 'dqng3i1', 'dqnku5x'],
+ 'text': ["The tax bill is 500 pages long and there were a lot of changes still going on right to the end. It's not just an adjustment to the income tax brackets, it's a whole bunch of changes. As such there is no good answer to your question. The big take aways are: - Big reduction in corporate income tax rate will make large companies very happy. - Pass through rate change will make certain styles of business (law firms, hedge funds) extremely happy - Income tax changes are moderate, and are set to expire (though it's the kind of thing that might just always get re-applied without being made permanent) - People in high tax states (California, New York) lose out, and many of them will end up with their taxes raised.",
+ 'None yet. It has to be reconciled with a vastly different house bill and then passed again.',
+ 'Also: does this apply to 2017 taxes? Or does it start with 2018 taxes?',
+ 'This article explains both the House and senate bills, including the proposed changes to your income taxes based on your income level. URL_0'],
+ 'score': [21, 19, 5, 3],
+ 'text_urls': [[],
+ [],
+ [],
+ ['https://www.investopedia.com/news/trumps-tax-reform-what-can-be-done/']]},
+ 'title_urls': ['url'],
+ 'selftext_urls': ['url']}
+```
+
+While this may look like a lot, you're only really interested in the `text` field. What's cool about language modeling
+tasks is you don't need labels (also known as an unsupervised task) because the next word *is* the label.
+
+## Preprocess
+
+
+
+The next step is to load a DistilGPT2 tokenizer to process the `text` subfield:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilgpt2")
+```
+
+You'll notice from the example above, the `text` field is actually nested inside `answers`. This means you'll need to
+extract the `text` subfield from its nested structure with the [`flatten`](https://huggingface.co/docs/datasets/process#flatten) method:
+
+```py
+>>> eli5 = eli5.flatten()
+>>> eli5["train"][0]
+{'q_id': '7h191n',
+ 'title': 'What does the tax bill that was passed today mean? How will it affect Americans in each tax bracket?',
+ 'selftext': '',
+ 'category': 'Economics',
+ 'subreddit': 'explainlikeimfive',
+ 'answers.a_id': ['dqnds8l', 'dqnd1jl', 'dqng3i1', 'dqnku5x'],
+ 'answers.text': ["The tax bill is 500 pages long and there were a lot of changes still going on right to the end. It's not just an adjustment to the income tax brackets, it's a whole bunch of changes. As such there is no good answer to your question. The big take aways are: - Big reduction in corporate income tax rate will make large companies very happy. - Pass through rate change will make certain styles of business (law firms, hedge funds) extremely happy - Income tax changes are moderate, and are set to expire (though it's the kind of thing that might just always get re-applied without being made permanent) - People in high tax states (California, New York) lose out, and many of them will end up with their taxes raised.",
+ 'None yet. It has to be reconciled with a vastly different house bill and then passed again.',
+ 'Also: does this apply to 2017 taxes? Or does it start with 2018 taxes?',
+ 'This article explains both the House and senate bills, including the proposed changes to your income taxes based on your income level. URL_0'],
+ 'answers.score': [21, 19, 5, 3],
+ 'answers.text_urls': [[],
+ [],
+ [],
+ ['https://www.investopedia.com/news/trumps-tax-reform-what-can-be-done/']],
+ 'title_urls': ['url'],
+ 'selftext_urls': ['url']}
+```
+
+Each subfield is now a separate column as indicated by the `answers` prefix, and the `text` field is a list now. Instead
+of tokenizing each sentence separately, convert the list to a string so you can jointly tokenize them.
+
+Here is a first preprocessing function to join the list of strings for each example and tokenize the result:
+
+```py
+>>> def preprocess_function(examples):
+... return tokenizer([" ".join(x) for x in examples["answers.text"]])
+```
+
+To apply this preprocessing function over the entire dataset, use the 🤗 Datasets [`~datasets.Dataset.map`] method. You can speed up the `map` function by setting `batched=True` to process multiple elements of the dataset at once, and increasing the number of processes with `num_proc`. Remove any columns you don't need:
+
+```py
+>>> tokenized_eli5 = eli5.map(
+... preprocess_function,
+... batched=True,
+... num_proc=4,
+... remove_columns=eli5["train"].column_names,
+... )
+```
+
+This dataset contains the token sequences, but some of these are longer than the maximum input length for the model.
+
+You can now use a second preprocessing function to
+
+- concatenate all the sequences
+- split the concatenated sequences into shorter chunks defined by `block_size`, which should be both shorter than the maximum input length and short enough for your GPU RAM.
+
+```py
+>>> block_size = 128
+
+
+>>> def group_texts(examples):
+... # Concatenate all texts.
+... concatenated_examples = {k: sum(examples[k], []) for k in examples.keys()}
+... total_length = len(concatenated_examples[list(examples.keys())[0]])
+... # We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
+... # customize this part to your needs.
+... if total_length >= block_size:
+... total_length = (total_length // block_size) * block_size
+... # Split by chunks of block_size.
+... result = {
+... k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
+... for k, t in concatenated_examples.items()
+... }
+... result["labels"] = result["input_ids"].copy()
+... return result
+```
+
+Apply the `group_texts` function over the entire dataset:
+
+```py
+>>> lm_dataset = tokenized_eli5.map(group_texts, batched=True, num_proc=4)
+```
+
+Now create a batch of examples using [`DataCollatorForLanguageModeling`]. It's more efficient to *dynamically pad* the
+sentences to the longest length in a batch during collation, instead of padding the whole dataset to the maximum length.
+
+
+
+Use the end-of-sequence token as the padding token and set `mlm=False`. This will use the inputs as labels shifted to the right by one element:
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> tokenizer.pad_token = tokenizer.eos_token
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False)
+```
+
+
+
+Use the end-of-sequence token as the padding token and set `mlm=False`. This will use the inputs as labels shifted to the right by one element:
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm=False, return_tensors="tf")
+```
+
+
+
+
+
+## Train
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the [basic tutorial](../training#train-with-pytorch-trainer)!
+
+
+
+You're ready to start training your model now! Load DistilGPT2 with [`AutoModelForCausalLM`]:
+
+```py
+>>> from transformers import AutoModelForCausalLM, TrainingArguments, Trainer
+
+>>> model = AutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`TrainingArguments`]. The only required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model).
+2. Pass the training arguments to [`Trainer`] along with the model, datasets, and data collator.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_eli5_clm-model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=lm_dataset["train"],
+... eval_dataset=lm_dataset["test"],
+... data_collator=data_collator,
+... tokenizer=tokenizer,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, use the [`~transformers.Trainer.evaluate`] method to evaluate your model and get its perplexity:
+
+```py
+>>> import math
+
+>>> eval_results = trainer.evaluate()
+>>> print(f"Perplexity: {math.exp(eval_results['eval_loss']):.2f}")
+Perplexity: 49.61
+```
+
+Then share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+If you aren't familiar with finetuning a model with Keras, take a look at the [basic tutorial](../training#train-a-tensorflow-model-with-keras)!
+
+
+To finetune a model in TensorFlow, start by setting up an optimizer function, learning rate schedule, and some training hyperparameters:
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+Then you can load DistilGPT2 with [`TFAutoModelForCausalLM`]:
+
+```py
+>>> from transformers import TFAutoModelForCausalLM
+
+>>> model = TFAutoModelForCausalLM.from_pretrained("distilbert/distilgpt2")
+```
+
+Convert your datasets to the `tf.data.Dataset` format with [`~transformers.TFPreTrainedModel.prepare_tf_dataset`]:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... lm_dataset["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... lm_dataset["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+Configure the model for training with [`compile`](https://keras.io/api/models/model_training_apis/#compile-method). Note that Transformers models all have a default task-relevant loss function, so you don't need to specify one unless you want to:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+This can be done by specifying where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> callback = PushToHubCallback(
+... output_dir="my_awesome_eli5_clm-model",
+... tokenizer=tokenizer,
+... )
+```
+
+Finally, you're ready to start training your model! Call [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) with your training and validation datasets, the number of epochs, and your callback to finetune the model:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=[callback])
+```
+
+Once training is completed, your model is automatically uploaded to the Hub so everyone can use it!
+
+
+
+
+
+For a more in-depth example of how to finetune a model for causal language modeling, take a look at the corresponding
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)
+or [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb).
+
+
+
+## Inference
+
+Great, now that you've finetuned a model, you can use it for inference!
+
+Come up with a prompt you'd like to generate text from:
+
+```py
+>>> prompt = "Somatic hypermutation allows the immune system to"
+```
+
+The simplest way to try out your finetuned model for inference is to use it in a [`pipeline`]. Instantiate a `pipeline` for text generation with your model, and pass your text to it:
+
+```py
+>>> from transformers import pipeline
+
+>>> generator = pipeline("text-generation", model="username/my_awesome_eli5_clm-model")
+>>> generator(prompt)
+[{'generated_text': "Somatic hypermutation allows the immune system to be able to effectively reverse the damage caused by an infection.\n\n\nThe damage caused by an infection is caused by the immune system's ability to perform its own self-correcting tasks."}]
+```
+
+
+
+Tokenize the text and return the `input_ids` as PyTorch tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("username/my_awesome_eli5_clm-model")
+>>> inputs = tokenizer(prompt, return_tensors="pt").input_ids
+```
+
+Use the [`~generation.GenerationMixin.generate`] method to generate text.
+For more details about the different text generation strategies and parameters for controlling generation, check out the [Text generation strategies](../generation_strategies) page.
+
+```py
+>>> from transformers import AutoModelForCausalLM
+
+>>> model = AutoModelForCausalLM.from_pretrained("username/my_awesome_eli5_clm-model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=True, top_k=50, top_p=0.95)
+```
+
+Decode the generated token ids back into text:
+
+```py
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+["Somatic hypermutation allows the immune system to react to drugs with the ability to adapt to a different environmental situation. In other words, a system of 'hypermutation' can help the immune system to adapt to a different environmental situation or in some cases even a single life. In contrast, researchers at the University of Massachusetts-Boston have found that 'hypermutation' is much stronger in mice than in humans but can be found in humans, and that it's not completely unknown to the immune system. A study on how the immune system"]
+```
+
+
+Tokenize the text and return the `input_ids` as TensorFlow tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("username/my_awesome_eli5_clm-model")
+>>> inputs = tokenizer(prompt, return_tensors="tf").input_ids
+```
+
+Use the [`~transformers.generation_tf_utils.TFGenerationMixin.generate`] method to create the summarization. For more details about the different text generation strategies and parameters for controlling generation, check out the [Text generation strategies](../generation_strategies) page.
+
+```py
+>>> from transformers import TFAutoModelForCausalLM
+
+>>> model = TFAutoModelForCausalLM.from_pretrained("username/my_awesome_eli5_clm-model")
+>>> outputs = model.generate(input_ids=inputs, max_new_tokens=100, do_sample=True, top_k=50, top_p=0.95)
+```
+
+Decode the generated token ids back into text:
+
+```py
+>>> tokenizer.batch_decode(outputs, skip_special_tokens=True)
+['Somatic hypermutation allows the immune system to detect the presence of other viruses as they become more prevalent. Therefore, researchers have identified a high proportion of human viruses. The proportion of virus-associated viruses in our study increases with age. Therefore, we propose a simple algorithm to detect the presence of these new viruses in our samples as a sign of improved immunity. A first study based on this algorithm, which will be published in Science on Friday, aims to show that this finding could translate into the development of a better vaccine that is more effective for']
+```
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/mask_generation.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/mask_generation.md
new file mode 100644
index 0000000000000000000000000000000000000000..28ecfd193be67af211d9b32dc4303e6e5a8bff70
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/mask_generation.md
@@ -0,0 +1,236 @@
+
+
+# Mask Generation
+
+Mask generation is the task of generating semantically meaningful masks for an image.
+This task is very similar to [image segmentation](semantic_segmentation), but many differences exist. Image segmentation models are trained on labeled datasets and are limited to the classes they have seen during training; they return a set of masks and corresponding classes, given an image.
+
+Mask generation models are trained on large amounts of data and operate in two modes.
+- Prompting mode: In this mode, the model takes in an image and a prompt, where a prompt can be a 2D point location (XY coordinates) in the image within an object or a bounding box surrounding an object. In prompting mode, the model only returns the mask over the object
+that the prompt is pointing out.
+- Segment Everything mode: In segment everything, given an image, the model generates every mask in the image. To do so, a grid of points is generated and overlaid on the image for inference.
+
+Mask generation task is supported by [Segment Anything Model (SAM)](model_doc/sam). It's a powerful model that consists of a Vision Transformer-based image encoder, a prompt encoder, and a two-way transformer mask decoder. Images and prompts are encoded, and the decoder takes these embeddings and generates valid masks.
+
+
+
+
+
+SAM serves as a powerful foundation model for segmentation as it has large data coverage. It is trained on
+[SA-1B](https://ai.meta.com/datasets/segment-anything/), a dataset with 1 million images and 1.1 billion masks.
+
+In this guide, you will learn how to:
+- Infer in segment everything mode with batching,
+- Infer in point prompting mode,
+- Infer in box prompting mode.
+
+First, let's install `transformers`:
+
+```bash
+pip install -q transformers
+```
+
+## Mask Generation Pipeline
+
+The easiest way to infer mask generation models is to use the `mask-generation` pipeline.
+
+```python
+>>> from transformers import pipeline
+
+>>> checkpoint = "facebook/sam-vit-base"
+>>> mask_generator = pipeline(model=checkpoint, task="mask-generation")
+```
+
+Let's see the image.
+
+```python
+from PIL import Image
+import requests
+
+img_url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg"
+image = Image.open(requests.get(img_url, stream=True).raw).convert("RGB")
+```
+
+
+
+
+
+Let's segment everything. `points-per-batch` enables parallel inference of points in segment everything mode. This enables faster inference, but consumes more memory. Moreover, SAM only enables batching over points and not the images. `pred_iou_thresh` is the IoU confidence threshold where only the masks above that certain threshold are returned.
+
+```python
+masks = mask_generator(image, points_per_batch=128, pred_iou_thresh=0.88)
+```
+
+The `masks` looks like the following:
+
+```bash
+{'masks': [array([[False, False, False, ..., True, True, True],
+ [False, False, False, ..., True, True, True],
+ [False, False, False, ..., True, True, True],
+ ...,
+ [False, False, False, ..., False, False, False],
+ [False, False, False, ..., False, False, False],
+ [False, False, False, ..., False, False, False]]),
+ array([[False, False, False, ..., False, False, False],
+ [False, False, False, ..., False, False, False],
+ [False, False, False, ..., False, False, False],
+ ...,
+'scores': tensor([0.9972, 0.9917,
+ ...,
+}
+```
+
+We can visualize them like this:
+
+```python
+import matplotlib.pyplot as plt
+
+plt.imshow(image, cmap='gray')
+
+for i, mask in enumerate(masks["masks"]):
+ plt.imshow(mask, cmap='viridis', alpha=0.1, vmin=0, vmax=1)
+
+plt.axis('off')
+plt.show()
+```
+
+Below is the original image in grayscale with colorful maps overlaid. Very impressive.
+
+
+
+
+
+
+## Model Inference
+
+### Point Prompting
+
+You can also use the model without the pipeline. To do so, initialize the model and
+the processor.
+
+```python
+from transformers import SamModel, SamProcessor, infer_device
+import torch
+device = infer_device()
+model = SamModel.from_pretrained("facebook/sam-vit-base").to(device)
+processor = SamProcessor.from_pretrained("facebook/sam-vit-base")
+```
+
+To do point prompting, pass the input point to the processor, then take the processor output
+and pass it to the model for inference. To post-process the model output, pass the outputs and
+`original_sizes` and `reshaped_input_sizes` we take from the processor's initial output. We need to pass these
+since the processor resizes the image, and the output needs to be extrapolated.
+
+```python
+input_points = [[[2592, 1728]]] # point location of the bee
+
+inputs = processor(image, input_points=input_points, return_tensors="pt").to(device)
+with torch.no_grad():
+ outputs = model(**inputs)
+masks = processor.image_processor.post_process_masks(outputs.pred_masks.cpu(), inputs["original_sizes"].cpu(), inputs["reshaped_input_sizes"].cpu())
+```
+We can visualize the three masks in the `masks` output.
+
+```python
+import matplotlib.pyplot as plt
+import numpy as np
+
+fig, axes = plt.subplots(1, 4, figsize=(15, 5))
+
+axes[0].imshow(image)
+axes[0].set_title('Original Image')
+mask_list = [masks[0][0][0].numpy(), masks[0][0][1].numpy(), masks[0][0][2].numpy()]
+
+for i, mask in enumerate(mask_list, start=1):
+ overlayed_image = np.array(image).copy()
+
+ overlayed_image[:,:,0] = np.where(mask == 1, 255, overlayed_image[:,:,0])
+ overlayed_image[:,:,1] = np.where(mask == 1, 0, overlayed_image[:,:,1])
+ overlayed_image[:,:,2] = np.where(mask == 1, 0, overlayed_image[:,:,2])
+
+ axes[i].imshow(overlayed_image)
+ axes[i].set_title(f'Mask {i}')
+for ax in axes:
+ ax.axis('off')
+
+plt.show()
+```
+
+
+
+
+
+### Box Prompting
+
+You can also do box prompting in a similar fashion to point prompting. You can simply pass the input box in the format of a list
+`[x_min, y_min, x_max, y_max]` format along with the image to the `processor`. Take the processor output and directly pass it
+to the model, then post-process the output again.
+
+
+```python
+# bounding box around the bee
+box = [2350, 1600, 2850, 2100]
+
+inputs = processor(
+ image,
+ input_boxes=[[[box]]],
+ return_tensors="pt"
+ ).to("cuda")
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+mask = processor.image_processor.post_process_masks(
+ outputs.pred_masks.cpu(),
+ inputs["original_sizes"].cpu(),
+ inputs["reshaped_input_sizes"].cpu()
+)[0][0][0].numpy()
+```
+
+You can visualize the bounding box around the bee as shown below.
+
+```python
+import matplotlib.patches as patches
+
+fig, ax = plt.subplots()
+ax.imshow(image)
+
+rectangle = patches.Rectangle((2350, 1600), 500, 500, linewidth=2, edgecolor='r', facecolor='none')
+ax.add_patch(rectangle)
+ax.axis("off")
+plt.show()
+```
+
+
+
+
+
+You can see the inference output below.
+
+```python
+fig, ax = plt.subplots()
+ax.imshow(image)
+ax.imshow(mask, cmap='viridis', alpha=0.4)
+
+ax.axis("off")
+plt.show()
+```
+
+
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/masked_language_modeling.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/masked_language_modeling.md
new file mode 100644
index 0000000000000000000000000000000000000000..469b1d7fcb99f63b0746cbba82dd5e8657cae7a3
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/masked_language_modeling.md
@@ -0,0 +1,445 @@
+
+
+# Masked language modeling
+
+[[open-in-colab]]
+
+
+
+Masked language modeling predicts a masked token in a sequence, and the model can attend to tokens bidirectionally. This
+means the model has full access to the tokens on the left and right. Masked language modeling is great for tasks that
+require a good contextual understanding of an entire sequence. BERT is an example of a masked language model.
+
+This guide will show you how to:
+
+1. Finetune [DistilRoBERTa](https://huggingface.co/distilbert/distilroberta-base) on the [r/askscience](https://www.reddit.com/r/askscience/) subset of the [ELI5](https://huggingface.co/datasets/eli5) dataset.
+2. Use your finetuned model for inference.
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/fill-mask)
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+We encourage you to log in to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to log in:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load ELI5 dataset
+
+Start by loading the first 5000 examples from the [ELI5-Category](https://huggingface.co/datasets/eli5_category) dataset with the 🤗 Datasets library. This'll give you a chance to experiment and make sure everything works before spending more time training on the full dataset.
+
+```py
+>>> from datasets import load_dataset
+
+>>> eli5 = load_dataset("eli5_category", split="train[:5000]")
+```
+
+Split the dataset's `train` split into a train and test set with the [`~datasets.Dataset.train_test_split`] method:
+
+```py
+>>> eli5 = eli5.train_test_split(test_size=0.2)
+```
+
+Then take a look at an example:
+
+```py
+>>> eli5["train"][0]
+{'q_id': '7h191n',
+ 'title': 'What does the tax bill that was passed today mean? How will it affect Americans in each tax bracket?',
+ 'selftext': '',
+ 'category': 'Economics',
+ 'subreddit': 'explainlikeimfive',
+ 'answers': {'a_id': ['dqnds8l', 'dqnd1jl', 'dqng3i1', 'dqnku5x'],
+ 'text': ["The tax bill is 500 pages long and there were a lot of changes still going on right to the end. It's not just an adjustment to the income tax brackets, it's a whole bunch of changes. As such there is no good answer to your question. The big take aways are: - Big reduction in corporate income tax rate will make large companies very happy. - Pass through rate change will make certain styles of business (law firms, hedge funds) extremely happy - Income tax changes are moderate, and are set to expire (though it's the kind of thing that might just always get re-applied without being made permanent) - People in high tax states (California, New York) lose out, and many of them will end up with their taxes raised.",
+ 'None yet. It has to be reconciled with a vastly different house bill and then passed again.',
+ 'Also: does this apply to 2017 taxes? Or does it start with 2018 taxes?',
+ 'This article explains both the House and senate bills, including the proposed changes to your income taxes based on your income level. URL_0'],
+ 'score': [21, 19, 5, 3],
+ 'text_urls': [[],
+ [],
+ [],
+ ['https://www.investopedia.com/news/trumps-tax-reform-what-can-be-done/']]},
+ 'title_urls': ['url'],
+ 'selftext_urls': ['url']}
+```
+
+While this may look like a lot, you're only really interested in the `text` field. What's cool about language modeling tasks is you don't need labels (also known as an unsupervised task) because the next word *is* the label.
+
+## Preprocess
+
+
+
+For masked language modeling, the next step is to load a DistilRoBERTa tokenizer to process the `text` subfield:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilroberta-base")
+```
+
+You'll notice from the example above, the `text` field is actually nested inside `answers`. This means you'll need to extract the `text` subfield from its nested structure with the [`flatten`](https://huggingface.co/docs/datasets/process#flatten) method:
+
+```py
+>>> eli5 = eli5.flatten()
+>>> eli5["train"][0]
+{'q_id': '7h191n',
+ 'title': 'What does the tax bill that was passed today mean? How will it affect Americans in each tax bracket?',
+ 'selftext': '',
+ 'category': 'Economics',
+ 'subreddit': 'explainlikeimfive',
+ 'answers.a_id': ['dqnds8l', 'dqnd1jl', 'dqng3i1', 'dqnku5x'],
+ 'answers.text': ["The tax bill is 500 pages long and there were a lot of changes still going on right to the end. It's not just an adjustment to the income tax brackets, it's a whole bunch of changes. As such there is no good answer to your question. The big take aways are: - Big reduction in corporate income tax rate will make large companies very happy. - Pass through rate change will make certain styles of business (law firms, hedge funds) extremely happy - Income tax changes are moderate, and are set to expire (though it's the kind of thing that might just always get re-applied without being made permanent) - People in high tax states (California, New York) lose out, and many of them will end up with their taxes raised.",
+ 'None yet. It has to be reconciled with a vastly different house bill and then passed again.',
+ 'Also: does this apply to 2017 taxes? Or does it start with 2018 taxes?',
+ 'This article explains both the House and senate bills, including the proposed changes to your income taxes based on your income level. URL_0'],
+ 'answers.score': [21, 19, 5, 3],
+ 'answers.text_urls': [[],
+ [],
+ [],
+ ['https://www.investopedia.com/news/trumps-tax-reform-what-can-be-done/']],
+ 'title_urls': ['url'],
+ 'selftext_urls': ['url']}
+```
+
+Each subfield is now a separate column as indicated by the `answers` prefix, and the `text` field is a list now. Instead
+of tokenizing each sentence separately, convert the list to a string so you can jointly tokenize them.
+
+Here is a first preprocessing function to join the list of strings for each example and tokenize the result:
+
+```py
+>>> def preprocess_function(examples):
+... return tokenizer([" ".join(x) for x in examples["answers.text"]])
+```
+
+To apply this preprocessing function over the entire dataset, use the 🤗 Datasets [`~datasets.Dataset.map`] method. You can speed up the `map` function by setting `batched=True` to process multiple elements of the dataset at once, and increasing the number of processes with `num_proc`. Remove any columns you don't need:
+
+```py
+>>> tokenized_eli5 = eli5.map(
+... preprocess_function,
+... batched=True,
+... num_proc=4,
+... remove_columns=eli5["train"].column_names,
+... )
+```
+
+This dataset contains the token sequences, but some of these are longer than the maximum input length for the model.
+
+You can now use a second preprocessing function to
+- concatenate all the sequences
+- split the concatenated sequences into shorter chunks defined by `block_size`, which should be both shorter than the maximum input length and short enough for your GPU RAM.
+
+```py
+>>> block_size = 128
+
+
+>>> def group_texts(examples):
+... # Concatenate all texts.
+... concatenated_examples = {k: sum(examples[k], []) for k in examples.keys()}
+... total_length = len(concatenated_examples[list(examples.keys())[0]])
+... # We drop the small remainder, we could add padding if the model supported it instead of this drop, you can
+... # customize this part to your needs.
+... if total_length >= block_size:
+... total_length = (total_length // block_size) * block_size
+... # Split by chunks of block_size.
+... result = {
+... k: [t[i : i + block_size] for i in range(0, total_length, block_size)]
+... for k, t in concatenated_examples.items()
+... }
+... return result
+```
+
+Apply the `group_texts` function over the entire dataset:
+
+```py
+>>> lm_dataset = tokenized_eli5.map(group_texts, batched=True, num_proc=4)
+```
+
+Now create a batch of examples using [`DataCollatorForLanguageModeling`]. It's more efficient to *dynamically pad* the sentences to the longest length in a batch during collation, instead of padding the whole dataset to the maximum length.
+
+
+
+
+Use the end-of-sequence token as the padding token and specify `mlm_probability` to randomly mask tokens each time you iterate over the data:
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> tokenizer.pad_token = tokenizer.eos_token
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=0.15)
+```
+
+
+
+Use the end-of-sequence token as the padding token and specify `mlm_probability` to randomly mask tokens each time you iterate over the data:
+
+```py
+>>> from transformers import DataCollatorForLanguageModeling
+
+>>> data_collator = DataCollatorForLanguageModeling(tokenizer=tokenizer, mlm_probability=0.15, return_tensors="tf")
+```
+
+
+
+## Train
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#train-with-pytorch-trainer)!
+
+
+
+You're ready to start training your model now! Load DistilRoBERTa with [`AutoModelForMaskedLM`]:
+
+```py
+>>> from transformers import AutoModelForMaskedLM
+
+>>> model = AutoModelForMaskedLM.from_pretrained("distilbert/distilroberta-base")
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`TrainingArguments`]. The only required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model).
+2. Pass the training arguments to [`Trainer`] along with the model, datasets, and data collator.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_eli5_mlm_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=lm_dataset["train"],
+... eval_dataset=lm_dataset["test"],
+... data_collator=data_collator,
+... tokenizer=tokenizer,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, use the [`~transformers.Trainer.evaluate`] method to evaluate your model and get its perplexity:
+
+```py
+>>> import math
+
+>>> eval_results = trainer.evaluate()
+>>> print(f"Perplexity: {math.exp(eval_results['eval_loss']):.2f}")
+Perplexity: 8.76
+```
+
+Then share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+If you aren't familiar with finetuning a model with Keras, take a look at the basic tutorial [here](../training#train-a-tensorflow-model-with-keras)!
+
+
+To finetune a model in TensorFlow, start by setting up an optimizer function, learning rate schedule, and some training hyperparameters:
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+Then you can load DistilRoBERTa with [`TFAutoModelForMaskedLM`]:
+
+```py
+>>> from transformers import TFAutoModelForMaskedLM
+
+>>> model = TFAutoModelForMaskedLM.from_pretrained("distilbert/distilroberta-base")
+```
+
+Convert your datasets to the `tf.data.Dataset` format with [`~transformers.TFPreTrainedModel.prepare_tf_dataset`]:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... lm_dataset["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... lm_dataset["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+Configure the model for training with [`compile`](https://keras.io/api/models/model_training_apis/#compile-method). Note that Transformers models all have a default task-relevant loss function, so you don't need to specify one unless you want to:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+This can be done by specifying where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> callback = PushToHubCallback(
+... output_dir="my_awesome_eli5_mlm_model",
+... tokenizer=tokenizer,
+... )
+```
+
+Finally, you're ready to start training your model! Call [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) with your training and validation datasets, the number of epochs, and your callback to finetune the model:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=[callback])
+```
+
+Once training is completed, your model is automatically uploaded to the Hub so everyone can use it!
+
+
+
+
+
+For a more in-depth example of how to finetune a model for masked language modeling, take a look at the corresponding
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling.ipynb)
+or [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/language_modeling-tf.ipynb).
+
+
+
+## Inference
+
+Great, now that you've finetuned a model, you can use it for inference!
+
+Come up with some text you'd like the model to fill in the blank with, and use the special `` token to indicate the blank:
+
+```py
+>>> text = "The Milky Way is a galaxy."
+```
+
+The simplest way to try out your finetuned model for inference is to use it in a [`pipeline`]. Instantiate a `pipeline` for fill-mask with your model, and pass your text to it. If you like, you can use the `top_k` parameter to specify how many predictions to return:
+
+```py
+>>> from transformers import pipeline
+
+>>> mask_filler = pipeline("fill-mask", "username/my_awesome_eli5_mlm_model")
+>>> mask_filler(text, top_k=3)
+[{'score': 0.5150994658470154,
+ 'token': 21300,
+ 'token_str': ' spiral',
+ 'sequence': 'The Milky Way is a spiral galaxy.'},
+ {'score': 0.07087188959121704,
+ 'token': 2232,
+ 'token_str': ' massive',
+ 'sequence': 'The Milky Way is a massive galaxy.'},
+ {'score': 0.06434620916843414,
+ 'token': 650,
+ 'token_str': ' small',
+ 'sequence': 'The Milky Way is a small galaxy.'}]
+```
+
+
+
+Tokenize the text and return the `input_ids` as PyTorch tensors. You'll also need to specify the position of the `` token:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("username/my_awesome_eli5_mlm_model")
+>>> inputs = tokenizer(text, return_tensors="pt")
+>>> mask_token_index = torch.where(inputs["input_ids"] == tokenizer.mask_token_id)[1]
+```
+
+Pass your inputs to the model and return the `logits` of the masked token:
+
+```py
+>>> from transformers import AutoModelForMaskedLM
+
+>>> model = AutoModelForMaskedLM.from_pretrained("username/my_awesome_eli5_mlm_model")
+>>> logits = model(**inputs).logits
+>>> mask_token_logits = logits[0, mask_token_index, :]
+```
+
+Then return the three masked tokens with the highest probability and print them out:
+
+```py
+>>> top_3_tokens = torch.topk(mask_token_logits, 3, dim=1).indices[0].tolist()
+
+>>> for token in top_3_tokens:
+... print(text.replace(tokenizer.mask_token, tokenizer.decode([token])))
+The Milky Way is a spiral galaxy.
+The Milky Way is a massive galaxy.
+The Milky Way is a small galaxy.
+```
+
+
+Tokenize the text and return the `input_ids` as TensorFlow tensors. You'll also need to specify the position of the `` token:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("username/my_awesome_eli5_mlm_model")
+>>> inputs = tokenizer(text, return_tensors="tf")
+>>> mask_token_index = tf.where(inputs["input_ids"] == tokenizer.mask_token_id)[0, 1]
+```
+
+Pass your inputs to the model and return the `logits` of the masked token:
+
+```py
+>>> from transformers import TFAutoModelForMaskedLM
+
+>>> model = TFAutoModelForMaskedLM.from_pretrained("username/my_awesome_eli5_mlm_model")
+>>> logits = model(**inputs).logits
+>>> mask_token_logits = logits[0, mask_token_index, :]
+```
+
+Then return the three masked tokens with the highest probability and print them out:
+
+```py
+>>> top_3_tokens = tf.math.top_k(mask_token_logits, 3).indices.numpy()
+
+>>> for token in top_3_tokens:
+... print(text.replace(tokenizer.mask_token, tokenizer.decode([token])))
+The Milky Way is a spiral galaxy.
+The Milky Way is a massive galaxy.
+The Milky Way is a small galaxy.
+```
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/monocular_depth_estimation.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/monocular_depth_estimation.md
new file mode 100644
index 0000000000000000000000000000000000000000..c90abce1cd57b4d2525d541c6c9c3f41acbfc4f1
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/monocular_depth_estimation.md
@@ -0,0 +1,159 @@
+
+
+# Monocular depth estimation
+
+Monocular depth estimation is a computer vision task that involves predicting the depth information of a scene from a
+single image. In other words, it is the process of estimating the distance of objects in a scene from
+a single camera viewpoint.
+
+Monocular depth estimation has various applications, including 3D reconstruction, augmented reality, autonomous driving,
+and robotics. It is a challenging task as it requires the model to understand the complex relationships between objects
+in the scene and the corresponding depth information, which can be affected by factors such as lighting conditions,
+occlusion, and texture.
+
+There are two main depth estimation categories:
+
+- **Absolute depth estimation**: This task variant aims to provide exact depth measurements from the camera. The term is used interchangeably with metric depth estimation, where depth is provided in precise measurements in meters or feet. Absolute depth estimation models output depth maps with numerical values that represent real-world distances.
+
+- **Relative depth estimation**: Relative depth estimation aims to predict the depth order of objects or points in a scene without providing the precise measurements. These models output a depth map that indicates which parts of the scene are closer or farther relative to each other without the actual distances to A and B.
+
+In this guide, we will see how to infer with [Depth Anything V2](https://huggingface.co/depth-anything/Depth-Anything-V2-Large), a state-of-the-art zero-shot relative depth estimation model, and [ZoeDepth](https://huggingface.co/docs/transformers/main/en/model_doc/zoedepth), an absolute depth estimation model.
+
+
+
+Check the [Depth Estimation](https://huggingface.co/tasks/depth-estimation) task page to view all compatible architectures and checkpoints.
+
+
+
+Before we begin, we need to install the latest version of Transformers:
+
+```bash
+pip install -q -U transformers
+```
+
+## Depth estimation pipeline
+
+The simplest way to try out inference with a model supporting depth estimation is to use the corresponding [`pipeline`].
+Instantiate a pipeline from a [checkpoint on the Hugging Face Hub](https://huggingface.co/models?pipeline_tag=depth-estimation&sort=downloads):
+
+```py
+>>> from transformers import pipeline, infer_device
+>>> import torch
+>>> device = infer_device()
+>>> checkpoint = "depth-anything/Depth-Anything-V2-base-hf"
+>>> pipe = pipeline("depth-estimation", model=checkpoint, device=device)
+```
+
+Next, choose an image to analyze:
+
+```py
+>>> from PIL import Image
+>>> import requests
+
+>>> url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> image
+```
+
+
+
+
+
+Pass the image to the pipeline.
+
+```py
+>>> predictions = pipe(image)
+```
+
+The pipeline returns a dictionary with two entries. The first one, called `predicted_depth`, is a tensor with the values
+being the depth expressed in meters for each pixel.
+The second one, `depth`, is a PIL image that visualizes the depth estimation result.
+
+Let's take a look at the visualized result:
+
+```py
+>>> predictions["depth"]
+```
+
+
+
+
+
+## Depth estimation inference by hand
+
+Now that you've seen how to use the depth estimation pipeline, let's see how we can replicate the same result by hand.
+
+Start by loading the model and associated processor from a [checkpoint on the Hugging Face Hub](https://huggingface.co/models?pipeline_tag=depth-estimation&sort=downloads).
+Here we'll use the same checkpoint as before:
+
+```py
+>>> from transformers import AutoImageProcessor, AutoModelForDepthEstimation
+
+>>> checkpoint = "Intel/zoedepth-nyu-kitti"
+
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint)
+>>> model = AutoModelForDepthEstimation.from_pretrained(checkpoint).to(device)
+```
+
+Prepare the image input for the model using the `image_processor` that will take care of the necessary image transformations
+such as resizing and normalization:
+
+```py
+>>> pixel_values = image_processor(image, return_tensors="pt").pixel_values.to(device)
+```
+
+Pass the prepared inputs through the model:
+
+```py
+>>> import torch
+
+>>> with torch.no_grad():
+... outputs = model(pixel_values)
+```
+
+Let's post-process the results to remove any padding and resize the depth map to match the original image size. The `post_process_depth_estimation` outputs a list of dicts containing the `"predicted_depth"`.
+
+```py
+>>> # ZoeDepth dynamically pads the input image. Thus we pass the original image size as argument
+>>> # to `post_process_depth_estimation` to remove the padding and resize to original dimensions.
+>>> post_processed_output = image_processor.post_process_depth_estimation(
+... outputs,
+... source_sizes=[(image.height, image.width)],
+... )
+
+>>> predicted_depth = post_processed_output[0]["predicted_depth"]
+>>> depth = (predicted_depth - predicted_depth.min()) / (predicted_depth.max() - predicted_depth.min())
+>>> depth = depth.detach().cpu().numpy() * 255
+>>> depth = Image.fromarray(depth.astype("uint8"))
+```
+
+
+
In the original implementation ZoeDepth model performs inference on both the original and flipped images and averages out the results. The post_process_depth_estimation function can handle this for us by passing the flipped outputs to the optional outputs_flipped argument:
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/multiple_choice.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/multiple_choice.md
new file mode 100644
index 0000000000000000000000000000000000000000..0cac42a649859fb7c709c9b9dbaeb4f30d8f2b82
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/multiple_choice.md
@@ -0,0 +1,369 @@
+
+
+# Multiple choice
+
+[[open-in-colab]]
+
+A multiple choice task is similar to question answering, except several candidate answers are provided along with a context and the model is trained to select the correct answer.
+
+This guide will show you how to:
+
+1. Finetune [BERT](https://huggingface.co/google-bert/bert-base-uncased) on the `regular` configuration of the [SWAG](https://huggingface.co/datasets/swag) dataset to select the best answer given multiple options and some context.
+2. Use your finetuned model for inference.
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+We encourage you to login to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to login:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load SWAG dataset
+
+Start by loading the `regular` configuration of the SWAG dataset from the 🤗 Datasets library:
+
+```py
+>>> from datasets import load_dataset
+
+>>> swag = load_dataset("swag", "regular")
+```
+
+Then take a look at an example:
+
+```py
+>>> swag["train"][0]
+{'ending0': 'passes by walking down the street playing their instruments.',
+ 'ending1': 'has heard approaching them.',
+ 'ending2': "arrives and they're outside dancing and asleep.",
+ 'ending3': 'turns the lead singer watches the performance.',
+ 'fold-ind': '3416',
+ 'gold-source': 'gold',
+ 'label': 0,
+ 'sent1': 'Members of the procession walk down the street holding small horn brass instruments.',
+ 'sent2': 'A drum line',
+ 'startphrase': 'Members of the procession walk down the street holding small horn brass instruments. A drum line',
+ 'video-id': 'anetv_jkn6uvmqwh4'}
+```
+
+While it looks like there are a lot of fields here, it is actually pretty straightforward:
+
+- `sent1` and `sent2`: these fields show how a sentence starts, and if you put the two together, you get the `startphrase` field.
+- `ending`: suggests a possible ending for how a sentence can end, but only one of them is correct.
+- `label`: identifies the correct sentence ending.
+
+## Preprocess
+
+The next step is to load a BERT tokenizer to process the sentence starts and the four possible endings:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("google-bert/bert-base-uncased")
+```
+
+The preprocessing function you want to create needs to:
+
+1. Make four copies of the `sent1` field and combine each of them with `sent2` to recreate how a sentence starts.
+2. Combine `sent2` with each of the four possible sentence endings.
+3. Flatten these two lists so you can tokenize them, and then unflatten them afterward so each example has a corresponding `input_ids`, `attention_mask`, and `labels` field.
+
+```py
+>>> ending_names = ["ending0", "ending1", "ending2", "ending3"]
+
+
+>>> def preprocess_function(examples):
+... first_sentences = [[context] * 4 for context in examples["sent1"]]
+... question_headers = examples["sent2"]
+... second_sentences = [
+... [f"{header} {examples[end][i]}" for end in ending_names] for i, header in enumerate(question_headers)
+... ]
+
+... first_sentences = sum(first_sentences, [])
+... second_sentences = sum(second_sentences, [])
+
+... tokenized_examples = tokenizer(first_sentences, second_sentences, truncation=True)
+... return {k: [v[i : i + 4] for i in range(0, len(v), 4)] for k, v in tokenized_examples.items()}
+```
+
+To apply the preprocessing function over the entire dataset, use 🤗 Datasets [`~datasets.Dataset.map`] method. You can speed up the `map` function by setting `batched=True` to process multiple elements of the dataset at once:
+
+```py
+>>> tokenized_swag = swag.map(preprocess_function, batched=True)
+```
+
+To create a batch of examples, it's more efficient to *dynamically pad* the sentences to the longest length in a batch during collation, instead of padding the whole dataset to the maximum length. [`DataCollatorForMultipleChoice`] flattens all the model inputs, applies padding, and then unflattens the results.
+```py
+>>> from transformers import DataCollatorForMultipleChoice
+>>> collator = DataCollatorForMultipleChoice(tokenizer=tokenizer)
+```
+
+## Evaluate
+
+Including a metric during training is often helpful for evaluating your model's performance. You can quickly load a evaluation method with the 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) library. For this task, load the [accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) metric (see the 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour) to learn more about how to load and compute a metric):
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+Then create a function that passes your predictions and labels to [`~evaluate.EvaluationModule.compute`] to calculate the accuracy:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... predictions = np.argmax(predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=labels)
+```
+
+Your `compute_metrics` function is ready to go now, and you'll return to it when you setup your training.
+
+## Train
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#train-with-pytorch-trainer)!
+
+
+
+You're ready to start training your model now! Load BERT with [`AutoModelForMultipleChoice`]:
+
+```py
+>>> from transformers import AutoModelForMultipleChoice, TrainingArguments, Trainer
+
+>>> model = AutoModelForMultipleChoice.from_pretrained("google-bert/bert-base-uncased")
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`TrainingArguments`]. The only required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model). At the end of each epoch, the [`Trainer`] will evaluate the accuracy and save the training checkpoint.
+2. Pass the training arguments to [`Trainer`] along with the model, dataset, tokenizer, data collator, and `compute_metrics` function.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_swag_model",
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... load_best_model_at_end=True,
+... learning_rate=5e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_swag["train"],
+... eval_dataset=tokenized_swag["validation"],
+... processing_class=tokenizer,
+... data_collator=collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+If you aren't familiar with finetuning a model with Keras, take a look at the basic tutorial [here](../training#train-a-tensorflow-model-with-keras)!
+
+
+To finetune a model in TensorFlow, start by setting up an optimizer function, learning rate schedule, and some training hyperparameters:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_train_epochs = 2
+>>> total_train_steps = (len(tokenized_swag["train"]) // batch_size) * num_train_epochs
+>>> optimizer, schedule = create_optimizer(init_lr=5e-5, num_warmup_steps=0, num_train_steps=total_train_steps)
+```
+
+Then you can load BERT with [`TFAutoModelForMultipleChoice`]:
+
+```py
+>>> from transformers import TFAutoModelForMultipleChoice
+
+>>> model = TFAutoModelForMultipleChoice.from_pretrained("google-bert/bert-base-uncased")
+```
+
+Convert your datasets to the `tf.data.Dataset` format with [`~transformers.TFPreTrainedModel.prepare_tf_dataset`]:
+
+```py
+>>> data_collator = DataCollatorForMultipleChoice(tokenizer=tokenizer)
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_swag["train"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_swag["validation"],
+... shuffle=False,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+```
+
+Configure the model for training with [`compile`](https://keras.io/api/models/model_training_apis/#compile-method). Note that Transformers models all have a default task-relevant loss function, so you don't need to specify one unless you want to:
+
+```py
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+The last two things to setup before you start training is to compute the accuracy from the predictions, and provide a way to push your model to the Hub. Both are done by using [Keras callbacks](../main_classes/keras_callbacks).
+
+Pass your `compute_metrics` function to [`~transformers.KerasMetricCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+Specify where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_model",
+... tokenizer=tokenizer,
+... )
+```
+
+Then bundle your callbacks together:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+Finally, you're ready to start training your model! Call [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) with your training and validation datasets, the number of epochs, and your callbacks to finetune the model:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=2, callbacks=callbacks)
+```
+
+Once training is completed, your model is automatically uploaded to the Hub so everyone can use it!
+
+
+
+
+
+
+For a more in-depth example of how to finetune a model for multiple choice, take a look at the corresponding
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice.ipynb)
+or [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/multiple_choice-tf.ipynb).
+
+
+
+## Inference
+
+Great, now that you've finetuned a model, you can use it for inference!
+
+Come up with some text and two candidate answers:
+
+```py
+>>> prompt = "France has a bread law, Le Décret Pain, with strict rules on what is allowed in a traditional baguette."
+>>> candidate1 = "The law does not apply to croissants and brioche."
+>>> candidate2 = "The law applies to baguettes."
+```
+
+
+
+Tokenize each prompt and candidate answer pair and return PyTorch tensors. You should also create some `labels`:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("username/my_awesome_swag_model")
+>>> inputs = tokenizer([[prompt, candidate1], [prompt, candidate2]], return_tensors="pt", padding=True)
+>>> labels = torch.tensor(0).unsqueeze(0)
+```
+
+Pass your inputs and labels to the model and return the `logits`:
+
+```py
+>>> from transformers import AutoModelForMultipleChoice
+
+>>> model = AutoModelForMultipleChoice.from_pretrained("username/my_awesome_swag_model")
+>>> outputs = model(**{k: v.unsqueeze(0) for k, v in inputs.items()}, labels=labels)
+>>> logits = outputs.logits
+```
+
+Get the class with the highest probability:
+
+```py
+>>> predicted_class = logits.argmax().item()
+>>> predicted_class
+0
+```
+
+
+Tokenize each prompt and candidate answer pair and return TensorFlow tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("username/my_awesome_swag_model")
+>>> inputs = tokenizer([[prompt, candidate1], [prompt, candidate2]], return_tensors="tf", padding=True)
+```
+
+Pass your inputs to the model and return the `logits`:
+
+```py
+>>> from transformers import TFAutoModelForMultipleChoice
+
+>>> model = TFAutoModelForMultipleChoice.from_pretrained("username/my_awesome_swag_model")
+>>> inputs = {k: tf.expand_dims(v, 0) for k, v in inputs.items()}
+>>> outputs = model(inputs)
+>>> logits = outputs.logits
+```
+
+Get the class with the highest probability:
+
+```py
+>>> predicted_class = int(tf.math.argmax(logits, axis=-1)[0])
+>>> predicted_class
+0
+```
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/object_detection.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/object_detection.md
new file mode 100644
index 0000000000000000000000000000000000000000..394e77104b74c764fca4476aa3bb9af6b7c7958a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/object_detection.md
@@ -0,0 +1,1540 @@
+
+
+# Object detection
+
+[[open-in-colab]]
+
+Object detection is the computer vision task of detecting instances (such as humans, buildings, or cars) in an image. Object detection models receive an image as input and output
+coordinates of the bounding boxes and associated labels of the detected objects. An image can contain multiple objects,
+each with its own bounding box and a label (e.g. it can have a car and a building), and each object can
+be present in different parts of an image (e.g. the image can have several cars).
+This task is commonly used in autonomous driving for detecting things like pedestrians, road signs, and traffic lights.
+Other applications include counting objects in images, image search, and more.
+
+In this guide, you will learn how to:
+
+ 1. Finetune [DETR](https://huggingface.co/docs/transformers/model_doc/detr), a model that combines a convolutional
+ backbone with an encoder-decoder Transformer, on the [CPPE-5](https://huggingface.co/datasets/cppe-5)
+ dataset.
+ 2. Use your finetuned model for inference.
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/object-detection)
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install -q datasets transformers accelerate timm
+pip install -q -U albumentations>=1.4.5 torchmetrics pycocotools
+```
+
+You'll use 🤗 Datasets to load a dataset from the Hugging Face Hub, 🤗 Transformers to train your model,
+and `albumentations` to augment the data.
+
+We encourage you to share your model with the community. Log in to your Hugging Face account to upload it to the Hub.
+When prompted, enter your token to log in:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+To get started, we'll define global constants, namely the model name and image size. For this tutorial, we'll use the conditional DETR model due to its faster convergence. Feel free to select any object detection model available in the `transformers` library.
+
+```py
+>>> MODEL_NAME = "microsoft/conditional-detr-resnet-50" # or "facebook/detr-resnet-50"
+>>> IMAGE_SIZE = 480
+```
+
+## Load the CPPE-5 dataset
+
+The [CPPE-5 dataset](https://huggingface.co/datasets/cppe-5) contains images with
+annotations identifying medical personal protective equipment (PPE) in the context of the COVID-19 pandemic.
+
+Start by loading the dataset and creating a `validation` split from `train`:
+
+```py
+>>> from datasets import load_dataset
+
+>>> cppe5 = load_dataset("cppe-5")
+
+>>> if "validation" not in cppe5:
+... split = cppe5["train"].train_test_split(0.15, seed=1337)
+... cppe5["train"] = split["train"]
+... cppe5["validation"] = split["test"]
+
+>>> cppe5
+DatasetDict({
+ train: Dataset({
+ features: ['image_id', 'image', 'width', 'height', 'objects'],
+ num_rows: 850
+ })
+ test: Dataset({
+ features: ['image_id', 'image', 'width', 'height', 'objects'],
+ num_rows: 29
+ })
+ validation: Dataset({
+ features: ['image_id', 'image', 'width', 'height', 'objects'],
+ num_rows: 150
+ })
+})
+```
+
+You'll see that this dataset has 1000 images for train and validation sets and a test set with 29 images.
+
+To get familiar with the data, explore what the examples look like.
+
+```py
+>>> cppe5["train"][0]
+{
+ 'image_id': 366,
+ 'image': ,
+ 'width': 500,
+ 'height': 500,
+ 'objects': {
+ 'id': [1932, 1933, 1934],
+ 'area': [27063, 34200, 32431],
+ 'bbox': [[29.0, 11.0, 97.0, 279.0],
+ [201.0, 1.0, 120.0, 285.0],
+ [382.0, 0.0, 113.0, 287.0]],
+ 'category': [0, 0, 0]
+ }
+}
+```
+
+The examples in the dataset have the following fields:
+- `image_id`: the example image id
+- `image`: a `PIL.Image.Image` object containing the image
+- `width`: width of the image
+- `height`: height of the image
+- `objects`: a dictionary containing bounding box metadata for the objects in the image:
+ - `id`: the annotation id
+ - `area`: the area of the bounding box
+ - `bbox`: the object's bounding box (in the [COCO format](https://albumentations.ai/docs/getting_started/bounding_boxes_augmentation/#coco) )
+ - `category`: the object's category, with possible values including `Coverall (0)`, `Face_Shield (1)`, `Gloves (2)`, `Goggles (3)` and `Mask (4)`
+
+You may notice that the `bbox` field follows the COCO format, which is the format that the DETR model expects.
+However, the grouping of the fields inside `objects` differs from the annotation format DETR requires. You will
+need to apply some preprocessing transformations before using this data for training.
+
+To get an even better understanding of the data, visualize an example in the dataset.
+
+```py
+>>> import numpy as np
+>>> import os
+>>> from PIL import Image, ImageDraw
+
+>>> image = cppe5["train"][2]["image"]
+>>> annotations = cppe5["train"][2]["objects"]
+>>> draw = ImageDraw.Draw(image)
+
+>>> categories = cppe5["train"].features["objects"]["category"].feature.names
+
+>>> id2label = {index: x for index, x in enumerate(categories, start=0)}
+>>> label2id = {v: k for k, v in id2label.items()}
+
+>>> for i in range(len(annotations["id"])):
+... box = annotations["bbox"][i]
+... class_idx = annotations["category"][i]
+... x, y, w, h = tuple(box)
+... # Check if coordinates are normalized or not
+... if max(box) > 1.0:
+... # Coordinates are un-normalized, no need to re-scale them
+... x1, y1 = int(x), int(y)
+... x2, y2 = int(x + w), int(y + h)
+... else:
+... # Coordinates are normalized, re-scale them
+... x1 = int(x * width)
+... y1 = int(y * height)
+... x2 = int((x + w) * width)
+... y2 = int((y + h) * height)
+... draw.rectangle((x, y, x + w, y + h), outline="red", width=1)
+... draw.text((x, y), id2label[class_idx], fill="white")
+
+>>> image
+```
+
+
+
+
+
+To visualize the bounding boxes with associated labels, you can get the labels from the dataset's metadata, specifically
+the `category` field.
+You'll also want to create dictionaries that map a label id to a label class (`id2label`) and the other way around (`label2id`).
+You can use them later when setting up the model. Including these maps will make your model reusable by others if you share
+it on the Hugging Face Hub. Please note that, the part of above code that draws the bounding boxes assume that it is in `COCO` format `(x_min, y_min, width, height)`. It has to be adjusted to work for other formats like `(x_min, y_min, x_max, y_max)`.
+
+As a final step of getting familiar with the data, explore it for potential issues. One common problem with datasets for
+object detection is bounding boxes that "stretch" beyond the edge of the image. Such "runaway" bounding boxes can raise
+errors during training and should be addressed. There are a few examples with this issue in this dataset.
+To keep things simple in this guide, we will set `clip=True` for `BboxParams` in transformations below.
+
+## Preprocess the data
+
+To finetune a model, you must preprocess the data you plan to use to match precisely the approach used for the pre-trained model.
+[`AutoImageProcessor`] takes care of processing image data to create `pixel_values`, `pixel_mask`, and
+`labels` that a DETR model can train with. The image processor has some attributes that you won't have to worry about:
+
+- `image_mean = [0.485, 0.456, 0.406 ]`
+- `image_std = [0.229, 0.224, 0.225]`
+
+These are the mean and standard deviation used to normalize images during the model pre-training. These values are crucial
+to replicate when doing inference or finetuning a pre-trained image model.
+
+Instantiate the image processor from the same checkpoint as the model you want to finetune.
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> MAX_SIZE = IMAGE_SIZE
+
+>>> image_processor = AutoImageProcessor.from_pretrained(
+... MODEL_NAME,
+... do_resize=True,
+... size={"max_height": MAX_SIZE, "max_width": MAX_SIZE},
+... do_pad=True,
+... pad_size={"height": MAX_SIZE, "width": MAX_SIZE},
+... )
+```
+
+Before passing the images to the `image_processor`, apply two preprocessing transformations to the dataset:
+- Augmenting images
+- Reformatting annotations to meet DETR expectations
+
+First, to make sure the model does not overfit on the training data, you can apply image augmentation with any data augmentation library. Here we use [Albumentations](https://albumentations.ai/docs/).
+This library ensures that transformations affect the image and update the bounding boxes accordingly.
+The 🤗 Datasets library documentation has a detailed [guide on how to augment images for object detection](https://huggingface.co/docs/datasets/object_detection),
+and it uses the exact same dataset as an example. Apply some geometric and color transformations to the image. For additional augmentation options, explore the [Albumentations Demo Space](https://huggingface.co/spaces/qubvel-hf/albumentations-demo).
+
+```py
+>>> import albumentations as A
+
+>>> train_augment_and_transform = A.Compose(
+... [
+... A.Perspective(p=0.1),
+... A.HorizontalFlip(p=0.5),
+... A.RandomBrightnessContrast(p=0.5),
+... A.HueSaturationValue(p=0.1),
+... ],
+... bbox_params=A.BboxParams(format="coco", label_fields=["category"], clip=True, min_area=25),
+... )
+
+>>> validation_transform = A.Compose(
+... [A.NoOp()],
+... bbox_params=A.BboxParams(format="coco", label_fields=["category"], clip=True),
+... )
+```
+
+The `image_processor` expects the annotations to be in the following format: `{'image_id': int, 'annotations': list[Dict]}`,
+ where each dictionary is a COCO object annotation. Let's add a function to reformat annotations for a single example:
+
+```py
+>>> def format_image_annotations_as_coco(image_id, categories, areas, bboxes):
+... """Format one set of image annotations to the COCO format
+
+... Args:
+... image_id (str): image id. e.g. "0001"
+... categories (list[int]): list of categories/class labels corresponding to provided bounding boxes
+... areas (list[float]): list of corresponding areas to provided bounding boxes
+... bboxes (list[tuple[float]]): list of bounding boxes provided in COCO format
+... ([center_x, center_y, width, height] in absolute coordinates)
+
+... Returns:
+... dict: {
+... "image_id": image id,
+... "annotations": list of formatted annotations
+... }
+... """
+... annotations = []
+... for category, area, bbox in zip(categories, areas, bboxes):
+... formatted_annotation = {
+... "image_id": image_id,
+... "category_id": category,
+... "iscrowd": 0,
+... "area": area,
+... "bbox": list(bbox),
+... }
+... annotations.append(formatted_annotation)
+
+... return {
+... "image_id": image_id,
+... "annotations": annotations,
+... }
+
+```
+
+Now you can combine the image and annotation transformations to use on a batch of examples:
+
+```py
+>>> def augment_and_transform_batch(examples, transform, image_processor, return_pixel_mask=False):
+... """Apply augmentations and format annotations in COCO format for object detection task"""
+
+... images = []
+... annotations = []
+... for image_id, image, objects in zip(examples["image_id"], examples["image"], examples["objects"]):
+... image = np.array(image.convert("RGB"))
+
+... # apply augmentations
+... output = transform(image=image, bboxes=objects["bbox"], category=objects["category"])
+... images.append(output["image"])
+
+... # format annotations in COCO format
+... formatted_annotations = format_image_annotations_as_coco(
+... image_id, output["category"], objects["area"], output["bboxes"]
+... )
+... annotations.append(formatted_annotations)
+
+... # Apply the image processor transformations: resizing, rescaling, normalization
+... result = image_processor(images=images, annotations=annotations, return_tensors="pt")
+
+... if not return_pixel_mask:
+... result.pop("pixel_mask", None)
+
+... return result
+```
+
+Apply this preprocessing function to the entire dataset using 🤗 Datasets [`~datasets.Dataset.with_transform`] method. This method applies
+transformations on the fly when you load an element of the dataset.
+
+At this point, you can check what an example from the dataset looks like after the transformations. You should see a tensor
+with `pixel_values`, a tensor with `pixel_mask`, and `labels`.
+
+```py
+>>> from functools import partial
+
+>>> # Make transform functions for batch and apply for dataset splits
+>>> train_transform_batch = partial(
+... augment_and_transform_batch, transform=train_augment_and_transform, image_processor=image_processor
+... )
+>>> validation_transform_batch = partial(
+... augment_and_transform_batch, transform=validation_transform, image_processor=image_processor
+... )
+
+>>> cppe5["train"] = cppe5["train"].with_transform(train_transform_batch)
+>>> cppe5["validation"] = cppe5["validation"].with_transform(validation_transform_batch)
+>>> cppe5["test"] = cppe5["test"].with_transform(validation_transform_batch)
+
+>>> cppe5["train"][15]
+{'pixel_values': tensor([[[ 1.9235, 1.9407, 1.9749, ..., -0.7822, -0.7479, -0.6965],
+ [ 1.9578, 1.9749, 1.9920, ..., -0.7993, -0.7650, -0.7308],
+ [ 2.0092, 2.0092, 2.0263, ..., -0.8507, -0.8164, -0.7822],
+ ...,
+ [ 0.0741, 0.0741, 0.0741, ..., 0.0741, 0.0741, 0.0741],
+ [ 0.0741, 0.0741, 0.0741, ..., 0.0741, 0.0741, 0.0741],
+ [ 0.0741, 0.0741, 0.0741, ..., 0.0741, 0.0741, 0.0741]],
+
+ [[ 1.6232, 1.6408, 1.6583, ..., 0.8704, 1.0105, 1.1331],
+ [ 1.6408, 1.6583, 1.6758, ..., 0.8529, 0.9930, 1.0980],
+ [ 1.6933, 1.6933, 1.7108, ..., 0.8179, 0.9580, 1.0630],
+ ...,
+ [ 0.2052, 0.2052, 0.2052, ..., 0.2052, 0.2052, 0.2052],
+ [ 0.2052, 0.2052, 0.2052, ..., 0.2052, 0.2052, 0.2052],
+ [ 0.2052, 0.2052, 0.2052, ..., 0.2052, 0.2052, 0.2052]],
+
+ [[ 1.8905, 1.9080, 1.9428, ..., -0.1487, -0.0964, -0.0615],
+ [ 1.9254, 1.9428, 1.9603, ..., -0.1661, -0.1138, -0.0790],
+ [ 1.9777, 1.9777, 1.9951, ..., -0.2010, -0.1138, -0.0790],
+ ...,
+ [ 0.4265, 0.4265, 0.4265, ..., 0.4265, 0.4265, 0.4265],
+ [ 0.4265, 0.4265, 0.4265, ..., 0.4265, 0.4265, 0.4265],
+ [ 0.4265, 0.4265, 0.4265, ..., 0.4265, 0.4265, 0.4265]]]),
+ 'labels': {'image_id': tensor([688]), 'class_labels': tensor([3, 4, 2, 0, 0]), 'boxes': tensor([[0.4700, 0.1933, 0.1467, 0.0767],
+ [0.4858, 0.2600, 0.1150, 0.1000],
+ [0.4042, 0.4517, 0.1217, 0.1300],
+ [0.4242, 0.3217, 0.3617, 0.5567],
+ [0.6617, 0.4033, 0.5400, 0.4533]]), 'area': tensor([ 4048., 4140., 5694., 72478., 88128.]), 'iscrowd': tensor([0, 0, 0, 0, 0]), 'orig_size': tensor([480, 480])}}
+```
+
+You have successfully augmented the individual images and prepared their annotations. However, preprocessing isn't
+complete yet. In the final step, create a custom `collate_fn` to batch images together.
+Pad images (which are now `pixel_values`) to the largest image in a batch, and create a corresponding `pixel_mask`
+to indicate which pixels are real (1) and which are padding (0).
+
+```py
+>>> import torch
+
+>>> def collate_fn(batch):
+... data = {}
+... data["pixel_values"] = torch.stack([x["pixel_values"] for x in batch])
+... data["labels"] = [x["labels"] for x in batch]
+... if "pixel_mask" in batch[0]:
+... data["pixel_mask"] = torch.stack([x["pixel_mask"] for x in batch])
+... return data
+
+```
+
+## Preparing function to compute mAP
+
+Object detection models are commonly evaluated with a set of COCO-style metrics. We are going to use `torchmetrics` to compute `mAP` (mean average precision) and `mAR` (mean average recall) metrics and will wrap it to `compute_metrics` function in order to use in [`Trainer`] for evaluation.
+
+Intermediate format of boxes used for training is `YOLO` (normalized) but we will compute metrics for boxes in `Pascal VOC` (absolute) format in order to correctly handle box areas. Let's define a function that converts bounding boxes to `Pascal VOC` format:
+
+```py
+>>> from transformers.image_transforms import center_to_corners_format
+
+>>> def convert_bbox_yolo_to_pascal(boxes, image_size):
+... """
+... Convert bounding boxes from YOLO format (x_center, y_center, width, height) in range [0, 1]
+... to Pascal VOC format (x_min, y_min, x_max, y_max) in absolute coordinates.
+
+... Args:
+... boxes (torch.Tensor): Bounding boxes in YOLO format
+... image_size (tuple[int, int]): Image size in format (height, width)
+
+... Returns:
+... torch.Tensor: Bounding boxes in Pascal VOC format (x_min, y_min, x_max, y_max)
+... """
+... # convert center to corners format
+... boxes = center_to_corners_format(boxes)
+
+... # convert to absolute coordinates
+... height, width = image_size
+... boxes = boxes * torch.tensor([[width, height, width, height]])
+
+... return boxes
+```
+
+Then, in `compute_metrics` function we collect `predicted` and `target` bounding boxes, scores and labels from evaluation loop results and pass it to the scoring function.
+
+```py
+>>> import numpy as np
+>>> from dataclasses import dataclass
+>>> from torchmetrics.detection.mean_ap import MeanAveragePrecision
+
+
+>>> @dataclass
+>>> class ModelOutput:
+... logits: torch.Tensor
+... pred_boxes: torch.Tensor
+
+
+>>> @torch.no_grad()
+>>> def compute_metrics(evaluation_results, image_processor, threshold=0.0, id2label=None):
+... """
+... Compute mean average mAP, mAR and their variants for the object detection task.
+
+... Args:
+... evaluation_results (EvalPrediction): Predictions and targets from evaluation.
+... threshold (float, optional): Threshold to filter predicted boxes by confidence. Defaults to 0.0.
+... id2label (Optional[dict], optional): Mapping from class id to class name. Defaults to None.
+
+... Returns:
+... Mapping[str, float]: Metrics in a form of dictionary {: }
+... """
+
+... predictions, targets = evaluation_results.predictions, evaluation_results.label_ids
+
+... # For metric computation we need to provide:
+... # - targets in a form of list of dictionaries with keys "boxes", "labels"
+... # - predictions in a form of list of dictionaries with keys "boxes", "scores", "labels"
+
+... image_sizes = []
+... post_processed_targets = []
+... post_processed_predictions = []
+
+... # Collect targets in the required format for metric computation
+... for batch in targets:
+... # collect image sizes, we will need them for predictions post processing
+... batch_image_sizes = torch.tensor(np.array([x["orig_size"] for x in batch]))
+... image_sizes.append(batch_image_sizes)
+... # collect targets in the required format for metric computation
+... # boxes were converted to YOLO format needed for model training
+... # here we will convert them to Pascal VOC format (x_min, y_min, x_max, y_max)
+... for image_target in batch:
+... boxes = torch.tensor(image_target["boxes"])
+... boxes = convert_bbox_yolo_to_pascal(boxes, image_target["orig_size"])
+... labels = torch.tensor(image_target["class_labels"])
+... post_processed_targets.append({"boxes": boxes, "labels": labels})
+
+... # Collect predictions in the required format for metric computation,
+... # model produce boxes in YOLO format, then image_processor convert them to Pascal VOC format
+... for batch, target_sizes in zip(predictions, image_sizes):
+... batch_logits, batch_boxes = batch[1], batch[2]
+... output = ModelOutput(logits=torch.tensor(batch_logits), pred_boxes=torch.tensor(batch_boxes))
+... post_processed_output = image_processor.post_process_object_detection(
+... output, threshold=threshold, target_sizes=target_sizes
+... )
+... post_processed_predictions.extend(post_processed_output)
+
+... # Compute metrics
+... metric = MeanAveragePrecision(box_format="xyxy", class_metrics=True)
+... metric.update(post_processed_predictions, post_processed_targets)
+... metrics = metric.compute()
+
+... # Replace list of per class metrics with separate metric for each class
+... classes = metrics.pop("classes")
+... map_per_class = metrics.pop("map_per_class")
+... mar_100_per_class = metrics.pop("mar_100_per_class")
+... for class_id, class_map, class_mar in zip(classes, map_per_class, mar_100_per_class):
+... class_name = id2label[class_id.item()] if id2label is not None else class_id.item()
+... metrics[f"map_{class_name}"] = class_map
+... metrics[f"mar_100_{class_name}"] = class_mar
+
+... metrics = {k: round(v.item(), 4) for k, v in metrics.items()}
+
+... return metrics
+
+
+>>> eval_compute_metrics_fn = partial(
+... compute_metrics, image_processor=image_processor, id2label=id2label, threshold=0.0
+... )
+```
+
+## Training the detection model
+
+You have done most of the heavy lifting in the previous sections, so now you are ready to train your model!
+The images in this dataset are still quite large, even after resizing. This means that finetuning this model will
+require at least one GPU.
+
+Training involves the following steps:
+1. Load the model with [`AutoModelForObjectDetection`] using the same checkpoint as in the preprocessing.
+2. Define your training hyperparameters in [`TrainingArguments`].
+3. Pass the training arguments to [`Trainer`] along with the model, dataset, image processor, and data collator.
+4. Call [`~Trainer.train`] to finetune your model.
+
+When loading the model from the same checkpoint that you used for the preprocessing, remember to pass the `label2id`
+and `id2label` maps that you created earlier from the dataset's metadata. Additionally, we specify `ignore_mismatched_sizes=True` to replace the existing classification head with a new one.
+
+```py
+>>> from transformers import AutoModelForObjectDetection
+
+>>> model = AutoModelForObjectDetection.from_pretrained(
+... MODEL_NAME,
+... id2label=id2label,
+... label2id=label2id,
+... ignore_mismatched_sizes=True,
+... )
+```
+
+In the [`TrainingArguments`] use `output_dir` to specify where to save your model, then configure hyperparameters as you see fit. For `num_train_epochs=30` training will take about 35 minutes in Google Colab T4 GPU, increase the number of epoch to get better results.
+
+Important notes:
+ - Do not remove unused columns because this will drop the image column. Without the image column, you
+can't create `pixel_values`. For this reason, set `remove_unused_columns` to `False`.
+ - Set `eval_do_concat_batches=False` to get proper evaluation results. Images have different number of target boxes, if batches are concatenated we will not be able to determine which boxes belongs to particular image.
+
+If you wish to share your model by pushing to the Hub, set `push_to_hub` to `True` (you must be signed in to Hugging
+Face to upload your model).
+
+```py
+>>> from transformers import TrainingArguments
+
+>>> training_args = TrainingArguments(
+... output_dir="detr_finetuned_cppe5",
+... num_train_epochs=30,
+... fp16=False,
+... per_device_train_batch_size=8,
+... dataloader_num_workers=4,
+... learning_rate=5e-5,
+... lr_scheduler_type="cosine",
+... weight_decay=1e-4,
+... max_grad_norm=0.01,
+... metric_for_best_model="eval_map",
+... greater_is_better=True,
+... load_best_model_at_end=True,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... save_total_limit=2,
+... remove_unused_columns=False,
+... eval_do_concat_batches=False,
+... push_to_hub=True,
+... )
+```
+
+Finally, bring everything together, and call [`~transformers.Trainer.train`]:
+
+```py
+>>> from transformers import Trainer
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=cppe5["train"],
+... eval_dataset=cppe5["validation"],
+... processing_class=image_processor,
+... data_collator=collate_fn,
+... compute_metrics=eval_compute_metrics_fn,
+... )
+
+>>> trainer.train()
+```
+
+
+
+ [3210/3210 26:07, Epoch 30/30]
+
+
+
+
+
+
Epoch
+
Training Loss
+
Validation Loss
+
Map
+
Map 50
+
Map 75
+
Map Small
+
Map Medium
+
Map Large
+
Mar 1
+
Mar 10
+
Mar 100
+
Mar Small
+
Mar Medium
+
Mar Large
+
Map Coverall
+
Mar 100 Coverall
+
Map Face Shield
+
Mar 100 Face Shield
+
Map Gloves
+
Mar 100 Gloves
+
Map Goggles
+
Mar 100 Goggles
+
Map Mask
+
Mar 100 Mask
+
+
+
+
+
1
+
No log
+
2.629903
+
0.008900
+
0.023200
+
0.006500
+
0.001300
+
0.002800
+
0.020500
+
0.021500
+
0.070400
+
0.101400
+
0.007600
+
0.106200
+
0.096100
+
0.036700
+
0.232000
+
0.000300
+
0.019000
+
0.003900
+
0.125400
+
0.000100
+
0.003100
+
0.003500
+
0.127600
+
+
+
2
+
No log
+
3.479864
+
0.014800
+
0.034600
+
0.010800
+
0.008600
+
0.011700
+
0.012500
+
0.041100
+
0.098700
+
0.130000
+
0.056000
+
0.062200
+
0.111900
+
0.053500
+
0.447300
+
0.010600
+
0.100000
+
0.000200
+
0.022800
+
0.000100
+
0.015400
+
0.009700
+
0.064400
+
+
+
3
+
No log
+
2.107622
+
0.041700
+
0.094000
+
0.034300
+
0.024100
+
0.026400
+
0.047400
+
0.091500
+
0.182800
+
0.225800
+
0.087200
+
0.199400
+
0.210600
+
0.150900
+
0.571200
+
0.017300
+
0.101300
+
0.007300
+
0.180400
+
0.002100
+
0.026200
+
0.031000
+
0.250200
+
+
+
4
+
No log
+
2.031242
+
0.055900
+
0.120600
+
0.046900
+
0.013800
+
0.038100
+
0.090300
+
0.105900
+
0.225600
+
0.266100
+
0.130200
+
0.228100
+
0.330000
+
0.191000
+
0.572100
+
0.010600
+
0.157000
+
0.014600
+
0.235300
+
0.001700
+
0.052300
+
0.061800
+
0.313800
+
+
+
5
+
3.889400
+
1.883433
+
0.089700
+
0.201800
+
0.067300
+
0.022800
+
0.065300
+
0.129500
+
0.136000
+
0.272200
+
0.303700
+
0.112900
+
0.312500
+
0.424600
+
0.300200
+
0.585100
+
0.032700
+
0.202500
+
0.031300
+
0.271000
+
0.008700
+
0.126200
+
0.075500
+
0.333800
+
+
+
6
+
3.889400
+
1.807503
+
0.118500
+
0.270900
+
0.090200
+
0.034900
+
0.076700
+
0.152500
+
0.146100
+
0.297800
+
0.325400
+
0.171700
+
0.283700
+
0.545900
+
0.396900
+
0.554500
+
0.043000
+
0.262000
+
0.054500
+
0.271900
+
0.020300
+
0.230800
+
0.077600
+
0.308000
+
+
+
7
+
3.889400
+
1.716169
+
0.143500
+
0.307700
+
0.123200
+
0.045800
+
0.097800
+
0.258300
+
0.165300
+
0.327700
+
0.352600
+
0.140900
+
0.336700
+
0.599400
+
0.442900
+
0.620700
+
0.069400
+
0.301300
+
0.081600
+
0.292000
+
0.011000
+
0.230800
+
0.112700
+
0.318200
+
+
+
8
+
3.889400
+
1.679014
+
0.153000
+
0.355800
+
0.127900
+
0.038700
+
0.115600
+
0.291600
+
0.176000
+
0.322500
+
0.349700
+
0.135600
+
0.326100
+
0.643700
+
0.431700
+
0.582900
+
0.069800
+
0.265800
+
0.088600
+
0.274600
+
0.028300
+
0.280000
+
0.146700
+
0.345300
+
+
+
9
+
3.889400
+
1.618239
+
0.172100
+
0.375300
+
0.137600
+
0.046100
+
0.141700
+
0.308500
+
0.194000
+
0.356200
+
0.386200
+
0.162400
+
0.359200
+
0.677700
+
0.469800
+
0.623900
+
0.102100
+
0.317700
+
0.099100
+
0.290200
+
0.029300
+
0.335400
+
0.160200
+
0.364000
+
+
+
10
+
1.599700
+
1.572512
+
0.179500
+
0.400400
+
0.147200
+
0.056500
+
0.141700
+
0.316700
+
0.213100
+
0.357600
+
0.381300
+
0.197900
+
0.344300
+
0.638500
+
0.466900
+
0.623900
+
0.101300
+
0.311400
+
0.104700
+
0.279500
+
0.051600
+
0.338500
+
0.173000
+
0.353300
+
+
+
11
+
1.599700
+
1.528889
+
0.192200
+
0.415000
+
0.160800
+
0.053700
+
0.150500
+
0.378000
+
0.211500
+
0.371700
+
0.397800
+
0.204900
+
0.374600
+
0.684800
+
0.491900
+
0.632400
+
0.131200
+
0.346800
+
0.122000
+
0.300900
+
0.038400
+
0.344600
+
0.177500
+
0.364400
+
+
+
12
+
1.599700
+
1.517532
+
0.198300
+
0.429800
+
0.159800
+
0.066400
+
0.162900
+
0.383300
+
0.220700
+
0.382100
+
0.405400
+
0.214800
+
0.383200
+
0.672900
+
0.469000
+
0.610400
+
0.167800
+
0.379700
+
0.119700
+
0.307100
+
0.038100
+
0.335400
+
0.196800
+
0.394200
+
+
+
13
+
1.599700
+
1.488849
+
0.209800
+
0.452300
+
0.172300
+
0.094900
+
0.171100
+
0.437800
+
0.222000
+
0.379800
+
0.411500
+
0.203800
+
0.397300
+
0.707500
+
0.470700
+
0.620700
+
0.186900
+
0.407600
+
0.124200
+
0.306700
+
0.059300
+
0.355400
+
0.207700
+
0.367100
+
+
+
14
+
1.599700
+
1.482210
+
0.228900
+
0.482600
+
0.187800
+
0.083600
+
0.191800
+
0.444100
+
0.225900
+
0.376900
+
0.407400
+
0.182500
+
0.384800
+
0.700600
+
0.512100
+
0.640100
+
0.175000
+
0.363300
+
0.144300
+
0.300000
+
0.083100
+
0.363100
+
0.229900
+
0.370700
+
+
+
15
+
1.326800
+
1.475198
+
0.216300
+
0.455600
+
0.174900
+
0.088500
+
0.183500
+
0.424400
+
0.226900
+
0.373400
+
0.404300
+
0.199200
+
0.396400
+
0.677800
+
0.496300
+
0.633800
+
0.166300
+
0.392400
+
0.128900
+
0.312900
+
0.085200
+
0.312300
+
0.205000
+
0.370200
+
+
+
16
+
1.326800
+
1.459697
+
0.233200
+
0.504200
+
0.192200
+
0.096000
+
0.202000
+
0.430800
+
0.239100
+
0.382400
+
0.412600
+
0.219500
+
0.403100
+
0.670400
+
0.485200
+
0.625200
+
0.196500
+
0.410100
+
0.135700
+
0.299600
+
0.123100
+
0.356900
+
0.225300
+
0.371100
+
+
+
17
+
1.326800
+
1.407340
+
0.243400
+
0.511900
+
0.204500
+
0.121000
+
0.215700
+
0.468000
+
0.246200
+
0.394600
+
0.424200
+
0.225900
+
0.416100
+
0.705200
+
0.494900
+
0.638300
+
0.224900
+
0.430400
+
0.157200
+
0.317900
+
0.115700
+
0.369200
+
0.224200
+
0.365300
+
+
+
18
+
1.326800
+
1.419522
+
0.245100
+
0.521500
+
0.210000
+
0.116100
+
0.211500
+
0.489900
+
0.255400
+
0.391600
+
0.419700
+
0.198800
+
0.421200
+
0.701400
+
0.501800
+
0.634200
+
0.226700
+
0.410100
+
0.154400
+
0.321400
+
0.105900
+
0.352300
+
0.236700
+
0.380400
+
+
+
19
+
1.158600
+
1.398764
+
0.253600
+
0.519200
+
0.213600
+
0.135200
+
0.207700
+
0.491900
+
0.257300
+
0.397300
+
0.428000
+
0.241400
+
0.401800
+
0.703500
+
0.509700
+
0.631100
+
0.236700
+
0.441800
+
0.155900
+
0.330800
+
0.128100
+
0.352300
+
0.237500
+
0.384000
+
+
+
20
+
1.158600
+
1.390591
+
0.248800
+
0.520200
+
0.216600
+
0.127500
+
0.211400
+
0.471900
+
0.258300
+
0.407000
+
0.429100
+
0.240300
+
0.407600
+
0.708500
+
0.505800
+
0.623400
+
0.235500
+
0.431600
+
0.150000
+
0.325000
+
0.125700
+
0.375400
+
0.227200
+
0.390200
+
+
+
21
+
1.158600
+
1.360608
+
0.262700
+
0.544800
+
0.222100
+
0.134700
+
0.230000
+
0.487500
+
0.269500
+
0.413300
+
0.436300
+
0.236200
+
0.419100
+
0.709300
+
0.514100
+
0.637400
+
0.257200
+
0.450600
+
0.165100
+
0.338400
+
0.139400
+
0.372300
+
0.237700
+
0.382700
+
+
+
22
+
1.158600
+
1.368296
+
0.262800
+
0.542400
+
0.236400
+
0.137400
+
0.228100
+
0.498500
+
0.266500
+
0.409000
+
0.433000
+
0.239900
+
0.418500
+
0.697500
+
0.520500
+
0.641000
+
0.257500
+
0.455700
+
0.162600
+
0.334800
+
0.140200
+
0.353800
+
0.233200
+
0.379600
+
+
+
23
+
1.158600
+
1.368176
+
0.264800
+
0.541100
+
0.233100
+
0.138200
+
0.223900
+
0.498700
+
0.272300
+
0.407400
+
0.434400
+
0.233100
+
0.418300
+
0.702000
+
0.524400
+
0.642300
+
0.262300
+
0.444300
+
0.159700
+
0.335300
+
0.140500
+
0.366200
+
0.236900
+
0.384000
+
+
+
24
+
1.049700
+
1.355271
+
0.269700
+
0.549200
+
0.239100
+
0.134700
+
0.229900
+
0.519200
+
0.274800
+
0.412700
+
0.437600
+
0.245400
+
0.417200
+
0.711200
+
0.523200
+
0.644100
+
0.272100
+
0.440500
+
0.166700
+
0.341500
+
0.137700
+
0.373800
+
0.249000
+
0.388000
+
+
+
25
+
1.049700
+
1.355180
+
0.272500
+
0.547900
+
0.243800
+
0.149700
+
0.229900
+
0.523100
+
0.272500
+
0.415700
+
0.442200
+
0.256200
+
0.420200
+
0.705800
+
0.523900
+
0.639600
+
0.271700
+
0.451900
+
0.166300
+
0.346900
+
0.153700
+
0.383100
+
0.247000
+
0.389300
+
+
+
26
+
1.049700
+
1.349337
+
0.275600
+
0.556300
+
0.246400
+
0.146700
+
0.234800
+
0.516300
+
0.274200
+
0.418300
+
0.440900
+
0.248700
+
0.418900
+
0.705800
+
0.523200
+
0.636500
+
0.274700
+
0.440500
+
0.172400
+
0.349100
+
0.155600
+
0.384600
+
0.252300
+
0.393800
+
+
+
27
+
1.049700
+
1.350782
+
0.275200
+
0.548700
+
0.246800
+
0.147300
+
0.236400
+
0.527200
+
0.280100
+
0.416200
+
0.442600
+
0.253400
+
0.424000
+
0.710300
+
0.526600
+
0.640100
+
0.273200
+
0.445600
+
0.167000
+
0.346900
+
0.160100
+
0.387700
+
0.249200
+
0.392900
+
+
+
28
+
1.049700
+
1.346533
+
0.277000
+
0.552800
+
0.252900
+
0.147400
+
0.240000
+
0.527600
+
0.280900
+
0.420900
+
0.444100
+
0.255500
+
0.424500
+
0.711200
+
0.530200
+
0.646800
+
0.277400
+
0.441800
+
0.170900
+
0.346900
+
0.156600
+
0.389200
+
0.249600
+
0.396000
+
+
+
29
+
0.993700
+
1.346575
+
0.277100
+
0.554800
+
0.252900
+
0.148400
+
0.239700
+
0.523600
+
0.278400
+
0.420000
+
0.443300
+
0.256300
+
0.424000
+
0.705600
+
0.529600
+
0.647300
+
0.273900
+
0.439200
+
0.174300
+
0.348700
+
0.157600
+
0.386200
+
0.250100
+
0.395100
+
+
+
30
+
0.993700
+
1.346446
+
0.277400
+
0.554700
+
0.252700
+
0.147900
+
0.240800
+
0.523600
+
0.278800
+
0.420400
+
0.443300
+
0.256100
+
0.424200
+
0.705500
+
0.530100
+
0.646800
+
0.275600
+
0.440500
+
0.174500
+
0.348700
+
0.157300
+
0.386200
+
0.249200
+
0.394200
+
+
+
+
+If you have set `push_to_hub` to `True` in the `training_args`, the training checkpoints are pushed to the
+Hugging Face Hub. Upon training completion, push the final model to the Hub as well by calling the [`~transformers.Trainer.push_to_hub`] method.
+
+```py
+>>> trainer.push_to_hub()
+```
+
+## Evaluate
+
+```py
+>>> from pprint import pprint
+
+>>> metrics = trainer.evaluate(eval_dataset=cppe5["test"], metric_key_prefix="test")
+>>> pprint(metrics)
+{'epoch': 30.0,
+ 'test_loss': 1.0877351760864258,
+ 'test_map': 0.4116,
+ 'test_map_50': 0.741,
+ 'test_map_75': 0.3663,
+ 'test_map_Coverall': 0.5937,
+ 'test_map_Face_Shield': 0.5863,
+ 'test_map_Gloves': 0.3416,
+ 'test_map_Goggles': 0.1468,
+ 'test_map_Mask': 0.3894,
+ 'test_map_large': 0.5637,
+ 'test_map_medium': 0.3257,
+ 'test_map_small': 0.3589,
+ 'test_mar_1': 0.323,
+ 'test_mar_10': 0.5237,
+ 'test_mar_100': 0.5587,
+ 'test_mar_100_Coverall': 0.6756,
+ 'test_mar_100_Face_Shield': 0.7294,
+ 'test_mar_100_Gloves': 0.4721,
+ 'test_mar_100_Goggles': 0.4125,
+ 'test_mar_100_Mask': 0.5038,
+ 'test_mar_large': 0.7283,
+ 'test_mar_medium': 0.4901,
+ 'test_mar_small': 0.4469,
+ 'test_runtime': 1.6526,
+ 'test_samples_per_second': 17.548,
+ 'test_steps_per_second': 2.42}
+```
+
+These results can be further improved by adjusting the hyperparameters in [`TrainingArguments`]. Give it a go!
+
+## Inference
+
+Now that you have finetuned a model, evaluated it, and uploaded it to the Hugging Face Hub, you can use it for inference.
+
+```py
+>>> import torch
+>>> import requests
+
+>>> from PIL import Image, ImageDraw
+>>> from transformers import AutoImageProcessor, AutoModelForObjectDetection
+
+>>> url = "https://images.pexels.com/photos/8413299/pexels-photo-8413299.jpeg?auto=compress&cs=tinysrgb&w=630&h=375&dpr=2"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+```
+
+Load model and image processor from the Hugging Face Hub (skip to use already trained in this session):
+```py
+>>> from transformers import infer_device
+
+>>> device = infer_device()
+>>> model_repo = "qubvel-hf/detr_finetuned_cppe5"
+
+>>> image_processor = AutoImageProcessor.from_pretrained(model_repo)
+>>> model = AutoModelForObjectDetection.from_pretrained(model_repo)
+>>> model = model.to(device)
+```
+
+And detect bounding boxes:
+
+```py
+
+>>> with torch.no_grad():
+... inputs = image_processor(images=[image], return_tensors="pt")
+... outputs = model(**inputs.to(device))
+... target_sizes = torch.tensor([[image.size[1], image.size[0]]])
+... results = image_processor.post_process_object_detection(outputs, threshold=0.3, target_sizes=target_sizes)[0]
+
+>>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
+... box = [round(i, 2) for i in box.tolist()]
+... print(
+... f"Detected {model.config.id2label[label.item()]} with confidence "
+... f"{round(score.item(), 3)} at location {box}"
+... )
+Detected Gloves with confidence 0.683 at location [244.58, 124.33, 300.35, 185.13]
+Detected Mask with confidence 0.517 at location [143.73, 64.58, 219.57, 125.89]
+Detected Gloves with confidence 0.425 at location [179.15, 155.57, 262.4, 226.35]
+Detected Coverall with confidence 0.407 at location [307.13, -1.18, 477.82, 318.06]
+Detected Coverall with confidence 0.391 at location [68.61, 126.66, 309.03, 318.89]
+```
+
+Let's plot the result:
+
+```py
+>>> draw = ImageDraw.Draw(image)
+
+>>> for score, label, box in zip(results["scores"], results["labels"], results["boxes"]):
+... box = [round(i, 2) for i in box.tolist()]
+... x, y, x2, y2 = tuple(box)
+... draw.rectangle((x, y, x2, y2), outline="red", width=1)
+... draw.text((x, y), model.config.id2label[label.item()], fill="white")
+
+>>> image
+```
+
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/prompting.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/prompting.md
new file mode 100644
index 0000000000000000000000000000000000000000..635b1fefa4189d8db19e2c53d1f73f8fdd66853e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/prompting.md
@@ -0,0 +1,267 @@
+
+
+# Prompt engineering
+
+[[open-in-colab]]
+
+Prompt engineering or prompting, uses natural language to improve large language model (LLM) performance on a variety of tasks. A prompt can steer the model towards generating a desired output. In many cases, you don't even need a [fine-tuned](#finetuning) model for a task. You just need a good prompt.
+
+Try prompting a LLM to classify some text. When you create a prompt, it's important to provide very specific instructions about the task and what the result should look like.
+
+```py
+from transformers import pipeline
+import torch
+
+pipeline = pipeline(task="text-generation", model="mistralai/Mistal-7B-Instruct-v0.1", torch_dtype=torch.bfloat16, device_map="auto")
+prompt = """Classify the text into neutral, negative or positive.
+Text: This movie is definitely one of my favorite movies of its kind. The interaction between respectable and morally strong characters is an ode to chivalry and the honor code amongst thieves and policemen.
+Sentiment:
+"""
+
+outputs = pipeline(prompt, max_new_tokens=10)
+for output in outputs:
+ print(f"Result: {output['generated_text']}")
+Result: Classify the text into neutral, negative or positive.
+Text: This movie is definitely one of my favorite movies of its kind. The interaction between respectable and morally strong characters is an ode to chivalry and the honor code amongst thieves and policemen.
+Sentiment:
+Positive
+```
+
+The challenge lies in designing prompts that produces the results you're expecting because language is so incredibly nuanced and expressive.
+
+This guide covers prompt engineering best practices, techniques, and examples for how to solve language and reasoning tasks.
+
+## Best practices
+
+1. Try to pick the latest models for the best performance. Keep in mind that LLMs can come in two variants, [base](https://hf.co/mistralai/Mistral-7B-v0.1) and [instruction-tuned](https://hf.co/mistralai/Mistral-7B-Instruct-v0.1) (or chat).
+
+ Base models are excellent at completing text given an initial prompt, but they're not as good at following instructions. Instruction-tuned models are specifically trained versions of the base models on instructional or conversational data. This makes instruction-tuned models a better fit for prompting.
+
+ > [!WARNING]
+ > Modern LLMs are typically decoder-only models, but there are some encoder-decoder LLMs like [Flan-T5](../model_doc/flan-t5) or [BART](../model_doc/bart) that may be used for prompting. For encoder-decoder models, make sure you set the pipeline task identifier to `text2text-generation` instead of `text-generation`.
+
+2. Start with a short and simple prompt, and iterate on it to get better results.
+
+3. Put instructions at the beginning or end of a prompt. For longer prompts, models may apply optimizations to prevent attention from scaling quadratically, which places more emphasis at the beginning and end of a prompt.
+
+4. Clearly separate instructions from the text of interest.
+
+5. Be specific and descriptive about the task and the desired output, including for example, its format, length, style, and language. Avoid ambiguous descriptions and instructions.
+
+6. Instructions should focus on "what to do" rather than "what not to do".
+
+7. Lead the model to generate the correct output by writing the first word or even the first sentence.
+
+8. Try other techniques like [few-shot](#few-shot) and [chain-of-thought](#chain-of-thought) to improve results.
+
+9. Test your prompts with different models to assess their robustness.
+
+10. Version and track your prompt performance.
+
+## Techniques
+
+Crafting a good prompt alone, also known as zero-shot prompting, may not be enough to get the results you want. You may need to try a few prompting techniques to get the best performance.
+
+This section covers a few prompting techniques.
+
+### Few-shot prompting
+
+Few-shot prompting improves accuracy and performance by including specific examples of what a model should generate given an input. The explicit examples give the model a better understanding of the task and the output format you’re looking for. Try experimenting with different numbers of examples (2, 4, 8, etc.) to see how it affects performance. The example below provides the model with 1 example (1-shot) of the output format (a date in MM/DD/YYYY format) it should return.
+
+```python
+from transformers import pipeline
+import torch
+
+pipeline = pipeline(model="mistralai/Mistral-7B-Instruct-v0.1", torch_dtype=torch.bfloat16, device_map="auto")
+prompt = """Text: The first human went into space and orbited the Earth on April 12, 1961.
+Date: 04/12/1961
+Text: The first-ever televised presidential debate in the United States took place on September 28, 1960, between presidential candidates John F. Kennedy and Richard Nixon.
+Date:"""
+
+outputs = pipeline(prompt, max_new_tokens=12, do_sample=True, top_k=10)
+for output in outputs:
+ print(f"Result: {output['generated_text']}")
+# Result: Text: The first human went into space and orbited the Earth on April 12, 1961.
+# Date: 04/12/1961
+# Text: The first-ever televised presidential debate in the United States took place on September 28, 1960, between presidential candidates John F. Kennedy and Richard Nixon.
+# Date: 09/28/1960
+```
+
+The downside of few-shot prompting is that you need to create lengthier prompts which increases computation and latency. There is also a limit to prompt lengths. Finally, a model can learn unintended patterns from your examples, and it may not work well on complex reasoning tasks.
+
+To improve few-shot prompting for modern instruction-tuned LLMs, use a model's specific [chat template](../conversations). These models are trained on datasets with turn-based conversations between a "user" and "assistant". Structuring your prompt to align with this can improve performance.
+
+Structure your prompt as a turn-based conversation and use the [`apply_chat_template`] method to tokenize and format it.
+
+```python
+from transformers import pipeline
+import torch
+
+pipeline = pipeline(model="mistralai/Mistral-7B-Instruct-v0.1", torch_dtype=torch.bfloat16, device_map="auto")
+
+messages = [
+ {"role": "user", "content": "Text: The first human went into space and orbited the Earth on April 12, 1961."},
+ {"role": "assistant", "content": "Date: 04/12/1961"},
+ {"role": "user", "content": "Text: The first-ever televised presidential debate in the United States took place on September 28, 1960, between presidential candidates John F. Kennedy and Richard Nixon."}
+]
+
+prompt = pipeline.tokenizer.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
+
+outputs = pipeline(prompt, max_new_tokens=12, do_sample=True, top_k=10)
+
+for output in outputs:
+ print(f"Result: {output['generated_text']}")
+```
+
+
+While the basic few-shot prompting approach embedded examples within a single text string, the chat template format offers the following benefits.
+
+- The model may have a potentially improved understanding because it can better recognize the pattern and the expected roles of user input and assistant output.
+- The model may more consistently output the desired output format because it is structured like its input during training.
+
+Always consult a specific instruction-tuned model's documentation to learn more about the format of their chat template so that you can structure your few-shot prompts accordingly.
+
+### Chain-of-thought
+
+Chain-of-thought (CoT) is effective at generating more coherent and well-reasoned outputs by providing a series of prompts that help a model "think" more thoroughly about a topic.
+
+The example below provides the model with several prompts to work through intermediate reasoning steps.
+
+```py
+from transformers import pipeline
+import torch
+
+pipeline = pipeline(model="mistralai/Mistral-7B-Instruct-v0.1", torch_dtype=torch.bfloat16, device_map="auto")
+prompt = """Let's go through this step-by-step:
+1. You start with 15 muffins.
+2. You eat 2 muffins, leaving you with 13 muffins.
+3. You give 5 muffins to your neighbor, leaving you with 8 muffins.
+4. Your partner buys 6 more muffins, bringing the total number of muffins to 14.
+5. Your partner eats 2 muffins, leaving you with 12 muffins.
+If you eat 6 muffins, how many are left?"""
+
+outputs = pipeline(prompt, max_new_tokens=20, do_sample=True, top_k=10)
+for output in outputs:
+ print(f"Result: {output['generated_text']}")
+Result: Let's go through this step-by-step:
+1. You start with 15 muffins.
+2. You eat 2 muffins, leaving you with 13 muffins.
+3. You give 5 muffins to your neighbor, leaving you with 8 muffins.
+4. Your partner buys 6 more muffins, bringing the total number of muffins to 14.
+5. Your partner eats 2 muffins, leaving you with 12 muffins.
+If you eat 6 muffins, how many are left?
+Answer: 6
+```
+
+Like [few-shot](#few-shot) prompting, the downside of CoT is that it requires more effort to design a series of prompts that help the model reason through a complex task and prompt length increases latency.
+
+## Fine-tuning
+
+While prompting is a powerful way to work with LLMs, there are scenarios where a fine-tuned model or even fine-tuning a model works better.
+
+Here are some examples scenarios where a fine-tuned model makes sense.
+
+- Your domain is extremely different from what a LLM was pretrained on, and extensive prompting didn't produce the results you want.
+- Your model needs to work well in a low-resource language.
+- Your model needs to be trained on sensitive data that have strict regulatory requirements.
+- You're using a small model due to cost, privacy, infrastructure, or other constraints.
+
+In all of these scenarios, ensure that you have a large enough domain-specific dataset to train your model with, have enough time and resources, and the cost of fine-tuning is worth it. Otherwise, you may be better off trying to optimize your prompt.
+
+## Examples
+
+The examples below demonstrate prompting a LLM for different tasks.
+
+
+
+
+```py
+from transformers import pipeline
+import torch
+
+pipeline = pipeline(model="mistralai/Mistral-7B-Instruct-v0.1", torch_dtype=torch.bfloat16, device_map="auto")
+prompt = """Return a list of named entities in the text.
+Text: The company was founded in 2016 by French entrepreneurs Clément Delangue, Julien Chaumond, and Thomas Wolf in New York City, originally as a company that developed a chatbot app targeted at teenagers.
+Named entities:
+"""
+
+outputs = pipeline(prompt, max_new_tokens=50, return_full_text=False)
+for output in outputs:
+ print(f"Result: {output['generated_text']}")
+Result: [Clément Delangue, Julien Chaumond, Thomas Wolf, company, New York City, chatbot app, teenagers]
+```
+
+
+
+
+```py
+from transformers import pipeline
+import torch
+
+pipeline = pipeline(model="mistralai/Mistral-7B-Instruct-v0.1", torch_dtype=torch.bfloat16, device_map="auto")
+prompt = """Translate the English text to French.
+Text: Sometimes, I've believed as many as six impossible things before breakfast.
+Translation:
+"""
+
+outputs = pipeline(prompt, max_new_tokens=20, do_sample=True, top_k=10, return_full_text=False)
+for output in outputs:
+ print(f"Result: {output['generated_text']}")
+Result: À l'occasion, j'ai croyu plus de six choses impossibles
+```
+
+
+
+
+```py
+from transformers import pipeline
+import torch
+
+pipeline = pipeline(model="mistralai/Mistral-7B-Instruct-v0.1", torch_dtype=torch.bfloat16, device_map="auto")
+prompt = """Permaculture is a design process mimicking the diversity, functionality and resilience of natural ecosystems. The principles and practices are drawn from traditional ecological knowledge of indigenous cultures combined with modern scientific understanding and technological innovations. Permaculture design provides a framework helping individuals and communities develop innovative, creative and effective strategies for meeting basic needs while preparing for and mitigating the projected impacts of climate change.
+Write a summary of the above text.
+Summary:
+"""
+
+outputs = pipeline(prompt, max_new_tokens=30, do_sample=True, top_k=10, return_full_text=False)
+for output in outputs:
+ print(f"Result: {output['generated_text']}")
+Result: Permaculture is the design process that involves mimicking natural ecosystems to provide sustainable solutions to basic needs. It is a holistic approach that comb
+```
+
+
+
+
+```py
+from transformers import pipeline
+import torch
+
+pipeline = pipeline(model="mistralai/Mistral-7B-Instruct-v0.1", torch_dtype=torch.bfloat16, device_map="auto")
+prompt = """Answer the question using the context below.
+Context: Gazpacho is a cold soup and drink made of raw, blended vegetables. Most gazpacho includes stale bread, tomato, cucumbers, onion, bell peppers, garlic, olive oil, wine vinegar, water, and salt. Northern recipes often include cumin and/or pimentón (smoked sweet paprika). Traditionally, gazpacho was made by pounding the vegetables in a mortar with a pestle; this more laborious method is still sometimes used as it helps keep the gazpacho cool and avoids the foam and silky consistency of smoothie versions made in blenders or food processors.
+Question: What modern tool is used to make gazpacho?
+Answer:
+"""
+
+outputs = pipeline(prompt, max_new_tokens=10, do_sample=True, top_k=10, return_full_text=False)
+for output in outputs:
+ print(f"Result: {output['generated_text']}")
+Result: A blender or food processor is the modern tool
+```
+
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/question_answering.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/question_answering.md
new file mode 100644
index 0000000000000000000000000000000000000000..41d7fd48cf816e099892c7bfa3037825721f97eb
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/question_answering.md
@@ -0,0 +1,427 @@
+
+
+# Question answering
+
+[[open-in-colab]]
+
+
+
+Question answering tasks return an answer given a question. If you've ever asked a virtual assistant like Alexa, Siri or Google what the weather is, then you've used a question answering model before. There are two common types of question answering tasks:
+
+- Extractive: extract the answer from the given context.
+- Abstractive: generate an answer from the context that correctly answers the question.
+
+This guide will show you how to:
+
+1. Finetune [DistilBERT](https://huggingface.co/distilbert/distilbert-base-uncased) on the [SQuAD](https://huggingface.co/datasets/squad) dataset for extractive question answering.
+2. Use your finetuned model for inference.
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/question-answering)
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate
+```
+
+We encourage you to login to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to login:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load SQuAD dataset
+
+Start by loading a smaller subset of the SQuAD dataset from the 🤗 Datasets library. This'll give you a chance to experiment and make sure everything works before spending more time training on the full dataset.
+
+```py
+>>> from datasets import load_dataset
+
+>>> squad = load_dataset("squad", split="train[:5000]")
+```
+
+Split the dataset's `train` split into a train and test set with the [`~datasets.Dataset.train_test_split`] method:
+
+```py
+>>> squad = squad.train_test_split(test_size=0.2)
+```
+
+Then take a look at an example:
+
+```py
+>>> squad["train"][0]
+{'answers': {'answer_start': [515], 'text': ['Saint Bernadette Soubirous']},
+ 'context': 'Architecturally, the school has a Catholic character. Atop the Main Building\'s gold dome is a golden statue of the Virgin Mary. Immediately in front of the Main Building and facing it, is a copper statue of Christ with arms upraised with the legend "Venite Ad Me Omnes". Next to the Main Building is the Basilica of the Sacred Heart. Immediately behind the basilica is the Grotto, a Marian place of prayer and reflection. It is a replica of the grotto at Lourdes, France where the Virgin Mary reputedly appeared to Saint Bernadette Soubirous in 1858. At the end of the main drive (and in a direct line that connects through 3 statues and the Gold Dome), is a simple, modern stone statue of Mary.',
+ 'id': '5733be284776f41900661182',
+ 'question': 'To whom did the Virgin Mary allegedly appear in 1858 in Lourdes France?',
+ 'title': 'University_of_Notre_Dame'
+}
+```
+
+There are several important fields here:
+
+- `answers`: the starting location of the answer token and the answer text.
+- `context`: background information from which the model needs to extract the answer.
+- `question`: the question a model should answer.
+
+## Preprocess
+
+
+
+The next step is to load a DistilBERT tokenizer to process the `question` and `context` fields:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+There are a few preprocessing steps particular to question answering tasks you should be aware of:
+
+1. Some examples in a dataset may have a very long `context` that exceeds the maximum input length of the model. To deal with longer sequences, truncate only the `context` by setting `truncation="only_second"`.
+2. Next, map the start and end positions of the answer to the original `context` by setting
+ `return_offset_mapping=True`.
+3. With the mapping in hand, now you can find the start and end tokens of the answer. Use the [`~tokenizers.Encoding.sequence_ids`] method to
+ find which part of the offset corresponds to the `question` and which corresponds to the `context`.
+
+Here is how you can create a function to truncate and map the start and end tokens of the `answer` to the `context`:
+
+```py
+>>> def preprocess_function(examples):
+... questions = [q.strip() for q in examples["question"]]
+... inputs = tokenizer(
+... questions,
+... examples["context"],
+... max_length=384,
+... truncation="only_second",
+... return_offsets_mapping=True,
+... padding="max_length",
+... )
+
+... offset_mapping = inputs.pop("offset_mapping")
+... answers = examples["answers"]
+... start_positions = []
+... end_positions = []
+
+... for i, offset in enumerate(offset_mapping):
+... answer = answers[i]
+... start_char = answer["answer_start"][0]
+... end_char = answer["answer_start"][0] + len(answer["text"][0])
+... sequence_ids = inputs.sequence_ids(i)
+
+... # Find the start and end of the context
+... idx = 0
+... while sequence_ids[idx] != 1:
+... idx += 1
+... context_start = idx
+... while sequence_ids[idx] == 1:
+... idx += 1
+... context_end = idx - 1
+
+... # If the answer is not fully inside the context, label it (0, 0)
+... if offset[context_start][0] > end_char or offset[context_end][1] < start_char:
+... start_positions.append(0)
+... end_positions.append(0)
+... else:
+... # Otherwise it's the start and end token positions
+... idx = context_start
+... while idx <= context_end and offset[idx][0] <= start_char:
+... idx += 1
+... start_positions.append(idx - 1)
+
+... idx = context_end
+... while idx >= context_start and offset[idx][1] >= end_char:
+... idx -= 1
+... end_positions.append(idx + 1)
+
+... inputs["start_positions"] = start_positions
+... inputs["end_positions"] = end_positions
+... return inputs
+```
+
+To apply the preprocessing function over the entire dataset, use 🤗 Datasets [`~datasets.Dataset.map`] function. You can speed up the `map` function by setting `batched=True` to process multiple elements of the dataset at once. Remove any columns you don't need:
+
+```py
+>>> tokenized_squad = squad.map(preprocess_function, batched=True, remove_columns=squad["train"].column_names)
+```
+
+Now create a batch of examples using [`DefaultDataCollator`]. Unlike other data collators in 🤗 Transformers, the [`DefaultDataCollator`] does not apply any additional preprocessing such as padding.
+
+
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator()
+```
+
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+```
+
+
+
+## Train
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#train-with-pytorch-trainer)!
+
+
+
+You're ready to start training your model now! Load DistilBERT with [`AutoModelForQuestionAnswering`]:
+
+```py
+>>> from transformers import AutoModelForQuestionAnswering, TrainingArguments, Trainer
+
+>>> model = AutoModelForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`TrainingArguments`]. The only required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model).
+2. Pass the training arguments to [`Trainer`] along with the model, dataset, tokenizer, and data collator.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_qa_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=3,
+... weight_decay=0.01,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_squad["train"],
+... eval_dataset=tokenized_squad["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+If you aren't familiar with finetuning a model with Keras, take a look at the basic tutorial [here](../training#train-a-tensorflow-model-with-keras)!
+
+
+To finetune a model in TensorFlow, start by setting up an optimizer function, learning rate schedule, and some training hyperparameters:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_epochs = 2
+>>> total_train_steps = (len(tokenized_squad["train"]) // batch_size) * num_epochs
+>>> optimizer, schedule = create_optimizer(
+... init_lr=2e-5,
+... num_warmup_steps=0,
+... num_train_steps=total_train_steps,
+... )
+```
+
+Then you can load DistilBERT with [`TFAutoModelForQuestionAnswering`]:
+
+```py
+>>> from transformers import TFAutoModelForQuestionAnswering
+
+>>> model = TFAutoModelForQuestionAnswering.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Convert your datasets to the `tf.data.Dataset` format with [`~transformers.TFPreTrainedModel.prepare_tf_dataset`]:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_squad["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_squad["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+Configure the model for training with [`compile`](https://keras.io/api/models/model_training_apis/#compile-method):
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer)
+```
+
+The last thing to setup before you start training is to provide a way to push your model to the Hub. This can be done by specifying where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> callback = PushToHubCallback(
+... output_dir="my_awesome_qa_model",
+... tokenizer=tokenizer,
+... )
+```
+
+Finally, you're ready to start training your model! Call [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) with your training and validation datasets, the number of epochs, and your callback to finetune the model:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3, callbacks=[callback])
+```
+Once training is completed, your model is automatically uploaded to the Hub so everyone can use it!
+
+
+
+
+
+For a more in-depth example of how to finetune a model for question answering, take a look at the corresponding
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering.ipynb)
+or [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/question_answering-tf.ipynb).
+
+
+
+## Evaluate
+
+Evaluation for question answering requires a significant amount of postprocessing. To avoid taking up too much of your time, this guide skips the evaluation step. The [`Trainer`] still calculates the evaluation loss during training so you're not completely in the dark about your model's performance.
+
+If you have more time and you're interested in how to evaluate your model for question answering, take a look at the [Question answering](https://huggingface.co/course/chapter7/7?fw=pt#post-processing) chapter from the 🤗 Hugging Face Course!
+
+## Inference
+
+Great, now that you've finetuned a model, you can use it for inference!
+
+Come up with a question and some context you'd like the model to predict:
+
+```py
+>>> question = "How many programming languages does BLOOM support?"
+>>> context = "BLOOM has 176 billion parameters and can generate text in 46 languages natural languages and 13 programming languages."
+```
+
+The simplest way to try out your finetuned model for inference is to use it in a [`pipeline`]. Instantiate a `pipeline` for question answering with your model, and pass your text to it:
+
+```py
+>>> from transformers import pipeline
+
+>>> question_answerer = pipeline("question-answering", model="my_awesome_qa_model")
+>>> question_answerer(question=question, context=context)
+{'score': 0.2058267742395401,
+ 'start': 10,
+ 'end': 95,
+ 'answer': '176 billion parameters and can generate text in 46 languages natural languages and 13'}
+```
+
+You can also manually replicate the results of the `pipeline` if you'd like:
+
+
+
+Tokenize the text and return PyTorch tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_qa_model")
+>>> inputs = tokenizer(question, context, return_tensors="pt")
+```
+
+Pass your inputs to the model and return the `logits`:
+
+```py
+>>> import torch
+>>> from transformers import AutoModelForQuestionAnswering
+
+>>> model = AutoModelForQuestionAnswering.from_pretrained("my_awesome_qa_model")
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+```
+
+Get the highest probability from the model output for the start and end positions:
+
+```py
+>>> answer_start_index = outputs.start_logits.argmax()
+>>> answer_end_index = outputs.end_logits.argmax()
+```
+
+Decode the predicted tokens to get the answer:
+
+```py
+>>> predict_answer_tokens = inputs.input_ids[0, answer_start_index : answer_end_index + 1]
+>>> tokenizer.decode(predict_answer_tokens)
+'176 billion parameters and can generate text in 46 languages natural languages and 13'
+```
+
+
+Tokenize the text and return TensorFlow tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("my_awesome_qa_model")
+>>> inputs = tokenizer(question, context, return_tensors="tf")
+```
+
+Pass your inputs to the model and return the `logits`:
+
+```py
+>>> from transformers import TFAutoModelForQuestionAnswering
+
+>>> model = TFAutoModelForQuestionAnswering.from_pretrained("my_awesome_qa_model")
+>>> outputs = model(**inputs)
+```
+
+Get the highest probability from the model output for the start and end positions:
+
+```py
+>>> answer_start_index = int(tf.math.argmax(outputs.start_logits, axis=-1)[0])
+>>> answer_end_index = int(tf.math.argmax(outputs.end_logits, axis=-1)[0])
+```
+
+Decode the predicted tokens to get the answer:
+
+```py
+>>> predict_answer_tokens = inputs.input_ids[0, answer_start_index : answer_end_index + 1]
+>>> tokenizer.decode(predict_answer_tokens)
+'176 billion parameters and can generate text in 46 languages natural languages and 13'
+```
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/semantic_segmentation.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/semantic_segmentation.md
new file mode 100644
index 0000000000000000000000000000000000000000..3bede1a448beeb0db30e22a6cf9c189b0e78a15e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/semantic_segmentation.md
@@ -0,0 +1,938 @@
+
+
+# Image Segmentation
+
+[[open-in-colab]]
+
+
+
+Image segmentation models separate areas corresponding to different areas of interest in an image. These models work by assigning a label to each pixel. There are several types of segmentation: semantic segmentation, instance segmentation, and panoptic segmentation.
+
+In this guide, we will:
+1. [Take a look at different types of segmentation](#types-of-segmentation).
+2. [Have an end-to-end fine-tuning example for semantic segmentation](#fine-tuning-a-model-for-segmentation).
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```py
+# uncomment to install the necessary libraries
+!pip install -q datasets transformers evaluate accelerate
+```
+
+We encourage you to log in to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to log in:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Types of Segmentation
+
+Semantic segmentation assigns a label or class to every single pixel in an image. Let's take a look at a semantic segmentation model output. It will assign the same class to every instance of an object it comes across in an image, for example, all cats will be labeled as "cat" instead of "cat-1", "cat-2".
+We can use transformers' image segmentation pipeline to quickly infer a semantic segmentation model. Let's take a look at the example image.
+
+```python
+from transformers import pipeline
+from PIL import Image
+import requests
+
+url = "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/transformers/tasks/segmentation_input.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+image
+```
+
+
+
+
+
+We will use [nvidia/segformer-b1-finetuned-cityscapes-1024-1024](https://huggingface.co/nvidia/segformer-b1-finetuned-cityscapes-1024-1024).
+
+```python
+semantic_segmentation = pipeline("image-segmentation", "nvidia/segformer-b1-finetuned-cityscapes-1024-1024")
+results = semantic_segmentation(image)
+results
+```
+
+The segmentation pipeline output includes a mask for every predicted class.
+```bash
+[{'score': None,
+ 'label': 'road',
+ 'mask': },
+ {'score': None,
+ 'label': 'sidewalk',
+ 'mask': },
+ {'score': None,
+ 'label': 'building',
+ 'mask': },
+ {'score': None,
+ 'label': 'wall',
+ 'mask': },
+ {'score': None,
+ 'label': 'pole',
+ 'mask': },
+ {'score': None,
+ 'label': 'traffic sign',
+ 'mask': },
+ {'score': None,
+ 'label': 'vegetation',
+ 'mask': },
+ {'score': None,
+ 'label': 'terrain',
+ 'mask': },
+ {'score': None,
+ 'label': 'sky',
+ 'mask': },
+ {'score': None,
+ 'label': 'car',
+ 'mask': }]
+```
+
+Taking a look at the mask for the car class, we can see every car is classified with the same mask.
+
+```python
+results[-1]["mask"]
+```
+
+
+
+
+In instance segmentation, the goal is not to classify every pixel, but to predict a mask for **every instance of an object** in a given image. It works very similar to object detection, where there is a bounding box for every instance, there's a segmentation mask instead. We will use [facebook/mask2former-swin-large-cityscapes-instance](https://huggingface.co/facebook/mask2former-swin-large-cityscapes-instance) for this.
+
+```python
+instance_segmentation = pipeline("image-segmentation", "facebook/mask2former-swin-large-cityscapes-instance")
+results = instance_segmentation(image)
+results
+```
+
+As you can see below, there are multiple cars classified, and there's no classification for pixels other than pixels that belong to car and person instances.
+
+```bash
+[{'score': 0.999944,
+ 'label': 'car',
+ 'mask': },
+ {'score': 0.999945,
+ 'label': 'car',
+ 'mask': },
+ {'score': 0.999652,
+ 'label': 'car',
+ 'mask': },
+ {'score': 0.903529,
+ 'label': 'person',
+ 'mask': }]
+```
+Checking out one of the car masks below.
+
+```python
+results[2]["mask"]
+```
+
+
+
+
+Panoptic segmentation combines semantic segmentation and instance segmentation, where every pixel is classified into a class and an instance of that class, and there are multiple masks for each instance of a class. We can use [facebook/mask2former-swin-large-cityscapes-panoptic](https://huggingface.co/facebook/mask2former-swin-large-cityscapes-panoptic) for this.
+
+```python
+panoptic_segmentation = pipeline("image-segmentation", "facebook/mask2former-swin-large-cityscapes-panoptic")
+results = panoptic_segmentation(image)
+results
+```
+As you can see below, we have more classes. We will later illustrate to see that every pixel is classified into one of the classes.
+
+```bash
+[{'score': 0.999981,
+ 'label': 'car',
+ 'mask': },
+ {'score': 0.999958,
+ 'label': 'car',
+ 'mask': },
+ {'score': 0.99997,
+ 'label': 'vegetation',
+ 'mask': },
+ {'score': 0.999575,
+ 'label': 'pole',
+ 'mask': },
+ {'score': 0.999958,
+ 'label': 'building',
+ 'mask': },
+ {'score': 0.999634,
+ 'label': 'road',
+ 'mask': },
+ {'score': 0.996092,
+ 'label': 'sidewalk',
+ 'mask': },
+ {'score': 0.999221,
+ 'label': 'car',
+ 'mask': },
+ {'score': 0.99987,
+ 'label': 'sky',
+ 'mask': }]
+```
+
+Let's have a side by side comparison for all types of segmentation.
+
+
+
+
+
+Seeing all types of segmentation, let's have a deep dive on fine-tuning a model for semantic segmentation.
+
+Common real-world applications of semantic segmentation include training self-driving cars to identify pedestrians and important traffic information, identifying cells and abnormalities in medical imagery, and monitoring environmental changes from satellite imagery.
+
+## Fine-tuning a Model for Segmentation
+
+We will now:
+
+1. Finetune [SegFormer](https://huggingface.co/docs/transformers/main/en/model_doc/segformer#segformer) on the [SceneParse150](https://huggingface.co/datasets/scene_parse_150) dataset.
+2. Use your fine-tuned model for inference.
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/image-segmentation)
+
+
+
+
+### Load SceneParse150 dataset
+
+Start by loading a smaller subset of the SceneParse150 dataset from the 🤗 Datasets library. This'll give you a chance to experiment and make sure everything works before spending more time training on the full dataset.
+
+```py
+>>> from datasets import load_dataset
+
+>>> ds = load_dataset("scene_parse_150", split="train[:50]")
+```
+
+Split the dataset's `train` split into a train and test set with the [`~datasets.Dataset.train_test_split`] method:
+
+```py
+>>> ds = ds.train_test_split(test_size=0.2)
+>>> train_ds = ds["train"]
+>>> test_ds = ds["test"]
+```
+
+Then take a look at an example:
+
+```py
+>>> train_ds[0]
+{'image': ,
+ 'annotation': ,
+ 'scene_category': 368}
+
+# view the image
+>>> train_ds[0]["image"]
+```
+
+- `image`: a PIL image of the scene.
+- `annotation`: a PIL image of the segmentation map, which is also the model's target.
+- `scene_category`: a category id that describes the image scene like "kitchen" or "office". In this guide, you'll only need `image` and `annotation`, both of which are PIL images.
+
+You'll also want to create a dictionary that maps a label id to a label class which will be useful when you set up the model later. Download the mappings from the Hub and create the `id2label` and `label2id` dictionaries:
+
+```py
+>>> import json
+>>> from pathlib import Path
+>>> from huggingface_hub import hf_hub_download
+
+>>> repo_id = "huggingface/label-files"
+>>> filename = "ade20k-id2label.json"
+>>> id2label = json.loads(Path(hf_hub_download(repo_id, filename, repo_type="dataset")).read_text())
+>>> id2label = {int(k): v for k, v in id2label.items()}
+>>> label2id = {v: k for k, v in id2label.items()}
+>>> num_labels = len(id2label)
+```
+
+#### Custom dataset
+
+You could also create and use your own dataset if you prefer to train with the [run_semantic_segmentation.py](https://github.com/huggingface/transformers/blob/main/examples/pytorch/semantic-segmentation/run_semantic_segmentation.py) script instead of a notebook instance. The script requires:
+
+1. a [`~datasets.DatasetDict`] with two [`~datasets.Image`] columns, "image" and "label"
+
+ ```py
+ from datasets import Dataset, DatasetDict, Image
+
+ image_paths_train = ["path/to/image_1.jpg/jpg", "path/to/image_2.jpg/jpg", ..., "path/to/image_n.jpg/jpg"]
+ label_paths_train = ["path/to/annotation_1.png", "path/to/annotation_2.png", ..., "path/to/annotation_n.png"]
+
+ image_paths_validation = [...]
+ label_paths_validation = [...]
+
+ def create_dataset(image_paths, label_paths):
+ dataset = Dataset.from_dict({"image": sorted(image_paths),
+ "label": sorted(label_paths)})
+ dataset = dataset.cast_column("image", Image())
+ dataset = dataset.cast_column("label", Image())
+ return dataset
+
+ # step 1: create Dataset objects
+ train_dataset = create_dataset(image_paths_train, label_paths_train)
+ validation_dataset = create_dataset(image_paths_validation, label_paths_validation)
+
+ # step 2: create DatasetDict
+ dataset = DatasetDict({
+ "train": train_dataset,
+ "validation": validation_dataset,
+ }
+ )
+
+ # step 3: push to Hub (assumes you have ran the hf auth login command in a terminal/notebook)
+ dataset.push_to_hub("your-name/dataset-repo")
+
+ # optionally, you can push to a private repo on the Hub
+ # dataset.push_to_hub("name of repo on the hub", private=True)
+ ```
+
+2. an id2label dictionary mapping the class integers to their class names
+
+ ```py
+ import json
+ # simple example
+ id2label = {0: 'cat', 1: 'dog'}
+ with open('id2label.json', 'w') as fp:
+ json.dump(id2label, fp)
+ ```
+
+As an example, take a look at this [example dataset](https://huggingface.co/datasets/nielsr/ade20k-demo) which was created with the steps shown above.
+
+### Preprocess
+
+The next step is to load a SegFormer image processor to prepare the images and annotations for the model. Some datasets, like this one, use the zero-index as the background class. However, the background class isn't actually included in the 150 classes, so you'll need to set `do_reduce_labels=True` to subtract one from all the labels. The zero-index is replaced by `255` so it's ignored by SegFormer's loss function:
+
+```py
+>>> from transformers import AutoImageProcessor
+
+>>> checkpoint = "nvidia/mit-b0"
+>>> image_processor = AutoImageProcessor.from_pretrained(checkpoint, do_reduce_labels=True)
+```
+
+
+
+
+It is common to apply some data augmentations to an image dataset to make a model more robust against overfitting. In this guide, you'll use the [`ColorJitter`](https://pytorch.org/vision/stable/generated/torchvision.transforms.ColorJitter.html) function from [torchvision](https://pytorch.org/vision/stable/index.html) to randomly change the color properties of an image, but you can also use any image library you like.
+
+```py
+>>> from torchvision.transforms import ColorJitter
+
+>>> jitter = ColorJitter(brightness=0.25, contrast=0.25, saturation=0.25, hue=0.1)
+```
+
+Now create two preprocessing functions to prepare the images and annotations for the model. These functions convert the images into `pixel_values` and annotations to `labels`. For the training set, `jitter` is applied before providing the images to the image processor. For the test set, the image processor crops and normalizes the `images`, and only crops the `labels` because no data augmentation is applied during testing.
+
+```py
+>>> def train_transforms(example_batch):
+... images = [jitter(x) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+
+
+>>> def val_transforms(example_batch):
+... images = [x for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+```
+
+To apply the `jitter` over the entire dataset, use the 🤗 Datasets [`~datasets.Dataset.set_transform`] function. The transform is applied on the fly which is faster and consumes less disk space:
+
+```py
+>>> train_ds.set_transform(train_transforms)
+>>> test_ds.set_transform(val_transforms)
+```
+
+
+
+
+
+
+It is common to apply some data augmentations to an image dataset to make a model more robust against overfitting.
+In this guide, you'll use [`tf.image`](https://www.tensorflow.org/api_docs/python/tf/image) to randomly change the color properties of an image, but you can also use any image
+library you like.
+Define two separate transformation functions:
+- training data transformations that include image augmentation
+- validation data transformations that only transpose the images, since computer vision models in 🤗 Transformers expect channels-first layout
+
+```py
+>>> import tensorflow as tf
+
+
+>>> def aug_transforms(image):
+... image = tf.keras.utils.img_to_array(image)
+... image = tf.image.random_brightness(image, 0.25)
+... image = tf.image.random_contrast(image, 0.5, 2.0)
+... image = tf.image.random_saturation(image, 0.75, 1.25)
+... image = tf.image.random_hue(image, 0.1)
+... image = tf.transpose(image, (2, 0, 1))
+... return image
+
+
+>>> def transforms(image):
+... image = tf.keras.utils.img_to_array(image)
+... image = tf.transpose(image, (2, 0, 1))
+... return image
+```
+
+Next, create two preprocessing functions to prepare batches of images and annotations for the model. These functions apply
+the image transformations and use the earlier loaded `image_processor` to convert the images into `pixel_values` and
+annotations to `labels`. `ImageProcessor` also takes care of resizing and normalizing the images.
+
+```py
+>>> def train_transforms(example_batch):
+... images = [aug_transforms(x.convert("RGB")) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+
+
+>>> def val_transforms(example_batch):
+... images = [transforms(x.convert("RGB")) for x in example_batch["image"]]
+... labels = [x for x in example_batch["annotation"]]
+... inputs = image_processor(images, labels)
+... return inputs
+```
+
+To apply the preprocessing transformations over the entire dataset, use the 🤗 Datasets [`~datasets.Dataset.set_transform`] function.
+The transform is applied on the fly which is faster and consumes less disk space:
+
+```py
+>>> train_ds.set_transform(train_transforms)
+>>> test_ds.set_transform(val_transforms)
+```
+
+
+
+### Evaluate
+
+Including a metric during training is often helpful for evaluating your model's performance. You can quickly load an evaluation method with the 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) library. For this task, load the [mean Intersection over Union](https://huggingface.co/spaces/evaluate-metric/accuracy) (IoU) metric (see the 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour) to learn more about how to load and compute a metric):
+
+```py
+>>> import evaluate
+
+>>> metric = evaluate.load("mean_iou")
+```
+
+Then create a function to [`~evaluate.EvaluationModule.compute`] the metrics. Your predictions need to be converted to
+logits first, and then reshaped to match the size of the labels before you can call [`~evaluate.EvaluationModule.compute`]:
+
+
+
+
+```py
+>>> import numpy as np
+>>> import torch
+>>> from torch import nn
+
+>>> def compute_metrics(eval_pred):
+... with torch.no_grad():
+... logits, labels = eval_pred
+... logits_tensor = torch.from_numpy(logits)
+... logits_tensor = nn.functional.interpolate(
+... logits_tensor,
+... size=labels.shape[-2:],
+... mode="bilinear",
+... align_corners=False,
+... ).argmax(dim=1)
+
+... pred_labels = logits_tensor.detach().cpu().numpy()
+... metrics = metric.compute(
+... predictions=pred_labels,
+... references=labels,
+... num_labels=num_labels,
+... ignore_index=255,
+... reduce_labels=False,
+... )
+... for key, value in metrics.items():
+... if isinstance(value, np.ndarray):
+... metrics[key] = value.tolist()
+... return metrics
+```
+
+
+
+
+
+
+
+
+```py
+>>> def compute_metrics(eval_pred):
+... logits, labels = eval_pred
+... logits = tf.transpose(logits, perm=[0, 2, 3, 1])
+... logits_resized = tf.image.resize(
+... logits,
+... size=tf.shape(labels)[1:],
+... method="bilinear",
+... )
+
+... pred_labels = tf.argmax(logits_resized, axis=-1)
+... metrics = metric.compute(
+... predictions=pred_labels,
+... references=labels,
+... num_labels=num_labels,
+... ignore_index=-1,
+... reduce_labels=image_processor.do_reduce_labels,
+... )
+
+... per_category_accuracy = metrics.pop("per_category_accuracy").tolist()
+... per_category_iou = metrics.pop("per_category_iou").tolist()
+
+... metrics.update({f"accuracy_{id2label[i]}": v for i, v in enumerate(per_category_accuracy)})
+... metrics.update({f"iou_{id2label[i]}": v for i, v in enumerate(per_category_iou)})
+... return {"val_" + k: v for k, v in metrics.items()}
+```
+
+
+
+
+Your `compute_metrics` function is ready to go now, and you'll return to it when you setup your training.
+
+### Train
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#finetune-with-trainer)!
+
+
+
+You're ready to start training your model now! Load SegFormer with [`AutoModelForSemanticSegmentation`], and pass the model the mapping between label ids and label classes:
+
+```py
+>>> from transformers import AutoModelForSemanticSegmentation, TrainingArguments, Trainer
+
+>>> model = AutoModelForSemanticSegmentation.from_pretrained(checkpoint, id2label=id2label, label2id=label2id)
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`TrainingArguments`]. It is important you don't remove unused columns because this'll drop the `image` column. Without the `image` column, you can't create `pixel_values`. Set `remove_unused_columns=False` to prevent this behavior! The only other required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model). At the end of each epoch, the [`Trainer`] will evaluate the IoU metric and save the training checkpoint.
+2. Pass the training arguments to [`Trainer`] along with the model, dataset, tokenizer, data collator, and `compute_metrics` function.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="segformer-b0-scene-parse-150",
+... learning_rate=6e-5,
+... num_train_epochs=50,
+... per_device_train_batch_size=2,
+... per_device_eval_batch_size=2,
+... save_total_limit=3,
+... eval_strategy="steps",
+... save_strategy="steps",
+... save_steps=20,
+... eval_steps=20,
+... logging_steps=1,
+... eval_accumulation_steps=5,
+... remove_unused_columns=False,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=train_ds,
+... eval_dataset=test_ds,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+
+
+
+If you are unfamiliar with fine-tuning a model with Keras, check out the [basic tutorial](./training#train-a-tensorflow-model-with-keras) first!
+
+
+
+To fine-tune a model in TensorFlow, follow these steps:
+1. Define the training hyperparameters, and set up an optimizer and a learning rate schedule.
+2. Instantiate a pretrained model.
+3. Convert a 🤗 Dataset to a `tf.data.Dataset`.
+4. Compile your model.
+5. Add callbacks to calculate metrics and upload your model to 🤗 Hub
+6. Use the `fit()` method to run the training.
+
+Start by defining the hyperparameters, optimizer and learning rate schedule:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 2
+>>> num_epochs = 50
+>>> num_train_steps = len(train_ds) * num_epochs
+>>> learning_rate = 6e-5
+>>> weight_decay_rate = 0.01
+
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=learning_rate,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=weight_decay_rate,
+... num_warmup_steps=0,
+... )
+```
+
+Then, load SegFormer with [`TFAutoModelForSemanticSegmentation`] along with the label mappings, and compile it with the
+optimizer. Note that Transformers models all have a default task-relevant loss function, so you don't need to specify one unless you want to:
+
+```py
+>>> from transformers import TFAutoModelForSemanticSegmentation
+
+>>> model = TFAutoModelForSemanticSegmentation.from_pretrained(
+... checkpoint,
+... id2label=id2label,
+... label2id=label2id,
+... )
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+Convert your datasets to the `tf.data.Dataset` format using the [`~datasets.Dataset.to_tf_dataset`] and the [`DefaultDataCollator`]:
+
+```py
+>>> from transformers import DefaultDataCollator
+
+>>> data_collator = DefaultDataCollator(return_tensors="tf")
+
+>>> tf_train_dataset = train_ds.to_tf_dataset(
+... columns=["pixel_values", "label"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+
+>>> tf_eval_dataset = test_ds.to_tf_dataset(
+... columns=["pixel_values", "label"],
+... shuffle=True,
+... batch_size=batch_size,
+... collate_fn=data_collator,
+... )
+```
+
+To compute the accuracy from the predictions and push your model to the 🤗 Hub, use [Keras callbacks](../main_classes/keras_callbacks).
+Pass your `compute_metrics` function to [`KerasMetricCallback`],
+and use the [`PushToHubCallback`] to upload the model:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback, PushToHubCallback
+
+>>> metric_callback = KerasMetricCallback(
+... metric_fn=compute_metrics, eval_dataset=tf_eval_dataset, batch_size=batch_size, label_cols=["labels"]
+... )
+
+>>> push_to_hub_callback = PushToHubCallback(output_dir="scene_segmentation", tokenizer=image_processor)
+
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+Finally, you are ready to train your model! Call `fit()` with your training and validation datasets, the number of epochs,
+and your callbacks to fine-tune the model:
+
+```py
+>>> model.fit(
+... tf_train_dataset,
+... validation_data=tf_eval_dataset,
+... callbacks=callbacks,
+... epochs=num_epochs,
+... )
+```
+
+Congratulations! You have fine-tuned your model and shared it on the 🤗 Hub. You can now use it for inference!
+
+
+
+### Inference
+
+Great, now that you've finetuned a model, you can use it for inference!
+
+Reload the dataset and load an image for inference.
+
+```py
+>>> from datasets import load_dataset
+
+>>> ds = load_dataset("scene_parse_150", split="train[:50]")
+>>> ds = ds.train_test_split(test_size=0.2)
+>>> test_ds = ds["test"]
+>>> image = ds["test"][0]["image"]
+>>> image
+```
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/sequence_classification.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/sequence_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..27516ace1cc345bd5caaf00774020749e32a2b84
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/sequence_classification.md
@@ -0,0 +1,391 @@
+
+
+# Text classification
+
+[[open-in-colab]]
+
+
+
+Text classification is a common NLP task that assigns a label or class to text. Some of the largest companies run text classification in production for a wide range of practical applications. One of the most popular forms of text classification is sentiment analysis, which assigns a label like 🙂 positive, 🙁 negative, or 😐 neutral to a sequence of text.
+
+This guide will show you how to:
+
+1. Finetune [DistilBERT](https://huggingface.co/distilbert/distilbert-base-uncased) on the [IMDb](https://huggingface.co/datasets/imdb) dataset to determine whether a movie review is positive or negative.
+2. Use your finetuned model for inference.
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/text-classification).
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate accelerate
+```
+
+We encourage you to login to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to login:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load IMDb dataset
+
+Start by loading the IMDb dataset from the 🤗 Datasets library:
+
+```py
+>>> from datasets import load_dataset
+
+>>> imdb = load_dataset("imdb")
+```
+
+Then take a look at an example:
+
+```py
+>>> imdb["test"][0]
+{
+ "label": 0,
+ "text": "I love sci-fi and am willing to put up with a lot. Sci-fi movies/TV are usually underfunded, under-appreciated and misunderstood. I tried to like this, I really did, but it is to good TV sci-fi as Babylon 5 is to Star Trek (the original). Silly prosthetics, cheap cardboard sets, stilted dialogues, CG that doesn't match the background, and painfully one-dimensional characters cannot be overcome with a 'sci-fi' setting. (I'm sure there are those of you out there who think Babylon 5 is good sci-fi TV. It's not. It's clichéd and uninspiring.) While US viewers might like emotion and character development, sci-fi is a genre that does not take itself seriously (cf. Star Trek). It may treat important issues, yet not as a serious philosophy. It's really difficult to care about the characters here as they are not simply foolish, just missing a spark of life. Their actions and reactions are wooden and predictable, often painful to watch. The makers of Earth KNOW it's rubbish as they have to always say \"Gene Roddenberry's Earth...\" otherwise people would not continue watching. Roddenberry's ashes must be turning in their orbit as this dull, cheap, poorly edited (watching it without advert breaks really brings this home) trudging Trabant of a show lumbers into space. Spoiler. So, kill off a main character. And then bring him back as another actor. Jeeez! Dallas all over again.",
+}
+```
+
+There are two fields in this dataset:
+
+- `text`: the movie review text.
+- `label`: a value that is either `0` for a negative review or `1` for a positive review.
+
+## Preprocess
+
+The next step is to load a DistilBERT tokenizer to preprocess the `text` field:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+Create a preprocessing function to tokenize `text` and truncate sequences to be no longer than DistilBERT's maximum input length:
+
+```py
+>>> def preprocess_function(examples):
+... return tokenizer(examples["text"], truncation=True)
+```
+
+To apply the preprocessing function over the entire dataset, use 🤗 Datasets [`~datasets.Dataset.map`] function. You can speed up `map` by setting `batched=True` to process multiple elements of the dataset at once:
+
+```py
+tokenized_imdb = imdb.map(preprocess_function, batched=True)
+```
+
+Now create a batch of examples using [`DataCollatorWithPadding`]. It's more efficient to *dynamically pad* the sentences to the longest length in a batch during collation, instead of padding the whole dataset to the maximum length.
+
+
+
+```py
+>>> from transformers import DataCollatorWithPadding
+
+>>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer)
+```
+
+
+```py
+>>> from transformers import DataCollatorWithPadding
+
+>>> data_collator = DataCollatorWithPadding(tokenizer=tokenizer, return_tensors="tf")
+```
+
+
+
+## Evaluate
+
+Including a metric during training is often helpful for evaluating your model's performance. You can quickly load a evaluation method with the 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) library. For this task, load the [accuracy](https://huggingface.co/spaces/evaluate-metric/accuracy) metric (see the 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour) to learn more about how to load and compute a metric):
+
+```py
+>>> import evaluate
+
+>>> accuracy = evaluate.load("accuracy")
+```
+
+Then create a function that passes your predictions and labels to [`~evaluate.EvaluationModule.compute`] to calculate the accuracy:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... predictions = np.argmax(predictions, axis=1)
+... return accuracy.compute(predictions=predictions, references=labels)
+```
+
+Your `compute_metrics` function is ready to go now, and you'll return to it when you setup your training.
+
+## Train
+
+Before you start training your model, create a map of the expected ids to their labels with `id2label` and `label2id`:
+
+```py
+>>> id2label = {0: "NEGATIVE", 1: "POSITIVE"}
+>>> label2id = {"NEGATIVE": 0, "POSITIVE": 1}
+```
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#train-with-pytorch-trainer)!
+
+
+
+You're ready to start training your model now! Load DistilBERT with [`AutoModelForSequenceClassification`] along with the number of expected labels, and the label mappings:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForSequenceClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=2, id2label=id2label, label2id=label2id
+... )
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`TrainingArguments`]. The only required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model). At the end of each epoch, the [`Trainer`] will evaluate the accuracy and save the training checkpoint.
+2. Pass the training arguments to [`Trainer`] along with the model, dataset, tokenizer, data collator, and `compute_metrics` function.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_model",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=2,
+... weight_decay=0.01,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... load_best_model_at_end=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_imdb["train"],
+... eval_dataset=tokenized_imdb["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+
+
+[`Trainer`] applies dynamic padding by default when you pass `tokenizer` to it. In this case, you don't need to specify a data collator explicitly.
+
+
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+If you aren't familiar with finetuning a model with Keras, take a look at the basic tutorial [here](../training#train-a-tensorflow-model-with-keras)!
+
+
+To finetune a model in TensorFlow, start by setting up an optimizer function, learning rate schedule, and some training hyperparameters:
+
+```py
+>>> from transformers import create_optimizer
+>>> import tensorflow as tf
+
+>>> batch_size = 16
+>>> num_epochs = 5
+>>> batches_per_epoch = len(tokenized_imdb["train"]) // batch_size
+>>> total_train_steps = int(batches_per_epoch * num_epochs)
+>>> optimizer, schedule = create_optimizer(init_lr=2e-5, num_warmup_steps=0, num_train_steps=total_train_steps)
+```
+
+Then you can load DistilBERT with [`TFAutoModelForSequenceClassification`] along with the number of expected labels, and the label mappings:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=2, id2label=id2label, label2id=label2id
+... )
+```
+
+Convert your datasets to the `tf.data.Dataset` format with [`~transformers.TFPreTrainedModel.prepare_tf_dataset`]:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_imdb["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_imdb["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+Configure the model for training with [`compile`](https://keras.io/api/models/model_training_apis/#compile-method). Note that Transformers models all have a default task-relevant loss function, so you don't need to specify one unless you want to:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+The last two things to setup before you start training is to compute the accuracy from the predictions, and provide a way to push your model to the Hub. Both are done by using [Keras callbacks](../main_classes/keras_callbacks).
+
+Pass your `compute_metrics` function to [`~transformers.KerasMetricCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+Specify where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_model",
+... tokenizer=tokenizer,
+... )
+```
+
+Then bundle your callbacks together:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+Finally, you're ready to start training your model! Call [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) with your training and validation datasets, the number of epochs, and your callbacks to finetune the model:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3, callbacks=callbacks)
+```
+
+Once training is completed, your model is automatically uploaded to the Hub so everyone can use it!
+
+
+
+
+
+For a more in-depth example of how to finetune a model for text classification, take a look at the corresponding
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification.ipynb)
+or [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/text_classification-tf.ipynb).
+
+
+
+## Inference
+
+Great, now that you've finetuned a model, you can use it for inference!
+
+Grab some text you'd like to run inference on:
+
+```py
+>>> text = "This was a masterpiece. Not completely faithful to the books, but enthralling from beginning to end. Might be my favorite of the three."
+```
+
+The simplest way to try out your finetuned model for inference is to use it in a [`pipeline`]. Instantiate a `pipeline` for sentiment analysis with your model, and pass your text to it:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("sentiment-analysis", model="stevhliu/my_awesome_model")
+>>> classifier(text)
+[{'label': 'POSITIVE', 'score': 0.9994940757751465}]
+```
+
+You can also manually replicate the results of the `pipeline` if you'd like:
+
+
+
+Tokenize the text and return PyTorch tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_model")
+>>> inputs = tokenizer(text, return_tensors="pt")
+```
+
+Pass your inputs to the model and return the `logits`:
+
+```py
+>>> from transformers import AutoModelForSequenceClassification
+
+>>> model = AutoModelForSequenceClassification.from_pretrained("stevhliu/my_awesome_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+Get the class with the highest probability, and use the model's `id2label` mapping to convert it to a text label:
+
+```py
+>>> predicted_class_id = logits.argmax().item()
+>>> model.config.id2label[predicted_class_id]
+'POSITIVE'
+```
+
+
+Tokenize the text and return TensorFlow tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_model")
+>>> inputs = tokenizer(text, return_tensors="tf")
+```
+
+Pass your inputs to the model and return the `logits`:
+
+```py
+>>> from transformers import TFAutoModelForSequenceClassification
+
+>>> model = TFAutoModelForSequenceClassification.from_pretrained("stevhliu/my_awesome_model")
+>>> logits = model(**inputs).logits
+```
+
+Get the class with the highest probability, and use the model's `id2label` mapping to convert it to a text label:
+
+```py
+>>> predicted_class_id = int(tf.math.argmax(logits, axis=-1)[0])
+>>> model.config.id2label[predicted_class_id]
+'POSITIVE'
+```
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/summarization.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/summarization.md
new file mode 100644
index 0000000000000000000000000000000000000000..e16dd17dfe1fc8186cd0f121f5f794d0f7f7c16e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/summarization.md
@@ -0,0 +1,400 @@
+
+
+# Summarization
+
+[[open-in-colab]]
+
+
+
+Summarization creates a shorter version of a document or an article that captures all the important information. Along with translation, it is another example of a task that can be formulated as a sequence-to-sequence task. Summarization can be:
+
+- Extractive: extract the most relevant information from a document.
+- Abstractive: generate new text that captures the most relevant information.
+
+This guide will show you how to:
+
+1. Finetune [T5](https://huggingface.co/google-t5/t5-small) on the California state bill subset of the [BillSum](https://huggingface.co/datasets/billsum) dataset for abstractive summarization.
+2. Use your finetuned model for inference.
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/summarization)
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate rouge_score
+```
+
+We encourage you to login to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to login:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load BillSum dataset
+
+Start by loading the smaller California state bill subset of the BillSum dataset from the 🤗 Datasets library:
+
+```py
+>>> from datasets import load_dataset
+
+>>> billsum = load_dataset("billsum", split="ca_test")
+```
+
+Split the dataset into a train and test set with the [`~datasets.Dataset.train_test_split`] method:
+
+```py
+>>> billsum = billsum.train_test_split(test_size=0.2)
+```
+
+Then take a look at an example:
+
+```py
+>>> billsum["train"][0]
+{'summary': 'Existing law authorizes state agencies to enter into contracts for the acquisition of goods or services upon approval by the Department of General Services. Existing law sets forth various requirements and prohibitions for those contracts, including, but not limited to, a prohibition on entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between spouses and domestic partners or same-sex and different-sex couples in the provision of benefits. Existing law provides that a contract entered into in violation of those requirements and prohibitions is void and authorizes the state or any person acting on behalf of the state to bring a civil action seeking a determination that a contract is in violation and therefore void. Under existing law, a willful violation of those requirements and prohibitions is a misdemeanor.\nThis bill would also prohibit a state agency from entering into contracts for the acquisition of goods or services of $100,000 or more with a contractor that discriminates between employees on the basis of gender identity in the provision of benefits, as specified. By expanding the scope of a crime, this bill would impose a state-mandated local program.\nThe California Constitution requires the state to reimburse local agencies and school districts for certain costs mandated by the state. Statutory provisions establish procedures for making that reimbursement.\nThis bill would provide that no reimbursement is required by this act for a specified reason.',
+ 'text': 'The people of the State of California do enact as follows:\n\n\nSECTION 1.\nSection 10295.35 is added to the Public Contract Code, to read:\n10295.35.\n(a) (1) Notwithstanding any other law, a state agency shall not enter into any contract for the acquisition of goods or services in the amount of one hundred thousand dollars ($100,000) or more with a contractor that, in the provision of benefits, discriminates between employees on the basis of an employee’s or dependent’s actual or perceived gender identity, including, but not limited to, the employee’s or dependent’s identification as transgender.\n(2) For purposes of this section, “contract” includes contracts with a cumulative amount of one hundred thousand dollars ($100,000) or more per contractor in each fiscal year.\n(3) For purposes of this section, an employee health plan is discriminatory if the plan is not consistent with Section 1365.5 of the Health and Safety Code and Section 10140 of the Insurance Code.\n(4) The requirements of this section shall apply only to those portions of a contractor’s operations that occur under any of the following conditions:\n(A) Within the state.\n(B) On real property outside the state if the property is owned by the state or if the state has a right to occupy the property, and if the contractor’s presence at that location is connected to a contract with the state.\n(C) Elsewhere in the United States where work related to a state contract is being performed.\n(b) Contractors shall treat as confidential, to the maximum extent allowed by law or by the requirement of the contractor’s insurance provider, any request by an employee or applicant for employment benefits or any documentation of eligibility for benefits submitted by an employee or applicant for employment.\n(c) After taking all reasonable measures to find a contractor that complies with this section, as determined by the state agency, the requirements of this section may be waived under any of the following circumstances:\n(1) There is only one prospective contractor willing to enter into a specific contract with the state agency.\n(2) The contract is necessary to respond to an emergency, as determined by the state agency, that endangers the public health, welfare, or safety, or the contract is necessary for the provision of essential services, and no entity that complies with the requirements of this section capable of responding to the emergency is immediately available.\n(3) The requirements of this section violate, or are inconsistent with, the terms or conditions of a grant, subvention, or agreement, if the agency has made a good faith attempt to change the terms or conditions of any grant, subvention, or agreement to authorize application of this section.\n(4) The contractor is providing wholesale or bulk water, power, or natural gas, the conveyance or transmission of the same, or ancillary services, as required for ensuring reliable services in accordance with good utility practice, if the purchase of the same cannot practically be accomplished through the standard competitive bidding procedures and the contractor is not providing direct retail services to end users.\n(d) (1) A contractor shall not be deemed to discriminate in the provision of benefits if the contractor, in providing the benefits, pays the actual costs incurred in obtaining the benefit.\n(2) If a contractor is unable to provide a certain benefit, despite taking reasonable measures to do so, the contractor shall not be deemed to discriminate in the provision of benefits.\n(e) (1) Every contract subject to this chapter shall contain a statement by which the contractor certifies that the contractor is in compliance with this section.\n(2) The department or other contracting agency shall enforce this section pursuant to its existing enforcement powers.\n(3) (A) If a contractor falsely certifies that it is in compliance with this section, the contract with that contractor shall be subject to Article 9 (commencing with Section 10420), unless, within a time period specified by the department or other contracting agency, the contractor provides to the department or agency proof that it has complied, or is in the process of complying, with this section.\n(B) The application of the remedies or penalties contained in Article 9 (commencing with Section 10420) to a contract subject to this chapter shall not preclude the application of any existing remedies otherwise available to the department or other contracting agency under its existing enforcement powers.\n(f) Nothing in this section is intended to regulate the contracting practices of any local jurisdiction.\n(g) This section shall be construed so as not to conflict with applicable federal laws, rules, or regulations. In the event that a court or agency of competent jurisdiction holds that federal law, rule, or regulation invalidates any clause, sentence, paragraph, or section of this code or the application thereof to any person or circumstances, it is the intent of the state that the court or agency sever that clause, sentence, paragraph, or section so that the remainder of this section shall remain in effect.\nSEC. 2.\nSection 10295.35 of the Public Contract Code shall not be construed to create any new enforcement authority or responsibility in the Department of General Services or any other contracting agency.\nSEC. 3.\nNo reimbursement is required by this act pursuant to Section 6 of Article XIII\u2009B of the California Constitution because the only costs that may be incurred by a local agency or school district will be incurred because this act creates a new crime or infraction, eliminates a crime or infraction, or changes the penalty for a crime or infraction, within the meaning of Section 17556 of the Government Code, or changes the definition of a crime within the meaning of Section 6 of Article XIII\u2009B of the California Constitution.',
+ 'title': 'An act to add Section 10295.35 to the Public Contract Code, relating to public contracts.'}
+```
+
+There are two fields that you'll want to use:
+
+- `text`: the text of the bill which'll be the input to the model.
+- `summary`: a condensed version of `text` which'll be the model target.
+
+## Preprocess
+
+The next step is to load a T5 tokenizer to process `text` and `summary`:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> checkpoint = "google-t5/t5-small"
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+```
+
+The preprocessing function you want to create needs to:
+
+1. Prefix the input with a prompt so T5 knows this is a summarization task. Some models capable of multiple NLP tasks require prompting for specific tasks.
+2. Use the keyword `text_target` argument when tokenizing labels.
+3. Truncate sequences to be no longer than the maximum length set by the `max_length` parameter.
+
+```py
+>>> prefix = "summarize: "
+
+
+>>> def preprocess_function(examples):
+... inputs = [prefix + doc for doc in examples["text"]]
+... model_inputs = tokenizer(inputs, max_length=1024, truncation=True)
+
+... labels = tokenizer(text_target=examples["summary"], max_length=128, truncation=True)
+
+... model_inputs["labels"] = labels["input_ids"]
+... return model_inputs
+```
+
+To apply the preprocessing function over the entire dataset, use 🤗 Datasets [`~datasets.Dataset.map`] method. You can speed up the `map` function by setting `batched=True` to process multiple elements of the dataset at once:
+
+```py
+>>> tokenized_billsum = billsum.map(preprocess_function, batched=True)
+```
+
+Now create a batch of examples using [`DataCollatorForSeq2Seq`]. It's more efficient to *dynamically pad* the sentences to the longest length in a batch during collation, instead of padding the whole dataset to the maximum length.
+
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint)
+```
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint, return_tensors="tf")
+```
+
+
+
+## Evaluate
+
+Including a metric during training is often helpful for evaluating your model's performance. You can quickly load a evaluation method with the 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) library. For this task, load the [ROUGE](https://huggingface.co/spaces/evaluate-metric/rouge) metric (see the 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour) to learn more about how to load and compute a metric):
+
+```py
+>>> import evaluate
+
+>>> rouge = evaluate.load("rouge")
+```
+
+Then create a function that passes your predictions and labels to [`~evaluate.EvaluationModule.compute`] to calculate the ROUGE metric:
+
+```py
+>>> import numpy as np
+
+
+>>> def compute_metrics(eval_pred):
+... predictions, labels = eval_pred
+... decoded_preds = tokenizer.batch_decode(predictions, skip_special_tokens=True)
+... labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
+... decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+... result = rouge.compute(predictions=decoded_preds, references=decoded_labels, use_stemmer=True)
+
+... prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in predictions]
+... result["gen_len"] = np.mean(prediction_lens)
+
+... return {k: round(v, 4) for k, v in result.items()}
+```
+
+Your `compute_metrics` function is ready to go now, and you'll return to it when you setup your training.
+
+## Train
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#train-with-pytorch-trainer)!
+
+
+
+You're ready to start training your model now! Load T5 with [`AutoModelForSeq2SeqLM`]:
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM, Seq2SeqTrainingArguments, Seq2SeqTrainer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`Seq2SeqTrainingArguments`]. The only required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model). At the end of each epoch, the [`Trainer`] will evaluate the ROUGE metric and save the training checkpoint.
+2. Pass the training arguments to [`Seq2SeqTrainer`] along with the model, dataset, tokenizer, data collator, and `compute_metrics` function.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = Seq2SeqTrainingArguments(
+... output_dir="my_awesome_billsum_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... weight_decay=0.01,
+... save_total_limit=3,
+... num_train_epochs=4,
+... predict_with_generate=True,
+... fp16=True, #change to bf16=True for XPU
+... push_to_hub=True,
+... )
+
+>>> trainer = Seq2SeqTrainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_billsum["train"],
+... eval_dataset=tokenized_billsum["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+If you aren't familiar with finetuning a model with Keras, take a look at the basic tutorial [here](../training#train-a-tensorflow-model-with-keras)!
+
+
+To finetune a model in TensorFlow, start by setting up an optimizer function, learning rate schedule, and some training hyperparameters:
+
+```py
+>>> from transformers import create_optimizer, AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+Then you can load T5 with [`TFAutoModelForSeq2SeqLM`]:
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+Convert your datasets to the `tf.data.Dataset` format with [`~transformers.TFPreTrainedModel.prepare_tf_dataset`]:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_billsum["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... tokenized_billsum["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+Configure the model for training with [`compile`](https://keras.io/api/models/model_training_apis/#compile-method). Note that Transformers models all have a default task-relevant loss function, so you don't need to specify one unless you want to:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+The last two things to setup before you start training is to compute the ROUGE score from the predictions, and provide a way to push your model to the Hub. Both are done by using [Keras callbacks](../main_classes/keras_callbacks).
+
+Pass your `compute_metrics` function to [`~transformers.KerasMetricCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_test_set)
+```
+
+Specify where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_billsum_model",
+... tokenizer=tokenizer,
+... )
+```
+
+Then bundle your callbacks together:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+Finally, you're ready to start training your model! Call [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) with your training and validation datasets, the number of epochs, and your callbacks to finetune the model:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=callbacks)
+```
+
+Once training is completed, your model is automatically uploaded to the Hub so everyone can use it!
+
+
+
+
+
+For a more in-depth example of how to finetune a model for summarization, take a look at the corresponding
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization.ipynb)
+or [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/summarization-tf.ipynb).
+
+
+
+## Inference
+
+Great, now that you've finetuned a model, you can use it for inference!
+
+Come up with some text you'd like to summarize. For T5, you need to prefix your input depending on the task you're working on. For summarization you should prefix your input as shown below:
+
+```py
+>>> text = "summarize: The Inflation Reduction Act lowers prescription drug costs, health care costs, and energy costs. It's the most aggressive action on tackling the climate crisis in American history, which will lift up American workers and create good-paying, union jobs across the country. It'll lower the deficit and ask the ultra-wealthy and corporations to pay their fair share. And no one making under $400,000 per year will pay a penny more in taxes."
+```
+
+The simplest way to try out your finetuned model for inference is to use it in a [`pipeline`]. Instantiate a `pipeline` for summarization with your model, and pass your text to it:
+
+```py
+>>> from transformers import pipeline
+
+>>> summarizer = pipeline("summarization", model="username/my_awesome_billsum_model")
+>>> summarizer(text)
+[{"summary_text": "The Inflation Reduction Act lowers prescription drug costs, health care costs, and energy costs. It's the most aggressive action on tackling the climate crisis in American history, which will lift up American workers and create good-paying, union jobs across the country."}]
+```
+
+You can also manually replicate the results of the `pipeline` if you'd like:
+
+
+
+
+Tokenize the text and return the `input_ids` as PyTorch tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("username/my_awesome_billsum_model")
+>>> inputs = tokenizer(text, return_tensors="pt").input_ids
+```
+
+Use the [`~generation.GenerationMixin.generate`] method to create the summarization. For more details about the different text generation strategies and parameters for controlling generation, check out the [Text Generation](../main_classes/text_generation) API.
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("username/my_awesome_billsum_model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=False)
+```
+
+Decode the generated token ids back into text:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'the inflation reduction act lowers prescription drug costs, health care costs, and energy costs. it's the most aggressive action on tackling the climate crisis in american history. it will ask the ultra-wealthy and corporations to pay their fair share.'
+```
+
+
+Tokenize the text and return the `input_ids` as TensorFlow tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("username/my_awesome_billsum_model")
+>>> inputs = tokenizer(text, return_tensors="tf").input_ids
+```
+
+Use the [`~transformers.generation_tf_utils.TFGenerationMixin.generate`] method to create the summarization. For more details about the different text generation strategies and parameters for controlling generation, check out the [Text Generation](../main_classes/text_generation) API.
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained("username/my_awesome_billsum_model")
+>>> outputs = model.generate(inputs, max_new_tokens=100, do_sample=False)
+```
+
+Decode the generated token ids back into text:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'the inflation reduction act lowers prescription drug costs, health care costs, and energy costs. it's the most aggressive action on tackling the climate crisis in american history. it will ask the ultra-wealthy and corporations to pay their fair share.'
+```
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/text-to-speech.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/text-to-speech.md
new file mode 100644
index 0000000000000000000000000000000000000000..28153cd1160eda0de08f300488ff23af5f10240a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/text-to-speech.md
@@ -0,0 +1,637 @@
+
+
+# Text to speech
+
+[[open-in-colab]]
+
+Text-to-speech (TTS) is the task of creating natural-sounding speech from text, where the speech can be generated in multiple
+languages and for multiple speakers. Several text-to-speech models are currently available in 🤗 Transformers, such as
+[Bark](../model_doc/bark), [MMS](../model_doc/mms), [VITS](../model_doc/vits) and [SpeechT5](../model_doc/speecht5).
+
+You can easily generate audio using the `"text-to-audio"` pipeline (or its alias - `"text-to-speech"`). Some models, like Bark,
+can also be conditioned to generate non-verbal communications such as laughing, sighing and crying, or even add music.
+Here's an example of how you would use the `"text-to-speech"` pipeline with Bark:
+
+```py
+>>> from transformers import pipeline
+
+>>> pipe = pipeline("text-to-speech", model="suno/bark-small")
+>>> text = "[clears throat] This is a test ... and I just took a long pause."
+>>> output = pipe(text)
+```
+
+Here's a code snippet you can use to listen to the resulting audio in a notebook:
+
+```python
+>>> from IPython.display import Audio
+>>> Audio(output["audio"], rate=output["sampling_rate"])
+```
+
+For more examples on what Bark and other pretrained TTS models can do, refer to our
+[Audio course](https://huggingface.co/learn/audio-course/chapter6/pre-trained_models).
+
+If you are looking to fine-tune a TTS model, the only text-to-speech models currently available in 🤗 Transformers
+are [SpeechT5](model_doc/speecht5) and [FastSpeech2Conformer](model_doc/fastspeech2_conformer), though more will be added in the future. SpeechT5 is pre-trained on a combination of speech-to-text and text-to-speech data, allowing it to learn a unified space of hidden representations shared by both text and speech. This means that the same pre-trained model can be fine-tuned for different tasks. Furthermore, SpeechT5 supports multiple speakers through x-vector speaker embeddings.
+
+The remainder of this guide illustrates how to:
+
+1. Fine-tune [SpeechT5](../model_doc/speecht5) that was originally trained on English speech on the Dutch (`nl`) language subset of the [VoxPopuli](https://huggingface.co/datasets/facebook/voxpopuli) dataset.
+2. Use your refined model for inference in one of two ways: using a pipeline or directly.
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install datasets soundfile speechbrain accelerate
+```
+
+Install 🤗Transformers from source as not all the SpeechT5 features have been merged into an official release yet:
+
+```bash
+pip install git+https://github.com/huggingface/transformers.git
+```
+
+
+
+To follow this guide you will need a GPU. If you're working in a notebook, run the following line to check if a GPU is available:
+
+```bash
+!nvidia-smi
+```
+
+or alternatively for AMD GPUs:
+
+```bash
+!rocm-smi
+```
+
+
+
+We encourage you to log in to your Hugging Face account to upload and share your model with the community. When prompted, enter your token to log in:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load the dataset
+
+[VoxPopuli](https://huggingface.co/datasets/facebook/voxpopuli) is a large-scale multilingual speech corpus consisting of
+data sourced from 2009-2020 European Parliament event recordings. It contains labelled audio-transcription data for 15
+European languages. In this guide, we are using the Dutch language subset, feel free to pick another subset.
+
+Note that VoxPopuli or any other automated speech recognition (ASR) dataset may not be the most suitable
+option for training TTS models. The features that make it beneficial for ASR, such as excessive background noise, are
+typically undesirable in TTS. However, finding top-quality, multilingual, and multi-speaker TTS datasets can be quite
+challenging.
+
+Let's load the data:
+
+```py
+>>> from datasets import load_dataset, Audio
+
+>>> dataset = load_dataset("facebook/voxpopuli", "nl", split="train")
+>>> len(dataset)
+20968
+```
+
+20968 examples should be sufficient for fine-tuning. SpeechT5 expects audio data to have a sampling rate of 16 kHz, so
+make sure the examples in the dataset meet this requirement:
+
+```py
+dataset = dataset.cast_column("audio", Audio(sampling_rate=16000))
+```
+
+## Preprocess the data
+
+Let's begin by defining the model checkpoint to use and loading the appropriate processor:
+
+```py
+>>> from transformers import SpeechT5Processor
+
+>>> checkpoint = "microsoft/speecht5_tts"
+>>> processor = SpeechT5Processor.from_pretrained(checkpoint)
+```
+
+### Text cleanup for SpeechT5 tokenization
+
+Start by cleaning up the text data. You'll need the tokenizer part of the processor to process the text:
+
+```py
+>>> tokenizer = processor.tokenizer
+```
+
+The dataset examples contain `raw_text` and `normalized_text` features. When deciding which feature to use as the text input,
+consider that the SpeechT5 tokenizer doesn't have any tokens for numbers. In `normalized_text` the numbers are written
+out as text. Thus, it is a better fit, and we recommend using `normalized_text` as input text.
+
+Because SpeechT5 was trained on the English language, it may not recognize certain characters in the Dutch dataset. If
+left as is, these characters will be converted to `` tokens. However, in Dutch, certain characters like `à` are
+used to stress syllables. In order to preserve the meaning of the text, we can replace this character with a regular `a`.
+
+To identify unsupported tokens, extract all unique characters in the dataset using the `SpeechT5Tokenizer` which
+works with characters as tokens. To do this, write the `extract_all_chars` mapping function that concatenates
+the transcriptions from all examples into one string and converts it to a set of characters.
+Make sure to set `batched=True` and `batch_size=-1` in `dataset.map()` so that all transcriptions are available at once for
+the mapping function.
+
+```py
+>>> def extract_all_chars(batch):
+... all_text = " ".join(batch["normalized_text"])
+... vocab = list(set(all_text))
+... return {"vocab": [vocab], "all_text": [all_text]}
+
+
+>>> vocabs = dataset.map(
+... extract_all_chars,
+... batched=True,
+... batch_size=-1,
+... keep_in_memory=True,
+... remove_columns=dataset.column_names,
+... )
+
+>>> dataset_vocab = set(vocabs["vocab"][0])
+>>> tokenizer_vocab = {k for k, _ in tokenizer.get_vocab().items()}
+```
+
+Now you have two sets of characters: one with the vocabulary from the dataset and one with the vocabulary from the tokenizer.
+To identify any unsupported characters in the dataset, you can take the difference between these two sets. The resulting
+set will contain the characters that are in the dataset but not in the tokenizer.
+
+```py
+>>> dataset_vocab - tokenizer_vocab
+{' ', 'à', 'ç', 'è', 'ë', 'í', 'ï', 'ö', 'ü'}
+```
+
+To handle the unsupported characters identified in the previous step, define a function that maps these characters to
+valid tokens. Note that spaces are already replaced by `▁` in the tokenizer and don't need to be handled separately.
+
+```py
+>>> replacements = [
+... ("à", "a"),
+... ("ç", "c"),
+... ("è", "e"),
+... ("ë", "e"),
+... ("í", "i"),
+... ("ï", "i"),
+... ("ö", "o"),
+... ("ü", "u"),
+... ]
+
+
+>>> def cleanup_text(inputs):
+... for src, dst in replacements:
+... inputs["normalized_text"] = inputs["normalized_text"].replace(src, dst)
+... return inputs
+
+
+>>> dataset = dataset.map(cleanup_text)
+```
+
+Now that you have dealt with special characters in the text, it's time to shift focus to the audio data.
+
+### Speakers
+
+The VoxPopuli dataset includes speech from multiple speakers, but how many speakers are represented in the dataset? To
+determine this, we can count the number of unique speakers and the number of examples each speaker contributes to the dataset.
+With a total of 20,968 examples in the dataset, this information will give us a better understanding of the distribution of
+speakers and examples in the data.
+
+```py
+>>> from collections import defaultdict
+
+>>> speaker_counts = defaultdict(int)
+
+>>> for speaker_id in dataset["speaker_id"]:
+... speaker_counts[speaker_id] += 1
+```
+
+By plotting a histogram you can get a sense of how much data there is for each speaker.
+
+```py
+>>> import matplotlib.pyplot as plt
+
+>>> plt.figure()
+>>> plt.hist(speaker_counts.values(), bins=20)
+>>> plt.ylabel("Speakers")
+>>> plt.xlabel("Examples")
+>>> plt.show()
+```
+
+
+
+
+
+The histogram reveals that approximately one-third of the speakers in the dataset have fewer than 100 examples, while
+around ten speakers have more than 500 examples. To improve training efficiency and balance the dataset, we can limit
+the data to speakers with between 100 and 400 examples.
+
+```py
+>>> def select_speaker(speaker_id):
+... return 100 <= speaker_counts[speaker_id] <= 400
+
+
+>>> dataset = dataset.filter(select_speaker, input_columns=["speaker_id"])
+```
+
+Let's check how many speakers remain:
+
+```py
+>>> len(set(dataset["speaker_id"]))
+42
+```
+
+Let's see how many examples are left:
+
+```py
+>>> len(dataset)
+9973
+```
+
+You are left with just under 10,000 examples from approximately 40 unique speakers, which should be sufficient.
+
+Note that some speakers with few examples may actually have more audio available if the examples are long. However,
+determining the total amount of audio for each speaker requires scanning through the entire dataset, which is a
+time-consuming process that involves loading and decoding each audio file. As such, we have chosen to skip this step here.
+
+### Speaker embeddings
+
+To enable the TTS model to differentiate between multiple speakers, you'll need to create a speaker embedding for each example.
+The speaker embedding is an additional input into the model that captures a particular speaker's voice characteristics.
+To generate these speaker embeddings, use the pre-trained [spkrec-xvect-voxceleb](https://huggingface.co/speechbrain/spkrec-xvect-voxceleb)
+model from SpeechBrain.
+
+Create a function `create_speaker_embedding()` that takes an input audio waveform and outputs a 512-element vector
+containing the corresponding speaker embedding.
+
+```py
+>>> import os
+>>> import torch
+>>> from speechbrain.inference.classifiers import EncoderClassifier
+>>> from transformers import infer_device
+
+>>> spk_model_name = "speechbrain/spkrec-xvect-voxceleb"
+>>> device = infer_device()
+>>> speaker_model = EncoderClassifier.from_hparams(
+... source=spk_model_name,
+... run_opts={"device": device},
+... savedir=os.path.join("/tmp", spk_model_name),
+... )
+
+
+>>> def create_speaker_embedding(waveform):
+... with torch.no_grad():
+... speaker_embeddings = speaker_model.encode_batch(torch.tensor(waveform))
+... speaker_embeddings = torch.nn.functional.normalize(speaker_embeddings, dim=2)
+... speaker_embeddings = speaker_embeddings.squeeze().cpu().numpy()
+... return speaker_embeddings
+```
+
+It's important to note that the `speechbrain/spkrec-xvect-voxceleb` model was trained on English speech from the VoxCeleb
+dataset, whereas the training examples in this guide are in Dutch. While we believe that this model will still generate
+reasonable speaker embeddings for our Dutch dataset, this assumption may not hold true in all cases.
+
+For optimal results, we recommend training an X-vector model on the target speech first. This will ensure that the model
+is better able to capture the unique voice characteristics present in the Dutch language.
+
+### Processing the dataset
+
+Finally, let's process the data into the format the model expects. Create a `prepare_dataset` function that takes in a
+single example and uses the `SpeechT5Processor` object to tokenize the input text and load the target audio into a log-mel spectrogram.
+It should also add the speaker embeddings as an additional input.
+
+```py
+>>> def prepare_dataset(example):
+... audio = example["audio"]
+
+... example = processor(
+... text=example["normalized_text"],
+... audio_target=audio["array"],
+... sampling_rate=audio["sampling_rate"],
+... return_attention_mask=False,
+... )
+
+... # strip off the batch dimension
+... example["labels"] = example["labels"][0]
+
+... # use SpeechBrain to obtain x-vector
+... example["speaker_embeddings"] = create_speaker_embedding(audio["array"])
+
+... return example
+```
+
+Verify the processing is correct by looking at a single example:
+
+```py
+>>> processed_example = prepare_dataset(dataset[0])
+>>> list(processed_example.keys())
+['input_ids', 'labels', 'stop_labels', 'speaker_embeddings']
+```
+
+Speaker embeddings should be a 512-element vector:
+
+```py
+>>> processed_example["speaker_embeddings"].shape
+(512,)
+```
+
+The labels should be a log-mel spectrogram with 80 mel bins.
+
+```py
+>>> import matplotlib.pyplot as plt
+
+>>> plt.figure()
+>>> plt.imshow(processed_example["labels"].T)
+>>> plt.show()
+```
+
+
+
+
+
+Side note: If you find this spectrogram confusing, it may be due to your familiarity with the convention of placing low frequencies
+at the bottom and high frequencies at the top of a plot. However, when plotting spectrograms as an image using the matplotlib library,
+the y-axis is flipped and the spectrograms appear upside down.
+
+Now apply the processing function to the entire dataset. This will take between 5 and 10 minutes.
+
+```py
+>>> dataset = dataset.map(prepare_dataset, remove_columns=dataset.column_names)
+```
+
+You'll see a warning saying that some examples in the dataset are longer than the maximum input length the model can handle (600 tokens).
+Remove those examples from the dataset. Here we go even further and to allow for larger batch sizes we remove anything over 200 tokens.
+
+```py
+>>> def is_not_too_long(input_ids):
+... input_length = len(input_ids)
+... return input_length < 200
+
+
+>>> dataset = dataset.filter(is_not_too_long, input_columns=["input_ids"])
+>>> len(dataset)
+8259
+```
+
+Next, create a basic train/test split:
+
+```py
+>>> dataset = dataset.train_test_split(test_size=0.1)
+```
+
+### Data collator
+
+In order to combine multiple examples into a batch, you need to define a custom data collator. This collator will pad shorter sequences with padding
+tokens, ensuring that all examples have the same length. For the spectrogram labels, the padded portions are replaced with the special value `-100`. This special value
+instructs the model to ignore that part of the spectrogram when calculating the spectrogram loss.
+
+```py
+>>> from dataclasses import dataclass
+>>> from typing import Any, Dict, List, Union
+
+
+>>> @dataclass
+... class TTSDataCollatorWithPadding:
+... processor: Any
+
+... def __call__(self, features: list[dict[str, Union[list[int], torch.Tensor]]]) -> dict[str, torch.Tensor]:
+... input_ids = [{"input_ids": feature["input_ids"]} for feature in features]
+... label_features = [{"input_values": feature["labels"]} for feature in features]
+... speaker_features = [feature["speaker_embeddings"] for feature in features]
+
+... # collate the inputs and targets into a batch
+... batch = processor.pad(input_ids=input_ids, labels=label_features, return_tensors="pt")
+
+... # replace padding with -100 to ignore loss correctly
+... batch["labels"] = batch["labels"].masked_fill(batch.decoder_attention_mask.unsqueeze(-1).ne(1), -100)
+
+... # not used during fine-tuning
+... del batch["decoder_attention_mask"]
+
+... # round down target lengths to multiple of reduction factor
+... if model.config.reduction_factor > 1:
+... target_lengths = torch.tensor([len(feature["input_values"]) for feature in label_features])
+... target_lengths = target_lengths.new(
+... [length - length % model.config.reduction_factor for length in target_lengths]
+... )
+... max_length = max(target_lengths)
+... batch["labels"] = batch["labels"][:, :max_length]
+
+... # also add in the speaker embeddings
+... batch["speaker_embeddings"] = torch.tensor(speaker_features)
+
+... return batch
+```
+
+In SpeechT5, the input to the decoder part of the model is reduced by a factor 2. In other words, it throws away every
+other timestep from the target sequence. The decoder then predicts a sequence that is twice as long. Since the original
+target sequence length may be odd, the data collator makes sure to round the maximum length of the batch down to be a
+multiple of 2.
+
+```py
+>>> data_collator = TTSDataCollatorWithPadding(processor=processor)
+```
+
+## Train the model
+
+Load the pre-trained model from the same checkpoint as you used for loading the processor:
+
+```py
+>>> from transformers import SpeechT5ForTextToSpeech
+
+>>> model = SpeechT5ForTextToSpeech.from_pretrained(checkpoint)
+```
+
+The `use_cache=True` option is incompatible with gradient checkpointing. Disable it for training.
+
+```py
+>>> model.config.use_cache = False
+```
+
+Define the training arguments. Here we are not computing any evaluation metrics during the training process. Instead, we'll
+only look at the loss:
+
+```python
+>>> from transformers import Seq2SeqTrainingArguments
+
+>>> training_args = Seq2SeqTrainingArguments(
+... output_dir="speecht5_finetuned_voxpopuli_nl", # change to a repo name of your choice
+... per_device_train_batch_size=4,
+... gradient_accumulation_steps=8,
+... learning_rate=1e-5,
+... warmup_steps=500,
+... max_steps=4000,
+... gradient_checkpointing=True,
+... fp16=True,
+... eval_strategy="steps",
+... per_device_eval_batch_size=2,
+... save_steps=1000,
+... eval_steps=1000,
+... logging_steps=25,
+... report_to=["tensorboard"],
+... load_best_model_at_end=True,
+... greater_is_better=False,
+... label_names=["labels"],
+... push_to_hub=True,
+... )
+```
+
+Instantiate the `Trainer` object and pass the model, dataset, and data collator to it.
+
+```py
+>>> from transformers import Seq2SeqTrainer
+
+>>> trainer = Seq2SeqTrainer(
+... args=training_args,
+... model=model,
+... train_dataset=dataset["train"],
+... eval_dataset=dataset["test"],
+... data_collator=data_collator,
+... processing_class=processor,
+... )
+```
+
+And with that, you're ready to start training! Training will take several hours. Depending on your GPU,
+it is possible that you will encounter a CUDA "out-of-memory" error when you start training. In this case, you can reduce
+the `per_device_train_batch_size` incrementally by factors of 2 and increase `gradient_accumulation_steps` by 2x to compensate.
+
+```py
+>>> trainer.train()
+```
+
+To be able to use your checkpoint with a pipeline, make sure to save the processor with the checkpoint:
+
+```py
+>>> processor.save_pretrained("YOUR_ACCOUNT_NAME/speecht5_finetuned_voxpopuli_nl")
+```
+
+Push the final model to the 🤗 Hub:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+## Inference
+
+### Inference with a pipeline
+
+Great, now that you've fine-tuned a model, you can use it for inference!
+First, let's see how you can use it with a corresponding pipeline. Let's create a `"text-to-speech"` pipeline with your
+checkpoint:
+
+```py
+>>> from transformers import pipeline
+
+>>> pipe = pipeline("text-to-speech", model="YOUR_ACCOUNT_NAME/speecht5_finetuned_voxpopuli_nl")
+```
+
+Pick a piece of text in Dutch you'd like narrated, e.g.:
+
+```py
+>>> text = "hallo allemaal, ik praat nederlands. groetjes aan iedereen!"
+```
+
+To use SpeechT5 with the pipeline, you'll need a speaker embedding. Let's get it from an example in the test dataset:
+
+```py
+>>> example = dataset["test"][304]
+>>> speaker_embeddings = torch.tensor(example["speaker_embeddings"]).unsqueeze(0)
+```
+
+Now you can pass the text and speaker embeddings to the pipeline, and it will take care of the rest:
+
+```py
+>>> forward_params = {"speaker_embeddings": speaker_embeddings}
+>>> output = pipe(text, forward_params=forward_params)
+>>> output
+{'audio': array([-6.82714235e-05, -4.26525949e-04, 1.06134125e-04, ...,
+ -1.22392643e-03, -7.76011671e-04, 3.29112721e-04], dtype=float32),
+ 'sampling_rate': 16000}
+```
+
+You can then listen to the result:
+
+```py
+>>> from IPython.display import Audio
+>>> Audio(output['audio'], rate=output['sampling_rate'])
+```
+
+### Run inference manually
+
+You can achieve the same inference results without using the pipeline, however, more steps will be required.
+
+Load the model from the 🤗 Hub:
+
+```py
+>>> model = SpeechT5ForTextToSpeech.from_pretrained("YOUR_ACCOUNT/speecht5_finetuned_voxpopuli_nl")
+```
+
+Pick an example from the test dataset obtain a speaker embedding.
+
+```py
+>>> example = dataset["test"][304]
+>>> speaker_embeddings = torch.tensor(example["speaker_embeddings"]).unsqueeze(0)
+```
+
+Define the input text and tokenize it.
+
+```py
+>>> text = "hallo allemaal, ik praat nederlands. groetjes aan iedereen!"
+>>> inputs = processor(text=text, return_tensors="pt")
+```
+
+Create a spectrogram with your model:
+
+```py
+>>> spectrogram = model.generate_speech(inputs["input_ids"], speaker_embeddings)
+```
+
+Visualize the spectrogram, if you'd like to:
+
+```py
+>>> plt.figure()
+>>> plt.imshow(spectrogram.T)
+>>> plt.show()
+```
+
+
+
+
+
+Finally, use the vocoder to turn the spectrogram into sound.
+
+```py
+>>> with torch.no_grad():
+... speech = vocoder(spectrogram)
+
+>>> from IPython.display import Audio
+
+>>> Audio(speech.numpy(), rate=16000)
+```
+
+In our experience, obtaining satisfactory results from this model can be challenging. The quality of the speaker
+embeddings appears to be a significant factor. Since SpeechT5 was pre-trained with English x-vectors, it performs best
+when using English speaker embeddings. If the synthesized speech sounds poor, try using a different speaker embedding.
+
+Increasing the training duration is also likely to enhance the quality of the results. Even so, the speech clearly is Dutch instead of English, and it does
+capture the voice characteristics of the speaker (compare to the original audio in the example).
+Another thing to experiment with is the model's configuration. For example, try using `config.reduction_factor = 1` to
+see if this improves the results.
+
+Finally, it is essential to consider ethical considerations. Although TTS technology has numerous useful applications, it
+may also be used for malicious purposes, such as impersonating someone's voice without their knowledge or consent. Please
+use TTS judiciously and responsibly.
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/token_classification.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/token_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..b93dd0cbe26d975ffe14f9f684b829163f13db65
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/token_classification.md
@@ -0,0 +1,557 @@
+
+
+# Token classification
+
+[[open-in-colab]]
+
+
+
+Token classification assigns a label to individual tokens in a sentence. One of the most common token classification tasks is Named Entity Recognition (NER). NER attempts to find a label for each entity in a sentence, such as a person, location, or organization.
+
+This guide will show you how to:
+
+1. Finetune [DistilBERT](https://huggingface.co/distilbert/distilbert-base-uncased) on the [WNUT 17](https://huggingface.co/datasets/wnut_17) dataset to detect new entities.
+2. Use your finetuned model for inference.
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/token-classification).
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate seqeval
+```
+
+We encourage you to login to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to login:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load WNUT 17 dataset
+
+Start by loading the WNUT 17 dataset from the 🤗 Datasets library:
+
+```py
+>>> from datasets import load_dataset
+
+>>> wnut = load_dataset("wnut_17")
+```
+
+Then take a look at an example:
+
+```py
+>>> wnut["train"][0]
+{'id': '0',
+ 'ner_tags': [0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 0, 7, 8, 8, 0, 7, 0, 0, 0, 0, 0, 0, 0, 0],
+ 'tokens': ['@paulwalk', 'It', "'s", 'the', 'view', 'from', 'where', 'I', "'m", 'living', 'for', 'two', 'weeks', '.', 'Empire', 'State', 'Building', '=', 'ESB', '.', 'Pretty', 'bad', 'storm', 'here', 'last', 'evening', '.']
+}
+```
+
+Each number in `ner_tags` represents an entity. Convert the numbers to their label names to find out what the entities are:
+
+```py
+>>> label_list = wnut["train"].features[f"ner_tags"].feature.names
+>>> label_list
+[
+ "O",
+ "B-corporation",
+ "I-corporation",
+ "B-creative-work",
+ "I-creative-work",
+ "B-group",
+ "I-group",
+ "B-location",
+ "I-location",
+ "B-person",
+ "I-person",
+ "B-product",
+ "I-product",
+]
+```
+
+The letter that prefixes each `ner_tag` indicates the token position of the entity:
+
+- `B-` indicates the beginning of an entity.
+- `I-` indicates a token is contained inside the same entity (for example, the `State` token is a part of an entity like
+ `Empire State Building`).
+- `0` indicates the token doesn't correspond to any entity.
+
+## Preprocess
+
+
+
+The next step is to load a DistilBERT tokenizer to preprocess the `tokens` field:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("distilbert/distilbert-base-uncased")
+```
+
+As you saw in the example `tokens` field above, it looks like the input has already been tokenized. But the input actually hasn't been tokenized yet and you'll need to set `is_split_into_words=True` to tokenize the words into subwords. For example:
+
+```py
+>>> example = wnut["train"][0]
+>>> tokenized_input = tokenizer(example["tokens"], is_split_into_words=True)
+>>> tokens = tokenizer.convert_ids_to_tokens(tokenized_input["input_ids"])
+>>> tokens
+['[CLS]', '@', 'paul', '##walk', 'it', "'", 's', 'the', 'view', 'from', 'where', 'i', "'", 'm', 'living', 'for', 'two', 'weeks', '.', 'empire', 'state', 'building', '=', 'es', '##b', '.', 'pretty', 'bad', 'storm', 'here', 'last', 'evening', '.', '[SEP]']
+```
+
+However, this adds some special tokens `[CLS]` and `[SEP]` and the subword tokenization creates a mismatch between the input and labels. A single word corresponding to a single label may now be split into two subwords. You'll need to realign the tokens and labels by:
+
+1. Mapping all tokens to their corresponding word with the [`word_ids`](https://huggingface.co/docs/transformers/main_classes/tokenizer#transformers.BatchEncoding.word_ids) method.
+2. Assigning the label `-100` to the special tokens `[CLS]` and `[SEP]` so they're ignored by the PyTorch loss function (see [CrossEntropyLoss](https://pytorch.org/docs/stable/generated/torch.nn.CrossEntropyLoss.html)).
+3. Only labeling the first token of a given word. Assign `-100` to other subtokens from the same word.
+
+Here is how you can create a function to realign the tokens and labels, and truncate sequences to be no longer than DistilBERT's maximum input length:
+
+```py
+>>> def tokenize_and_align_labels(examples):
+... tokenized_inputs = tokenizer(examples["tokens"], truncation=True, is_split_into_words=True)
+
+... labels = []
+... for i, label in enumerate(examples[f"ner_tags"]):
+... word_ids = tokenized_inputs.word_ids(batch_index=i) # Map tokens to their respective word.
+... previous_word_idx = None
+... label_ids = []
+... for word_idx in word_ids: # Set the special tokens to -100.
+... if word_idx is None:
+... label_ids.append(-100)
+... elif word_idx != previous_word_idx: # Only label the first token of a given word.
+... label_ids.append(label[word_idx])
+... else:
+... label_ids.append(-100)
+... previous_word_idx = word_idx
+... labels.append(label_ids)
+
+... tokenized_inputs["labels"] = labels
+... return tokenized_inputs
+```
+
+To apply the preprocessing function over the entire dataset, use 🤗 Datasets [`~datasets.Dataset.map`] function. You can speed up the `map` function by setting `batched=True` to process multiple elements of the dataset at once:
+
+```py
+>>> tokenized_wnut = wnut.map(tokenize_and_align_labels, batched=True)
+```
+
+Now create a batch of examples using [`DataCollatorWithPadding`]. It's more efficient to *dynamically pad* the sentences to the longest length in a batch during collation, instead of padding the whole dataset to the maximum length.
+
+
+
+```py
+>>> from transformers import DataCollatorForTokenClassification
+
+>>> data_collator = DataCollatorForTokenClassification(tokenizer=tokenizer)
+```
+
+
+```py
+>>> from transformers import DataCollatorForTokenClassification
+
+>>> data_collator = DataCollatorForTokenClassification(tokenizer=tokenizer, return_tensors="tf")
+```
+
+
+
+## Evaluate
+
+Including a metric during training is often helpful for evaluating your model's performance. You can quickly load a evaluation method with the 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) library. For this task, load the [seqeval](https://huggingface.co/spaces/evaluate-metric/seqeval) framework (see the 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour) to learn more about how to load and compute a metric). Seqeval actually produces several scores: precision, recall, F1, and accuracy.
+
+```py
+>>> import evaluate
+
+>>> seqeval = evaluate.load("seqeval")
+```
+
+Get the NER labels first, and then create a function that passes your true predictions and true labels to [`~evaluate.EvaluationModule.compute`] to calculate the scores:
+
+```py
+>>> import numpy as np
+
+>>> labels = [label_list[i] for i in example[f"ner_tags"]]
+
+
+>>> def compute_metrics(p):
+... predictions, labels = p
+... predictions = np.argmax(predictions, axis=2)
+
+... true_predictions = [
+... [label_list[p] for (p, l) in zip(prediction, label) if l != -100]
+... for prediction, label in zip(predictions, labels)
+... ]
+... true_labels = [
+... [label_list[l] for (p, l) in zip(prediction, label) if l != -100]
+... for prediction, label in zip(predictions, labels)
+... ]
+
+... results = seqeval.compute(predictions=true_predictions, references=true_labels)
+... return {
+... "precision": results["overall_precision"],
+... "recall": results["overall_recall"],
+... "f1": results["overall_f1"],
+... "accuracy": results["overall_accuracy"],
+... }
+```
+
+Your `compute_metrics` function is ready to go now, and you'll return to it when you setup your training.
+
+## Train
+
+Before you start training your model, create a map of the expected ids to their labels with `id2label` and `label2id`:
+
+```py
+>>> id2label = {
+... 0: "O",
+... 1: "B-corporation",
+... 2: "I-corporation",
+... 3: "B-creative-work",
+... 4: "I-creative-work",
+... 5: "B-group",
+... 6: "I-group",
+... 7: "B-location",
+... 8: "I-location",
+... 9: "B-person",
+... 10: "I-person",
+... 11: "B-product",
+... 12: "I-product",
+... }
+>>> label2id = {
+... "O": 0,
+... "B-corporation": 1,
+... "I-corporation": 2,
+... "B-creative-work": 3,
+... "I-creative-work": 4,
+... "B-group": 5,
+... "I-group": 6,
+... "B-location": 7,
+... "I-location": 8,
+... "B-person": 9,
+... "I-person": 10,
+... "B-product": 11,
+... "I-product": 12,
+... }
+```
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#train-with-pytorch-trainer)!
+
+
+
+You're ready to start training your model now! Load DistilBERT with [`AutoModelForTokenClassification`] along with the number of expected labels, and the label mappings:
+
+```py
+>>> from transformers import AutoModelForTokenClassification, TrainingArguments, Trainer
+
+>>> model = AutoModelForTokenClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=13, id2label=id2label, label2id=label2id
+... )
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`TrainingArguments`]. The only required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model). At the end of each epoch, the [`Trainer`] will evaluate the seqeval scores and save the training checkpoint.
+2. Pass the training arguments to [`Trainer`] along with the model, dataset, tokenizer, data collator, and `compute_metrics` function.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = TrainingArguments(
+... output_dir="my_awesome_wnut_model",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... num_train_epochs=2,
+... weight_decay=0.01,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... load_best_model_at_end=True,
+... push_to_hub=True,
+... )
+
+>>> trainer = Trainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_wnut["train"],
+... eval_dataset=tokenized_wnut["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+If you aren't familiar with finetuning a model with Keras, take a look at the basic tutorial [here](../training#train-a-tensorflow-model-with-keras)!
+
+
+To finetune a model in TensorFlow, start by setting up an optimizer function, learning rate schedule, and some training hyperparameters:
+
+```py
+>>> from transformers import create_optimizer
+
+>>> batch_size = 16
+>>> num_train_epochs = 3
+>>> num_train_steps = (len(tokenized_wnut["train"]) // batch_size) * num_train_epochs
+>>> optimizer, lr_schedule = create_optimizer(
+... init_lr=2e-5,
+... num_train_steps=num_train_steps,
+... weight_decay_rate=0.01,
+... num_warmup_steps=0,
+... )
+```
+
+Then you can load DistilBERT with [`TFAutoModelForTokenClassification`] along with the number of expected labels, and the label mappings:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained(
+... "distilbert/distilbert-base-uncased", num_labels=13, id2label=id2label, label2id=label2id
+... )
+```
+
+Convert your datasets to the `tf.data.Dataset` format with [`~transformers.TFPreTrainedModel.prepare_tf_dataset`]:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_wnut["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_validation_set = model.prepare_tf_dataset(
+... tokenized_wnut["validation"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+Configure the model for training with [`compile`](https://keras.io/api/models/model_training_apis/#compile-method). Note that Transformers models all have a default task-relevant loss function, so you don't need to specify one unless you want to:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+The last two things to setup before you start training is to compute the seqeval scores from the predictions, and provide a way to push your model to the Hub. Both are done by using [Keras callbacks](../main_classes/keras_callbacks).
+
+Pass your `compute_metrics` function to [`~transformers.KerasMetricCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_validation_set)
+```
+
+Specify where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_wnut_model",
+... tokenizer=tokenizer,
+... )
+```
+
+Then bundle your callbacks together:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+Finally, you're ready to start training your model! Call [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) with your training and validation datasets, the number of epochs, and your callbacks to finetune the model:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_validation_set, epochs=3, callbacks=callbacks)
+```
+
+Once training is completed, your model is automatically uploaded to the Hub so everyone can use it!
+
+
+
+
+
+For a more in-depth example of how to finetune a model for token classification, take a look at the corresponding
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification.ipynb)
+or [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/token_classification-tf.ipynb).
+
+
+
+## Inference
+
+Great, now that you've finetuned a model, you can use it for inference!
+
+Grab some text you'd like to run inference on:
+
+```py
+>>> text = "The Golden State Warriors are an American professional basketball team based in San Francisco."
+```
+
+The simplest way to try out your finetuned model for inference is to use it in a [`pipeline`]. Instantiate a `pipeline` for NER with your model, and pass your text to it:
+
+```py
+>>> from transformers import pipeline
+
+>>> classifier = pipeline("ner", model="stevhliu/my_awesome_wnut_model")
+>>> classifier(text)
+[{'entity': 'B-location',
+ 'score': 0.42658573,
+ 'index': 2,
+ 'word': 'golden',
+ 'start': 4,
+ 'end': 10},
+ {'entity': 'I-location',
+ 'score': 0.35856336,
+ 'index': 3,
+ 'word': 'state',
+ 'start': 11,
+ 'end': 16},
+ {'entity': 'B-group',
+ 'score': 0.3064001,
+ 'index': 4,
+ 'word': 'warriors',
+ 'start': 17,
+ 'end': 25},
+ {'entity': 'B-location',
+ 'score': 0.65523505,
+ 'index': 13,
+ 'word': 'san',
+ 'start': 80,
+ 'end': 83},
+ {'entity': 'B-location',
+ 'score': 0.4668663,
+ 'index': 14,
+ 'word': 'francisco',
+ 'start': 84,
+ 'end': 93}]
+```
+
+You can also manually replicate the results of the `pipeline` if you'd like:
+
+
+
+Tokenize the text and return PyTorch tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> inputs = tokenizer(text, return_tensors="pt")
+```
+
+Pass your inputs to the model and return the `logits`:
+
+```py
+>>> from transformers import AutoModelForTokenClassification
+
+>>> model = AutoModelForTokenClassification.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> with torch.no_grad():
+... logits = model(**inputs).logits
+```
+
+Get the class with the highest probability, and use the model's `id2label` mapping to convert it to a text label:
+
+```py
+>>> predictions = torch.argmax(logits, dim=2)
+>>> predicted_token_class = [model.config.id2label[t.item()] for t in predictions[0]]
+>>> predicted_token_class
+['O',
+ 'O',
+ 'B-location',
+ 'I-location',
+ 'B-group',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'B-location',
+ 'B-location',
+ 'O',
+ 'O']
+```
+
+
+Tokenize the text and return TensorFlow tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> inputs = tokenizer(text, return_tensors="tf")
+```
+
+Pass your inputs to the model and return the `logits`:
+
+```py
+>>> from transformers import TFAutoModelForTokenClassification
+
+>>> model = TFAutoModelForTokenClassification.from_pretrained("stevhliu/my_awesome_wnut_model")
+>>> logits = model(**inputs).logits
+```
+
+Get the class with the highest probability, and use the model's `id2label` mapping to convert it to a text label:
+
+```py
+>>> predicted_token_class_ids = tf.math.argmax(logits, axis=-1)
+>>> predicted_token_class = [model.config.id2label[t] for t in predicted_token_class_ids[0].numpy().tolist()]
+>>> predicted_token_class
+['O',
+ 'O',
+ 'B-location',
+ 'I-location',
+ 'B-group',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'O',
+ 'B-location',
+ 'B-location',
+ 'O',
+ 'O']
+```
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/translation.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/translation.md
new file mode 100644
index 0000000000000000000000000000000000000000..922cdc7241176a22faf030e37ea21b5b7f467ba3
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/translation.md
@@ -0,0 +1,409 @@
+
+
+# Translation
+
+[[open-in-colab]]
+
+
+
+Translation converts a sequence of text from one language to another. It is one of several tasks you can formulate as a sequence-to-sequence problem, a powerful framework for returning some output from an input, like translation or summarization. Translation systems are commonly used for translation between different language texts, but it can also be used for speech or some combination in between like text-to-speech or speech-to-text.
+
+This guide will show you how to:
+
+1. Finetune [T5](https://huggingface.co/google-t5/t5-small) on the English-French subset of the [OPUS Books](https://huggingface.co/datasets/opus_books) dataset to translate English text to French.
+2. Use your finetuned model for inference.
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/translation).
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install transformers datasets evaluate sacrebleu
+```
+
+We encourage you to login to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to login:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load OPUS Books dataset
+
+Start by loading the English-French subset of the [OPUS Books](https://huggingface.co/datasets/opus_books) dataset from the 🤗 Datasets library:
+
+```py
+>>> from datasets import load_dataset
+
+>>> books = load_dataset("opus_books", "en-fr")
+```
+
+Split the dataset into a train and test set with the [`~datasets.Dataset.train_test_split`] method:
+
+```py
+>>> books = books["train"].train_test_split(test_size=0.2)
+```
+
+Then take a look at an example:
+
+```py
+>>> books["train"][0]
+{'id': '90560',
+ 'translation': {'en': 'But this lofty plateau measured only a few fathoms, and soon we reentered Our Element.',
+ 'fr': 'Mais ce plateau élevé ne mesurait que quelques toises, et bientôt nous fûmes rentrés dans notre élément.'}}
+```
+
+`translation`: an English and French translation of the text.
+
+## Preprocess
+
+
+
+The next step is to load a T5 tokenizer to process the English-French language pairs:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> checkpoint = "google-t5/t5-small"
+>>> tokenizer = AutoTokenizer.from_pretrained(checkpoint)
+```
+
+The preprocessing function you want to create needs to:
+
+1. Prefix the input with a prompt so T5 knows this is a translation task. Some models capable of multiple NLP tasks require prompting for specific tasks.
+2. Set the target language (French) in the `text_target` parameter to ensure the tokenizer processes the target text correctly. If you don't set `text_target`, the tokenizer processes the target text as English.
+3. Truncate sequences to be no longer than the maximum length set by the `max_length` parameter.
+
+```py
+>>> source_lang = "en"
+>>> target_lang = "fr"
+>>> prefix = "translate English to French: "
+
+
+>>> def preprocess_function(examples):
+... inputs = [prefix + example[source_lang] for example in examples["translation"]]
+... targets = [example[target_lang] for example in examples["translation"]]
+... model_inputs = tokenizer(inputs, text_target=targets, max_length=128, truncation=True)
+... return model_inputs
+```
+
+To apply the preprocessing function over the entire dataset, use 🤗 Datasets [`~datasets.Dataset.map`] method. You can speed up the `map` function by setting `batched=True` to process multiple elements of the dataset at once:
+
+```py
+>>> tokenized_books = books.map(preprocess_function, batched=True)
+```
+
+Now create a batch of examples using [`DataCollatorForSeq2Seq`]. It's more efficient to *dynamically pad* the sentences to the longest length in a batch during collation, instead of padding the whole dataset to the maximum length.
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint)
+```
+
+
+
+```py
+>>> from transformers import DataCollatorForSeq2Seq
+
+>>> data_collator = DataCollatorForSeq2Seq(tokenizer=tokenizer, model=checkpoint, return_tensors="tf")
+```
+
+
+
+## Evaluate
+
+Including a metric during training is often helpful for evaluating your model's performance. You can quickly load a evaluation method with the 🤗 [Evaluate](https://huggingface.co/docs/evaluate/index) library. For this task, load the [SacreBLEU](https://huggingface.co/spaces/evaluate-metric/sacrebleu) metric (see the 🤗 Evaluate [quick tour](https://huggingface.co/docs/evaluate/a_quick_tour) to learn more about how to load and compute a metric):
+
+```py
+>>> import evaluate
+
+>>> metric = evaluate.load("sacrebleu")
+```
+
+Then create a function that passes your predictions and labels to [`~evaluate.EvaluationModule.compute`] to calculate the SacreBLEU score:
+
+```py
+>>> import numpy as np
+
+
+>>> def postprocess_text(preds, labels):
+... preds = [pred.strip() for pred in preds]
+... labels = [[label.strip()] for label in labels]
+
+... return preds, labels
+
+
+>>> def compute_metrics(eval_preds):
+... preds, labels = eval_preds
+... if isinstance(preds, tuple):
+... preds = preds[0]
+... decoded_preds = tokenizer.batch_decode(preds, skip_special_tokens=True)
+
+... labels = np.where(labels != -100, labels, tokenizer.pad_token_id)
+... decoded_labels = tokenizer.batch_decode(labels, skip_special_tokens=True)
+
+... decoded_preds, decoded_labels = postprocess_text(decoded_preds, decoded_labels)
+
+... result = metric.compute(predictions=decoded_preds, references=decoded_labels)
+... result = {"bleu": result["score"]}
+
+... prediction_lens = [np.count_nonzero(pred != tokenizer.pad_token_id) for pred in preds]
+... result["gen_len"] = np.mean(prediction_lens)
+... result = {k: round(v, 4) for k, v in result.items()}
+... return result
+```
+
+Your `compute_metrics` function is ready to go now, and you'll return to it when you setup your training.
+
+## Train
+
+
+
+
+
+If you aren't familiar with finetuning a model with the [`Trainer`], take a look at the basic tutorial [here](../training#train-with-pytorch-trainer)!
+
+
+
+You're ready to start training your model now! Load T5 with [`AutoModelForSeq2SeqLM`]:
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM, Seq2SeqTrainingArguments, Seq2SeqTrainer
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+At this point, only three steps remain:
+
+1. Define your training hyperparameters in [`Seq2SeqTrainingArguments`]. The only required parameter is `output_dir` which specifies where to save your model. You'll push this model to the Hub by setting `push_to_hub=True` (you need to be signed in to Hugging Face to upload your model). At the end of each epoch, the [`Trainer`] will evaluate the SacreBLEU metric and save the training checkpoint.
+2. Pass the training arguments to [`Seq2SeqTrainer`] along with the model, dataset, tokenizer, data collator, and `compute_metrics` function.
+3. Call [`~Trainer.train`] to finetune your model.
+
+```py
+>>> training_args = Seq2SeqTrainingArguments(
+... output_dir="my_awesome_opus_books_model",
+... eval_strategy="epoch",
+... learning_rate=2e-5,
+... per_device_train_batch_size=16,
+... per_device_eval_batch_size=16,
+... weight_decay=0.01,
+... save_total_limit=3,
+... num_train_epochs=2,
+... predict_with_generate=True,
+... fp16=True, #change to bf16=True for XPU
+... push_to_hub=True,
+... )
+
+>>> trainer = Seq2SeqTrainer(
+... model=model,
+... args=training_args,
+... train_dataset=tokenized_books["train"],
+... eval_dataset=tokenized_books["test"],
+... processing_class=tokenizer,
+... data_collator=data_collator,
+... compute_metrics=compute_metrics,
+... )
+
+>>> trainer.train()
+```
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+
+
+
+If you aren't familiar with finetuning a model with Keras, take a look at the basic tutorial [here](../training#train-a-tensorflow-model-with-keras)!
+
+
+To finetune a model in TensorFlow, start by setting up an optimizer function, learning rate schedule, and some training hyperparameters:
+
+```py
+>>> from transformers import AdamWeightDecay
+
+>>> optimizer = AdamWeightDecay(learning_rate=2e-5, weight_decay_rate=0.01)
+```
+
+Then you can load T5 with [`TFAutoModelForSeq2SeqLM`]:
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained(checkpoint)
+```
+
+Convert your datasets to the `tf.data.Dataset` format with [`~transformers.TFPreTrainedModel.prepare_tf_dataset`]:
+
+```py
+>>> tf_train_set = model.prepare_tf_dataset(
+... tokenized_books["train"],
+... shuffle=True,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+
+>>> tf_test_set = model.prepare_tf_dataset(
+... tokenized_books["test"],
+... shuffle=False,
+... batch_size=16,
+... collate_fn=data_collator,
+... )
+```
+
+Configure the model for training with [`compile`](https://keras.io/api/models/model_training_apis/#compile-method). Note that Transformers models all have a default task-relevant loss function, so you don't need to specify one unless you want to:
+
+```py
+>>> import tensorflow as tf
+
+>>> model.compile(optimizer=optimizer) # No loss argument!
+```
+
+The last two things to setup before you start training is to compute the SacreBLEU metric from the predictions, and provide a way to push your model to the Hub. Both are done by using [Keras callbacks](../main_classes/keras_callbacks).
+
+Pass your `compute_metrics` function to [`~transformers.KerasMetricCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import KerasMetricCallback
+
+>>> metric_callback = KerasMetricCallback(metric_fn=compute_metrics, eval_dataset=tf_test_set)
+```
+
+Specify where to push your model and tokenizer in the [`~transformers.PushToHubCallback`]:
+
+```py
+>>> from transformers.keras_callbacks import PushToHubCallback
+
+>>> push_to_hub_callback = PushToHubCallback(
+... output_dir="my_awesome_opus_books_model",
+... tokenizer=tokenizer,
+... )
+```
+
+Then bundle your callbacks together:
+
+```py
+>>> callbacks = [metric_callback, push_to_hub_callback]
+```
+
+Finally, you're ready to start training your model! Call [`fit`](https://keras.io/api/models/model_training_apis/#fit-method) with your training and validation datasets, the number of epochs, and your callbacks to finetune the model:
+
+```py
+>>> model.fit(x=tf_train_set, validation_data=tf_test_set, epochs=3, callbacks=callbacks)
+```
+
+Once training is completed, your model is automatically uploaded to the Hub so everyone can use it!
+
+
+
+
+
+For a more in-depth example of how to finetune a model for translation, take a look at the corresponding
+[PyTorch notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation.ipynb)
+or [TensorFlow notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/translation-tf.ipynb).
+
+
+
+## Inference
+
+Great, now that you've finetuned a model, you can use it for inference!
+
+Come up with some text you'd like to translate to another language. For T5, you need to prefix your input depending on the task you're working on. For translation from English to French, you should prefix your input as shown below:
+
+```py
+>>> text = "translate English to French: Legumes share resources with nitrogen-fixing bacteria."
+```
+
+The simplest way to try out your finetuned model for inference is to use it in a [`pipeline`]. Instantiate a `pipeline` for translation with your model, and pass your text to it:
+
+```py
+>>> from transformers import pipeline
+
+# Change `xx` to the language of the input and `yy` to the language of the desired output.
+# Examples: "en" for English, "fr" for French, "de" for German, "es" for Spanish, "zh" for Chinese, etc; translation_en_to_fr translates English to French
+# You can view all the lists of languages here - https://huggingface.co/languages
+>>> translator = pipeline("translation_xx_to_yy", model="username/my_awesome_opus_books_model")
+>>> translator(text)
+[{'translation_text': 'Legumes partagent des ressources avec des bactéries azotantes.'}]
+```
+
+You can also manually replicate the results of the `pipeline` if you'd like:
+
+
+
+Tokenize the text and return the `input_ids` as PyTorch tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("username/my_awesome_opus_books_model")
+>>> inputs = tokenizer(text, return_tensors="pt").input_ids
+```
+
+Use the [`~generation.GenerationMixin.generate`] method to create the translation. For more details about the different text generation strategies and parameters for controlling generation, check out the [Text Generation](../main_classes/text_generation) API.
+
+```py
+>>> from transformers import AutoModelForSeq2SeqLM
+
+>>> model = AutoModelForSeq2SeqLM.from_pretrained("username/my_awesome_opus_books_model")
+>>> outputs = model.generate(inputs, max_new_tokens=40, do_sample=True, top_k=30, top_p=0.95)
+```
+
+Decode the generated token ids back into text:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'Les lignées partagent des ressources avec des bactéries enfixant l'azote.'
+```
+
+
+Tokenize the text and return the `input_ids` as TensorFlow tensors:
+
+```py
+>>> from transformers import AutoTokenizer
+
+>>> tokenizer = AutoTokenizer.from_pretrained("username/my_awesome_opus_books_model")
+>>> inputs = tokenizer(text, return_tensors="tf").input_ids
+```
+
+Use the [`~transformers.generation_tf_utils.TFGenerationMixin.generate`] method to create the translation. For more details about the different text generation strategies and parameters for controlling generation, check out the [Text Generation](../main_classes/text_generation) API.
+
+```py
+>>> from transformers import TFAutoModelForSeq2SeqLM
+
+>>> model = TFAutoModelForSeq2SeqLM.from_pretrained("username/my_awesome_opus_books_model")
+>>> outputs = model.generate(inputs, max_new_tokens=40, do_sample=True, top_k=30, top_p=0.95)
+```
+
+Decode the generated token ids back into text:
+
+```py
+>>> tokenizer.decode(outputs[0], skip_special_tokens=True)
+'Les lugumes partagent les ressources avec des bactéries fixatrices d'azote.'
+```
+
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/video_classification.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/video_classification.md
new file mode 100644
index 0000000000000000000000000000000000000000..7a8c6ba45d04d382fc01994e79e65f64326fca45
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/video_classification.md
@@ -0,0 +1,516 @@
+
+
+# Video classification
+
+[[open-in-colab]]
+
+Video classification is the task of assigning a label or class to an entire video. Videos are expected to have only one class for each video. Video classification models take a video as input and return a prediction about which class the video belongs to. These models can be used to categorize what a video is all about. A real-world application of video classification is action / activity recognition, which is useful for fitness applications. It is also helpful for vision-impaired individuals, especially when they are commuting.
+
+This guide will show you how to:
+
+1. Fine-tune [VideoMAE](https://huggingface.co/docs/transformers/main/en/model_doc/videomae) on a subset of the [UCF101](https://www.crcv.ucf.edu/data/UCF101.php) dataset.
+2. Use your fine-tuned model for inference.
+
+
+
+To see all architectures and checkpoints compatible with this task, we recommend checking the [task-page](https://huggingface.co/tasks/video-classification).
+
+
+
+Before you begin, make sure you have all the necessary libraries installed:
+
+```bash
+pip install -q pytorchvideo transformers evaluate
+```
+
+You will use [PyTorchVideo](https://pytorchvideo.org/) (dubbed `pytorchvideo`) to process and prepare the videos.
+
+We encourage you to log in to your Hugging Face account so you can upload and share your model with the community. When prompted, enter your token to log in:
+
+```py
+>>> from huggingface_hub import notebook_login
+
+>>> notebook_login()
+```
+
+## Load UCF101 dataset
+
+Start by loading a subset of the [UCF-101 dataset](https://www.crcv.ucf.edu/data/UCF101.php). This will give you a chance to experiment and make sure everything works before spending more time training on the full dataset.
+
+```py
+>>> from huggingface_hub import hf_hub_download
+
+>>> hf_dataset_identifier = "sayakpaul/ucf101-subset"
+>>> filename = "UCF101_subset.tar.gz"
+>>> file_path = hf_hub_download(repo_id=hf_dataset_identifier, filename=filename, repo_type="dataset")
+```
+
+After the subset has been downloaded, you need to extract the compressed archive:
+
+```py
+>>> import tarfile
+
+>>> with tarfile.open(file_path) as t:
+... t.extractall(".")
+```
+
+At a high level, the dataset is organized like so:
+
+```bash
+UCF101_subset/
+ train/
+ BandMarching/
+ video_1.mp4
+ video_2.mp4
+ ...
+ Archery
+ video_1.mp4
+ video_2.mp4
+ ...
+ ...
+ val/
+ BandMarching/
+ video_1.mp4
+ video_2.mp4
+ ...
+ Archery
+ video_1.mp4
+ video_2.mp4
+ ...
+ ...
+ test/
+ BandMarching/
+ video_1.mp4
+ video_2.mp4
+ ...
+ Archery
+ video_1.mp4
+ video_2.mp4
+ ...
+ ...
+```
+
+You can then count the number of total videos.
+
+```py
+>>> import pathlib
+>>> dataset_root_path = "UCF101_subset"
+>>> dataset_root_path = pathlib.Path(dataset_root_path)
+```
+
+```py
+>>> video_count_train = len(list(dataset_root_path.glob("train/*/*.avi")))
+>>> video_count_val = len(list(dataset_root_path.glob("val/*/*.avi")))
+>>> video_count_test = len(list(dataset_root_path.glob("test/*/*.avi")))
+>>> video_total = video_count_train + video_count_val + video_count_test
+>>> print(f"Total videos: {video_total}")
+```
+
+```py
+>>> all_video_file_paths = (
+... list(dataset_root_path.glob("train/*/*.avi"))
+... + list(dataset_root_path.glob("val/*/*.avi"))
+... + list(dataset_root_path.glob("test/*/*.avi"))
+... )
+>>> all_video_file_paths[:5]
+```
+
+The (`sorted`) video paths appear like so:
+
+```bash
+...
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g07_c04.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g07_c06.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g08_c01.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g09_c02.avi',
+'UCF101_subset/train/ApplyEyeMakeup/v_ApplyEyeMakeup_g09_c06.avi'
+...
+```
+
+You will notice that there are video clips belonging to the same group / scene where group is denoted by `g` in the video file paths. `v_ApplyEyeMakeup_g07_c04.avi` and `v_ApplyEyeMakeup_g07_c06.avi`, for example.
+
+For the validation and evaluation splits, you wouldn't want to have video clips from the same group / scene to prevent [data leakage](https://www.kaggle.com/code/alexisbcook/data-leakage). The subset that you are using in this tutorial takes this information into account.
+
+Next up, you will derive the set of labels present in the dataset. Also, create two dictionaries that'll be helpful when initializing the model:
+
+* `label2id`: maps the class names to integers.
+* `id2label`: maps the integers to class names.
+
+```py
+>>> class_labels = sorted({str(path).split("/")[2] for path in all_video_file_paths})
+>>> label2id = {label: i for i, label in enumerate(class_labels)}
+>>> id2label = {i: label for label, i in label2id.items()}
+
+>>> print(f"Unique classes: {list(label2id.keys())}.")
+
+# Unique classes: ['ApplyEyeMakeup', 'ApplyLipstick', 'Archery', 'BabyCrawling', 'BalanceBeam', 'BandMarching', 'BaseballPitch', 'Basketball', 'BasketballDunk', 'BenchPress'].
+```
+
+There are 10 unique classes. For each class, there are 30 videos in the training set.
+
+## Load a model to fine-tune
+
+Instantiate a video classification model from a pretrained checkpoint and its associated image processor. The model's encoder comes with pre-trained parameters, and the classification head is randomly initialized. The image processor will come in handy when writing the preprocessing pipeline for our dataset.
+
+```py
+>>> from transformers import VideoMAEImageProcessor, VideoMAEForVideoClassification
+
+>>> model_ckpt = "MCG-NJU/videomae-base"
+>>> image_processor = VideoMAEImageProcessor.from_pretrained(model_ckpt)
+>>> model = VideoMAEForVideoClassification.from_pretrained(
+... model_ckpt,
+... label2id=label2id,
+... id2label=id2label,
+... ignore_mismatched_sizes=True, # provide this in case you're planning to fine-tune an already fine-tuned checkpoint
+... )
+```
+
+While the model is loading, you might notice the following warning:
+
+```bash
+Some weights of the model checkpoint at MCG-NJU/videomae-base were not used when initializing VideoMAEForVideoClassification: [..., 'decoder.decoder_layers.1.attention.output.dense.bias', 'decoder.decoder_layers.2.attention.attention.key.weight']
+- This IS expected if you are initializing VideoMAEForVideoClassification from the checkpoint of a model trained on another task or with another architecture (e.g. initializing a BertForSequenceClassification model from a BertForPreTraining model).
+- This IS NOT expected if you are initializing VideoMAEForVideoClassification from the checkpoint of a model that you expect to be exactly identical (initializing a BertForSequenceClassification model from a BertForSequenceClassification model).
+Some weights of VideoMAEForVideoClassification were not initialized from the model checkpoint at MCG-NJU/videomae-base and are newly initialized: ['classifier.bias', 'classifier.weight']
+You should probably TRAIN this model on a down-stream task to be able to use it for predictions and inference.
+```
+
+The warning is telling us we are throwing away some weights (e.g. the weights and bias of the `classifier` layer) and randomly initializing some others (the weights and bias of a new `classifier` layer). This is expected in this case, because we are adding a new head for which we don't have pretrained weights, so the library warns us we should fine-tune this model before using it for inference, which is exactly what we are going to do.
+
+**Note** that [this checkpoint](https://huggingface.co/MCG-NJU/videomae-base-finetuned-kinetics) leads to better performance on this task as the checkpoint was obtained fine-tuning on a similar downstream task having considerable domain overlap. You can check out [this checkpoint](https://huggingface.co/sayakpaul/videomae-base-finetuned-kinetics-finetuned-ucf101-subset) which was obtained by fine-tuning `MCG-NJU/videomae-base-finetuned-kinetics`.
+
+## Prepare the datasets for training
+
+For preprocessing the videos, you will leverage the [PyTorchVideo library](https://pytorchvideo.org/). Start by importing the dependencies we need.
+
+```py
+>>> import pytorchvideo.data
+
+>>> from pytorchvideo.transforms import (
+... ApplyTransformToKey,
+... Normalize,
+... RandomShortSideScale,
+... RemoveKey,
+... ShortSideScale,
+... UniformTemporalSubsample,
+... )
+
+>>> from torchvision.transforms import (
+... Compose,
+... Lambda,
+... RandomCrop,
+... RandomHorizontalFlip,
+... Resize,
+... )
+```
+
+For the training dataset transformations, use a combination of uniform temporal subsampling, pixel normalization, random cropping, and random horizontal flipping. For the validation and evaluation dataset transformations, keep the same transformation chain except for random cropping and horizontal flipping. To learn more about the details of these transformations check out the [official documentation of PyTorchVideo](https://pytorchvideo.org).
+
+Use the `image_processor` associated with the pre-trained model to obtain the following information:
+
+* Image mean and standard deviation with which the video frame pixels will be normalized.
+* Spatial resolution to which the video frames will be resized.
+
+Start by defining some constants.
+
+```py
+>>> mean = image_processor.image_mean
+>>> std = image_processor.image_std
+>>> if "shortest_edge" in image_processor.size:
+... height = width = image_processor.size["shortest_edge"]
+>>> else:
+... height = image_processor.size["height"]
+... width = image_processor.size["width"]
+>>> resize_to = (height, width)
+
+>>> num_frames_to_sample = model.config.num_frames
+>>> sample_rate = 4
+>>> fps = 30
+>>> clip_duration = num_frames_to_sample * sample_rate / fps
+```
+
+Now, define the dataset-specific transformations and the datasets respectively. Starting with the training set:
+
+```py
+>>> train_transform = Compose(
+... [
+... ApplyTransformToKey(
+... key="video",
+... transform=Compose(
+... [
+... UniformTemporalSubsample(num_frames_to_sample),
+... Lambda(lambda x: x / 255.0),
+... Normalize(mean, std),
+... RandomShortSideScale(min_size=256, max_size=320),
+... RandomCrop(resize_to),
+... RandomHorizontalFlip(p=0.5),
+... ]
+... ),
+... ),
+... ]
+... )
+
+>>> train_dataset = pytorchvideo.data.Ucf101(
+... data_path=os.path.join(dataset_root_path, "train"),
+... clip_sampler=pytorchvideo.data.make_clip_sampler("random", clip_duration),
+... decode_audio=False,
+... transform=train_transform,
+... )
+```
+
+The same sequence of workflow can be applied to the validation and evaluation sets:
+
+```py
+>>> val_transform = Compose(
+... [
+... ApplyTransformToKey(
+... key="video",
+... transform=Compose(
+... [
+... UniformTemporalSubsample(num_frames_to_sample),
+... Lambda(lambda x: x / 255.0),
+... Normalize(mean, std),
+... Resize(resize_to),
+... ]
+... ),
+... ),
+... ]
+... )
+
+>>> val_dataset = pytorchvideo.data.Ucf101(
+... data_path=os.path.join(dataset_root_path, "val"),
+... clip_sampler=pytorchvideo.data.make_clip_sampler("uniform", clip_duration),
+... decode_audio=False,
+... transform=val_transform,
+... )
+
+>>> test_dataset = pytorchvideo.data.Ucf101(
+... data_path=os.path.join(dataset_root_path, "test"),
+... clip_sampler=pytorchvideo.data.make_clip_sampler("uniform", clip_duration),
+... decode_audio=False,
+... transform=val_transform,
+... )
+```
+
+**Note**: The above dataset pipelines are taken from the [official PyTorchVideo example](https://pytorchvideo.org/docs/tutorial_classification#dataset). We're using the [`pytorchvideo.data.Ucf101()`](https://pytorchvideo.readthedocs.io/en/latest/api/data/data.html#pytorchvideo.data.Ucf101) function because it's tailored for the UCF-101 dataset. Under the hood, it returns a [`pytorchvideo.data.labeled_video_dataset.LabeledVideoDataset`](https://pytorchvideo.readthedocs.io/en/latest/api/data/data.html#pytorchvideo.data.LabeledVideoDataset) object. `LabeledVideoDataset` class is the base class for all things video in the PyTorchVideo dataset. So, if you want to use a custom dataset not supported off-the-shelf by PyTorchVideo, you can extend the `LabeledVideoDataset` class accordingly. Refer to the `data` API [documentation to](https://pytorchvideo.readthedocs.io/en/latest/api/data/data.html) learn more. Also, if your dataset follows a similar structure (as shown above), then using the `pytorchvideo.data.Ucf101()` should work just fine.
+
+You can access the `num_videos` argument to know the number of videos in the dataset.
+
+```py
+>>> print(train_dataset.num_videos, val_dataset.num_videos, test_dataset.num_videos)
+# (300, 30, 75)
+```
+
+## Visualize the preprocessed video for better debugging
+
+```py
+>>> import imageio
+>>> import numpy as np
+>>> from IPython.display import Image
+
+>>> def unnormalize_img(img):
+... """Un-normalizes the image pixels."""
+... img = (img * std) + mean
+... img = (img * 255).astype("uint8")
+... return img.clip(0, 255)
+
+>>> def create_gif(video_tensor, filename="sample.gif"):
+... """Prepares a GIF from a video tensor.
+...
+... The video tensor is expected to have the following shape:
+... (num_frames, num_channels, height, width).
+... """
+... frames = []
+... for video_frame in video_tensor:
+... frame_unnormalized = unnormalize_img(video_frame.permute(1, 2, 0).numpy())
+... frames.append(frame_unnormalized)
+... kargs = {"duration": 0.25}
+... imageio.mimsave(filename, frames, "GIF", **kargs)
+... return filename
+
+>>> def display_gif(video_tensor, gif_name="sample.gif"):
+... """Prepares and displays a GIF from a video tensor."""
+... video_tensor = video_tensor.permute(1, 0, 2, 3)
+... gif_filename = create_gif(video_tensor, gif_name)
+... return Image(filename=gif_filename)
+
+>>> sample_video = next(iter(train_dataset))
+>>> video_tensor = sample_video["video"]
+>>> display_gif(video_tensor)
+```
+
+
+
+
+
+## Train the model
+
+Leverage [`Trainer`](https://huggingface.co/docs/transformers/main_classes/trainer) from 🤗 Transformers for training the model. To instantiate a `Trainer`, you need to define the training configuration and an evaluation metric. The most important is the [`TrainingArguments`](https://huggingface.co/transformers/main_classes/trainer.html#transformers.TrainingArguments), which is a class that contains all the attributes to configure the training. It requires an output folder name, which will be used to save the checkpoints of the model. It also helps sync all the information in the model repository on 🤗 Hub.
+
+Most of the training arguments are self-explanatory, but one that is quite important here is `remove_unused_columns=False`. This one will drop any features not used by the model's call function. By default it's `True` because usually it's ideal to drop unused feature columns, making it easier to unpack inputs into the model's call function. But, in this case, you need the unused features ('video' in particular) in order to create `pixel_values` (which is a mandatory key our model expects in its inputs).
+
+
+```py
+>>> from transformers import TrainingArguments, Trainer
+
+>>> model_name = model_ckpt.split("/")[-1]
+>>> new_model_name = f"{model_name}-finetuned-ucf101-subset"
+>>> num_epochs = 4
+
+>>> args = TrainingArguments(
+... new_model_name,
+... remove_unused_columns=False,
+... eval_strategy="epoch",
+... save_strategy="epoch",
+... learning_rate=5e-5,
+... per_device_train_batch_size=batch_size,
+... per_device_eval_batch_size=batch_size,
+... warmup_ratio=0.1,
+... logging_steps=10,
+... load_best_model_at_end=True,
+... metric_for_best_model="accuracy",
+... push_to_hub=True,
+... max_steps=(train_dataset.num_videos // batch_size) * num_epochs,
+... )
+```
+
+The dataset returned by `pytorchvideo.data.Ucf101()` doesn't implement the `__len__` method. As such, we must define `max_steps` when instantiating `TrainingArguments`.
+
+Next, you need to define a function to compute the metrics from the predictions, which will use the `metric` you'll load now. The only preprocessing you have to do is to take the argmax of our predicted logits:
+
+```py
+import evaluate
+
+metric = evaluate.load("accuracy")
+
+
+def compute_metrics(eval_pred):
+ predictions = np.argmax(eval_pred.predictions, axis=1)
+ return metric.compute(predictions=predictions, references=eval_pred.label_ids)
+```
+
+**A note on evaluation**:
+
+In the [VideoMAE paper](https://huggingface.co/papers/2203.12602), the authors use the following evaluation strategy. They evaluate the model on several clips from test videos and apply different crops to those clips and report the aggregate score. However, in the interest of simplicity and brevity, we don't consider that in this tutorial.
+
+Also, define a `collate_fn`, which will be used to batch examples together. Each batch consists of 2 keys, namely `pixel_values` and `labels`.
+
+```py
+>>> def collate_fn(examples):
+... # permute to (num_frames, num_channels, height, width)
+... pixel_values = torch.stack(
+... [example["video"].permute(1, 0, 2, 3) for example in examples]
+... )
+... labels = torch.tensor([example["label"] for example in examples])
+... return {"pixel_values": pixel_values, "labels": labels}
+```
+
+Then you just pass all of this along with the datasets to `Trainer`:
+
+```py
+>>> trainer = Trainer(
+... model,
+... args,
+... train_dataset=train_dataset,
+... eval_dataset=val_dataset,
+... processing_class=image_processor,
+... compute_metrics=compute_metrics,
+... data_collator=collate_fn,
+... )
+```
+
+You might wonder why you passed along the `image_processor` as a tokenizer when you preprocessed the data already. This is only to make sure the image processor configuration file (stored as JSON) will also be uploaded to the repo on the Hub.
+
+Now fine-tune our model by calling the `train` method:
+
+```py
+>>> train_results = trainer.train()
+```
+
+Once training is completed, share your model to the Hub with the [`~transformers.Trainer.push_to_hub`] method so everyone can use your model:
+
+```py
+>>> trainer.push_to_hub()
+```
+
+## Inference
+
+Great, now that you have fine-tuned a model, you can use it for inference!
+
+Load a video for inference:
+
+```py
+>>> sample_test_video = next(iter(test_dataset))
+```
+
+
+
+
+
+The simplest way to try out your fine-tuned model for inference is to use it in a [`pipeline`](https://huggingface.co/docs/transformers/main/en/main_classes/pipelines#transformers.VideoClassificationPipeline). Instantiate a `pipeline` for video classification with your model, and pass your video to it:
+
+```py
+>>> from transformers import pipeline
+
+>>> video_cls = pipeline(model="my_awesome_video_cls_model")
+>>> video_cls("https://huggingface.co/datasets/sayakpaul/ucf101-subset/resolve/main/v_BasketballDunk_g14_c06.avi")
+[{'score': 0.9272987842559814, 'label': 'BasketballDunk'},
+ {'score': 0.017777055501937866, 'label': 'BabyCrawling'},
+ {'score': 0.01663011871278286, 'label': 'BalanceBeam'},
+ {'score': 0.009560945443809032, 'label': 'BandMarching'},
+ {'score': 0.0068979403004050255, 'label': 'BaseballPitch'}]
+```
+
+You can also manually replicate the results of the `pipeline` if you'd like.
+
+
+```py
+>>> def run_inference(model, video):
+... # (num_frames, num_channels, height, width)
+... perumuted_sample_test_video = video.permute(1, 0, 2, 3)
+... inputs = {
+... "pixel_values": perumuted_sample_test_video.unsqueeze(0),
+... "labels": torch.tensor(
+... [sample_test_video["label"]]
+... ), # this can be skipped if you don't have labels available.
+... }
+
+... device = torch.device("cuda" if torch.cuda.is_available() else "cpu")
+... inputs = {k: v.to(device) for k, v in inputs.items()}
+... model = model.to(device)
+
+... # forward pass
+... with torch.no_grad():
+... outputs = model(**inputs)
+... logits = outputs.logits
+
+... return logits
+```
+
+Now, pass your input to the model and return the `logits`:
+
+```py
+>>> logits = run_inference(trained_model, sample_test_video["video"])
+```
+
+Decoding the `logits`, we get:
+
+```py
+>>> predicted_class_idx = logits.argmax(-1).item()
+>>> print("Predicted class:", model.config.id2label[predicted_class_idx])
+# Predicted class: BasketballDunk
+```
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/video_text_to_text.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/video_text_to_text.md
new file mode 100644
index 0000000000000000000000000000000000000000..a7aafdf1954771ce015c8fa622026feb278d08e3
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/tasks/video_text_to_text.md
@@ -0,0 +1,147 @@
+
+
+# Video-text-to-text
+
+[[open-in-colab]]
+
+Video-text-to-text models, also known as video language models or vision language models with video input, are language models that take a video input. These models can tackle various tasks, from video question answering to video captioning.
+
+These models have nearly the same architecture as [image-text-to-text](../image_text_to_text) models except for some changes to accept video data, since video data is essentially image frames with temporal dependencies. Some image-text-to-text models take in multiple images, but this alone is inadequate for a model to accept videos. Moreover, video-text-to-text models are often trained with all vision modalities. Each example might have videos, multiple videos, images and multiple images. Some of these models can also take interleaved inputs. For example, you can refer to a specific video inside a string of text by adding a video token in text like "What is happening in this video? `
 +
 +
 +
 +
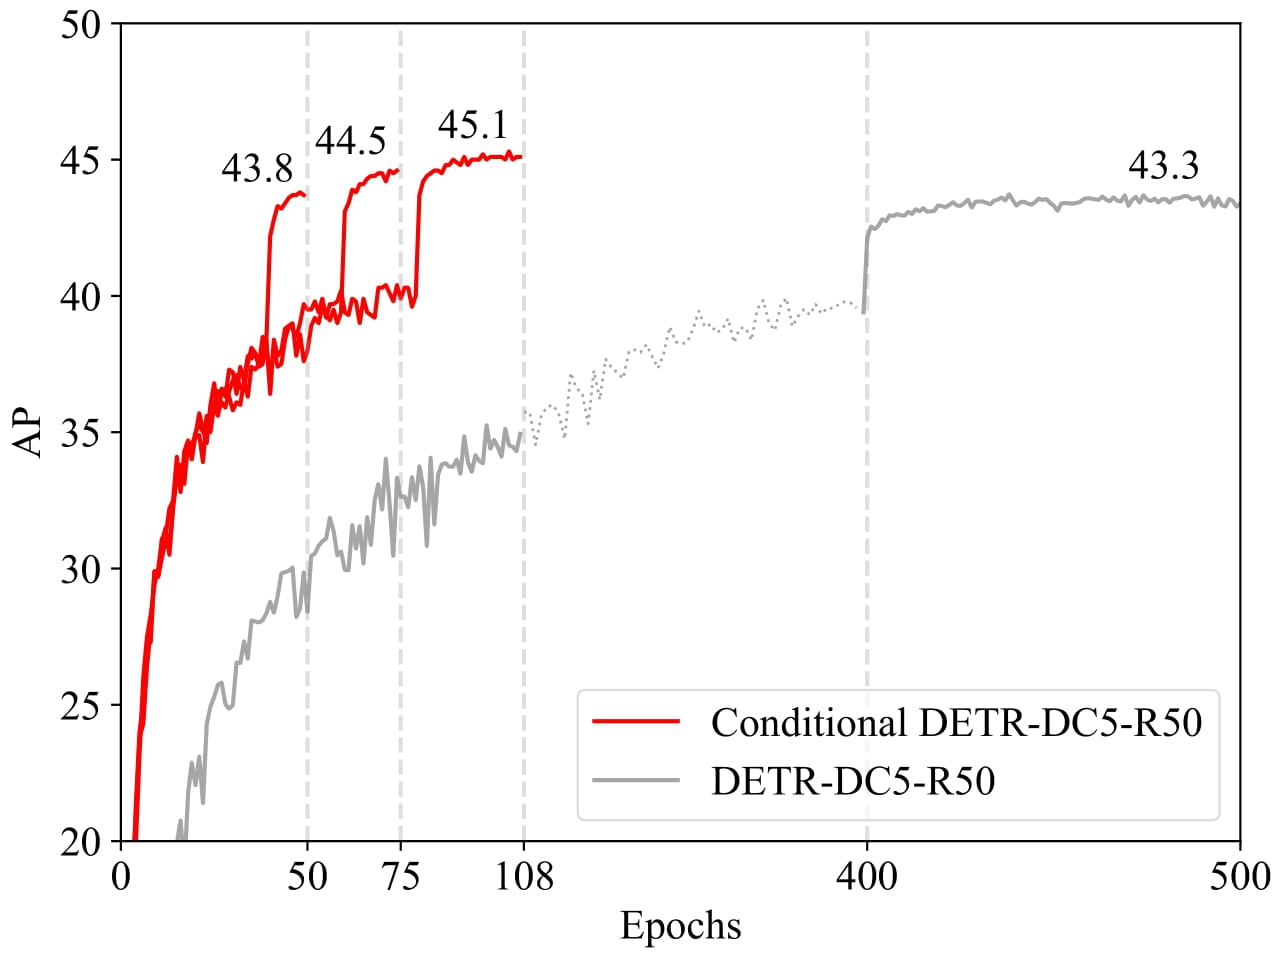 +
+ Conditional DETR shows much faster convergence compared to the original DETR. Taken from the original paper.
+
+This model was contributed by [DepuMeng](https://huggingface.co/DepuMeng). The original code can be found [here](https://github.com/Atten4Vis/ConditionalDETR).
+
+## Resources
+
+- Scripts for finetuning [`ConditionalDetrForObjectDetection`] with [`Trainer`] or [Accelerate](https://huggingface.co/docs/accelerate/index) can be found [here](https://github.com/huggingface/transformers/tree/main/examples/pytorch/object-detection).
+- See also: [Object detection task guide](../tasks/object_detection).
+
+## ConditionalDetrConfig
+
+[[autodoc]] ConditionalDetrConfig
+
+## ConditionalDetrImageProcessor
+
+[[autodoc]] ConditionalDetrImageProcessor
+ - preprocess
+
+## ConditionalDetrImageProcessorFast
+
+[[autodoc]] ConditionalDetrImageProcessorFast
+ - preprocess
+ - post_process_object_detection
+ - post_process_instance_segmentation
+ - post_process_semantic_segmentation
+ - post_process_panoptic_segmentation
+
+## ConditionalDetrFeatureExtractor
+
+[[autodoc]] ConditionalDetrFeatureExtractor
+ - __call__
+ - post_process_object_detection
+ - post_process_instance_segmentation
+ - post_process_semantic_segmentation
+ - post_process_panoptic_segmentation
+
+## ConditionalDetrModel
+
+[[autodoc]] ConditionalDetrModel
+ - forward
+
+## ConditionalDetrForObjectDetection
+
+[[autodoc]] ConditionalDetrForObjectDetection
+ - forward
+
+## ConditionalDetrForSegmentation
+
+[[autodoc]] ConditionalDetrForSegmentation
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/convbert.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/convbert.md
new file mode 100644
index 0000000000000000000000000000000000000000..1fbfb809638018601e6c5662b94c5329f1799a29
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/convbert.md
@@ -0,0 +1,142 @@
+
+*This model was released on 2020-08-06 and added to Hugging Face Transformers on 2021-01-27.*
+
+# ConvBERT
+
+
 +
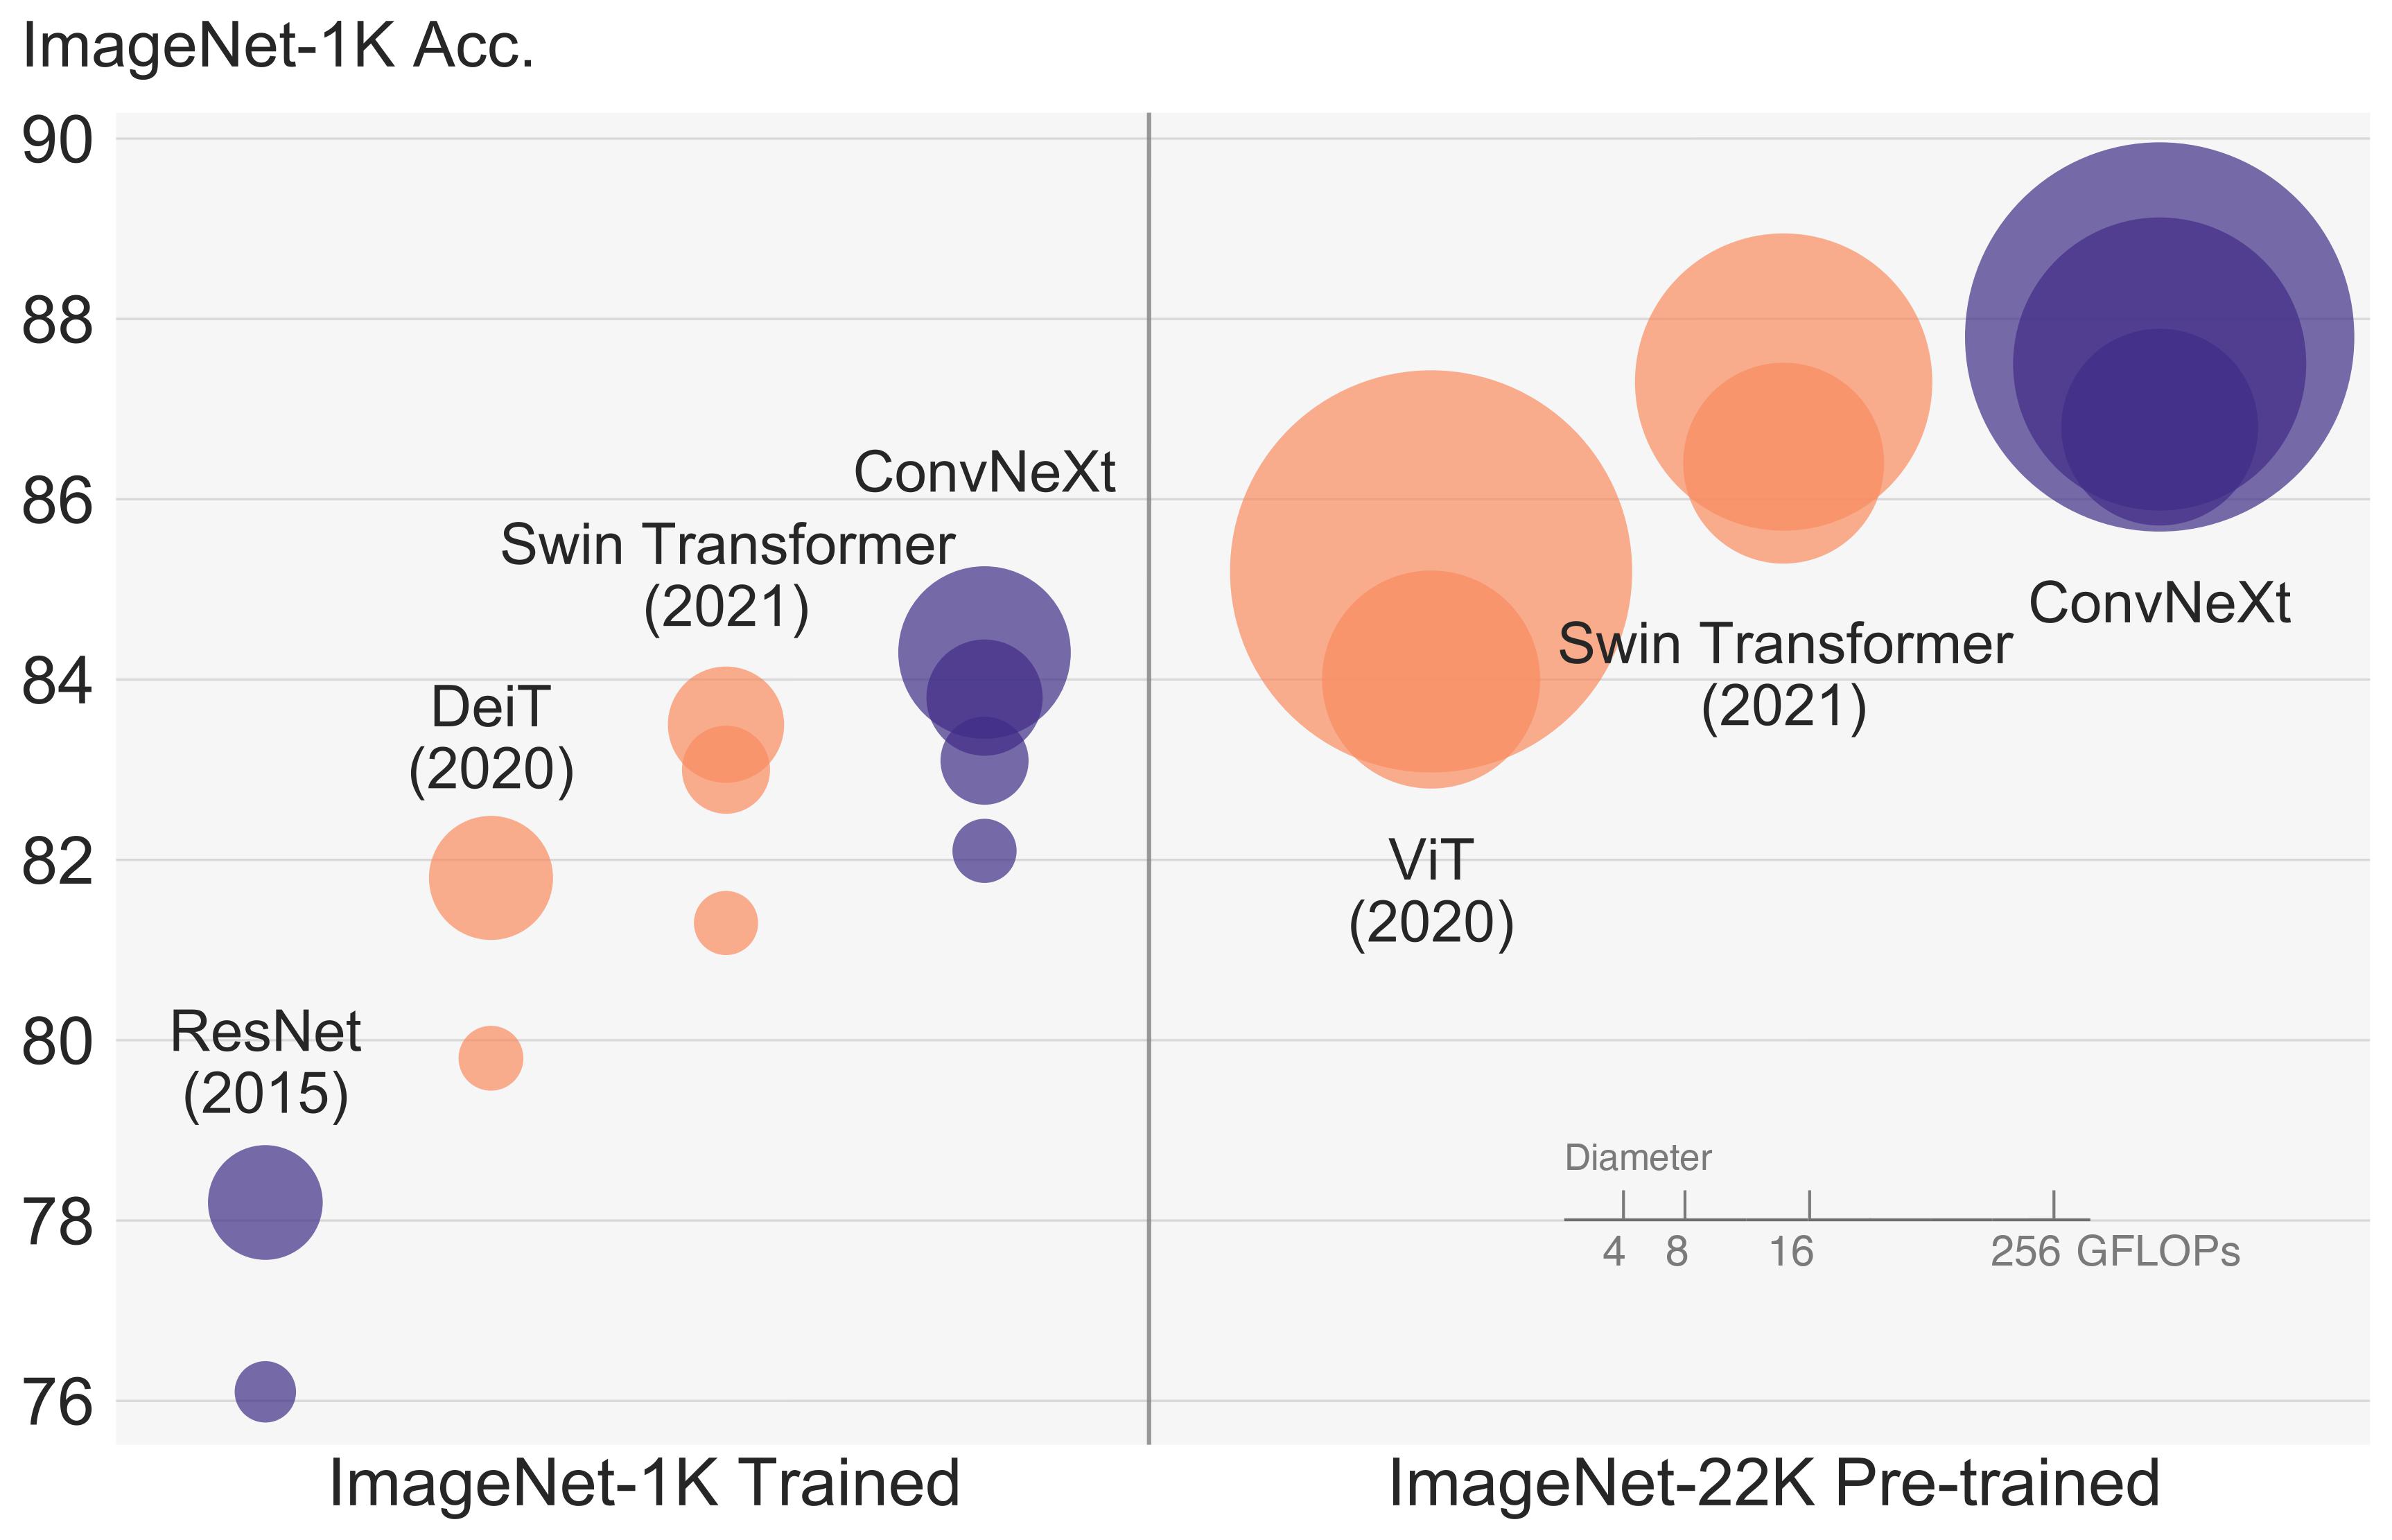 +
+ ConvNeXT architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). TensorFlow version of the model was contributed by [ariG23498](https://github.com/ariG23498),
+[gante](https://github.com/gante), and [sayakpaul](https://github.com/sayakpaul) (equal contribution). The original code can be found [here](https://github.com/facebookresearch/ConvNeXt).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with ConvNeXT.
+
+
 +
+ ConvNeXt V2 architecture. Taken from the original paper.
+
+This model was contributed by [adirik](https://huggingface.co/adirik). The original code can be found [here](https://github.com/facebookresearch/ConvNeXt-V2).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with ConvNeXt V2.
+
+
 +
 +
 +
 +
+The abstract from the paper is the following:
+
+*We present in this paper a novel query formulation using dynamic anchor boxes
+for DETR (DEtection TRansformer) and offer a deeper understanding of the role
+of queries in DETR. This new formulation directly uses box coordinates as queries
+in Transformer decoders and dynamically updates them layer-by-layer. Using box
+coordinates not only helps using explicit positional priors to improve the query-to-feature similarity and eliminate the slow training convergence issue in DETR,
+but also allows us to modulate the positional attention map using the box width
+and height information. Such a design makes it clear that queries in DETR can be
+implemented as performing soft ROI pooling layer-by-layer in a cascade manner.
+As a result, it leads to the best performance on MS-COCO benchmark among
+the DETR-like detection models under the same setting, e.g., AP 45.7% using
+ResNet50-DC5 as backbone trained in 50 epochs. We also conducted extensive
+experiments to confirm our analysis and verify the effectiveness of our methods.*
+
+This model was contributed by [davidhajdu](https://huggingface.co/davidhajdu).
+The original code can be found [here](https://github.com/IDEA-Research/DAB-DETR).
+
+## How to Get Started with the Model
+
+Use the code below to get started with the model.
+
+```python
+import torch
+import requests
+
+from PIL import Image
+from transformers import AutoModelForObjectDetection, AutoImageProcessor
+
+url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+image = Image.open(requests.get(url, stream=True).raw)
+
+image_processor = AutoImageProcessor.from_pretrained("IDEA-Research/dab-detr-resnet-50")
+model = AutoModelForObjectDetection.from_pretrained("IDEA-Research/dab-detr-resnet-50")
+
+inputs = image_processor(images=image, return_tensors="pt")
+
+with torch.no_grad():
+ outputs = model(**inputs)
+
+results = image_processor.post_process_object_detection(outputs, target_sizes=torch.tensor([image.size[::-1]]), threshold=0.3)
+
+for result in results:
+ for score, label_id, box in zip(result["scores"], result["labels"], result["boxes"]):
+ score, label = score.item(), label_id.item()
+ box = [round(i, 2) for i in box.tolist()]
+ print(f"{model.config.id2label[label]}: {score:.2f} {box}")
+```
+This should output
+```
+cat: 0.87 [14.7, 49.39, 320.52, 469.28]
+remote: 0.86 [41.08, 72.37, 173.39, 117.2]
+cat: 0.86 [344.45, 19.43, 639.85, 367.86]
+remote: 0.61 [334.27, 75.93, 367.92, 188.81]
+couch: 0.59 [-0.04, 1.34, 639.9, 477.09]
+```
+
+There are three other ways to instantiate a DAB-DETR model (depending on what you prefer):
+
+Option 1: Instantiate DAB-DETR with pre-trained weights for entire model
+```py
+>>> from transformers import DabDetrForObjectDetection
+
+>>> model = DabDetrForObjectDetection.from_pretrained("IDEA-Research/dab-detr-resnet-50")
+```
+
+Option 2: Instantiate DAB-DETR with randomly initialized weights for Transformer, but pre-trained weights for backbone
+```py
+>>> from transformers import DabDetrConfig, DabDetrForObjectDetection
+
+>>> config = DabDetrConfig()
+>>> model = DabDetrForObjectDetection(config)
+```
+Option 3: Instantiate DAB-DETR with randomly initialized weights for backbone + Transformer
+```py
+>>> config = DabDetrConfig(use_pretrained_backbone=False)
+>>> model = DabDetrForObjectDetection(config)
+```
+
+
+## DabDetrConfig
+
+[[autodoc]] DabDetrConfig
+
+## DabDetrModel
+
+[[autodoc]] DabDetrModel
+ - forward
+
+## DabDetrForObjectDetection
+
+[[autodoc]] DabDetrForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dac.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dac.md
new file mode 100644
index 0000000000000000000000000000000000000000..e17cc69fc37aaab3b271d69710d422c29211d0a1
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dac.md
@@ -0,0 +1,85 @@
+
+*This model was released on 2023-06-11 and added to Hugging Face Transformers on 2024-08-19.*
+
+# DAC
+
+
 +
+ Deformable DETR architecture. Taken from the original paper.
+
+You can find all the available Deformable DETR checkpoints under the [SenseTime](https://huggingface.co/SenseTime) organization.
+
+> [!TIP]
+> This model was contributed by [nielsr](https://huggingface.co/nielsr).
+>
+> Click on the Deformable DETR models in the right sidebar for more examples of how to apply Deformable DETR to different object detection and segmentation tasks.
+
+The example below demonstrates how to perform object detection with the [`Pipeline`] and the [`AutoModel`] class.
+
+
 +
+ Depth Anything overview. Taken from the original paper.
+
+The Depth Anything models were contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/DepthAnything/Depth-Anything-V2).
+
+## Usage example
+
+There are 2 main ways to use Depth Anything V2: either using the pipeline API, which abstracts away all the complexity for you, or by using the `DepthAnythingForDepthEstimation` class yourself.
+
+### Pipeline API
+
+The pipeline allows to use the model in a few lines of code:
+
+```python
+>>> from transformers import pipeline
+>>> from PIL import Image
+>>> import requests
+
+>>> # load pipe
+>>> pipe = pipeline(task="depth-estimation", model="depth-anything/Depth-Anything-V2-Small-hf")
+
+>>> # load image
+>>> url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> # inference
+>>> depth = pipe(image)["depth"]
+```
+
+### Using the model yourself
+
+If you want to do the pre- and post-processing yourself, here's how to do that:
+
+```python
+>>> from transformers import AutoImageProcessor, AutoModelForDepthEstimation
+>>> import torch
+>>> import numpy as np
+>>> from PIL import Image
+>>> import requests
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> image_processor = AutoImageProcessor.from_pretrained("depth-anything/Depth-Anything-V2-Small-hf")
+>>> model = AutoModelForDepthEstimation.from_pretrained("depth-anything/Depth-Anything-V2-Small-hf")
+
+>>> # prepare image for the model
+>>> inputs = image_processor(images=image, return_tensors="pt")
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> # interpolate to original size and visualize the prediction
+>>> post_processed_output = image_processor.post_process_depth_estimation(
+... outputs,
+... target_sizes=[(image.height, image.width)],
+... )
+
+>>> predicted_depth = post_processed_output[0]["predicted_depth"]
+>>> depth = (predicted_depth - predicted_depth.min()) / (predicted_depth.max() - predicted_depth.min())
+>>> depth = depth.detach().cpu().numpy() * 255
+>>> depth = Image.fromarray(depth.astype("uint8"))
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Depth Anything.
+
+- [Monocular depth estimation task guide](../tasks/monocular_depth_estimation)
+- [Depth Anything V2 demo](https://huggingface.co/spaces/depth-anything/Depth-Anything-V2).
+- A notebook showcasing inference with [`DepthAnythingForDepthEstimation`] can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/Depth%20Anything/Predicting_depth_in_an_image_with_Depth_Anything.ipynb). 🌎
+- [Core ML conversion of the `small` variant for use on Apple Silicon](https://huggingface.co/apple/coreml-depth-anything-v2-small).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## DepthAnythingConfig
+
+[[autodoc]] DepthAnythingConfig
+
+## DepthAnythingForDepthEstimation
+
+[[autodoc]] DepthAnythingForDepthEstimation
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/depth_pro.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/depth_pro.md
new file mode 100644
index 0000000000000000000000000000000000000000..db0d27d1d308577852a9e02a93b939ce6d13719e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/depth_pro.md
@@ -0,0 +1,188 @@
+
+*This model was released on 2024-10-02 and added to Hugging Face Transformers on 2025-02-10.*
+
+# DepthPro
+
+
 +
+ DepthPro Outputs. Taken from the official code.
+
+This model was contributed by [geetu040](https://github.com/geetu040). The original code can be found [here](https://github.com/apple/ml-depth-pro).
+
+## Usage Tips
+
+The DepthPro model processes an input image by first downsampling it at multiple scales and splitting each scaled version into patches. These patches are then encoded using a shared Vision Transformer (ViT)-based Dinov2 patch encoder, while the full image is processed by a separate image encoder. The extracted patch features are merged into feature maps, upsampled, and fused using a DPT-like decoder to generate the final depth estimation. If enabled, an additional Field of View (FOV) encoder processes the image for estimating the camera's field of view, aiding in depth accuracy.
+
+```py
+>>> import requests
+>>> from PIL import Image
+>>> import torch
+>>> from transformers import DepthProImageProcessorFast, DepthProForDepthEstimation, infer_device
+
+>>> device = infer_device()
+
+>>> url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> image_processor = DepthProImageProcessorFast.from_pretrained("apple/DepthPro-hf")
+>>> model = DepthProForDepthEstimation.from_pretrained("apple/DepthPro-hf").to(device)
+
+>>> inputs = image_processor(images=image, return_tensors="pt").to(model.device)
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> post_processed_output = image_processor.post_process_depth_estimation(
+... outputs, target_sizes=[(image.height, image.width)],
+... )
+
+>>> field_of_view = post_processed_output[0]["field_of_view"]
+>>> focal_length = post_processed_output[0]["focal_length"]
+>>> depth = post_processed_output[0]["predicted_depth"]
+>>> depth = (depth - depth.min()) / depth.max()
+>>> depth = depth * 255.
+>>> depth = depth.detach().cpu().numpy()
+>>> depth = Image.fromarray(depth.astype("uint8"))
+```
+
+### Architecture and Configuration
+
+
 +
+ DepthPro architecture. Taken from the original paper.
+
+The `DepthProForDepthEstimation` model uses a `DepthProEncoder`, for encoding the input image and a `FeatureFusionStage` for fusing the output features from encoder.
+
+The `DepthProEncoder` further uses two encoders:
+- `patch_encoder`
+ - Input image is scaled with multiple ratios, as specified in the `scaled_images_ratios` configuration.
+ - Each scaled image is split into smaller **patches** of size `patch_size` with overlapping areas determined by `scaled_images_overlap_ratios`.
+ - These patches are processed by the **`patch_encoder`**
+- `image_encoder`
+ - Input image is also rescaled to `patch_size` and processed by the **`image_encoder`**
+
+Both these encoders can be configured via `patch_model_config` and `image_model_config` respectively, both of which are separate `Dinov2Model` by default.
+
+Outputs from both encoders (`last_hidden_state`) and selected intermediate states (`hidden_states`) from **`patch_encoder`** are fused by a `DPT`-based `FeatureFusionStage` for depth estimation.
+
+### Field-of-View (FOV) Prediction
+
+The network is supplemented with a focal length estimation head. A small convolutional head ingests frozen features from the depth estimation network and task-specific features from a separate ViT image encoder to predict the horizontal angular field-of-view.
+
+The `use_fov_model` parameter in `DepthProConfig` controls whether **FOV prediction** is enabled. By default, it is set to `False` to conserve memory and computation. When enabled, the **FOV encoder** is instantiated based on the `fov_model_config` parameter, which defaults to a `Dinov2Model`. The `use_fov_model` parameter can also be passed when initializing the `DepthProForDepthEstimation` model.
+
+The pretrained model at checkpoint `apple/DepthPro-hf` uses the FOV encoder. To use the pretrained-model without FOV encoder, set `use_fov_model=False` when loading the model, which saves computation.
+```py
+>>> from transformers import DepthProForDepthEstimation
+>>> model = DepthProForDepthEstimation.from_pretrained("apple/DepthPro-hf", use_fov_model=False)
+```
+
+To instantiate a new model with FOV encoder, set `use_fov_model=True` in the config.
+```py
+>>> from transformers import DepthProConfig, DepthProForDepthEstimation
+>>> config = DepthProConfig(use_fov_model=True)
+>>> model = DepthProForDepthEstimation(config)
+```
+
+Or set `use_fov_model=True` when initializing the model, which overrides the value in config.
+```py
+>>> from transformers import DepthProConfig, DepthProForDepthEstimation
+>>> config = DepthProConfig()
+>>> model = DepthProForDepthEstimation(config, use_fov_model=True)
+```
+
+### Using Scaled Dot Product Attention (SDPA)
+
+PyTorch includes a native scaled dot-product attention (SDPA) operator as part of `torch.nn.functional`. This function
+encompasses several implementations that can be applied depending on the inputs and the hardware in use. See the
+[official documentation](https://pytorch.org/docs/stable/generated/torch.nn.functional.scaled_dot_product_attention.html)
+or the [GPU Inference](https://huggingface.co/docs/transformers/main/en/perf_infer_gpu_one#pytorch-scaled-dot-product-attention)
+page for more information.
+
+SDPA is used by default for `torch>=2.1.1` when an implementation is available, but you may also set
+`attn_implementation="sdpa"` in `from_pretrained()` to explicitly request SDPA to be used.
+
+```py
+from transformers import DepthProForDepthEstimation
+model = DepthProForDepthEstimation.from_pretrained("apple/DepthPro-hf", attn_implementation="sdpa", torch_dtype=torch.float16)
+```
+
+For the best speedups, we recommend loading the model in half-precision (e.g. `torch.float16` or `torch.bfloat16`).
+
+On a local benchmark (A100-40GB, PyTorch 2.3.0, OS Ubuntu 22.04) with `float32` and `google/vit-base-patch16-224` model, we saw the following speedups during inference.
+
+| Batch size | Average inference time (ms), eager mode | Average inference time (ms), sdpa model | Speed up, Sdpa / Eager (x) |
+|--------------|-------------------------------------------|-------------------------------------------|------------------------------|
+| 1 | 7 | 6 | 1.17 |
+| 2 | 8 | 6 | 1.33 |
+| 4 | 8 | 6 | 1.33 |
+| 8 | 8 | 6 | 1.33 |
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with DepthPro:
+
+- Research Paper: [Depth Pro: Sharp Monocular Metric Depth in Less Than a Second](https://huggingface.co/papers/2410.02073)
+- Official Implementation: [apple/ml-depth-pro](https://github.com/apple/ml-depth-pro)
+- DepthPro Inference Notebook: [DepthPro Inference](https://github.com/qubvel/transformers-notebooks/blob/main/notebooks/DepthPro_inference.ipynb)
+- DepthPro for Super Resolution and Image Segmentation
+ - Read blog on Medium: [Depth Pro: Beyond Depth](https://medium.com/@raoarmaghanshakir040/depth-pro-beyond-depth-9d822fc557ba)
+ - Code on Github: [geetu040/depthpro-beyond-depth](https://github.com/geetu040/depthpro-beyond-depth)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## DepthProConfig
+
+[[autodoc]] DepthProConfig
+
+## DepthProImageProcessor
+
+[[autodoc]] DepthProImageProcessor
+ - preprocess
+ - post_process_depth_estimation
+
+## DepthProImageProcessorFast
+
+[[autodoc]] DepthProImageProcessorFast
+ - preprocess
+ - post_process_depth_estimation
+
+## DepthProModel
+
+[[autodoc]] DepthProModel
+ - forward
+
+## DepthProForDepthEstimation
+
+[[autodoc]] DepthProForDepthEstimation
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deta.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deta.md
new file mode 100644
index 0000000000000000000000000000000000000000..0dda1c891791dabb4f9ab0323686298d351db387
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/deta.md
@@ -0,0 +1,78 @@
+
+*This model was released on 2022-12-12 and added to Hugging Face Transformers on 2023-06-20.*
+
+# DETA
+
+
 +
+ DETA overview. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/jozhang97/DETA).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with DETA.
+
+- Demo notebooks for DETA can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/DETA).
+- Scripts for finetuning [`DetaForObjectDetection`] with [`Trainer`] or [Accelerate](https://huggingface.co/docs/accelerate/index) can be found [here](https://github.com/huggingface/transformers/tree/main/examples/pytorch/object-detection).
+- See also: [Object detection task guide](../tasks/object_detection).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## DetaConfig
+
+[[autodoc]] DetaConfig
+
+## DetaImageProcessor
+
+[[autodoc]] DetaImageProcessor
+ - preprocess
+ - post_process_object_detection
+
+## DetaModel
+
+[[autodoc]] DetaModel
+ - forward
+
+## DetaForObjectDetection
+
+[[autodoc]] DetaForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/detr.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/detr.md
new file mode 100644
index 0000000000000000000000000000000000000000..86c42c8adf584ac6f220cb8f7aa24712868200dd
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/detr.md
@@ -0,0 +1,206 @@
+
+*This model was released on 2020-05-26 and added to Hugging Face Transformers on 2021-06-09.*
+
+
 +
 +
+ Visualization of attention maps of various models trained with vs. without registers. Taken from the original paper.
+
+Tips:
+
+- Usage of DINOv2 with Registers is identical to DINOv2 without, you'll just get better performance.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/facebookresearch/dinov2).
+
+
+## Dinov2WithRegistersConfig
+
+[[autodoc]] Dinov2WithRegistersConfig
+
+## Dinov2WithRegistersModel
+
+[[autodoc]] Dinov2WithRegistersModel
+ - forward
+
+## Dinov2WithRegistersForImageClassification
+
+[[autodoc]] Dinov2WithRegistersForImageClassification
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dinov3.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dinov3.md
new file mode 100644
index 0000000000000000000000000000000000000000..b3f2067fe92dfee76d8d90034a854577c220792c
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/dinov3.md
@@ -0,0 +1,181 @@
+
+
+
 +
 +
+You can find all the original DiT checkpoints under the [Microsoft](https://huggingface.co/microsoft?search_models=dit) organization.
+
+> [!TIP]
+> Refer to the [BEiT](./beit) docs for more examples of how to apply DiT to different vision tasks.
+
+The example below demonstrates how to classify an image with [`Pipeline`] or the [`AutoModel`] class.
+
+
 +
+As shown in the figure below, the sequence transformation part of the Doge architecture uses `Dynamic Mask Attention`, which can be understood as using self-attention related to value states during training, and using state-space without past state decay during inference, to solve the problem of existing Transformers or SSMs getting lost in long text. The state transformation part of Doge uses `Cross Domain Mixture of Experts`, which consists of dense linear layers and sparse embedding layers, and can additionally increase sparse parameters to continue training from dense weight checkpoints without retraining the entire model, thereby reducing the cost of continuous iteration of the model. In addition, Doge also uses `RMSNorm` and `Residual` with learnable parameters to adapt the gradient range of deep models.
+
+Checkout all Doge model checkpoints [here](https://huggingface.co/collections/SmallDoge/doge-slm-679cc991f027c4a3abbded4a).
+
+
+## Usage
+
+
 +
+ DPT architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found [here](https://github.com/isl-org/DPT).
+
+## Usage tips
+
+DPT is compatible with the [`AutoBackbone`] class. This allows to use the DPT framework with various computer vision backbones available in the library, such as [`VitDetBackbone`] or [`Dinov2Backbone`]. One can create it as follows:
+
+```python
+from transformers import Dinov2Config, DPTConfig, DPTForDepthEstimation
+
+# initialize with a Transformer-based backbone such as DINOv2
+# in that case, we also specify `reshape_hidden_states=False` to get feature maps of shape (batch_size, num_channels, height, width)
+backbone_config = Dinov2Config.from_pretrained("facebook/dinov2-base", out_features=["stage1", "stage2", "stage3", "stage4"], reshape_hidden_states=False)
+
+config = DPTConfig(backbone_config=backbone_config)
+model = DPTForDepthEstimation(config=config)
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with DPT.
+
+- Demo notebooks for [`DPTForDepthEstimation`] can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/DPT).
+
+- [Semantic segmentation task guide](../tasks/semantic_segmentation)
+- [Monocular depth estimation task guide](../tasks/monocular_depth_estimation)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## DPTConfig
+
+[[autodoc]] DPTConfig
+
+## DPTFeatureExtractor
+
+[[autodoc]] DPTFeatureExtractor
+ - __call__
+ - post_process_semantic_segmentation
+
+## DPTImageProcessor
+
+[[autodoc]] DPTImageProcessor
+ - preprocess
+
+## DPTImageProcessorFast
+
+[[autodoc]] DPTImageProcessorFast
+ - preprocess
+ - post_process_semantic_segmentation
+ - post_process_depth_estimation
+
+## DPTModel
+
+[[autodoc]] DPTModel
+ - forward
+
+## DPTForDepthEstimation
+
+[[autodoc]] DPTForDepthEstimation
+ - forward
+
+## DPTForSemanticSegmentation
+
+[[autodoc]] DPTForSemanticSegmentation
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/efficientformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/efficientformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..320834a439b8dd47de86b7ca6529b3e22b87ac71
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/efficientformer.md
@@ -0,0 +1,110 @@
+
+*This model was released on 2022-06-02 and added to Hugging Face Transformers on 2023-06-20.*
+
+# EfficientFormer
+
+
 +
 +
 +
 +
 +
 +
 +
 +
+ GIT architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/microsoft/GenerativeImage2Text).
+
+## Usage tips
+
+- GIT is implemented in a very similar way to GPT-2, the only difference being that the model is also conditioned on `pixel_values`.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with GIT.
+
+- Demo notebooks regarding inference + fine-tuning GIT on custom data can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/GIT).
+- See also: [Causal language modeling task guide](../tasks/language_modeling)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we will review it.
+The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## GitVisionConfig
+
+[[autodoc]] GitVisionConfig
+
+## GitVisionModel
+
+[[autodoc]] GitVisionModel
+ - forward
+
+## GitConfig
+
+[[autodoc]] GitConfig
+ - all
+
+## GitProcessor
+
+[[autodoc]] GitProcessor
+ - __call__
+
+## GitModel
+
+[[autodoc]] GitModel
+ - forward
+
+## GitForCausalLM
+
+[[autodoc]] GitForCausalLM
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm.md
new file mode 100644
index 0000000000000000000000000000000000000000..ca50c32da21b62922da09ac306728f4faa980591
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/glm.md
@@ -0,0 +1,107 @@
+
+*This model was released on 2024-06-18 and added to Hugging Face Transformers on 2024-10-18.*
+
+# GLM
+
+
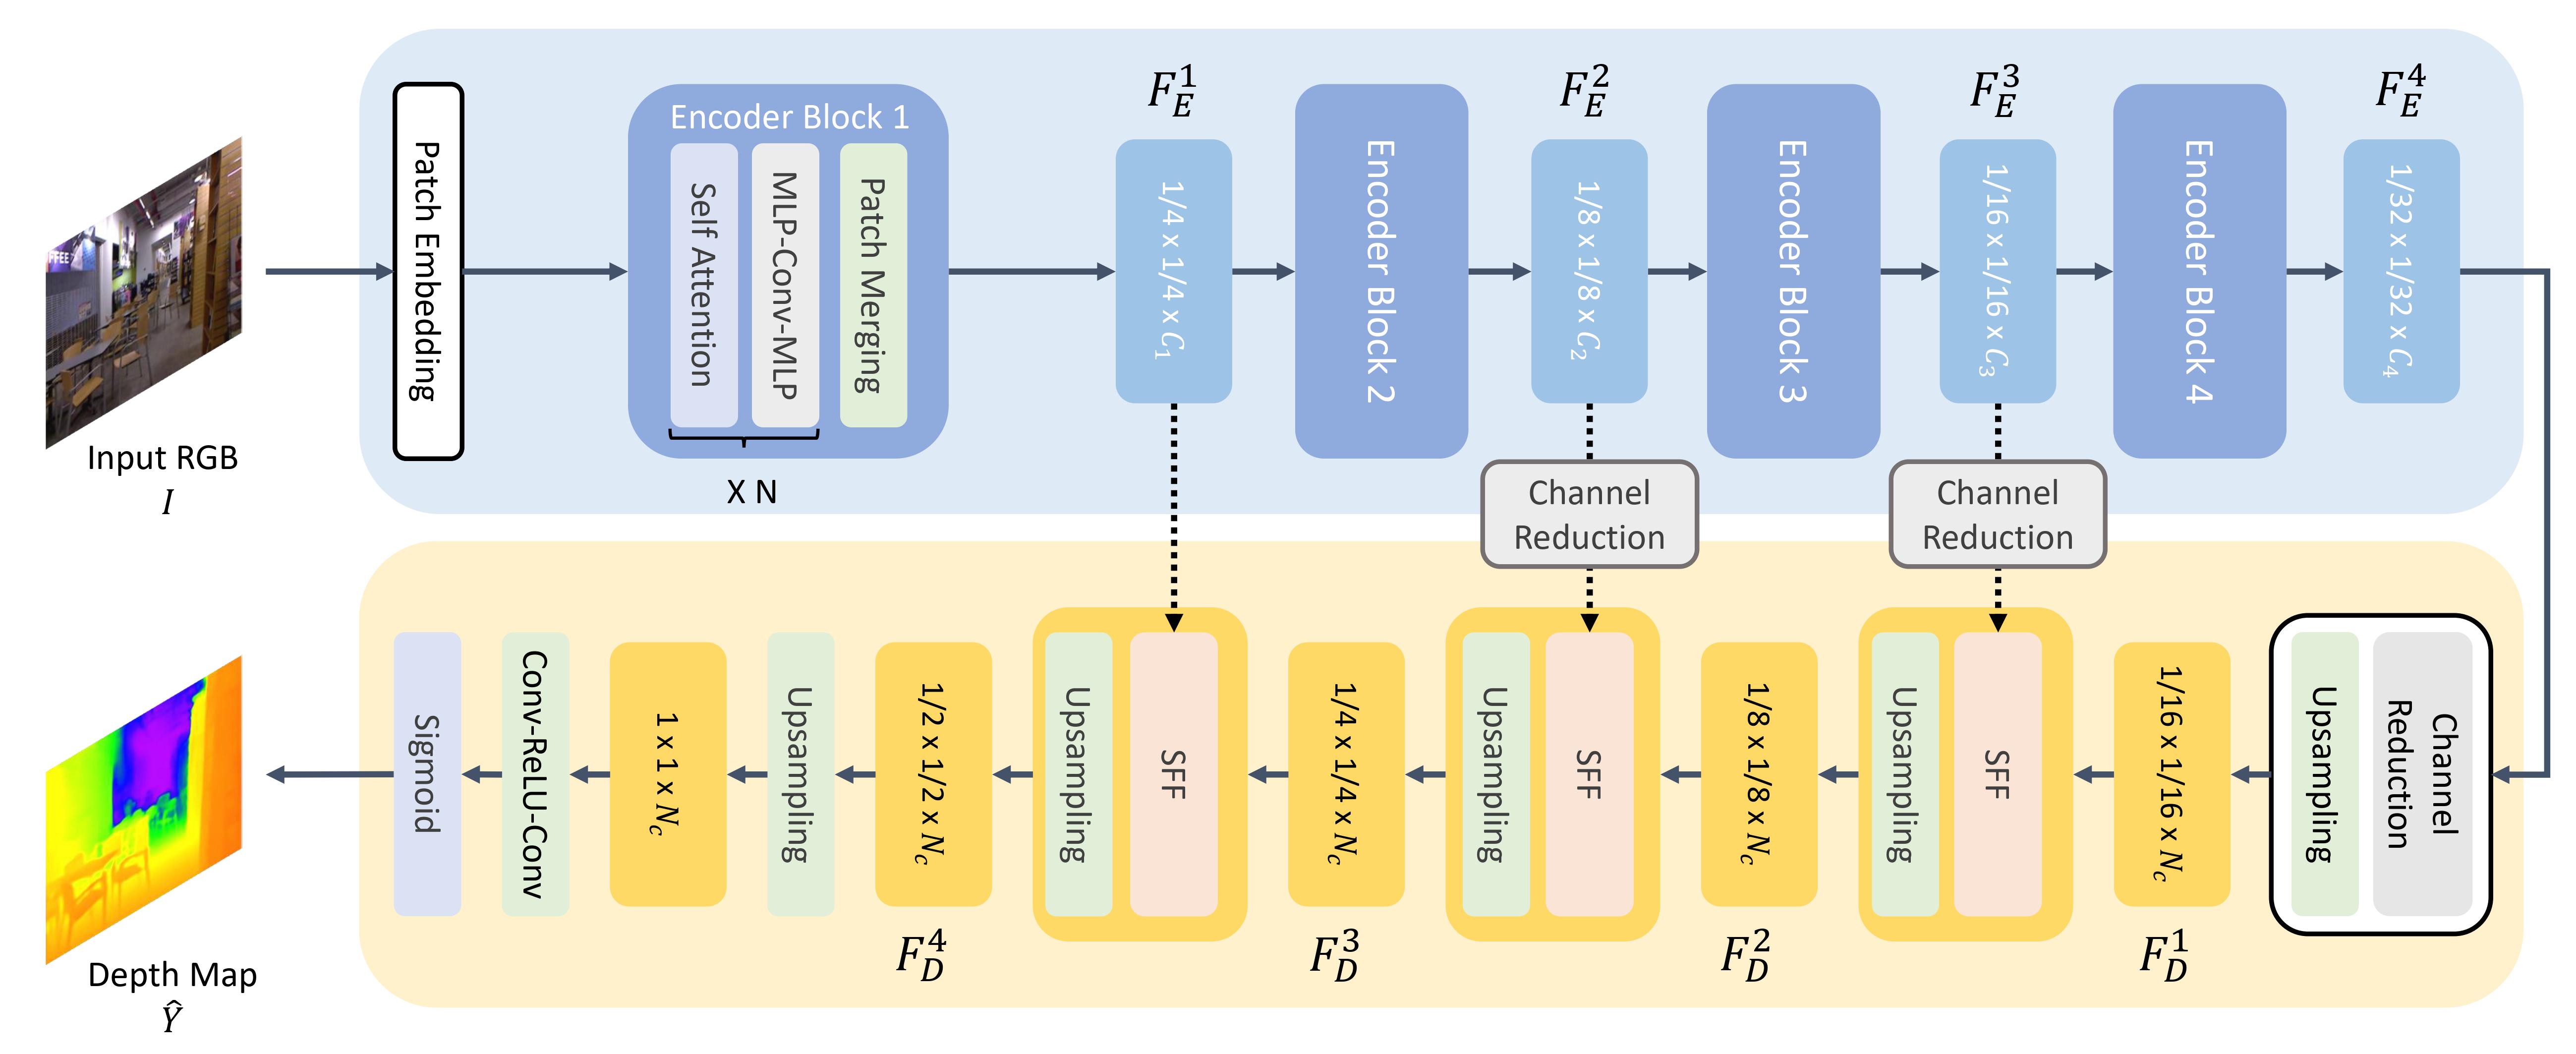 +
+ Summary of the approach. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found [here](https://github.com/vinvino02/GLPDepth).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with GLPN.
+
+- Demo notebooks for [`GLPNForDepthEstimation`] can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/GLPN).
+- [Monocular depth estimation task guide](../tasks/monocular_depth_estimation)
+
+## GLPNConfig
+
+[[autodoc]] GLPNConfig
+
+## GLPNFeatureExtractor
+
+[[autodoc]] GLPNFeatureExtractor
+ - __call__
+
+## GLPNImageProcessor
+
+[[autodoc]] GLPNImageProcessor
+ - preprocess
+
+## GLPNModel
+
+[[autodoc]] GLPNModel
+ - forward
+
+## GLPNForDepthEstimation
+
+[[autodoc]] GLPNForDepthEstimation
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/got_ocr2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/got_ocr2.md
new file mode 100644
index 0000000000000000000000000000000000000000..e1f7f1d430e94623488c6c4bdc6bb9e09131bbe6
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/got_ocr2.md
@@ -0,0 +1,288 @@
+
+*This model was released on 2024-09-03 and added to Hugging Face Transformers on 2025-01-31.*
+
+# GOT-OCR2
+
+
 +
+ GOT-OCR2 training stages. Taken from the original paper.
+
+
+Tips:
+
+GOT-OCR2 works on a wide range of tasks, including plain document OCR, scene text OCR, formatted document OCR, and even OCR for tables, charts, mathematical formulas, geometric shapes, molecular formulas and sheet music. While this implementation of the model will only output plain text, the outputs can be further processed to render the desired format, with packages like `pdftex`, `mathpix`, `matplotlib`, `tikz`, `verovio` or `pyecharts`.
+The model can also be used for interactive OCR, where the user can specify the region to be recognized by providing the coordinates or the color of the region's bounding box.
+
+This model was contributed by [yonigozlan](https://huggingface.co/yonigozlan).
+The original code can be found [here](https://github.com/Ucas-HaoranWei/GOT-OCR2.0).
+
+## Usage example
+
+### Plain text inference
+
+```python
+>>> import torch
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, infer_device
+
+>>> device = infer_device()
+>>> model = AutoModelForImageTextToText.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", device_map=device)
+>>> processor = AutoProcessor.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", use_fast=True)
+
+>>> image = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/image_ocr.jpg"
+>>> inputs = processor(image, return_tensors="pt", device=device).to(device)
+
+>>> generate_ids = model.generate(
+... **inputs,
+... do_sample=False,
+... tokenizer=processor.tokenizer,
+... stop_strings="<|im_end|>",
+... max_new_tokens=4096,
+... )
+
+>>> processor.decode(generate_ids[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+"R&D QUALITY IMPROVEMENT\nSUGGESTION/SOLUTION FORM\nName/Phone Ext. : (...)"
+```
+
+### Plain text inference batched
+
+```python
+>>> import torch
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, infer_device
+
+>>> device = infer_device()
+>>> model = AutoModelForImageTextToText.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", device_map=device)
+>>> processor = AutoProcessor.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", use_fast=True)
+
+>>> image1 = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/multi_box.png"
+>>> image2 = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/image_ocr.jpg"
+
+>>> inputs = processor([image1, image2], return_tensors="pt", device=device).to(device)
+
+>>> generate_ids = model.generate(
+... **inputs,
+... do_sample=False,
+... tokenizer=processor.tokenizer,
+... stop_strings="<|im_end|>",
+... max_new_tokens=4,
+... )
+
+>>> processor.batch_decode(generate_ids[:, inputs["input_ids"].shape[1] :], skip_special_tokens=True)
+["Reducing the number", "R&D QUALITY"]
+```
+
+### Formatted text inference
+
+GOT-OCR2 can also generate formatted text, such as markdown or LaTeX. Here is an example of how to generate formatted text:
+
+```python
+>>> import torch
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, infer_device
+
+>>> device = infer_device()
+>>> model = AutoModelForImageTextToText.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", device_map=device)
+>>> processor = AutoProcessor.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", use_fast=True)
+
+>>> image = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/latex.png"
+>>> inputs = processor(image, return_tensors="pt", format=True, device=device).to(device)
+
+>>> generate_ids = model.generate(
+... **inputs,
+... do_sample=False,
+... tokenizer=processor.tokenizer,
+... stop_strings="<|im_end|>",
+... max_new_tokens=4096,
+... )
+
+>>> processor.decode(generate_ids[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+"\\author{\nHanwen Jiang* \\(\\quad\\) Arjun Karpur \\({ }^{\\dagger} \\quad\\) Bingyi Cao \\({ }^{\\dagger} \\quad\\) (...)"
+```
+
+### Inference on multiple pages
+
+Although it might be reasonable in most cases to use a “for loop” for multi-page processing, some text data with formatting across several pages make it necessary to process all pages at once. GOT introduces a multi-page OCR (without “for loop”) feature, where multiple pages can be processed by the model at once, with the output being one continuous text.
+Here is an example of how to process multiple pages at once:
+
+
+```python
+>>> import torch
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, infer_device
+
+>>> device = infer_device()
+>>> model = AutoModelForImageTextToText.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", device_map=device)
+>>> processor = AutoProcessor.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", use_fast=True)
+
+>>> image1 = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/page1.png"
+>>> image2 = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/page2.png"
+>>> inputs = processor([image1, image2], return_tensors="pt", multi_page=True, format=True, device=device).to(device)
+
+>>> generate_ids = model.generate(
+... **inputs,
+... do_sample=False,
+... tokenizer=processor.tokenizer,
+... stop_strings="<|im_end|>",
+... max_new_tokens=4096,
+... )
+
+>>> processor.decode(generate_ids[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+"\\title{\nGeneral OCR Theory: Towards OCR-2.0 via a Unified End-to-end Model\n}\n\\author{\nHaoran Wei (...)"
+```
+
+### Inference on cropped patches
+
+GOT supports a 1024×1024 input resolution, which is sufficient for most OCR tasks, such as scene OCR or processing A4-sized PDF pages. However, certain scenarios, like horizontally stitched two-page PDFs commonly found in academic papers or images with unusual aspect ratios, can lead to accuracy issues when processed as a single image. To address this, GOT can dynamically crop an image into patches, process them all at once, and merge the results for better accuracy with such inputs.
+Here is an example of how to process cropped patches:
+
+```python
+>>> import torch
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, infer_device
+
+>>> device = infer_device()
+>>> model = AutoModelForImageTextToText.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", torch_dtype=torch.bfloat16, device_map=device)
+>>> processor = AutoProcessor.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", use_fast=True)
+
+>>> image = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/one_column.png"
+>>> inputs = processor(image, return_tensors="pt", format=True, crop_to_patches=True, max_patches=3, device=device).to(device)
+
+>>> generate_ids = model.generate(
+... **inputs,
+... do_sample=False,
+... tokenizer=processor.tokenizer,
+... stop_strings="<|im_end|>",
+... max_new_tokens=4096,
+... )
+
+>>> processor.decode(generate_ids[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+"on developing architectural improvements to make learnable matching methods generalize.\nMotivated by the above observations, (...)"
+```
+
+### Inference on a specific region
+
+GOT supports interactive OCR, where the user can specify the region to be recognized by providing the coordinates or the color of the region's bounding box. Here is an example of how to process a specific region:
+
+```python
+>>> import torch
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText
+
+>>> device = infer_device()
+>>> model = AutoModelForImageTextToText.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", device_map=device)
+>>> processor = AutoProcessor.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", use_fast=True)
+
+>>> image = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/multi_box.png"
+>>> inputs = processor(image, return_tensors="pt", color="green", device=device).to(device) # or box=[x1, y1, x2, y2] for coordinates (image pixels)
+
+>>> generate_ids = model.generate(
+... **inputs,
+... do_sample=False,
+... tokenizer=processor.tokenizer,
+... stop_strings="<|im_end|>",
+... max_new_tokens=4096,
+... )
+
+>>> processor.decode(generate_ids[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+"You should keep in mind what features from the module should be used, especially \nwhen you’re planning to sell a template."
+```
+
+### Inference on general OCR data example: sheet music
+
+Although this implementation of the model will only output plain text, the outputs can be further processed to render the desired format, with packages like `pdftex`, `mathpix`, `matplotlib`, `tikz`, `verovio` or `pyecharts`.
+Here is an example of how to process sheet music:
+
+```python
+>>> import torch
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, infer_device
+>>> import verovio
+
+>>> device = infer_device()
+>>> model = AutoModelForImageTextToText.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", device_map=device)
+>>> processor = AutoProcessor.from_pretrained("stepfun-ai/GOT-OCR-2.0-hf", use_fast=True)
+
+>>> image = "https://huggingface.co/datasets/hf-internal-testing/fixtures_got_ocr/resolve/main/sheet_music.png"
+>>> inputs = processor(image, return_tensors="pt", format=True, device=device).to(device)
+
+>>> generate_ids = model.generate(
+... **inputs,
+... do_sample=False,
+... tokenizer=processor.tokenizer,
+... stop_strings="<|im_end|>",
+... max_new_tokens=4096,
+... )
+
+>>> outputs = processor.decode(generate_ids[0, inputs["input_ids"].shape[1]:], skip_special_tokens=True)
+>>> tk = verovio.toolkit()
+>>> tk.loadData(outputs)
+>>> tk.setOptions(
+... {
+... "pageWidth": 2100,
+... "pageHeight": 800,
+... "footer": "none",
+... "barLineWidth": 0.5,
+... "beamMaxSlope": 15,
+... "staffLineWidth": 0.2,
+... "spacingStaff": 6,
+... }
+... )
+>>> tk.getPageCount()
+>>> svg = tk.renderToSVG()
+>>> svg = svg.replace('overflow="inherit"', 'overflow="visible"')
+>>> with open("output.svg", "w") as f:
+>>> f.write(svg)
+```
+
 +
+## GotOcr2Config
+
+[[autodoc]] GotOcr2Config
+
+## GotOcr2VisionConfig
+
+[[autodoc]] GotOcr2VisionConfig
+
+## GotOcr2ImageProcessor
+
+[[autodoc]] GotOcr2ImageProcessor
+
+## GotOcr2ImageProcessorFast
+
+[[autodoc]] GotOcr2ImageProcessorFast
+
+## GotOcr2Processor
+
+[[autodoc]] GotOcr2Processor
+
+## GotOcr2Model
+
+[[autodoc]] GotOcr2Model
+
+## GotOcr2ForConditionalGeneration
+
+[[autodoc]] GotOcr2ForConditionalGeneration
+ - forward
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt-sw3.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt-sw3.md
new file mode 100644
index 0000000000000000000000000000000000000000..82de953418356a32b397efffac4df80560fd2325
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/gpt-sw3.md
@@ -0,0 +1,77 @@
+
+*This model was released on 2022-06-25 and added to Hugging Face Transformers on 2022-12-12.*
+
+# GPT-Sw3
+
+
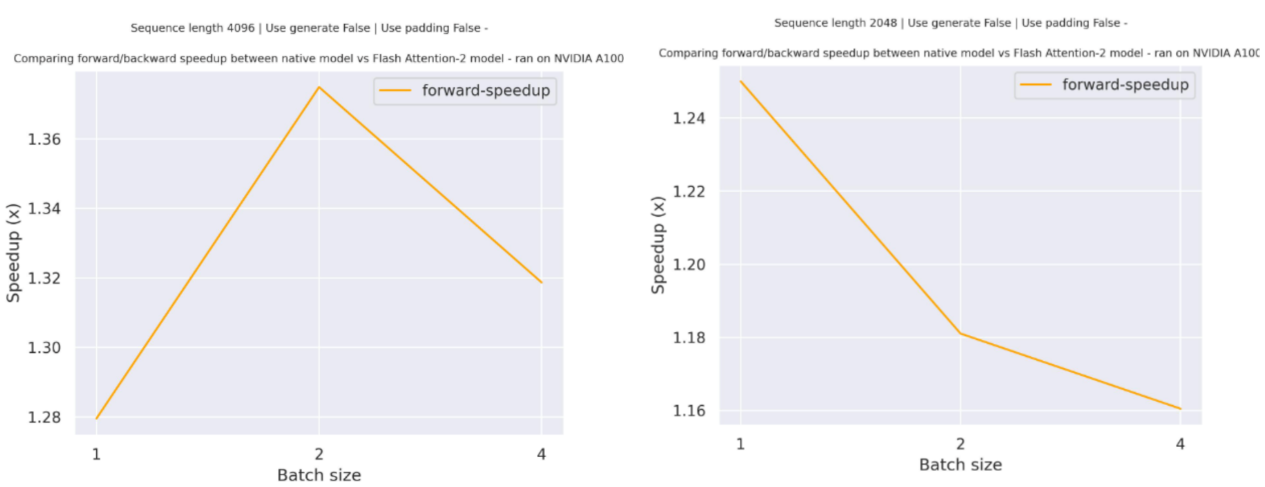 +
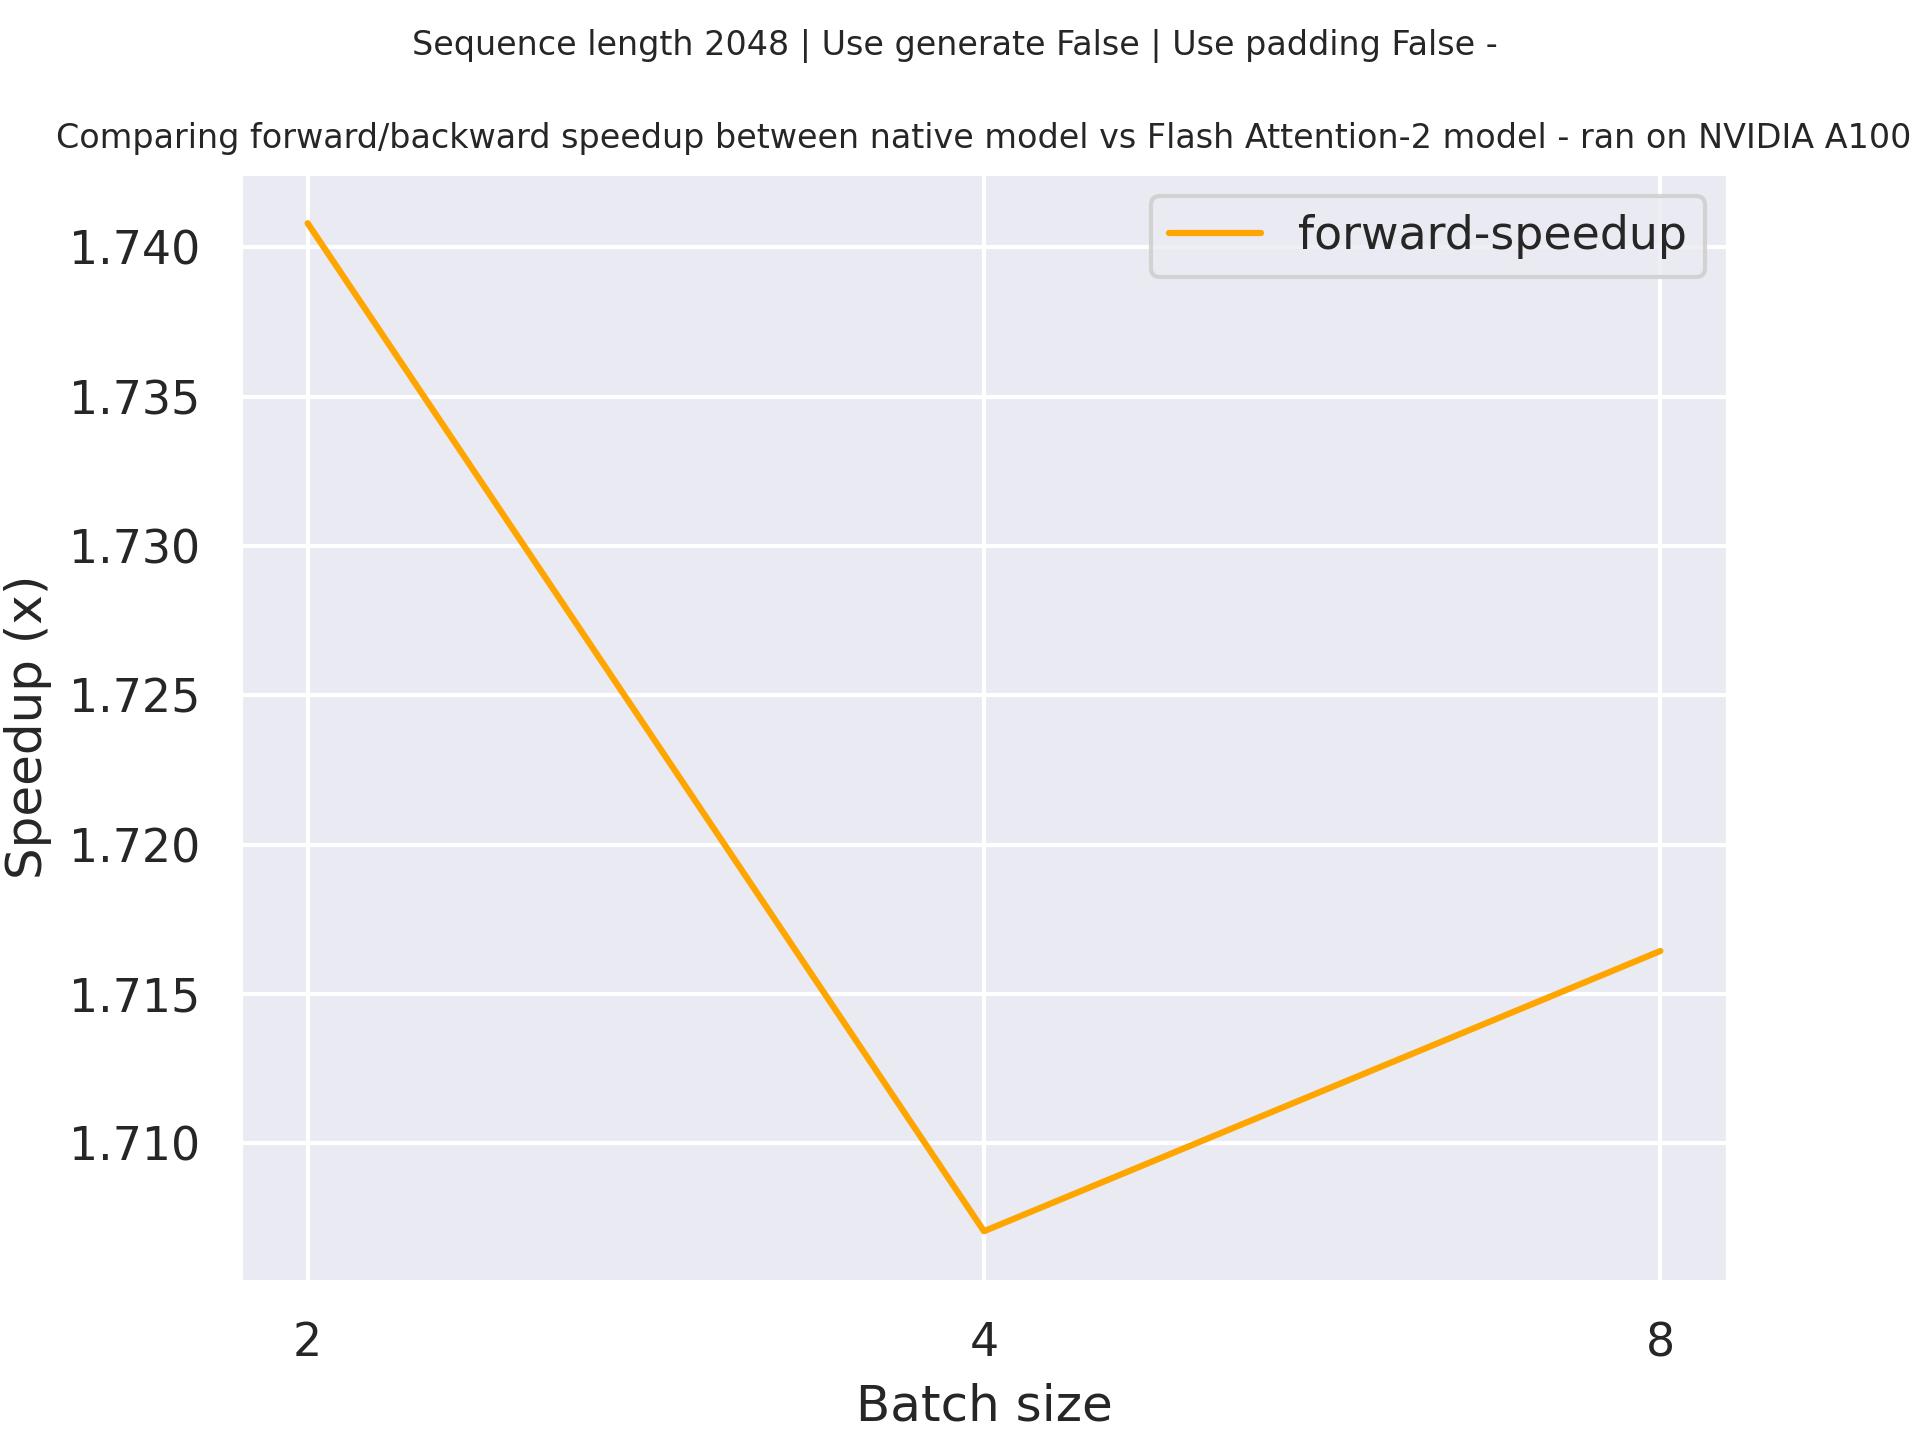 +
 +
+
 +
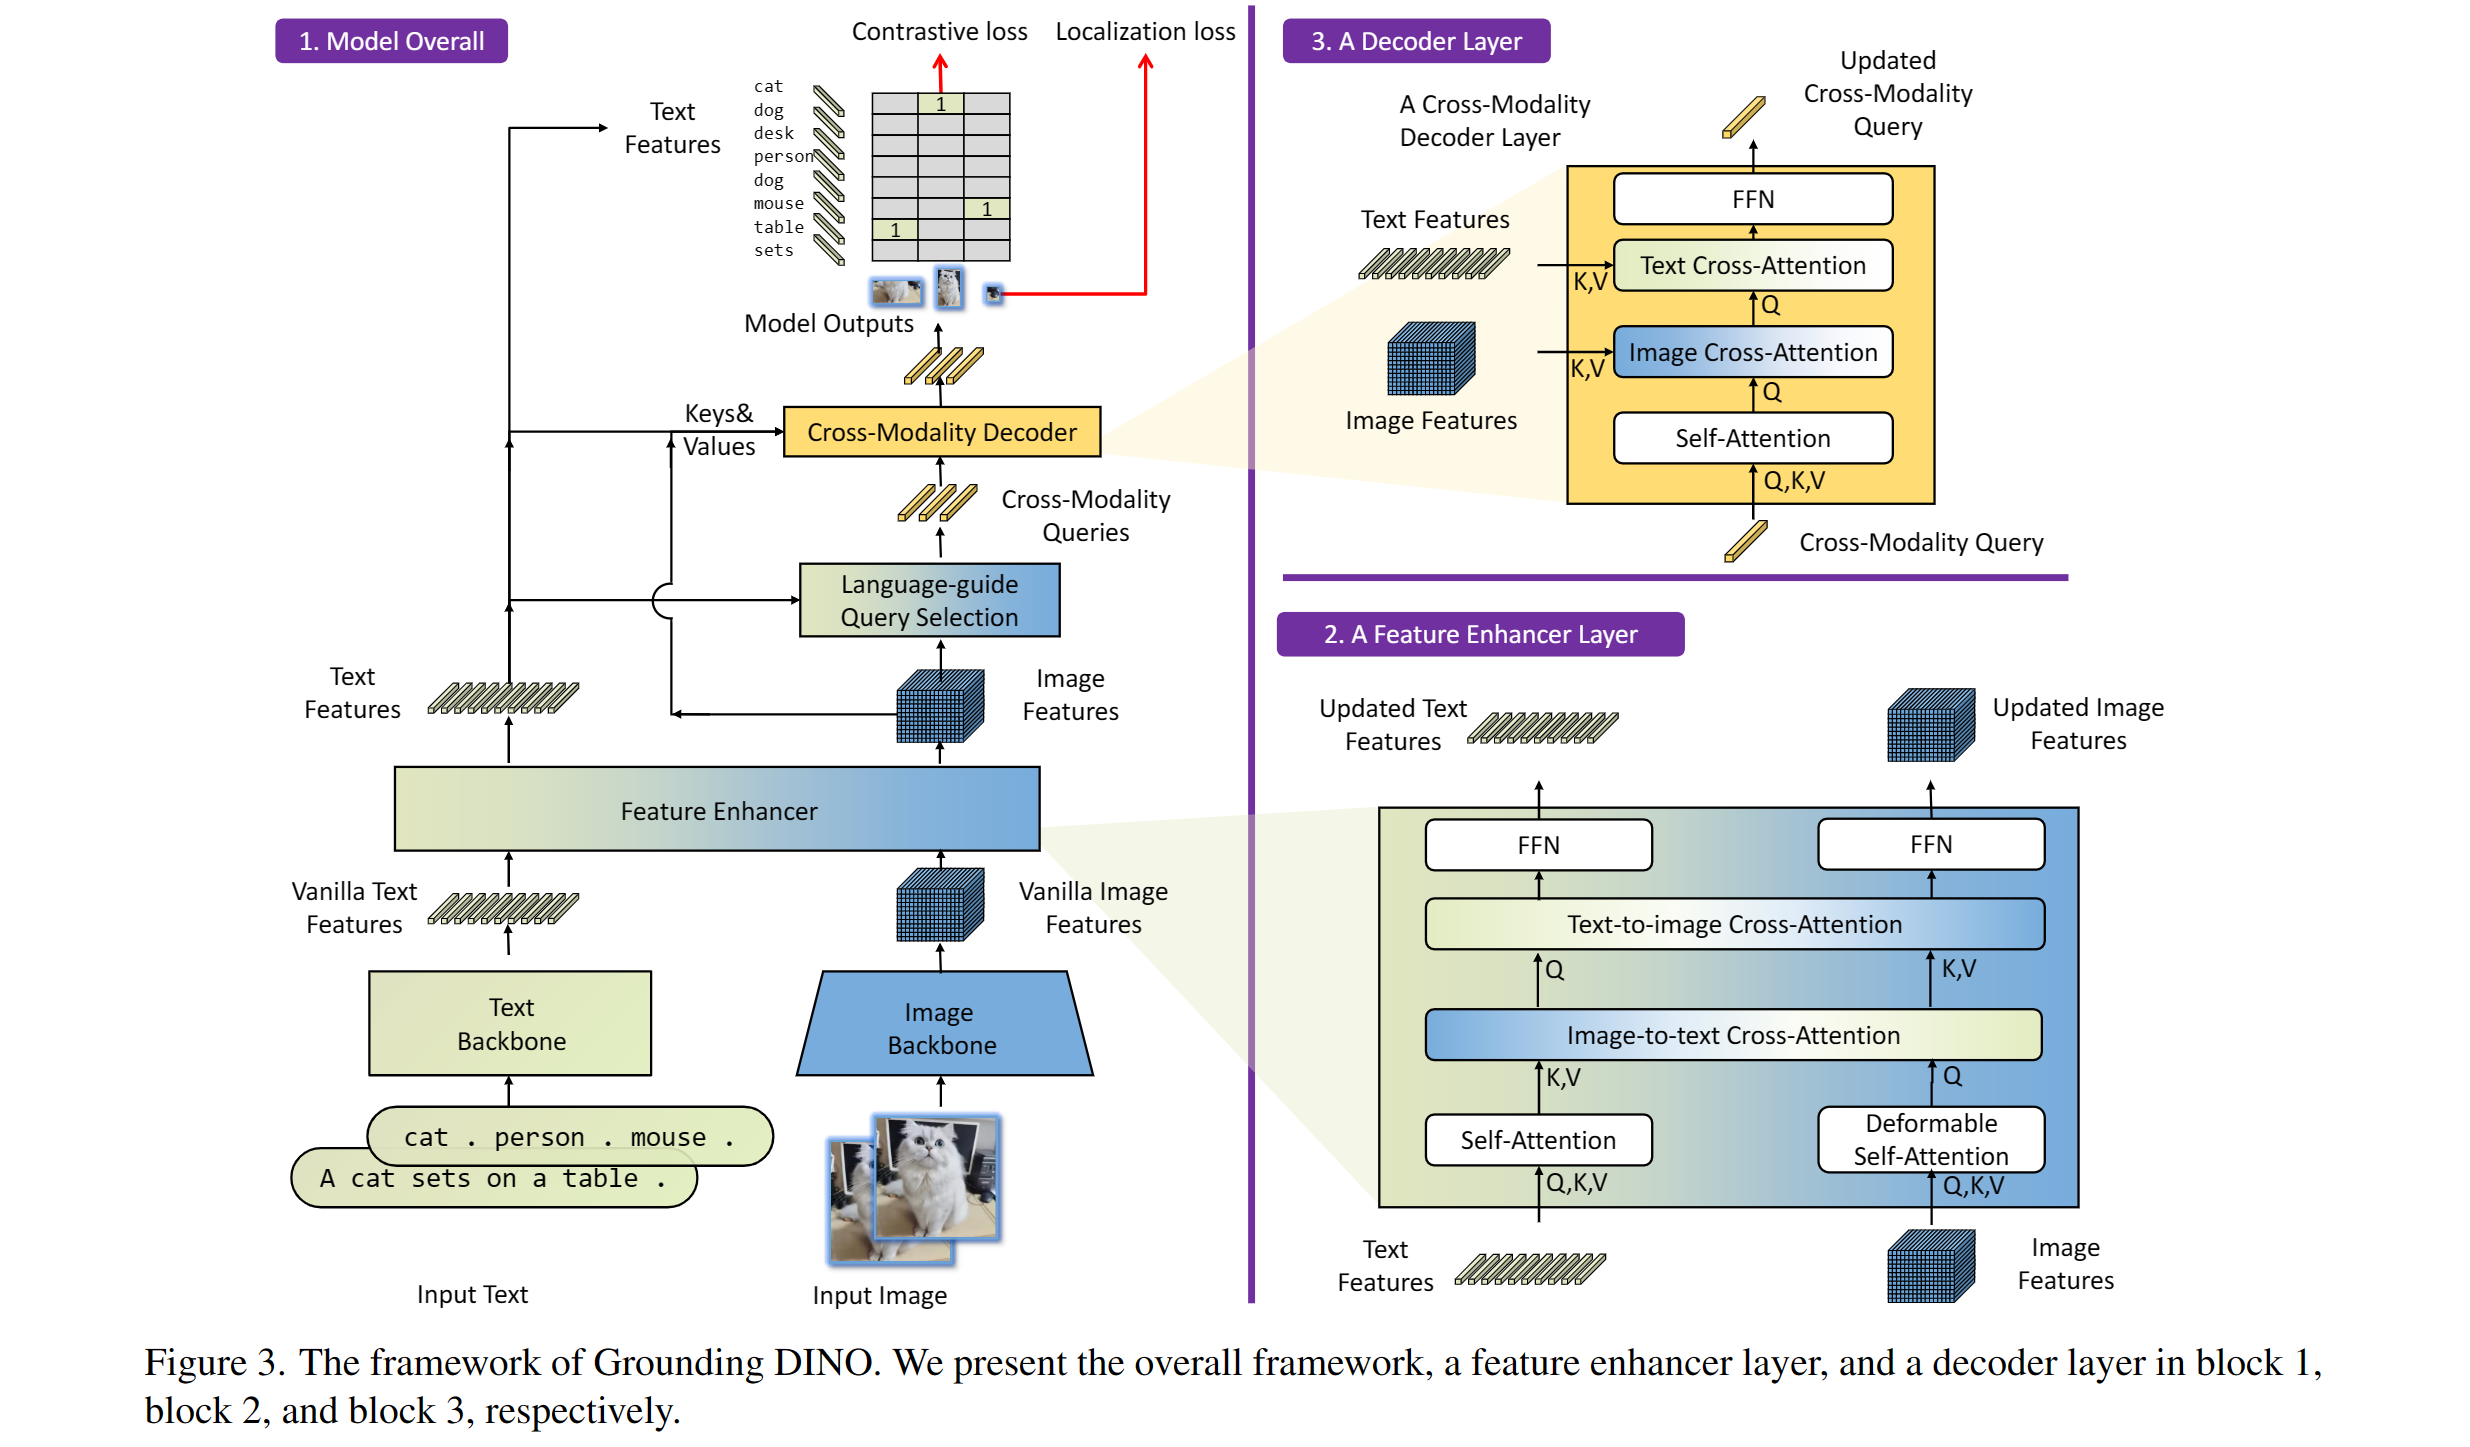 +
+ Grounding DINO overview. Taken from the original paper.
+
+This model was contributed by [EduardoPacheco](https://huggingface.co/EduardoPacheco) and [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/IDEA-Research/GroundingDINO).
+
+## Usage tips
+
+- One can use [`GroundingDinoProcessor`] to prepare image-text pairs for the model.
+- To separate classes in the text use a period e.g. "a cat. a dog."
+- When using multiple classes (e.g. `"a cat. a dog."`), use `post_process_grounded_object_detection` from [`GroundingDinoProcessor`] to post process outputs. Since, the labels returned from `post_process_object_detection` represent the indices from the model dimension where prob > threshold.
+
+Here's how to use the model for zero-shot object detection:
+
+```python
+>>> import requests
+
+>>> import torch
+>>> from PIL import Image
+>>> from transformers import AutoProcessor, AutoModelForZeroShotObjectDetection
+
+>>> model_id = "IDEA-Research/grounding-dino-tiny"
+>>> device = "cuda"
+
+>>> processor = AutoProcessor.from_pretrained(model_id)
+>>> model = AutoModelForZeroShotObjectDetection.from_pretrained(model_id).to(device)
+
+>>> image_url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(image_url, stream=True).raw)
+>>> # Check for cats and remote controls
+>>> text_labels = [["a cat", "a remote control"]]
+
+>>> inputs = processor(images=image, text=text_labels, return_tensors="pt").to(device)
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> results = processor.post_process_grounded_object_detection(
+... outputs,
+... inputs.input_ids,
+... box_threshold=0.4,
+... text_threshold=0.3,
+... target_sizes=[image.size[::-1]]
+... )
+
+# Retrieve the first image result
+>>> result = results[0]
+>>> for box, score, labels in zip(result["boxes"], result["scores"], result["labels"]):
+... box = [round(x, 2) for x in box.tolist()]
+... print(f"Detected {labels} with confidence {round(score.item(), 3)} at location {box}")
+Detected a cat with confidence 0.468 at location [344.78, 22.9, 637.3, 373.62]
+Detected a cat with confidence 0.426 at location [11.74, 51.55, 316.51, 473.22]
+```
+
+## Grounded SAM
+
+One can combine Grounding DINO with the [Segment Anything](sam) model for text-based mask generation as introduced in [Grounded SAM: Assembling Open-World Models for Diverse Visual Tasks](https://huggingface.co/papers/2401.14159). You can refer to this [demo notebook](https://github.com/NielsRogge/Transformers-Tutorials/blob/master/Grounding%20DINO/GroundingDINO_with_Segment_Anything.ipynb) 🌍 for details.
+
+
 +
+ Grounded SAM overview. Taken from the original repository.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Grounding DINO. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- Demo notebooks regarding inference with Grounding DINO as well as combining it with [SAM](sam) can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Grounding%20DINO). 🌎
+
+## GroundingDinoImageProcessor
+
+[[autodoc]] GroundingDinoImageProcessor
+ - preprocess
+
+## GroundingDinoImageProcessorFast
+
+[[autodoc]] GroundingDinoImageProcessorFast
+ - preprocess
+ - post_process_object_detection
+
+## GroundingDinoProcessor
+
+[[autodoc]] GroundingDinoProcessor
+ - post_process_grounded_object_detection
+
+## GroundingDinoConfig
+
+[[autodoc]] GroundingDinoConfig
+
+## GroundingDinoModel
+
+[[autodoc]] GroundingDinoModel
+ - forward
+
+## GroundingDinoForObjectDetection
+
+[[autodoc]] GroundingDinoForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/groupvit.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/groupvit.md
new file mode 100644
index 0000000000000000000000000000000000000000..ceb29d897f27c040cf32960330fdeb596ca11e45
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/groupvit.md
@@ -0,0 +1,102 @@
+
+*This model was released on 2022-02-22 and added to Hugging Face Transformers on 2022-06-28.*
+
+# GroupViT
+
+
 +
+ Hiera architecture. Taken from the original paper.
+
+This model was a joint contribution by [EduardoPacheco](https://huggingface.co/EduardoPacheco) and [namangarg110](https://huggingface.co/namangarg110). The original code can be found [here] (https://github.com/facebookresearch/hiera).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Hiera. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
 +
+ Idefics2 architecture. Taken from the original paper.
+
+This model was contributed by [amyeroberts](https://huggingface.co/amyeroberts).
+The original code can be found [here](https://huggingface.co/HuggingFaceM4/idefics2).
+
+## Usage tips
+
+- Each sample can contain multiple images, and the number of images can vary between samples. The processor will pad the inputs to the maximum number of images in a batch for input to the model.
+- The processor has a `do_image_splitting` option. If `True`, each input image will be split into 4 sub-images, and concatenated with the original to form 5 images. This is useful for increasing model performance. Make sure `processor.image_processor.do_image_splitting` is set to `False` if the model was not trained with this option.
+- `text` passed to the processor should have the `
 +
+
+> Click on the I-JEPA models in the right sidebar for more examples of how to apply I-JEPA to different image representation and classification tasks.
+
+The example below demonstrates how to extract image features with [`Pipeline`] or the [`AutoModel`] class.
+
+
 +
+ Summary of the approach. Taken from the [original paper](https://cdn.openai.com/papers/Generative_Pretraining_from_Pixels_V2.pdf).
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr), based on [this issue](https://github.com/openai/image-gpt/issues/7). The original code can be found
+[here](https://github.com/openai/image-gpt).
+
+## Usage tips
+
+- ImageGPT is almost exactly the same as [GPT-2](gpt2), with the exception that a different activation
+ function is used (namely "quick gelu"), and the layer normalization layers don't mean center the inputs. ImageGPT
+ also doesn't have tied input- and output embeddings.
+- As the time- and memory requirements of the attention mechanism of Transformers scales quadratically in the sequence
+ length, the authors pre-trained ImageGPT on smaller input resolutions, such as 32x32 and 64x64. However, feeding a
+ sequence of 32x32x3=3072 tokens from 0..255 into a Transformer is still prohibitively large. Therefore, the authors
+ applied k-means clustering to the (R,G,B) pixel values with k=512. This way, we only have a 32*32 = 1024-long
+ sequence, but now of integers in the range 0..511. So we are shrinking the sequence length at the cost of a bigger
+ embedding matrix. In other words, the vocabulary size of ImageGPT is 512, + 1 for a special "start of sentence" (SOS)
+ token, used at the beginning of every sequence. One can use [`ImageGPTImageProcessor`] to prepare
+ images for the model.
+- Despite being pre-trained entirely unsupervised (i.e. without the use of any labels), ImageGPT produces fairly
+ performant image features useful for downstream tasks, such as image classification. The authors showed that the
+ features in the middle of the network are the most performant, and can be used as-is to train a linear model (such as
+ a sklearn logistic regression model for example). This is also referred to as "linear probing". Features can be
+ easily obtained by first forwarding the image through the model, then specifying `output_hidden_states=True`, and
+ then average-pool the hidden states at whatever layer you like.
+- Alternatively, one can further fine-tune the entire model on a downstream dataset, similar to BERT. For this, you can
+ use [`ImageGPTForImageClassification`].
+- ImageGPT comes in different sizes: there's ImageGPT-small, ImageGPT-medium and ImageGPT-large. The authors did also
+ train an XL variant, which they didn't release. The differences in size are summarized in the following table:
+
+| **Model variant** | **Depths** | **Hidden sizes** | **Decoder hidden size** | **Params (M)** | **ImageNet-1k Top 1** |
+|---|---|---|---|---|---|
+| MiT-b0 | [2, 2, 2, 2] | [32, 64, 160, 256] | 256 | 3.7 | 70.5 |
+| MiT-b1 | [2, 2, 2, 2] | [64, 128, 320, 512] | 256 | 14.0 | 78.7 |
+| MiT-b2 | [3, 4, 6, 3] | [64, 128, 320, 512] | 768 | 25.4 | 81.6 |
+| MiT-b3 | [3, 4, 18, 3] | [64, 128, 320, 512] | 768 | 45.2 | 83.1 |
+| MiT-b4 | [3, 8, 27, 3] | [64, 128, 320, 512] | 768 | 62.6 | 83.6 |
+| MiT-b5 | [3, 6, 40, 3] | [64, 128, 320, 512] | 768 | 82.0 | 83.8 |
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with ImageGPT.
+
+
 +
+ InstructBLIP architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/salesforce/LAVIS/tree/main/projects/instructblip).
+
+## Usage tips
+
+InstructBLIP uses the same architecture as [BLIP-2](blip2) with a tiny but important difference: it also feeds the text prompt (instruction) to the Q-Former.
+
+> [!NOTE]
+> BLIP models after release v4.46 will raise warnings about adding `processor.num_query_tokens = {{num_query_tokens}}` and expand model embeddings layer to add special `
 +
+ Overview of InternVL3 models architecture, which is the same as InternVL2.5. Taken from the original checkpoint.
+
+
+
+
 +
+ Comparison of InternVL3 performance on OpenCompass against other SOTA VLLMs. Taken from the original checkpoint.
+
+
+
+This model was contributed by [yonigozlan](https://huggingface.co/yonigozlan).
+The original code can be found [here](https://github.com/OpenGVLab/InternVL).
+
+## Usage example
+
+### Inference with Pipeline
+
+Here is how you can use the `image-text-to-text` pipeline to perform inference with the `InternVL3` models in just a few lines of code:
+
+```python
+>>> from transformers import pipeline
+
+>>> messages = [
+... {
+... "role": "user",
+... "content": [
+... {
+... "type": "image",
+... "image": "https://huggingface.co/datasets/huggingface/documentation-images/resolve/main/bee.jpg",
+... },
+... {"type": "text", "text": "Describe this image."},
+... ],
+... },
+... ]
+
+>>> pipe = pipeline("image-text-to-text", model="OpenGVLab/InternVL3-1B-hf")
+>>> outputs = pipe(text=messages, max_new_tokens=50, return_full_text=False)
+>>> outputs[0]["generated_text"]
+'The image showcases a vibrant scene of nature, featuring several flowers and a bee. \n\n1. **Foreground Flowers**: \n - The primary focus is on a large, pink cosmos flower with a prominent yellow center. The petals are soft and slightly r'
+```
+### Inference on a single image
+
+This example demonstrates how to perform inference on a single image with the InternVL models using chat templates.
+
+> [!NOTE]
+> Note that the model has been trained with a specific prompt format for chatting. Use `processor.apply_chat_template(my_conversation_dict)` to correctly format your prompts.
+
+```python
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText
+>>> import torch
+
+>>> model_checkpoint = "OpenGVLab/InternVL3-1B-hf"
+>>> processor = AutoProcessor.from_pretrained(model_checkpoint)
+>>> model = AutoModelForImageTextToText.from_pretrained(model_checkpoint, device_map="auto", torch_dtype=torch.bfloat16)
+
+>>> messages = [
+... {
+... "role": "user",
+... "content": [
+... {"type": "image", "url": "http://images.cocodataset.org/val2017/000000039769.jpg"},
+... {"type": "text", "text": "Please describe the image explicitly."},
+... ],
+... }
+... ]
+
+>>> inputs = processor.apply_chat_template(messages, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt").to(model.device, dtype=torch.bfloat16)
+
+>>> generate_ids = model.generate(**inputs, max_new_tokens=50)
+>>> decoded_output = processor.decode(generate_ids[0, inputs["input_ids"].shape[1] :], skip_special_tokens=True)
+
+>>> decoded_output
+'The image shows two cats lying on a pink blanket. The cat on the left is a tabby with a mix of brown, black, and white fur, and it appears to be sleeping with its head resting on the blanket. The cat on the'
+```
+
+### Text-only generation
+This example shows how to generate text using the InternVL model without providing any image input.
+
+
+```python
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText
+>>> import torch
+
+>>> model_checkpoint = "OpenGVLab/InternVL3-1B-hf"
+>>> processor = AutoProcessor.from_pretrained(model_checkpoint)
+>>> model = AutoModelForImageTextToText.from_pretrained(model_checkpoint, device_map="auto", torch_dtype=torch.bfloat16)
+
+>>> messages = [
+... {
+... "role": "user",
+... "content": [
+... {"type": "text", "text": "Write a haiku"},
+... ],
+... }
+... ]
+
+>>> inputs = processor.apply_chat_template(messages, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt").to(torch_device, dtype=torch.bfloat16)
+
+>>> generate_ids = model.generate(**inputs, max_new_tokens=50)
+>>> decoded_output = processor.decode(generate_ids[0, inputs["input_ids"].shape[1] :], skip_special_tokens=True)
+
+>>> print(decoded_output)
+"Whispers of dawn,\nSilent whispers of the night,\nNew day's light begins."
+```
+
+### Batched image and text inputs
+InternVL models also support batched image and text inputs.
+
+```python
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText
+>>> import torch
+
+>>> model_checkpoint = "OpenGVLab/InternVL3-1B-hf"
+>>> processor = AutoProcessor.from_pretrained(model_checkpoint)
+>>> model = AutoModelForImageTextToText.from_pretrained(model_checkpoint, device_map="auto", torch_dtype=torch.bfloat16)
+
+>>> messages = [
+... [
+... {
+... "role": "user",
+... "content": [
+... {"type": "image", "url": "https://llava-vl.github.io/static/images/view.jpg"},
+... {"type": "text", "text": "Write a haiku for this image"},
+... ],
+... },
+... ],
+... [
+... {
+... "role": "user",
+... "content": [
+... {"type": "image", "url": "https://www.ilankelman.org/stopsigns/australia.jpg"},
+... {"type": "text", "text": "Describe this image"},
+... ],
+... },
+... ],
+... ]
+
+
+>>> inputs = processor.apply_chat_template(messages, padding=True, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt").to(model.device, dtype=torch.bfloat16)
+
+>>> output = model.generate(**inputs, max_new_tokens=25)
+
+>>> decoded_outputs = processor.batch_decode(output, skip_special_tokens=True)
+>>> decoded_outputs
+["user\n\nWrite a haiku for this image\nassistant\nSilky lake, \nWooden pier, \nNature's peace.",
+ 'user\n\nDescribe this image\nassistant\nThe image shows a street scene with a traditional Chinese archway, known as a "Chinese Gate" or "Chinese Gate of']
+```
+
+### Batched multi-image input
+This implementation of the InternVL models supports batched text-images inputs with different number of images for each text.
+
+```python
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText
+>>> import torch
+
+>>> model_checkpoint = "OpenGVLab/InternVL3-1B-hf"
+>>> processor = AutoProcessor.from_pretrained(model_checkpoint)
+>>> model = AutoModelForImageTextToText.from_pretrained(model_checkpoint, device_map="auto", torch_dtype=torch.bfloat16)
+
+>>> messages = [
+... [
+... {
+... "role": "user",
+... "content": [
+... {"type": "image", "url": "https://llava-vl.github.io/static/images/view.jpg"},
+... {"type": "text", "text": "Write a haiku for this image"},
+... ],
+... },
+... ],
+... [
+... {
+... "role": "user",
+... "content": [
+... {"type": "image", "url": "https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg"},
+... {"type": "image", "url": "https://thumbs.dreamstime.com/b/golden-gate-bridge-san-francisco-purple-flowers-california-echium-candicans-36805947.jpg"},
+... {"type": "text", "text": "These images depict two different landmarks. Can you identify them?"},
+... ],
+... },
+... ],
+>>> ]
+
+>>> inputs = processor.apply_chat_template(messages, padding=True, add_generation_prompt=True, tokenize=True, return_dict=True, return_tensors="pt").to(model.device, dtype=torch.bfloat16)
+
+>>> output = model.generate(**inputs, max_new_tokens=25)
+
+>>> decoded_outputs = processor.batch_decode(output, skip_special_tokens=True)
+>>> decoded_outputs
+["user\n\nWrite a haiku for this image\nassistant\nSilky lake, \nWooden pier, \nNature's peace.",
+ 'user\n\n\nThese images depict two different landmarks. Can you identify them?\nassistant\nYes, these images depict the Statue of Liberty and the Golden Gate Bridge.']
+```
+
+### Video input
+InternVL models can also handle video inputs. Here is an example of how to perform inference on a video input using chat templates.
+
+```python
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, BitsAndBytesConfig
+
+>>> model_checkpoint = "OpenGVLab/InternVL3-8B-hf"
+>>> quantization_config = BitsAndBytesConfig(load_in_4bit=True)
+>>> processor = AutoProcessor.from_pretrained(model_checkpoint)
+>>> model = AutoModelForImageTextToText.from_pretrained(model_checkpoint, quantization_config=quantization_config)
+
+>>> messages = [
+... {
+... "role": "user",
+... "content": [
+... {
+... "type": "video",
+... "url": "https://huggingface.co/datasets/hf-internal-testing/fixtures_videos/resolve/main/tennis.mp4",
+... },
+... {"type": "text", "text": "What type of shot is the man performing?"},
+... ],
+... }
+>>> ]
+>>> inputs = processor.apply_chat_template(
+... messages,
+... return_tensors="pt",
+... add_generation_prompt=True,
+... tokenize=True,
+... return_dict=True,
+... num_frames=8,
+>>> ).to(model.device, dtype=torch.float16)
+
+>>> output = model.generate(**inputs, max_new_tokens=25)
+
+>>> decoded_output = processor.decode(output[0, inputs["input_ids"].shape[1] :], skip_special_tokens=True)
+>>> decoded_output
+'The man is performing a forehand shot.'
+```
+
+### Interleaved image and video inputs
+This example showcases how to handle a batch of chat conversations with interleaved image and video inputs using chat template.
+
+```python
+>>> from transformers import AutoProcessor, AutoModelForImageTextToText, BitsAndBytesConfig
+>>> import torch
+
+>>> model_checkpoint = "OpenGVLab/InternVL3-1B-hf"
+>>> processor = AutoProcessor.from_pretrained(model_checkpoint)
+>>> model = AutoModelForImageTextToText.from_pretrained(model_checkpoint, device_map="auto", torch_dtype=torch.bfloat16)
+
+>>> messages = [
+... [
+... {
+... "role": "user",
+... "content": [
+... {"type": "image", "url": "https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg"},
+... {"type": "image", "url": "https://thumbs.dreamstime.com/b/golden-gate-bridge-san-francisco-purple-flowers-california-echium-candicans-36805947.jpg"},
+... {"type": "text", "text": "These images depict two different landmarks. Can you identify them?"},
+... ],
+... },
+... ],
+... [
+... {
+... "role": "user",
+... "content": [
+... {"type": "video", "url": "https://huggingface.co/datasets/hf-internal-testing/fixtures_videos/resolve/main/tennis.mp4"},
+... {"type": "text", "text": "What type of shot is the man performing?"},
+... ],
+... },
+... ],
+... [
+... {
+... "role": "user",
+... "content": [
+... {"type": "image", "url": "https://llava-vl.github.io/static/images/view.jpg"},
+... {"type": "text", "text": "Write a haiku for this image"},
+... ],
+... },
+... ],
+>>> ]
+>>> inputs = processor.apply_chat_template(
+... messages,
+... padding=True,
+... add_generation_prompt=True,
+... tokenize=True,
+... return_dict=True,
+... return_tensors="pt",
+>>> ).to(model.device, dtype=torch.bfloat16)
+
+>>> outputs = model.generate(**inputs, max_new_tokens=25)
+
+>>> decoded_outputs = processor.batch_decode(outputs, skip_special_tokens=True)
+>>> decoded_outputs
+['user\n\n\nThese images depict two different landmarks. Can you identify them?\nassistant\nThe images depict the Statue of Liberty and the Golden Gate Bridge.',
+ 'user\nFrame1: \nFrame2: \nFrame3: \nFrame4: \nFrame5: \nFrame6: \nFrame7: \nFrame8: \nWhat type of shot is the man performing?\nassistant\nA forehand shot',
+ "user\n\nWrite a haiku for this image\nassistant\nSilky lake, \nWooden pier, \nNature's peace."]
+```
+
+## InternVLVisionConfig
+
+[[autodoc]] InternVLVisionConfig
+
+## InternVLConfig
+
+[[autodoc]] InternVLConfig
+
+## InternVLVisionModel
+
+[[autodoc]] InternVLVisionModel
+ - forward
+
+## InternVLModel
+
+[[autodoc]] InternVLModel
+ - forward
+
+## InternVLForConditionalGeneration
+
+[[autodoc]] InternVLForConditionalGeneration
+ - forward
+
+## InternVLProcessor
+
+[[autodoc]] InternVLProcessor
+
+## InternVLVideoProcessor
+
+[[autodoc]] InternVLVideoProcessor
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/jamba.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/jamba.md
new file mode 100644
index 0000000000000000000000000000000000000000..46903a50cdf4ead95da398b35bf8acf495864ab4
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/jamba.md
@@ -0,0 +1,159 @@
+
+*This model was released on 2024-03-28 and added to Hugging Face Transformers on 2024-04-18.*
+
+
 +
+ Overview of tasks that KOSMOS-2 can handle. Taken from the original paper.
+
+## Example
+
+```python
+>>> from PIL import Image
+>>> import requests
+>>> from transformers import AutoProcessor, Kosmos2ForConditionalGeneration
+
+>>> model = Kosmos2ForConditionalGeneration.from_pretrained("microsoft/kosmos-2-patch14-224")
+>>> processor = AutoProcessor.from_pretrained("microsoft/kosmos-2-patch14-224")
+
+>>> url = "https://huggingface.co/microsoft/kosmos-2-patch14-224/resolve/main/snowman.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> prompt = "
 +
+
 +
+ Overview of tasks that KOSMOS-2.5 can handle. Taken from the original paper.
+
+The examples below demonstrates how to generate with [`AutoModel`], for both Markdown and OCR tasks.
+
+
 +
 +
+ LayoutLMv3 architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The TensorFlow version of this model was added by [chriskoo](https://huggingface.co/chriskoo), [tokec](https://huggingface.co/tokec), and [lre](https://huggingface.co/lre). The original code can be found [here](https://github.com/microsoft/unilm/tree/master/layoutlmv3).
+
+## Usage tips
+
+- In terms of data processing, LayoutLMv3 is identical to its predecessor [LayoutLMv2](layoutlmv2), except that:
+ - images need to be resized and normalized with channels in regular RGB format. LayoutLMv2 on the other hand normalizes the images internally and expects the channels in BGR format.
+ - text is tokenized using byte-pair encoding (BPE), as opposed to WordPiece.
+ Due to these differences in data preprocessing, one can use [`LayoutLMv3Processor`] which internally combines a [`LayoutLMv3ImageProcessor`] (for the image modality) and a [`LayoutLMv3Tokenizer`]/[`LayoutLMv3TokenizerFast`] (for the text modality) to prepare all data for the model.
+- Regarding usage of [`LayoutLMv3Processor`], we refer to the [usage guide](layoutlmv2#usage-layoutlmv2processor) of its predecessor.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LayoutLMv3. If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+
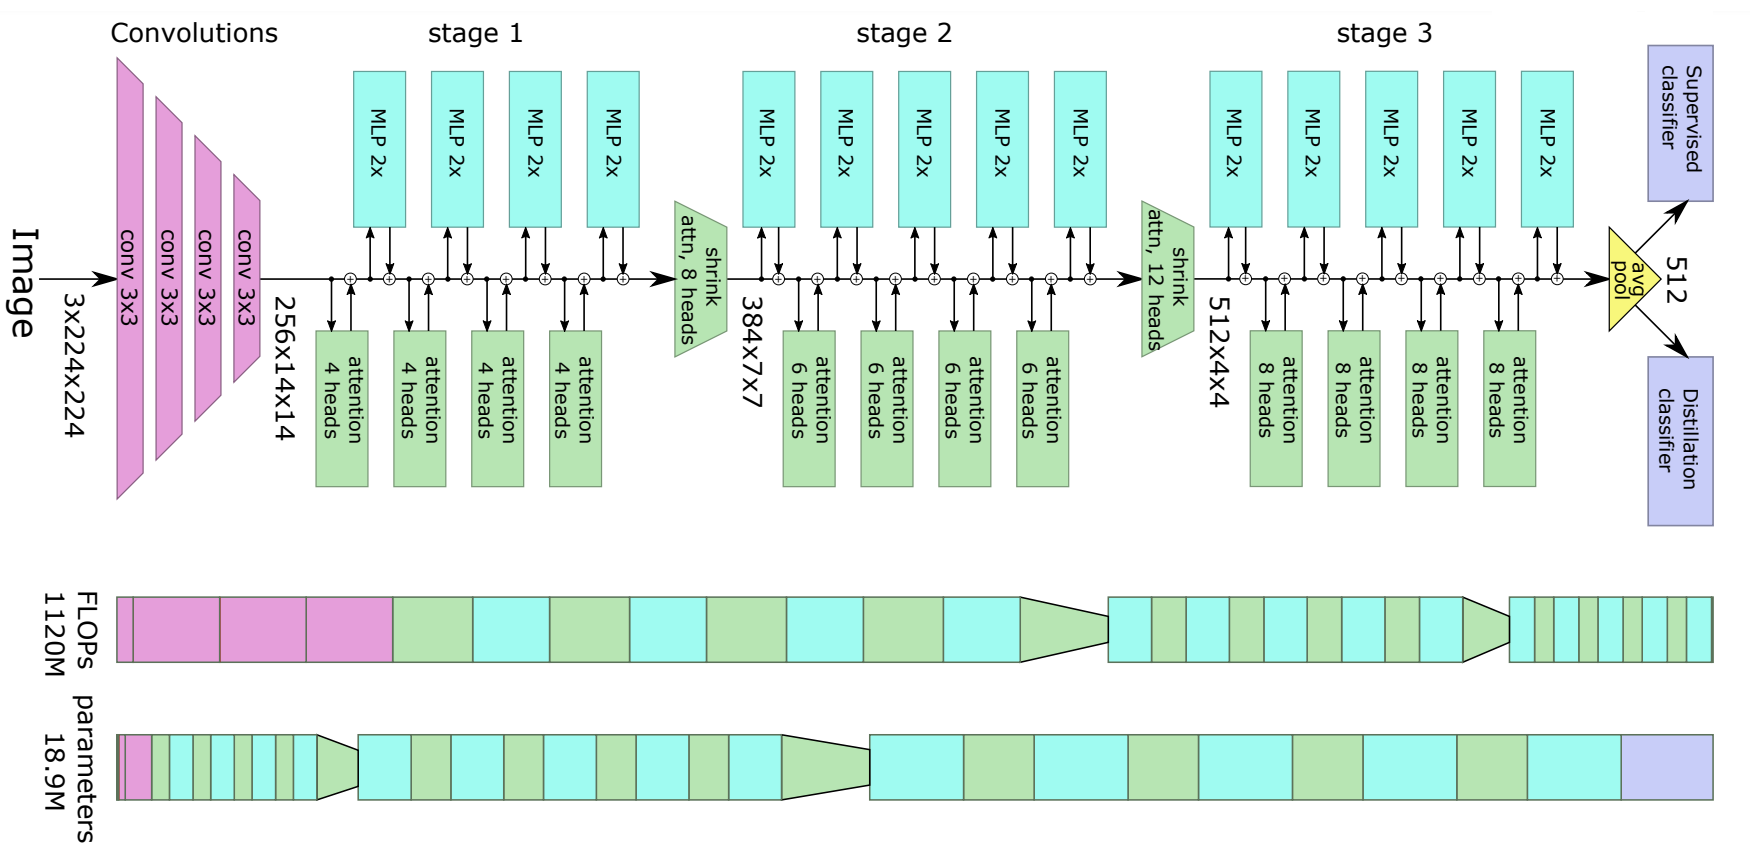 +
+ LeViT Architecture. Taken from the original paper.
+
+This model was contributed by [anugunj](https://huggingface.co/anugunj). The original code can be found [here](https://github.com/facebookresearch/LeViT).
+
+## Usage tips
+
+- Compared to ViT, LeViT models use an additional distillation head to effectively learn from a teacher (which, in the LeViT paper, is a ResNet like-model). The distillation head is learned through backpropagation under supervision of a ResNet like-model. They also draw inspiration from convolution neural networks to use activation maps with decreasing resolutions to increase the efficiency.
+- There are 2 ways to fine-tune distilled models, either (1) in a classic way, by only placing a prediction head on top
+ of the final hidden state and not using the distillation head, or (2) by placing both a prediction head and distillation
+ head on top of the final hidden state. In that case, the prediction head is trained using regular cross-entropy between
+ the prediction of the head and the ground-truth label, while the distillation prediction head is trained using hard distillation
+ (cross-entropy between the prediction of the distillation head and the label predicted by the teacher). At inference time,
+ one takes the average prediction between both heads as final prediction. (2) is also called "fine-tuning with distillation",
+ because one relies on a teacher that has already been fine-tuned on the downstream dataset. In terms of models, (1) corresponds
+ to [`LevitForImageClassification`] and (2) corresponds to [`LevitForImageClassificationWithTeacher`].
+- All released checkpoints were pre-trained and fine-tuned on [ImageNet-1k](https://huggingface.co/datasets/imagenet-1k)
+ (also referred to as ILSVRC 2012, a collection of 1.3 million images and 1,000 classes). only. No external data was used. This is in
+ contrast with the original ViT model, which used external data like the JFT-300M dataset/Imagenet-21k for
+ pre-training.
+- The authors of LeViT released 5 trained LeViT models, which you can directly plug into [`LevitModel`] or [`LevitForImageClassification`].
+ Techniques like data augmentation, optimization, and regularization were used in order to simulate training on a much larger dataset
+ (while only using ImageNet-1k for pre-training). The 5 variants available are (all trained on images of size 224x224):
+ *facebook/levit-128S*, *facebook/levit-128*, *facebook/levit-192*, *facebook/levit-256* and
+ *facebook/levit-384*. Note that one should use [`LevitImageProcessor`] in order to
+ prepare images for the model.
+- [`LevitForImageClassificationWithTeacher`] currently supports only inference and not training or fine-tuning.
+- You can check out demo notebooks regarding inference as well as fine-tuning on custom data [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/VisionTransformer)
+ (you can just replace [`ViTFeatureExtractor`] by [`LevitImageProcessor`] and [`ViTForImageClassification`] by [`LevitForImageClassification`] or [`LevitForImageClassificationWithTeacher`]).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LeViT.
+
+
 +
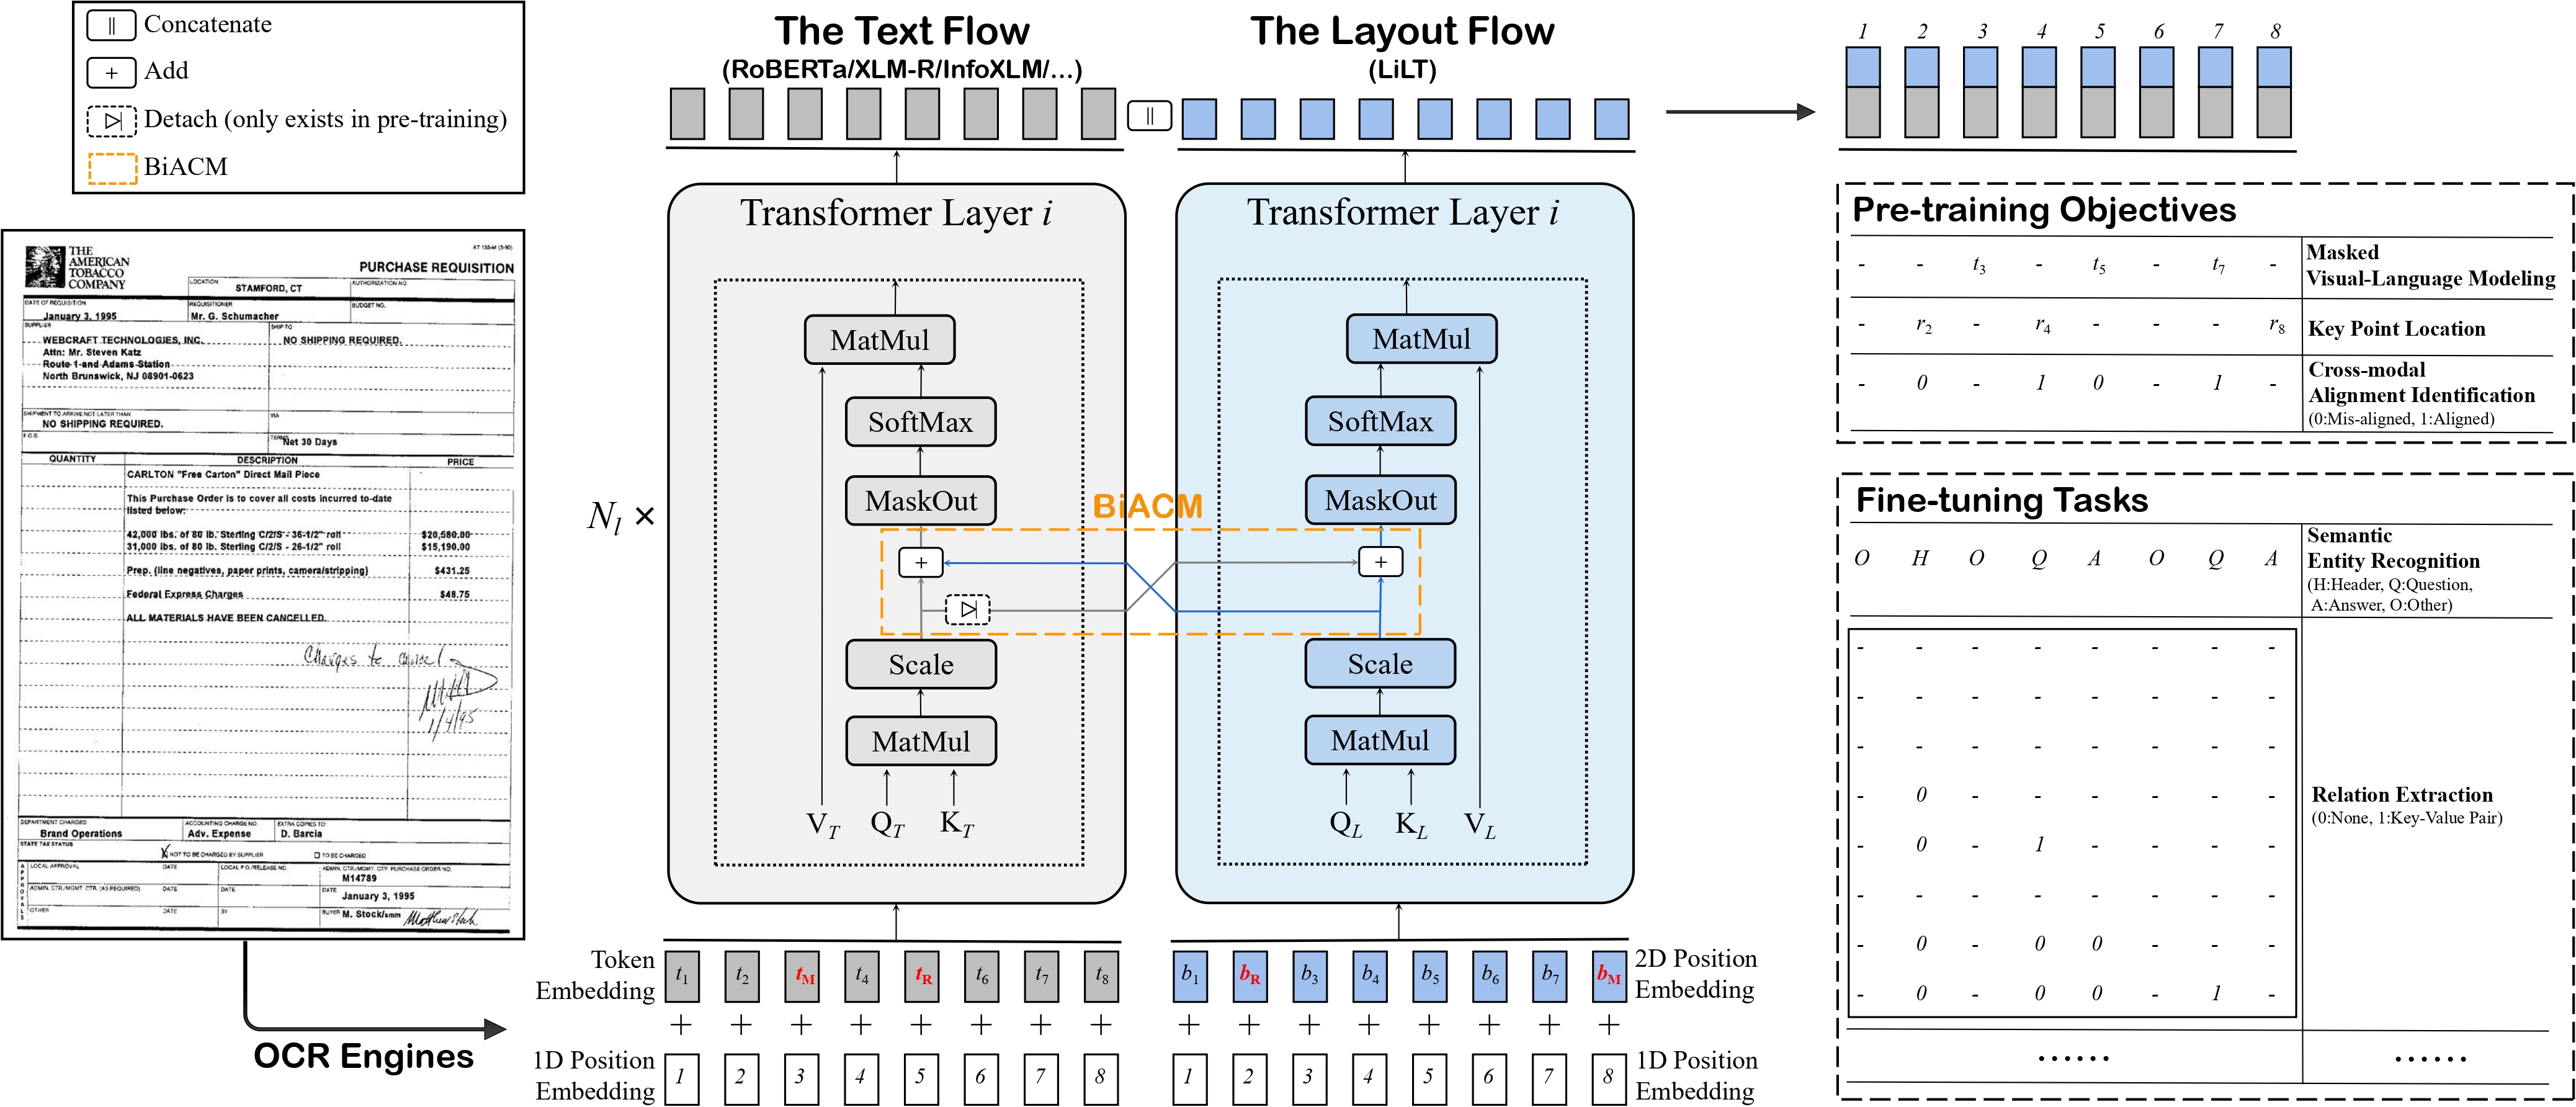 +
+ LiLT architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/jpwang/lilt).
+
+## Usage tips
+
+- To combine the Language-Independent Layout Transformer with a new RoBERTa checkpoint from the [hub](https://huggingface.co/models?search=roberta), refer to [this guide](https://github.com/jpWang/LiLT#or-generate-your-own-checkpoint-optional).
+The script will result in `config.json` and `pytorch_model.bin` files being stored locally. After doing this, one can do the following (assuming you're logged in with your HuggingFace account):
+
+```python
+from transformers import LiltModel
+
+model = LiltModel.from_pretrained("path_to_your_files")
+model.push_to_hub("name_of_repo_on_the_hub")
+```
+
+- When preparing data for the model, make sure to use the token vocabulary that corresponds to the RoBERTa checkpoint you combined with the Layout Transformer.
+- As [lilt-roberta-en-base](https://huggingface.co/SCUT-DLVCLab/lilt-roberta-en-base) uses the same vocabulary as [LayoutLMv3](layoutlmv3), one can use [`LayoutLMv3TokenizerFast`] to prepare data for the model.
+The same is true for [lilt-roberta-en-base](https://huggingface.co/SCUT-DLVCLab/lilt-infoxlm-base): one can use [`LayoutXLMTokenizerFast`] for that model.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with LiLT.
+
+- Demo notebooks for LiLT can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/LiLT).
+
+**Documentation resources**
+- [Text classification task guide](../tasks/sequence_classification)
+- [Token classification task guide](../tasks/token_classification)
+- [Question answering task guide](../tasks/question_answering)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## LiltConfig
+
+[[autodoc]] LiltConfig
+
+## LiltModel
+
+[[autodoc]] LiltModel
+ - forward
+
+## LiltForSequenceClassification
+
+[[autodoc]] LiltForSequenceClassification
+ - forward
+
+## LiltForTokenClassification
+
+[[autodoc]] LiltForTokenClassification
+ - forward
+
+## LiltForQuestionAnswering
+
+[[autodoc]] LiltForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llama.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llama.md
new file mode 100644
index 0000000000000000000000000000000000000000..d241ccdd1001dcfe9732875e652f889216fad4e5
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/llama.md
@@ -0,0 +1,183 @@
+
+*This model was released on 2023-02-27 and added to Hugging Face Transformers on 2023-03-16.*
+
+
 +
 +
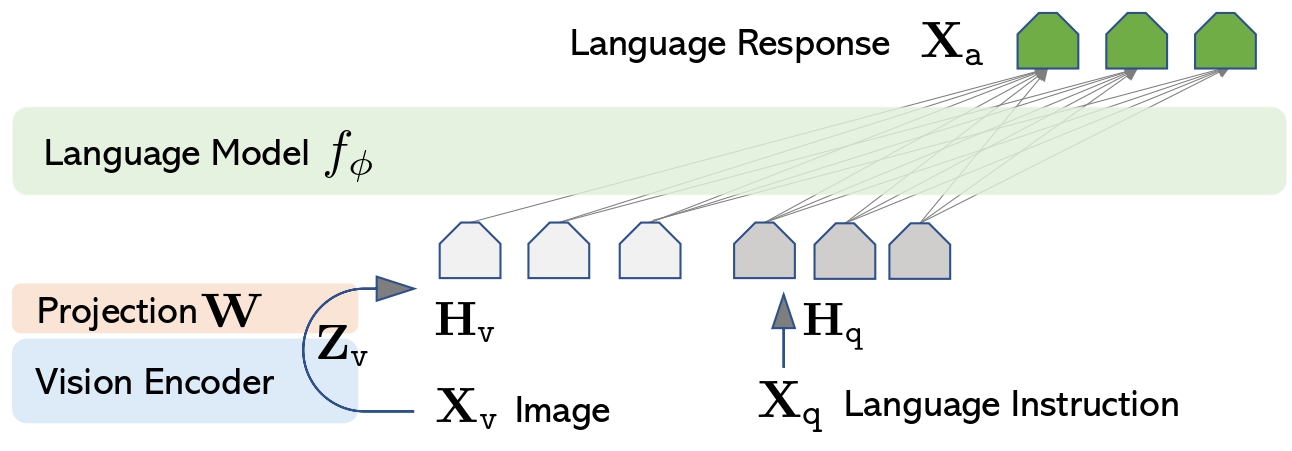 +
+ LLaVa architecture. Taken from the original paper.
+
+This model was contributed by [ArthurZ](https://huggingface.co/ArthurZ) and [ybelkada](https://huggingface.co/ybelkada).
+The original code can be found [here](https://github.com/haotian-liu/LLaVA/tree/main/llava).
+
+## Usage tips
+
+- We advise users to use `padding_side="left"` when computing batched generation as it leads to more accurate results. Simply make sure to call `processor.tokenizer.padding_side = "left"` before generating.
+
+- Note the model has not been explicitly trained to process multiple images in the same prompt, although this is technically possible, you may experience inaccurate results.
+
+
+> [!NOTE]
+> LLaVA models after release v4.46 will raise warnings about adding `processor.patch_size = {{patch_size}}`, `processor.num_additional_image_tokens = {{num_additional_image_tokens}}` and processor.vision_feature_select_strategy = {{vision_feature_select_strategy}}`. It is strongly recommended to add the attributes to the processor if you own the model checkpoint, or open a PR if it is not owned by you.
+Adding these attributes means that LLaVA will try to infer the number of image tokens required per image and expand the text with as many `
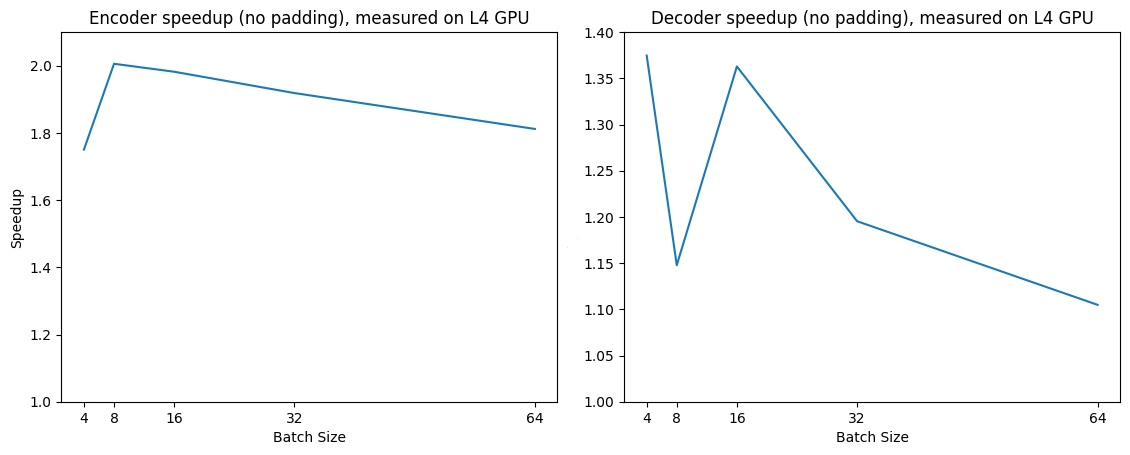 +
 +
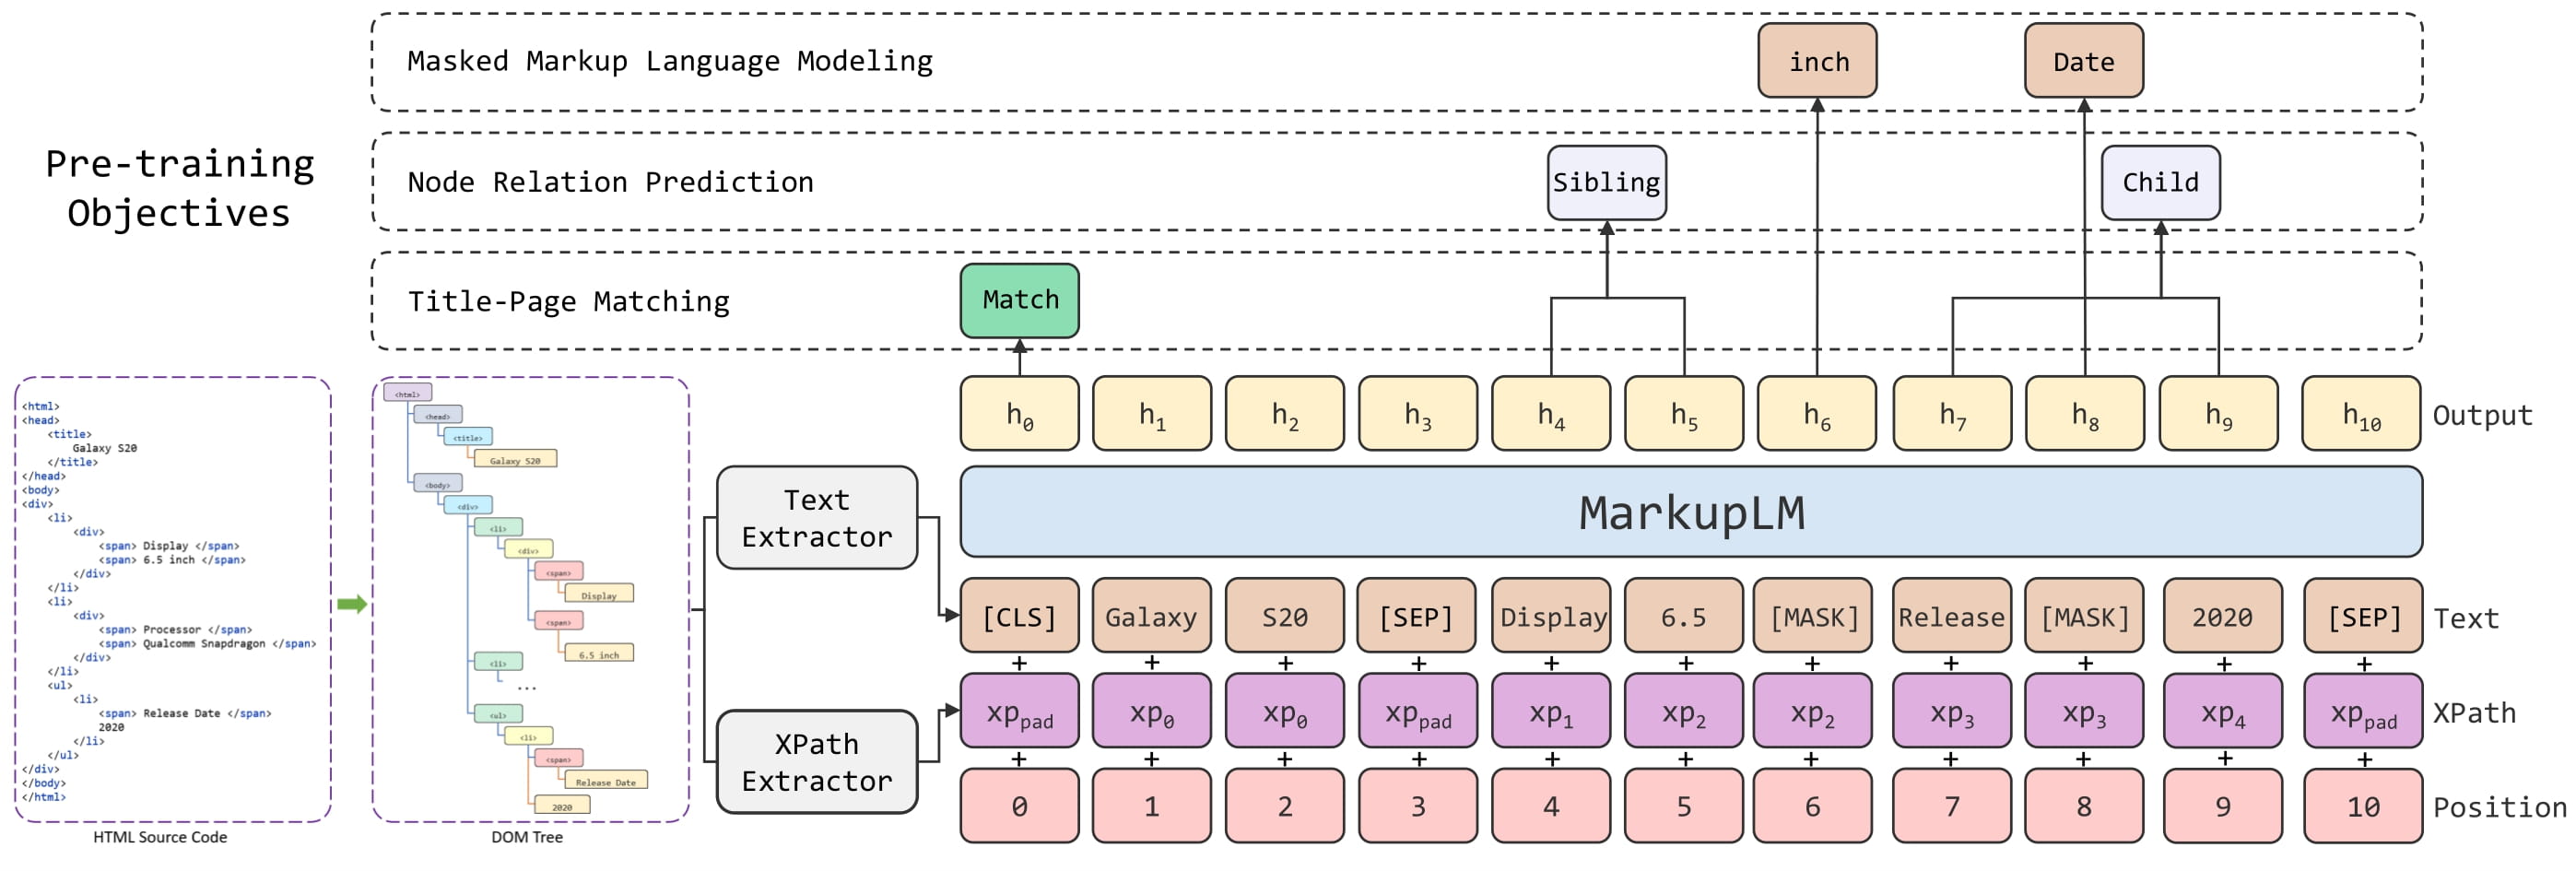 +
+ MarkupLM architecture. Taken from the original paper.
+
+## Usage: MarkupLMProcessor
+
+The easiest way to prepare data for the model is to use [`MarkupLMProcessor`], which internally combines a feature extractor
+([`MarkupLMFeatureExtractor`]) and a tokenizer ([`MarkupLMTokenizer`] or [`MarkupLMTokenizerFast`]). The feature extractor is
+used to extract all nodes and xpaths from the HTML strings, which are then provided to the tokenizer, which turns them into the
+token-level inputs of the model (`input_ids` etc.). Note that you can still use the feature extractor and tokenizer separately,
+if you only want to handle one of the two tasks.
+
+```python
+from transformers import MarkupLMFeatureExtractor, MarkupLMTokenizerFast, MarkupLMProcessor
+
+feature_extractor = MarkupLMFeatureExtractor()
+tokenizer = MarkupLMTokenizerFast.from_pretrained("microsoft/markuplm-base")
+processor = MarkupLMProcessor(feature_extractor, tokenizer)
+```
+
+In short, one can provide HTML strings (and possibly additional data) to [`MarkupLMProcessor`],
+and it will create the inputs expected by the model. Internally, the processor first uses
+[`MarkupLMFeatureExtractor`] to get a list of nodes and corresponding xpaths. The nodes and
+xpaths are then provided to [`MarkupLMTokenizer`] or [`MarkupLMTokenizerFast`], which converts them
+to token-level `input_ids`, `attention_mask`, `token_type_ids`, `xpath_subs_seq`, `xpath_tags_seq`.
+Optionally, one can provide node labels to the processor, which are turned into token-level `labels`.
+
+[`MarkupLMFeatureExtractor`] uses [Beautiful Soup](https://www.crummy.com/software/BeautifulSoup/bs4/doc/), a Python library for
+pulling data out of HTML and XML files, under the hood. Note that you can still use your own parsing solution of
+choice, and provide the nodes and xpaths yourself to [`MarkupLMTokenizer`] or [`MarkupLMTokenizerFast`].
+
+In total, there are 5 use cases that are supported by the processor. Below, we list them all. Note that each of these
+use cases work for both batched and non-batched inputs (we illustrate them for non-batched inputs).
+
+**Use case 1: web page classification (training, inference) + token classification (inference), parse_html = True**
+
+This is the simplest case, in which the processor will use the feature extractor to get all nodes and xpaths from the HTML.
+
+```python
+>>> from transformers import MarkupLMProcessor
+
+>>> processor = MarkupLMProcessor.from_pretrained("microsoft/markuplm-base")
+
+>>> html_string = """
+...
+...
+...
+...
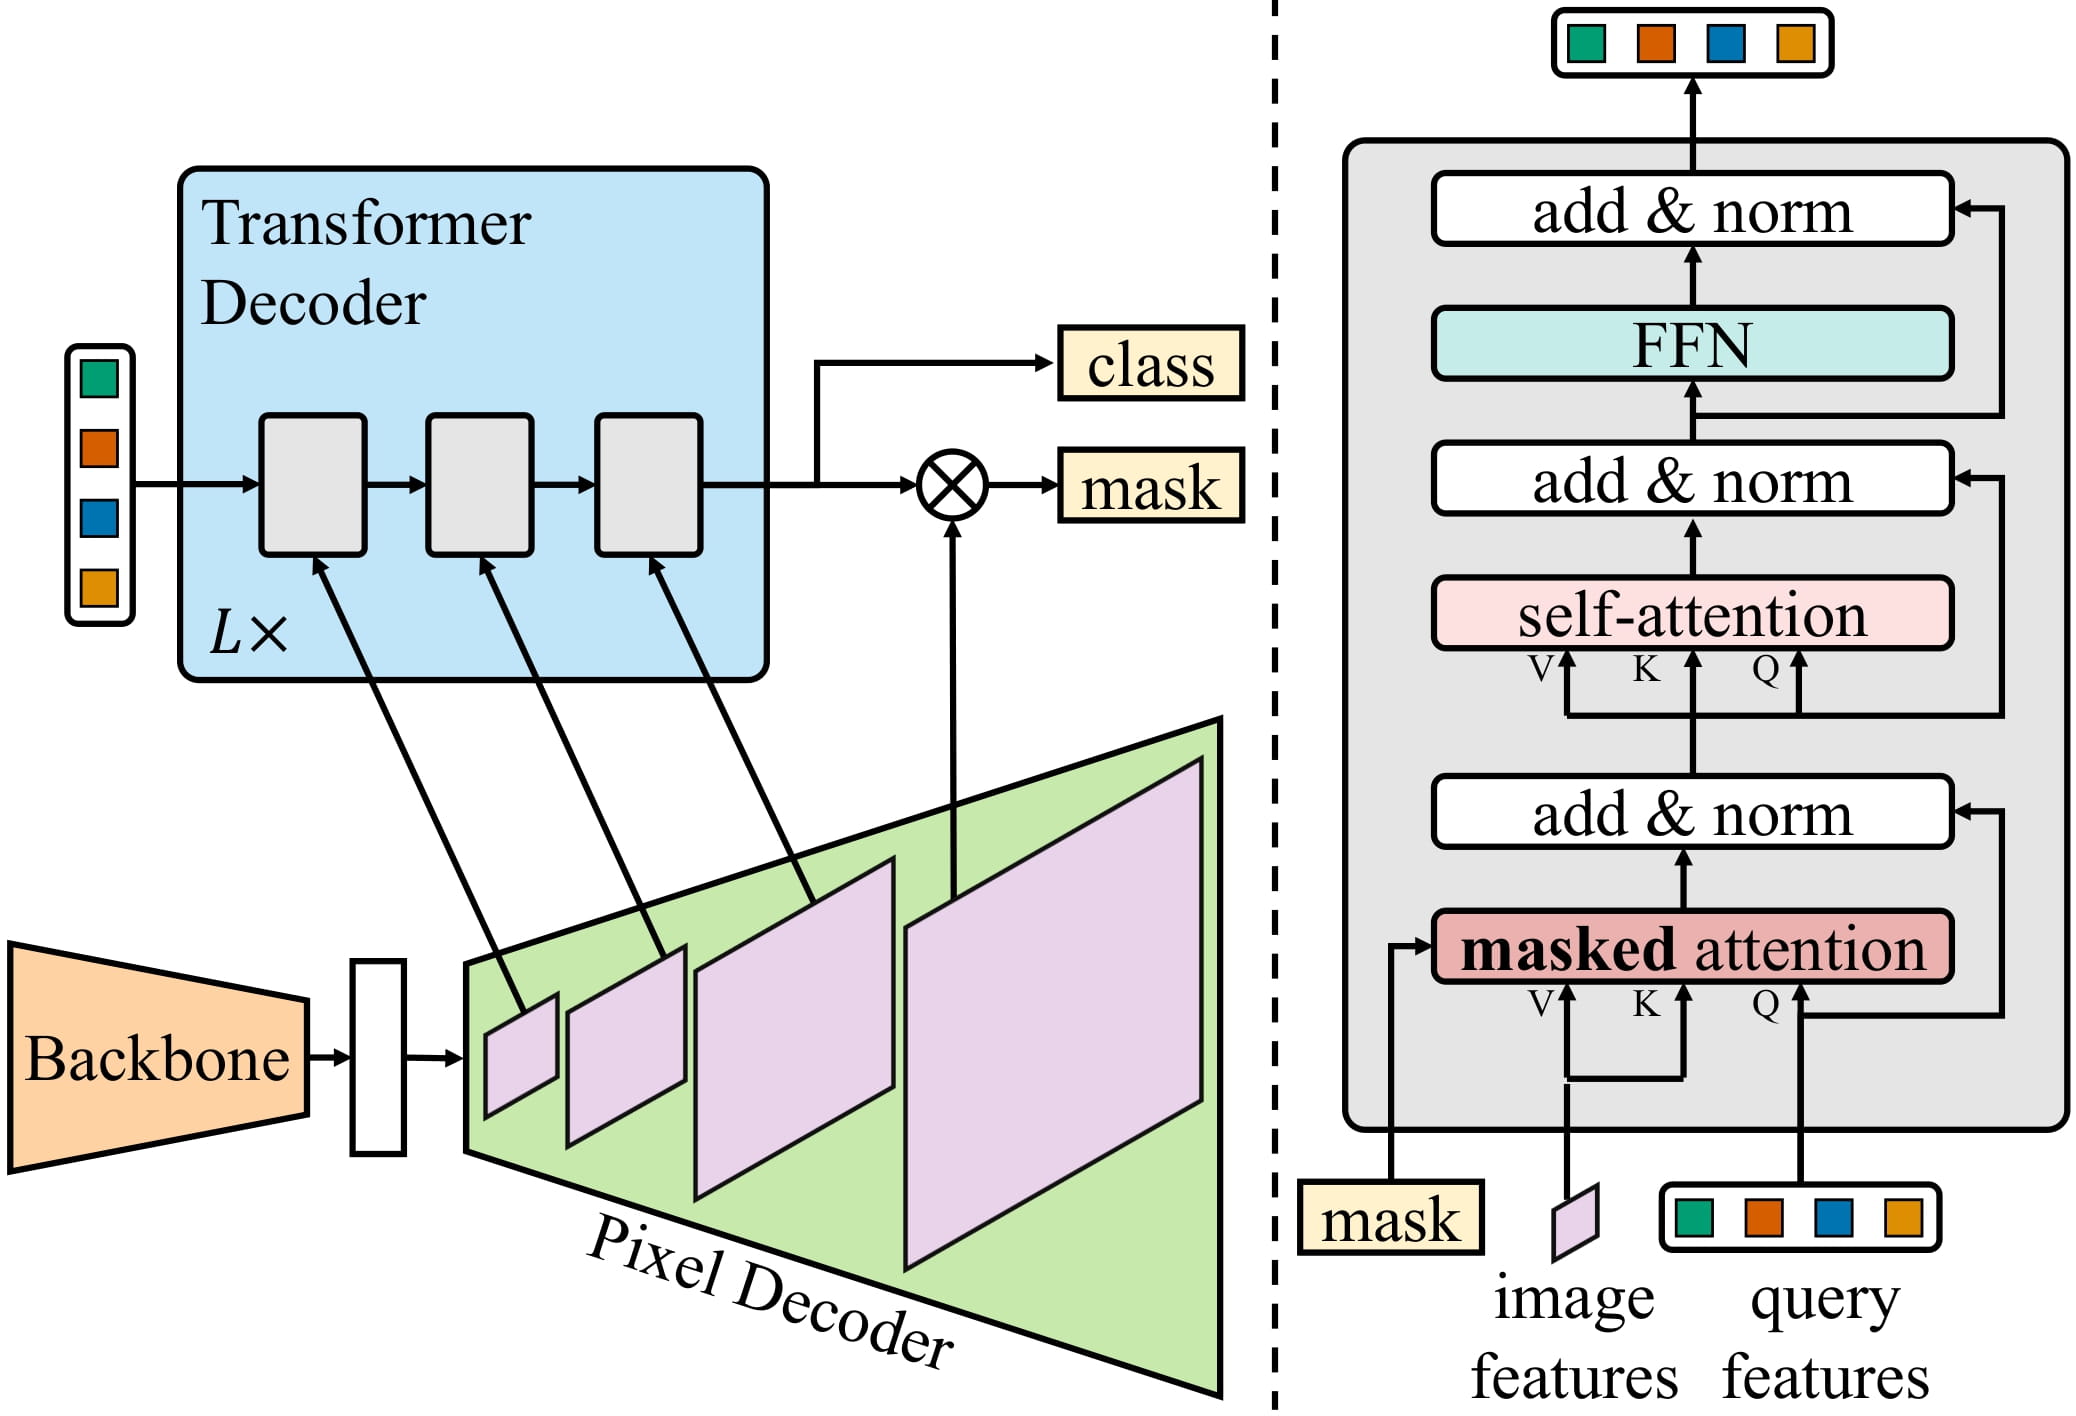 +
+ Mask2Former architecture. Taken from the original paper.
+
+This model was contributed by [Shivalika Singh](https://huggingface.co/shivi) and [Alara Dirik](https://huggingface.co/adirik). The original code can be found [here](https://github.com/facebookresearch/Mask2Former).
+
+## Usage tips
+
+- Mask2Former uses the same preprocessing and postprocessing steps as [MaskFormer](maskformer). Use [`Mask2FormerImageProcessor`] or [`AutoImageProcessor`] to prepare images and optional targets for the model.
+- To get the final segmentation, depending on the task, you can call [`~Mask2FormerImageProcessor.post_process_semantic_segmentation`] or [`~Mask2FormerImageProcessor.post_process_instance_segmentation`] or [`~Mask2FormerImageProcessor.post_process_panoptic_segmentation`]. All three tasks can be solved using [`Mask2FormerForUniversalSegmentation`] output, panoptic segmentation accepts an optional `label_ids_to_fuse` argument to fuse instances of the target object/s (e.g. sky) together.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Mask2Former.
+
+- Demo notebooks regarding inference + fine-tuning Mask2Former on custom data can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Mask2Former).
+- Scripts for finetuning [`Mask2Former`] with [`Trainer`] or [Accelerate](https://huggingface.co/docs/accelerate/index) can be found [here](https://github.com/huggingface/transformers/tree/main/examples/pytorch/instance-segmentation).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we will review it.
+The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## Mask2FormerConfig
+
+[[autodoc]] Mask2FormerConfig
+
+## MaskFormer specific outputs
+
+[[autodoc]] models.mask2former.modeling_mask2former.Mask2FormerModelOutput
+
+[[autodoc]] models.mask2former.modeling_mask2former.Mask2FormerForUniversalSegmentationOutput
+
+## Mask2FormerModel
+
+[[autodoc]] Mask2FormerModel
+ - forward
+
+## Mask2FormerForUniversalSegmentation
+
+[[autodoc]] Mask2FormerForUniversalSegmentation
+ - forward
+
+## Mask2FormerImageProcessor
+
+[[autodoc]] Mask2FormerImageProcessor
+ - preprocess
+ - encode_inputs
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## Mask2FormerImageProcessorFast
+
+[[autodoc]] Mask2FormerImageProcessorFast
+ - preprocess
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/maskformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/maskformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..17ef4c876e0851ee0ca858468929605b51e7092b
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/maskformer.md
@@ -0,0 +1,105 @@
+
+*This model was released on 2021-07-13 and added to Hugging Face Transformers on 2022-03-02.*
+
+# MaskFormer
+
+
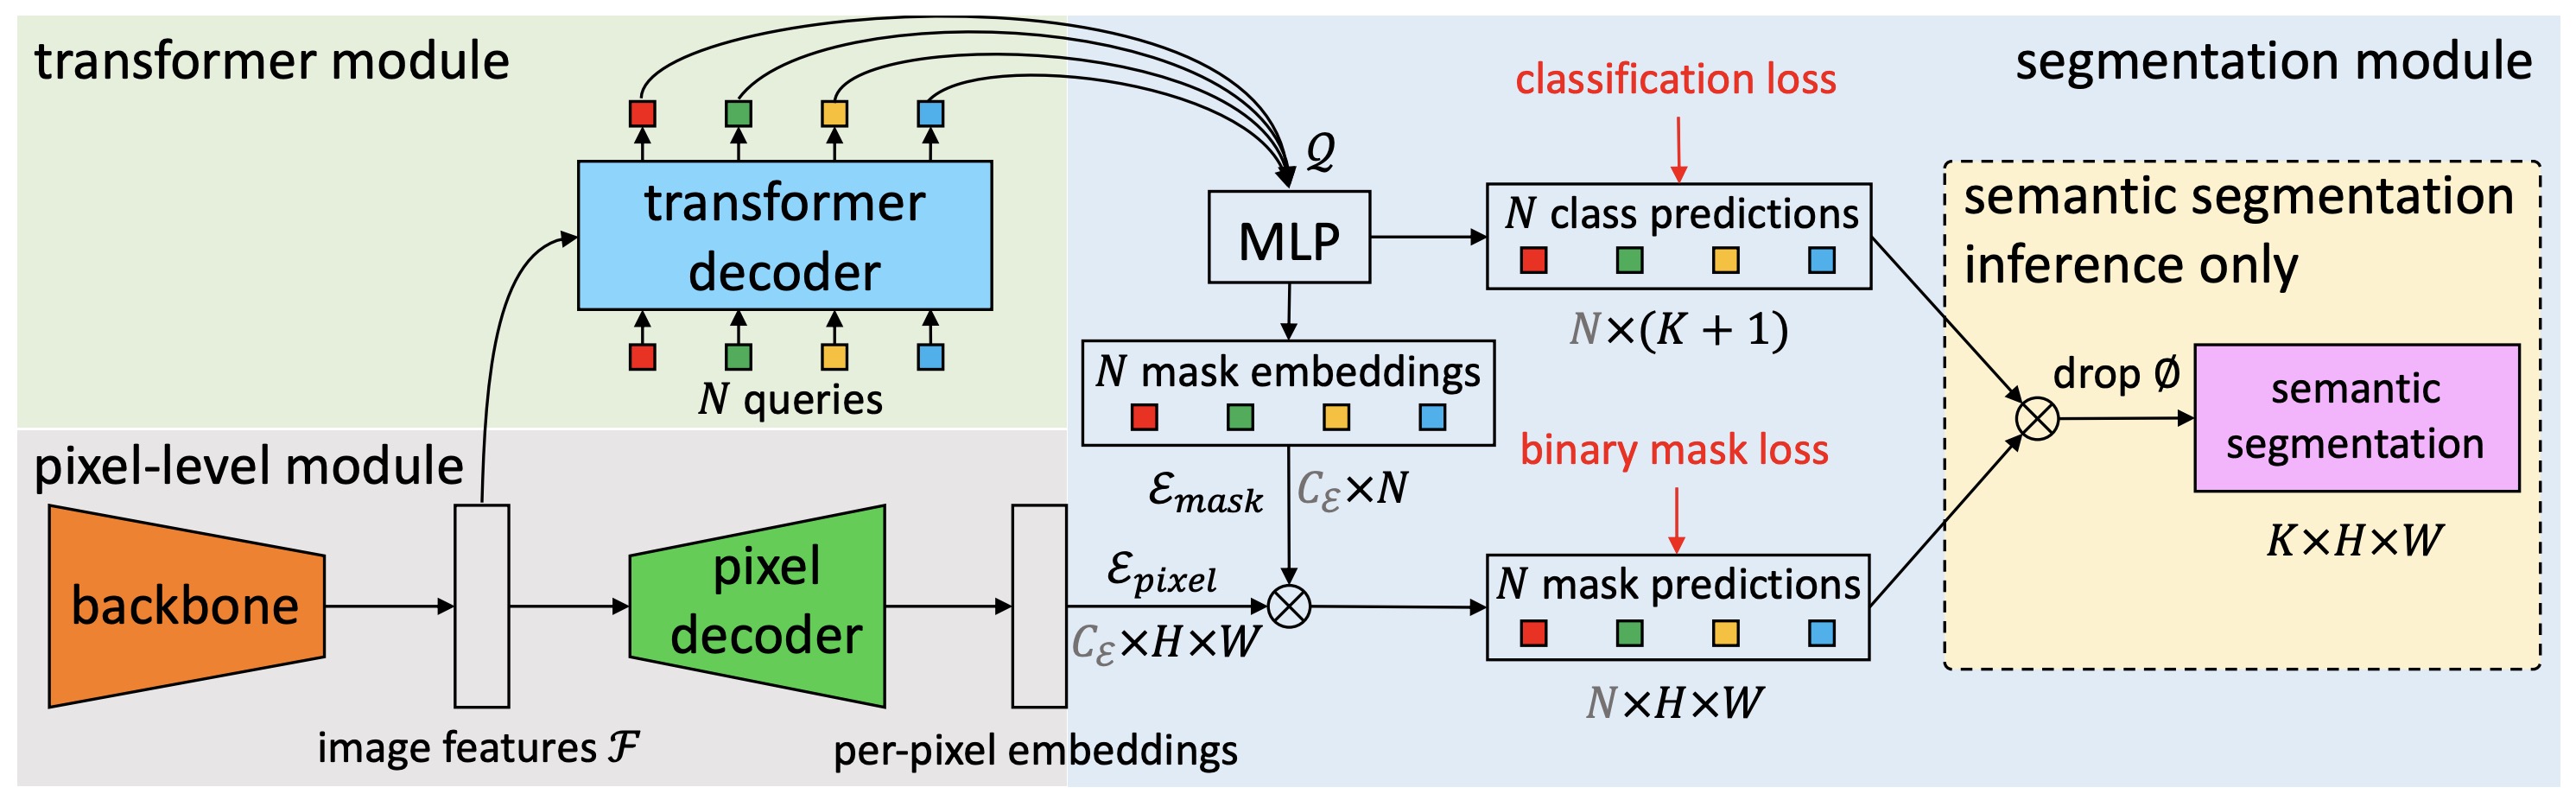 +
+This model was contributed by [francesco](https://huggingface.co/francesco). The original code can be found [here](https://github.com/facebookresearch/MaskFormer).
+
+## Usage tips
+
+- MaskFormer's Transformer decoder is identical to the decoder of [DETR](detr). During training, the authors of DETR did find it helpful to use auxiliary losses in the decoder, especially to help the model output the correct number of objects of each class. If you set the parameter `use_auxiliary_loss` of [`MaskFormerConfig`] to `True`, then prediction feedforward neural networks and Hungarian losses are added after each decoder layer (with the FFNs sharing parameters).
+- If you want to train the model in a distributed environment across multiple nodes, then one should update the
+ `get_num_masks` function inside in the `MaskFormerLoss` class of `modeling_maskformer.py`. When training on multiple nodes, this should be
+ set to the average number of target masks across all nodes, as can be seen in the original implementation [here](https://github.com/facebookresearch/MaskFormer/blob/da3e60d85fdeedcb31476b5edd7d328826ce56cc/mask_former/modeling/criterion.py#L169).
+- One can use [`MaskFormerImageProcessor`] to prepare images for the model and optional targets for the model.
+- To get the final segmentation, depending on the task, you can call [`~MaskFormerImageProcessor.post_process_semantic_segmentation`] or [`~MaskFormerImageProcessor.post_process_panoptic_segmentation`]. Both tasks can be solved using [`MaskFormerForInstanceSegmentation`] output, panoptic segmentation accepts an optional `label_ids_to_fuse` argument to fuse instances of the target object/s (e.g. sky) together.
+
+## Resources
+
+
 +
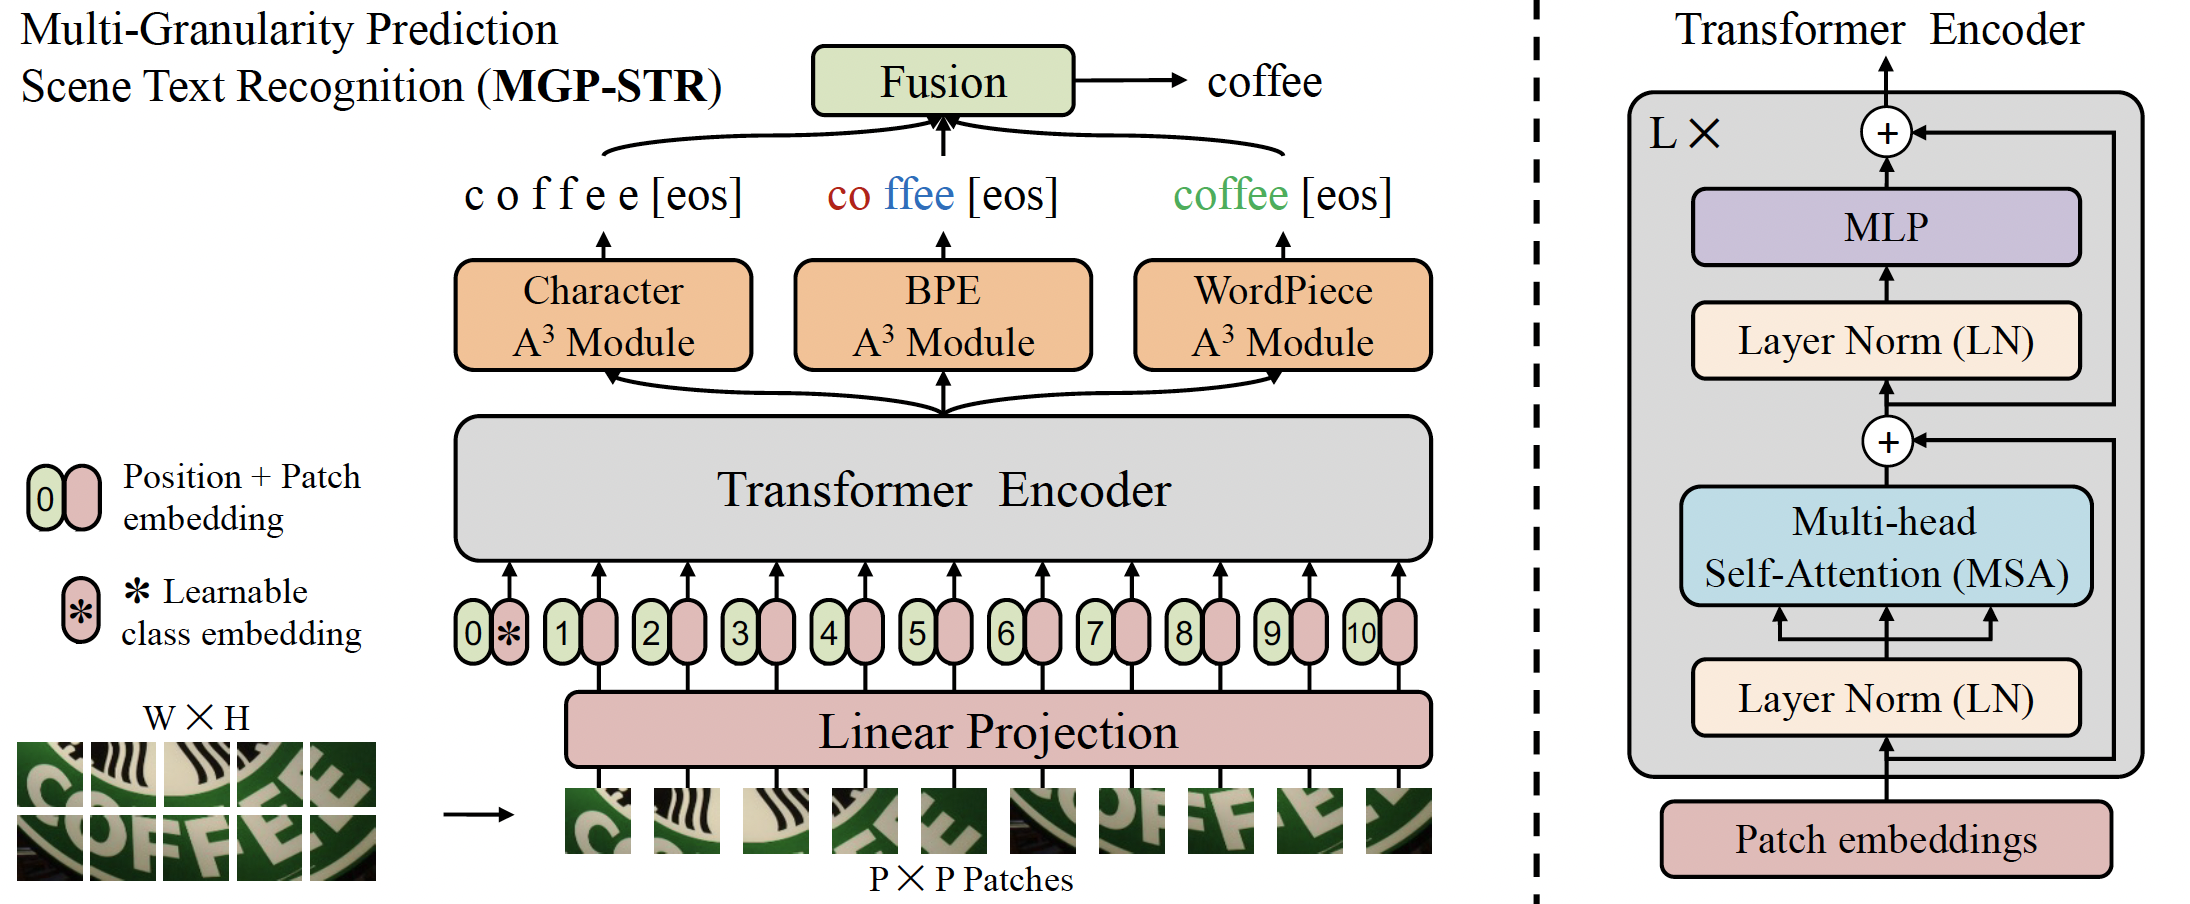 +
+ MGP-STR architecture. Taken from the original paper.
+
+MGP-STR is trained on two synthetic datasets [MJSynth](http://www.robots.ox.ac.uk/~vgg/data/text/) (MJ) and [SynthText](http://www.robots.ox.ac.uk/~vgg/data/scenetext/) (ST) without fine-tuning on other datasets. It achieves state-of-the-art results on six standard Latin scene text benchmarks, including 3 regular text datasets (IC13, SVT, IIIT) and 3 irregular ones (IC15, SVTP, CUTE).
+This model was contributed by [yuekun](https://huggingface.co/yuekun). The original code can be found [here](https://github.com/AlibabaResearch/AdvancedLiterateMachinery/tree/main/OCR/MGP-STR).
+
+## Inference example
+
+[`MgpstrModel`] accepts images as input and generates three types of predictions, which represent textual information at different granularities.
+The three types of predictions are fused to give the final prediction result.
+
+The [`ViTImageProcessor`] class is responsible for preprocessing the input image and
+[`MgpstrTokenizer`] decodes the generated character tokens to the target string. The
+[`MgpstrProcessor`] wraps [`ViTImageProcessor`] and [`MgpstrTokenizer`]
+into a single instance to both extract the input features and decode the predicted token ids.
+
+- Step-by-step Optical Character Recognition (OCR)
+
+```py
+>>> from transformers import MgpstrProcessor, MgpstrForSceneTextRecognition
+>>> import requests
+>>> from PIL import Image
+
+>>> processor = MgpstrProcessor.from_pretrained('alibaba-damo/mgp-str-base')
+>>> model = MgpstrForSceneTextRecognition.from_pretrained('alibaba-damo/mgp-str-base')
+
+>>> # load image from the IIIT-5k dataset
+>>> url = "https://i.postimg.cc/ZKwLg2Gw/367-14.png"
+>>> image = Image.open(requests.get(url, stream=True).raw).convert("RGB")
+
+>>> pixel_values = processor(images=image, return_tensors="pt").pixel_values
+>>> outputs = model(pixel_values)
+
+>>> generated_text = processor.batch_decode(outputs.logits)['generated_text']
+```
+
+## MgpstrConfig
+
+[[autodoc]] MgpstrConfig
+
+## MgpstrTokenizer
+
+[[autodoc]] MgpstrTokenizer
+ - save_vocabulary
+
+## MgpstrProcessor
+
+[[autodoc]] MgpstrProcessor
+ - __call__
+ - batch_decode
+
+## MgpstrModel
+
+[[autodoc]] MgpstrModel
+ - forward
+
+## MgpstrForSceneTextRecognition
+
+[[autodoc]] MgpstrForSceneTextRecognition
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mimi.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mimi.md
new file mode 100644
index 0000000000000000000000000000000000000000..2d655aa5966081b0037310967c23d1e2a14a0cea
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/mimi.md
@@ -0,0 +1,74 @@
+
+*This model was released on 2024-09-17 and added to Hugging Face Transformers on 2024-09-18.*
+
+
 +
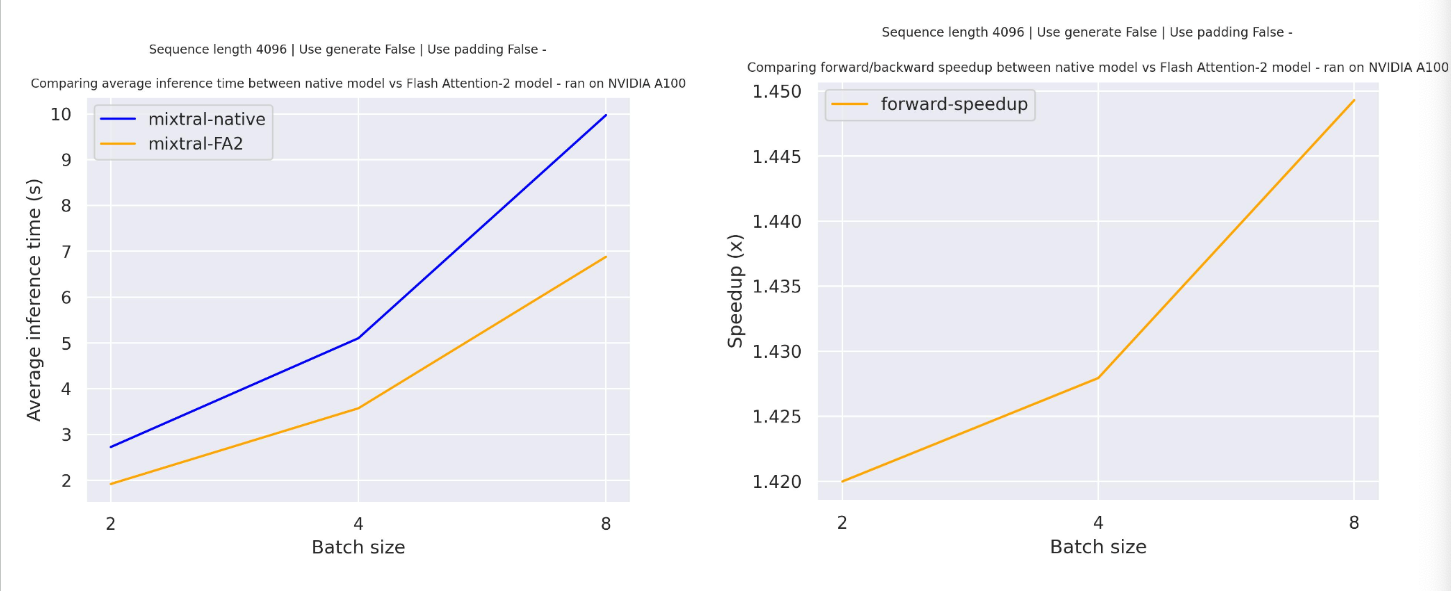 +
 +
 +
 +
 +
 +
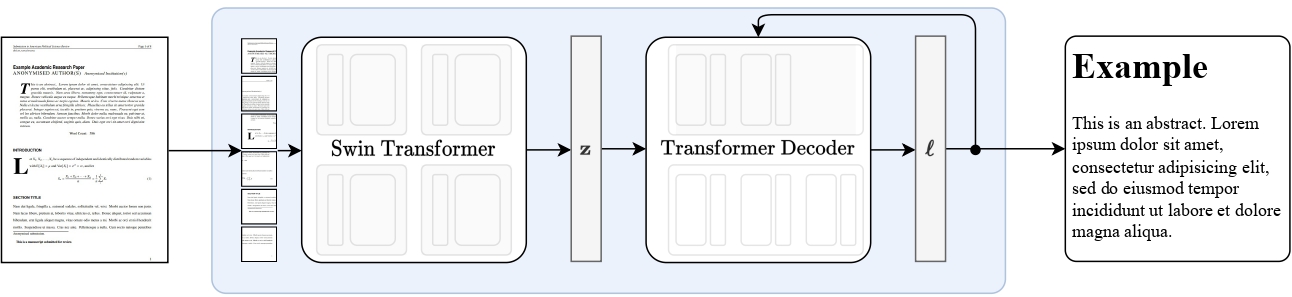 +
+ Nougat high-level overview. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found
+[here](https://github.com/facebookresearch/nougat).
+
+## Usage tips
+
+- The quickest way to get started with Nougat is by checking the [tutorial
+ notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Nougat), which show how to use the model
+ at inference time as well as fine-tuning on custom data.
+- Nougat is always used within the [VisionEncoderDecoder](vision-encoder-decoder) framework. The model is identical to [Donut](donut) in terms of architecture.
+
+## Inference
+
+Nougat's [`VisionEncoderDecoder`] model accepts images as input and makes use of
+[`~generation.GenerationMixin.generate`] to autoregressively generate text given the input image.
+
+The [`NougatImageProcessor`] class is responsible for preprocessing the input image and
+[`NougatTokenizerFast`] decodes the generated target tokens to the target string. The
+[`NougatProcessor`] wraps [`NougatImageProcessor`] and [`NougatTokenizerFast`] classes
+into a single instance to both extract the input features and decode the predicted token ids.
+
+- Step-by-step PDF transcription
+
+```py
+>>> from huggingface_hub import hf_hub_download
+>>> import re
+>>> from PIL import Image
+
+>>> from transformers import NougatProcessor, VisionEncoderDecoderModel, infer_device
+>>> from datasets import load_dataset
+>>> import torch
+
+>>> processor = NougatProcessor.from_pretrained("facebook/nougat-base")
+>>> model = VisionEncoderDecoderModel.from_pretrained("facebook/nougat-base")
+
+>>> device = infer_device()
+>>> model.to(device) # doctest: +IGNORE_RESULT
+
+>>> # prepare PDF image for the model
+>>> filepath = hf_hub_download(repo_id="hf-internal-testing/fixtures_docvqa", filename="nougat_paper.png", repo_type="dataset")
+>>> image = Image.open(filepath)
+>>> pixel_values = processor(image, return_tensors="pt").pixel_values
+
+>>> # generate transcription (here we only generate 30 tokens)
+>>> outputs = model.generate(
+... pixel_values.to(device),
+... min_length=1,
+... max_new_tokens=30,
+... bad_words_ids=[[processor.tokenizer.unk_token_id]],
+... )
+
+>>> sequence = processor.batch_decode(outputs, skip_special_tokens=True)[0]
+>>> sequence = processor.post_process_generation(sequence, fix_markdown=False)
+>>> # note: we're using repr here such for the sake of printing the \n characters, feel free to just print the sequence
+>>> print(repr(sequence))
+'\n\n# Nougat: Neural Optical Understanding for Academic Documents\n\n Lukas Blecher\n\nCorrespondence to: lblecher@'
+```
+
+See the [model hub](https://huggingface.co/models?filter=nougat) to look for Nougat checkpoints.
+
+
 +
+ OmDet-Turbo architecture overview. Taken from the original paper.
+
+This model was contributed by [yonigozlan](https://huggingface.co/yonigozlan).
+The original code can be found [here](https://github.com/om-ai-lab/OmDet).
+
+## Usage tips
+
+One unique property of OmDet-Turbo compared to other zero-shot object detection models, such as [Grounding DINO](grounding-dino), is the decoupled classes and prompt embedding structure that allows caching of text embeddings. This means that the model needs both classes and task as inputs, where classes is a list of objects we want to detect and task is the grounded text used to guide open-vocabulary detection. This approach limits the scope of the open-vocabulary detection and makes the decoding process faster.
+
+[`OmDetTurboProcessor`] is used to prepare the classes, task and image triplet. The task input is optional, and when not provided, it will default to `"Detect [class1], [class2], [class3], ..."`. To process the results from the model, one can use `post_process_grounded_object_detection` from [`OmDetTurboProcessor`]. Notably, this function takes in the input classes, as unlike other zero-shot object detection models, the decoupling of classes and task embeddings means that no decoding of the predicted class embeddings is needed in the post-processing step, and the predicted classes can be matched to the inputted ones directly.
+
+## Usage example
+
+### Single image inference
+
+Here's how to load the model and prepare the inputs to perform zero-shot object detection on a single image:
+
+```python
+>>> import torch
+>>> import requests
+>>> from PIL import Image
+
+>>> from transformers import AutoProcessor, OmDetTurboForObjectDetection
+
+>>> processor = AutoProcessor.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+>>> model = OmDetTurboForObjectDetection.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> text_labels = ["cat", "remote"]
+>>> inputs = processor(image, text=text_labels, return_tensors="pt")
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> # convert outputs (bounding boxes and class logits)
+>>> results = processor.post_process_grounded_object_detection(
+... outputs,
+... target_sizes=[(image.height, image.width)],
+... text_labels=text_labels,
+... threshold=0.3,
+... nms_threshold=0.3,
+... )
+>>> result = results[0]
+>>> boxes, scores, text_labels = result["boxes"], result["scores"], result["text_labels"]
+>>> for box, score, text_label in zip(boxes, scores, text_labels):
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"Detected {text_label} with confidence {round(score.item(), 3)} at location {box}")
+Detected remote with confidence 0.768 at location [39.89, 70.35, 176.74, 118.04]
+Detected cat with confidence 0.72 at location [11.6, 54.19, 314.8, 473.95]
+Detected remote with confidence 0.563 at location [333.38, 75.77, 370.7, 187.03]
+Detected cat with confidence 0.552 at location [345.15, 23.95, 639.75, 371.67]
+```
+
+### Multi image inference
+
+OmDet-Turbo can perform batched multi-image inference, with support for different text prompts and classes in the same batch:
+
+```python
+>>> import torch
+>>> import requests
+>>> from io import BytesIO
+>>> from PIL import Image
+>>> from transformers import AutoProcessor, OmDetTurboForObjectDetection
+
+>>> processor = AutoProcessor.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+>>> model = OmDetTurboForObjectDetection.from_pretrained("omlab/omdet-turbo-swin-tiny-hf")
+
+>>> url1 = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image1 = Image.open(BytesIO(requests.get(url1).content)).convert("RGB")
+>>> text_labels1 = ["cat", "remote"]
+>>> task1 = "Detect {}.".format(", ".join(text_labels1))
+
+>>> url2 = "http://images.cocodataset.org/train2017/000000257813.jpg"
+>>> image2 = Image.open(BytesIO(requests.get(url2).content)).convert("RGB")
+>>> text_labels2 = ["boat"]
+>>> task2 = "Detect everything that looks like a boat."
+
+>>> url3 = "https://cdn.britannica.com/61/93061-050-99147DCE/Statue-of-Liberty-Island-New-York-Bay.jpg"
+>>> image3 = Image.open(BytesIO(requests.get(url3).content)).convert("RGB")
+>>> text_labels3 = ["statue", "trees"]
+>>> task3 = "Focus on the foreground, detect statue and trees."
+
+>>> inputs = processor(
+... images=[image1, image2, image3],
+... text=[text_labels1, text_labels2, text_labels3],
+... task=[task1, task2, task3],
+... return_tensors="pt",
+... )
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> # convert outputs (bounding boxes and class logits)
+>>> results = processor.post_process_grounded_object_detection(
+... outputs,
+... text_labels=[text_labels1, text_labels2, text_labels3],
+... target_sizes=[(image.height, image.width) for image in [image1, image2, image3]],
+... threshold=0.2,
+... nms_threshold=0.3,
+... )
+
+>>> for i, result in enumerate(results):
+... for score, text_label, box in zip(
+... result["scores"], result["text_labels"], result["boxes"]
+... ):
+... box = [round(i, 1) for i in box.tolist()]
+... print(
+... f"Detected {text_label} with confidence "
+... f"{round(score.item(), 2)} at location {box} in image {i}"
+... )
+Detected remote with confidence 0.77 at location [39.9, 70.4, 176.7, 118.0] in image 0
+Detected cat with confidence 0.72 at location [11.6, 54.2, 314.8, 474.0] in image 0
+Detected remote with confidence 0.56 at location [333.4, 75.8, 370.7, 187.0] in image 0
+Detected cat with confidence 0.55 at location [345.2, 24.0, 639.8, 371.7] in image 0
+Detected boat with confidence 0.32 at location [146.9, 219.8, 209.6, 250.7] in image 1
+Detected boat with confidence 0.3 at location [319.1, 223.2, 403.2, 238.4] in image 1
+Detected boat with confidence 0.27 at location [37.7, 220.3, 84.0, 235.9] in image 1
+Detected boat with confidence 0.22 at location [407.9, 207.0, 441.7, 220.2] in image 1
+Detected statue with confidence 0.73 at location [544.7, 210.2, 651.9, 502.8] in image 2
+Detected trees with confidence 0.25 at location [3.9, 584.3, 391.4, 785.6] in image 2
+Detected trees with confidence 0.25 at location [1.4, 621.2, 118.2, 787.8] in image 2
+Detected statue with confidence 0.2 at location [428.1, 205.5, 767.3, 759.5] in image 2
+
+```
+
+## OmDetTurboConfig
+
+[[autodoc]] OmDetTurboConfig
+
+## OmDetTurboProcessor
+
+[[autodoc]] OmDetTurboProcessor
+ - post_process_grounded_object_detection
+
+## OmDetTurboForObjectDetection
+
+[[autodoc]] OmDetTurboForObjectDetection
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/oneformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/oneformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..c4b3bd142fe04b71100dad7d978f8387e296856d
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/oneformer.md
@@ -0,0 +1,97 @@
+
+*This model was released on 2022-11-10 and added to Hugging Face Transformers on 2023-01-19.*
+
+# OneFormer
+
+
 +
+The abstract from the paper is the following:
+
+*Universal Image Segmentation is not a new concept. Past attempts to unify image segmentation in the last decades include scene parsing, panoptic segmentation, and, more recently, new panoptic architectures. However, such panoptic architectures do not truly unify image segmentation because they need to be trained individually on the semantic, instance, or panoptic segmentation to achieve the best performance. Ideally, a truly universal framework should be trained only once and achieve SOTA performance across all three image segmentation tasks. To that end, we propose OneFormer, a universal image segmentation framework that unifies segmentation with a multi-task train-once design. We first propose a task-conditioned joint training strategy that enables training on ground truths of each domain (semantic, instance, and panoptic segmentation) within a single multi-task training process. Secondly, we introduce a task token to condition our model on the task at hand, making our model task-dynamic to support multi-task training and inference. Thirdly, we propose using a query-text contrastive loss during training to establish better inter-task and inter-class distinctions. Notably, our single OneFormer model outperforms specialized Mask2Former models across all three segmentation tasks on ADE20k, CityScapes, and COCO, despite the latter being trained on each of the three tasks individually with three times the resources. With new ConvNeXt and DiNAT backbones, we observe even more performance improvement. We believe OneFormer is a significant step towards making image segmentation more universal and accessible.*
+
+The figure below illustrates the architecture of OneFormer. Taken from the [original paper](https://huggingface.co/papers/2211.06220).
+
+
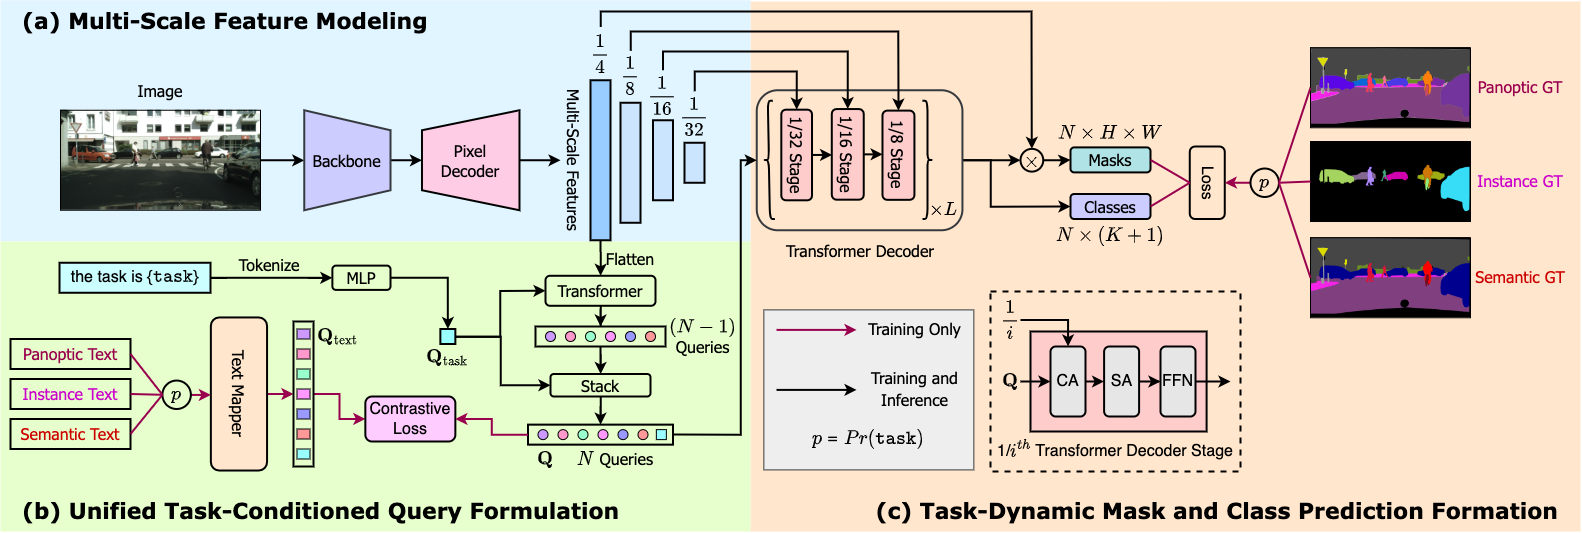 +
+This model was contributed by [Jitesh Jain](https://huggingface.co/praeclarumjj3). The original code can be found [here](https://github.com/SHI-Labs/OneFormer).
+
+## Usage tips
+
+- OneFormer requires two inputs during inference: *image* and *task token*.
+- During training, OneFormer only uses panoptic annotations.
+- If you want to train the model in a distributed environment across multiple nodes, then one should update the
+ `get_num_masks` function inside in the `OneFormerLoss` class of `modeling_oneformer.py`. When training on multiple nodes, this should be
+ set to the average number of target masks across all nodes, as can be seen in the original implementation [here](https://github.com/SHI-Labs/OneFormer/blob/33ebb56ed34f970a30ae103e786c0cb64c653d9a/oneformer/modeling/criterion.py#L287).
+- One can use [`OneFormerProcessor`] to prepare input images and task inputs for the model and optional targets for the model. [`OneFormerProcessor`] wraps [`OneFormerImageProcessor`] and [`CLIPTokenizer`] into a single instance to both prepare the images and encode the task inputs.
+- To get the final segmentation, depending on the task, you can call [`~OneFormerProcessor.post_process_semantic_segmentation`] or [`~OneFormerImageProcessor.post_process_instance_segmentation`] or [`~OneFormerImageProcessor.post_process_panoptic_segmentation`]. All three tasks can be solved using [`OneFormerForUniversalSegmentation`] output, panoptic segmentation accepts an optional `label_ids_to_fuse` argument to fuse instances of the target object/s (e.g. sky) together.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with OneFormer.
+
+- Demo notebooks regarding inference + fine-tuning on custom data can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/OneFormer).
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we will review it.
+The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## OneFormer specific outputs
+
+[[autodoc]] models.oneformer.modeling_oneformer.OneFormerModelOutput
+
+[[autodoc]] models.oneformer.modeling_oneformer.OneFormerForUniversalSegmentationOutput
+
+## OneFormerConfig
+
+[[autodoc]] OneFormerConfig
+
+## OneFormerImageProcessor
+
+[[autodoc]] OneFormerImageProcessor
+ - preprocess
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## OneFormerImageProcessorFast
+
+[[autodoc]] OneFormerImageProcessorFast
+ - preprocess
+ - post_process_semantic_segmentation
+ - post_process_instance_segmentation
+ - post_process_panoptic_segmentation
+
+## OneFormerProcessor
+
+[[autodoc]] OneFormerProcessor
+
+## OneFormerModel
+
+[[autodoc]] OneFormerModel
+ - forward
+
+## OneFormerForUniversalSegmentation
+
+[[autodoc]] OneFormerForUniversalSegmentation
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/open-llama.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/open-llama.md
new file mode 100644
index 0000000000000000000000000000000000000000..38954cd315d0c76fc4d1edd6d4080580eb25e8ba
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/open-llama.md
@@ -0,0 +1,66 @@
+
+*This model was released on 2023-04-16 and added to Hugging Face Transformers on 2023-06-20.*
+
+# Open-Llama
+
+
 +
 +
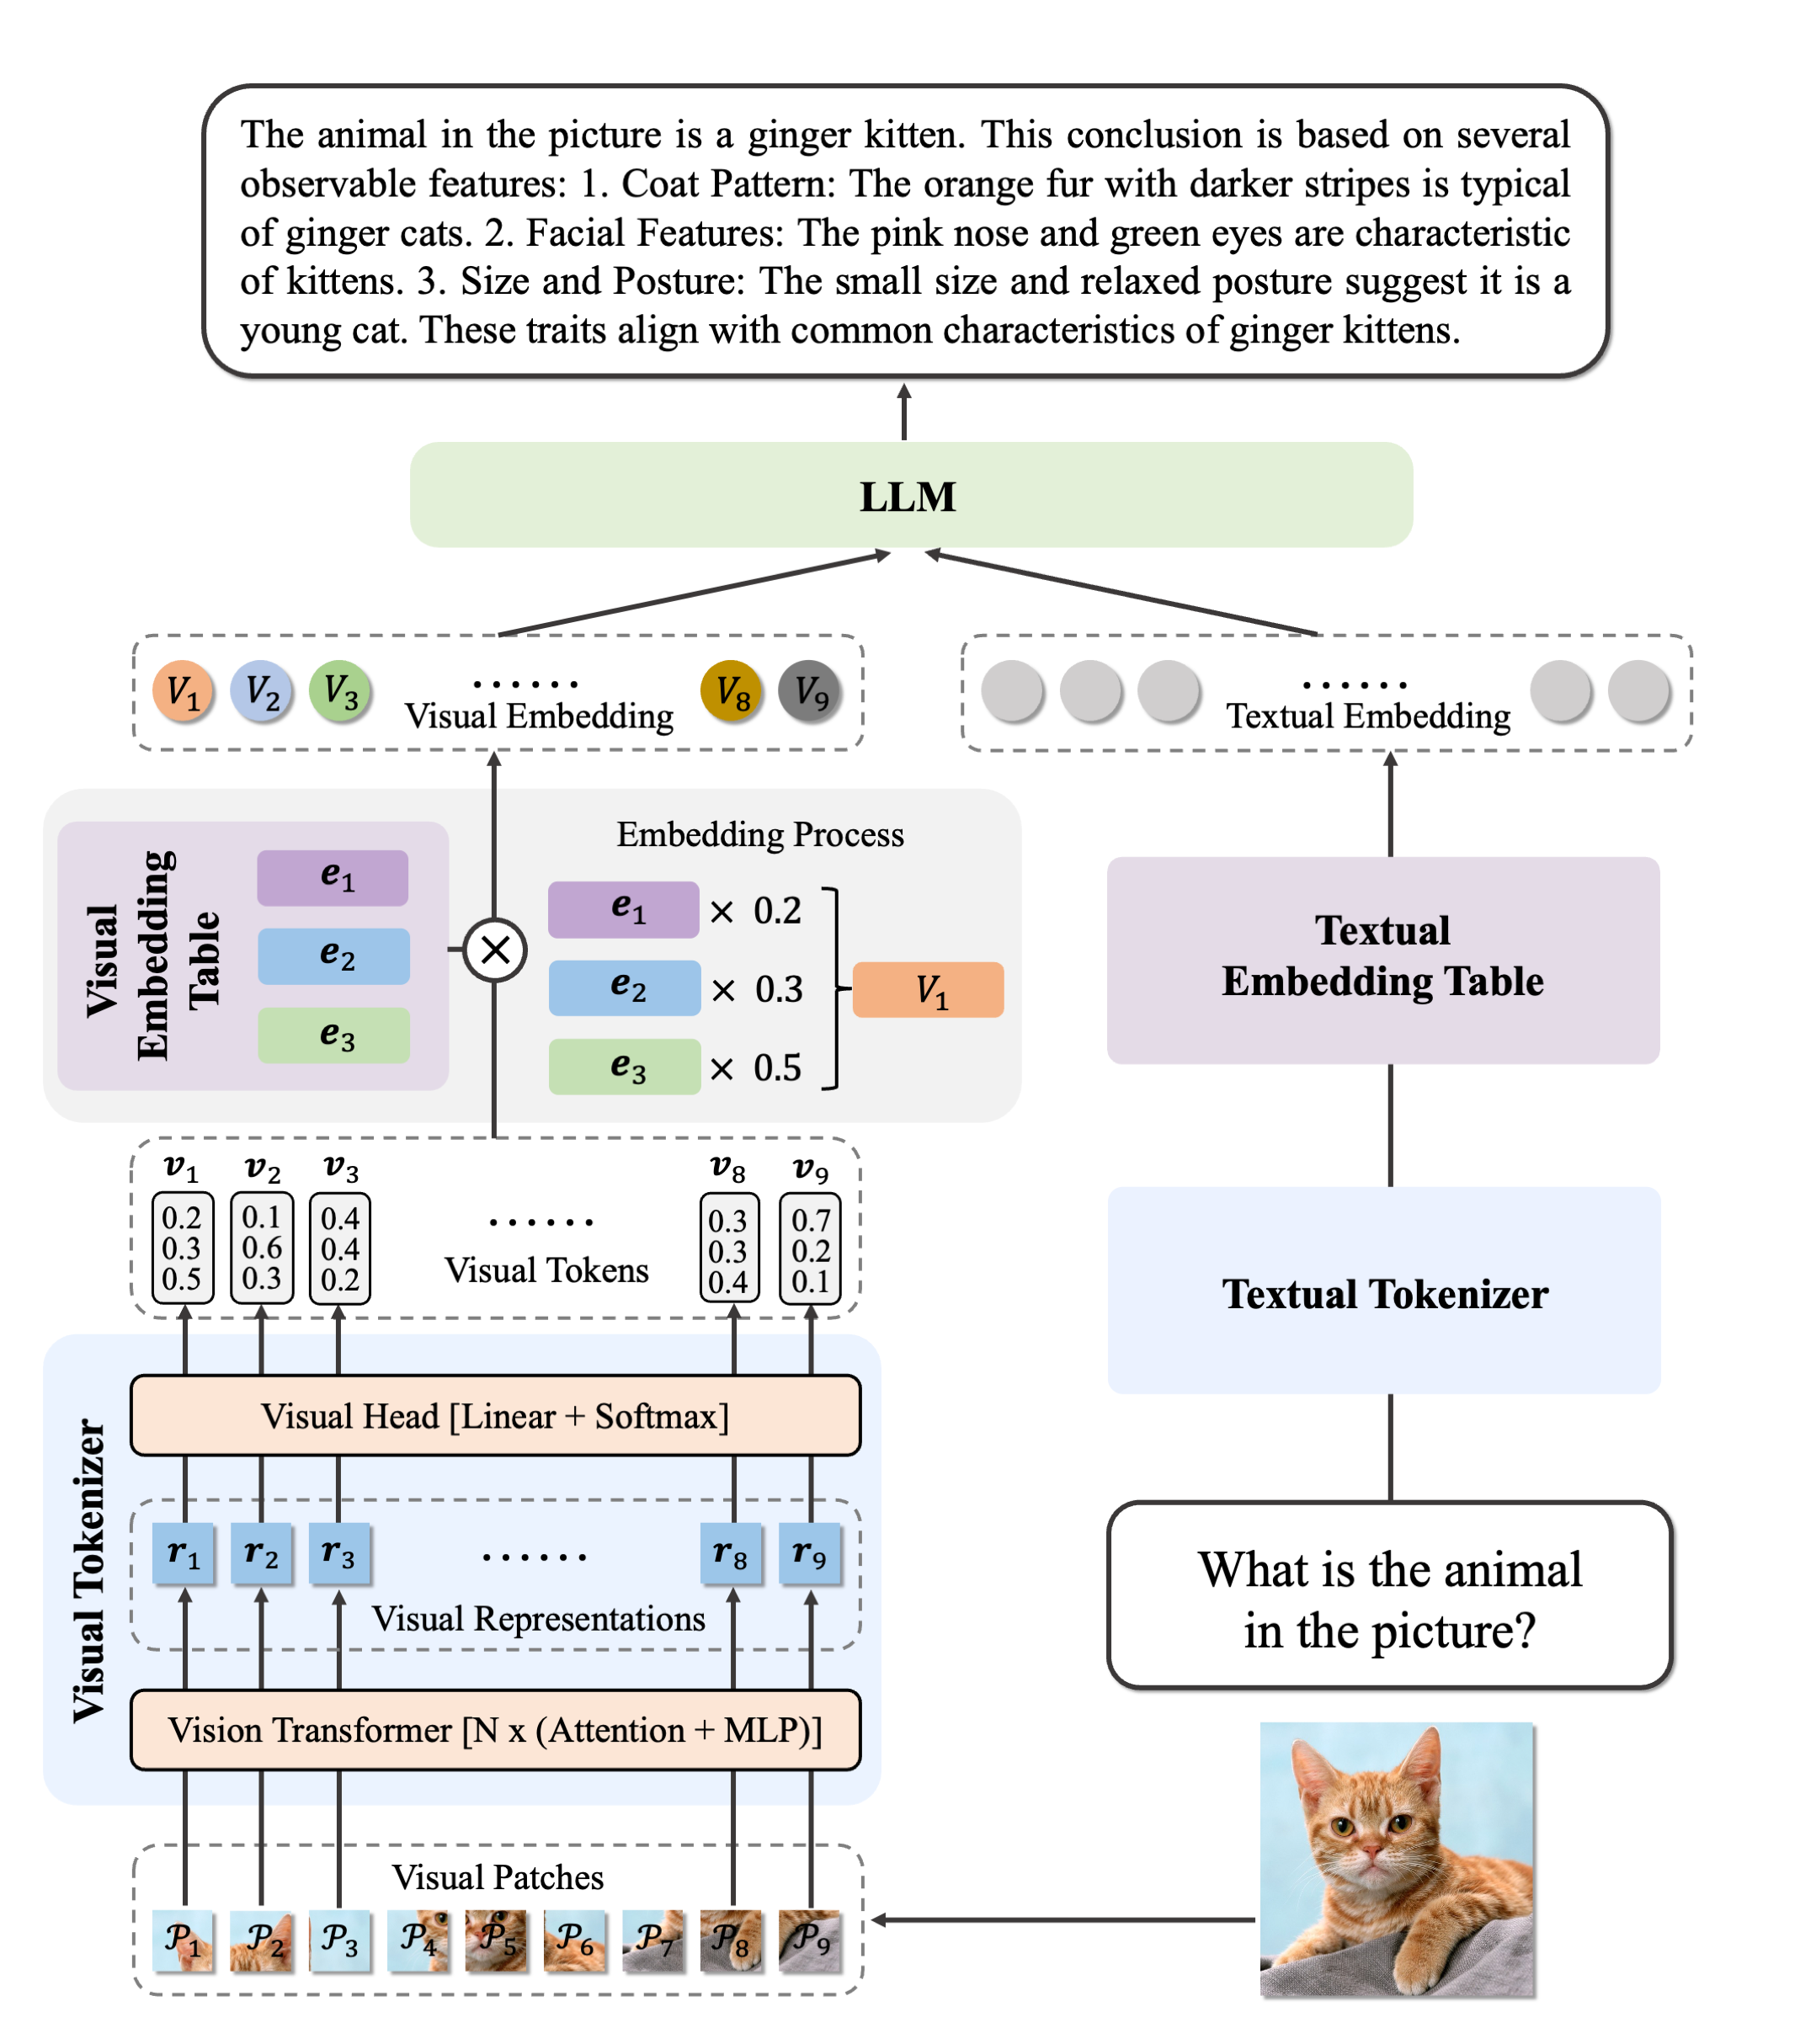 +
+ Ovis2 architecture.
+
+This model was contributed by [thisisiron](https://huggingface.co/thisisiron).
+
+## Usage example
+
+```python
+
+from PIL import Image
+import requests
+import torch
+from torchvision import io
+from typing import Dict
+from transformers.image_utils import load_images, load_video
+from transformers import AutoModelForVision2Seq, AutoTokenizer, AutoProcessor, infer_device
+
+device = f"{infer_device()}:0"
+
+model = AutoModelForVision2Seq.from_pretrained(
+ "thisisiron/Ovis2-2B-hf",
+ torch_dtype=torch.bfloat16,
+).eval().to(device)
+processor = AutoProcessor.from_pretrained("thisisiron/Ovis2-2B-hf")
+
+messages = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "Describe the image."},
+ ],
+ },
+]
+url = "http://images.cocodataset.org/val2014/COCO_val2014_000000537955.jpg"
+image = Image.open(requests.get(url, stream=True).raw)
+messages = processor.apply_chat_template(messages, tokenize=False, add_generation_prompt=True)
+print(messages)
+
+inputs = processor(
+ images=[image],
+ text=messages,
+ return_tensors="pt",
+)
+inputs = inputs.to(model.device)
+inputs['pixel_values'] = inputs['pixel_values'].to(torch.bfloat16)
+
+with torch.inference_mode():
+ output_ids = model.generate(**inputs, max_new_tokens=128, do_sample=False)
+ generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(inputs.input_ids, output_ids)]
+ output_text = processor.batch_decode(generated_ids, skip_special_tokens=True)
+ print(output_text)
+```
+
+## Ovis2Config
+
+[[autodoc]] Ovis2Config
+
+## Ovis2VisionConfig
+
+[[autodoc]] Ovis2VisionConfig
+
+## Ovis2Model
+
+[[autodoc]] Ovis2Model
+
+## Ovis2ForConditionalGeneration
+
+[[autodoc]] Ovis2ForConditionalGeneration
+ - forward
+
+## Ovis2ImageProcessor
+
+[[autodoc]] Ovis2ImageProcessor
+
+## Ovis2ImageProcessorFast
+
+[[autodoc]] Ovis2ImageProcessorFast
+
+## Ovis2Processor
+
+[[autodoc]] Ovis2Processor
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/owlv2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/owlv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..675dc1c9c0d5014e5d1c7ee295bf057d79d3dd28
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/owlv2.md
@@ -0,0 +1,145 @@
+
+*This model was released on 2023-06-16 and added to Hugging Face Transformers on 2023-10-13.*
+
+# OWLv2
+
+
 +
+ OWLv2 high-level overview. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/google-research/scenic/tree/main/scenic/projects/owl_vit).
+
+## Usage example
+
+OWLv2 is, just like its predecessor [OWL-ViT](owlvit), a zero-shot text-conditioned object detection model. OWL-ViT uses [CLIP](clip) as its multi-modal backbone, with a ViT-like Transformer to get visual features and a causal language model to get the text features. To use CLIP for detection, OWL-ViT removes the final token pooling layer of the vision model and attaches a lightweight classification and box head to each transformer output token. Open-vocabulary classification is enabled by replacing the fixed classification layer weights with the class-name embeddings obtained from the text model. The authors first train CLIP from scratch and fine-tune it end-to-end with the classification and box heads on standard detection datasets using a bipartite matching loss. One or multiple text queries per image can be used to perform zero-shot text-conditioned object detection.
+
+[`Owlv2ImageProcessor`] can be used to resize (or rescale) and normalize images for the model and [`CLIPTokenizer`] is used to encode the text. [`Owlv2Processor`] wraps [`Owlv2ImageProcessor`] and [`CLIPTokenizer`] into a single instance to both encode the text and prepare the images. The following example shows how to perform object detection using [`Owlv2Processor`] and [`Owlv2ForObjectDetection`].
+
+```python
+>>> import requests
+>>> from PIL import Image
+>>> import torch
+
+>>> from transformers import Owlv2Processor, Owlv2ForObjectDetection
+
+>>> processor = Owlv2Processor.from_pretrained("google/owlv2-base-patch16-ensemble")
+>>> model = Owlv2ForObjectDetection.from_pretrained("google/owlv2-base-patch16-ensemble")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> text_labels = [["a photo of a cat", "a photo of a dog"]]
+>>> inputs = processor(text=text_labels, images=image, return_tensors="pt")
+>>> outputs = model(**inputs)
+
+>>> # Target image sizes (height, width) to rescale box predictions [batch_size, 2]
+>>> target_sizes = torch.tensor([(image.height, image.width)])
+>>> # Convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax)
+>>> results = processor.post_process_grounded_object_detection(
+... outputs=outputs, target_sizes=target_sizes, threshold=0.1, text_labels=text_labels
+... )
+>>> # Retrieve predictions for the first image for the corresponding text queries
+>>> result = results[0]
+>>> boxes, scores, text_labels = result["boxes"], result["scores"], result["text_labels"]
+>>> for box, score, text_label in zip(boxes, scores, text_labels):
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"Detected {text_label} with confidence {round(score.item(), 3)} at location {box}")
+Detected a photo of a cat with confidence 0.614 at location [341.67, 23.39, 642.32, 371.35]
+Detected a photo of a cat with confidence 0.665 at location [6.75, 51.96, 326.62, 473.13]
+```
+
+## Resources
+
+- A demo notebook on using OWLv2 for zero- and one-shot (image-guided) object detection can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/OWLv2).
+- [Zero-shot object detection task guide](../tasks/zero_shot_object_detection)
+
+
 +
+ OWL-ViT architecture. Taken from the original paper.
+
+This model was contributed by [adirik](https://huggingface.co/adirik). The original code can be found [here](https://github.com/google-research/scenic/tree/main/scenic/projects/owl_vit).
+
+## Usage tips
+
+OWL-ViT is a zero-shot text-conditioned object detection model. OWL-ViT uses [CLIP](clip) as its multi-modal backbone, with a ViT-like Transformer to get visual features and a causal language model to get the text features. To use CLIP for detection, OWL-ViT removes the final token pooling layer of the vision model and attaches a lightweight classification and box head to each transformer output token. Open-vocabulary classification is enabled by replacing the fixed classification layer weights with the class-name embeddings obtained from the text model. The authors first train CLIP from scratch and fine-tune it end-to-end with the classification and box heads on standard detection datasets using a bipartite matching loss. One or multiple text queries per image can be used to perform zero-shot text-conditioned object detection.
+
+[`OwlViTImageProcessor`] can be used to resize (or rescale) and normalize images for the model and [`CLIPTokenizer`] is used to encode the text. [`OwlViTProcessor`] wraps [`OwlViTImageProcessor`] and [`CLIPTokenizer`] into a single instance to both encode the text and prepare the images. The following example shows how to perform object detection using [`OwlViTProcessor`] and [`OwlViTForObjectDetection`].
+
+```python
+>>> import requests
+>>> from PIL import Image
+>>> import torch
+
+>>> from transformers import OwlViTProcessor, OwlViTForObjectDetection
+
+>>> processor = OwlViTProcessor.from_pretrained("google/owlvit-base-patch32")
+>>> model = OwlViTForObjectDetection.from_pretrained("google/owlvit-base-patch32")
+
+>>> url = "http://images.cocodataset.org/val2017/000000039769.jpg"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+>>> text_labels = [["a photo of a cat", "a photo of a dog"]]
+>>> inputs = processor(text=text_labels, images=image, return_tensors="pt")
+>>> outputs = model(**inputs)
+
+>>> # Target image sizes (height, width) to rescale box predictions [batch_size, 2]
+>>> target_sizes = torch.tensor([(image.height, image.width)])
+>>> # Convert outputs (bounding boxes and class logits) to Pascal VOC format (xmin, ymin, xmax, ymax)
+>>> results = processor.post_process_grounded_object_detection(
+... outputs=outputs, target_sizes=target_sizes, threshold=0.1, text_labels=text_labels
+... )
+>>> # Retrieve predictions for the first image for the corresponding text queries
+>>> result = results[0]
+>>> boxes, scores, text_labels = result["boxes"], result["scores"], result["text_labels"]
+>>> for box, score, text_label in zip(boxes, scores, text_labels):
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"Detected {text_label} with confidence {round(score.item(), 3)} at location {box}")
+Detected a photo of a cat with confidence 0.707 at location [324.97, 20.44, 640.58, 373.29]
+Detected a photo of a cat with confidence 0.717 at location [1.46, 55.26, 315.55, 472.17]
+```
+
+## Resources
+
+A demo notebook on using OWL-ViT for zero- and one-shot (image-guided) object detection can be found [here](https://github.com/huggingface/notebooks/blob/main/examples/zeroshot_object_detection_with_owlvit.ipynb).
+
+## OwlViTConfig
+
+[[autodoc]] OwlViTConfig
+ - from_text_vision_configs
+
+## OwlViTTextConfig
+
+[[autodoc]] OwlViTTextConfig
+
+## OwlViTVisionConfig
+
+[[autodoc]] OwlViTVisionConfig
+
+## OwlViTImageProcessor
+
+[[autodoc]] OwlViTImageProcessor
+ - preprocess
+
+## OwlViTImageProcessorFast
+
+[[autodoc]] OwlViTImageProcessorFast
+ - preprocess
+ - post_process_object_detection
+ - post_process_image_guided_detection
+
+## OwlViTProcessor
+
+[[autodoc]] OwlViTProcessor
+ - __call__
+ - post_process_grounded_object_detection
+ - post_process_image_guided_detection
+
+## OwlViTModel
+
+[[autodoc]] OwlViTModel
+ - forward
+ - get_text_features
+ - get_image_features
+
+## OwlViTTextModel
+
+[[autodoc]] OwlViTTextModel
+ - forward
+
+## OwlViTVisionModel
+
+[[autodoc]] OwlViTVisionModel
+ - forward
+
+## OwlViTForObjectDetection
+
+[[autodoc]] OwlViTForObjectDetection
+ - forward
+ - image_guided_detection
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/paligemma.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/paligemma.md
new file mode 100644
index 0000000000000000000000000000000000000000..2ff64076d53a0f1fc199a2d678888f8548398e59
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/paligemma.md
@@ -0,0 +1,185 @@
+
+*This model was released on 2024-07-10 and added to Hugging Face Transformers on 2024-05-14.*
+
+
 +
 +
+ Perceiver IO architecture. Taken from the original paper
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be found
+[here](https://github.com/deepmind/deepmind-research/tree/master/perceiver).
+
+
 +
 +
+ Pixtral architecture. Taken from the blog post.
+
+Tips:
+
+- Pixtral is a multimodal model, taking images and text as input, and producing text as output.
+- This model follows the [Llava](llava) architecture. The model uses [`PixtralVisionModel`] for its vision encoder, and [`MistralForCausalLM`] for its language decoder.
+- The main contribution is the 2d ROPE (rotary position embeddings) on the images, and support for arbitrary image sizes (the images are not padded together nor are they resized).
+- Similar to [Llava](llava), the model internally replaces the `[IMG]` token placeholders by image embeddings from the vision encoder. The format for one or multiple prompts is the following:
+```
+"
 +
+This model was contributed by [heytanay](https://huggingface.co/heytanay). The original code can be found [here](https://github.com/sail-sg/poolformer).
+
+## Usage tips
+
+- PoolFormer has a hierarchical architecture, where instead of Attention, a simple Average Pooling layer is present. All checkpoints of the model can be found on the [hub](https://huggingface.co/models?other=poolformer).
+- One can use [`PoolFormerImageProcessor`] to prepare images for the model.
+- As most models, PoolFormer comes in different sizes, the details of which can be found in the table below.
+
+| **Model variant** | **Depths** | **Hidden sizes** | **Params (M)** | **ImageNet-1k Top 1** |
+| :---------------: | ------------- | ------------------- | :------------: | :-------------------: |
+| s12 | [2, 2, 6, 2] | [64, 128, 320, 512] | 12 | 77.2 |
+| s24 | [4, 4, 12, 4] | [64, 128, 320, 512] | 21 | 80.3 |
+| s36 | [6, 6, 18, 6] | [64, 128, 320, 512] | 31 | 81.4 |
+| m36 | [6, 6, 18, 6] | [96, 192, 384, 768] | 56 | 82.1 |
+| m48 | [8, 8, 24, 8] | [96, 192, 384, 768] | 73 | 82.5 |
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with PoolFormer.
+
+
 +
+ Prompt Depth Anything overview. Taken from the original paper.
+
+## Usage example
+
+The Transformers library allows you to use the model with just a few lines of code:
+
+```python
+>>> import torch
+>>> import requests
+>>> import numpy as np
+
+>>> from PIL import Image
+>>> from transformers import AutoImageProcessor, AutoModelForDepthEstimation
+
+>>> url = "https://github.com/DepthAnything/PromptDA/blob/main/assets/example_images/image.jpg?raw=true"
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> image_processor = AutoImageProcessor.from_pretrained("depth-anything/prompt-depth-anything-vits-hf")
+>>> model = AutoModelForDepthEstimation.from_pretrained("depth-anything/prompt-depth-anything-vits-hf")
+
+>>> prompt_depth_url = "https://github.com/DepthAnything/PromptDA/blob/main/assets/example_images/arkit_depth.png?raw=true"
+>>> prompt_depth = Image.open(requests.get(prompt_depth_url, stream=True).raw)
+>>> # the prompt depth can be None, and the model will output a monocular relative depth.
+
+>>> # prepare image for the model
+>>> inputs = image_processor(images=image, return_tensors="pt", prompt_depth=prompt_depth)
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> # interpolate to original size
+>>> post_processed_output = image_processor.post_process_depth_estimation(
+... outputs,
+... target_sizes=[(image.height, image.width)],
+... )
+
+>>> # visualize the prediction
+>>> predicted_depth = post_processed_output[0]["predicted_depth"]
+>>> depth = predicted_depth * 1000
+>>> depth = depth.detach().cpu().numpy()
+>>> depth = Image.fromarray(depth.astype("uint16")) # mm
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with Prompt Depth Anything.
+
+- [Prompt Depth Anything Demo](https://huggingface.co/spaces/depth-anything/PromptDA)
+- [Prompt Depth Anything Interactive Results](https://promptda.github.io/interactive.html)
+
+If you are interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## PromptDepthAnythingConfig
+
+[[autodoc]] PromptDepthAnythingConfig
+
+## PromptDepthAnythingForDepthEstimation
+
+[[autodoc]] PromptDepthAnythingForDepthEstimation
+ - forward
+
+## PromptDepthAnythingImageProcessor
+
+[[autodoc]] PromptDepthAnythingImageProcessor
+ - preprocess
+ - post_process_depth_estimation
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/prophetnet.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/prophetnet.md
new file mode 100644
index 0000000000000000000000000000000000000000..19131b75ce02b5de34c48afc4a866cb625b17ac6
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/prophetnet.md
@@ -0,0 +1,99 @@
+
+*This model was released on 2020-01-13 and added to Hugging Face Transformers on 2020-11-16.*
+
+# ProphetNet
+
+
 +
+ Qwen2-VL architecture. Taken from the blog post.
+
+This model was contributed by [simonJJJ](https://huggingface.co/simonJJJ).
+
+## Usage example
+
+### Single Media inference
+
+The model can accept both images and videos as input. Here's an example code for inference.
+
+```python
+
+import torch
+from transformers import Qwen2VLForConditionalGeneration, AutoTokenizer, AutoProcessor
+
+# Load the model in half-precision on the available device(s)
+model = Qwen2VLForConditionalGeneration.from_pretrained("Qwen/Qwen2-VL-7B-Instruct", device_map="auto")
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-VL-7B-Instruct")
+
+
+conversation = [
+ {
+ "role":"user",
+ "content":[
+ {
+ "type":"image",
+ "url": "https://qianwen-res.oss-cn-beijing.aliyuncs.com/Qwen-VL/assets/demo.jpeg"
+ },
+ {
+ "type":"text",
+ "text":"Describe this image."
+ }
+ ]
+ }
+]
+
+inputs = processor.apply_chat_template(
+ conversation,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+).to(model.device)
+
+# Inference: Generation of the output
+output_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(inputs.input_ids, output_ids)]
+output_text = processor.batch_decode(generated_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+print(output_text)
+
+
+
+# Video
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "video", "path": "/path/to/video.mp4"},
+ {"type": "text", "text": "What happened in the video?"},
+ ],
+ }
+]
+
+inputs = processor.apply_chat_template(
+ conversation,
+ video_fps=1,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+).to(model.device)
+
+
+# Inference: Generation of the output
+output_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(inputs.input_ids, output_ids)]
+output_text = processor.batch_decode(generated_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+print(output_text)
+```
+
+### Batch Mixed Media Inference
+
+The model can batch inputs composed of mixed samples of various types such as images, videos, and text. Here is an example.
+
+```python
+
+# Conversation for the first image
+conversation1 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "path": "/path/to/image1.jpg"},
+ {"type": "text", "text": "Describe this image."}
+ ]
+ }
+]
+
+# Conversation with two images
+conversation2 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "path": "/path/to/image2.jpg"},
+ {"type": "image", "path": "/path/to/image3.jpg"},
+ {"type": "text", "text": "What is written in the pictures?"}
+ ]
+ }
+]
+
+# Conversation with pure text
+conversation3 = [
+ {
+ "role": "user",
+ "content": "who are you?"
+ }
+]
+
+
+# Conversation with mixed midia
+conversation4 = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image", "path": "/path/to/image3.jpg"},
+ {"type": "image", "path": "/path/to/image4.jpg"},
+ {"type": "video", "path": "/path/to/video.jpg"},
+ {"type": "text", "text": "What are the common elements in these medias?"},
+ ],
+ }
+]
+
+conversations = [conversation1, conversation2, conversation3, conversation4]
+# Preparation for batch inference
+ipnuts = processor.apply_chat_template(
+ conversations,
+ video_fps=1,
+ add_generation_prompt=True,
+ tokenize=True,
+ return_dict=True,
+ return_tensors="pt"
+).to(model.device)
+
+
+# Batch Inference
+output_ids = model.generate(**inputs, max_new_tokens=128)
+generated_ids = [output_ids[len(input_ids):] for input_ids, output_ids in zip(inputs.input_ids, output_ids)]
+output_text = processor.batch_decode(generated_ids, skip_special_tokens=True, clean_up_tokenization_spaces=True)
+print(output_text)
+```
+
+### Usage Tips
+
+#### Image Resolution trade-off
+
+The model supports a wide range of resolution inputs. By default, it uses the native resolution for input, but higher resolutions can enhance performance at the cost of more computation. Users can set the minimum and maximum number of pixels to achieve an optimal configuration for their needs.
+
+```python
+min_pixels = 224*224
+max_pixels = 2048*2048
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-VL-7B-Instruct", min_pixels=min_pixels, max_pixels=max_pixels)
+```
+
+In case of limited GPU RAM, one can reduce the resolution as follows:
+
+```python
+min_pixels = 256*28*28
+max_pixels = 1024*28*28
+processor = AutoProcessor.from_pretrained("Qwen/Qwen2-VL-7B-Instruct", min_pixels=min_pixels, max_pixels=max_pixels)
+```
+This ensures each image gets encoded using a number between 256-1024 tokens. The 28 comes from the fact that the model uses a patch size of 14 and a temporal patch size of 2 (14 x 2 = 28).
+
+
+#### Multiple Image Inputs
+
+By default, images and video content are directly included in the conversation. When handling multiple images, it's helpful to add labels to the images and videos for better reference. Users can control this behavior with the following settings:
+
+```python
+conversation = [
+ {
+ "role": "user",
+ "content": [
+ {"type": "image"},
+ {"type": "text", "text": "Hello, how are you?"}
+ ]
+ },
+ {
+ "role": "assistant",
+ "content": "I'm doing well, thank you for asking. How can I assist you today?"
+ },
+ {
+ "role": "user",
+ "content": [
+ {"type": "text", "text": "Can you describe these images and video?"},
+ {"type": "image"},
+ {"type": "image"},
+ {"type": "video"},
+ {"type": "text", "text": "These are from my vacation."}
+ ]
+ },
+ {
+ "role": "assistant",
+ "content": "I'd be happy to describe the images and video for you. Could you please provide more context about your vacation?"
+ },
+ {
+ "role": "user",
+ "content": "It was a trip to the mountains. Can you see the details in the images and video?"
+ }
+]
+
+# default:
+prompt_without_id = processor.apply_chat_template(conversation, add_generation_prompt=True)
+# Excepted output: '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n<|im_start|>user\n<|vision_start|><|image_pad|><|vision_end|>Hello, how are you?<|im_end|>\n<|im_start|>assistant\nI'm doing well, thank you for asking. How can I assist you today?<|im_end|>\n<|im_start|>user\nCan you describe these images and video?<|vision_start|><|image_pad|><|vision_end|><|vision_start|><|image_pad|><|vision_end|><|vision_start|><|video_pad|><|vision_end|>These are from my vacation.<|im_end|>\n<|im_start|>assistant\nI'd be happy to describe the images and video for you. Could you please provide more context about your vacation?<|im_end|>\n<|im_start|>user\nIt was a trip to the mountains. Can you see the details in the images and video?<|im_end|>\n<|im_start|>assistant\n'
+
+
+# add ids
+prompt_with_id = processor.apply_chat_template(conversation, add_generation_prompt=True, add_vision_id=True)
+# Excepted output: '<|im_start|>system\nYou are a helpful assistant.<|im_end|>\n<|im_start|>user\nPicture 1: <|vision_start|><|image_pad|><|vision_end|>Hello, how are you?<|im_end|>\n<|im_start|>assistant\nI'm doing well, thank you for asking. How can I assist you today?<|im_end|>\n<|im_start|>user\nCan you describe these images and video?Picture 2: <|vision_start|><|image_pad|><|vision_end|>Picture 3: <|vision_start|><|image_pad|><|vision_end|>Video 1: <|vision_start|><|video_pad|><|vision_end|>These are from my vacation.<|im_end|>\n<|im_start|>assistant\nI'd be happy to describe the images and video for you. Could you please provide more context about your vacation?<|im_end|>\n<|im_start|>user\nIt was a trip to the mountains. Can you see the details in the images and video?<|im_end|>\n<|im_start|>assistant\n'
+
+```
+
+#### Flash-Attention 2 to speed up generation
+
+First, make sure to install the latest version of Flash Attention 2:
+
+```bash
+pip install -U flash-attn --no-build-isolation
+```
+
+Also, you should have a hardware that is compatible with Flash-Attention 2. Read more about it in the official documentation of the [flash attention repository](https://github.com/Dao-AILab/flash-attention). FlashAttention-2 can only be used when a model is loaded in `torch.float16` or `torch.bfloat16`.
+
+To load and run a model using Flash Attention-2, simply add `attn_implementation="flash_attention_2"` when loading the model as follows:
+
+```python
+from transformers import Qwen2VLForConditionalGeneration
+
+model = Qwen2VLForConditionalGeneration.from_pretrained(
+ "Qwen/Qwen2-VL-7B-Instruct",
+ torch_dtype=torch.bfloat16,
+ attn_implementation="flash_attention_2",
+)
+```
+
+## Qwen2VLConfig
+
+[[autodoc]] Qwen2VLConfig
+
+## Qwen2VLTextConfig
+
+[[autodoc]] Qwen2VLTextConfig
+
+## Qwen2VLImageProcessor
+
+[[autodoc]] Qwen2VLImageProcessor
+ - preprocess
+
+## Qwen2VLVideoProcessor
+
+[[autodoc]] Qwen2VLVideoProcessor
+ - preprocess
+
+## Qwen2VLImageProcessorFast
+
+[[autodoc]] Qwen2VLImageProcessorFast
+ - preprocess
+
+## Qwen2VLProcessor
+
+[[autodoc]] Qwen2VLProcessor
+
+## Qwen2VLTextModel
+
+[[autodoc]] Qwen2VLTextModel
+ - forward
+
+## Qwen2VLModel
+
+[[autodoc]] Qwen2VLModel
+ - forward
+
+## Qwen2VLForConditionalGeneration
+
+[[autodoc]] Qwen2VLForConditionalGeneration
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen3.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen3.md
new file mode 100644
index 0000000000000000000000000000000000000000..87e6ba500f969cbd1b5017e0cc6cb0776f3e97c2
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen3.md
@@ -0,0 +1,60 @@
+
+*This model was released on 2025-04-29 and added to Hugging Face Transformers on 2025-03-31.*
+
+# Qwen3
+
+## Overview
+
+[Qwen3](https://huggingface.co/papers/2505.09388) refers to the dense model architecture Qwen3-32B which was released with its mixture of experts variant [Qwen3MoE](qwen3_moe) ([blog post](https://qwenlm.github.io/blog/qwen3/)).
+
+### Model Details
+
+To be released with the official model launch.
+
+
+## Usage tips
+
+To be released with the official model launch.
+
+## Qwen3Config
+
+[[autodoc]] Qwen3Config
+
+## Qwen3Model
+
+[[autodoc]] Qwen3Model
+ - forward
+
+## Qwen3ForCausalLM
+
+[[autodoc]] Qwen3ForCausalLM
+ - forward
+
+## Qwen3ForSequenceClassification
+
+[[autodoc]] Qwen3ForSequenceClassification
+ - forward
+
+## Qwen3ForTokenClassification
+
+[[autodoc]] Qwen3ForTokenClassification
+ - forward
+
+## Qwen3ForQuestionAnswering
+
+[[autodoc]] Qwen3ForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen3_moe.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen3_moe.md
new file mode 100644
index 0000000000000000000000000000000000000000..2d1090f1e90a8598696cd07111479d6554c0ba63
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/qwen3_moe.md
@@ -0,0 +1,59 @@
+
+*This model was released on 2025-04-29 and added to Hugging Face Transformers on 2025-03-31.*
+
+# Qwen3MoE
+
+## Overview
+
+[Qwen3MoE](https://huggingface.co/papers/2505.09388) refers to the mixture of experts model architecture Qwen3-235B-A22B which was released with its dense variant [Qwen3](qwen3) ([blog post](https://qwenlm.github.io/blog/qwen3/)).
+
+### Model Details
+
+To be released with the official model launch.
+
+## Usage tips
+
+To be released with the official model launch.
+
+## Qwen3MoeConfig
+
+[[autodoc]] Qwen3MoeConfig
+
+## Qwen3MoeModel
+
+[[autodoc]] Qwen3MoeModel
+ - forward
+
+## Qwen3MoeForCausalLM
+
+[[autodoc]] Qwen3MoeForCausalLM
+ - forward
+
+## Qwen3MoeForSequenceClassification
+
+[[autodoc]] Qwen3MoeForSequenceClassification
+ - forward
+
+## Qwen3MoeForTokenClassification
+
+[[autodoc]] Qwen3MoeForTokenClassification
+ - forward
+
+## Qwen3MoeForQuestionAnswering
+
+[[autodoc]] Qwen3MoeForQuestionAnswering
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rag.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rag.md
new file mode 100644
index 0000000000000000000000000000000000000000..55de807ccd09e34cf99ff0a21cf2f5e5ba42754e
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/rag.md
@@ -0,0 +1,149 @@
+
+*This model was released on 2020-05-22 and added to Hugging Face Transformers on 2020-11-16.*
+
+# RAG
+
+
 +
+This model was contributed by [Francesco](https://huggingface.co/Francesco). The TensorFlow version of this model was added by [amyeroberts](https://huggingface.co/amyeroberts). The original code can be found [here](https://github.com/KaimingHe/deep-residual-networks).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with ResNet.
+
+
 +
+ RT-DETR performance relative to YOLO models. Taken from the original paper.
+
+The model version was contributed by [rafaelpadilla](https://huggingface.co/rafaelpadilla) and [sangbumchoi](https://github.com/SangbumChoi). The original code can be found [here](https://github.com/lyuwenyu/RT-DETR/).
+
+
+## Usage tips
+
+Initially, an image is processed using a pre-trained convolutional neural network, specifically a Resnet-D variant as referenced in the original code. This network extracts features from the final three layers of the architecture. Following this, a hybrid encoder is employed to convert the multi-scale features into a sequential array of image features. Then, a decoder, equipped with auxiliary prediction heads is used to refine the object queries. This process facilitates the direct generation of bounding boxes, eliminating the need for any additional post-processing to acquire the logits and coordinates for the bounding boxes.
+
+```py
+>>> import torch
+>>> import requests
+
+>>> from PIL import Image
+>>> from transformers import RTDetrForObjectDetection, RTDetrImageProcessor
+
+>>> url = 'http://images.cocodataset.org/val2017/000000039769.jpg'
+>>> image = Image.open(requests.get(url, stream=True).raw)
+
+>>> image_processor = RTDetrImageProcessor.from_pretrained("PekingU/rtdetr_r50vd")
+>>> model = RTDetrForObjectDetection.from_pretrained("PekingU/rtdetr_r50vd")
+
+>>> inputs = image_processor(images=image, return_tensors="pt")
+
+>>> with torch.no_grad():
+... outputs = model(**inputs)
+
+>>> results = image_processor.post_process_object_detection(outputs, target_sizes=torch.tensor([(image.height, image.width)]), threshold=0.3)
+
+>>> for result in results:
+... for score, label_id, box in zip(result["scores"], result["labels"], result["boxes"]):
+... score, label = score.item(), label_id.item()
+... box = [round(i, 2) for i in box.tolist()]
+... print(f"{model.config.id2label[label]}: {score:.2f} {box}")
+sofa: 0.97 [0.14, 0.38, 640.13, 476.21]
+cat: 0.96 [343.38, 24.28, 640.14, 371.5]
+cat: 0.96 [13.23, 54.18, 318.98, 472.22]
+remote: 0.95 [40.11, 73.44, 175.96, 118.48]
+remote: 0.92 [333.73, 76.58, 369.97, 186.99]
+```
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with RT-DETR.
+
+
 +
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The TensorFlow version
+of the model was contributed by [sayakpaul](https://huggingface.co/sayakpaul). The original code can be found [here](https://github.com/NVlabs/SegFormer).
+
+## Usage tips
+
+- SegFormer consists of a hierarchical Transformer encoder, and a lightweight all-MLP decoder head.
+ [`SegformerModel`] is the hierarchical Transformer encoder (which in the paper is also referred to
+ as Mix Transformer or MiT). [`SegformerForSemanticSegmentation`] adds the all-MLP decoder head on
+ top to perform semantic segmentation of images. In addition, there's
+ [`SegformerForImageClassification`] which can be used to - you guessed it - classify images. The
+ authors of SegFormer first pre-trained the Transformer encoder on ImageNet-1k to classify images. Next, they throw
+ away the classification head, and replace it by the all-MLP decode head. Next, they fine-tune the model altogether on
+ ADE20K, Cityscapes and COCO-stuff, which are important benchmarks for semantic segmentation. All checkpoints can be
+ found on the [hub](https://huggingface.co/models?other=segformer).
+- The quickest way to get started with SegFormer is by checking the [example notebooks](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/SegFormer) (which showcase both inference and
+ fine-tuning on custom data). One can also check out the [blog post](https://huggingface.co/blog/fine-tune-segformer) introducing SegFormer and illustrating how it can be fine-tuned on custom data.
+- TensorFlow users should refer to [this repository](https://github.com/deep-diver/segformer-tf-transformers) that shows off-the-shelf inference and fine-tuning.
+- One can also check out [this interactive demo on Hugging Face Spaces](https://huggingface.co/spaces/chansung/segformer-tf-transformers)
+ to try out a SegFormer model on custom images.
+- SegFormer works on any input size, as it pads the input to be divisible by `config.patch_sizes`.
+- One can use [`SegformerImageProcessor`] to prepare images and corresponding segmentation maps
+ for the model. Note that this image processor is fairly basic and does not include all data augmentations used in
+ the original paper. The original preprocessing pipelines (for the ADE20k dataset for instance) can be found [here](https://github.com/NVlabs/SegFormer/blob/master/local_configs/_base_/datasets/ade20k_repeat.py). The most
+ important preprocessing step is that images and segmentation maps are randomly cropped and padded to the same size,
+ such as 512x512 or 640x640, after which they are normalized.
+- One additional thing to keep in mind is that one can initialize [`SegformerImageProcessor`] with
+ `do_reduce_labels` set to `True` or `False`. In some datasets (like ADE20k), the 0 index is used in the annotated
+ segmentation maps for background. However, ADE20k doesn't include the "background" class in its 150 labels.
+ Therefore, `do_reduce_labels` is used to reduce all labels by 1, and to make sure no loss is computed for the
+ background class (i.e. it replaces 0 in the annotated maps by 255, which is the *ignore_index* of the loss function
+ used by [`SegformerForSemanticSegmentation`]). However, other datasets use the 0 index as
+ background class and include this class as part of all labels. In that case, `do_reduce_labels` should be set to
+ `False`, as loss should also be computed for the background class.
+- As most models, SegFormer comes in different sizes, the details of which can be found in the table below
+ (taken from Table 7 of the [original paper](https://huggingface.co/papers/2105.15203)).
+
+| **Model variant** | **Depths** | **Hidden sizes** | **Decoder hidden size** | **Params (M)** | **ImageNet-1k Top 1** |
+| :---------------: | ------------- | ------------------- | :---------------------: | :------------: | :-------------------: |
+| MiT-b0 | [2, 2, 2, 2] | [32, 64, 160, 256] | 256 | 3.7 | 70.5 |
+| MiT-b1 | [2, 2, 2, 2] | [64, 128, 320, 512] | 256 | 14.0 | 78.7 |
+| MiT-b2 | [3, 4, 6, 3] | [64, 128, 320, 512] | 768 | 25.4 | 81.6 |
+| MiT-b3 | [3, 4, 18, 3] | [64, 128, 320, 512] | 768 | 45.2 | 83.1 |
+| MiT-b4 | [3, 8, 27, 3] | [64, 128, 320, 512] | 768 | 62.6 | 83.6 |
+| MiT-b5 | [3, 6, 40, 3] | [64, 128, 320, 512] | 768 | 82.0 | 83.8 |
+
+Note that MiT in the above table refers to the Mix Transformer encoder backbone introduced in SegFormer. For
+SegFormer's results on the segmentation datasets like ADE20k, refer to the [paper](https://huggingface.co/papers/2105.15203).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with SegFormer.
+
+
 +
 +
+You can find all the original SuperPoint checkpoints under the [Magic Leap Community](https://huggingface.co/magic-leap-community) organization.
+
+> [!TIP]
+> This model was contributed by [stevenbucaille](https://huggingface.co/stevenbucaille).
+>
+> Click on the SuperPoint models in the right sidebar for more examples of how to apply SuperPoint to different computer vision tasks.
+
+
+
+The example below demonstrates how to detect interest points in an image with the [`AutoModel`] class.
+
 +
 +
+ Swin2SR architecture. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/mv-lab/swin2sr).
+
+## Resources
+
+Demo notebooks for Swin2SR can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/Swin2SR).
+
+A demo Space for image super-resolution with SwinSR can be found [here](https://huggingface.co/spaces/jjourney1125/swin2sr).
+
+## Swin2SRImageProcessor
+
+[[autodoc]] Swin2SRImageProcessor
+ - preprocess
+
+## Swin2SRImageProcessorFast
+
+[[autodoc]] Swin2SRImageProcessorFast
+ - preprocess
+
+## Swin2SRConfig
+
+[[autodoc]] Swin2SRConfig
+
+## Swin2SRModel
+
+[[autodoc]] Swin2SRModel
+ - forward
+
+## Swin2SRForImageSuperResolution
+
+[[autodoc]] Swin2SRForImageSuperResolution
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/swinv2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/swinv2.md
new file mode 100644
index 0000000000000000000000000000000000000000..87de7aefa411d4459019644b201127eae2556985
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/swinv2.md
@@ -0,0 +1,104 @@
+
+*This model was released on 2021-11-18 and added to Hugging Face Transformers on 2022-07-27.*
+
+
 +
+ Table detection and table structure recognition clarified. Taken from the original paper.
+
+The authors released 2 models, one for [table detection](https://huggingface.co/microsoft/table-transformer-detection) in
+documents, one for [table structure recognition](https://huggingface.co/microsoft/table-transformer-structure-recognition)
+(the task of recognizing the individual rows, columns etc. in a table).
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code can be
+found [here](https://github.com/microsoft/table-transformer).
+
+## Resources
+
+
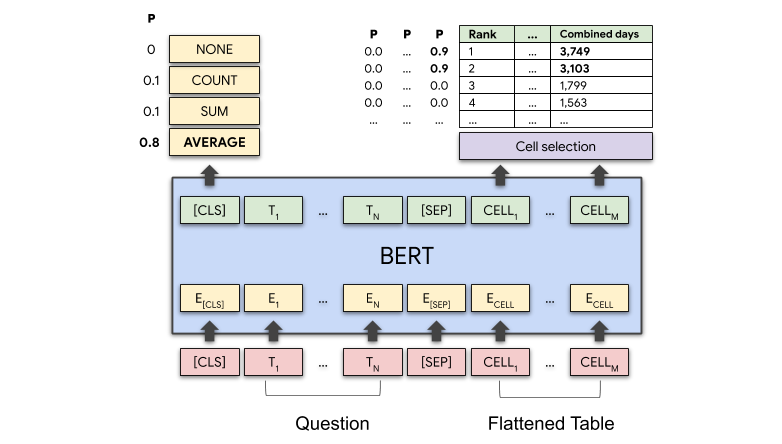 +
+ TAPAS architecture. Taken from the original blog post.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The Tensorflow version of this model was contributed by [kamalkraj](https://huggingface.co/kamalkraj). The original code can be found [here](https://github.com/google-research/tapas).
+
+## Usage tips
+
+- TAPAS is a model that uses relative position embeddings by default (restarting the position embeddings at every cell of the table). Note that this is something that was added after the publication of the original TAPAS paper. According to the authors, this usually results in a slightly better performance, and allows you to encode longer sequences without running out of embeddings. This is reflected in the `reset_position_index_per_cell` parameter of [`TapasConfig`], which is set to `True` by default. The default versions of the models available on the [hub](https://huggingface.co/models?search=tapas) all use relative position embeddings. You can still use the ones with absolute position embeddings by passing in an additional argument `revision="no_reset"` when calling the `from_pretrained()` method. Note that it's usually advised to pad the inputs on the right rather than the left.
+- TAPAS is based on BERT, so `TAPAS-base` for example corresponds to a `BERT-base` architecture. Of course, `TAPAS-large` will result in the best performance (the results reported in the paper are from `TAPAS-large`). Results of the various sized models are shown on the [original GitHub repository](https://github.com/google-research/tapas).
+- TAPAS has checkpoints fine-tuned on SQA, which are capable of answering questions related to a table in a conversational set-up. This means that you can ask follow-up questions such as "what is his age?" related to the previous question. Note that the forward pass of TAPAS is a bit different in case of a conversational set-up: in that case, you have to feed every table-question pair one by one to the model, such that the `prev_labels` token type ids can be overwritten by the predicted `labels` of the model to the previous question. See "Usage" section for more info.
+- TAPAS is similar to BERT and therefore relies on the masked language modeling (MLM) objective. It is therefore efficient at predicting masked tokens and at NLU in general, but is not optimal for text generation. Models trained with a causal language modeling (CLM) objective are better in that regard. Note that TAPAS can be used as an encoder in the EncoderDecoderModel framework, to combine it with an autoregressive text decoder such as GPT-2.
+
+## Usage: fine-tuning
+
+Here we explain how you can fine-tune [`TapasForQuestionAnswering`] on your own dataset.
+
+**STEP 1: Choose one of the 3 ways in which you can use TAPAS - or experiment**
+
+Basically, there are 3 different ways in which one can fine-tune [`TapasForQuestionAnswering`], corresponding to the different datasets on which Tapas was fine-tuned:
+
+1. SQA: if you're interested in asking follow-up questions related to a table, in a conversational set-up. For example if you first ask "what's the name of the first actor?" then you can ask a follow-up question such as "how old is he?". Here, questions do not involve any aggregation (all questions are cell selection questions).
+2. WTQ: if you're not interested in asking questions in a conversational set-up, but rather just asking questions related to a table, which might involve aggregation, such as counting a number of rows, summing up cell values or averaging cell values. You can then for example ask "what's the total number of goals Cristiano Ronaldo made in his career?". This case is also called **weak supervision**, since the model itself must learn the appropriate aggregation operator (SUM/COUNT/AVERAGE/NONE) given only the answer to the question as supervision.
+3. WikiSQL-supervised: this dataset is based on WikiSQL with the model being given the ground truth aggregation operator during training. This is also called **strong supervision**. Here, learning the appropriate aggregation operator is much easier.
+
+To summarize:
+
+| **Task** | **Example dataset** | **Description** |
+|-------------------------------------|---------------------|---------------------------------------------------------------------------------------------------------|
+| Conversational | SQA | Conversational, only cell selection questions |
+| Weak supervision for aggregation | WTQ | Questions might involve aggregation, and the model must learn this given only the answer as supervision |
+| Strong supervision for aggregation | WikiSQL-supervised | Questions might involve aggregation, and the model must learn this given the gold aggregation operator |
+
+
 +
+ TextNet backbone as part of FAST. Taken from the original paper.
+
+This model was contributed by [Raghavan](https://huggingface.co/Raghavan), [jadechoghari](https://huggingface.co/jadechoghari) and [nielsr](https://huggingface.co/nielsr).
+
+## Usage tips
+
+TextNet is mainly used as a backbone network for the architecture search of text detection. Each stage of the backbone network is comprised of a stride-2 convolution and searchable blocks.
+Specifically, we present a layer-level candidate set, defined as {conv3×3, conv1×3, conv3×1, identity}. As the 1×3 and 3×1 convolutions have asymmetric kernels and oriented structure priors, they may help to capture the features of extreme aspect-ratio and rotated text lines.
+
+TextNet is the backbone for Fast, but can also be used as an efficient text/image classification, we add a `TextNetForImageClassification` as is it would allow people to train an image classifier on top of the pre-trained textnet weights
+
+## TextNetConfig
+
+[[autodoc]] TextNetConfig
+
+## TextNetImageProcessor
+
+[[autodoc]] TextNetImageProcessor
+ - preprocess
+
+## TextNetImageProcessorFast
+
+[[autodoc]] TextNetImageProcessorFast
+ - preprocess
+
+## TextNetModel
+
+[[autodoc]] TextNetModel
+ - forward
+
+## TextNetForImageClassification
+
+[[autodoc]] TextNetForImageClassification
+ - forward
+
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/time_series_transformer.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/time_series_transformer.md
new file mode 100644
index 0000000000000000000000000000000000000000..c38671f00fb3e5295209e316f81b604ecc54e835
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/time_series_transformer.md
@@ -0,0 +1,77 @@
+
+*This model was released on 2022-12-01 and added to Hugging Face Transformers on 2022-09-30.*
+
+# Time Series Transformer
+
+
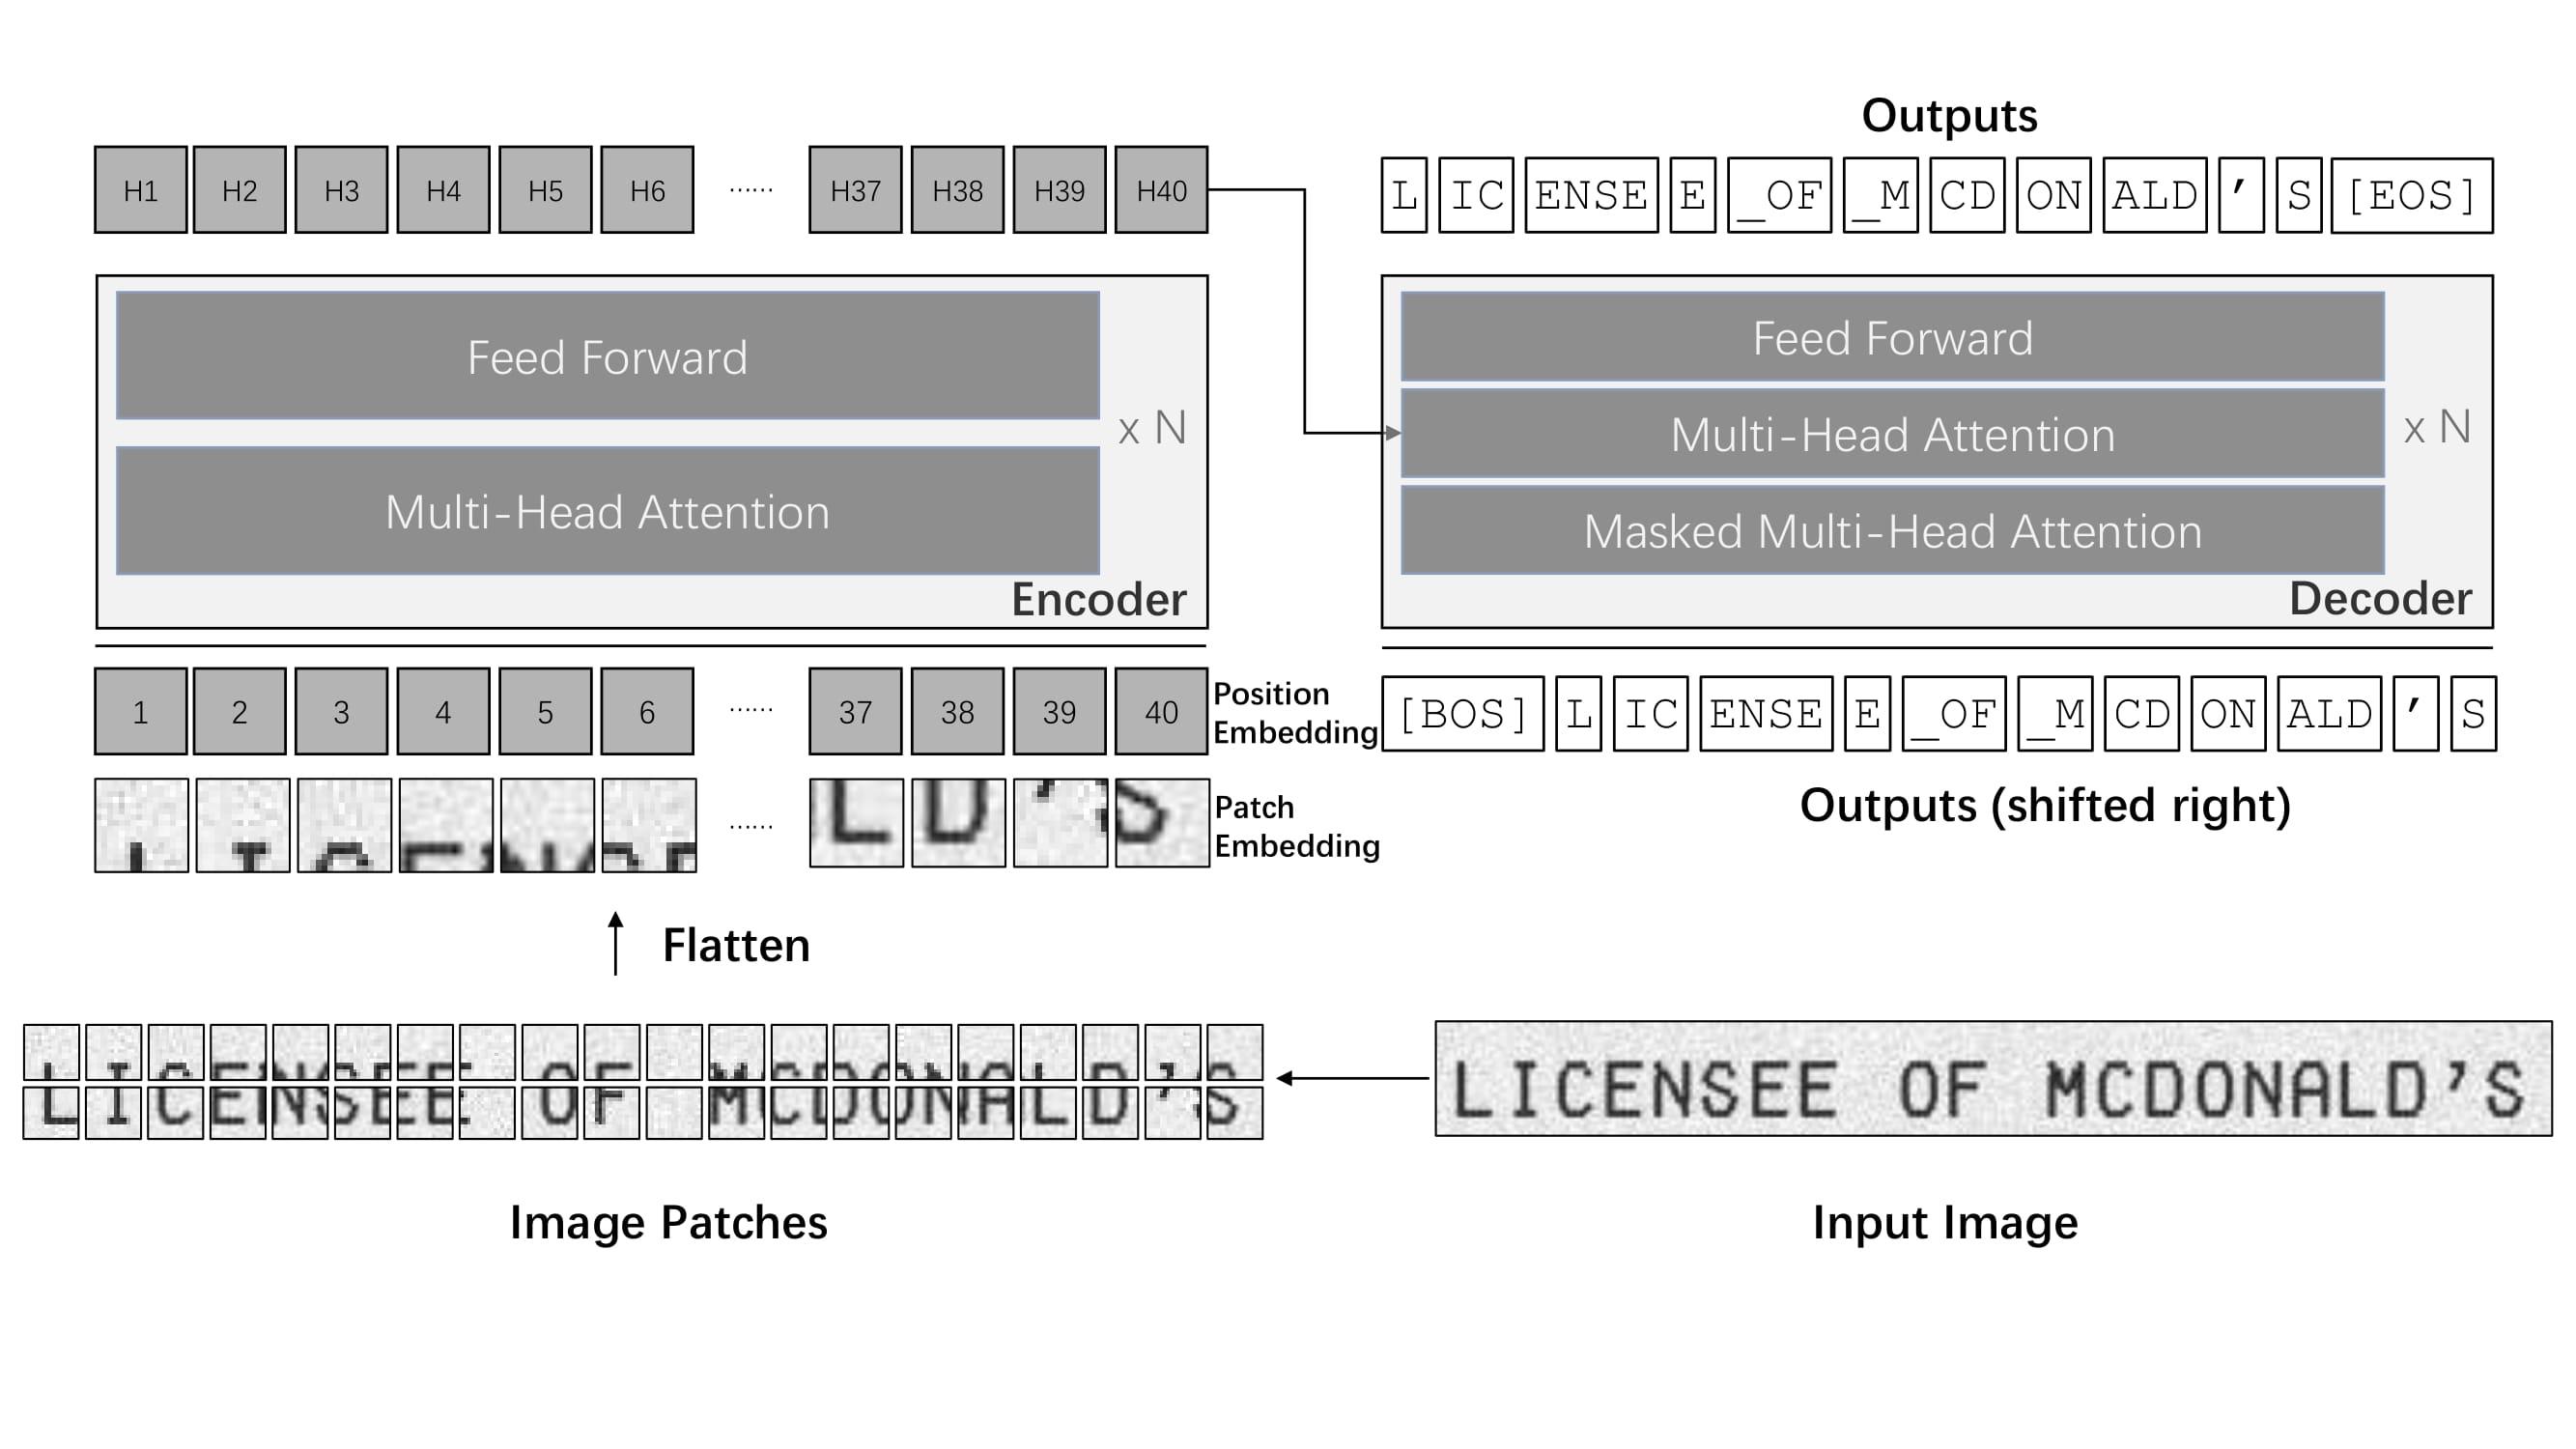 + TrOCR architecture. Taken from the original paper.
+
+
+> [!TIP]
+> This model was contributed by [nielsr](https://huggingface.co/nielsr).
+>
+> Click on the TrOCR models in the right sidebar for more examples of how to apply TrOCR to different image and text tasks.
+
+
+The example below demonstrates how to perform optical character recognition (OCR) with the [`AutoModel`] class.
+
+
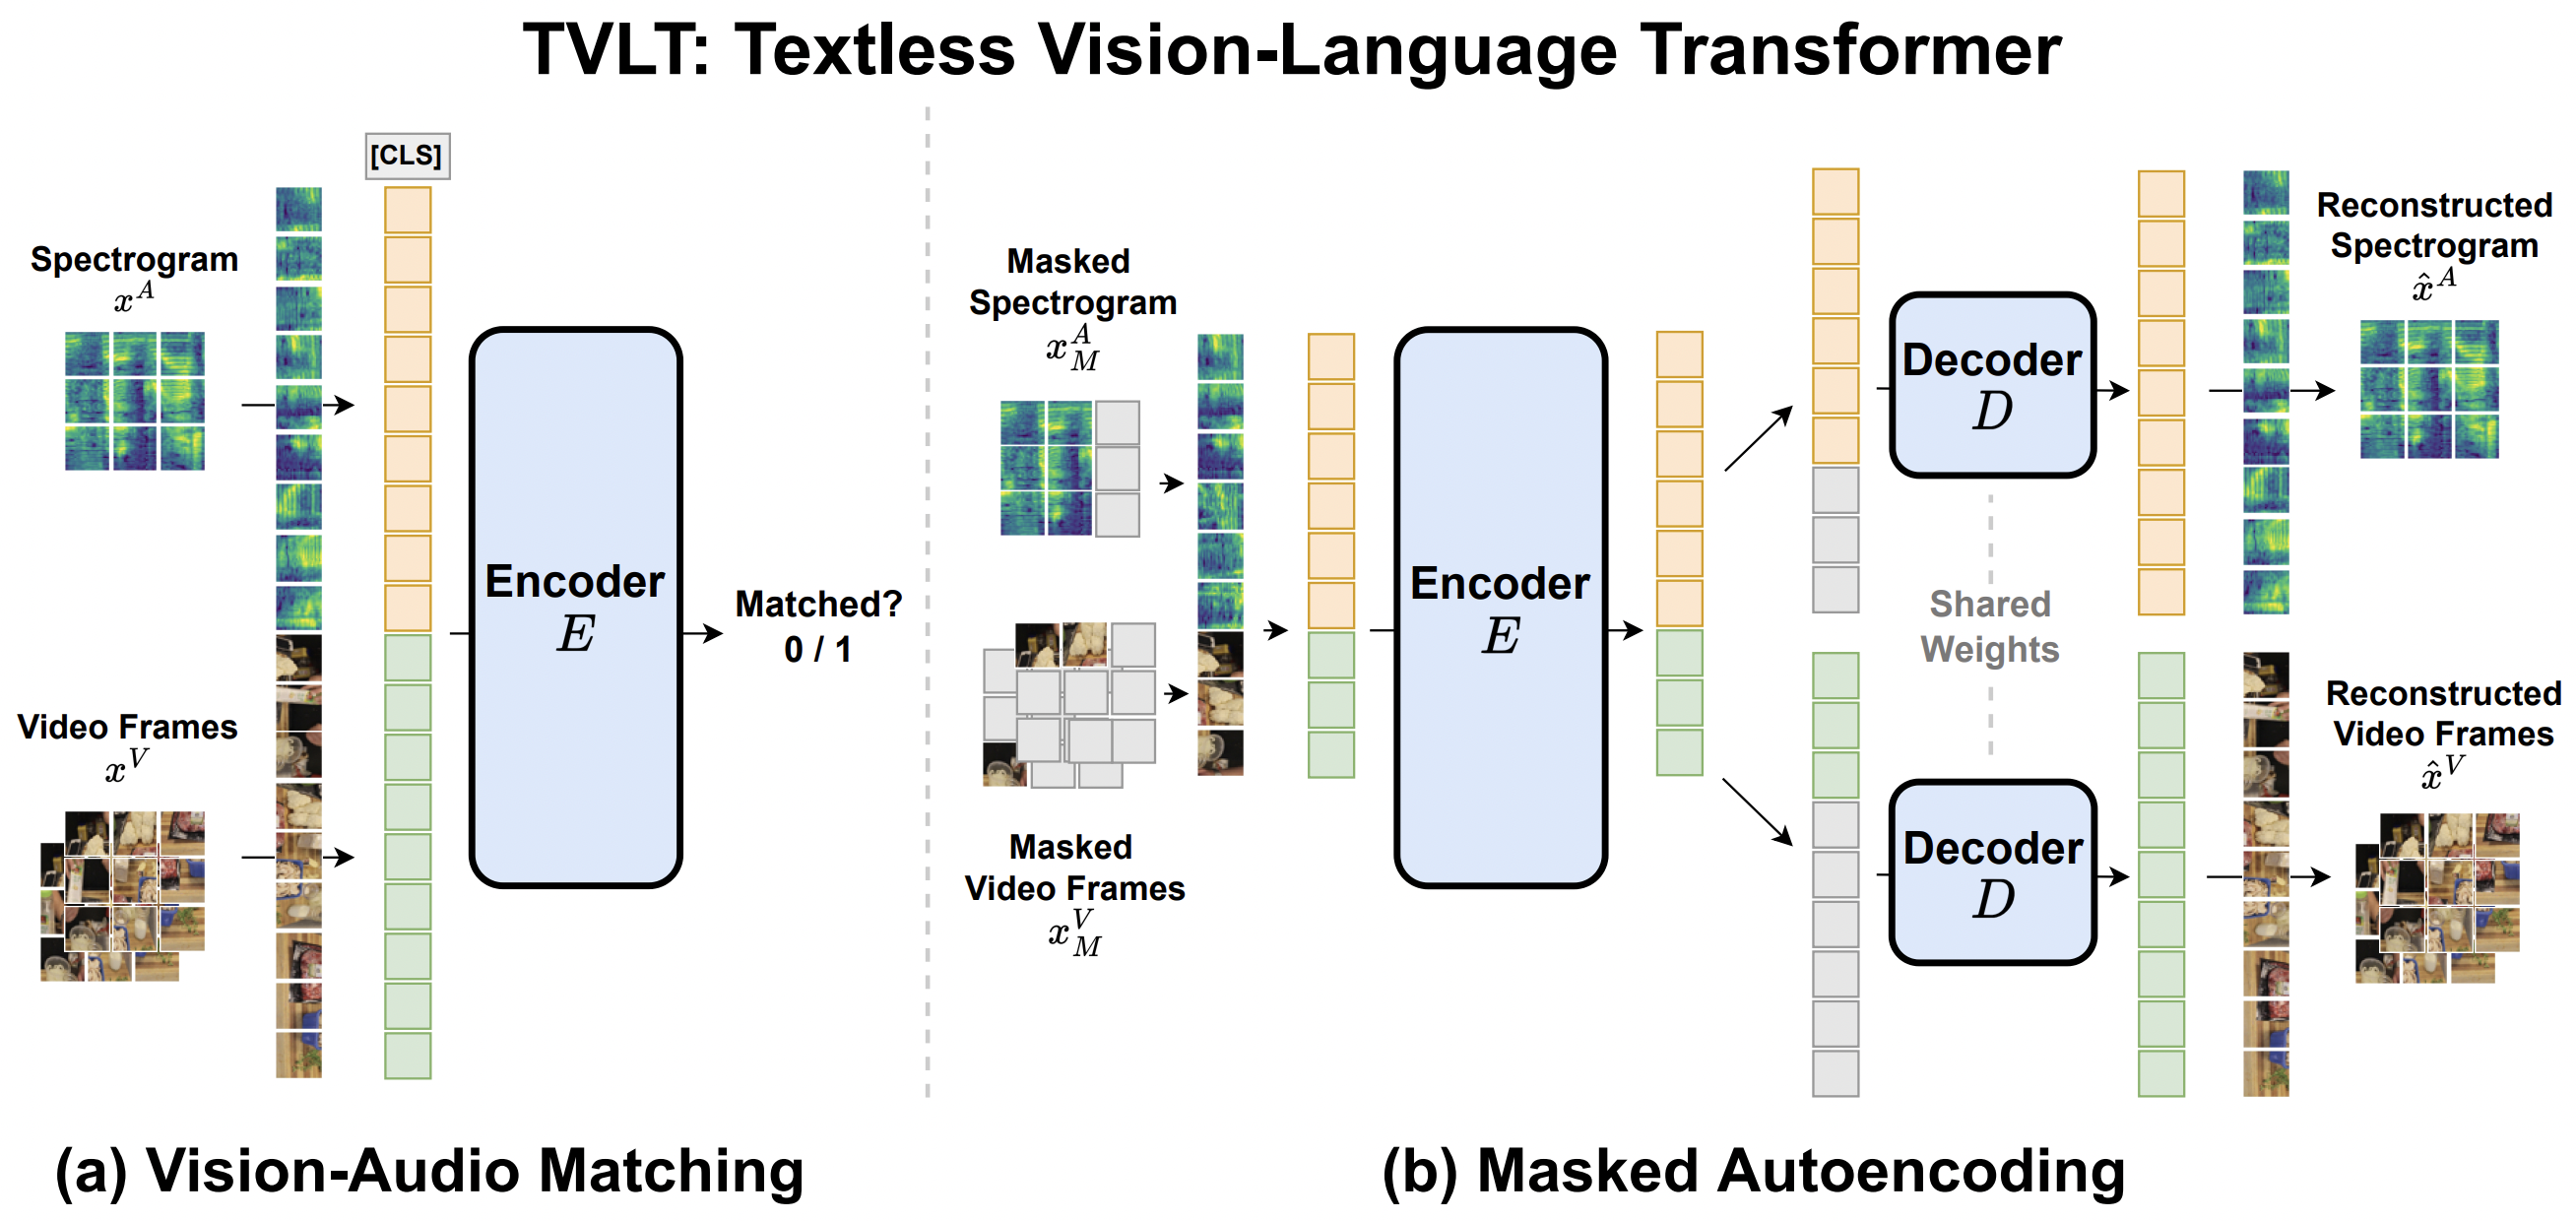 +
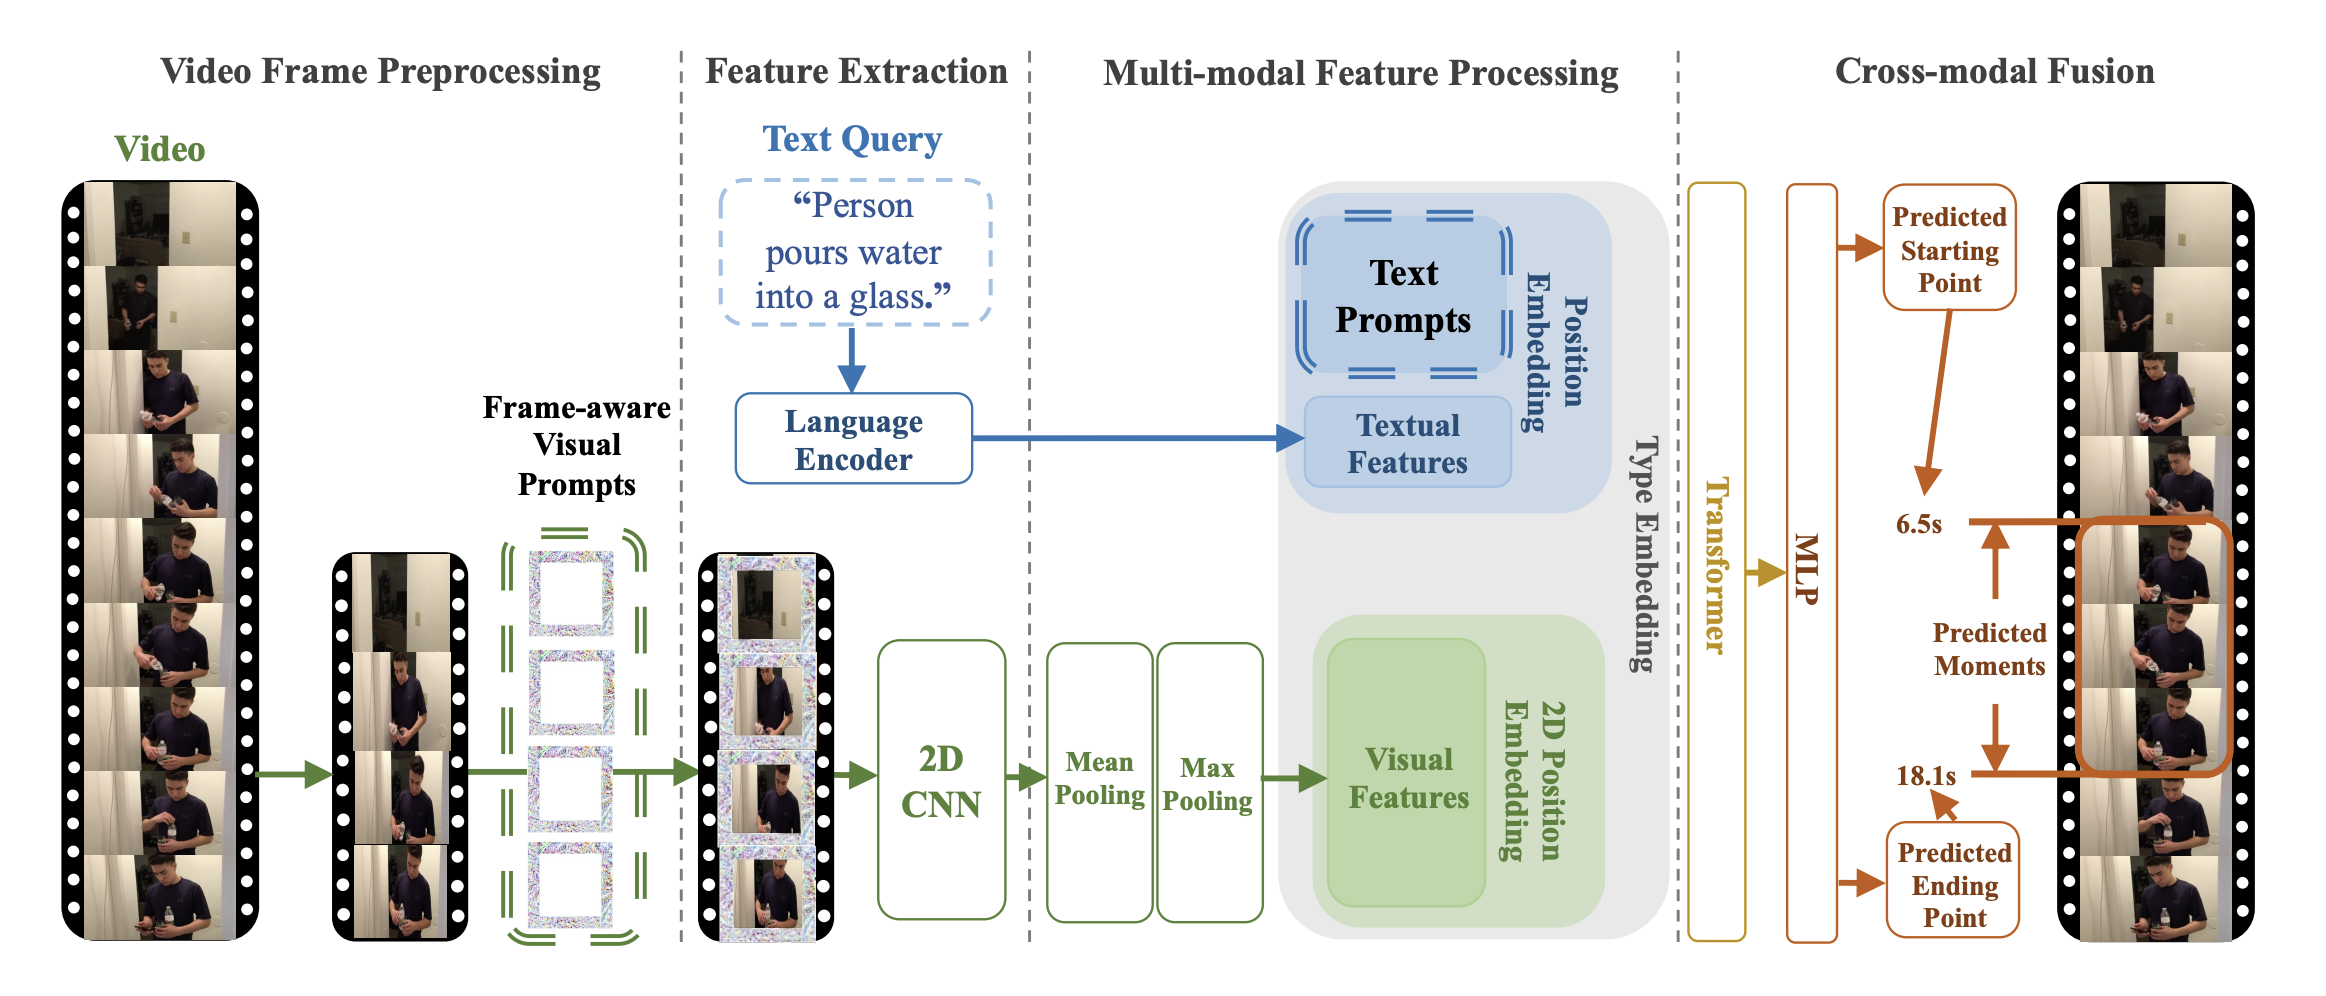 +
+ TVP architecture. Taken from the original paper.
+
+This model was contributed by [Jiqing Feng](https://huggingface.co/Jiqing). The original code can be found [here](https://github.com/intel/TVP).
+
+## Usage tips and examples
+
+Prompts are optimized perturbation patterns, which would be added to input video frames or text features. Universal set refers to using the same exact set of prompts for any input, this means that these prompts are added consistently to all video frames and text features, regardless of the input's content.
+
+TVP consists of a visual encoder and cross-modal encoder. A universal set of visual prompts and text prompts to be integrated into sampled video frames and textual features, respectively. Specially, a set of different visual prompts are applied to uniformly-sampled frames of one untrimmed video in order.
+
+The goal of this model is to incorporate trainable prompts into both visual inputs and textual features to temporal video grounding(TVG) problems.
+In principle, one can apply any visual, cross-modal encoder in the proposed architecture.
+
+The [`TvpProcessor`] wraps [`BertTokenizer`] and [`TvpImageProcessor`] into a single instance to both
+encode the text and prepare the images respectively.
+
+The following example shows how to run temporal video grounding using [`TvpProcessor`] and [`TvpForVideoGrounding`].
+```python
+import av
+import cv2
+import numpy as np
+import torch
+from huggingface_hub import hf_hub_download
+from transformers import AutoProcessor, TvpForVideoGrounding
+
+
+def pyav_decode(container, sampling_rate, num_frames, clip_idx, num_clips, target_fps):
+ '''
+ Convert the video from its original fps to the target_fps and decode the video with PyAV decoder.
+ Args:
+ container (container): pyav container.
+ sampling_rate (int): frame sampling rate (interval between two sampled frames).
+ num_frames (int): number of frames to sample.
+ clip_idx (int): if clip_idx is -1, perform random temporal sampling.
+ If clip_idx is larger than -1, uniformly split the video to num_clips
+ clips, and select the clip_idx-th video clip.
+ num_clips (int): overall number of clips to uniformly sample from the given video.
+ target_fps (int): the input video may have different fps, convert it to
+ the target video fps before frame sampling.
+ Returns:
+ frames (tensor): decoded frames from the video. Return None if the no
+ video stream was found.
+ fps (float): the number of frames per second of the video.
+ '''
+ video = container.streams.video[0]
+ fps = float(video.average_rate)
+ clip_size = sampling_rate * num_frames / target_fps * fps
+ delta = max(num_frames - clip_size, 0)
+ start_idx = delta * clip_idx / num_clips
+ end_idx = start_idx + clip_size - 1
+ timebase = video.duration / num_frames
+ video_start_pts = int(start_idx * timebase)
+ video_end_pts = int(end_idx * timebase)
+ seek_offset = max(video_start_pts - 1024, 0)
+ container.seek(seek_offset, any_frame=False, backward=True, stream=video)
+ frames = {}
+ for frame in container.decode(video=0):
+ if frame.pts < video_start_pts:
+ continue
+ frames[frame.pts] = frame
+ if frame.pts > video_end_pts:
+ break
+ frames = [frames[pts] for pts in sorted(frames)]
+ return frames, fps
+
+
+def decode(container, sampling_rate, num_frames, clip_idx, num_clips, target_fps):
+ '''
+ Decode the video and perform temporal sampling.
+ Args:
+ container (container): pyav container.
+ sampling_rate (int): frame sampling rate (interval between two sampled frames).
+ num_frames (int): number of frames to sample.
+ clip_idx (int): if clip_idx is -1, perform random temporal sampling.
+ If clip_idx is larger than -1, uniformly split the video to num_clips
+ clips, and select the clip_idx-th video clip.
+ num_clips (int): overall number of clips to uniformly sample from the given video.
+ target_fps (int): the input video may have different fps, convert it to
+ the target video fps before frame sampling.
+ Returns:
+ frames (tensor): decoded frames from the video.
+ '''
+ assert clip_idx >= -2, "Not a valid clip_idx {}".format(clip_idx)
+ frames, fps = pyav_decode(container, sampling_rate, num_frames, clip_idx, num_clips, target_fps)
+ clip_size = sampling_rate * num_frames / target_fps * fps
+ index = np.linspace(0, clip_size - 1, num_frames)
+ index = np.clip(index, 0, len(frames) - 1).astype(np.int64)
+ frames = np.array([frames[idx].to_rgb().to_ndarray() for idx in index])
+ frames = frames.transpose(0, 3, 1, 2)
+ return frames
+
+
+file = hf_hub_download(repo_id="Intel/tvp_demo", filename="AK2KG.mp4", repo_type="dataset")
+model = TvpForVideoGrounding.from_pretrained("Intel/tvp-base")
+
+decoder_kwargs = dict(
+ container=av.open(file, metadata_errors="ignore"),
+ sampling_rate=1,
+ num_frames=model.config.num_frames,
+ clip_idx=0,
+ num_clips=1,
+ target_fps=3,
+)
+raw_sampled_frms = decode(**decoder_kwargs)
+
+text = "a person is sitting on a bed."
+processor = AutoProcessor.from_pretrained("Intel/tvp-base")
+model_inputs = processor(
+ text=[text], videos=list(raw_sampled_frms), return_tensors="pt", max_text_length=100#, size=size
+)
+
+model_inputs["pixel_values"] = model_inputs["pixel_values"].to(model.dtype)
+output = model(**model_inputs)
+
+def get_video_duration(filename):
+ cap = cv2.VideoCapture(filename)
+ if cap.isOpened():
+ rate = cap.get(5)
+ frame_num = cap.get(7)
+ duration = frame_num/rate
+ return duration
+ return -1
+
+duration = get_video_duration(file)
+start, end = processor.post_process_video_grounding(output.logits, duration)
+
+print(f"The time slot of the video corresponding to the text \"{text}\" is from {start}s to {end}s")
+```
+
+Tips:
+
+- This implementation of TVP uses [`BertTokenizer`] to generate text embeddings and Resnet-50 model to compute visual embeddings.
+- Checkpoints for pre-trained [tvp-base](https://huggingface.co/Intel/tvp-base) is released.
+- Please refer to [Table 2](https://huggingface.co/papers/2303.04995) for TVP's performance on Temporal Video Grounding task.
+
+
+## TvpConfig
+
+[[autodoc]] TvpConfig
+
+## TvpImageProcessor
+
+[[autodoc]] TvpImageProcessor
+ - preprocess
+
+## TvpImageProcessorFast
+
+[[autodoc]] TvpImageProcessorFast
+ - preprocess
+
+## TvpProcessor
+
+[[autodoc]] TvpProcessor
+ - __call__
+
+## TvpModel
+
+[[autodoc]] TvpModel
+ - forward
+
+## TvpForVideoGrounding
+
+[[autodoc]] TvpForVideoGrounding
+ - forward
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/udop.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/udop.md
new file mode 100644
index 0000000000000000000000000000000000000000..eb400cc39d5f49f0283a3c61c7adb9dbe4bc585a
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/udop.md
@@ -0,0 +1,118 @@
+
+*This model was released on 2022-12-05 and added to Hugging Face Transformers on 2024-03-04.*
+
+# UDOP
+
+
 +
+ UDOP architecture. Taken from the original paper.
+
+## Usage tips
+
+- In addition to *input_ids*, [`UdopForConditionalGeneration`] also expects the input `bbox`, which are
+ the bounding boxes (i.e. 2D-positions) of the input tokens. These can be obtained using an external OCR engine such
+ as Google's [Tesseract](https://github.com/tesseract-ocr/tesseract) (there's a [Python wrapper](https://pypi.org/project/pytesseract/) available). Each bounding box should be in (x0, y0, x1, y1) format, where (x0, y0) corresponds to the position of the upper left corner in the bounding box, and (x1, y1) represents the
+ position of the lower right corner. Note that one first needs to normalize the bounding boxes to be on a 0-1000
+ scale. To normalize, you can use the following function:
+
+```python
+def normalize_bbox(bbox, width, height):
+ return [
+ int(1000 * (bbox[0] / width)),
+ int(1000 * (bbox[1] / height)),
+ int(1000 * (bbox[2] / width)),
+ int(1000 * (bbox[3] / height)),
+ ]
+```
+
+Here, `width` and `height` correspond to the width and height of the original document in which the token
+occurs. Those can be obtained using the Python Image Library (PIL) library for example, as follows:
+
+```python
+from PIL import Image
+
+# Document can be a png, jpg, etc. PDFs must be converted to images.
+image = Image.open(name_of_your_document).convert("RGB")
+
+width, height = image.size
+```
+
+One can use [`UdopProcessor`] to prepare images and text for the model, which takes care of all of this. By default, this class uses the Tesseract engine to extract a list of words and boxes (coordinates) from a given document. Its functionality is equivalent to that of [`LayoutLMv3Processor`], hence it supports passing either `apply_ocr=False` in case you prefer to use your own OCR engine or `apply_ocr=True` in case you want the default OCR engine to be used. Refer to the [usage guide of LayoutLMv2](layoutlmv2#usage-layoutlmv2processor) regarding all possible use cases (the functionality of `UdopProcessor` is identical).
+
+- If using an own OCR engine of choice, one recommendation is Azure's [Read API](https://learn.microsoft.com/en-us/azure/ai-services/computer-vision/how-to/call-read-api), which supports so-called line segments. Use of segment position embeddings typically results in better performance.
+- At inference time, it's recommended to use the `generate` method to autoregressively generate text given a document image.
+- The model has been pre-trained on both self-supervised and supervised objectives. One can use the various task prefixes (prompts) used during pre-training to test out the out-of-the-box capabilities. For instance, the model can be prompted with "Question answering. What is the date?", as "Question answering." is the task prefix used during pre-training for DocVQA. Refer to the [paper](https://huggingface.co/papers/2212.02623) (table 1) for all task prefixes.
+- One can also fine-tune [`UdopEncoderModel`], which is the encoder-only part of UDOP, which can be seen as a LayoutLMv3-like Transformer encoder. For discriminative tasks, one can just add a linear classifier on top of it and fine-tune it on a labeled dataset.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr).
+The original code can be found [here](https://github.com/microsoft/UDOP).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with UDOP. If
+you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll
+review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+- Demo notebooks regarding UDOP can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/UDOP) that show how
+to fine-tune UDOP on a custom dataset as well as inference. 🌎
+- [Document question answering task guide](../tasks/document_question_answering)
+
+## UdopConfig
+
+[[autodoc]] UdopConfig
+
+## UdopTokenizer
+
+[[autodoc]] UdopTokenizer
+ - build_inputs_with_special_tokens
+ - get_special_tokens_mask
+ - create_token_type_ids_from_sequences
+ - save_vocabulary
+
+## UdopTokenizerFast
+
+[[autodoc]] UdopTokenizerFast
+
+## UdopProcessor
+
+[[autodoc]] UdopProcessor
+ - __call__
+
+## UdopModel
+
+[[autodoc]] UdopModel
+ - forward
+
+## UdopForConditionalGeneration
+
+[[autodoc]] UdopForConditionalGeneration
+ - forward
+
+## UdopEncoderModel
+
+[[autodoc]] UdopEncoderModel
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ul2.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ul2.md
new file mode 100644
index 0000000000000000000000000000000000000000..ca0bacbc43f18e37366947ba8c4230f394d9359f
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/ul2.md
@@ -0,0 +1,51 @@
+
+*This model was released on 2022-05-10 and added to Hugging Face Transformers on 2023-06-20.*
+
+# UL2
+
+
 +
+ UPerNet framework. Taken from the original paper.
+
+This model was contributed by [nielsr](https://huggingface.co/nielsr). The original code is based on OpenMMLab's mmsegmentation [here](https://github.com/open-mmlab/mmsegmentation/blob/master/mmseg/models/decode_heads/uper_head.py).
+
+## Usage examples
+
+UPerNet is a general framework for semantic segmentation. It can be used with any vision backbone, like so:
+
+```py
+from transformers import SwinConfig, UperNetConfig, UperNetForSemanticSegmentation
+
+backbone_config = SwinConfig(out_features=["stage1", "stage2", "stage3", "stage4"])
+
+config = UperNetConfig(backbone_config=backbone_config)
+model = UperNetForSemanticSegmentation(config)
+```
+
+To use another vision backbone, like [ConvNeXt](convnext), simply instantiate the model with the appropriate backbone:
+
+```py
+from transformers import ConvNextConfig, UperNetConfig, UperNetForSemanticSegmentation
+
+backbone_config = ConvNextConfig(out_features=["stage1", "stage2", "stage3", "stage4"])
+
+config = UperNetConfig(backbone_config=backbone_config)
+model = UperNetForSemanticSegmentation(config)
+```
+
+Note that this will randomly initialize all the weights of the model.
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with UPerNet.
+
+- Demo notebooks for UPerNet can be found [here](https://github.com/NielsRogge/Transformers-Tutorials/tree/master/UPerNet).
+- [`UperNetForSemanticSegmentation`] is supported by this [example script](https://github.com/huggingface/transformers/tree/main/examples/pytorch/semantic-segmentation) and [notebook](https://colab.research.google.com/github/huggingface/notebooks/blob/main/examples/semantic_segmentation.ipynb).
+- See also: [Semantic segmentation task guide](../tasks/semantic_segmentation)
+
+If you're interested in submitting a resource to be included here, please feel free to open a Pull Request and we'll review it! The resource should ideally demonstrate something new instead of duplicating an existing resource.
+
+## UperNetConfig
+
+[[autodoc]] UperNetConfig
+
+## UperNetForSemanticSegmentation
+
+[[autodoc]] UperNetForSemanticSegmentation
+ - forward
\ No newline at end of file
diff --git a/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/van.md b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/van.md
new file mode 100644
index 0000000000000000000000000000000000000000..0e07e314bee979cf180bfcb1e636fd63d9049647
--- /dev/null
+++ b/tasks/tasksmith-5cbfd9f64dbc/environment/source/docs/source/en/model_doc/van.md
@@ -0,0 +1,77 @@
+
+*This model was released on 2022-02-20 and added to Hugging Face Transformers on 2023-06-20.*
+
+# VAN
+
+
 +
+This model was contributed by [Francesco](https://huggingface.co/Francesco). The original code can be found [here](https://github.com/Visual-Attention-Network/VAN-Classification).
+
+## Resources
+
+A list of official Hugging Face and community (indicated by 🌎) resources to help you get started with VAN.
+
+
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +
 +